
🔥🔥🔥 [IEEE TCSVT] Latest Papers, Codes and Datasets on Vid-LLMs.
3,289
212 commits
updated Sep 24, 2026
README
Awesome-LLMs-for-Video-Understanding 
🔥🔥🔥 Video Understanding with Large Language Models: A Survey
Yolo Y. Tang1, Jing Bi1, Siting Xu2, Luchuan Song1, Susan Liang1 , Teng Wang2,3 , Daoan Zhang1 , Jie An1 , Jingyang Lin1 , Rongyi Zhu1 , Ali Vosoughi1 , Chao Huang1 , Zeliang Zhang1 , Pinxin Liu1 , Mingqian Feng1 , Feng Zheng2 , Jianguo Zhang2 , Ping Luo3 , Jiebo Luo1, Chenliang Xu1.
1University of Rochester, 2Southern University of Science and Technology, 3The University of Hong Kong
Paper | arXiv | Project Page
📢 News
[10/06/2025]
🔥 Our follow-up work—Video-LMM Post-Training: A Deep Dive into Video Reasoning with Large Multimodal Models—is now available on arXiv and Hugging Face Papers!
[05/04/2025]
🌟 Our Vid-LLM survey has been accepted to the IEEE Transactions on Circuits and Systems for Video Technology (TCSVT)! 👉 IEEE Xplore | GitHub
[07/23/2024]
📢 We've recently updated our survey: “Video Understanding with Large Language Models: A Survey”!
✨ This comprehensive survey covers video understanding techniques powered by large language models (Vid-LLMs), training strategies, relevant tasks, datasets, benchmarks, and evaluation methods, and discusses the applications of Vid-LLMs across various domains.
🚀 What's New in This Update:
✅ Updated to include around 100 additional Vid-LLMs and 15 new benchmarks as of June 2024.
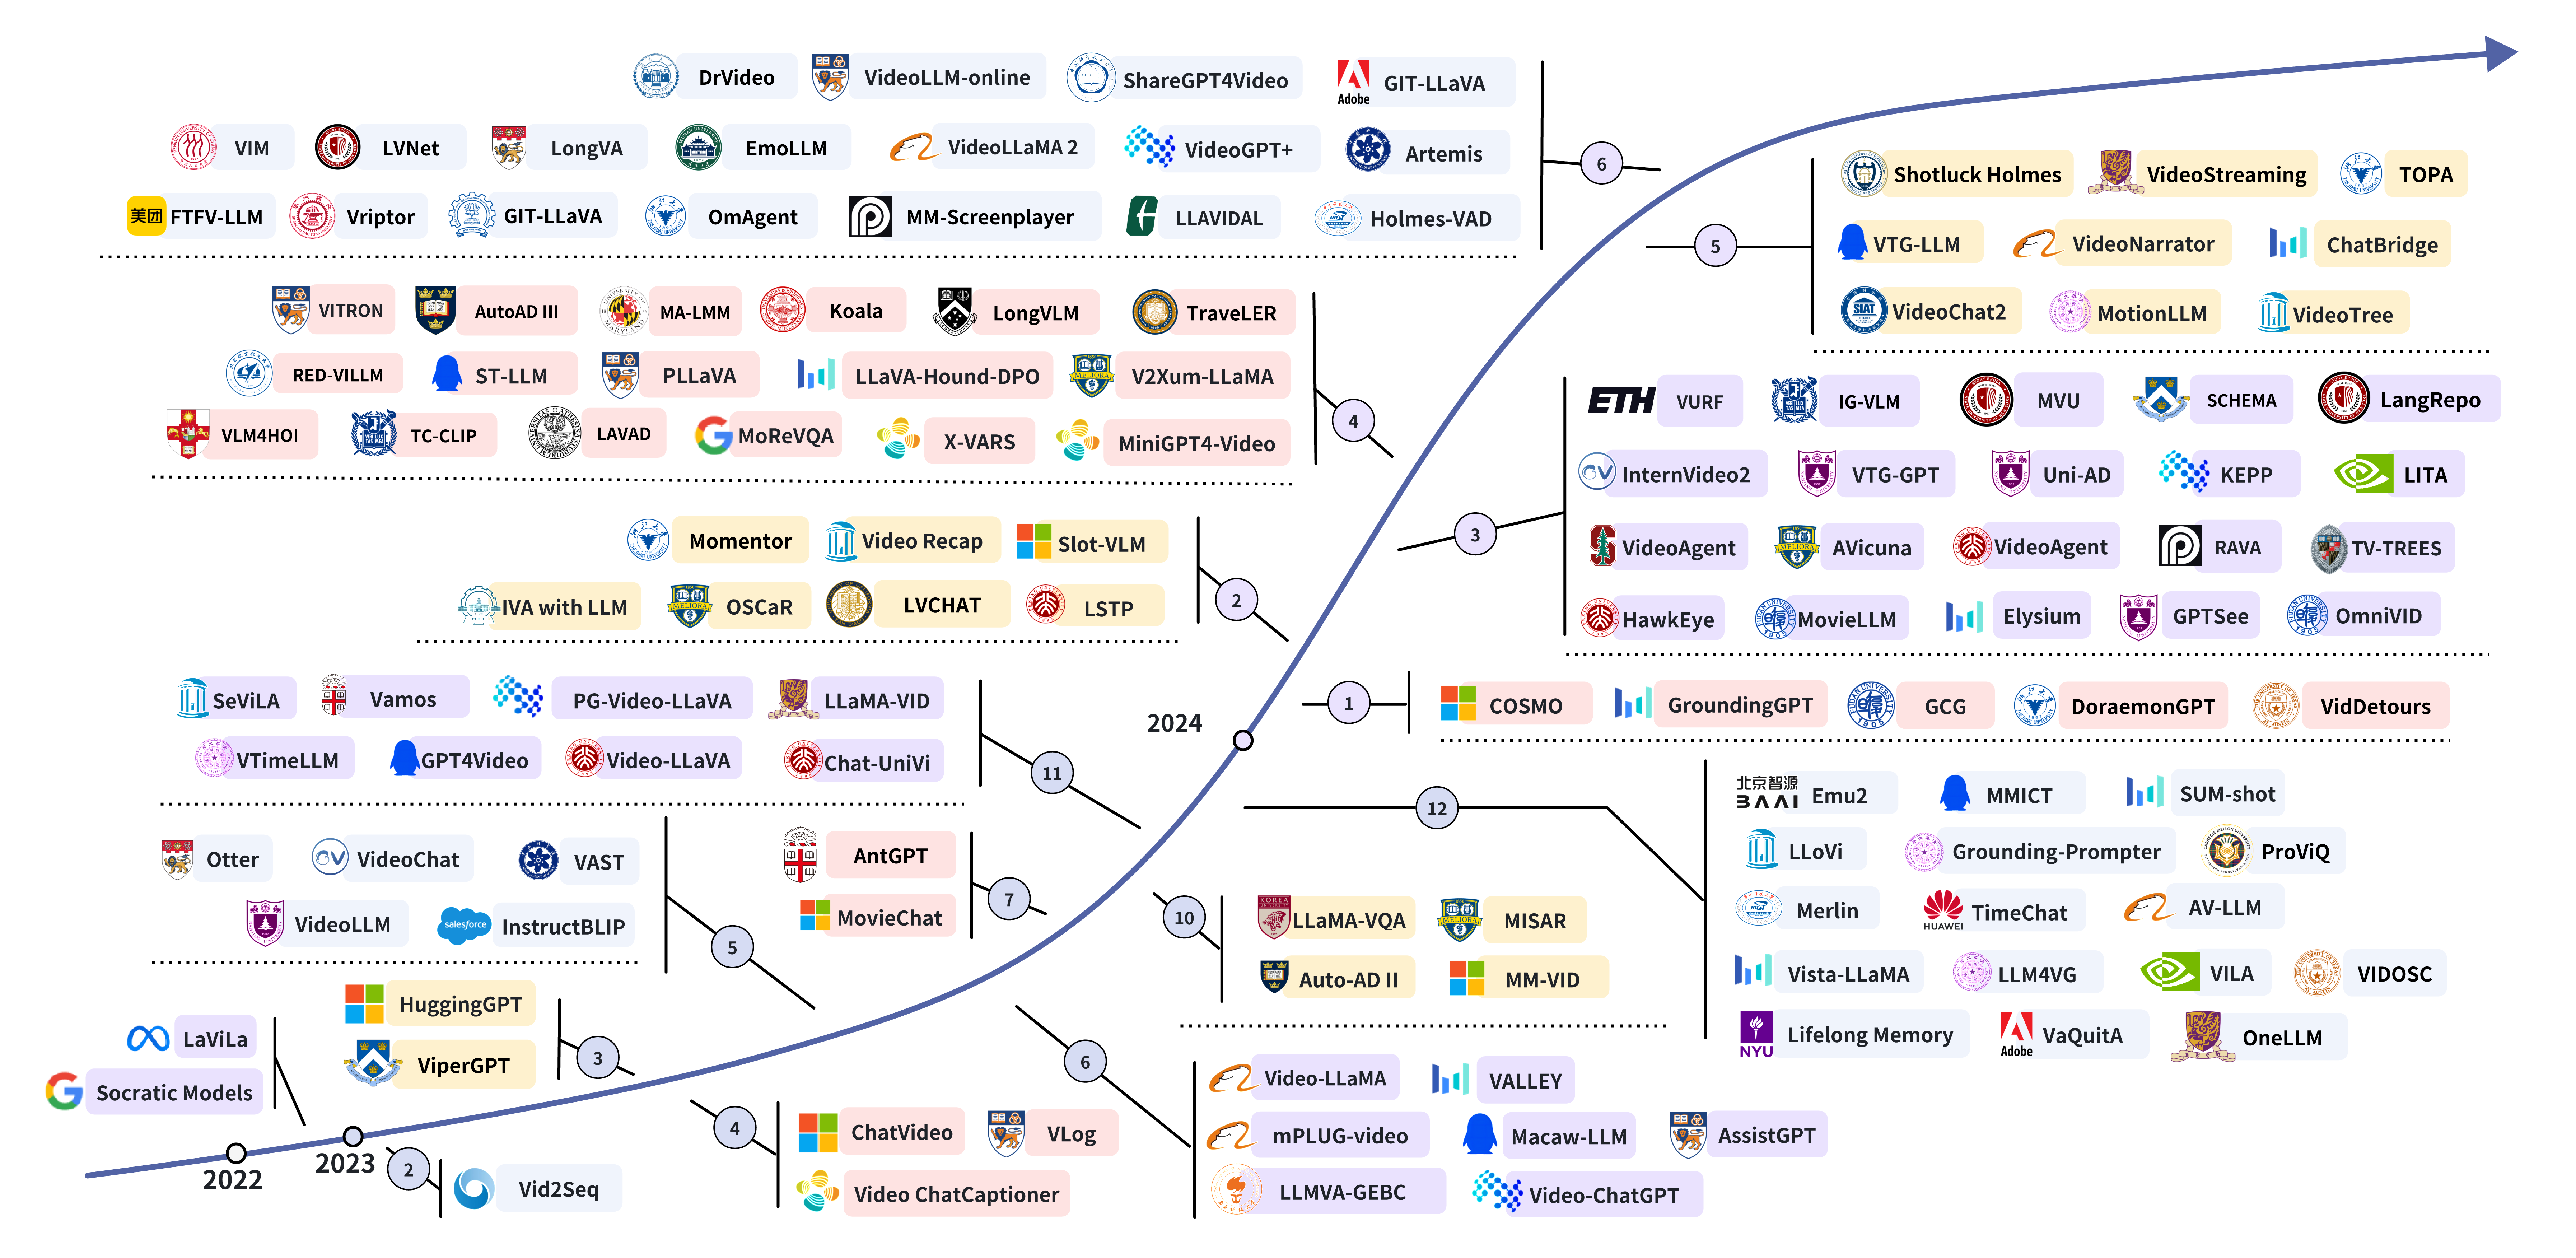
✅ Introduced a novel taxonomy for Vid-LLMs based on video representation and LLM functionality.
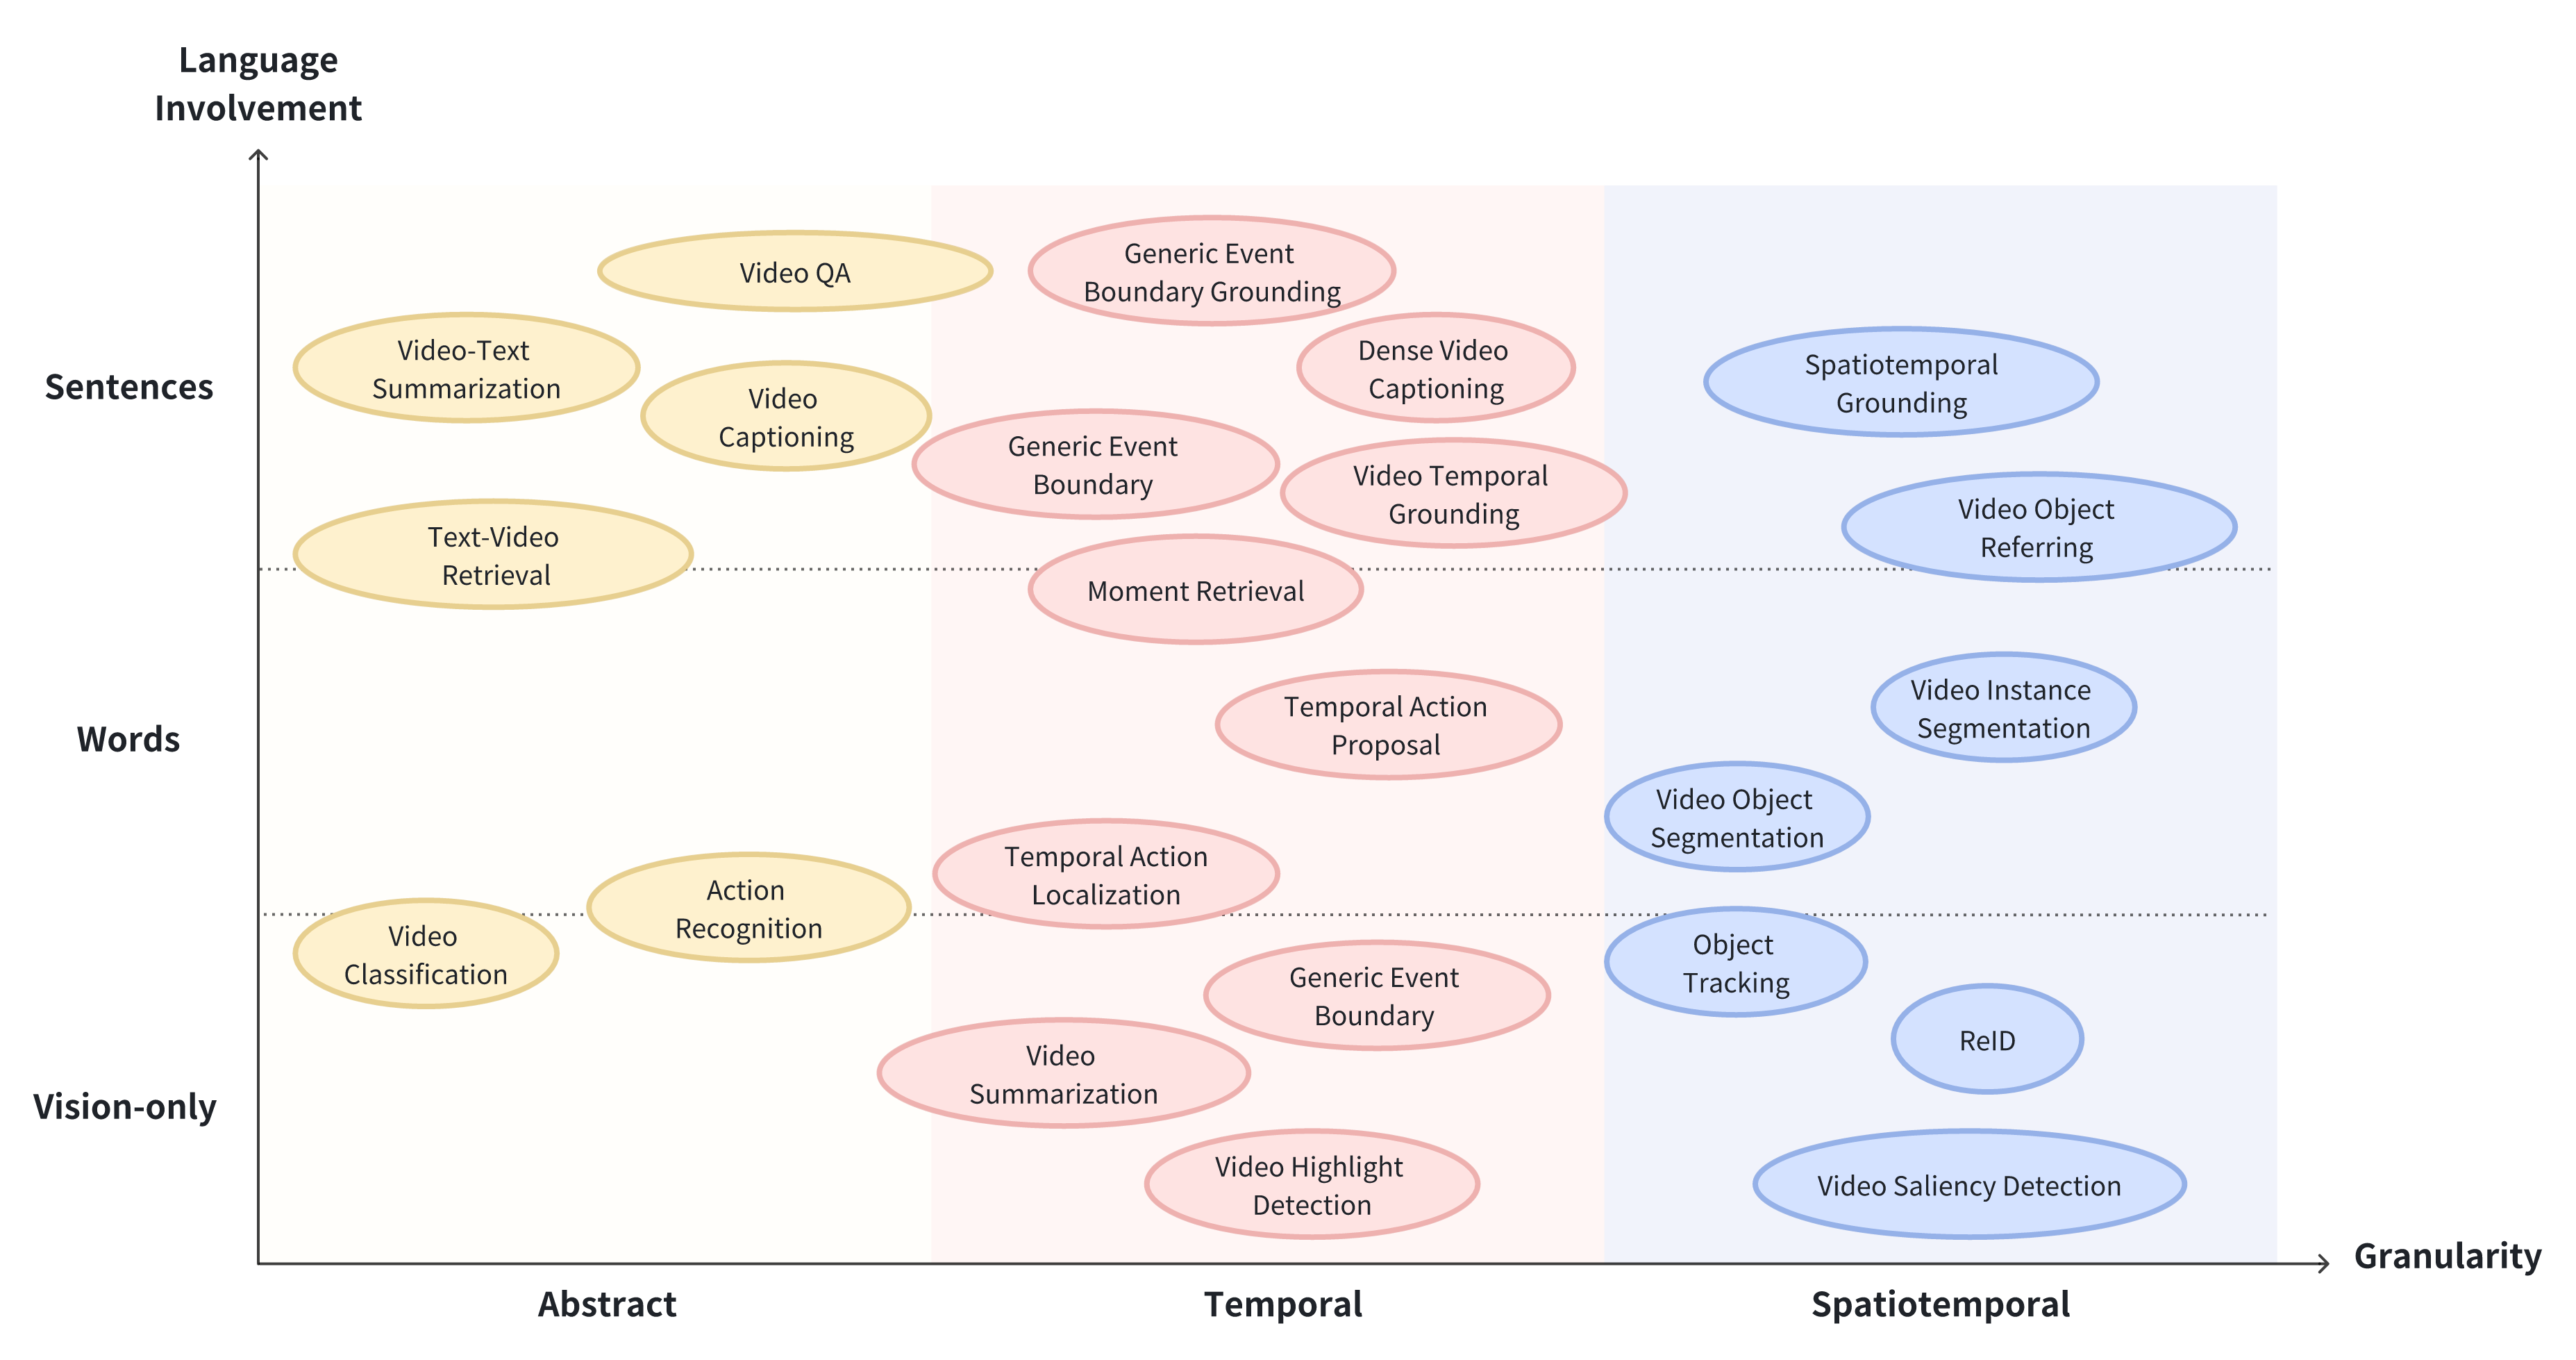
✅ Added a Preliminary chapter, reclassifying video understanding tasks from the perspectives of granularity and language involvement, and enhanced the LLM Background section.
✅ Added a new Training Strategies chapter, removing adapters as a factor for model classification.
✅ All figures and tables have been redesigned.
Multiple minor updates will follow this major update. And the GitHub repository will be gradually updated soon. We welcome your reading and feedback ❤️
Table of Contents- Awesome-LLMs-for-Video-Understanding
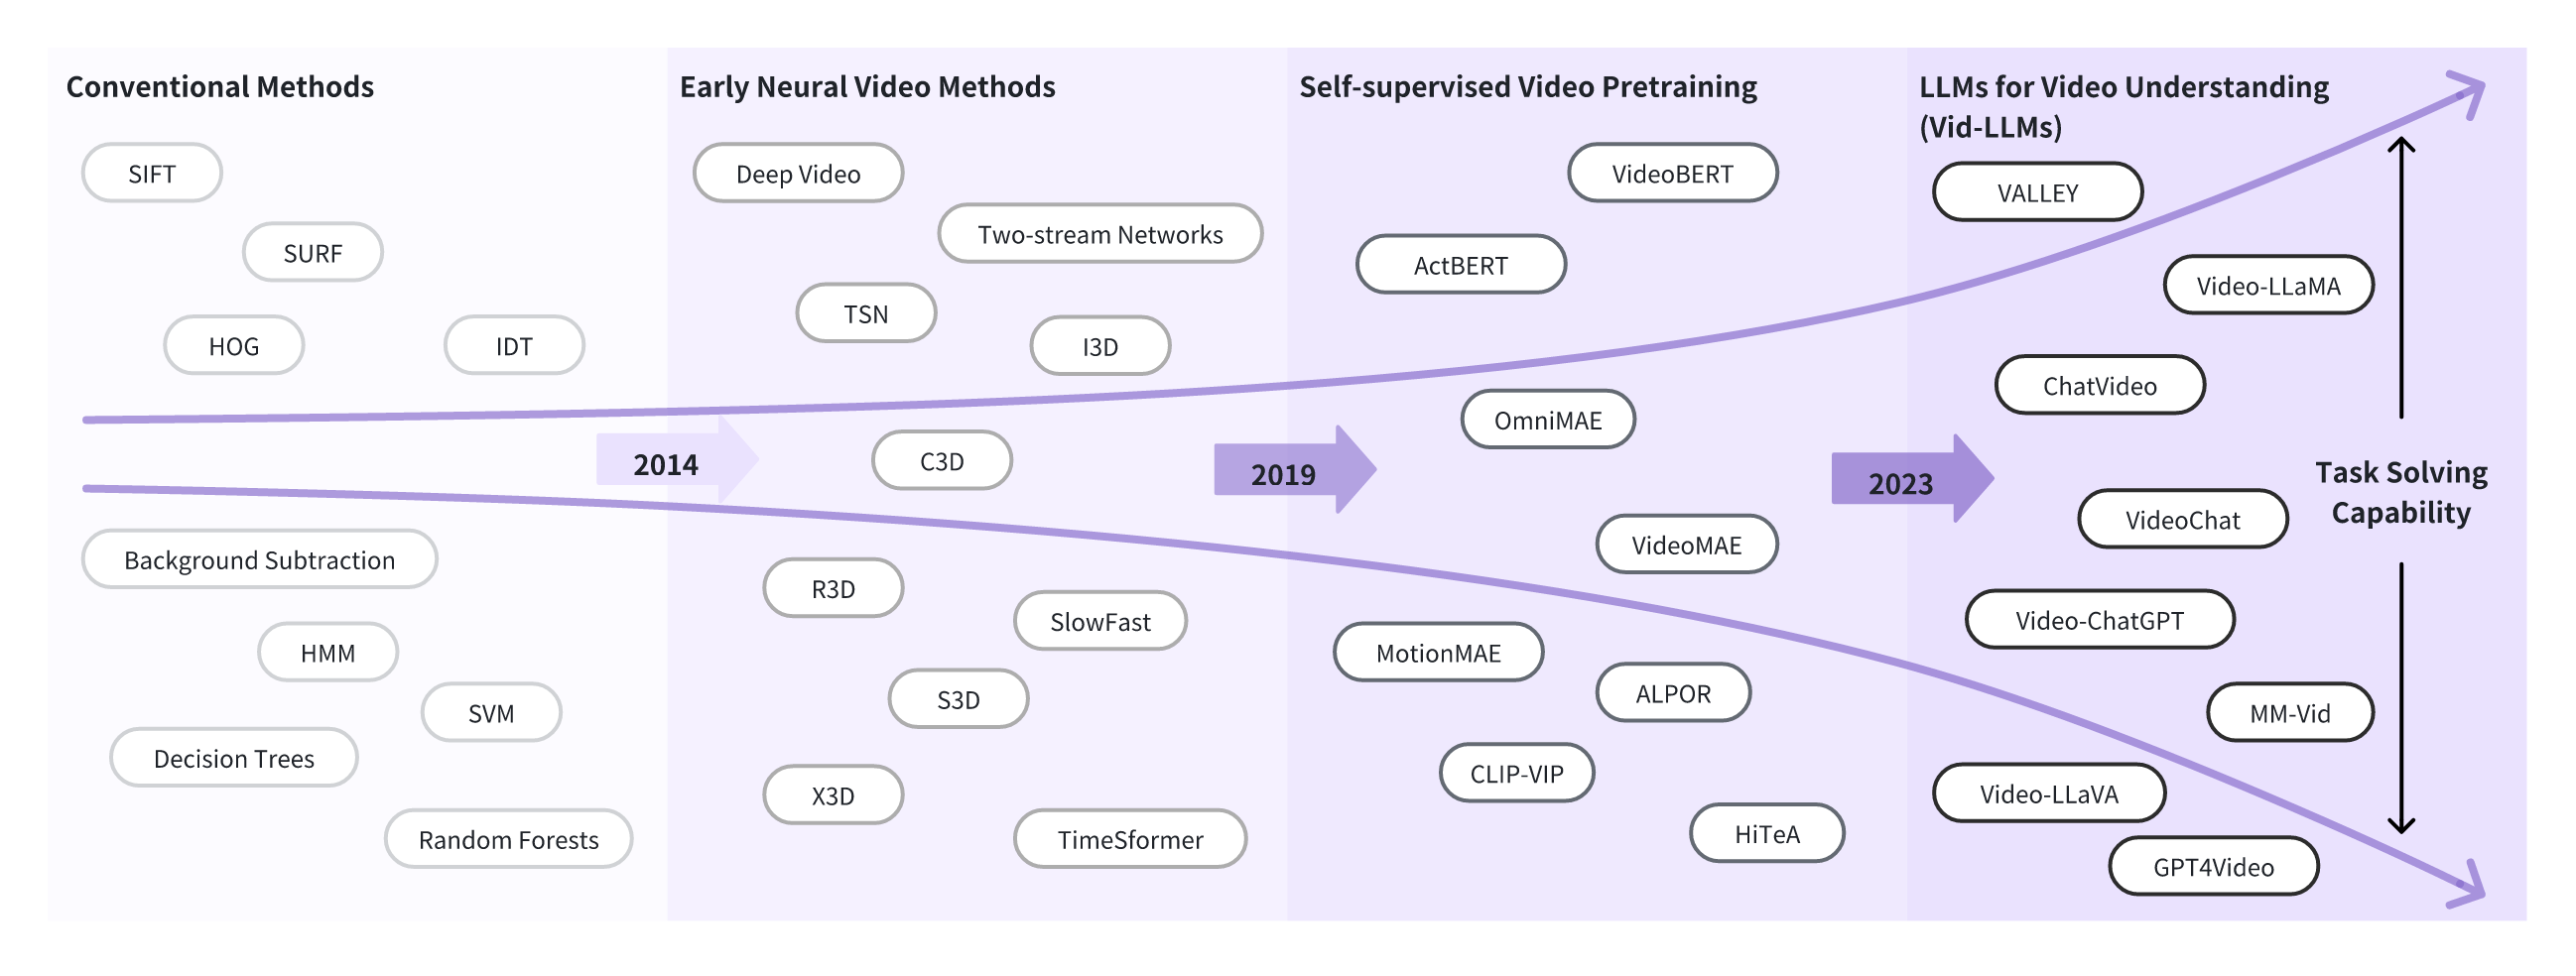
Why we need Vid-LLMs?
😎 Vid-LLMs: Models
📑 Citation
If you find our survey useful for your research, please cite the following paper:
@article{vidllmsurvey,
  author={Tang, Yunlong and Bi, Jing and Xu, Siting and Song, Luchuan and Liang, Susan and Wang, Teng and Zhang, Daoan and An, Jie and Lin, Jingyang and Zhu, Rongyi and Vosoughi, Ali and Huang, Chao and Zhang, Zeliang and Liu, Pinxin and Feng, Mingqian and Zheng, Feng and Zhang, Jianguo and Luo, Ping and Luo, Jiebo and Xu, Chenliang},
  journal={IEEE Transactions on Circuits and Systems for Video Technology},
  title={Video Understanding with Large Language Models: A Survey},
  year={2025},
  doi={10.1109/TCSVT.2025.3566695}
}
🗒️ Taxonomy 1
🕹️ Video Analyzer × LLM
LLM as Summarizer

LLM as Manager

👾 Video Embedder × LLM
LLM as Text Decoder
LLM as Regressor
LLM as Hidden Layer
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
| VTG-LLM integrating timestamp knowledge into video LLMs for enhanced video temporal grounding | VTG-LLM | 05/2024 | code | arXiv |
| VITRON: A Unified Pixel-level Vision LLM for Understanding, Generating, Segmenting, Editing | VITRON | 04/2024 | project page | NeurIPS |
| VTG-GPT: Tuning-Free Zero-Shot Video Temporal Grounding with GPT | VTG-GPT | 03/2024 | code | arXiv |
| Momentor advancing video large language model with fine-grained temporal reasoning | Momentor | 02/2024 | code | ICML |
| Detours for navigating instructional videos | VidDetours | 01/2024 | code | CVPR |
| OneLLM: One Framework to Align All Modalities with Language | OneLLM | 12/2023 | code | arXiv |
| GPT4Video a unified multimodal large language model for lnstruction-followed understanding and safety-aware generation | GPT4Video | 11/2023 | code | ACMMM |
🧭 (Analyzer + Embedder) × LLM
LLM as Manager
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
| MM-VID: Advancing Video Understanding with GPT-4V(ision) | MM-VID | 10/2023 | - | arXiv |
LLM as Summarizer
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
| Shot2Story20K a new benchmark for comprehensive understanding of multi-shot videos | SUM-shot | 12/2023 | code | arXiv |
LLM as Regressor
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
| Vript: A Video Is Worth Thousands of Words | Vriptor | 06/2024 | code | NeurIPS |
| Merlin:Empowering Multimodal LLMs with Foresight Minds | Merlin | 12/2023 | project page | ECCV |
| VideoChat: Chat-Centric Video Understanding | VideoChat | 05/2023 | code | arXiv |
| Vid2Seq: Large-Scale Pretraining of a Visual Language Model for Dense Video Captioning | Vid2Seq | 02/2023 | code | CVPR |
LLM as Text Decoder
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
| Contextual AD Narration with Interleaved Multimodal Sequence | Uni-AD | 03/2024 | code | arXiv |
| MM-Narrator: Narrating Long-form Videos with Multimodal In-Context Learning | MM-narrator | 11/2023 | project page | arXiv |
| Vamos: Versatile Action Models for Video Understanding | Vamos | 11/2023 | project page | ECCV |
| AutoAD II: The Sequel -- Who, When, and What in Movie Audio Description | Auto-AD II | 10/2023 | project page | ICCV |
LLM as Hidden Layer
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
PG-Video-LLaVA: Pixel Grounding Large Video-Language Models | PG-Video-LLaVA | 11/2023 | code | arXiv |
🗒️ Taxonomy 2
🤖 LLM-based Video Agents


🎥 Vid-LLM Pretraining
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
Learning Video Representations from Large Language Models | LaViLa | 12/2022 | code | CVPR |
| Vid2Seq: Large-Scale Pretraining of a Visual Language Model for Dense Video Captioning | Vid2Seq | 02/2023 | code | CVPR |
VAST: A Vision-Audio-Subtitle-Text Omni-Modality Foundation Model and Dataset | VAST | 05/2023 | code | NeurIPS |
| Merlin:Empowering Multimodal LLMs with Foresight Minds | Merlin | 12/2023 | - | arXiv |
👀 Vid-LLM Instruction Tuning
Fine-tuning with Connective Adapters


Fine-tuning with Insertive Adapters
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
Otter: A Multi-Modal Model with In-Context Instruction Tuning | Otter | 06/2023 | code | arXiv |
VideoLLM: Modeling Video Sequence with Large Language Models | VideoLLM | 05/2023 | code | arXiv |
Fine-tuning with Hybrid Adapters
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
VTimeLLM: Empower LLM to Grasp Video Moments | VTimeLLM | 11/2023 | code | arXiv |
| GPT4Video: A Unified Multimodal Large Language Model for lnstruction-Followed Understanding and Safety-Aware Generation | GPT4Video | 11/2023 | - | arXiv |
🦾 Hybrid Methods
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
VideoChat: Chat-Centric Video Understanding | VideoChat | 05/2023 | code demo | arXiv |
| PG-Video-LLaVA: Pixel Grounding Large Video-Language Models | PG-Video-LLaVA | 11/2023 | code | arXiv |
TimeChat: A Time-sensitive Multimodal Large Language Model for Long Video Understanding | TimeChat | 12/2023 | code | CVPR |
Video-GroundingDINO: Towards Open-Vocabulary Spatio-Temporal Video Grounding | Video-GroundingDINO | 12/2023 | code | arXiv |
| A Video Is Worth 4096 Tokens: Verbalize Videos To Understand Them In Zero Shot | Video4096 | 05/2023 | EMNLP |
💎 Training-free Methods
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
| Beyond Training: Dynamic Token Merging for Zero-Shot Video Understanding | DyTo | 11/2024 | code | ICCV2025 |
| SlowFast-LLaVA: A Strong Training-Free Baseline for Video Large Language Models | SlowFast-LLaVA | 07/2024 | - | arXiv |
| TS-LLaVA: Constructing Visual Tokens through Thumbnail-and-Sampling for Training-Free Video Large Language Models | TS-LLaVA | 11/2024 | code | arXiv |
| Can Sound Replace Vision in LLaVA With Token Substitution? | SoundCLIP | 08/2025 | code | arXiv |
D-CoDe: Scaling Image-Pretrained VLMs to Video via Dynamic Compression and Question Decomposition  | D-CoDe | 08/2025 | code project page | EMNLP |
Tasks, Datasets, and Benchmarks
Recognition and Anticipation
| Name | Paper | Date | Link | Venue |
|---|---|---|---|---|
| Charades | Hollywood in homes: Crowdsourcing data collection for activity understanding | 2016 | Link | ECCV |
| YouTube8M | YouTube-8M: A Large-Scale Video Classification Benchmark | 2016 | Link | - |
| ActivityNet | ActivityNet: A Large-Scale Video Benchmark for Human Activity Understanding | 2015 | Link | CVPR |
| Kinetics-GEBC | GEB+: A Benchmark for Generic Event Boundary Captioning, Grounding and Retrieval | 2022 | Link | ECCV |
| Kinetics-400 | The Kinetics Human Action Video Dataset | 2017 | Link | - |
| VidChapters-7M | VidChapters-7M: Video Chapters at Scale | 2023 | Link | NeurIPS |
| BlackSwanSuite | Black Swan: Abductive and Defeasible Video Reasoning in Unpredictable Events  | 2025 | Link | CVPR |
Captioning and Description
Grounding and Retrieval
| Name | Paper | Date | Link | Venue |
|---|---|---|---|---|
| Epic-Kitchens-100 | Rescaling Egocentric Vision | 2021 | Link | IJCV |
| VCR (Visual Commonsense Reasoning) | From Recognition to Cognition: Visual Commonsense Reasoning | 2019 | Link | CVPR |
| Ego4D-MQ and Ego4D-NLQ | Ego4D: Around the World in 3,000 Hours of Egocentric Video | 2021 | Link | CVPR |
| Vid-STG | Where Does It Exist: Spatio-Temporal Video Grounding for Multi-Form Sentences | 2020 | Link | CVPR |
| Charades-STA | TALL: Temporal Activity Localization via Language Query | 2017 | Link | ICCV |
| DiDeMo | Localizing Moments in Video with Natural Language | 2017 | Link | ICCV |
Question Answering
Video Instruction Tuning
Pretraining Dataset
| Name | Paper | Date | Link | Venue |
|---|---|---|---|---|
| VidChapters-7M | VidChapters-7M: Video Chapters at Scale | 2023 | Link | NeurIPS |
| VALOR-1M | VALOR: Vision-Audio-Language Omni-Perception Pretraining Model and Dataset | 2023 | Link | arXiv |
| Youku-mPLUG | Youku-mPLUG: A 10 Million Large-scale Chinese Video-Language Dataset for Pre-training and Benchmarks | 2023 | Link | arXiv |
| InternVid | InternVid: A Large-scale Video-Text Dataset for Multimodal Understanding and Generation | 2023 | Link | arXiv |
| VAST-27M | VAST: A Vision-Audio-Subtitle-Text Omni-Modality Foundation Model and Dataset | 2023 | Link | NeurIPS |
Fine-tuning Dataset
| Name | Paper | Date | Link | Venue |
|---|---|---|---|---|
| MIMIC-IT | MIMIC-IT: Multi-Modal In-Context Instruction Tuning | 2023 | Link | arXiv |
| VideoInstruct100K | Video-ChatGPT: Towards Detailed Video Understanding via Large Vision and Language Models | 2023 | Link | arXiv |
| TimeIT | TimeChat: A Time-sensitive Multimodal Large Language Model for Long Video Understanding | 2023 | Link | CVPR |
Video-based Large Language Models Benchmark


Video Dataset Tools
- Thordata Video Dataset Toolkit: Documentation and planned tooling for loading, validating, documenting, and preparing video datasets, including manifest and metadata workflows.
Contributing
We welcome everyone to contribute to this repository and help improve it. You can submit pull requests to add new papers, projects, and helpful materials, or to correct any errors that you may find. Please make sure that your pull requests follow the "Title|Model|Date|Code|Venue" format. Thank you for your valuable contributions!
🌟 Star History
♥️ Contributors
Our project wouldn't be possible without the contributions of these amazing people! Thank you all for making this project better.
Yolo Y. Tang @ University of Rochester
Jing Bi @ University of Rochester
Siting Xu @ Southern University of Science and Technology
Luchuan Song @ University of Rochester
Susan Liang @ University of Rochester
Teng Wang @ The University of Hong Kong
Daoan Zhang @ University of Rochester
Jie An @ University of Rochester
Jingyang Lin @ University of Rochester
Rongyi Zhu @ University of Rochester
Ali Vosoughi @ University of Rochester
Chao Huang @ University of Rochester
Zeliang Zhang @ University of Rochester
Pinxin Liu @ University of Rochester
Mingqian Feng @ University of Rochester
Feng Zheng @ Southern University of Science and Technology
Jianguo Zhang @ Southern University of Science and Technology
Ping Luo @ University of Hong Kong
Jiebo Luo @ University of Rochester
Chenliang Xu @ University of Rochester
Contributors


Similar repos


🔥🔥🔥 [IEEE TCSVT] Latest Papers, Codes and Datasets on Vid-LLMs.
3,289
212 commits
updated Sep 24, 2026
README
Awesome-LLMs-for-Video-Understanding
🔥🔥🔥 Video Understanding with Large Language Models: A Survey
Yolo Y. Tang1, Jing Bi1, Siting Xu2, Luchuan Song1, Susan Liang1 , Teng Wang2,3 , Daoan Zhang1 , Jie An1 , Jingyang Lin1 , Rongyi Zhu1 , Ali Vosoughi1 , Chao Huang1 , Zeliang Zhang1 , Pinxin Liu1 , Mingqian Feng1 , Feng Zheng2 , Jianguo Zhang2 , Ping Luo3 , Jiebo Luo1, Chenliang Xu1.
1University of Rochester, 2Southern University of Science and Technology, 3The University of Hong Kong
Paper | arXiv | Project Page
📢 News
[10/06/2025]
🔥 Our follow-up work—Video-LMM Post-Training: A Deep Dive into Video Reasoning with Large Multimodal Models—is now available on arXiv and Hugging Face Papers!
[05/04/2025]
🌟 Our Vid-LLM survey has been accepted to the IEEE Transactions on Circuits and Systems for Video Technology (TCSVT)! 👉 IEEE Xplore | GitHub
[07/23/2024]
📢 We've recently updated our survey: “Video Understanding with Large Language Models: A Survey”!
✨ This comprehensive survey covers video understanding techniques powered by large language models (Vid-LLMs), training strategies, relevant tasks, datasets, benchmarks, and evaluation methods, and discusses the applications of Vid-LLMs across various domains.
🚀 What's New in This Update:
✅ Updated to include around 100 additional Vid-LLMs and 15 new benchmarks as of June 2024.
✅ Introduced a novel taxonomy for Vid-LLMs based on video representation and LLM functionality.
✅ Added a Preliminary chapter, reclassifying video understanding tasks from the perspectives of granularity and language involvement, and enhanced the LLM Background section.
✅ Added a new Training Strategies chapter, removing adapters as a factor for model classification.
✅ All figures and tables have been redesigned.
Multiple minor updates will follow this major update. And the GitHub repository will be gradually updated soon. We welcome your reading and feedback ❤️
Table of Contents- Awesome-LLMs-for-Video-Understanding
Why we need Vid-LLMs?
😎 Vid-LLMs: Models
📑 Citation
If you find our survey useful for your research, please cite the following paper:
@article{vidllmsurvey,
  author={Tang, Yunlong and Bi, Jing and Xu, Siting and Song, Luchuan and Liang, Susan and Wang, Teng and Zhang, Daoan and An, Jie and Lin, Jingyang and Zhu, Rongyi and Vosoughi, Ali and Huang, Chao and Zhang, Zeliang and Liu, Pinxin and Feng, Mingqian and Zheng, Feng and Zhang, Jianguo and Luo, Ping and Luo, Jiebo and Xu, Chenliang},
  journal={IEEE Transactions on Circuits and Systems for Video Technology},
  title={Video Understanding with Large Language Models: A Survey},
  year={2025},
  doi={10.1109/TCSVT.2025.3566695}
}
🗒️ Taxonomy 1
🕹️ Video Analyzer × LLM
LLM as Summarizer
LLM as Manager
👾 Video Embedder × LLM
LLM as Text Decoder
LLM as Regressor
LLM as Hidden Layer
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
| VTG-LLM integrating timestamp knowledge into video LLMs for enhanced video temporal grounding | VTG-LLM | 05/2024 | code | arXiv |
| VITRON: A Unified Pixel-level Vision LLM for Understanding, Generating, Segmenting, Editing | VITRON | 04/2024 | project page | NeurIPS |
| VTG-GPT: Tuning-Free Zero-Shot Video Temporal Grounding with GPT | VTG-GPT | 03/2024 | code | arXiv |
| Momentor advancing video large language model with fine-grained temporal reasoning | Momentor | 02/2024 | code | ICML |
| Detours for navigating instructional videos | VidDetours | 01/2024 | code | CVPR |
| OneLLM: One Framework to Align All Modalities with Language | OneLLM | 12/2023 | code | arXiv |
| GPT4Video a unified multimodal large language model for lnstruction-followed understanding and safety-aware generation | GPT4Video | 11/2023 | code | ACMMM |
🧭 (Analyzer + Embedder) × LLM
LLM as Manager
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
| MM-VID: Advancing Video Understanding with GPT-4V(ision) | MM-VID | 10/2023 | - | arXiv |
LLM as Summarizer
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
| Shot2Story20K a new benchmark for comprehensive understanding of multi-shot videos | SUM-shot | 12/2023 | code | arXiv |
LLM as Regressor
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
| Vript: A Video Is Worth Thousands of Words | Vriptor | 06/2024 | code | NeurIPS |
| Merlin:Empowering Multimodal LLMs with Foresight Minds | Merlin | 12/2023 | project page | ECCV |
| VideoChat: Chat-Centric Video Understanding | VideoChat | 05/2023 | code | arXiv |
| Vid2Seq: Large-Scale Pretraining of a Visual Language Model for Dense Video Captioning | Vid2Seq | 02/2023 | code | CVPR |
LLM as Text Decoder
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
| Contextual AD Narration with Interleaved Multimodal Sequence | Uni-AD | 03/2024 | code | arXiv |
| MM-Narrator: Narrating Long-form Videos with Multimodal In-Context Learning | MM-narrator | 11/2023 | project page | arXiv |
| Vamos: Versatile Action Models for Video Understanding | Vamos | 11/2023 | project page | ECCV |
| AutoAD II: The Sequel -- Who, When, and What in Movie Audio Description | Auto-AD II | 10/2023 | project page | ICCV |
LLM as Hidden Layer
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
| PG-Video-LLaVA: Pixel Grounding Large Video-Language Models | PG-Video-LLaVA | 11/2023 | code | arXiv |
🗒️ Taxonomy 2
🤖 LLM-based Video Agents
🎥 Vid-LLM Pretraining
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
| Learning Video Representations from Large Language Models | LaViLa | 12/2022 | code | CVPR |
| Vid2Seq: Large-Scale Pretraining of a Visual Language Model for Dense Video Captioning | Vid2Seq | 02/2023 | code | CVPR |
| VAST: A Vision-Audio-Subtitle-Text Omni-Modality Foundation Model and Dataset | VAST | 05/2023 | code | NeurIPS |
| Merlin:Empowering Multimodal LLMs with Foresight Minds | Merlin | 12/2023 | - | arXiv |
👀 Vid-LLM Instruction Tuning
Fine-tuning with Connective Adapters
Fine-tuning with Insertive Adapters
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
| Otter: A Multi-Modal Model with In-Context Instruction Tuning | Otter | 06/2023 | code | arXiv |
| VideoLLM: Modeling Video Sequence with Large Language Models | VideoLLM | 05/2023 | code | arXiv |
Fine-tuning with Hybrid Adapters
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
| VTimeLLM: Empower LLM to Grasp Video Moments | VTimeLLM | 11/2023 | code | arXiv |
| GPT4Video: A Unified Multimodal Large Language Model for lnstruction-Followed Understanding and Safety-Aware Generation | GPT4Video | 11/2023 | - | arXiv |
🦾 Hybrid Methods
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
| VideoChat: Chat-Centric Video Understanding | VideoChat | 05/2023 | code demo | arXiv |
| PG-Video-LLaVA: Pixel Grounding Large Video-Language Models | PG-Video-LLaVA | 11/2023 | code | arXiv |
| TimeChat: A Time-sensitive Multimodal Large Language Model for Long Video Understanding | TimeChat | 12/2023 | code | CVPR |
| Video-GroundingDINO: Towards Open-Vocabulary Spatio-Temporal Video Grounding | Video-GroundingDINO | 12/2023 | code | arXiv |
| A Video Is Worth 4096 Tokens: Verbalize Videos To Understand Them In Zero Shot | Video4096 | 05/2023 | EMNLP |
💎 Training-free Methods
| Title | Model | Date | Code | Venue |
|---|---|---|---|---|
| Beyond Training: Dynamic Token Merging for Zero-Shot Video Understanding | DyTo | 11/2024 | code | ICCV2025 |
| SlowFast-LLaVA: A Strong Training-Free Baseline for Video Large Language Models | SlowFast-LLaVA | 07/2024 | - | arXiv |
| TS-LLaVA: Constructing Visual Tokens through Thumbnail-and-Sampling for Training-Free Video Large Language Models | TS-LLaVA | 11/2024 | code | arXiv |
| Can Sound Replace Vision in LLaVA With Token Substitution? | SoundCLIP | 08/2025 | code | arXiv |
| D-CoDe: Scaling Image-Pretrained VLMs to Video via Dynamic Compression and Question Decomposition | D-CoDe | 08/2025 | code project page | EMNLP |
Tasks, Datasets, and Benchmarks
Recognition and Anticipation
| Name | Paper | Date | Link | Venue |
|---|---|---|---|---|
| Charades | Hollywood in homes: Crowdsourcing data collection for activity understanding | 2016 | Link | ECCV |
| YouTube8M | YouTube-8M: A Large-Scale Video Classification Benchmark | 2016 | Link | - |
| ActivityNet | ActivityNet: A Large-Scale Video Benchmark for Human Activity Understanding | 2015 | Link | CVPR |
| Kinetics-GEBC | GEB+: A Benchmark for Generic Event Boundary Captioning, Grounding and Retrieval | 2022 | Link | ECCV |
| Kinetics-400 | The Kinetics Human Action Video Dataset | 2017 | Link | - |
| VidChapters-7M | VidChapters-7M: Video Chapters at Scale | 2023 | Link | NeurIPS |
| BlackSwanSuite | Black Swan: Abductive and Defeasible Video Reasoning in Unpredictable Events | 2025 | Link | CVPR |
Captioning and Description
Grounding and Retrieval
| Name | Paper | Date | Link | Venue |
|---|---|---|---|---|
| Epic-Kitchens-100 | Rescaling Egocentric Vision | 2021 | Link | IJCV |
| VCR (Visual Commonsense Reasoning) | From Recognition to Cognition: Visual Commonsense Reasoning | 2019 | Link | CVPR |
| Ego4D-MQ and Ego4D-NLQ | Ego4D: Around the World in 3,000 Hours of Egocentric Video | 2021 | Link | CVPR |
| Vid-STG | Where Does It Exist: Spatio-Temporal Video Grounding for Multi-Form Sentences | 2020 | Link | CVPR |
| Charades-STA | TALL: Temporal Activity Localization via Language Query | 2017 | Link | ICCV |
| DiDeMo | Localizing Moments in Video with Natural Language | 2017 | Link | ICCV |
Question Answering
Video Instruction Tuning
Pretraining Dataset
| Name | Paper | Date | Link | Venue |
|---|---|---|---|---|
| VidChapters-7M | VidChapters-7M: Video Chapters at Scale | 2023 | Link | NeurIPS |
| VALOR-1M | VALOR: Vision-Audio-Language Omni-Perception Pretraining Model and Dataset | 2023 | Link | arXiv |
| Youku-mPLUG | Youku-mPLUG: A 10 Million Large-scale Chinese Video-Language Dataset for Pre-training and Benchmarks | 2023 | Link | arXiv |
| InternVid | InternVid: A Large-scale Video-Text Dataset for Multimodal Understanding and Generation | 2023 | Link | arXiv |
| VAST-27M | VAST: A Vision-Audio-Subtitle-Text Omni-Modality Foundation Model and Dataset | 2023 | Link | NeurIPS |
Fine-tuning Dataset
| Name | Paper | Date | Link | Venue |
|---|---|---|---|---|
| MIMIC-IT | MIMIC-IT: Multi-Modal In-Context Instruction Tuning | 2023 | Link | arXiv |
| VideoInstruct100K | Video-ChatGPT: Towards Detailed Video Understanding via Large Vision and Language Models | 2023 | Link | arXiv |
| TimeIT | TimeChat: A Time-sensitive Multimodal Large Language Model for Long Video Understanding | 2023 | Link | CVPR |
Video-based Large Language Models Benchmark
Video Dataset Tools
- Thordata Video Dataset Toolkit: Documentation and planned tooling for loading, validating, documenting, and preparing video datasets, including manifest and metadata workflows.
Contributing
We welcome everyone to contribute to this repository and help improve it. You can submit pull requests to add new papers, projects, and helpful materials, or to correct any errors that you may find. Please make sure that your pull requests follow the "Title|Model|Date|Code|Venue" format. Thank you for your valuable contributions!
🌟 Star History
♥️ Contributors
Our project wouldn't be possible without the contributions of these amazing people! Thank you all for making this project better.
Yolo Y. Tang @ University of Rochester
Jing Bi @ University of Rochester
Siting Xu @ Southern University of Science and Technology
Luchuan Song @ University of Rochester
Susan Liang @ University of Rochester
Teng Wang @ The University of Hong Kong
Daoan Zhang @ University of Rochester
Jie An @ University of Rochester
Jingyang Lin @ University of Rochester
Rongyi Zhu @ University of Rochester
Ali Vosoughi @ University of Rochester
Chao Huang @ University of Rochester
Zeliang Zhang @ University of Rochester
Pinxin Liu @ University of Rochester
Mingqian Feng @ University of Rochester
Feng Zheng @ Southern University of Science and Technology
Jianguo Zhang @ Southern University of Science and Technology
Ping Luo @ University of Hong Kong
Jiebo Luo @ University of Rochester
Chenliang Xu @ University of Rochester