iLearn-Lab/Awesome-VLM-based-VLA-for-Robotic-Manipulation

A curated list of large VLM-based VLA models for robotic manipulation.

452

54 commits

updated Aug 27, 2026

See the code

README

Awesome VLM-based VLA for Robotic Manipulation

arXiv Lab Contribution Welcome GitHub star chart License

πŸ› οΈ We're still cooking β€” Stay tuned!πŸ› οΈ
⭐ Give us a star if you like it! ⭐
✨If you find this work useful for your research, please kindly cite our paper.✨
πŸ“’ Update: Under Minor Revision at IEEE TPAMI.

image info

πŸ”₯ Large VLM-based Vision-Language-Action (VLA) models have recently emerged as a transformative paradigm for robotic manipulation by tightly coupling perception, language understanding, and action generation. Built upon large Vision-Language Models (VLMs), they enable robots to interpret natural language instructions, perceive complex environments, and perform diverse manipulation tasks with strong generalization.

πŸ“ We present the first systematic survey on large VLM-based VLA models for robotic manipulation. This repository serves as the companion resource to our survey: "Large VLM-based Vision-Language-Action Models for Robotic Manipulation: A Survey", and includes all the research papers, benchmarks, and resources reviewed in the paper, organized for easy access and reference.

πŸ“Œ We will keep updating this repository with newly published works to reflect the latest progress in the field.

Table of Contents

Monolithic Models

Single-System

YearVenuePaperWebsiteCode
2023CoRLRT-2: Vision-Language-Action Models Transfer Web Knowledge to Robotic Control🌐-
2023ICRART-2-X: Open X-Embodiment: Robotic Learning Datasets and RT-X Models🌐-
2023NeurIPSRoboFlamingo: Vision-Language Foundation Models as Effective Robot ImitatorsπŸŒπŸ’»
2023ICMLLEO Agent: An Embodied Generalist Agent in 3D WorldπŸŒπŸ’»
2024NeurIPSRoboMamba: Efficient Vision-Language-Action Model for Robotic Reasoning and ManipulationπŸŒπŸ’»
2024CoRLOpenVLA: An Open-Source Vision-Language-Action ModelπŸŒπŸ’»
2024CoRLECOT-Lite: Robotic Control via Embodied Chain-of-Thought ReasoningπŸŒπŸ’»
2024ICRAReVLA: Reverting Visual Domain Limitation of Robotic Foundation Models🌐-
2024NeurIPSDeeR-VLA: Dynamic Inference of Multimodal Large Language Models for Efficient Robot Execution-πŸ’»
2024ICLRTraceVLA: Visual Trace Prompting Enhances Spatial-Temporal Awareness for Generalist Robotic PoliciesπŸŒπŸ’»
2025ICRAFuSe: Beyond Sight: Finetuning Generalist Robot Policies with Heterogeneous Sensors via Language GroundingπŸŒπŸ’»
2025CVPRUniAct: Universal Actions for Enhanced Embodied Foundation ModelsπŸŒπŸ’»
2025arXivSpatialVLA: Exploring Spatial Representations for Visual-Language-Action ModelπŸŒπŸ’»
2025ICMLUP-VLA: A Unified Understanding and Prediction Model for Embodied Agent-πŸ’»
2025ICLRVLAS: Vision-Language-Action Model with Speech Instructions for Customized Robot Manipulation--
2025arXivOpenVLA-OFT: Fine-Tuning Vision-Language-Action Models: Optimizing Speed and SuccessπŸŒπŸ’»
2025arXivPD-VLA: Accelerating Vision-Language-Action Model Integrated with Action Chunking via Parallel Decoding--
2025arXivHybridVLA: Collaborative Diffusion and Autoregression in a Unified Vision-Language-Action ModelπŸŒπŸ’»
2025arXivMoLe-VLA: Dynamic Layer-Skipping Vision-Language-Action Model via Mixture-of-Layers for Efficient Robot ManipulationπŸŒπŸ’»
2025CVPRCoT-VLA: Visual Chain-of-Thought Reasoning for Vision-Language-Action Models🌐-
2025arXivNORA: A Small Open-Sourced Generalist Vision-Language-Action Model for Embodied TasksπŸŒπŸ’»
2025arXivVTLA: Vision-Tactile-Language-Action Model with Preference Learning for Insertion Manipulation🌐-
2025arXivOE-VLA: Unveiling the Potential of Vision-Language-Action Models with Open-Ended Multimodal Instructions--
2025arXivReFineVLA: Reasoning-Aware Teacher-Guided Transfer Fine-Tuning--
2025arXivFLashVLA: Think Twice, Act Once: Token-Aware Compression and Action Reuse for Efficient Inference in Vision-Language-Action Models--
2025arXivLoHoVLA: A Unified Vision-Language-Action Model for Long-Horizon Embodied Tasks--
2025arXivBitVLA: 1-Bit Vision-Language-Action Models for Robotics Manipulation-πŸ’»
2025arXivBridgeVLA: Input-Output Alignment for Efficient 3D Manipulation Learning with Vision-Language ModelsπŸŒπŸ’»
2025arXivUniVLA: Unified Vision-Language-Action ModelπŸŒπŸ’»
2025arXivWorldVLA: Towards Autoregressive Action World Model-πŸ’»
2025arXiv4D-VLA: Spatiotemporal Vision-Language-Action Pretraining with Cross-Scene Calibration-πŸ’»
2025ICCVVQ-VLA: Improving Vision-Language-Action Models via Scaling Vector-Quantized Action TokenizersπŸŒπŸ’»
2025arXivVOTE: Vision-Language-Action Optimization with Trajectory Ensemble Voting--
2025arXivSpecVLA: Speculative Decoding for Vision-Language-Action Models with Relaxed Acceptance--
2025arXivST-VLA: Spatial Traces: Enhancing VLA Models with Spatial-Temporal Understanding🌐-
2025arXivDiscrete Diffusion VLA: Bringing Discrete Diffusion to Action Decoding in Vision-Language-Action Policies--
2025arXivLLaDA-VLA: Vision Language Diffusion Action Models🌐-
2025arXivOccVLA: Vision-Language-Action Model with Implicit 3D Occupancy Supervision--
2025arXivTwinVLA: Data-Efficient Bimanual Manipulation with Twin Single-Arm Vision-Language-Action Models🌐-
2025arXivSTARE-VLA: Progressive Stage-Aware Reinforcement for Fine-Tuning Vision-Language-Action Models🌐-

Dual-System

YearVenuePaperWebsiteCode
2024arXivA dual process vla: efficient robotic manipulation leveraging vlm--
2024arXivTowards synergistic, generalized, and efficient dual-system for robotic manipulation🌐-
2024IROSFrom llms to actions: latent codes as bridges in hierarchical robot control--
2025arXivGr00t n1: an open foundation model for generalist humanoid robots--
2024arXivCogact: a foundational vision-language-action model for synergizing cognition and action in robotic manipulationπŸŒπŸ’»
2024CoRLHirt: enhancing robotic control with hierarchical robot transformers--
2025arXivGraspVLA: a Grasping Foundation Model Pre-trained on Billion-scale Synthetic Action DataπŸŒπŸ’»
2025arXivFast-in-slow: a dual-system foundation model unifying fast manipulation within slow reasoningπŸŒπŸ’»
2025arXivOpenhelix: A short survey, empirical analysis, and open-source dual-system vla model for robotic manipulationπŸŒπŸ’»
2025arXivChatvla: unified multimodal understanding and robot control with vision-language-action modelπŸŒπŸ’»
2025arXivChatvla-2: vision-language-action model with open-world embodied reasoning from pretrained knowledge🌐-
2025ICMLDiffusionvla: scaling robot foundation models via unified diffusion and autoregressionπŸŒπŸ’»
2025arXivTrivla: a unified triple-system-based unified vision-language-action model for general robot control🌐-
2025arXivInformation-theoretic graph fusion with vision-language-action model for policy reasoning and dual robotic control--
2025arXivRationalvla: a rational vision-language-action model with dual system🌐-
2025ICCVVq-vla: improving vision-language-action models via scaling vector-quantized action tokenizersπŸŒπŸ’»
2025RA-LTinyvla: towards fast, data-efficient vision-language-action models for robotic manipulationπŸŒπŸ’»
2025RSSΟ€0: A vision-language-action flow model for general robot control🌐-
2025RSSFast: efficient action tokenization for vision-language-action models🌐-
2025arXivΟ€0.5: a vision language-action model with open-world generalization🌐-
2025arXivKnowledge insulating vision-language-action models: train fast, run fast, generalize better🌐-
2025arXivForcevla: enhancing vla models with a force-aware moe for contact-rich manipulation🌐-
2025arXivSmolvla: a vision-language-action model for affordable and efficient robotics-πŸ’»
2025arXivOnetwovla: a unified vision-language-action model with adaptive reasoningπŸŒπŸ’»
2025arXivTactile-vla: unlocking vision-language-action model’s physical knowledge for tactile generalization--
2025arXivGr-3 technical report🌐-
2025arXivVilla-x: enhancing latent action modeling in vision-language-action modelsπŸŒπŸ’»
2025arXivThinkAct: Vision-Language-Action Reasoning via Reinforced Visual Latent Planning🌐-
2025arXivF1: A Vision-Language-Action Model Bridging Understanding and Generation to ActionsπŸŒπŸ’»
2025arXiviFlyBot-VLA🌐-
2025arXiviFlyBot-VLA Technical Report🌐-
2025arXivEvo-1: Lightweight Vision-Language-Action Model with Preserved Semantic AlignmentπŸŒπŸ’»
2025arXivNORA-1.5: A Vision-Language-Action Model Trained using World Model- and Action-based Preference RewardsπŸŒπŸ’»
2025arXivΟ€*0.6: a VLA that Learns from Experience🌐-
2025arXivManualVLA: A Unified VLA Model for Chain-of-Thought Manual Generation and Robotic Manipulation🌐-
2025arXivMETIS: Multi-Source Egocentric Training for Integrated Dexterous Vision-Language-Action Model🌐-

Hierarchical Models

Planner Only


Planner + Policy

YearVenuePaperWebsiteCode
2023arXivInstruct2Act: Mapping multi-modality instructions to robotic actions with large language model-πŸ’»
2023CoRLVoxPoser: Composable 3D value maps for robotic manipulation with language modelsπŸŒπŸ’»
2024CVPRSkillDiffuser: Interpretable hierarchical planning via skill abstractions in diffusion-based task executionπŸŒπŸ’»
2024arXivRoboMatrix: A skill-centric hierarchical framework for scalable robot task planning and execution in open-world-πŸ’»
2024CoRLRT-Affordance: Reasoning about robotic manipulation with affordances🌐-
2024CoRLLLARVA: Vision-action instruction tuning enhances robot learningπŸŒπŸ’»
2024CVPRMALMM: Multi-agent large language models for zero-shot robotics manipulationπŸŒπŸ’»
2024arXivRT-H: Action Hierarchies Using Language🌐-
2024CoRLReKep: Spatio-temporal reasoning of relational keypoint constraints for robotic manipulationπŸŒπŸ’»
2025ICLRHAMSTER: Hierarchical action models for open-world robot manipulationπŸŒπŸ’»
2025ICMLHiRobot: Open-ended instruction following with hierarchical vision-language-action models🌐-
2025arXivAgentic Robot: A brain-inspired framework for vision-language-action models in embodied agentsπŸŒπŸ’»
2025arXivDexVLA: Vision-language model with plug-in diffusion expert for general robot controlπŸŒπŸ’»
2025arXivPointVLA: Injecting the 3D world into vision-language-action models🌐-
2025arXivA0: An affordance-aware hierarchical model for general robotic manipulationπŸŒπŸ’»
2025arXivFrom seeing to doing: Bridging reasoning and decision for robotic manipulationπŸŒπŸ’»
2025ICCVRoBridge: A hierarchical architecture bridging cognition and execution for general robotic manipulationπŸŒπŸ’»
2025arXivRoboCerebra: A large-scale benchmark for long-horizon robotic manipulation evaluation🌐-
2025arXivΟ€0.5: A vision-language-action model with open-world generalization🌐-
2025arXivDexGraspVLA: A vision-language-action framework towards general dexterous graspingπŸŒπŸ’»
2025arXivHiBerNAC: Hierarchical brain-emulated robotic neural agent collective for disentangling complex manipulation--
2025arXivRobix: A Unified Model for Robot Interaction, Reasoning and Planning🌐-

Other Advanced Field

Reinforcement Learning-based Methods


Training-Free Methods


Learning from Human Videos


World Model-based VLA

Datasets and Benchmarks

Real-world Robot Datasets


Simulation Environments and Benchmarks

YearVenuePaperWebsiteCodeData
2022CoRLBEHAVIOR‑1K: A Human‑Centered, Embodied AI Benchmark with 1,000 Everyday Activities and Realistic SimulationπŸŒπŸ’»πŸ“¦
2020CVPRALFRED: A Benchmark for Interpreting Grounded Instructions for Everyday TasksπŸŒπŸ’»πŸ“¦
2020RA-LRLBench: The Robot Learning Benchmark & Learning EnvironmentπŸŒπŸ’»πŸ“¦
2024arXivPerActΒ²: Benchmarking and Learning for Robotic Bimanual Manipulation TasksπŸŒπŸ’»πŸ“¦
2020CoRLMeta‑World: A Benchmark and Evaluation for Multi‑Task and Meta Reinforcement LearningπŸŒπŸ’»πŸ“¦
2019CoRLRelay Policy Learning: Solving Long-Horizon Tasks via Imitation and Reinforcement LearningπŸŒπŸ’»πŸ“¦
2023NeurIPSLIBERO: Benchmarking Knowledge Transfer for Lifelong Robot LearningπŸŒπŸ’»πŸ“¦
2022RA-LCALVIN: A Benchmark for Language‑Conditioned Policy Learning for Long‑Horizon Robot Manipulation TasksπŸŒπŸ’»πŸ“¦
2024arXivMIKASA: Memory, Benchmark & Robots: A Benchmark for Solving Complex Tasks with Reinforcement LearningπŸŒπŸ’»πŸ“¦
2024CoRLSIMPLER: Evaluating Real‑World Robot Manipulation Policies in SimulationπŸŒπŸ’»πŸ“¦
2019ICCVHabitat: A Platform for Embodied AI ResearchπŸŒπŸ’»πŸ“¦
2021NeurIPSHabitatβ€―2.0: Training Home Assistants to Rearrange their HabitatπŸŒπŸ’»πŸ“¦
2024ICLRHabitatβ€―3.0: A Co‑Habitat for Humans, Avatars and RobotsπŸŒπŸ’»πŸ“¦
2020CVPRSAPIEN: A Simulated Part-based Interactive EnvironmentπŸŒπŸ’»πŸ“¦
2024RSSTheβ€―Colosseum: A Benchmark for Evaluating Generalization for Robotic ManipulationπŸŒπŸ’»πŸ“¦
2025ICCVVLABench: A Large‑Scale Benchmark for Language‑Conditioned Robotics Manipulation with Long‑Horizon Reasoning TasksπŸŒπŸ’»πŸ“¦

Human Behavior Datasets


Embodied Datasets and Benchmarks

Star History Chart

Citation

If you find this survey helpful for your research or applications, please consider citing it using the following BibTeX entry:

@misc{shao2025largevlmbasedvisionlanguageactionmodels,
      title={Large VLM-based Vision-Language-Action Models for Robotic Manipulation: A Survey}, 
      author={Rui Shao and Wei Li and Lingsen Zhang and Renshan Zhang and Zhiyang Liu and Ran Chen and Liqiang Nie},
      year={2025},
      eprint={2508.13073},
      archivePrefix={arXiv},
      primaryClass={cs.RO},
      url={https://arxiv.org/abs/2508.13073}, 
}

Contact Us

For any questions or suggestions, please feel free to contact us at:

Email: shaorui@hit.edu.cn and liwei2024@stu.hit.edu.cn

Contributors

zls030726

18 commits

CRRaphael

10 commits

yyyyyyang813

8 commits

liwei-2013

6 commits

iLearn-Lab/Awesome-VLM-based-VLA-for-Robotic-Manipulation

A curated list of large VLM-based VLA models for robotic manipulation.

452

54 commits

updated Aug 27, 2026

See the code

README

Awesome VLM-based VLA for Robotic Manipulation

arXiv Lab Contribution Welcome GitHub star chart License

πŸ› οΈ We're still cooking β€” Stay tuned!πŸ› οΈ
⭐ Give us a star if you like it! ⭐
✨If you find this work useful for your research, please kindly cite our paper.✨
πŸ“’ Update: Under Minor Revision at IEEE TPAMI.
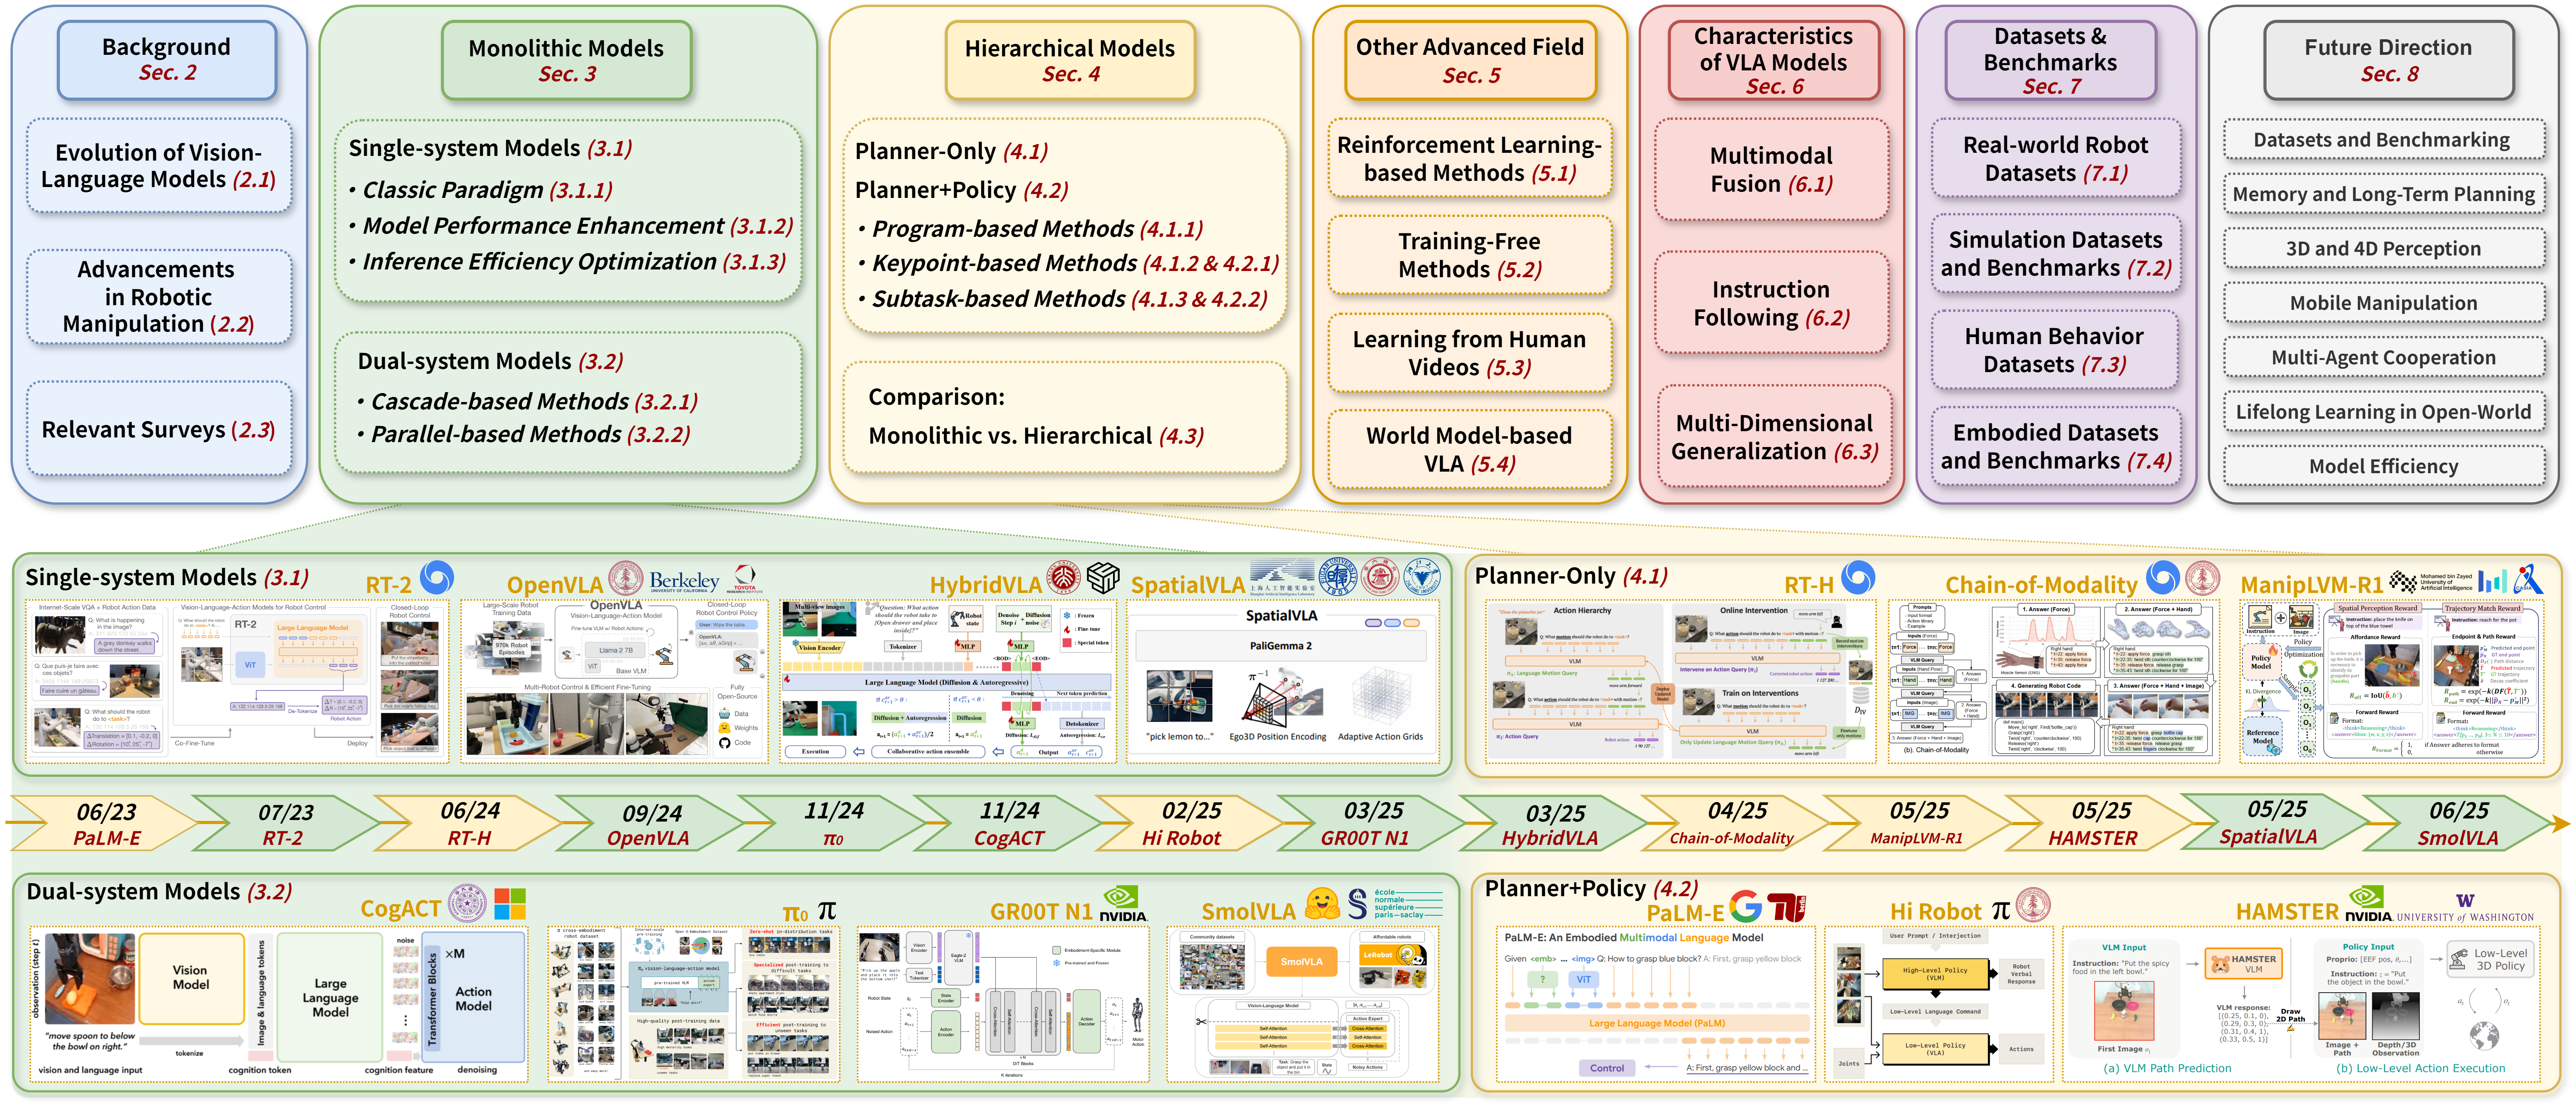
image info

πŸ”₯ Large VLM-based Vision-Language-Action (VLA) models have recently emerged as a transformative paradigm for robotic manipulation by tightly coupling perception, language understanding, and action generation. Built upon large Vision-Language Models (VLMs), they enable robots to interpret natural language instructions, perceive complex environments, and perform diverse manipulation tasks with strong generalization.

πŸ“ We present the first systematic survey on large VLM-based VLA models for robotic manipulation. This repository serves as the companion resource to our survey: "Large VLM-based Vision-Language-Action Models for Robotic Manipulation: A Survey", and includes all the research papers, benchmarks, and resources reviewed in the paper, organized for easy access and reference.

πŸ“Œ We will keep updating this repository with newly published works to reflect the latest progress in the field.

Table of Contents

Monolithic Models

Single-System

YearVenuePaperWebsiteCode
2023CoRLRT-2: Vision-Language-Action Models Transfer Web Knowledge to Robotic Control🌐-
2023ICRART-2-X: Open X-Embodiment: Robotic Learning Datasets and RT-X Models🌐-
2023NeurIPSRoboFlamingo: Vision-Language Foundation Models as Effective Robot ImitatorsπŸŒπŸ’»
2023ICMLLEO Agent: An Embodied Generalist Agent in 3D WorldπŸŒπŸ’»
2024NeurIPSRoboMamba: Efficient Vision-Language-Action Model for Robotic Reasoning and ManipulationπŸŒπŸ’»
2024CoRLOpenVLA: An Open-Source Vision-Language-Action ModelπŸŒπŸ’»
2024CoRLECOT-Lite: Robotic Control via Embodied Chain-of-Thought ReasoningπŸŒπŸ’»
2024ICRAReVLA: Reverting Visual Domain Limitation of Robotic Foundation Models🌐-
2024NeurIPSDeeR-VLA: Dynamic Inference of Multimodal Large Language Models for Efficient Robot Execution-πŸ’»
2024ICLRTraceVLA: Visual Trace Prompting Enhances Spatial-Temporal Awareness for Generalist Robotic PoliciesπŸŒπŸ’»
2025ICRAFuSe: Beyond Sight: Finetuning Generalist Robot Policies with Heterogeneous Sensors via Language GroundingπŸŒπŸ’»
2025CVPRUniAct: Universal Actions for Enhanced Embodied Foundation ModelsπŸŒπŸ’»
2025arXivSpatialVLA: Exploring Spatial Representations for Visual-Language-Action ModelπŸŒπŸ’»
2025ICMLUP-VLA: A Unified Understanding and Prediction Model for Embodied Agent-πŸ’»
2025ICLRVLAS: Vision-Language-Action Model with Speech Instructions for Customized Robot Manipulation--
2025arXivOpenVLA-OFT: Fine-Tuning Vision-Language-Action Models: Optimizing Speed and SuccessπŸŒπŸ’»
2025arXivPD-VLA: Accelerating Vision-Language-Action Model Integrated with Action Chunking via Parallel Decoding--
2025arXivHybridVLA: Collaborative Diffusion and Autoregression in a Unified Vision-Language-Action ModelπŸŒπŸ’»
2025arXivMoLe-VLA: Dynamic Layer-Skipping Vision-Language-Action Model via Mixture-of-Layers for Efficient Robot ManipulationπŸŒπŸ’»
2025CVPRCoT-VLA: Visual Chain-of-Thought Reasoning for Vision-Language-Action Models🌐-
2025arXivNORA: A Small Open-Sourced Generalist Vision-Language-Action Model for Embodied TasksπŸŒπŸ’»
2025arXivVTLA: Vision-Tactile-Language-Action Model with Preference Learning for Insertion Manipulation🌐-
2025arXivOE-VLA: Unveiling the Potential of Vision-Language-Action Models with Open-Ended Multimodal Instructions--
2025arXivReFineVLA: Reasoning-Aware Teacher-Guided Transfer Fine-Tuning--
2025arXivFLashVLA: Think Twice, Act Once: Token-Aware Compression and Action Reuse for Efficient Inference in Vision-Language-Action Models--
2025arXivLoHoVLA: A Unified Vision-Language-Action Model for Long-Horizon Embodied Tasks--
2025arXivBitVLA: 1-Bit Vision-Language-Action Models for Robotics Manipulation-πŸ’»
2025arXivBridgeVLA: Input-Output Alignment for Efficient 3D Manipulation Learning with Vision-Language ModelsπŸŒπŸ’»
2025arXivUniVLA: Unified Vision-Language-Action ModelπŸŒπŸ’»
2025arXivWorldVLA: Towards Autoregressive Action World Model-πŸ’»
2025arXiv4D-VLA: Spatiotemporal Vision-Language-Action Pretraining with Cross-Scene Calibration-πŸ’»
2025ICCVVQ-VLA: Improving Vision-Language-Action Models via Scaling Vector-Quantized Action TokenizersπŸŒπŸ’»
2025arXivVOTE: Vision-Language-Action Optimization with Trajectory Ensemble Voting--
2025arXivSpecVLA: Speculative Decoding for Vision-Language-Action Models with Relaxed Acceptance--
2025arXivST-VLA: Spatial Traces: Enhancing VLA Models with Spatial-Temporal Understanding🌐-
2025arXivDiscrete Diffusion VLA: Bringing Discrete Diffusion to Action Decoding in Vision-Language-Action Policies--
2025arXivLLaDA-VLA: Vision Language Diffusion Action Models🌐-
2025arXivOccVLA: Vision-Language-Action Model with Implicit 3D Occupancy Supervision--
2025arXivTwinVLA: Data-Efficient Bimanual Manipulation with Twin Single-Arm Vision-Language-Action Models🌐-
2025arXivSTARE-VLA: Progressive Stage-Aware Reinforcement for Fine-Tuning Vision-Language-Action Models🌐-

Dual-System

YearVenuePaperWebsiteCode
2024arXivA dual process vla: efficient robotic manipulation leveraging vlm--
2024arXivTowards synergistic, generalized, and efficient dual-system for robotic manipulation🌐-
2024IROSFrom llms to actions: latent codes as bridges in hierarchical robot control--
2025arXivGr00t n1: an open foundation model for generalist humanoid robots--
2024arXivCogact: a foundational vision-language-action model for synergizing cognition and action in robotic manipulationπŸŒπŸ’»
2024CoRLHirt: enhancing robotic control with hierarchical robot transformers--
2025arXivGraspVLA: a Grasping Foundation Model Pre-trained on Billion-scale Synthetic Action DataπŸŒπŸ’»
2025arXivFast-in-slow: a dual-system foundation model unifying fast manipulation within slow reasoningπŸŒπŸ’»
2025arXivOpenhelix: A short survey, empirical analysis, and open-source dual-system vla model for robotic manipulationπŸŒπŸ’»
2025arXivChatvla: unified multimodal understanding and robot control with vision-language-action modelπŸŒπŸ’»
2025arXivChatvla-2: vision-language-action model with open-world embodied reasoning from pretrained knowledge🌐-
2025ICMLDiffusionvla: scaling robot foundation models via unified diffusion and autoregressionπŸŒπŸ’»
2025arXivTrivla: a unified triple-system-based unified vision-language-action model for general robot control🌐-
2025arXivInformation-theoretic graph fusion with vision-language-action model for policy reasoning and dual robotic control--
2025arXivRationalvla: a rational vision-language-action model with dual system🌐-
2025ICCVVq-vla: improving vision-language-action models via scaling vector-quantized action tokenizersπŸŒπŸ’»
2025RA-LTinyvla: towards fast, data-efficient vision-language-action models for robotic manipulationπŸŒπŸ’»
2025RSSΟ€0: A vision-language-action flow model for general robot control🌐-
2025RSSFast: efficient action tokenization for vision-language-action models🌐-
2025arXivΟ€0.5: a vision language-action model with open-world generalization🌐-
2025arXivKnowledge insulating vision-language-action models: train fast, run fast, generalize better🌐-
2025arXivForcevla: enhancing vla models with a force-aware moe for contact-rich manipulation🌐-
2025arXivSmolvla: a vision-language-action model for affordable and efficient robotics-πŸ’»
2025arXivOnetwovla: a unified vision-language-action model with adaptive reasoningπŸŒπŸ’»
2025arXivTactile-vla: unlocking vision-language-action model’s physical knowledge for tactile generalization--
2025arXivGr-3 technical report🌐-
2025arXivVilla-x: enhancing latent action modeling in vision-language-action modelsπŸŒπŸ’»
2025arXivThinkAct: Vision-Language-Action Reasoning via Reinforced Visual Latent Planning🌐-
2025arXivF1: A Vision-Language-Action Model Bridging Understanding and Generation to ActionsπŸŒπŸ’»
2025arXiviFlyBot-VLA🌐-
2025arXiviFlyBot-VLA Technical Report🌐-
2025arXivEvo-1: Lightweight Vision-Language-Action Model with Preserved Semantic AlignmentπŸŒπŸ’»
2025arXivNORA-1.5: A Vision-Language-Action Model Trained using World Model- and Action-based Preference RewardsπŸŒπŸ’»
2025arXivΟ€*0.6: a VLA that Learns from Experience🌐-
2025arXivManualVLA: A Unified VLA Model for Chain-of-Thought Manual Generation and Robotic Manipulation🌐-
2025arXivMETIS: Multi-Source Egocentric Training for Integrated Dexterous Vision-Language-Action Model🌐-

Hierarchical Models

Planner Only


Planner + Policy

YearVenuePaperWebsiteCode
2023arXivInstruct2Act: Mapping multi-modality instructions to robotic actions with large language model-πŸ’»
2023CoRLVoxPoser: Composable 3D value maps for robotic manipulation with language modelsπŸŒπŸ’»
2024CVPRSkillDiffuser: Interpretable hierarchical planning via skill abstractions in diffusion-based task executionπŸŒπŸ’»
2024arXivRoboMatrix: A skill-centric hierarchical framework for scalable robot task planning and execution in open-world-πŸ’»
2024CoRLRT-Affordance: Reasoning about robotic manipulation with affordances🌐-
2024CoRLLLARVA: Vision-action instruction tuning enhances robot learningπŸŒπŸ’»
2024CVPRMALMM: Multi-agent large language models for zero-shot robotics manipulationπŸŒπŸ’»
2024arXivRT-H: Action Hierarchies Using Language🌐-
2024CoRLReKep: Spatio-temporal reasoning of relational keypoint constraints for robotic manipulationπŸŒπŸ’»
2025ICLRHAMSTER: Hierarchical action models for open-world robot manipulationπŸŒπŸ’»
2025ICMLHiRobot: Open-ended instruction following with hierarchical vision-language-action models🌐-
2025arXivAgentic Robot: A brain-inspired framework for vision-language-action models in embodied agentsπŸŒπŸ’»
2025arXivDexVLA: Vision-language model with plug-in diffusion expert for general robot controlπŸŒπŸ’»
2025arXivPointVLA: Injecting the 3D world into vision-language-action models🌐-
2025arXivA0: An affordance-aware hierarchical model for general robotic manipulationπŸŒπŸ’»
2025arXivFrom seeing to doing: Bridging reasoning and decision for robotic manipulationπŸŒπŸ’»
2025ICCVRoBridge: A hierarchical architecture bridging cognition and execution for general robotic manipulationπŸŒπŸ’»
2025arXivRoboCerebra: A large-scale benchmark for long-horizon robotic manipulation evaluation🌐-
2025arXivΟ€0.5: A vision-language-action model with open-world generalization🌐-
2025arXivDexGraspVLA: A vision-language-action framework towards general dexterous graspingπŸŒπŸ’»
2025arXivHiBerNAC: Hierarchical brain-emulated robotic neural agent collective for disentangling complex manipulation--
2025arXivRobix: A Unified Model for Robot Interaction, Reasoning and Planning🌐-

Other Advanced Field

Reinforcement Learning-based Methods


Training-Free Methods


Learning from Human Videos


World Model-based VLA

Datasets and Benchmarks

Real-world Robot Datasets


Simulation Environments and Benchmarks

YearVenuePaperWebsiteCodeData
2022CoRLBEHAVIOR‑1K: A Human‑Centered, Embodied AI Benchmark with 1,000 Everyday Activities and Realistic SimulationπŸŒπŸ’»πŸ“¦
2020CVPRALFRED: A Benchmark for Interpreting Grounded Instructions for Everyday TasksπŸŒπŸ’»πŸ“¦
2020RA-LRLBench: The Robot Learning Benchmark & Learning EnvironmentπŸŒπŸ’»πŸ“¦
2024arXivPerActΒ²: Benchmarking and Learning for Robotic Bimanual Manipulation TasksπŸŒπŸ’»πŸ“¦
2020CoRLMeta‑World: A Benchmark and Evaluation for Multi‑Task and Meta Reinforcement LearningπŸŒπŸ’»πŸ“¦
2019CoRLRelay Policy Learning: Solving Long-Horizon Tasks via Imitation and Reinforcement LearningπŸŒπŸ’»πŸ“¦
2023NeurIPSLIBERO: Benchmarking Knowledge Transfer for Lifelong Robot LearningπŸŒπŸ’»πŸ“¦
2022RA-LCALVIN: A Benchmark for Language‑Conditioned Policy Learning for Long‑Horizon Robot Manipulation TasksπŸŒπŸ’»πŸ“¦
2024arXivMIKASA: Memory, Benchmark & Robots: A Benchmark for Solving Complex Tasks with Reinforcement LearningπŸŒπŸ’»πŸ“¦
2024CoRLSIMPLER: Evaluating Real‑World Robot Manipulation Policies in SimulationπŸŒπŸ’»πŸ“¦
2019ICCVHabitat: A Platform for Embodied AI ResearchπŸŒπŸ’»πŸ“¦
2021NeurIPSHabitatβ€―2.0: Training Home Assistants to Rearrange their HabitatπŸŒπŸ’»πŸ“¦
2024ICLRHabitatβ€―3.0: A Co‑Habitat for Humans, Avatars and RobotsπŸŒπŸ’»πŸ“¦
2020CVPRSAPIEN: A Simulated Part-based Interactive EnvironmentπŸŒπŸ’»πŸ“¦
2024RSSTheβ€―Colosseum: A Benchmark for Evaluating Generalization for Robotic ManipulationπŸŒπŸ’»πŸ“¦
2025ICCVVLABench: A Large‑Scale Benchmark for Language‑Conditioned Robotics Manipulation with Long‑Horizon Reasoning TasksπŸŒπŸ’»πŸ“¦

Human Behavior Datasets


Embodied Datasets and Benchmarks

Star History Chart

Citation

If you find this survey helpful for your research or applications, please consider citing it using the following BibTeX entry:

@misc{shao2025largevlmbasedvisionlanguageactionmodels,
      title={Large VLM-based Vision-Language-Action Models for Robotic Manipulation: A Survey}, 
      author={Rui Shao and Wei Li and Lingsen Zhang and Renshan Zhang and Zhiyang Liu and Ran Chen and Liqiang Nie},
      year={2025},
      eprint={2508.13073},
      archivePrefix={arXiv},
      primaryClass={cs.RO},
      url={https://arxiv.org/abs/2508.13073}, 
}

Contact Us

For any questions or suggestions, please feel free to contact us at:

Email: shaorui@hit.edu.cn and liwei2024@stu.hit.edu.cn

Contributors

zls030726

18 commits

CRRaphael

10 commits

yyyyyyang813

8 commits

liwei-2013

6 commits