
README
From Visual Synthesis to Interactive Worlds:
Toward Production-Ready 3D Asset Generation


Jiafeng Wu1,2*† ·
Zhuofan Lou1,3*† ·
Jian Liu1‡
Chunchao Guo4 ·
Dazhao Du1 ·
Song Guo1§
1 The Hong Kong University of Science and Technology
2 Huazhong University of Science and Technology ·
3 Sichuan University ·
4 Tencent
* Equal contribution · † Work done during internship at HKUST · ‡ Project lead · § Corresponding author
✦ Production-Oriented 3D Generation Survey ✦
🧭 Taxonomy · 🗂 Data · 📦 Objects · 🧍 Characters · 🌍 Scenes · 📏 Evaluation · 🏭 Industry
News
- 🔥 [2026-04] v2.0: Introduces a production-ready two-dimensional taxonomy spanning asset tiers and pipeline stages, and expands the collection to data foundations, geometry, topology, appearance, rigging, scene assembly, evaluation, and industry systems.
- 📚 [2025-08] v1.0: Established the initial curated 3D AIGC paper collection, organized object, scene, and avatar methods under 3D-native, 2D-prior, and hybrid paradigms, and tracked surveys, datasets, talks, companies, and implementations.
Abstract
Three-dimensional content generation has progressed from producing isolated, visually plausible shapes to constructing structured assets that can be deployed in real-time interactive environments. This trajectory is driven by converging demands from game development, embodied AI, world simulation, digital twins, and spatial computing, all of which require 3D content that goes beyond surface appearance to satisfy engine-level constraints on topology, UV parameterization, physically based materials, skeletal rigging, and physics-aware scene layout. Despite rapid advances in generative modeling, a persistent gap separates the outputs of current methods from the production-ready standard expected by interactive applications. This survey addresses that gap by organizing the literature around the asset production pipeline rather than algorithmic families.
At a Glance
- 🧭 Organized by a production-ready, pipeline-first taxonomy rather than isolated algorithm families.
- 📦 Covers three asset tiers: general objects, characters and avatars, and scenes and environments.
- 🛠 Tracks the full asset workflow from data foundations through geometry, topology, appearance, rigging, and scene assembly.
- 📚 Consolidates methods, datasets, evaluation criteria, and industry references in one companion list.
Table of Contents
- 🧭 Survey Taxonomy
- 🗂 Data Foundations & Benchmarks
- 📦 General Objects & Props
- 🧍 Characters & Avatars
- 🌍 Scenes & Environments
- 📏 Evaluation & Benchmarks
- 🏭 Industry & Companies
- 📝 Citation
- 🤝 Contributing
- 🙏 Acknowledgments
- 🗃 v1 Paper Collection
- ⭐ Star History
Survey Taxonomy
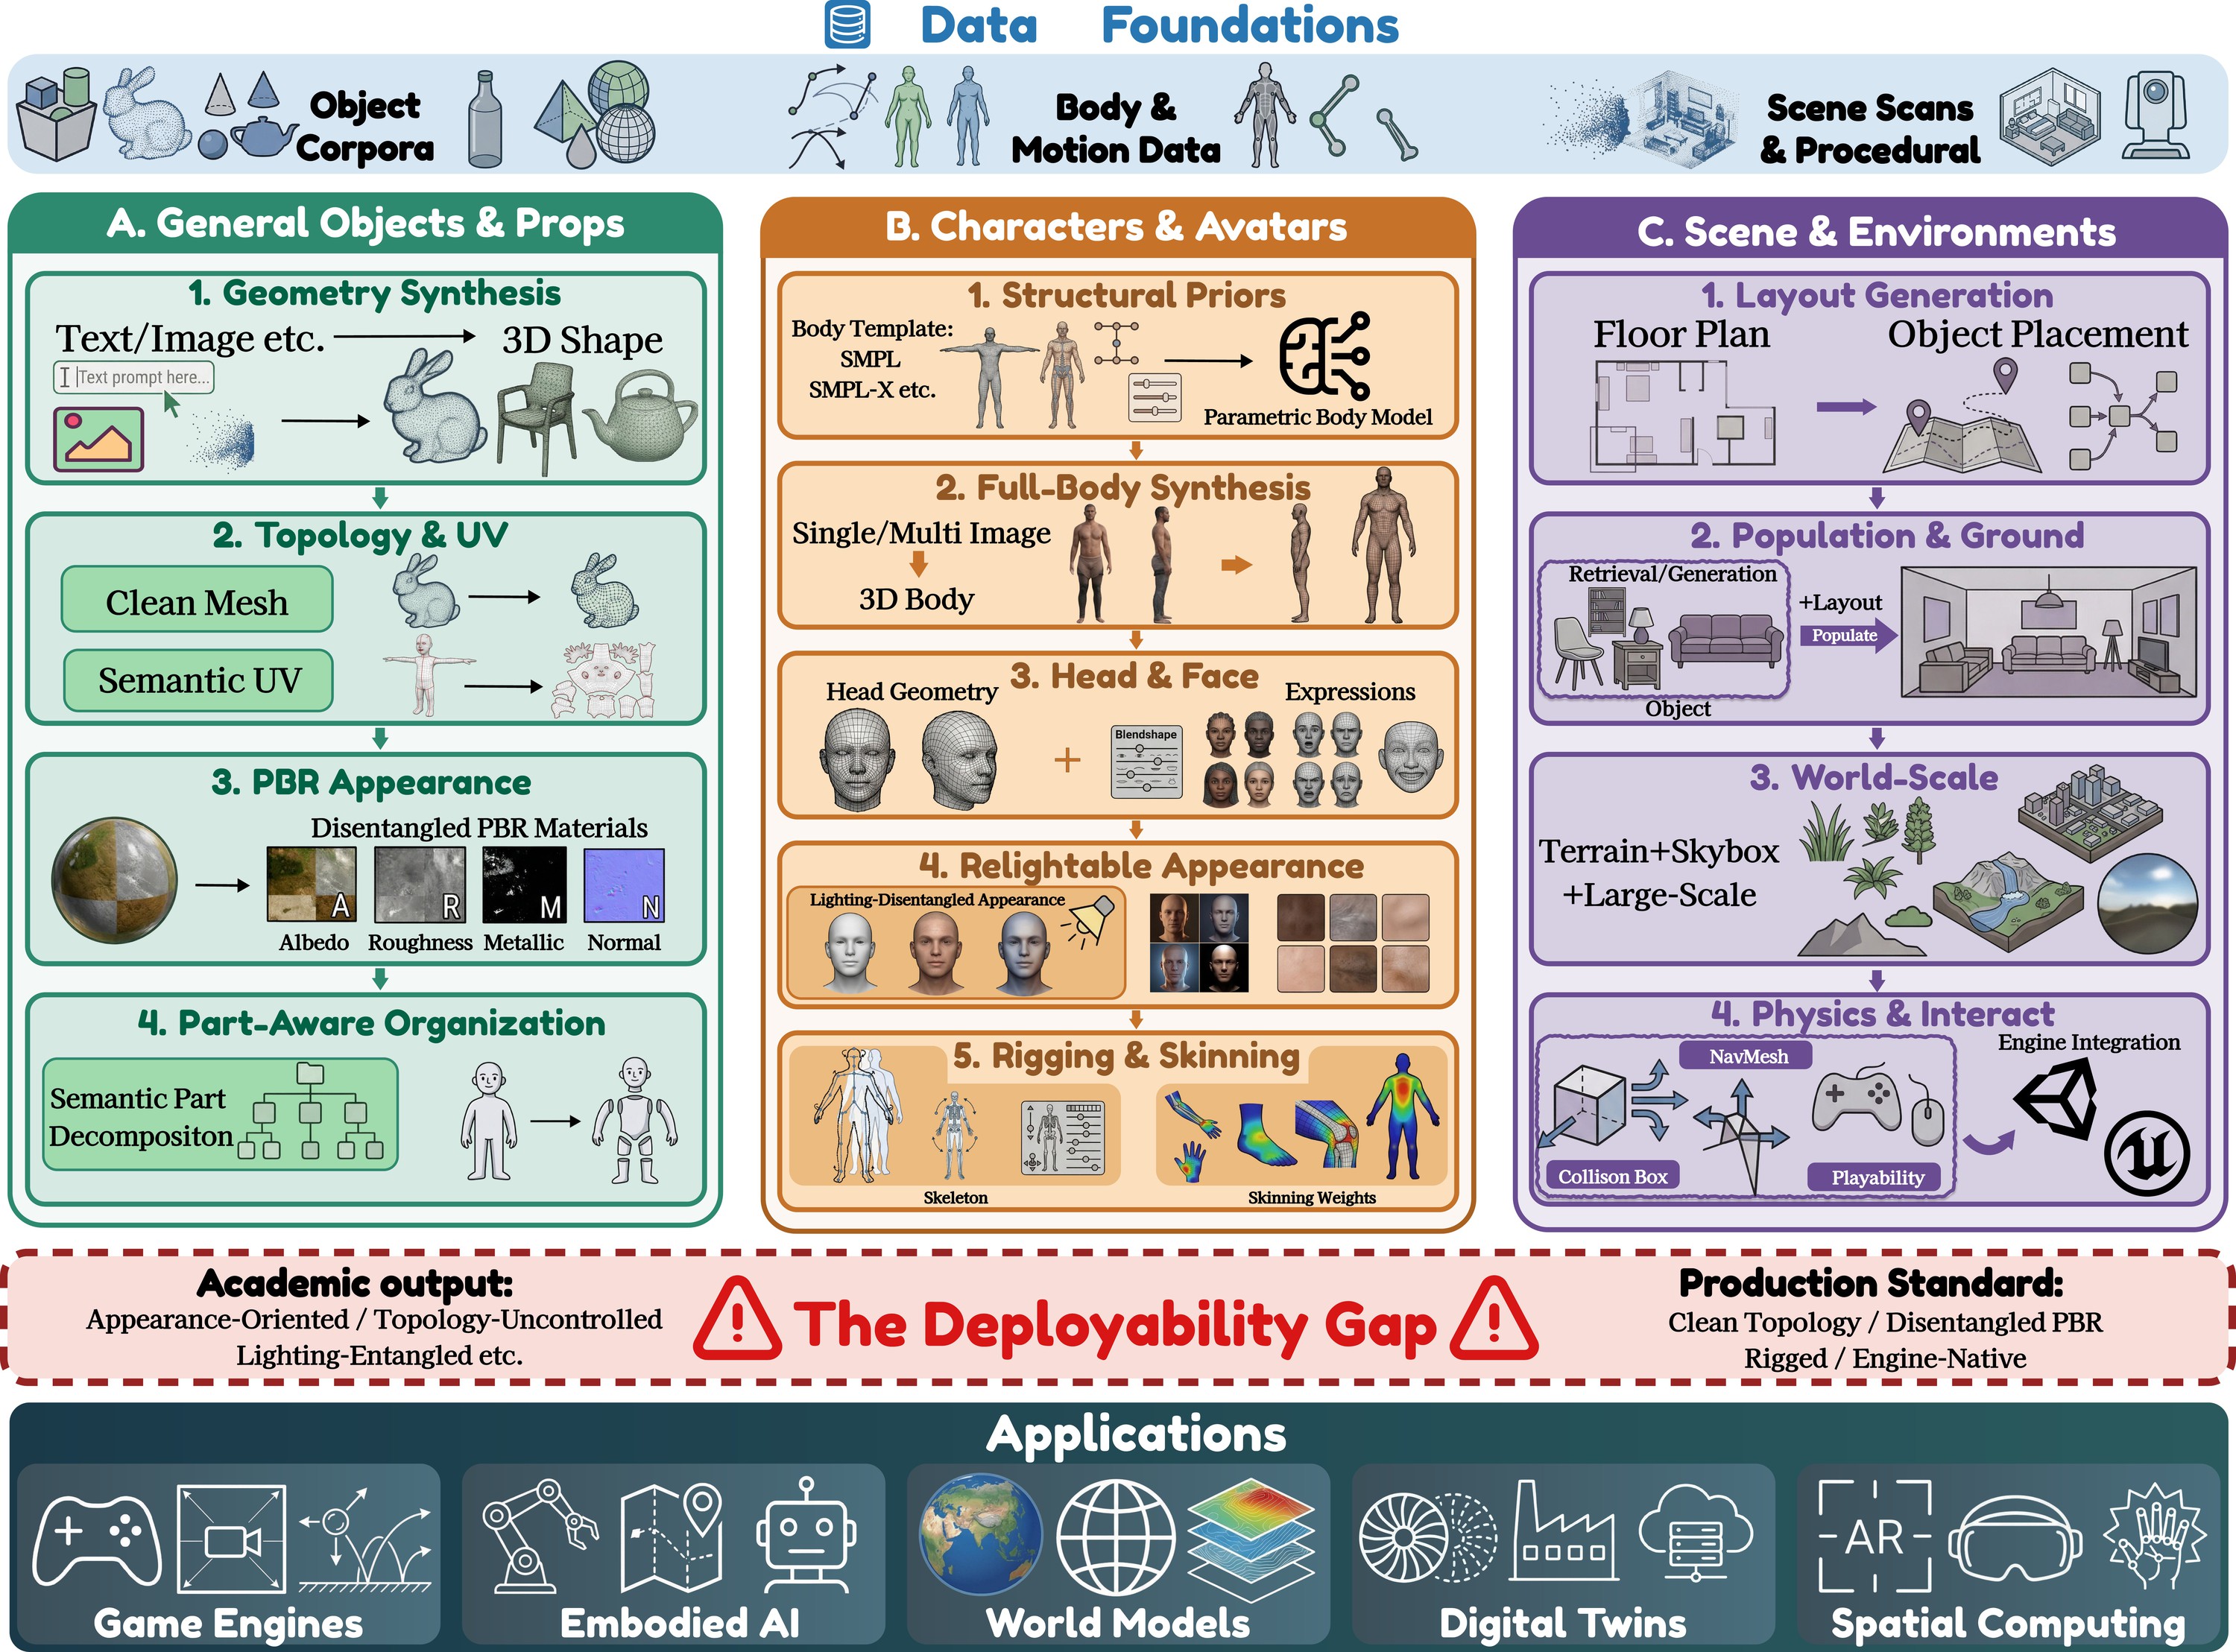
The survey is organized around a two-dimensional taxonomy:
- Horizontal axis (asset types): General Objects, Characters & Avatars, Scenes & Environments
- Vertical axis (pipeline stages): Data Foundations → Geometry → Topology → Appearance → Rigging → Scene Assembly
This structure mirrors the production pipeline used in game engines and interactive applications, enabling direct assessment of where each method fits within a deployment workflow.
Data Foundations & Benchmarks
Object Datasets
| Dataset | Year | Scale | Description |
|---|---|---|---|
| ShapeNet | 2015 | 51K models, 55 categories | Large-scale 3D shape repository (Chang et al.) |
| ModelNet | 2015 | 12K CAD models, 40 categories | Princeton 3D object benchmark (Wu et al.) |
| ABC | 2019 | 1M+ CAD models | Mechanical parts with parametric annotations (Koch et al.) |
| Thingi10K | 2016 | 10K printable models | Web-derived 3D printing models with diverse topology (Zhou and Jacobson) |
| PartNet | 2019 | 27K objects, 573K parts | Part-level object annotations for structural decomposition (Mo et al.) |
| Text2Shape | 2018 | 75K text-shape pairs | Paired text and shape corpus for language-conditioned 3D generation (Chen et al.) |
| GSO (Google Scanned Objects) | 2022 | 1K+ scans | Household objects with PBR materials (Downs et al.) |
| ABO (Amazon Berkeley Objects) | 2022 | 8K+ models | Product catalog with multi-view images (Collins et al.) |
| CO3D | 2021 | 1.5M frames, 19K objects | Multi-view real-capture object dataset for category-level reconstruction (Reizenstein et al.) |
| Objaverse | 2023 | 800K+ objects | Internet-scale 3D asset collection (Deitke et al.) |
| Objaverse-XL | 2024 | 10.2M objects | Extended internet-scale collection (Deitke et al.) |
Character Datasets
| Dataset | Year | Scale | Description |
|---|---|---|---|
| FAUST | 2014 | 300 scans, 10 subjects | Real body scans with ground-truth correspondence (Bogo et al.) |
| RenderPeople | 2018 | 4.5K+ subjects | Commercially scanned textured human meshes for character production (RenderPeople) |
| AMASS | 2019 | Large-scale motion capture | Unified motion capture archive (Mahmood et al.) |
| CAPE | 2020 | 4D clothing | Clothed body scans with pose variation (Ma et al.) |
| THuman2.0 | 2021 | 526 high-res scans | Detailed textured human models (Yu et al.) |
| HuMMan | 2022 | 1K subjects | Multi-modal human dataset (Cai et al.) |
| HumanML3D | 2022 | 14.6K text-motion sequences | Text-aligned motion corpus for controllable human generation and evaluation (Guo et al.) |
| Motion-X | 2024 | Large-scale motion | Expressive whole-body motion dataset (Lin et al.) |
Scene Datasets
| Dataset | Year | Scale | Description |
|---|---|---|---|
| ScanNet | 2017 | 1,513 indoor scans | RGB-D reconstructions with annotations (Dai et al.) |
| ScanNet++ | 2023 | 460 scenes | Laser+DSLR indoor scans with material annotations (Yeshwanth et al.) |
| Matterport3D | 2017 | 90 buildings | Large-scale indoor environments (Chang et al.) |
| HM3D | 2021 | 1K buildings | Habitat-scale indoor scans with navigation annotations (Ramakrishnan et al.) |
| Structured3D | 2020 | 3.5K houses | Synthetic indoor scenes with layout and topology labels (Zheng et al.) |
| Hypersim | 2021 | 461 scenes, 77K images | Photorealistic synthetic scenes with material labels (Roberts et al.) |
| 3D-FRONT | 2021 | 18K rooms | Professionally designed indoor layouts (Fu et al.) |
| ProcTHOR | 2022 | Procedural houses | Infinitely scalable simulated interiors (Deitke et al.) |
| Infinigen | 2023 | Procedural nature | Photorealistic procedural generation of natural worlds (Raistrick et al.) |
| Infinigen Indoors | 2024 | Procedural interiors | Indoor extension of Infinigen (Raistrick et al.) |
General Objects & Props
Geometry Generation
Score Distillation (SDS)
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| DreamFusion | 2022 | ICLR 2023 | Pioneering open-domain text-to-3D via SDS | 📄 | - | 🌐 | 📖 |
| Magic3D | 2023 | CVPR 2023 | Coarse-to-fine SDS for higher-resolution detail | 📄 | - | 🌐 | 📖 |
| Fantasia3D | 2023 | ICCV 2023 | Disentangled geometry-appearance SDS with DMTet | 📄 | 💻 | - | 📖 |
| ProlificDreamer | 2023 | NeurIPS 2023 | Variational SDS reducing over-smoothing | 📄 | 💻 | - | 📖 |
| RichDreamer | 2024 | CVPR 2024 | Normal-depth diffusion prior for stable geometry | 📄 | 💻 | - | 📖 |
Multi-View Reconstruction (MV)
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| Zero-1-to-3 | 2023 | ICCV 2023 | View-conditioned diffusion for novel-view synthesis | 📄 | 💻 | - | 📖 |
| MVDream | 2024 | ICML 2024 | Multi-view consistent diffusion model | 📄 | 💻 | - | 📖 |
| Wonder3D | 2024 | CVPR 2024 | Color + normal diffusion for normal-guided recon. | 📄 | 💻 | - | 📖 |
| SV3D | 2024 | ECCV 2024 | Video diffusion for dense multi-view generation | 📄 | - | 🌐 | 📖 |
GAN-based
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| 3D-GAN | 2016 | NeurIPS 2016 | Pioneering voxel-based adversarial 3D generation | 📄 | - | - | 📖 |
| Tree-GAN | 2019 | arXiv 2019 | Tree-structured generator for point clouds | 📄 | - | - | 📖 |
| SP-GAN | 2021 | ICCV 2021 | Spherical prior for global shape consistency | 📄 | - | - | 📖 |
| SDF-StyleGAN | 2022 | CVPR 2022 | StyleGAN adapted for high-resolution SDF fields | 📄 | - | - | 📖 |
VAE / AE
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| AtlasNet | 2018 | CVPR 2018 | Patch-deformation VAE for surface reconstruction | 📄 | 💻 | - | 📖 |
| TM-Net | 2021 | arXiv 2021 | Joint geometry-texture VAE generation | 📄 | - | - | 📖 |
| Michelangelo | 2023 | NeurIPS 2023 | Aligned shape-conditioned VAE with multimodal input | 📄 | 💻 | - | 📖 |
| CLAY | 2024 | arXiv 2024 | Large-scale VAE + DiT for controllable 3D generation | 📄 | - | - | 📖 |
Direct 3D Diffusion
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| PC-DPM | 2021 | ICLR 2021 | DDPM for point cloud denoising generation | 📄 | - | - | 📖 |
| MeshDiffusion | 2023 | ICLR 2023 | Score-based diffusion directly on mesh vertices | 📄 | 💻 | - | 📖 |
| TetraDiffusion | 2024 | arXiv 2024 | Tetrahedral diffusion for high-resolution topology | 📄 | - | - | 📖 |
Feed-Forward (FF)
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| Pixel2Mesh | 2018 | ECCV 2018 | GCN-based mesh deformation from single image | 📄 | 💻 | - | 📖 |
| LRM | 2023 | ICLR 2024 | Transformer-based large reconstruction model | 📄 | - | 🌐 | 📖 |
| TripoSR | 2024 | arXiv 2024 | Distilled feed-forward for sub-second reconstruction | 📄 | 💻 | - | 📖 |
| GS-LRM | 2024 | ECCV 2024 | Large reconstruction model for 3D Gaussian Splatting | 📄 | - | 🌐 | 📖 |
| InstantMesh | 2024 | arXiv 2024 | Multi-view to FlexiCubes mesh with UV | 📄 | 💻 | - | 📖 |
| LGM | 2024 | arXiv 2024 | Large multi-view Gaussian model for high-resolution 3D content | 📄 | 💻 | - | 📖 |
| SF3D | 2024 | arXiv 2024 | Joint mesh + UV + PBR material prediction | 📄 | 💻 | - | 📖 |
| Fast3R | 2025 | arXiv 2025 | Amortized scalable multi-view 3D reconstruction | 📄 | - | - | 📖 |
Latent Generative Models (LGM)
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| Shap-E | 2023 | arXiv 2023 | Fast text/image-to-3D via latent diffusion | 📄 | 💻 | - | 📖 |
| 3DShape2VecSet | 2023 | SIGGRAPH 2023 | Unordered vector-set VAE + diffusion | 📄 | 💻 | - | 📖 |
| LATTICE | 2025 | arXiv 2025 | High-fidelity 3D generation at scale in compact latent space | 📄 | - | - | 📖 |
| XCube | 2024 | CVPR 2024 | Hierarchical sparse-voxel latent diffusion | 📄 | - | - | 📖 |
| TRELLIS | 2025 | CVPR 2025 | Structured latent (SLAT) with rectified flow | 📄 | 💻 | - | 📖 |
| TRELLIS.2 | 2025 | arXiv 2025 | O-Voxel representation, 4B params, PBR output | 📄 | 💻 | - | 📖 |
| SparseFlex | 2025 | arXiv 2025 | Sparse isosurface VAE + flow for arbitrary topology | 📄 | - | - | 📖 |
| TripoSG | 2025 | arXiv 2025 | VAE + rectified flow DiT for high-fidelity meshes | 📄 | 💻 | - | 📖 |
| MeshCraft | 2025 | arXiv 2025 | Face-token VAE + flow DiT for parallel mesh gen. | 📄 | - | - | 📖 |
Part-Aware
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| PAGENet | 2020 | AAAI 2020 | Part-aware generation network | - | - | - | 📖 |
| SAMPart3D | 2024 | arXiv 2024 | Multi-granularity zero-shot 3D part segmentation | - | - | - | 📖 |
| HoloPart | 2025 | arXiv 2025 | Amodal 3D part completion | - | - | - | 📖 |
| X-Part | 2025 | arXiv 2025 | Structure-coherent controllable shape decomposition | 📄 | - | - | 📖 |
| PartGen | 2025 | arXiv 2025 | Part-level multi-view diffusion generation | - | - | - | 📖 |
| PartCrafter | 2025 | arXiv 2025 | Part-wise 3D reconstruction and editing | - | - | - | 📖 |
| OmniPart | 2025 | arXiv 2025 | Unified part-aware reconstruction pipeline | - | - | - | 📖 |
Topology Generation
Indirect Methods (Post-hoc Remeshing)
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| Instant Meshes | 2015 | ACM TOG 2015 | Field-aligned instant quad/tri remeshing | - | 💻 | - | 📖 |
| QuadriFlow | 2018 | SGP 2018 | Scalable instant field-aligned quad remeshing | 📄 | 💻 | - | 📖 |
| NeurCross | 2025 | arXiv 2025 | Neural-guided cross-field remeshing | - | - | - | 📖 |
Direct Methods -- Autoregressive
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| PolyGen | 2020 | ICML 2020 | Pioneering vertex-then-face autoregressive mesh gen. | 📄 | 💻 | - | 📖 |
| MeshGPT | 2024 | ICLR 2024 | VQ-VAE codebook tokenization for mesh generation | 📄 | - | 🌐 | 📖 |
| MeshAnything | 2024 | arXiv 2024 | Shape-conditioned artist mesh extraction | 📄 | 💻 | - | 📖 |
| MeshAnything V2 | 2025 | arXiv 2025 | Adjacent mesh tokenization with improved compression | 📄 | 💻 | - | 📖 |
| Meshtron | 2024 | arXiv 2024 | Artist-like mesh generation at scale from artist-created data | 📄 | - | - | 📖 |
| PivotMesh | 2024 | arXiv 2024 | Coarse-to-fine mesh scaffolding | 📄 | 💻 | - | 📖 |
| EdgeRunner | 2024 | arXiv 2024 | Hybrid AR-latent mesh generation pipeline | 📄 | 💻 | - | 📖 |
| QuadGPT | 2025 | arXiv 2025 | Autoregressive quad-mesh generation for edge loops | 📄 | - | - | 📖 |
| DeepMesh | 2025 | ICCV 2025 | RL-based preference alignment for artist-quality mesh | 📄 | 💻 | - | 📖 |
| Mesh-RFT | 2025 | arXiv 2025 | Masked DPO for localized mesh defect correction | 📄 | - | - | 📖 |
Direct Methods -- Diffusion
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| PolyDiff | 2023 | ICCV 2023 | Discrete denoising diffusion over triangle soups | 📄 | - | - | 📖 |
| SpaceMesh | 2024 | arXiv 2024 | Continuous halfedge latent diffusion; ultra-fast | 📄 | - | - | 📖 |
| MeshCraft | 2025 | arXiv 2025 | Flow-based DiT with face-count control | 📄 | - | - | 📖 |
Appearance Generation
UV Unwrapping
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| xatlas | 2018 | Open-source | Production-baseline automatic UV atlas packer | - | 💻 | - | 📖 |
| UVAtlas | 2023 | Open-source | Production-baseline atlas generation for UV layout | - | 💻 | - | 📖 |
| Auto-UV | 2025 | arXiv 2025 | Learned seam prediction for UV unwrapping | - | - | - | 📖 |
| Flatten Anything | 2024 | arXiv 2024 | Unsupervised cycle-consistent UV mapping | - | - | - | 📖 |
| FlexPara | 2025 | arXiv 2025 | Flexible unsupervised UV parameterization | 📄 | - | - | 📖 |
| PartUV | 2025 | arXiv 2025 | Semantic chart-aligned UV partitioning | - | - | - | 📖 |
| ArtUV | 2025 | arXiv 2025 | Artist-style UV packing and layout | 📄 | - | - | 📖 |
| SeamCrafter | 2025 | arXiv 2025 | Seam preference optimization for UV quality | 📄 | - | - | 📖 |
| Hunyuan3D Studio | 2025 | arXiv 2025 | End-to-end game-ready asset pipeline with integrated UV construction | 📄 | - | - | 📖 |
Texture & PBR Material Generation
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| TEXTure | 2023 | SIGGRAPH 2023 | Iterative text-guided texture painting | 📄 | 💻 | - | 📖 |
| Text2Tex | 2023 | ICCV 2023 | Progressive inpainting for mesh texturing | 📄 | 💻 | - | 📖 |
| TexFusion | 2023 | arXiv 2023 | Cross-view aggregated texture fusion | 📄 | - | - | 📖 |
| Paint3D | 2024 | arXiv 2024 | Illumination-free texture diffusion for PBR | 📄 | 💻 | - | 📖 |
| FlashTex | 2024 | arXiv 2024 | Fast text-to-texture generation | 📄 | - | - | 📖 |
| TexGen | 2024 | arXiv 2024 | Feed-forward UV-space texture diffusion | - | - | - | 📖 |
| MVPaint | 2025 | arXiv 2025 | Multi-view consistent texture painting | 📄 | - | - | 📖 |
| MaterialMVP | 2025 | ICCV 2025 | Illumination-invariant multi-view PBR diffusion | - | - | - | 📖 |
| MaterialAnything | 2024 | arXiv 2024 | PBR material decomposition as first-class objective | 📄 | - | - | 📖 |
| 3DTopia-XL | 2024 | arXiv 2024 | Primitive diffusion for high-quality 3D assets with joint UV/PBR objectives | 📄 | 💻 | - | 📖 |
| Meta 3D AssetGen | 2024 | arXiv 2024 | Unified UV + geometry + PBR material pipeline | 📄 | - | - | 📖 |
| PBR3DGen | 2025 | arXiv 2025 | VLM-guided mesh generation with PBR materials | 📄 | - | - | 📖 |
Characters & Avatars
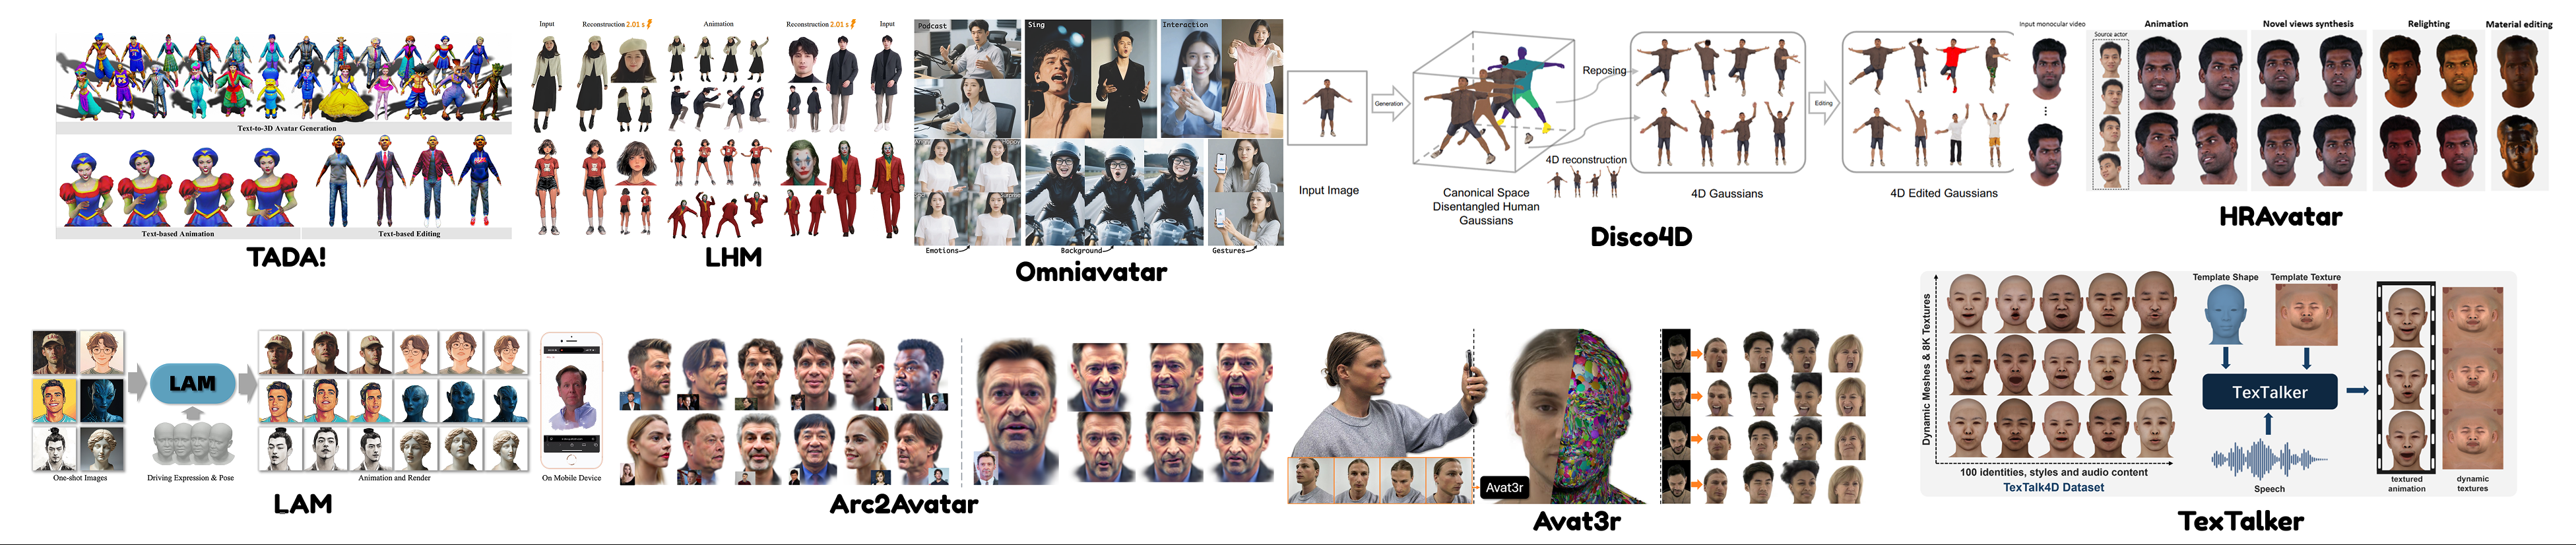
Structural Priors
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| SMPL | 2015 | SIGGRAPH Asia 2015 | Skinned multi-person linear body model | 📄 | - | - | 📖 |
| SMPL-X | 2019 | CVPR 2019 | Expressive body + hands + face parametric model | - | - | - | 📖 |
| FLAME | 2017 | SIGGRAPH Asia 2017 | Learned head model with expression blendshapes | - | - | - | 📖 |
Full-Body Synthesis
Parametric Template
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| Tex2Shape | 2019 | ICCV 2019 | UV-space displacement prediction on SMPL | - | - | - | 📖 |
| CAPE | 2020 | CVPR 2020 | Pose-dependent clothing offsets on body mesh | - | - | - | 📖 |
| ExPose | 2020 | ECCV 2020 | Monocular body + hands + face estimation | - | - | - | 📖 |
| STAR | 2020 | ECCV 2020 | Sparse parametric SMPL variant | - | - | - | 📖 |
| HybrIK | 2021 | CVPR 2021 | Hybrid analytical-regressive IK for body mesh | - | - | - | 📖 |
Implicit / Hybrid
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| PIFu | 2019 | ICCV 2019 | Pixel-aligned implicit function for clothed humans | - | - | - | 📖 |
| ARCH | 2020 | CVPR 2020 | Canonical implicit field with SMPL-guided rigging | - | - | - | 📖 |
| PIFuHD | 2020 | CVPR 2020 | Multi-level implicit for high-res human recon. | - | - | - | 📖 |
| PaMIR | 2021 | TPAMI 2021 | Parametric body model inside implicit recon. | - | - | - | 📖 |
| SMPLicit | 2021 | CVPR 2021 | Implicit clothing conditioned on SMPL parameters | 📄 | 💻 | - | 📖 |
| ICON | 2022 | CVPR 2022 | Normal-guided implicit body with SMPL | - | - | - | 📖 |
| gDNA | 2022 | ECCV 2022 | Generative implicit model for diverse humans | - | - | - | 📖 |
| ECON | 2023 | CVPR 2023 | Implicit + explicit mesh hybrid reconstruction | - | - | - | 📖 |
| S3F | 2023 | ICCV 2023 | Structured 3D features with SMPL semi-supervision | - | - | - | 📖 |
GAN / Diffusion Generative
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| StylePeople | 2021 | arXiv 2021 | GAN-based clothed mesh synthesis | - | - | - | 📖 |
| AvatarGen | 2022 | arXiv 2022 | SDF + tri-plane GAN for 3D avatars | - | - | - | 📖 |
| AvatarCLIP | 2022 | SIGGRAPH 2022 | CLIP-guided text-to-avatar generation | 📄 | 💻 | - | 📖 |
| Get3DHuman | 2023 | arXiv 2023 | Tri-plane/SDF GAN for full-body humans | 📄 | 💻 | - | 📖 |
| GETAvatar | 2023 | NeurIPS 2023 | GAN + SMPL for animatable textured mesh | - | - | - | 📖 |
| AvatarCraft | 2023 | arXiv 2023 | SDS-based NeRF-to-mesh avatar generation | - | - | - | 📖 |
| DreamHuman | 2023 | arXiv 2023 | SDS + imGHUM body prior for text-to-human | 📄 | - | - | 📖 |
| ChuPa | 2023 | arXiv 2023 | 2D diffusion on SMPL with displacement | - | - | - | 📖 |
| DreamAvatar | 2024 | arXiv 2024 | SDS + SMPL-guided NeRF avatar synthesis | - | - | - | 📖 |
| Morphable Diffusion | 2024 | CVPR 2024 | 3D-consistent diffusion for single-image avatar creation | 📄 | - | - | 📖 |
| SiTH | 2024 | CVPR 2024 | Single-view textured human reconstruction with image-conditioned diffusion | 📄 | - | - | 📖 |
| TADA! | 2024 | CVPR 2024 | SMPL-X + texture with LBS-ready rigging | 📄 | 💻 | - | 📖 |
Feed-Forward / Real-Time
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| InstantAvatar | 2023 | CVPR 2023 | Fast neural field from monocular video | - | - | - | 📖 |
| SHERF | 2023 | arXiv 2023 | Canonical-prior NeRF for generalizable humans | - | - | - | 📖 |
| LRM | 2023 | ICLR 2024 | Feed-forward large reconstruction model adapted to human body synthesis | 📄 | - | 🌐 | 📖 |
| Human GS | 2024 | arXiv 2024 | Canonical 3DGS with skinning from multi-view | - | - | - | 📖 |
| HUGS | 2024 | CVPR 2024 | 3DGS + SMPL for real-time avatar playback | - | - | - | 📖 |
| 3DGS-Avatar | 2024 | arXiv 2024 | Deformable 3DGS bound to skinning weights | 📄 | 💻 | - | 📖 |
| LHM | 2025 | arXiv 2025 | Dense Gaussians on SMPL; animatable in seconds | - | - | - | 📖 |
| OmniAvatar | 2025 | arXiv 2025 | Video diffusion for temporally coherent avatars | - | - | - | 📖 |
Head & Face Synthesis
Morphable + Neural
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| i3DMM | 2021 | arXiv 2021 | Implicit SDF-based 3D morphable model | - | - | - | 📖 |
| NerFace | 2021 | arXiv 2021 | NeRF with expression-conditioned deformation | - | - | - | 📖 |
| EG3D | 2022 | CVPR 2022 | Efficient tri-plane GAN for 3D face generation | - | - | - | 📖 |
| NPHM | 2023 | arXiv 2023 | Dual-SDF for identity + expression disentanglement | - | - | - | 📖 |
| Next3D | 2023 | CVPR 2023 | Tri-plane + texture rasterization with FLAME | - | - | - | 📖 |
| PanoHead | 2023 | CVPR 2023 | Depth-aware tri-grid for full 360-degree heads | - | - | - | 📖 |
| RODIN | 2023 | arXiv 2023 | Diffusion on tri-plane for novel-ID head generation | - | - | - | 📖 |
| HeadSculpt | 2023 | arXiv 2023 | SDS NeRF with SMPL-X prior for head sculpting | - | - | - | 📖 |
Mesh-Anchored Gaussians
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| GaussianAvatars | 2024 | CVPR 2024 | 3DGS bound to FLAME triangles for animation | - | - | - | 📖 |
| FlashAvatar | 2024 | arXiv 2024 | >300 FPS 3DGS + FLAME; production-ready | - | - | - | 📖 |
| MonoGaussianAvatar | 2024 | arXiv 2024 | Monocular-video 3DGS on FLAME mesh | - | - | - | 📖 |
| RGCA (Relightable) | 2024 | arXiv 2024 | Full PBR 3DGS decomposition for relighting | - | - | - | 📖 |
Feed-Forward Reconstruction
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| GAGAvatar | 2024 | arXiv 2024 | Generalizable 3DGS from single image with FLAME | - | - | - | 📖 |
| Arc2Avatar | 2025 | arXiv 2025 | Identity-guided single-image 3DGS head recon. | - | - | - | 📖 |
| HRAvatar | 2025 | arXiv 2025 | PBR 3DGS with roughness + Fresnel from mono video | - | - | - | 📖 |
| LAM | 2025 | arXiv 2025 | Large Avatar Model; 280 FPS, LBS-compatible | - | - | - | 📖 |
| Avat3r | 2025 | arXiv 2025 | Sparse-view canonical 3DGS via ViT | - | - | - | 📖 |
Rendering & Animation
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| SadTalker | 2023 | CVPR 2023 | Audio-to-FLAME coefficients for talking-head video | - | - | - | 📖 |
| HunyuanVideo-Avatar | 2025 | arXiv 2025 | High-fidelity audio-driven human animation for multiple characters | 📄 | - | - | 📖 |
| TexTalker | 2025 | arXiv 2025 | Audio-sync wrinkle maps + geometric deformation | - | - | - | 📖 |
Rigging & Skinning
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| RigNet | 2020 | SIGGRAPH 2020 | End-to-end GNN skeleton + skinning prediction | - | - | - | 📖 |
| SkinningNet | 2022 | arXiv 2022 | Two-stream GNN for heterogeneous skeletal topologies | - | - | - | 📖 |
| DeePSD | 2021 | arXiv 2021 | Unsupervised physics-based garment skinning | - | - | - | 📖 |
Note: TADA!, ChuPa, LAM, and HRAvatar also include rigging capabilities -- see above.
Scenes & Environments
Layout Generation
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| ATISS | 2021 | NeurIPS 2021 | Autoregressive transformer for room layouts | 📄 | 💻 | - | 📖 |
| ProcTHOR | 2022 | NeurIPS 2022 | Procedural interactive houses for embodied AI | - | 💻 | 🌐 | 📖 |
| Pose2Room | 2022 | arXiv 2022 | Activity-driven affordance-aware room layout | - | - | - | 📖 |
| DiffuScene | 2024 | arXiv 2024 | Diffusion + retrieval for furnished indoor scenes | 📄 | 💻 | - | 📖 |
| Holodeck | 2024 | CVPR 2024 | LLM-planned embodied environment generation | - | - | - | 📖 |
| LayoutGPT | 2023 | arXiv 2023 | LLM-generated indoor layouts from text | - | - | - | 📖 |
| LLplace | 2024 | arXiv 2024 | Dialogue-driven interactive layout editing | 📄 | - | - | 📖 |
| CityCraft | 2024 | arXiv 2024 | Language-guided city-scale layout generation | 📄 | - | - | 📖 |
Scene Population & Asset Grounding
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| MIME | 2023 | arXiv 2023 | Human-motion-informed object placement | - | - | - | 📖 |
| AnyHome | 2023 | arXiv 2023 | Open-vocabulary text-to-house scene generation | 📄 | - | - | 📖 |
| Open-Universe | 2024 | arXiv 2024 | LLM programs + solver for open-vocabulary scenes | 📄 | - | - | 📖 |
| SceneCraft | 2024 | arXiv 2024 | Blender code agent for executable scene scripts | - | - | - | 📖 |
| PhyScene | 2024 | arXiv 2024 | Physics-guided diffusion for interactable scenes | - | - | - | 📖 |
| UnrealLLM | 2025 | arXiv 2025 | Unreal Engine PCG agents from language | - | - | - | 📖 |
| Layout2Scene | 2025 | arXiv 2025 | Layout-guided diffusion for holistic scenes | 📄 | - | - | 📖 |
| 3D-GPT | 2023 | arXiv 2023 | Procedural modeling as language-conditioned programs | 📄 | 💻 | - | 📖 |
| PhysGen3D | 2025 | arXiv 2025 | Miniature interactive worlds with physics simulation | - | - | - | 📖 |
World-Scale Generation
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| Text2Light | 2022 | arXiv 2022 | Text-conditioned HDR panorama for skybox/lighting | 📄 | 💻 | - | 📖 |
| Text2Room | 2023 | arXiv 2023 | 2D diffusion lifted to textured room meshes | 📄 | 💻 | - | 📖 |
| Infinigen | 2023 | CVPR 2023 | Photorealistic procedural natural world generation | - | - | - | 📖 |
| CityDreamer | 2024 | arXiv 2024 | Unbounded urban synthesis with stuff + thing fields | 📄 | 💻 | - | 📖 |
| Infinigen Indoors | 2024 | arXiv 2024 | Photorealistic procedural indoor worlds | - | - | - | 📖 |
| LayerPano3D | 2025 | arXiv 2025 | Layered panorama to explorable 3DGS scene | - | - | - | 📖 |
| WorldCraft | 2025 | arXiv 2025 | LLM-agentic world editing and customization | 📄 | - | - | 📖 |
Evaluation & Benchmarks
The survey identifies several complementary evaluation dimensions for production-ready 3D generation:
| Dimension | Metrics |
|---|---|
| Geometric Fidelity | Chamfer Distance (CD), Earth Mover's Distance (EMD), F-Score, Normal Consistency, Coverage (COV), Minimum Matching Distance (MMD), 1-NNA |
| Appearance Quality | PSNR, SSIM, LPIPS, FID, KID, CLIP Score, CLIP R-Precision |
| PBR / Relighting | Relighting consistency, albedo/roughness/metallic separation quality, paper-specific material decomposition tests |
| Asset Usability | UV stretch and angular distortion, seam visibility, chart packing efficiency, overlap detection, rig smoothness, retargeting success, engine import success |
| Topology Readiness | Manifoldness, watertightness, genus correctness, quad ratio, edge-flow alignment, collision-mesh quality |
| Scene-Level | Physical plausibility, interpenetration, NavMesh connectivity, navigation success rate, affordance compatibility, A/B preference, Likert ratings |
A key finding of this survey is that existing benchmarks systematically overestimate deployment readiness by focusing on geometric and appearance metrics while neglecting topology, UV/PBR, engine import, and other asset usability criteria required for interactive applications.
Industry & Companies
| Company | Key Product | Type | Link |
|---|---|---|---|
| Tripo AI | Tripo V2.5 | Closed | tripo3d.ai |
| Tencent | Hunyuan3D | Open + Closed | 3d.hunyuan.tencent.com |
| ByteDance | MVDream | Open | - |
| Meshy AI | Meshy 5 | Closed | meshy.ai |
| Deemos | Rodin Gen 1.5 | Closed | hyperhuman.deemos.com |
| DreamTech | - | Closed | dreamtech.com |
| Luma AI | Genie | Closed | lumalabs.ai |
| CSM AI | - | Closed | csm.ai |
| Stability AI | SF3D | Open | stability.ai |
| NVIDIA | Edify 3D | Closed | build.nvidia.com |
| SUDO AI | - | Closed | sudo.ai |
Citation
If you find this survey useful, please cite our paper:
@article{wu2026visual,
  title={From Visual Synthesis to Interactive Worlds: Toward Production-Ready 3D Asset Generation},
  author={Wu, Jiafeng and Lou, Zhuofan and Liu, Jian and Du, Dazhao and Guo, Chunchao and Guo, Song},
  journal={arXiv preprint arXiv:2604.23629},
  year={2026}
}
If you also use resources from the v1 collection, please additionally cite:
@article{liu2024comprehensive,
  title={A Comprehensive Survey on 3D Content Generation},
  author={Liu, Jian and Huang, Xiaoshui and Huang, Tianyu and Chen, Lu and Hou, Yuenan and Tang, Shixiang and Liu, Ziwei and Ouyang, Wanli and Zuo, Wangmeng and Jiang, Junjun and others},
  journal={arXiv preprint arXiv:2402.01166},
  year={2024}
}
Contributing
We welcome contributions! Please see CONTRIBUTING.md for guidelines.
Note: Pull requests should target the v2 branch. The
mainbranch preserves the original v1 awesome list.
Acknowledgments
This work was supported by The Hong Kong University of Science and Technology and Tencent.
v1 Paper Collection
The original awesome list curated is preserved on the main branch. It contains a broader collection of AIGC 3D papers organized by topic without the production-pipeline focus of v2.
Star History
Contributors


Similar repos


Languages
Python
100.0%
README
From Visual Synthesis to Interactive Worlds:
Toward Production-Ready 3D Asset Generation
Jiafeng Wu1,2*† ·
Zhuofan Lou1,3*† ·
Jian Liu1‡
Chunchao Guo4 ·
Dazhao Du1 ·
Song Guo1§
1 The Hong Kong University of Science and Technology
2 Huazhong University of Science and Technology ·
3 Sichuan University ·
4 Tencent
* Equal contribution · † Work done during internship at HKUST · ‡ Project lead · § Corresponding author
✦ Production-Oriented 3D Generation Survey ✦
🧭 Taxonomy · 🗂 Data · 📦 Objects · 🧍 Characters · 🌍 Scenes · 📏 Evaluation · 🏭 Industry
News
- 🔥 [2026-04] v2.0: Introduces a production-ready two-dimensional taxonomy spanning asset tiers and pipeline stages, and expands the collection to data foundations, geometry, topology, appearance, rigging, scene assembly, evaluation, and industry systems.
- 📚 [2025-08] v1.0: Established the initial curated 3D AIGC paper collection, organized object, scene, and avatar methods under 3D-native, 2D-prior, and hybrid paradigms, and tracked surveys, datasets, talks, companies, and implementations.
Abstract
Three-dimensional content generation has progressed from producing isolated, visually plausible shapes to constructing structured assets that can be deployed in real-time interactive environments. This trajectory is driven by converging demands from game development, embodied AI, world simulation, digital twins, and spatial computing, all of which require 3D content that goes beyond surface appearance to satisfy engine-level constraints on topology, UV parameterization, physically based materials, skeletal rigging, and physics-aware scene layout. Despite rapid advances in generative modeling, a persistent gap separates the outputs of current methods from the production-ready standard expected by interactive applications. This survey addresses that gap by organizing the literature around the asset production pipeline rather than algorithmic families.
At a Glance
- 🧭 Organized by a production-ready, pipeline-first taxonomy rather than isolated algorithm families.
- 📦 Covers three asset tiers: general objects, characters and avatars, and scenes and environments.
- 🛠 Tracks the full asset workflow from data foundations through geometry, topology, appearance, rigging, and scene assembly.
- 📚 Consolidates methods, datasets, evaluation criteria, and industry references in one companion list.
Table of Contents
- 🧭 Survey Taxonomy
- 🗂 Data Foundations & Benchmarks
- 📦 General Objects & Props
- 🧍 Characters & Avatars
- 🌍 Scenes & Environments
- 📏 Evaluation & Benchmarks
- 🏭 Industry & Companies
- 📝 Citation
- 🤝 Contributing
- 🙏 Acknowledgments
- 🗃 v1 Paper Collection
- ⭐ Star History
Survey Taxonomy
The survey is organized around a two-dimensional taxonomy:
- Horizontal axis (asset types): General Objects, Characters & Avatars, Scenes & Environments
- Vertical axis (pipeline stages): Data Foundations → Geometry → Topology → Appearance → Rigging → Scene Assembly
This structure mirrors the production pipeline used in game engines and interactive applications, enabling direct assessment of where each method fits within a deployment workflow.
Data Foundations & Benchmarks
Object Datasets
| Dataset | Year | Scale | Description |
|---|---|---|---|
| ShapeNet | 2015 | 51K models, 55 categories | Large-scale 3D shape repository (Chang et al.) |
| ModelNet | 2015 | 12K CAD models, 40 categories | Princeton 3D object benchmark (Wu et al.) |
| ABC | 2019 | 1M+ CAD models | Mechanical parts with parametric annotations (Koch et al.) |
| Thingi10K | 2016 | 10K printable models | Web-derived 3D printing models with diverse topology (Zhou and Jacobson) |
| PartNet | 2019 | 27K objects, 573K parts | Part-level object annotations for structural decomposition (Mo et al.) |
| Text2Shape | 2018 | 75K text-shape pairs | Paired text and shape corpus for language-conditioned 3D generation (Chen et al.) |
| GSO (Google Scanned Objects) | 2022 | 1K+ scans | Household objects with PBR materials (Downs et al.) |
| ABO (Amazon Berkeley Objects) | 2022 | 8K+ models | Product catalog with multi-view images (Collins et al.) |
| CO3D | 2021 | 1.5M frames, 19K objects | Multi-view real-capture object dataset for category-level reconstruction (Reizenstein et al.) |
| Objaverse | 2023 | 800K+ objects | Internet-scale 3D asset collection (Deitke et al.) |
| Objaverse-XL | 2024 | 10.2M objects | Extended internet-scale collection (Deitke et al.) |
Character Datasets
| Dataset | Year | Scale | Description |
|---|---|---|---|
| FAUST | 2014 | 300 scans, 10 subjects | Real body scans with ground-truth correspondence (Bogo et al.) |
| RenderPeople | 2018 | 4.5K+ subjects | Commercially scanned textured human meshes for character production (RenderPeople) |
| AMASS | 2019 | Large-scale motion capture | Unified motion capture archive (Mahmood et al.) |
| CAPE | 2020 | 4D clothing | Clothed body scans with pose variation (Ma et al.) |
| THuman2.0 | 2021 | 526 high-res scans | Detailed textured human models (Yu et al.) |
| HuMMan | 2022 | 1K subjects | Multi-modal human dataset (Cai et al.) |
| HumanML3D | 2022 | 14.6K text-motion sequences | Text-aligned motion corpus for controllable human generation and evaluation (Guo et al.) |
| Motion-X | 2024 | Large-scale motion | Expressive whole-body motion dataset (Lin et al.) |
Scene Datasets
| Dataset | Year | Scale | Description |
|---|---|---|---|
| ScanNet | 2017 | 1,513 indoor scans | RGB-D reconstructions with annotations (Dai et al.) |
| ScanNet++ | 2023 | 460 scenes | Laser+DSLR indoor scans with material annotations (Yeshwanth et al.) |
| Matterport3D | 2017 | 90 buildings | Large-scale indoor environments (Chang et al.) |
| HM3D | 2021 | 1K buildings | Habitat-scale indoor scans with navigation annotations (Ramakrishnan et al.) |
| Structured3D | 2020 | 3.5K houses | Synthetic indoor scenes with layout and topology labels (Zheng et al.) |
| Hypersim | 2021 | 461 scenes, 77K images | Photorealistic synthetic scenes with material labels (Roberts et al.) |
| 3D-FRONT | 2021 | 18K rooms | Professionally designed indoor layouts (Fu et al.) |
| ProcTHOR | 2022 | Procedural houses | Infinitely scalable simulated interiors (Deitke et al.) |
| Infinigen | 2023 | Procedural nature | Photorealistic procedural generation of natural worlds (Raistrick et al.) |
| Infinigen Indoors | 2024 | Procedural interiors | Indoor extension of Infinigen (Raistrick et al.) |
General Objects & Props
Geometry Generation
Score Distillation (SDS)
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| DreamFusion | 2022 | ICLR 2023 | Pioneering open-domain text-to-3D via SDS | 📄 | - | 🌐 | 📖 |
| Magic3D | 2023 | CVPR 2023 | Coarse-to-fine SDS for higher-resolution detail | 📄 | - | 🌐 | 📖 |
| Fantasia3D | 2023 | ICCV 2023 | Disentangled geometry-appearance SDS with DMTet | 📄 | 💻 | - | 📖 |
| ProlificDreamer | 2023 | NeurIPS 2023 | Variational SDS reducing over-smoothing | 📄 | 💻 | - | 📖 |
| RichDreamer | 2024 | CVPR 2024 | Normal-depth diffusion prior for stable geometry | 📄 | 💻 | - | 📖 |
Multi-View Reconstruction (MV)
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| Zero-1-to-3 | 2023 | ICCV 2023 | View-conditioned diffusion for novel-view synthesis | 📄 | 💻 | - | 📖 |
| MVDream | 2024 | ICML 2024 | Multi-view consistent diffusion model | 📄 | 💻 | - | 📖 |
| Wonder3D | 2024 | CVPR 2024 | Color + normal diffusion for normal-guided recon. | 📄 | 💻 | - | 📖 |
| SV3D | 2024 | ECCV 2024 | Video diffusion for dense multi-view generation | 📄 | - | 🌐 | 📖 |
GAN-based
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| 3D-GAN | 2016 | NeurIPS 2016 | Pioneering voxel-based adversarial 3D generation | 📄 | - | - | 📖 |
| Tree-GAN | 2019 | arXiv 2019 | Tree-structured generator for point clouds | 📄 | - | - | 📖 |
| SP-GAN | 2021 | ICCV 2021 | Spherical prior for global shape consistency | 📄 | - | - | 📖 |
| SDF-StyleGAN | 2022 | CVPR 2022 | StyleGAN adapted for high-resolution SDF fields | 📄 | - | - | 📖 |
VAE / AE
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| AtlasNet | 2018 | CVPR 2018 | Patch-deformation VAE for surface reconstruction | 📄 | 💻 | - | 📖 |
| TM-Net | 2021 | arXiv 2021 | Joint geometry-texture VAE generation | 📄 | - | - | 📖 |
| Michelangelo | 2023 | NeurIPS 2023 | Aligned shape-conditioned VAE with multimodal input | 📄 | 💻 | - | 📖 |
| CLAY | 2024 | arXiv 2024 | Large-scale VAE + DiT for controllable 3D generation | 📄 | - | - | 📖 |
Direct 3D Diffusion
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| PC-DPM | 2021 | ICLR 2021 | DDPM for point cloud denoising generation | 📄 | - | - | 📖 |
| MeshDiffusion | 2023 | ICLR 2023 | Score-based diffusion directly on mesh vertices | 📄 | 💻 | - | 📖 |
| TetraDiffusion | 2024 | arXiv 2024 | Tetrahedral diffusion for high-resolution topology | 📄 | - | - | 📖 |
Feed-Forward (FF)
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| Pixel2Mesh | 2018 | ECCV 2018 | GCN-based mesh deformation from single image | 📄 | 💻 | - | 📖 |
| LRM | 2023 | ICLR 2024 | Transformer-based large reconstruction model | 📄 | - | 🌐 | 📖 |
| TripoSR | 2024 | arXiv 2024 | Distilled feed-forward for sub-second reconstruction | 📄 | 💻 | - | 📖 |
| GS-LRM | 2024 | ECCV 2024 | Large reconstruction model for 3D Gaussian Splatting | 📄 | - | 🌐 | 📖 |
| InstantMesh | 2024 | arXiv 2024 | Multi-view to FlexiCubes mesh with UV | 📄 | 💻 | - | 📖 |
| LGM | 2024 | arXiv 2024 | Large multi-view Gaussian model for high-resolution 3D content | 📄 | 💻 | - | 📖 |
| SF3D | 2024 | arXiv 2024 | Joint mesh + UV + PBR material prediction | 📄 | 💻 | - | 📖 |
| Fast3R | 2025 | arXiv 2025 | Amortized scalable multi-view 3D reconstruction | 📄 | - | - | 📖 |
Latent Generative Models (LGM)
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| Shap-E | 2023 | arXiv 2023 | Fast text/image-to-3D via latent diffusion | 📄 | 💻 | - | 📖 |
| 3DShape2VecSet | 2023 | SIGGRAPH 2023 | Unordered vector-set VAE + diffusion | 📄 | 💻 | - | 📖 |
| LATTICE | 2025 | arXiv 2025 | High-fidelity 3D generation at scale in compact latent space | 📄 | - | - | 📖 |
| XCube | 2024 | CVPR 2024 | Hierarchical sparse-voxel latent diffusion | 📄 | - | - | 📖 |
| TRELLIS | 2025 | CVPR 2025 | Structured latent (SLAT) with rectified flow | 📄 | 💻 | - | 📖 |
| TRELLIS.2 | 2025 | arXiv 2025 | O-Voxel representation, 4B params, PBR output | 📄 | 💻 | - | 📖 |
| SparseFlex | 2025 | arXiv 2025 | Sparse isosurface VAE + flow for arbitrary topology | 📄 | - | - | 📖 |
| TripoSG | 2025 | arXiv 2025 | VAE + rectified flow DiT for high-fidelity meshes | 📄 | 💻 | - | 📖 |
| MeshCraft | 2025 | arXiv 2025 | Face-token VAE + flow DiT for parallel mesh gen. | 📄 | - | - | 📖 |
Part-Aware
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| PAGENet | 2020 | AAAI 2020 | Part-aware generation network | - | - | - | 📖 |
| SAMPart3D | 2024 | arXiv 2024 | Multi-granularity zero-shot 3D part segmentation | - | - | - | 📖 |
| HoloPart | 2025 | arXiv 2025 | Amodal 3D part completion | - | - | - | 📖 |
| X-Part | 2025 | arXiv 2025 | Structure-coherent controllable shape decomposition | 📄 | - | - | 📖 |
| PartGen | 2025 | arXiv 2025 | Part-level multi-view diffusion generation | - | - | - | 📖 |
| PartCrafter | 2025 | arXiv 2025 | Part-wise 3D reconstruction and editing | - | - | - | 📖 |
| OmniPart | 2025 | arXiv 2025 | Unified part-aware reconstruction pipeline | - | - | - | 📖 |
Topology Generation
Indirect Methods (Post-hoc Remeshing)
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| Instant Meshes | 2015 | ACM TOG 2015 | Field-aligned instant quad/tri remeshing | - | 💻 | - | 📖 |
| QuadriFlow | 2018 | SGP 2018 | Scalable instant field-aligned quad remeshing | 📄 | 💻 | - | 📖 |
| NeurCross | 2025 | arXiv 2025 | Neural-guided cross-field remeshing | - | - | - | 📖 |
Direct Methods -- Autoregressive
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| PolyGen | 2020 | ICML 2020 | Pioneering vertex-then-face autoregressive mesh gen. | 📄 | 💻 | - | 📖 |
| MeshGPT | 2024 | ICLR 2024 | VQ-VAE codebook tokenization for mesh generation | 📄 | - | 🌐 | 📖 |
| MeshAnything | 2024 | arXiv 2024 | Shape-conditioned artist mesh extraction | 📄 | 💻 | - | 📖 |
| MeshAnything V2 | 2025 | arXiv 2025 | Adjacent mesh tokenization with improved compression | 📄 | 💻 | - | 📖 |
| Meshtron | 2024 | arXiv 2024 | Artist-like mesh generation at scale from artist-created data | 📄 | - | - | 📖 |
| PivotMesh | 2024 | arXiv 2024 | Coarse-to-fine mesh scaffolding | 📄 | 💻 | - | 📖 |
| EdgeRunner | 2024 | arXiv 2024 | Hybrid AR-latent mesh generation pipeline | 📄 | 💻 | - | 📖 |
| QuadGPT | 2025 | arXiv 2025 | Autoregressive quad-mesh generation for edge loops | 📄 | - | - | 📖 |
| DeepMesh | 2025 | ICCV 2025 | RL-based preference alignment for artist-quality mesh | 📄 | 💻 | - | 📖 |
| Mesh-RFT | 2025 | arXiv 2025 | Masked DPO for localized mesh defect correction | 📄 | - | - | 📖 |
Direct Methods -- Diffusion
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| PolyDiff | 2023 | ICCV 2023 | Discrete denoising diffusion over triangle soups | 📄 | - | - | 📖 |
| SpaceMesh | 2024 | arXiv 2024 | Continuous halfedge latent diffusion; ultra-fast | 📄 | - | - | 📖 |
| MeshCraft | 2025 | arXiv 2025 | Flow-based DiT with face-count control | 📄 | - | - | 📖 |
Appearance Generation
UV Unwrapping
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| xatlas | 2018 | Open-source | Production-baseline automatic UV atlas packer | - | 💻 | - | 📖 |
| UVAtlas | 2023 | Open-source | Production-baseline atlas generation for UV layout | - | 💻 | - | 📖 |
| Auto-UV | 2025 | arXiv 2025 | Learned seam prediction for UV unwrapping | - | - | - | 📖 |
| Flatten Anything | 2024 | arXiv 2024 | Unsupervised cycle-consistent UV mapping | - | - | - | 📖 |
| FlexPara | 2025 | arXiv 2025 | Flexible unsupervised UV parameterization | 📄 | - | - | 📖 |
| PartUV | 2025 | arXiv 2025 | Semantic chart-aligned UV partitioning | - | - | - | 📖 |
| ArtUV | 2025 | arXiv 2025 | Artist-style UV packing and layout | 📄 | - | - | 📖 |
| SeamCrafter | 2025 | arXiv 2025 | Seam preference optimization for UV quality | 📄 | - | - | 📖 |
| Hunyuan3D Studio | 2025 | arXiv 2025 | End-to-end game-ready asset pipeline with integrated UV construction | 📄 | - | - | 📖 |
Texture & PBR Material Generation
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| TEXTure | 2023 | SIGGRAPH 2023 | Iterative text-guided texture painting | 📄 | 💻 | - | 📖 |
| Text2Tex | 2023 | ICCV 2023 | Progressive inpainting for mesh texturing | 📄 | 💻 | - | 📖 |
| TexFusion | 2023 | arXiv 2023 | Cross-view aggregated texture fusion | 📄 | - | - | 📖 |
| Paint3D | 2024 | arXiv 2024 | Illumination-free texture diffusion for PBR | 📄 | 💻 | - | 📖 |
| FlashTex | 2024 | arXiv 2024 | Fast text-to-texture generation | 📄 | - | - | 📖 |
| TexGen | 2024 | arXiv 2024 | Feed-forward UV-space texture diffusion | - | - | - | 📖 |
| MVPaint | 2025 | arXiv 2025 | Multi-view consistent texture painting | 📄 | - | - | 📖 |
| MaterialMVP | 2025 | ICCV 2025 | Illumination-invariant multi-view PBR diffusion | - | - | - | 📖 |
| MaterialAnything | 2024 | arXiv 2024 | PBR material decomposition as first-class objective | 📄 | - | - | 📖 |
| 3DTopia-XL | 2024 | arXiv 2024 | Primitive diffusion for high-quality 3D assets with joint UV/PBR objectives | 📄 | 💻 | - | 📖 |
| Meta 3D AssetGen | 2024 | arXiv 2024 | Unified UV + geometry + PBR material pipeline | 📄 | - | - | 📖 |
| PBR3DGen | 2025 | arXiv 2025 | VLM-guided mesh generation with PBR materials | 📄 | - | - | 📖 |
Characters & Avatars
Structural Priors
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| SMPL | 2015 | SIGGRAPH Asia 2015 | Skinned multi-person linear body model | 📄 | - | - | 📖 |
| SMPL-X | 2019 | CVPR 2019 | Expressive body + hands + face parametric model | - | - | - | 📖 |
| FLAME | 2017 | SIGGRAPH Asia 2017 | Learned head model with expression blendshapes | - | - | - | 📖 |
Full-Body Synthesis
Parametric Template
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| Tex2Shape | 2019 | ICCV 2019 | UV-space displacement prediction on SMPL | - | - | - | 📖 |
| CAPE | 2020 | CVPR 2020 | Pose-dependent clothing offsets on body mesh | - | - | - | 📖 |
| ExPose | 2020 | ECCV 2020 | Monocular body + hands + face estimation | - | - | - | 📖 |
| STAR | 2020 | ECCV 2020 | Sparse parametric SMPL variant | - | - | - | 📖 |
| HybrIK | 2021 | CVPR 2021 | Hybrid analytical-regressive IK for body mesh | - | - | - | 📖 |
Implicit / Hybrid
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| PIFu | 2019 | ICCV 2019 | Pixel-aligned implicit function for clothed humans | - | - | - | 📖 |
| ARCH | 2020 | CVPR 2020 | Canonical implicit field with SMPL-guided rigging | - | - | - | 📖 |
| PIFuHD | 2020 | CVPR 2020 | Multi-level implicit for high-res human recon. | - | - | - | 📖 |
| PaMIR | 2021 | TPAMI 2021 | Parametric body model inside implicit recon. | - | - | - | 📖 |
| SMPLicit | 2021 | CVPR 2021 | Implicit clothing conditioned on SMPL parameters | 📄 | 💻 | - | 📖 |
| ICON | 2022 | CVPR 2022 | Normal-guided implicit body with SMPL | - | - | - | 📖 |
| gDNA | 2022 | ECCV 2022 | Generative implicit model for diverse humans | - | - | - | 📖 |
| ECON | 2023 | CVPR 2023 | Implicit + explicit mesh hybrid reconstruction | - | - | - | 📖 |
| S3F | 2023 | ICCV 2023 | Structured 3D features with SMPL semi-supervision | - | - | - | 📖 |
GAN / Diffusion Generative
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| StylePeople | 2021 | arXiv 2021 | GAN-based clothed mesh synthesis | - | - | - | 📖 |
| AvatarGen | 2022 | arXiv 2022 | SDF + tri-plane GAN for 3D avatars | - | - | - | 📖 |
| AvatarCLIP | 2022 | SIGGRAPH 2022 | CLIP-guided text-to-avatar generation | 📄 | 💻 | - | 📖 |
| Get3DHuman | 2023 | arXiv 2023 | Tri-plane/SDF GAN for full-body humans | 📄 | 💻 | - | 📖 |
| GETAvatar | 2023 | NeurIPS 2023 | GAN + SMPL for animatable textured mesh | - | - | - | 📖 |
| AvatarCraft | 2023 | arXiv 2023 | SDS-based NeRF-to-mesh avatar generation | - | - | - | 📖 |
| DreamHuman | 2023 | arXiv 2023 | SDS + imGHUM body prior for text-to-human | 📄 | - | - | 📖 |
| ChuPa | 2023 | arXiv 2023 | 2D diffusion on SMPL with displacement | - | - | - | 📖 |
| DreamAvatar | 2024 | arXiv 2024 | SDS + SMPL-guided NeRF avatar synthesis | - | - | - | 📖 |
| Morphable Diffusion | 2024 | CVPR 2024 | 3D-consistent diffusion for single-image avatar creation | 📄 | - | - | 📖 |
| SiTH | 2024 | CVPR 2024 | Single-view textured human reconstruction with image-conditioned diffusion | 📄 | - | - | 📖 |
| TADA! | 2024 | CVPR 2024 | SMPL-X + texture with LBS-ready rigging | 📄 | 💻 | - | 📖 |
Feed-Forward / Real-Time
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| InstantAvatar | 2023 | CVPR 2023 | Fast neural field from monocular video | - | - | - | 📖 |
| SHERF | 2023 | arXiv 2023 | Canonical-prior NeRF for generalizable humans | - | - | - | 📖 |
| LRM | 2023 | ICLR 2024 | Feed-forward large reconstruction model adapted to human body synthesis | 📄 | - | 🌐 | 📖 |
| Human GS | 2024 | arXiv 2024 | Canonical 3DGS with skinning from multi-view | - | - | - | 📖 |
| HUGS | 2024 | CVPR 2024 | 3DGS + SMPL for real-time avatar playback | - | - | - | 📖 |
| 3DGS-Avatar | 2024 | arXiv 2024 | Deformable 3DGS bound to skinning weights | 📄 | 💻 | - | 📖 |
| LHM | 2025 | arXiv 2025 | Dense Gaussians on SMPL; animatable in seconds | - | - | - | 📖 |
| OmniAvatar | 2025 | arXiv 2025 | Video diffusion for temporally coherent avatars | - | - | - | 📖 |
Head & Face Synthesis
Morphable + Neural
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| i3DMM | 2021 | arXiv 2021 | Implicit SDF-based 3D morphable model | - | - | - | 📖 |
| NerFace | 2021 | arXiv 2021 | NeRF with expression-conditioned deformation | - | - | - | 📖 |
| EG3D | 2022 | CVPR 2022 | Efficient tri-plane GAN for 3D face generation | - | - | - | 📖 |
| NPHM | 2023 | arXiv 2023 | Dual-SDF for identity + expression disentanglement | - | - | - | 📖 |
| Next3D | 2023 | CVPR 2023 | Tri-plane + texture rasterization with FLAME | - | - | - | 📖 |
| PanoHead | 2023 | CVPR 2023 | Depth-aware tri-grid for full 360-degree heads | - | - | - | 📖 |
| RODIN | 2023 | arXiv 2023 | Diffusion on tri-plane for novel-ID head generation | - | - | - | 📖 |
| HeadSculpt | 2023 | arXiv 2023 | SDS NeRF with SMPL-X prior for head sculpting | - | - | - | 📖 |
Mesh-Anchored Gaussians
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| GaussianAvatars | 2024 | CVPR 2024 | 3DGS bound to FLAME triangles for animation | - | - | - | 📖 |
| FlashAvatar | 2024 | arXiv 2024 | >300 FPS 3DGS + FLAME; production-ready | - | - | - | 📖 |
| MonoGaussianAvatar | 2024 | arXiv 2024 | Monocular-video 3DGS on FLAME mesh | - | - | - | 📖 |
| RGCA (Relightable) | 2024 | arXiv 2024 | Full PBR 3DGS decomposition for relighting | - | - | - | 📖 |
Feed-Forward Reconstruction
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| GAGAvatar | 2024 | arXiv 2024 | Generalizable 3DGS from single image with FLAME | - | - | - | 📖 |
| Arc2Avatar | 2025 | arXiv 2025 | Identity-guided single-image 3DGS head recon. | - | - | - | 📖 |
| HRAvatar | 2025 | arXiv 2025 | PBR 3DGS with roughness + Fresnel from mono video | - | - | - | 📖 |
| LAM | 2025 | arXiv 2025 | Large Avatar Model; 280 FPS, LBS-compatible | - | - | - | 📖 |
| Avat3r | 2025 | arXiv 2025 | Sparse-view canonical 3DGS via ViT | - | - | - | 📖 |
Rendering & Animation
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| SadTalker | 2023 | CVPR 2023 | Audio-to-FLAME coefficients for talking-head video | - | - | - | 📖 |
| HunyuanVideo-Avatar | 2025 | arXiv 2025 | High-fidelity audio-driven human animation for multiple characters | 📄 | - | - | 📖 |
| TexTalker | 2025 | arXiv 2025 | Audio-sync wrinkle maps + geometric deformation | - | - | - | 📖 |
Rigging & Skinning
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| RigNet | 2020 | SIGGRAPH 2020 | End-to-end GNN skeleton + skinning prediction | - | - | - | 📖 |
| SkinningNet | 2022 | arXiv 2022 | Two-stream GNN for heterogeneous skeletal topologies | - | - | - | 📖 |
| DeePSD | 2021 | arXiv 2021 | Unsupervised physics-based garment skinning | - | - | - | 📖 |
Note: TADA!, ChuPa, LAM, and HRAvatar also include rigging capabilities -- see above.
Scenes & Environments
Layout Generation
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| ATISS | 2021 | NeurIPS 2021 | Autoregressive transformer for room layouts | 📄 | 💻 | - | 📖 |
| ProcTHOR | 2022 | NeurIPS 2022 | Procedural interactive houses for embodied AI | - | 💻 | 🌐 | 📖 |
| Pose2Room | 2022 | arXiv 2022 | Activity-driven affordance-aware room layout | - | - | - | 📖 |
| DiffuScene | 2024 | arXiv 2024 | Diffusion + retrieval for furnished indoor scenes | 📄 | 💻 | - | 📖 |
| Holodeck | 2024 | CVPR 2024 | LLM-planned embodied environment generation | - | - | - | 📖 |
| LayoutGPT | 2023 | arXiv 2023 | LLM-generated indoor layouts from text | - | - | - | 📖 |
| LLplace | 2024 | arXiv 2024 | Dialogue-driven interactive layout editing | 📄 | - | - | 📖 |
| CityCraft | 2024 | arXiv 2024 | Language-guided city-scale layout generation | 📄 | - | - | 📖 |
Scene Population & Asset Grounding
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| MIME | 2023 | arXiv 2023 | Human-motion-informed object placement | - | - | - | 📖 |
| AnyHome | 2023 | arXiv 2023 | Open-vocabulary text-to-house scene generation | 📄 | - | - | 📖 |
| Open-Universe | 2024 | arXiv 2024 | LLM programs + solver for open-vocabulary scenes | 📄 | - | - | 📖 |
| SceneCraft | 2024 | arXiv 2024 | Blender code agent for executable scene scripts | - | - | - | 📖 |
| PhyScene | 2024 | arXiv 2024 | Physics-guided diffusion for interactable scenes | - | - | - | 📖 |
| UnrealLLM | 2025 | arXiv 2025 | Unreal Engine PCG agents from language | - | - | - | 📖 |
| Layout2Scene | 2025 | arXiv 2025 | Layout-guided diffusion for holistic scenes | 📄 | - | - | 📖 |
| 3D-GPT | 2023 | arXiv 2023 | Procedural modeling as language-conditioned programs | 📄 | 💻 | - | 📖 |
| PhysGen3D | 2025 | arXiv 2025 | Miniature interactive worlds with physics simulation | - | - | - | 📖 |
World-Scale Generation
| Method | Year | Venue | Highlight | 📄 | 💻 | 🌐 | 📖 |
|---|---|---|---|---|---|---|---|
| Text2Light | 2022 | arXiv 2022 | Text-conditioned HDR panorama for skybox/lighting | 📄 | 💻 | - | 📖 |
| Text2Room | 2023 | arXiv 2023 | 2D diffusion lifted to textured room meshes | 📄 | 💻 | - | 📖 |
| Infinigen | 2023 | CVPR 2023 | Photorealistic procedural natural world generation | - | - | - | 📖 |
| CityDreamer | 2024 | arXiv 2024 | Unbounded urban synthesis with stuff + thing fields | 📄 | 💻 | - | 📖 |
| Infinigen Indoors | 2024 | arXiv 2024 | Photorealistic procedural indoor worlds | - | - | - | 📖 |
| LayerPano3D | 2025 | arXiv 2025 | Layered panorama to explorable 3DGS scene | - | - | - | 📖 |
| WorldCraft | 2025 | arXiv 2025 | LLM-agentic world editing and customization | 📄 | - | - | 📖 |
Evaluation & Benchmarks
The survey identifies several complementary evaluation dimensions for production-ready 3D generation:
| Dimension | Metrics |
|---|---|
| Geometric Fidelity | Chamfer Distance (CD), Earth Mover's Distance (EMD), F-Score, Normal Consistency, Coverage (COV), Minimum Matching Distance (MMD), 1-NNA |
| Appearance Quality | PSNR, SSIM, LPIPS, FID, KID, CLIP Score, CLIP R-Precision |
| PBR / Relighting | Relighting consistency, albedo/roughness/metallic separation quality, paper-specific material decomposition tests |
| Asset Usability | UV stretch and angular distortion, seam visibility, chart packing efficiency, overlap detection, rig smoothness, retargeting success, engine import success |
| Topology Readiness | Manifoldness, watertightness, genus correctness, quad ratio, edge-flow alignment, collision-mesh quality |
| Scene-Level | Physical plausibility, interpenetration, NavMesh connectivity, navigation success rate, affordance compatibility, A/B preference, Likert ratings |
A key finding of this survey is that existing benchmarks systematically overestimate deployment readiness by focusing on geometric and appearance metrics while neglecting topology, UV/PBR, engine import, and other asset usability criteria required for interactive applications.
Industry & Companies
| Company | Key Product | Type | Link |
|---|---|---|---|
| Tripo AI | Tripo V2.5 | Closed | tripo3d.ai |
| Tencent | Hunyuan3D | Open + Closed | 3d.hunyuan.tencent.com |
| ByteDance | MVDream | Open | - |
| Meshy AI | Meshy 5 | Closed | meshy.ai |
| Deemos | Rodin Gen 1.5 | Closed | hyperhuman.deemos.com |
| DreamTech | - | Closed | dreamtech.com |
| Luma AI | Genie | Closed | lumalabs.ai |
| CSM AI | - | Closed | csm.ai |
| Stability AI | SF3D | Open | stability.ai |
| NVIDIA | Edify 3D | Closed | build.nvidia.com |
| SUDO AI | - | Closed | sudo.ai |
Citation
If you find this survey useful, please cite our paper:
@article{wu2026visual,
  title={From Visual Synthesis to Interactive Worlds: Toward Production-Ready 3D Asset Generation},
  author={Wu, Jiafeng and Lou, Zhuofan and Liu, Jian and Du, Dazhao and Guo, Chunchao and Guo, Song},
  journal={arXiv preprint arXiv:2604.23629},
  year={2026}
}
If you also use resources from the v1 collection, please additionally cite:
@article{liu2024comprehensive,
  title={A Comprehensive Survey on 3D Content Generation},
  author={Liu, Jian and Huang, Xiaoshui and Huang, Tianyu and Chen, Lu and Hou, Yuenan and Tang, Shixiang and Liu, Ziwei and Ouyang, Wanli and Zuo, Wangmeng and Jiang, Junjun and others},
  journal={arXiv preprint arXiv:2402.01166},
  year={2024}
}
Contributing
We welcome contributions! Please see CONTRIBUTING.md for guidelines.
Note: Pull requests should target the v2 branch. The
mainbranch preserves the original v1 awesome list.
Acknowledgments
This work was supported by The Hong Kong University of Science and Technology and Tencent.
v1 Paper Collection
The original awesome list curated is preserved on the main branch. It contains a broader collection of AIGC 3D papers organized by topic without the production-pipeline focus of v2.
Star History
Similar repos
Contributors
Languages
Python
100.0%