TextFlux: An OCR-Free DiT Model for High-Fidelity Multilingual Scene Text Synthesis
10
9 commits
3 linked in READMEs
updated Aug 6, 2025
README
TextFlux: An OCR-Free DiT Model for High-Fidelity Multilingual Scene Text Synthesis




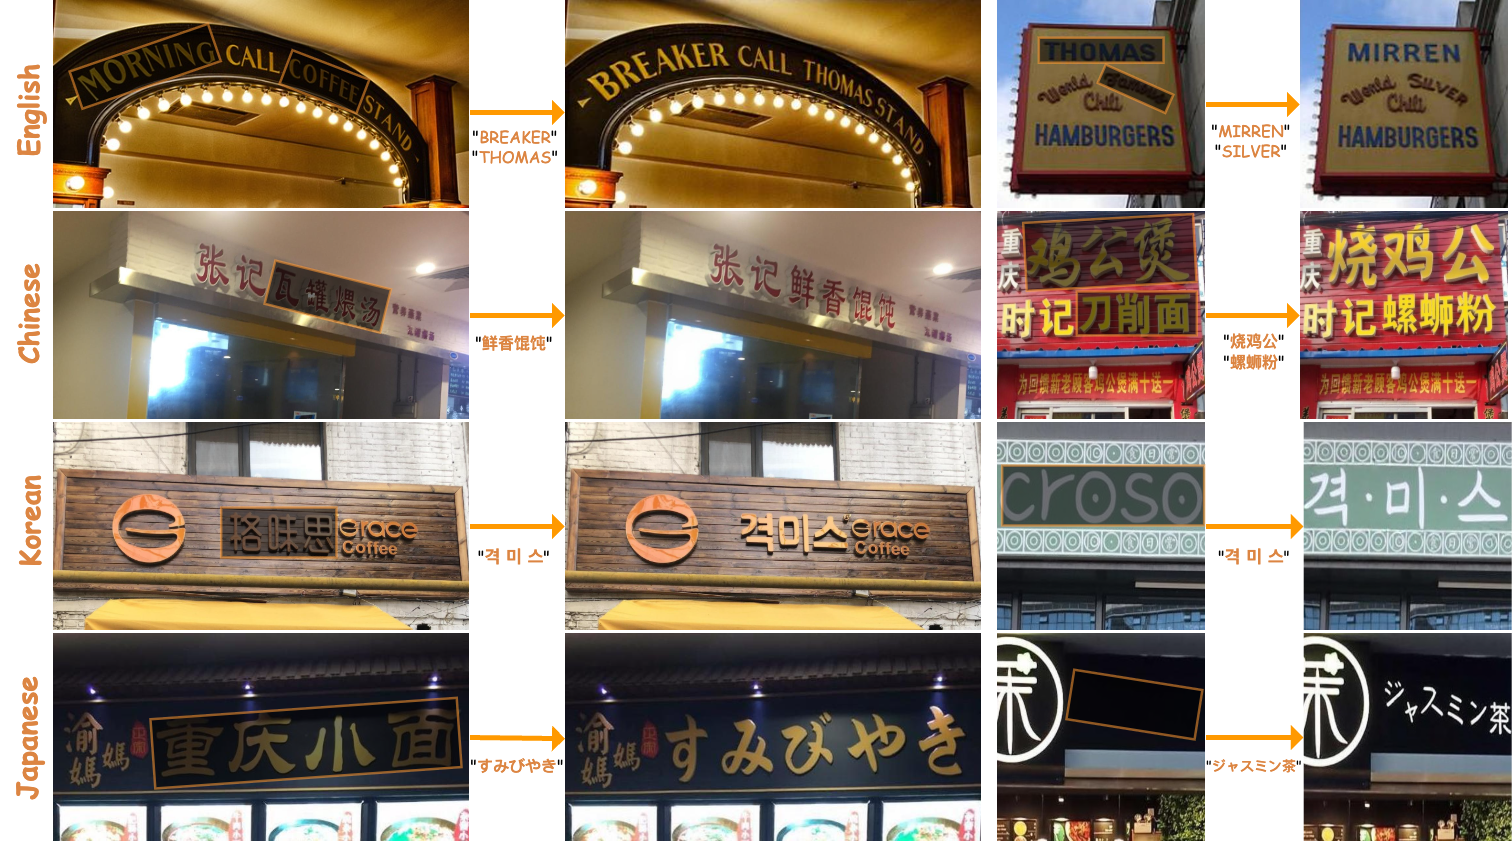
TextFlux is an OCR-free framework using a Diffusion Transformer (DiT, based on FLUX.1-Fill-dev) for high-fidelity multilingual scene text synthesis. It simplifies the learning task by providing direct visual glyph guidance through spatial concatenation of rendered glyphs with the scene image, enabling the model to focus on contextual reasoning and visual fusion.
Key Features
- OCR-Free: Simplified architecture without OCR encoders.
- High-Fidelity & Contextual Styles: Precise rendering, stylistically consistent with scenes.
- Multilingual & Low-Resource: Strong performance across languages, adapts to new languages with minimal data (e.g., <1,000 samples).
- Zero-Shot Generalization: Renders characters unseen during training.
- Controllable Multi-Line Text: Flexible multi-line synthesis with line-level control.
- Data Efficient: Uses a fraction of data (e.g., ~1%) compared to other methods.
Updates
2025/05/27: Our Full-Param Weights and LoRA Weights are now available 🤗!2025/05/25: Our Paper on ArXiv is available 🥳!
Setup
-
Clone/Download: Get the necessary code and model weights.
-
Dependencies:
conda create -n textflux python==3.11.4 -y
conda activate textflux
pip3 install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu118

pip install -r requirements.txt
# Ensure diffusers >= 0.32.1
Gradio Demo
Provides "Normal Mode" (for pre-combined inputs) and "Custom Mode" (upload scene, draw masks, input text for automatic template generation and concatenation).
python demo.py
Acknowledgement
Our code is modified based on Diffusers. We adopt black-forest-labs/FLUX.1-Fill-dev as the base model. Thanks to all the contributors for the helpful discussions!
License
The use of this model, TextFlux, is governed by the FLUX.1 [dev] Non-Commercial License Agreement (or the specific version applicable to FLUX.1-Fill-dev, upon which TextFlux is based).
Citation
@misc{xie2025textfluxocrfreeditmodel,
      title={TextFlux: An OCR-Free DiT Model for High-Fidelity Multilingual Scene Text Synthesis},
      author={Yu Xie and Jielei Zhang and Pengyu Chen and Ziyue Wang and Weihang Wang and Longwen Gao and Peiyi Li and Huyang Sun and Qiang Zhang and Qian Qiao and Jiaqing Fan and Zhouhui Lian},
      year={2025},
      eprint={2505.17778},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2505.17778},
}
Contributors

9 commits
Similar repos





Linked in READMEs


TextFlux: An OCR-Free DiT Model for High-Fidelity Multilingual Scene Text Synthesis
10
9 commits
3 linked in READMEs
updated Aug 6, 2025
README
TextFlux: An OCR-Free DiT Model for High-Fidelity Multilingual Scene Text Synthesis
TextFlux is an OCR-free framework using a Diffusion Transformer (DiT, based on FLUX.1-Fill-dev) for high-fidelity multilingual scene text synthesis. It simplifies the learning task by providing direct visual glyph guidance through spatial concatenation of rendered glyphs with the scene image, enabling the model to focus on contextual reasoning and visual fusion.
Key Features
- OCR-Free: Simplified architecture without OCR encoders.
- High-Fidelity & Contextual Styles: Precise rendering, stylistically consistent with scenes.
- Multilingual & Low-Resource: Strong performance across languages, adapts to new languages with minimal data (e.g., <1,000 samples).
- Zero-Shot Generalization: Renders characters unseen during training.
- Controllable Multi-Line Text: Flexible multi-line synthesis with line-level control.
- Data Efficient: Uses a fraction of data (e.g., ~1%) compared to other methods.
Updates
2025/05/27: Our Full-Param Weights and LoRA Weights are now available 🤗!2025/05/25: Our Paper on ArXiv is available 🥳!
Setup
-
Clone/Download: Get the necessary code and model weights.
-
Dependencies:
conda create -n textflux python==3.11.4 -y
conda activate textflux
pip3 install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu118

pip install -r requirements.txt
# Ensure diffusers >= 0.32.1
Gradio Demo
Provides "Normal Mode" (for pre-combined inputs) and "Custom Mode" (upload scene, draw masks, input text for automatic template generation and concatenation).
python demo.py
Acknowledgement
Our code is modified based on Diffusers. We adopt black-forest-labs/FLUX.1-Fill-dev as the base model. Thanks to all the contributors for the helpful discussions!
License
The use of this model, TextFlux, is governed by the FLUX.1 [dev] Non-Commercial License Agreement (or the specific version applicable to FLUX.1-Fill-dev, upon which TextFlux is based).
Citation
@misc{xie2025textfluxocrfreeditmodel,
      title={TextFlux: An OCR-Free DiT Model for High-Fidelity Multilingual Scene Text Synthesis},
      author={Yu Xie and Jielei Zhang and Pengyu Chen and Ziyue Wang and Weihang Wang and Longwen Gao and Peiyi Li and Huyang Sun and Qiang Zhang and Qian Qiao and Jiaqing Fan and Zhouhui Lian},
      year={2025},
      eprint={2505.17778},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2505.17778},
}
Similar repos
Linked in READMEs
Contributors
9 commits