Efficient Physical-World Agents
Tencent Robotics X × Hy Vision Team × Futian Laboratory


[2026-07-15] 🚀 We have released Hy-Embodied-VLM-1.0! An efficient Mixture-of-Experts vision–language foundation model for embodied agents in the physical world, activating only ~3B parameters per token (~30B total) for high inference efficiency. Weights are available on Hugging Face, together with inference code for both HuggingFace transformers and vLLM.[2026-06-15] 🤖 We have released HY-VLA-0.5! The official code, UMI-trained weights and 2000+ hours of high-fidelity UMI data are now available.[2026-04-09] 🚀 We have released HY-Embodied-0.5, featuring the open-sourced HY-Embodied-0.5 MoT-2B weights on Hugging Face along with the official inference code!Building capable embodied agents requires not only multimodal perception and understanding, but also agentic capabilities for reasoning about actions, adapting to evolving situations, and interacting with the physical world. In this report, we introduce Hy-Embodied-VLM-1.0, an efficient and powerful embodied foundation model specifically designed for embodied agents operating in the physical world.
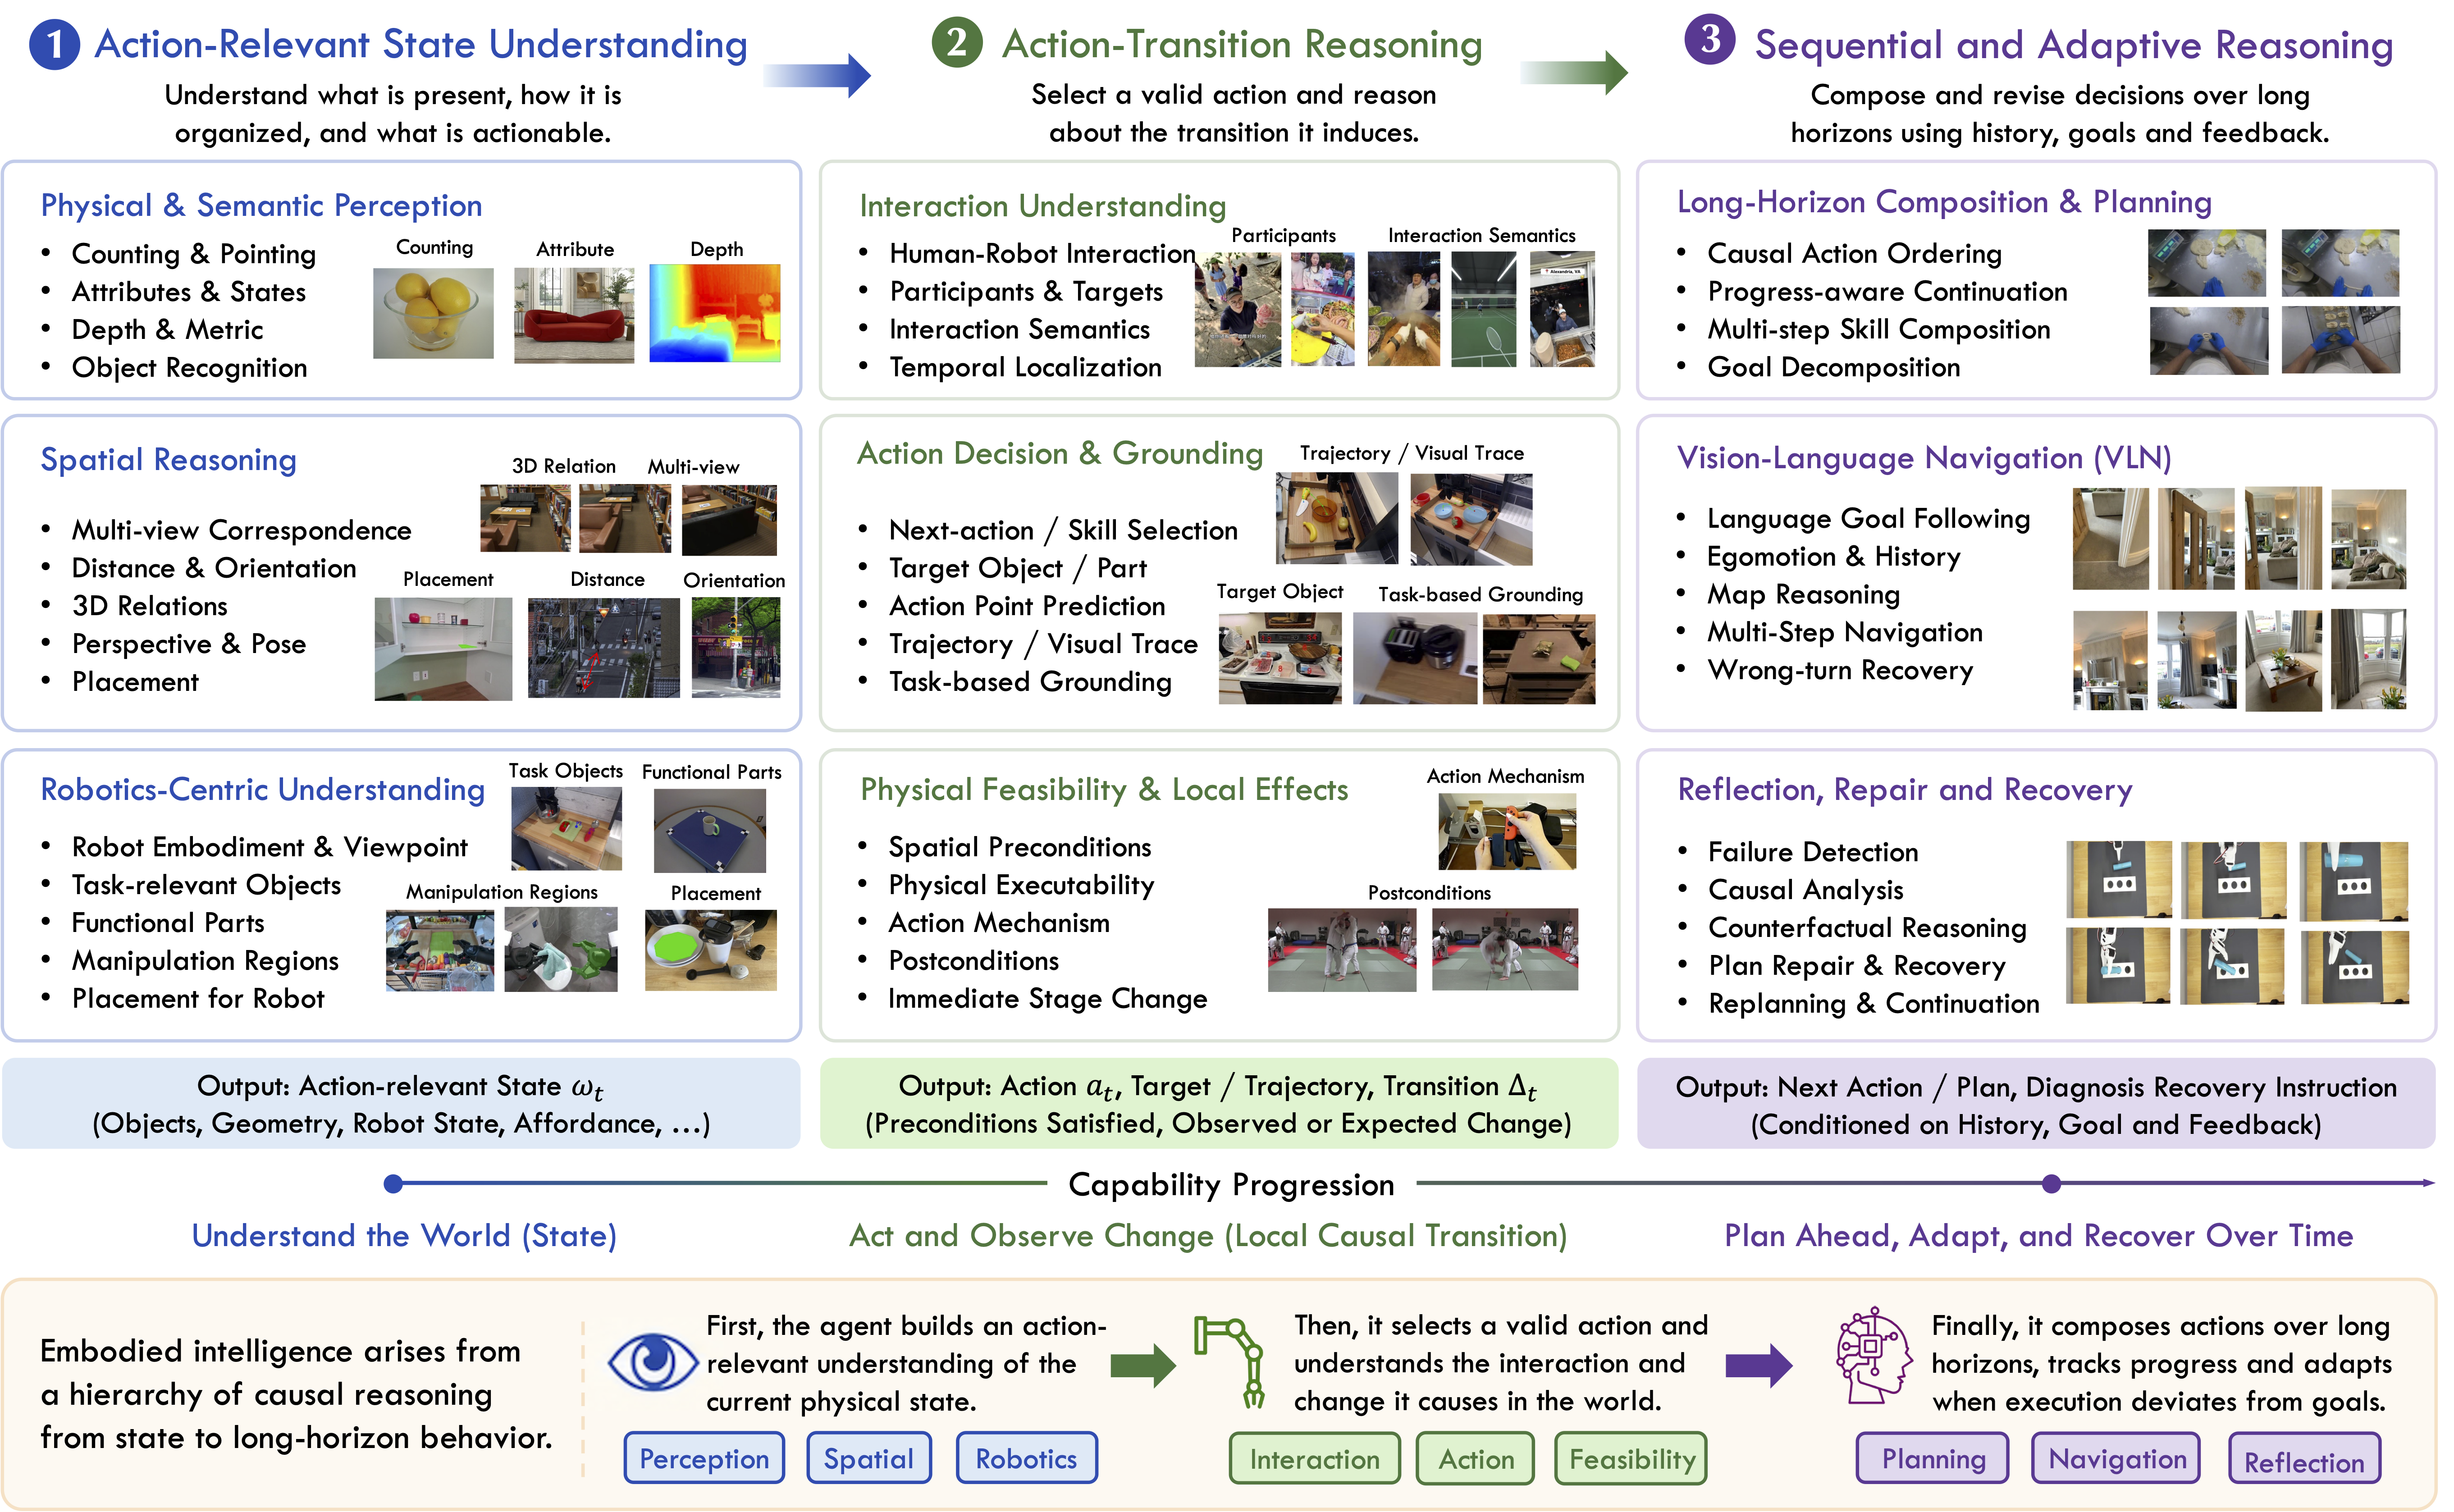
To cultivate such capabilities from the pre-training stage onward, we define an action-centric capability taxonomy comprising three progressive dimensions: Action-Relevant State Understanding, Action–Transition Reasoning, and Sequential and Adaptive Reasoning. Guided by this taxonomy, we develop a systematic data pipeline and curate data mixtures spanning both pre-training and post-training.
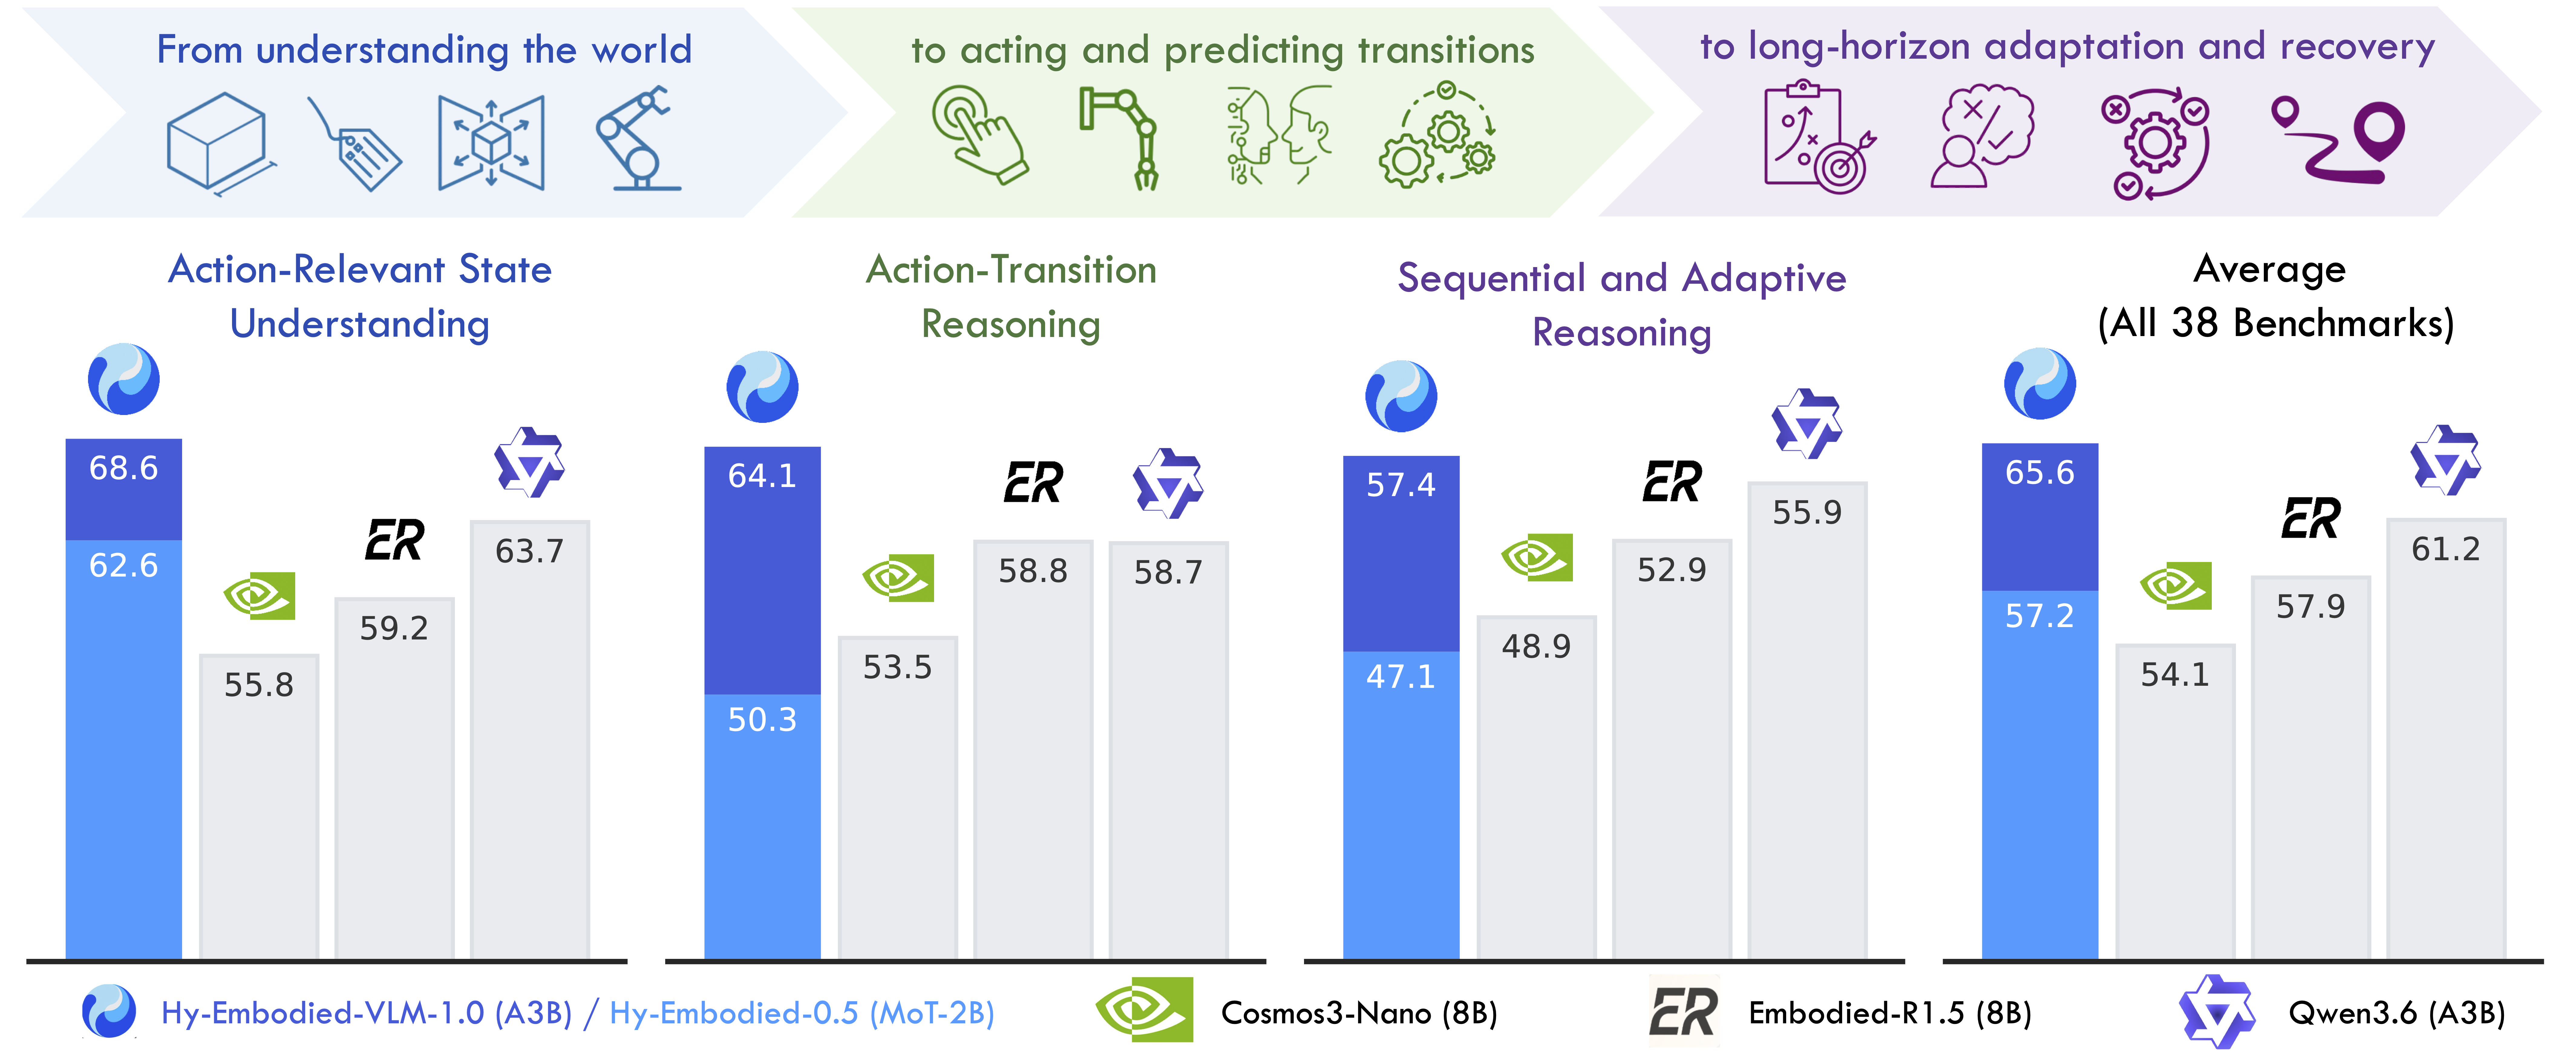
To deliver strong physical-world understanding and interaction capabilities while supporting latency-sensitive deployment, we build our model on the Hy3-A3B language backbone and the Hy-ViT2 vision encoder. Its efficient Mixture-of-Experts architecture combines strong model capacity with high inference efficiency. We evaluate Hy-Embodied-VLM-1.0 on a comprehensive suite of 38 benchmarks covering embodied perception, physical-world understanding, and embodied reasoning. The model achieves the best performance among similarly sized models on 19 of the 38 benchmarks and substantially outperforms strong competitors, including Qwen3.6-A3B and Cosmos 3. Compared with the previous-generation Hy-Embodied-0.5 MoT-2B, Hy-Embodied-VLM-1.0 improves average performance by 8.4%. Despite activating only 3B parameters, it achieves performance close to that of the previous-generation model with 32B activated parameters. Beyond static benchmark evaluation, Hy-Embodied-VLM-1.0 also demonstrates strong performance on embodied agentic tasks requiring multi-turn interaction and long-horizon reasoning.
| Field | Value |
|---|---|
| Architecture | HYV3VLForConditionalGeneration (VL wrapper over HYV3ForCausalLM MoE LLM + Hy-ViT2 vision encoder) |
| Model type | hy_v3_vl |
| Total parameters | ~30B |
| Activated parameters per token | ~3B (8 of 128 experts + 1 shared) |
| Context length | 32,768 tokens |
| Precision | BF16 |
| Vision inputs | Image (up to 128 per prompt); native aspect ratios |
| Chat template | Unified chat_template.jinja bundled with weights (supports enable_thinking kwarg) |
We pin dependencies to the versions we validated end-to-end
(vllm==0.14.1 + transformers==4.57.6 + torch==2.9.1). The cleanest
way to install these — with the CUDA build matched to your driver — is
uv:
# Install uv once (skip if you already have it)
curl -LsSf https://astral.sh/uv/install.sh | sh

# Create a fresh venv (Python 3.10+)
uv venv --python 3.12
source .venv/bin/activate

# Clone the repo (provides the vLLM plugin and example scripts)
git clone https://github.com/Tencent-Hunyuan/HY-Embodied
cd HY-Embodied
vLLM is the recommended path for serving Hy-Embodied-VLM-1.0. Install
vLLM together with matched torch/transformers wheels, then install this
repo's plugin (registers the HYV3VL model and the reasoning / tool-call
parsers):
# One-shot install: vllm + torch + torchvision + transformers at matching
# versions, with the CUDA build picked from your driver.
uv pip install vllm==0.14.1 --torch-backend auto

# Install this repo's vLLM plugin (registers HYV3VL model + parsers)
uv pip install -e Hy-Embodied-VLM-1.0/inference/vllm/
serve.sh wraps vllm serve with the required flags
(--reasoning-parser hunyuan_v3, --tool-call-parser hy_v3,
--trust-remote-code, image mm-limit, chat template). It defaults to the
Hub id tencent/Hy-Embodied-VLM-1.0, so no manual download is needed:
# TP=4 by default; override MODEL_PATH / TP / PORT via env vars.
bash Hy-Embodied-VLM-1.0/inference/vllm/serve.sh
curl http://127.0.0.1:8080/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "hy_a3b",
    "messages": [{"role": "user", "content": "Describe how to grasp a cup."}],
    "max_tokens": 512,
    "chat_template_kwargs": {"enable_thinking": true}
  }'
import base64
from pathlib import Path
from openai import OpenAI  # pip install "openai>=1.30" pillow

client = OpenAI(base_url="http://127.0.0.1:8080/v1", api_key="EMPTY")

# --- text-only ---
resp = client.chat.completions.create(
    model="hy_a3b",
    messages=[{"role": "user", "content": "How do you open a fridge?"}],
    max_tokens=512,
    temperature=0.7,
    extra_body={"chat_template_kwargs": {"enable_thinking": True}},
)
msg = resp.choices[0].message
if getattr(msg, "reasoning_content", None):
    print("[thinking]", msg.reasoning_content)
print("[answer]  ", msg.content)

# --- image + text ---
def encode_image(path):
    mime = "image/jpeg" if path.lower().endswith((".jpg", ".jpeg")) else "image/png"
    return f"data:{mime};base64,{base64.b64encode(Path(path).read_bytes()).decode()}"

resp = client.chat.completions.create(
    model="hy_a3b",
    messages=[{
        "role": "user",
        "content": [
            {"type": "image_url", "image_url": {"url": encode_image("example.jpg")}},
            {"type": "text", "text": "Describe the image in detail."},
        ],
    }],
    max_tokens=1024,
    temperature=0.7,
    extra_body={"chat_template_kwargs": {"enable_thinking": True}},
)
print(resp.choices[0].message.content)
See Hy-Embodied-VLM-1.0/inference/vllm/README.md for full serving options and example_client.py for the complete client (including streaming).
transformers (single-instance)For single-instance / offline inference without a server:
uv pip install torch==2.9.1 torchvision==0.24.1 --torch-backend auto
uv pip install transformers==4.57.6 accelerate pillow

# Run the demo (single image + a small batch; thinking and non-thinking modes)
cd Hy-Embodied-VLM-1.0/inference/transformers
python infer_hf.py
Hy-Embodied-VLM-1.0 is a hybrid reasoning model. Both modes are trained into the same weights; selection is per-request via a chat-template kwarg.
enable_thinking | Prompt suffix | When to use |
|---|---|---|
True (default) | <think> | Complex spatial reasoning, planning, multi-step tasks |
False | <think></think> | Direct answers, low-latency single-turn Q&A |
We deliberately use
enable_thinking(Qwen3 convention) rather thanreasoning_effort. vLLM prior to v0.22 has a top-levelrequest.reasoning_effortfield that silently clobberschat_template_kwargs["reasoning_effort"](fixed by vllm-project/vllm#43401);enable_thinkingavoids the clobber and works across all vLLM versions.
Note: We evaluated Hy-Embodied-VLM-1.0 A3B across 38 embodied-relevant benchmarks against parameter-comparable state-of-the-art models. For detailed methodology, please refer to our technical report.
| Benchmark | Hy-Embodied 0.5 MoT-2B | Qwen3.6-A3B | Embodied-R1.5 8B | Cosmos3-Nano 8B | Hy-Embodied VLM-1.0 A3B |
|---|---|---|---|---|---|
| BLINK | 82.7 | 87.9 | 77.8 | 82.4 | 87.3 |
| CV-Bench | 89.2 | 88.6 | 86.8 | 88.0 | 89.7 |
| PixMo-Points | 51.4 | 57.5 | 57.1 | 59.8 | 64.6 |
| PointBench | 69.0 | 35.1 | 59.1 | 39.2 | 71.7 |
| Depth-InHouse | 45.7 | 63.0 | 52.0 | 47.0 | 67.6 |
| 3DSRBench | 57.0 | 49.9 | 42.6 | 31.9 | 52.6 |
| All-Angles-Bench | 55.1 | 64.0 | 48.4 | 51.9 | 63.4 |
| DA-2K | 92.3 | 81.4 | 80.5 | 82.8 | 83.2 |
| ERQA | 54.5 | 57.5 | 37.3 | 45.0 | 60.8 |
| EmbSpatial-Bench | 82.8 | 83.2 | 76.0 | 80.0 | 82.7 |
| MMSI-Bench | 33.2 | 41.9 | 29.8 | 34.0 | 41.8 |
| MindCube | 66.3 | 55.0 | 27.9 | 32.8 | 70.0 |
| SAT | 76.7 | 80.7 | 60.7 | 54.0 | 78.0 |
| SIBench-mini | 58.2 | 60.9 | 51.9 | 52.5 | 64.5 |
| SITE-Bench-Image | 62.7 | 71.7 | 60.3 | 59.6 | 72.3 |
| ViewSpatial-Bench | 53.1 | 49.0 | 43.7 | 52.0 | 53.3 |
| OpenEQA | 54.4 | 73.2 | 53.9 | 53.8 | 63.1 |
| PartAfford | 30.1 | 25.5 | 82.6 | 32.2 | 63.7 |
| RoboAfford | 73.5 | 66.7 | 60.6 | 76.2 | 71.5 |
| RoboRefIt | 82.8 | 78.5 | 77.2 | 55.4 | 88.2 |
| RefSpatial-Bench | 45.8 | 53.1 | 52.4 | 44.4 | 53.4 |
| RoboSpatial-Home | 55.7 | 70.9 | 69.1 | 58.3 | 69.4 |
| Where2Place | 68.0 | 70.0 | 73.0 | 71.0 | 65.0 |
| Benchmark | Hy-Embodied 0.5 MoT-2B | Qwen3.6-A3B | Embodied-R1.5 8B | Cosmos3-Nano 8B | Hy-Embodied VLM-1.0 A3B |
|---|---|---|---|---|---|
| FineBench | 56.9 | 76.9 | 67.1 | 63.5 | 80.3 |
| CrossHOI-Bench | 40.7 | 58.0 | 55.1 | 51.0 | 63.2 |
| PIO | 54.6 | 47.9 | 61.6 | 54.4 | 65.3 |
| VABench-Point | 26.0 | 50.5 | 61.4 | 45.2 | 59.7 |
| VABench-Visual-Trace | 75.0 | 80.3 | 89.8 | 81.6 | 79.7 |
| ShareRobot-Bench-Affordance | 26.8 | 28.2 | 25.2 | 23.0 | 26.7 |
| ShareRobot-Bench-Trajectory | 73.3 | 68.9 | 69.2 | 65.5 | 76.7 |
| RoboBench-MCQ | 49.2 | 59.1 | 41.1 | 43.5 | 61.2 |
| Benchmark | Hy-Embodied 0.5 MoT-2B | Qwen3.6-A3B | Embodied-R1.5 8B | Cosmos3-Nano 8B | Hy-Embodied VLM-1.0 A3B |
|---|---|---|---|---|---|
| SITE-Bench-Video | 63.5 | 71.1 | 59.1 | 57.6 | 69.2 |
| VSIBench | 60.5 | 57.5 | 59.2 | 50.4 | 58.9 |
| EgoPlan2 | 45.5 | 49.9 | 61.0 | 42.6 | 49.6 |
| Cosmos | 54.3 | 67.8 | 68.6 | 67.1 | 66.9 |
| VLABench | 16.2 | 49.9 | 39.4 | 48.9 | 51.1 |
| RoboBench-Planning | 54.2 | 53.9 | 39.4 | 41.5 | 54.9 |
| RoboFAC | 35.6 | 41.4 | 43.9 | 34.4 | 51.0 |
Note: Hy-Embodied variants and Qwen3.6-A3B are evaluated in thinking mode; Embodied-R1.5-8B is only available in its Instruct configuration; Cosmos3-Nano-8B is reported in non-thinking mode (enabling thinking substantially degrades its performance).
Prior releases of the Hy-Embodied family remain fully available:
| Version | Description | Location |
|---|---|---|
| Hy-Embodied-0.5 (MoT-2B) | The first release: MoT architecture, 2B activated params, tuned for edge deployment | Hy-Embodied-0.5/ |
| Hy-Embodied-0.5-VLA | UMI-trained VLA for real-robot manipulation | Tencent-Hunyuan/Hy-Embodied-0.5-VLA |
| Hy-Embodied-0.5-X | Extended variant with additional post-training | Tencent-Hunyuan/HY-Embodied-0.5-X |
Released under Apache License 2.0. See LICENSE.
If you find our work useful for your research and applications, please cite our tech reports using this BibTeX:
@article{tencent2026hyembodiedvlm10,
  title         = {Hy-Embodied-VLM-1.0: Efficient Physical-World Agents},
  author        = {Wang, Ziyi and Yu, Xumin and Rao, Yongming and Ling, Yonggen and Li, Yunheng and Wang, Oran and Gao, Mingqi and Zhou, Yuchen and Liang, Yves and Liu, Zuyan and others},
  year          = {2026},
  eprint        = {2607.12894},
  archivePrefix = {arXiv},
  url           = {https://arxiv.org/abs/2607.12894}
}

@article{tencent2026hyembodied05,
  title         = {HY-Embodied-0.5: Embodied Foundation Models for Real-World Agents},
  author        = {Team, HY and Yu, Xumin and Liu, Zuyan and Wang, Ziyi and Zhang, He and Rao, Yongming and Liu, Fangfu and Zhang, Yani and Zhao, Ruowen and Wang, Oran and others},
  year          = {2026},
  eprint        = {2604.07430},
  archivePrefix = {arXiv},
  url           = {https://arxiv.org/abs/2604.07430}
}
Built on the Hy3 MoE LLM backbone and the Hy-ViT2 vision encoder. We thank the broader Tencent Hunyuan and Robotics X communities for infrastructure, evaluation resources, and design feedback.
Efficient Physical-World Agents
Tencent Robotics X × Hy Vision Team × Futian Laboratory
[2026-07-15] 🚀 We have released Hy-Embodied-VLM-1.0! An efficient Mixture-of-Experts vision–language foundation model for embodied agents in the physical world, activating only ~3B parameters per token (~30B total) for high inference efficiency. Weights are available on Hugging Face, together with inference code for both HuggingFace transformers and vLLM.[2026-06-15] 🤖 We have released HY-VLA-0.5! The official code, UMI-trained weights and 2000+ hours of high-fidelity UMI data are now available.[2026-04-09] 🚀 We have released HY-Embodied-0.5, featuring the open-sourced HY-Embodied-0.5 MoT-2B weights on Hugging Face along with the official inference code!Building capable embodied agents requires not only multimodal perception and understanding, but also agentic capabilities for reasoning about actions, adapting to evolving situations, and interacting with the physical world. In this report, we introduce Hy-Embodied-VLM-1.0, an efficient and powerful embodied foundation model specifically designed for embodied agents operating in the physical world.
To cultivate such capabilities from the pre-training stage onward, we define an action-centric capability taxonomy comprising three progressive dimensions: Action-Relevant State Understanding, Action–Transition Reasoning, and Sequential and Adaptive Reasoning. Guided by this taxonomy, we develop a systematic data pipeline and curate data mixtures spanning both pre-training and post-training.
To deliver strong physical-world understanding and interaction capabilities while supporting latency-sensitive deployment, we build our model on the Hy3-A3B language backbone and the Hy-ViT2 vision encoder. Its efficient Mixture-of-Experts architecture combines strong model capacity with high inference efficiency. We evaluate Hy-Embodied-VLM-1.0 on a comprehensive suite of 38 benchmarks covering embodied perception, physical-world understanding, and embodied reasoning. The model achieves the best performance among similarly sized models on 19 of the 38 benchmarks and substantially outperforms strong competitors, including Qwen3.6-A3B and Cosmos 3. Compared with the previous-generation Hy-Embodied-0.5 MoT-2B, Hy-Embodied-VLM-1.0 improves average performance by 8.4%. Despite activating only 3B parameters, it achieves performance close to that of the previous-generation model with 32B activated parameters. Beyond static benchmark evaluation, Hy-Embodied-VLM-1.0 also demonstrates strong performance on embodied agentic tasks requiring multi-turn interaction and long-horizon reasoning.
| Field | Value |
|---|---|
| Architecture | HYV3VLForConditionalGeneration (VL wrapper over HYV3ForCausalLM MoE LLM + Hy-ViT2 vision encoder) |
| Model type | hy_v3_vl |
| Total parameters | ~30B |
| Activated parameters per token | ~3B (8 of 128 experts + 1 shared) |
| Context length | 32,768 tokens |
| Precision | BF16 |
| Vision inputs | Image (up to 128 per prompt); native aspect ratios |
| Chat template | Unified chat_template.jinja bundled with weights (supports enable_thinking kwarg) |
We pin dependencies to the versions we validated end-to-end
(vllm==0.14.1 + transformers==4.57.6 + torch==2.9.1). The cleanest
way to install these — with the CUDA build matched to your driver — is
uv:
# Install uv once (skip if you already have it)
curl -LsSf https://astral.sh/uv/install.sh | sh

# Create a fresh venv (Python 3.10+)
uv venv --python 3.12
source .venv/bin/activate

# Clone the repo (provides the vLLM plugin and example scripts)
git clone https://github.com/Tencent-Hunyuan/HY-Embodied
cd HY-Embodied
vLLM is the recommended path for serving Hy-Embodied-VLM-1.0. Install
vLLM together with matched torch/transformers wheels, then install this
repo's plugin (registers the HYV3VL model and the reasoning / tool-call
parsers):
# One-shot install: vllm + torch + torchvision + transformers at matching
# versions, with the CUDA build picked from your driver.
uv pip install vllm==0.14.1 --torch-backend auto

# Install this repo's vLLM plugin (registers HYV3VL model + parsers)
uv pip install -e Hy-Embodied-VLM-1.0/inference/vllm/
serve.sh wraps vllm serve with the required flags
(--reasoning-parser hunyuan_v3, --tool-call-parser hy_v3,
--trust-remote-code, image mm-limit, chat template). It defaults to the
Hub id tencent/Hy-Embodied-VLM-1.0, so no manual download is needed:
# TP=4 by default; override MODEL_PATH / TP / PORT via env vars.
bash Hy-Embodied-VLM-1.0/inference/vllm/serve.sh
curl http://127.0.0.1:8080/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "hy_a3b",
    "messages": [{"role": "user", "content": "Describe how to grasp a cup."}],
    "max_tokens": 512,
    "chat_template_kwargs": {"enable_thinking": true}
  }'
import base64
from pathlib import Path
from openai import OpenAI  # pip install "openai>=1.30" pillow

client = OpenAI(base_url="http://127.0.0.1:8080/v1", api_key="EMPTY")

# --- text-only ---
resp = client.chat.completions.create(
    model="hy_a3b",
    messages=[{"role": "user", "content": "How do you open a fridge?"}],
    max_tokens=512,
    temperature=0.7,
    extra_body={"chat_template_kwargs": {"enable_thinking": True}},
)
msg = resp.choices[0].message
if getattr(msg, "reasoning_content", None):
    print("[thinking]", msg.reasoning_content)
print("[answer]  ", msg.content)

# --- image + text ---
def encode_image(path):
    mime = "image/jpeg" if path.lower().endswith((".jpg", ".jpeg")) else "image/png"
    return f"data:{mime};base64,{base64.b64encode(Path(path).read_bytes()).decode()}"

resp = client.chat.completions.create(
    model="hy_a3b",
    messages=[{
        "role": "user",
        "content": [
            {"type": "image_url", "image_url": {"url": encode_image("example.jpg")}},
            {"type": "text", "text": "Describe the image in detail."},
        ],
    }],
    max_tokens=1024,
    temperature=0.7,
    extra_body={"chat_template_kwargs": {"enable_thinking": True}},
)
print(resp.choices[0].message.content)
See Hy-Embodied-VLM-1.0/inference/vllm/README.md for full serving options and example_client.py for the complete client (including streaming).
transformers (single-instance)For single-instance / offline inference without a server:
uv pip install torch==2.9.1 torchvision==0.24.1 --torch-backend auto
uv pip install transformers==4.57.6 accelerate pillow

# Run the demo (single image + a small batch; thinking and non-thinking modes)
cd Hy-Embodied-VLM-1.0/inference/transformers
python infer_hf.py
Hy-Embodied-VLM-1.0 is a hybrid reasoning model. Both modes are trained into the same weights; selection is per-request via a chat-template kwarg.
enable_thinking | Prompt suffix | When to use |
|---|---|---|
True (default) | <think> | Complex spatial reasoning, planning, multi-step tasks |
False | <think></think> | Direct answers, low-latency single-turn Q&A |
We deliberately use
enable_thinking(Qwen3 convention) rather thanreasoning_effort. vLLM prior to v0.22 has a top-levelrequest.reasoning_effortfield that silently clobberschat_template_kwargs["reasoning_effort"](fixed by vllm-project/vllm#43401);enable_thinkingavoids the clobber and works across all vLLM versions.
Note: We evaluated Hy-Embodied-VLM-1.0 A3B across 38 embodied-relevant benchmarks against parameter-comparable state-of-the-art models. For detailed methodology, please refer to our technical report.
| Benchmark | Hy-Embodied 0.5 MoT-2B | Qwen3.6-A3B | Embodied-R1.5 8B | Cosmos3-Nano 8B | Hy-Embodied VLM-1.0 A3B |
|---|---|---|---|---|---|
| BLINK | 82.7 | 87.9 | 77.8 | 82.4 | 87.3 |
| CV-Bench | 89.2 | 88.6 | 86.8 | 88.0 | 89.7 |
| PixMo-Points | 51.4 | 57.5 | 57.1 | 59.8 | 64.6 |
| PointBench | 69.0 | 35.1 | 59.1 | 39.2 | 71.7 |
| Depth-InHouse | 45.7 | 63.0 | 52.0 | 47.0 | 67.6 |
| 3DSRBench | 57.0 | 49.9 | 42.6 | 31.9 | 52.6 |
| All-Angles-Bench | 55.1 | 64.0 | 48.4 | 51.9 | 63.4 |
| DA-2K | 92.3 | 81.4 | 80.5 | 82.8 | 83.2 |
| ERQA | 54.5 | 57.5 | 37.3 | 45.0 | 60.8 |
| EmbSpatial-Bench | 82.8 | 83.2 | 76.0 | 80.0 | 82.7 |
| MMSI-Bench | 33.2 | 41.9 | 29.8 | 34.0 | 41.8 |
| MindCube | 66.3 | 55.0 | 27.9 | 32.8 | 70.0 |
| SAT | 76.7 | 80.7 | 60.7 | 54.0 | 78.0 |
| SIBench-mini | 58.2 | 60.9 | 51.9 | 52.5 | 64.5 |
| SITE-Bench-Image | 62.7 | 71.7 | 60.3 | 59.6 | 72.3 |
| ViewSpatial-Bench | 53.1 | 49.0 | 43.7 | 52.0 | 53.3 |
| OpenEQA | 54.4 | 73.2 | 53.9 | 53.8 | 63.1 |
| PartAfford | 30.1 | 25.5 | 82.6 | 32.2 | 63.7 |
| RoboAfford | 73.5 | 66.7 | 60.6 | 76.2 | 71.5 |
| RoboRefIt | 82.8 | 78.5 | 77.2 | 55.4 | 88.2 |
| RefSpatial-Bench | 45.8 | 53.1 | 52.4 | 44.4 | 53.4 |
| RoboSpatial-Home | 55.7 | 70.9 | 69.1 | 58.3 | 69.4 |
| Where2Place | 68.0 | 70.0 | 73.0 | 71.0 | 65.0 |
| Benchmark | Hy-Embodied 0.5 MoT-2B | Qwen3.6-A3B | Embodied-R1.5 8B | Cosmos3-Nano 8B | Hy-Embodied VLM-1.0 A3B |
|---|---|---|---|---|---|
| FineBench | 56.9 | 76.9 | 67.1 | 63.5 | 80.3 |
| CrossHOI-Bench | 40.7 | 58.0 | 55.1 | 51.0 | 63.2 |
| PIO | 54.6 | 47.9 | 61.6 | 54.4 | 65.3 |
| VABench-Point | 26.0 | 50.5 | 61.4 | 45.2 | 59.7 |
| VABench-Visual-Trace | 75.0 | 80.3 | 89.8 | 81.6 | 79.7 |
| ShareRobot-Bench-Affordance | 26.8 | 28.2 | 25.2 | 23.0 | 26.7 |
| ShareRobot-Bench-Trajectory | 73.3 | 68.9 | 69.2 | 65.5 | 76.7 |
| RoboBench-MCQ | 49.2 | 59.1 | 41.1 | 43.5 | 61.2 |
| Benchmark | Hy-Embodied 0.5 MoT-2B | Qwen3.6-A3B | Embodied-R1.5 8B | Cosmos3-Nano 8B | Hy-Embodied VLM-1.0 A3B |
|---|---|---|---|---|---|
| SITE-Bench-Video | 63.5 | 71.1 | 59.1 | 57.6 | 69.2 |
| VSIBench | 60.5 | 57.5 | 59.2 | 50.4 | 58.9 |
| EgoPlan2 | 45.5 | 49.9 | 61.0 | 42.6 | 49.6 |
| Cosmos | 54.3 | 67.8 | 68.6 | 67.1 | 66.9 |
| VLABench | 16.2 | 49.9 | 39.4 | 48.9 | 51.1 |
| RoboBench-Planning | 54.2 | 53.9 | 39.4 | 41.5 | 54.9 |
| RoboFAC | 35.6 | 41.4 | 43.9 | 34.4 | 51.0 |
Note: Hy-Embodied variants and Qwen3.6-A3B are evaluated in thinking mode; Embodied-R1.5-8B is only available in its Instruct configuration; Cosmos3-Nano-8B is reported in non-thinking mode (enabling thinking substantially degrades its performance).
Prior releases of the Hy-Embodied family remain fully available:
| Version | Description | Location |
|---|---|---|
| Hy-Embodied-0.5 (MoT-2B) | The first release: MoT architecture, 2B activated params, tuned for edge deployment | Hy-Embodied-0.5/ |
| Hy-Embodied-0.5-VLA | UMI-trained VLA for real-robot manipulation | Tencent-Hunyuan/Hy-Embodied-0.5-VLA |
| Hy-Embodied-0.5-X | Extended variant with additional post-training | Tencent-Hunyuan/HY-Embodied-0.5-X |
Released under Apache License 2.0. See LICENSE.
If you find our work useful for your research and applications, please cite our tech reports using this BibTeX:
@article{tencent2026hyembodiedvlm10,
  title         = {Hy-Embodied-VLM-1.0: Efficient Physical-World Agents},
  author        = {Wang, Ziyi and Yu, Xumin and Rao, Yongming and Ling, Yonggen and Li, Yunheng and Wang, Oran and Gao, Mingqi and Zhou, Yuchen and Liang, Yves and Liu, Zuyan and others},
  year          = {2026},
  eprint        = {2607.12894},
  archivePrefix = {arXiv},
  url           = {https://arxiv.org/abs/2607.12894}
}

@article{tencent2026hyembodied05,
  title         = {HY-Embodied-0.5: Embodied Foundation Models for Real-World Agents},
  author        = {Team, HY and Yu, Xumin and Liu, Zuyan and Wang, Ziyi and Zhang, He and Rao, Yongming and Liu, Fangfu and Zhang, Yani and Zhao, Ruowen and Wang, Oran and others},
  year          = {2026},
  eprint        = {2604.07430},
  archivePrefix = {arXiv},
  url           = {https://arxiv.org/abs/2604.07430}
}
Built on the Hy3 MoE LLM backbone and the Hy-ViT2 vision encoder. We thank the broader Tencent Hunyuan and Robotics X communities for infrastructure, evaluation resources, and design feedback.




