
README
jiwo-0.8b
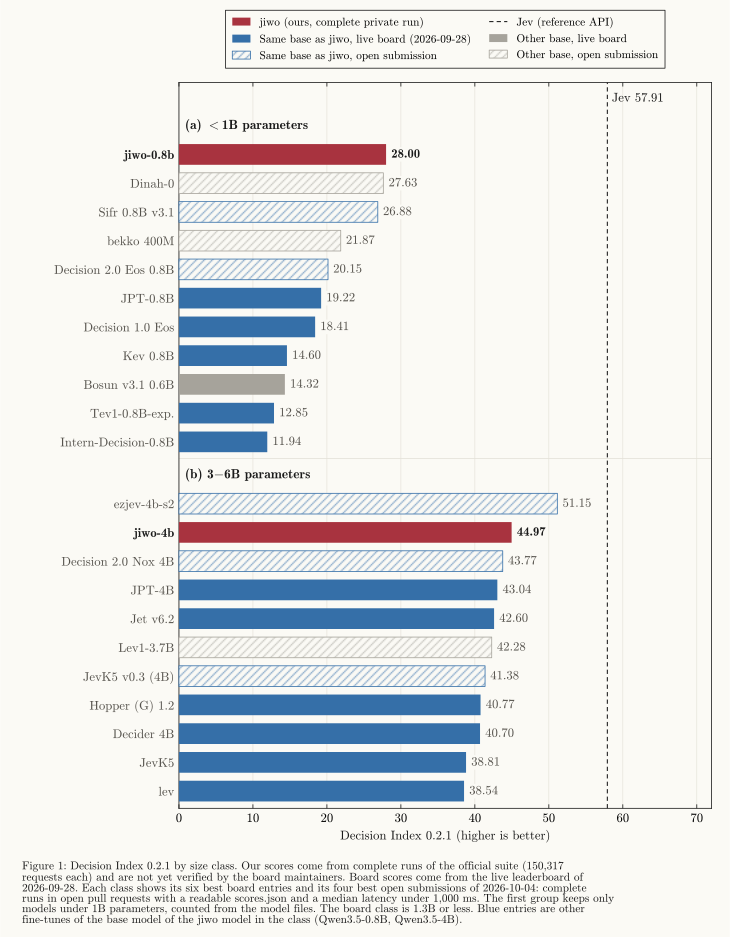
The highest Decision Index score of all models under 1B parameters (28.00): 1st of 33 on the live board and in open submissions, and ahead of every other Qwen3.5-0.8B fine-tune.
jiwo-0.8b is a decision model. It reads a state and one or more typed questions. For each question, it returns a probability for every option in one forward pass. It does not generate text.
The request and response format is the format of TypeSafe's Jev API (POST /v1/systemone). jiwo is an independent
project. TypeSafe does not endorse it.
| Base model | Qwen/Qwen3.5-0.8B |
| Parameters | 0.75B |
| Weights | Full weights: decoder, tokenizer and readout |
| Question types | choice (at most 255 options), score (2 to 10 levels), noul (true or false) |
| Training context length | 8,192 tokens |
| Licence | Apache-2.0 |
Code, server and documentation: github.com/jiwidi/jiwo. The other model of the family is eljiwo/jiwo-4b.
Evaluation
| Benchmark | Result |
|---|---|
| Decision Index 0.2.1 | 28.00, 1st of 23 under 1B parameters on the live board of 2026-09-28, and 1st of 33 with open submissions¹ |
| Area skill ×100: knowledge / language / retrieval and classification / tools / arts | 10.3 / 32.3 / 44.5 / 38.0 / 11.2 |
| Untrained Qwen3.5-0.8B, same server and suite, temperatures fitted on the same calibration data | 6.99: +21.0 points for jiwo-0.8b |
| Best other Qwen3.5-0.8B fine-tune on the live board | JPT-0.8B, 19.22: +45.7% for jiwo-0.8b |
| Best other Qwen3.5-0.8B fine-tune, including open submissions¹ | Sifr 0.8B v3.1, 26.88: +4.2% for jiwo-0.8b |
| Median request latency on one H100 | 48 ms |
The score comes from a complete run of the suite (150,317 requests), served by jiwo serve with
JIWO_MAX_LENGTH=65536. The board maintainers did not verify it yet.
¹ Complete runs in open pull requests (as of 2026-10-04) with a readable scores.json and a median latency under 1,000 ms, the limit of the board. The board's smallest class is 1.3B parameters or less. In that class, one open submission scores higher: EXAONE-4.0-1.2B-JEV v0.3 (1.28B parameters, 30.29).
Use the model
pip install "jiwo @ git+https://github.com/jiwidi/jiwo" # on NVIDIA GPUs: "jiwo[cuda] @ git+..."
from jiwo.model import DecisionModel

model = DecisionModel.from_pretrained("eljiwo/jiwo-0.8b")
question = {"type": "noul", "instructions": "The customer is angry."}
response = model.decide("Refund please, the parcel arrived crushed.", {"angry": question})
print(response["answers"]["angry"]["noul"])  # the probability that the statement is true
Or serve it over HTTP. The server listens on 127.0.0.1:8765:
JIWO_CHECKPOINT=eljiwo/jiwo-0.8b jiwo serve
curl -s localhost:8765/v1/systemone -H 'content-type: application/json' -d '{
  "state": "Refund please, the parcel arrived crushed.",
  "questions": {
    "team":  {"type": "choice", "instructions": "Which team handles this?",
              "criteria": {"billing": "Payments and refunds", "shipping": "Damaged or lost parcels", "account": null}},
    "angry": {"type": "noul", "instructions": "The customer is angry."},
    "urgency": {"type": "score", "instructions": "How urgent is it?", "criteria": ["Not urgent", "Soon", "Now"]}}}'
The jiwo README describes the response, the errors and all settings.
Request format
A request has a state (a string, a JSON object or a JSON array) and at most 64 named questions.
| Type | Meaning | criteria |
|---|---|---|
choice | Pick one of N named options | An object that maps option keys to descriptions or null |
score | Rate the state on 2 to 10 ordered levels | A list of level descriptions, lowest level first |
noul | Decide whether a statement is true | Optional. Descriptions for the keys true and false |
How the model works
- The decoder of the base model reads one prompt for each (state, question) pair.
- A linear readout with one row per answer code (A, B, ..., Z, AA, ...) gives one logit for each option.
- A softmax with a fitted temperature for each question type gives the probabilities.
Training data
The model was fine-tuned on the train splits of public datasets and on synthetic data. The training data is mostly English.
Limits
- The training prompts had at most 8,192 tokens. By default, the server refuses a longer prompt with a 400 error.
You can set a larger
JIWO_MAX_LENGTH, but the model did not see longer prompts in training. - A
choicequestion can have at most 255 options. - The model was trained mostly on English. Other languages are not evaluated.
- The model gives probabilities, not explanations. Check its answers before you use them for decisions with a high cost.
Licence
Apache-2.0, the licence of the base model. See LICENSE.
Similar repos



README
jiwo-0.8b
The highest Decision Index score of all models under 1B parameters (28.00): 1st of 33 on the live board and in open submissions, and ahead of every other Qwen3.5-0.8B fine-tune.
jiwo-0.8b is a decision model. It reads a state and one or more typed questions. For each question, it returns a probability for every option in one forward pass. It does not generate text.
The request and response format is the format of TypeSafe's Jev API (POST /v1/systemone). jiwo is an independent
project. TypeSafe does not endorse it.
| Base model | Qwen/Qwen3.5-0.8B |
| Parameters | 0.75B |
| Weights | Full weights: decoder, tokenizer and readout |
| Question types | choice (at most 255 options), score (2 to 10 levels), noul (true or false) |
| Training context length | 8,192 tokens |
| Licence | Apache-2.0 |
Code, server and documentation: github.com/jiwidi/jiwo. The other model of the family is eljiwo/jiwo-4b.
Evaluation
| Benchmark | Result |
|---|---|
| Decision Index 0.2.1 | 28.00, 1st of 23 under 1B parameters on the live board of 2026-09-28, and 1st of 33 with open submissions¹ |
| Area skill ×100: knowledge / language / retrieval and classification / tools / arts | 10.3 / 32.3 / 44.5 / 38.0 / 11.2 |
| Untrained Qwen3.5-0.8B, same server and suite, temperatures fitted on the same calibration data | 6.99: +21.0 points for jiwo-0.8b |
| Best other Qwen3.5-0.8B fine-tune on the live board | JPT-0.8B, 19.22: +45.7% for jiwo-0.8b |
| Best other Qwen3.5-0.8B fine-tune, including open submissions¹ | Sifr 0.8B v3.1, 26.88: +4.2% for jiwo-0.8b |
| Median request latency on one H100 | 48 ms |
The score comes from a complete run of the suite (150,317 requests), served by jiwo serve with
JIWO_MAX_LENGTH=65536. The board maintainers did not verify it yet.
¹ Complete runs in open pull requests (as of 2026-10-04) with a readable scores.json and a median latency under 1,000 ms, the limit of the board. The board's smallest class is 1.3B parameters or less. In that class, one open submission scores higher: EXAONE-4.0-1.2B-JEV v0.3 (1.28B parameters, 30.29).
Use the model
pip install "jiwo @ git+https://github.com/jiwidi/jiwo" # on NVIDIA GPUs: "jiwo[cuda] @ git+..."
from jiwo.model import DecisionModel

model = DecisionModel.from_pretrained("eljiwo/jiwo-0.8b")
question = {"type": "noul", "instructions": "The customer is angry."}
response = model.decide("Refund please, the parcel arrived crushed.", {"angry": question})
print(response["answers"]["angry"]["noul"])  # the probability that the statement is true
Or serve it over HTTP. The server listens on 127.0.0.1:8765:
JIWO_CHECKPOINT=eljiwo/jiwo-0.8b jiwo serve
curl -s localhost:8765/v1/systemone -H 'content-type: application/json' -d '{
  "state": "Refund please, the parcel arrived crushed.",
  "questions": {
    "team":  {"type": "choice", "instructions": "Which team handles this?",
              "criteria": {"billing": "Payments and refunds", "shipping": "Damaged or lost parcels", "account": null}},
    "angry": {"type": "noul", "instructions": "The customer is angry."},
    "urgency": {"type": "score", "instructions": "How urgent is it?", "criteria": ["Not urgent", "Soon", "Now"]}}}'
The jiwo README describes the response, the errors and all settings.
Request format
A request has a state (a string, a JSON object or a JSON array) and at most 64 named questions.
| Type | Meaning | criteria |
|---|---|---|
choice | Pick one of N named options | An object that maps option keys to descriptions or null |
score | Rate the state on 2 to 10 ordered levels | A list of level descriptions, lowest level first |
noul | Decide whether a statement is true | Optional. Descriptions for the keys true and false |
How the model works
- The decoder of the base model reads one prompt for each (state, question) pair.
- A linear readout with one row per answer code (A, B, ..., Z, AA, ...) gives one logit for each option.
- A softmax with a fitted temperature for each question type gives the probabilities.
Training data
The model was fine-tuned on the train splits of public datasets and on synthetic data. The training data is mostly English.
Limits
- The training prompts had at most 8,192 tokens. By default, the server refuses a longer prompt with a 400 error.
You can set a larger
JIWO_MAX_LENGTH, but the model did not see longer prompts in training. - A
choicequestion can have at most 255 options. - The model was trained mostly on English. Other languages are not evaluated.
- The model gives probabilities, not explanations. Check its answers before you use them for decisions with a high cost.
Licence
Apache-2.0, the licence of the base model. See LICENSE.