InSTA: Towards Internet-Scale Training For Agents
19
6 commits
2 linked in READMEs
updated May 28, 2025
README
InSTA: Towards Internet-Scale Training For Agents
Brandon Trabucco (1) Gunnar Sigurdsson (2) Robinson Piramuthu (2) Ruslan Salakhutdinov (1)
(1) Carnegie Mellon University, Machine Learning Department (2) Amazon
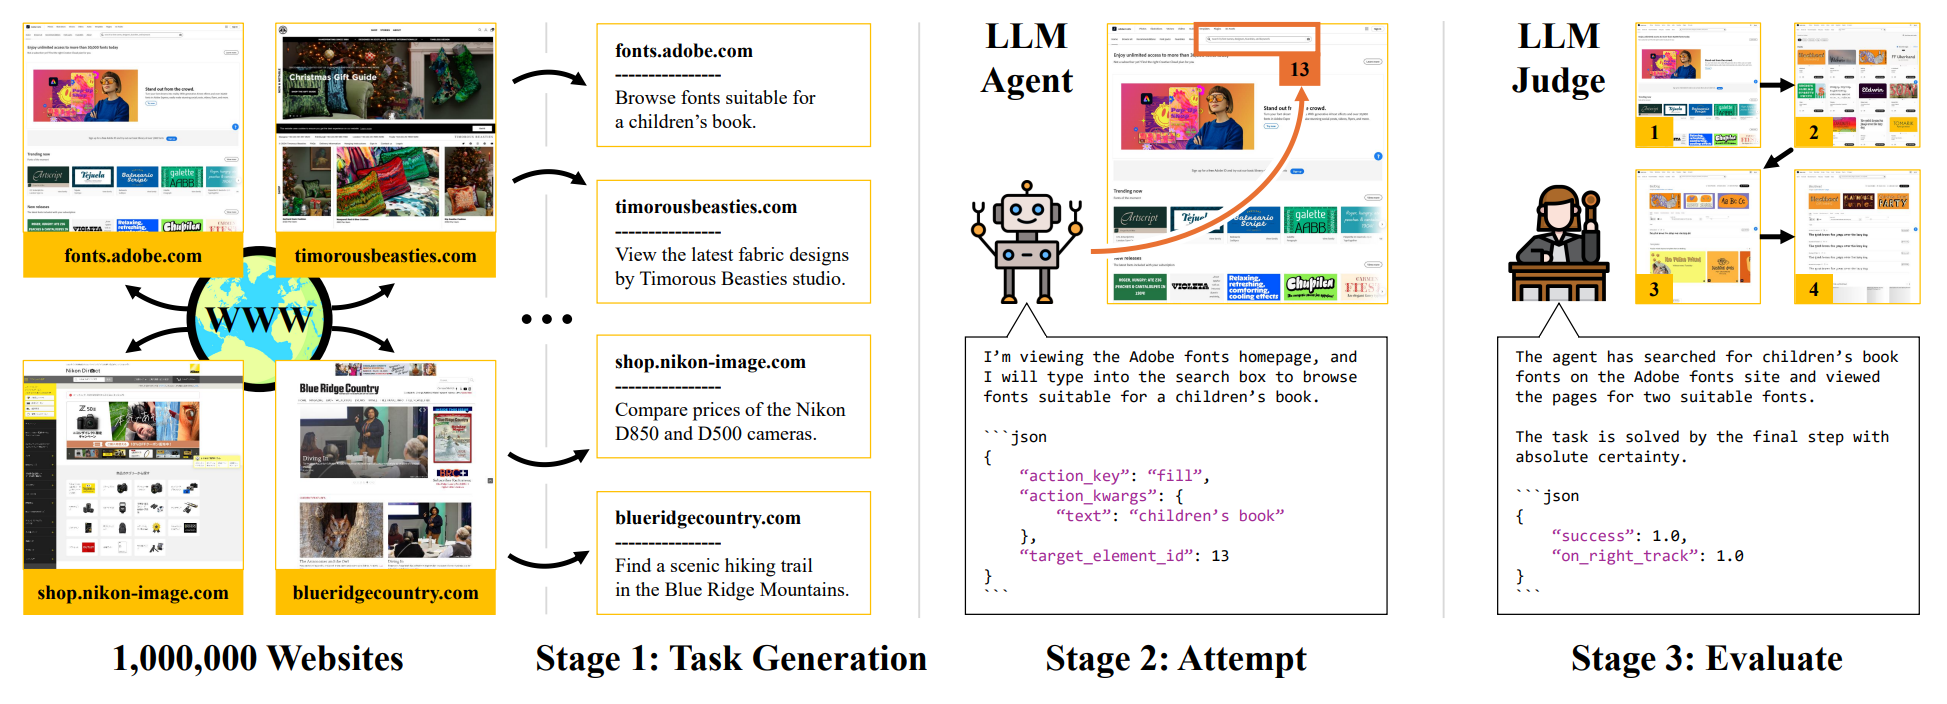
This is a dataset from the authors of the paper Towards Internet-Scale Training For Agents, and contains 150k web navigation tasks to facilitate internet-scale training of LLM agents without relying heavily on human annotations. The dataset is split into training (143k examples) and testing (3k examples) sets with different websites and tasks.
Dataset Structure
The dataset contains two splits: train and test. Each example consists of four fields:
website: The domain of the website (e.g.,wikipedia.org).instruction: The web navigation task to be performed on the website (e.g., "Find information about the history of coffee").steps: List of steps agents can follow to complete the task.criteria: List of success criteria for the task to be considered solved.
The dataset can be loaded using the following code snippet:
import datasets
datasets.load_dataset("data-for-agents/insta-150k-v3")
Evaluating Your Agents
We provide an official LLM Judge in our code repository, which can be used to evaluate your own agents and compare to ours. Load the train split for training your agents, and load the test split for testing purposes.
Citing Us
Please cite our work using the following bibtex:
@misc{Trabucco2025InSTA,
  title={InSTA: Towards Internet-Scale Training For Agents},
  author={Brandon Trabucco and Gunnar Sigurdsson and Robinson Piramuthu and Ruslan Salakhutdinov},
  year={2025},
  eprint={2502.06776},
  archivePrefix={arXiv},
  primaryClass={cs.LG},
}
Contributors
6 commits
Similar repos





InSTA: Towards Internet-Scale Training For Agents
19
6 commits
2 linked in READMEs
updated May 28, 2025
README
InSTA: Towards Internet-Scale Training For Agents
Brandon Trabucco (1) Gunnar Sigurdsson (2) Robinson Piramuthu (2) Ruslan Salakhutdinov (1)
(1) Carnegie Mellon University, Machine Learning Department (2) Amazon
This is a dataset from the authors of the paper Towards Internet-Scale Training For Agents, and contains 150k web navigation tasks to facilitate internet-scale training of LLM agents without relying heavily on human annotations. The dataset is split into training (143k examples) and testing (3k examples) sets with different websites and tasks.
Dataset Structure
The dataset contains two splits: train and test. Each example consists of four fields:
website: The domain of the website (e.g.,wikipedia.org).instruction: The web navigation task to be performed on the website (e.g., "Find information about the history of coffee").steps: List of steps agents can follow to complete the task.criteria: List of success criteria for the task to be considered solved.
The dataset can be loaded using the following code snippet:
import datasets
datasets.load_dataset("data-for-agents/insta-150k-v3")
Evaluating Your Agents
We provide an official LLM Judge in our code repository, which can be used to evaluate your own agents and compare to ours. Load the train split for training your agents, and load the test split for testing purposes.
Citing Us
Please cite our work using the following bibtex:
@misc{Trabucco2025InSTA,
  title={InSTA: Towards Internet-Scale Training For Agents},
  author={Brandon Trabucco and Gunnar Sigurdsson and Robinson Piramuthu and Ruslan Salakhutdinov},
  year={2025},
  eprint={2502.06776},
  archivePrefix={arXiv},
  primaryClass={cs.LG},
}
Similar repos
Linked in READMEs
Contributors
6 commits