Dataset Card for NIH Chest X-ray dataset
62
92 commits
1 linked in READMEs
updated Sep 11, 2024
README
Dataset Card for NIH Chest X-ray dataset
Table of Contents
- Table of Contents
- Dataset Description
- Dataset Structure
- Dataset Creation
- Considerations for Using the Data
- Additional Information
Dataset Description
- Homepage: NIH Chest X-ray Dataset of 10 Common Thorax Disease Categories
- Repository:
- Paper: ChestX-ray8: Hospital-scale Chest X-ray Database and Benchmarks on Weakly-Supervised Classification and Localization of Common Thorax Diseases
- Leaderboard:
- Point of Contact: rms@nih.gov
Dataset Summary
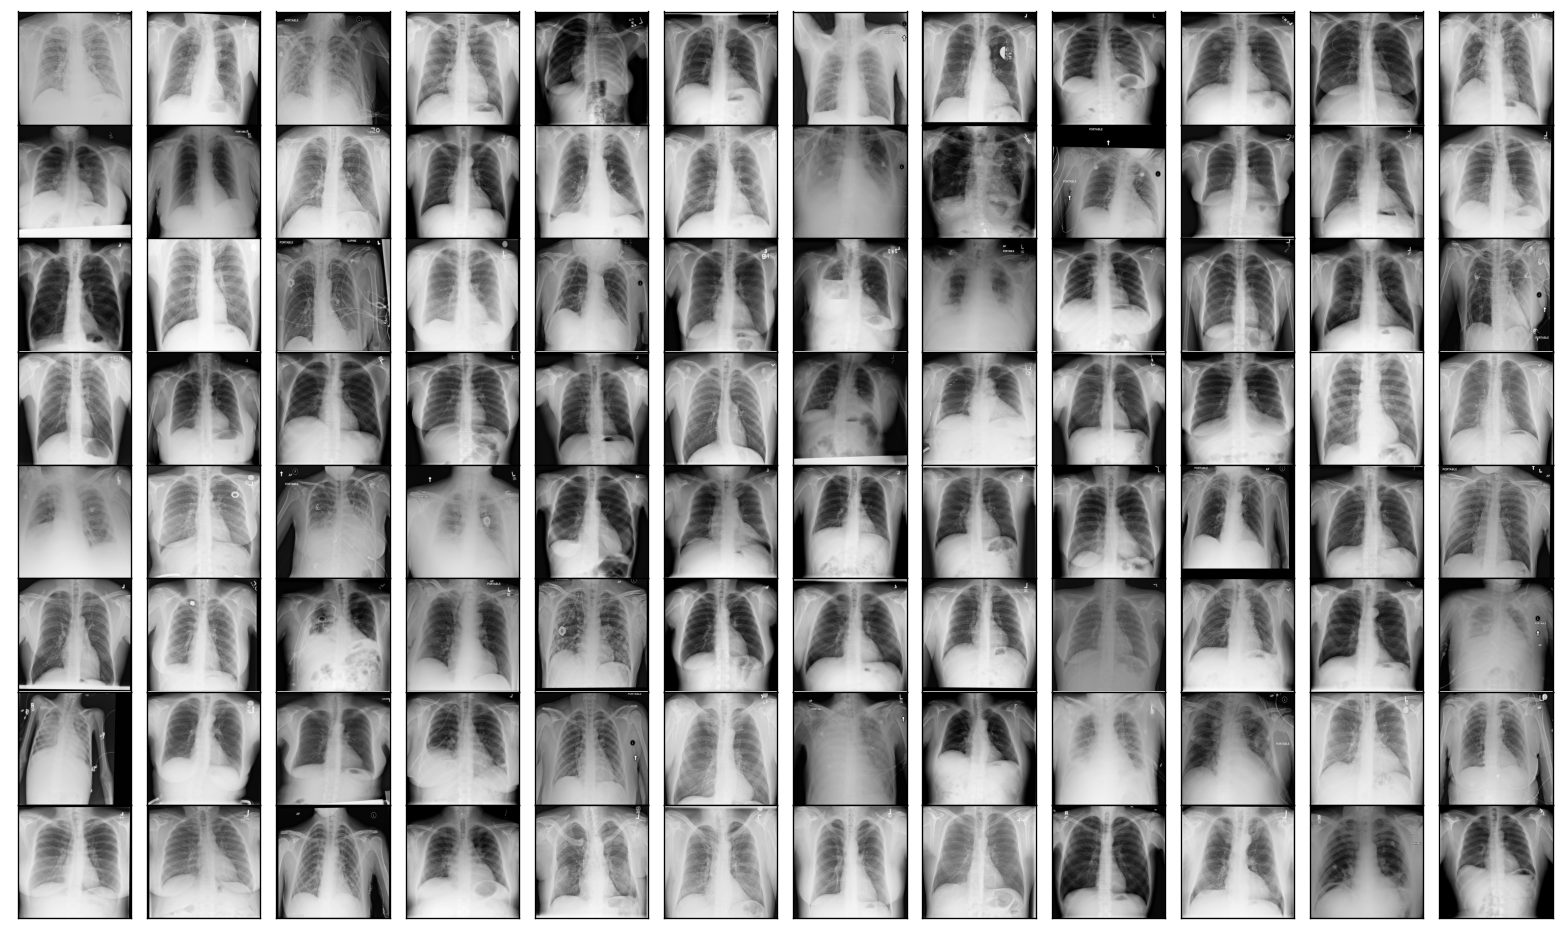
ChestX-ray dataset comprises 112,120 frontal-view X-ray images of 30,805 unique patients with the text-mined fourteen disease image labels (where each image can have multi-labels), mined from the associated radiological reports using natural language processing. Fourteen common thoracic pathologies include Atelectasis, Consolidation, Infiltration, Pneumothorax, Edema, Emphysema, Fibrosis, Effusion, Pneumonia, Pleural_thickening, Cardiomegaly, Nodule, Mass and Hernia, which is an extension of the 8 common disease patterns listed in our CVPR2017 paper. Note that original radiology reports (associated with these chest x-ray studies) are not meant to be publicly shared for many reasons. The text-mined disease labels are expected to have accuracy >90%.Please find more details and benchmark performance of trained models based on 14 disease labels in our arxiv paper: 1705.02315
Dataset Structure
Data Instances
A sample from the training set is provided below:
{'image_file_path': '/root/.cache/huggingface/datasets/downloads/extracted/95db46f21d556880cf0ecb11d45d5ba0b58fcb113c9a0fff2234eba8f74fe22a/images/00000798_022.png',
 'image': <PIL.PngImagePlugin.PngImageFile image mode=L size=1024x1024 at 0x7F2151B144D0>,
 'labels': [9, 3]}
Data Fields
The data instances have the following fields:
image_file_pathastrwith the image pathimage: APIL.Image.Imageobject containing the image. Note that when accessing the image column:dataset[0]["image"]the image file is automatically decoded. Decoding of a large number of image files might take a significant amount of time. Thus it is important to first query the sample index before the"image"column, i.e.dataset[0]["image"]should always be preferred overdataset["image"][0].labels: anintclassification label.
Class Label Mappings
```json { "No Finding": 0, "Atelectasis": 1, "Cardiomegaly": 2, "Effusion": 3, "Infiltration": 4, "Mass": 5, "Nodule": 6, "Pneumonia": 7, "Pneumothorax": 8, "Consolidation": 9, "Edema": 10, "Emphysema": 11, "Fibrosis": 12, "Pleural_Thickening": 13, "Hernia": 14 } ```Label distribution on the dataset:
| labels | obs | freq |
|---|---|---|
| No Finding | 60361 | 0.426468 |
| Infiltration | 19894 | 0.140557 |
| Effusion | 13317 | 0.0940885 |
| Atelectasis | 11559 | 0.0816677 |
| Nodule | 6331 | 0.0447304 |
| Mass | 5782 | 0.0408515 |
| Pneumothorax | 5302 | 0.0374602 |
| Consolidation | 4667 | 0.0329737 |
| Pleural_Thickening | 3385 | 0.023916 |
| Cardiomegaly | 2776 | 0.0196132 |
| Emphysema | 2516 | 0.0177763 |
| Edema | 2303 | 0.0162714 |
| Fibrosis | 1686 | 0.0119121 |
| Pneumonia | 1431 | 0.0101104 |
| Hernia | 227 | 0.00160382 |
Data Splits
| train | test | |
|---|---|---|
| # of examples | 86524 | 25596 |
Label distribution by dataset split:
| labels | ('Train', 'obs') | ('Train', 'freq') | ('Test', 'obs') | ('Test', 'freq') |
|---|---|---|---|---|
| No Finding | 50500 | 0.483392 | 9861 | 0.266032 |
| Infiltration | 13782 | 0.131923 | 6112 | 0.164891 |
| Effusion | 8659 | 0.082885 | 4658 | 0.125664 |
| Atelectasis | 8280 | 0.0792572 | 3279 | 0.0884614 |
| Nodule | 4708 | 0.0450656 | 1623 | 0.0437856 |
| Mass | 4034 | 0.038614 | 1748 | 0.0471578 |
| Consolidation | 2852 | 0.0272997 | 1815 | 0.0489654 |
| Pneumothorax | 2637 | 0.0252417 | 2665 | 0.0718968 |
| Pleural_Thickening | 2242 | 0.0214607 | 1143 | 0.0308361 |
| Cardiomegaly | 1707 | 0.0163396 | 1069 | 0.0288397 |
| Emphysema | 1423 | 0.0136211 | 1093 | 0.0294871 |
| Edema | 1378 | 0.0131904 | 925 | 0.0249548 |
| Fibrosis | 1251 | 0.0119747 | 435 | 0.0117355 |
| Pneumonia | 876 | 0.00838518 | 555 | 0.0149729 |
| Hernia | 141 | 0.00134967 | 86 | 0.00232012 |
Dataset Creation
Curation Rationale
[More Information Needed]
Source Data
Initial Data Collection and Normalization
[More Information Needed]
Who are the source language producers?
[More Information Needed]
Annotations
Annotation process
[More Information Needed]
Who are the annotators?
[More Information Needed]
Personal and Sensitive Information
[More Information Needed]
Considerations for Using the Data
Social Impact of Dataset
[More Information Needed]
Discussion of Biases
[More Information Needed]
Other Known Limitations
[More Information Needed]
Additional Information
Dataset Curators
[More Information Needed]
License and attribution
There are no restrictions on the use of the NIH chest x-ray images. However, the dataset has the following attribution requirements:
- Provide a link to the NIH download site: https://nihcc.app.box.com/v/ChestXray-NIHCC
- Include a citation to the CVPR 2017 paper (see Citation information section)
- Acknowledge that the NIH Clinical Center is the data provider
Citation Information
@inproceedings{Wang_2017,
	doi = {10.1109/cvpr.2017.369},
	url = {https://doi.org/10.1109%2Fcvpr.2017.369},
	year = 2017,
	month = {jul},
	publisher = {{IEEE}
},
	author = {Xiaosong Wang and Yifan Peng and Le Lu and Zhiyong Lu and Mohammadhadi Bagheri and Ronald M. Summers},
	title = {{ChestX}-Ray8: Hospital-Scale Chest X-Ray Database and Benchmarks on Weakly-Supervised Classification and Localization of Common Thorax Diseases},
	booktitle = {2017 {IEEE} Conference on Computer Vision and Pattern Recognition ({CVPR})}
}
Contributions
Thanks to @alcazar90 for adding this dataset.
Similar repos




Dataset Card for NIH Chest X-ray dataset
62
92 commits
1 linked in READMEs
updated Sep 11, 2024
README
Dataset Card for NIH Chest X-ray dataset
Table of Contents
- Table of Contents
- Dataset Description
- Dataset Structure
- Dataset Creation
- Considerations for Using the Data
- Additional Information
Dataset Description
- Homepage: NIH Chest X-ray Dataset of 10 Common Thorax Disease Categories
- Repository:
- Paper: ChestX-ray8: Hospital-scale Chest X-ray Database and Benchmarks on Weakly-Supervised Classification and Localization of Common Thorax Diseases
- Leaderboard:
- Point of Contact: rms@nih.gov
Dataset Summary
ChestX-ray dataset comprises 112,120 frontal-view X-ray images of 30,805 unique patients with the text-mined fourteen disease image labels (where each image can have multi-labels), mined from the associated radiological reports using natural language processing. Fourteen common thoracic pathologies include Atelectasis, Consolidation, Infiltration, Pneumothorax, Edema, Emphysema, Fibrosis, Effusion, Pneumonia, Pleural_thickening, Cardiomegaly, Nodule, Mass and Hernia, which is an extension of the 8 common disease patterns listed in our CVPR2017 paper. Note that original radiology reports (associated with these chest x-ray studies) are not meant to be publicly shared for many reasons. The text-mined disease labels are expected to have accuracy >90%.Please find more details and benchmark performance of trained models based on 14 disease labels in our arxiv paper: 1705.02315
Dataset Structure
Data Instances
A sample from the training set is provided below:
{'image_file_path': '/root/.cache/huggingface/datasets/downloads/extracted/95db46f21d556880cf0ecb11d45d5ba0b58fcb113c9a0fff2234eba8f74fe22a/images/00000798_022.png',
 'image': <PIL.PngImagePlugin.PngImageFile image mode=L size=1024x1024 at 0x7F2151B144D0>,
 'labels': [9, 3]}
Data Fields
The data instances have the following fields:
image_file_pathastrwith the image pathimage: APIL.Image.Imageobject containing the image. Note that when accessing the image column:dataset[0]["image"]the image file is automatically decoded. Decoding of a large number of image files might take a significant amount of time. Thus it is important to first query the sample index before the"image"column, i.e.dataset[0]["image"]should always be preferred overdataset["image"][0].labels: anintclassification label.
Class Label Mappings
```json { "No Finding": 0, "Atelectasis": 1, "Cardiomegaly": 2, "Effusion": 3, "Infiltration": 4, "Mass": 5, "Nodule": 6, "Pneumonia": 7, "Pneumothorax": 8, "Consolidation": 9, "Edema": 10, "Emphysema": 11, "Fibrosis": 12, "Pleural_Thickening": 13, "Hernia": 14 } ```Label distribution on the dataset:
| labels | obs | freq |
|---|---|---|
| No Finding | 60361 | 0.426468 |
| Infiltration | 19894 | 0.140557 |
| Effusion | 13317 | 0.0940885 |
| Atelectasis | 11559 | 0.0816677 |
| Nodule | 6331 | 0.0447304 |
| Mass | 5782 | 0.0408515 |
| Pneumothorax | 5302 | 0.0374602 |
| Consolidation | 4667 | 0.0329737 |
| Pleural_Thickening | 3385 | 0.023916 |
| Cardiomegaly | 2776 | 0.0196132 |
| Emphysema | 2516 | 0.0177763 |
| Edema | 2303 | 0.0162714 |
| Fibrosis | 1686 | 0.0119121 |
| Pneumonia | 1431 | 0.0101104 |
| Hernia | 227 | 0.00160382 |
Data Splits
| train | test | |
|---|---|---|
| # of examples | 86524 | 25596 |
Label distribution by dataset split:
| labels | ('Train', 'obs') | ('Train', 'freq') | ('Test', 'obs') | ('Test', 'freq') |
|---|---|---|---|---|
| No Finding | 50500 | 0.483392 | 9861 | 0.266032 |
| Infiltration | 13782 | 0.131923 | 6112 | 0.164891 |
| Effusion | 8659 | 0.082885 | 4658 | 0.125664 |
| Atelectasis | 8280 | 0.0792572 | 3279 | 0.0884614 |
| Nodule | 4708 | 0.0450656 | 1623 | 0.0437856 |
| Mass | 4034 | 0.038614 | 1748 | 0.0471578 |
| Consolidation | 2852 | 0.0272997 | 1815 | 0.0489654 |
| Pneumothorax | 2637 | 0.0252417 | 2665 | 0.0718968 |
| Pleural_Thickening | 2242 | 0.0214607 | 1143 | 0.0308361 |
| Cardiomegaly | 1707 | 0.0163396 | 1069 | 0.0288397 |
| Emphysema | 1423 | 0.0136211 | 1093 | 0.0294871 |
| Edema | 1378 | 0.0131904 | 925 | 0.0249548 |
| Fibrosis | 1251 | 0.0119747 | 435 | 0.0117355 |
| Pneumonia | 876 | 0.00838518 | 555 | 0.0149729 |
| Hernia | 141 | 0.00134967 | 86 | 0.00232012 |
Dataset Creation
Curation Rationale
[More Information Needed]
Source Data
Initial Data Collection and Normalization
[More Information Needed]
Who are the source language producers?
[More Information Needed]
Annotations
Annotation process
[More Information Needed]
Who are the annotators?
[More Information Needed]
Personal and Sensitive Information
[More Information Needed]
Considerations for Using the Data
Social Impact of Dataset
[More Information Needed]
Discussion of Biases
[More Information Needed]
Other Known Limitations
[More Information Needed]
Additional Information
Dataset Curators
[More Information Needed]
License and attribution
There are no restrictions on the use of the NIH chest x-ray images. However, the dataset has the following attribution requirements:
- Provide a link to the NIH download site: https://nihcc.app.box.com/v/ChestXray-NIHCC
- Include a citation to the CVPR 2017 paper (see Citation information section)
- Acknowledge that the NIH Clinical Center is the data provider
Citation Information
@inproceedings{Wang_2017,
	doi = {10.1109/cvpr.2017.369},
	url = {https://doi.org/10.1109%2Fcvpr.2017.369},
	year = 2017,
	month = {jul},
	publisher = {{IEEE}
},
	author = {Xiaosong Wang and Yifan Peng and Le Lu and Zhiyong Lu and Mohammadhadi Bagheri and Ronald M. Summers},
	title = {{ChestX}-Ray8: Hospital-Scale Chest X-Ray Database and Benchmarks on Weakly-Supervised Classification and Localization of Common Thorax Diseases},
	booktitle = {2017 {IEEE} Conference on Computer Vision and Pattern Recognition ({CVPR})}
}
Contributions
Thanks to @alcazar90 for adding this dataset.