Paper | Github | AceCode-87K | AceCodePair-300K | RM/RL Models
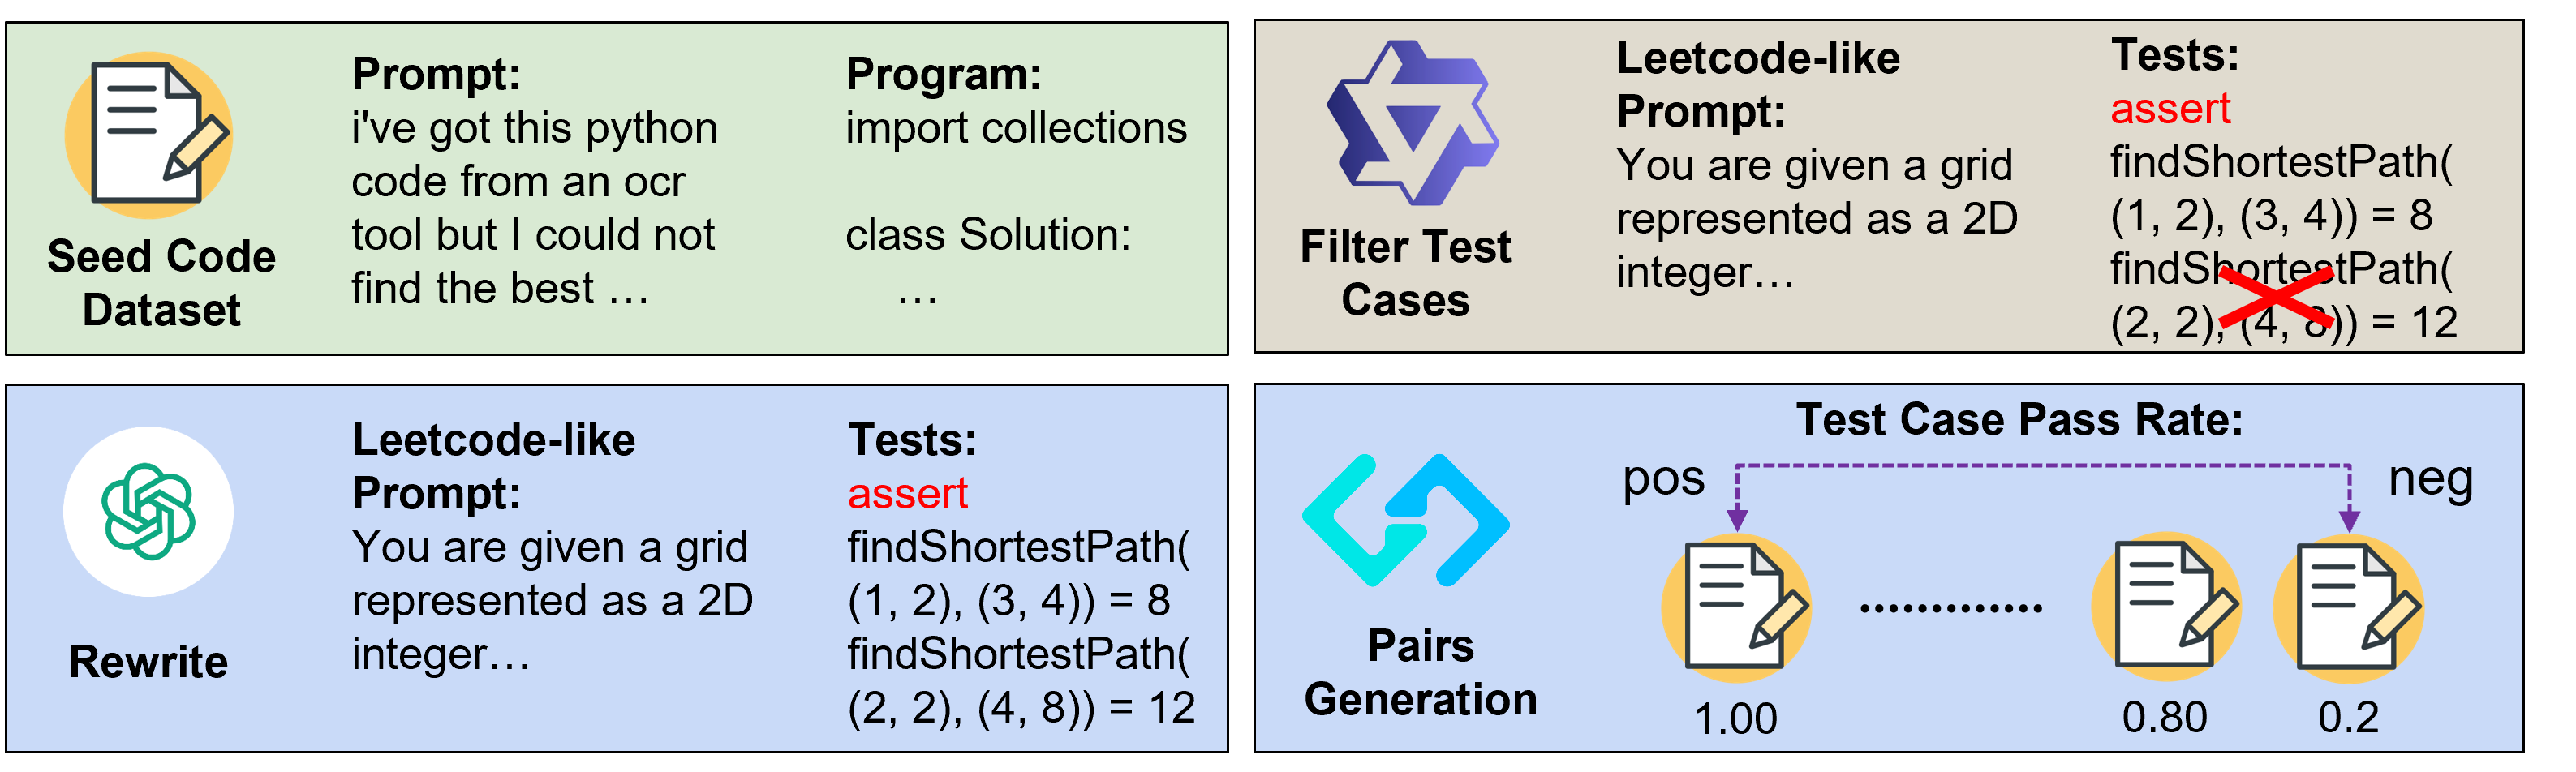
We introduce AceCoder, the first work to propose a fully automated pipeline for synthesizing large-scale reliable tests used for the reward model training and reinforcement learning in the coding scenario. To do this, we curated the dataset AceCode-87K, where we start from a seed code dataset and prompt powerful LLMs to "imagine" proper test cases for the coding question and filter the noisy ones. We sample inferences from existing coder models and compute their pass rate as the reliable and verifiable rewards for both training the reward model and conducting the reinforcement learning for coder LLM.
Id (str): Unique identifier for each questionsource (str): which datasetquestion (str): the questiontest_cases (List[str]): test cases for the questioninferences (List[dict]):
model_name (str): the model namecompletion_id (int): the completion idcompletion (str): the completionpass_rate (float): the pass ratetest_results (List[int]): the test resultscontext_messages (List[List[dict]]): context messages for the question
content (str): the content of the messagerole (str): the role of the messageimport datasets
dataset = datasets.load_dataset("TIGER-Lab/AceCode-87K", split='train')
context_messages as the key.@article{AceCoder,
title={AceCoder: Acing Coder RL via Automated Test-Case Synthesis},
author={Zeng, Huaye and Jiang, Dongfu and Wang, Haozhe and Nie, Ping and Chen, Xiaotong and Chen, Wenhu},
journal={ArXiv},
year={2025},
volume={abs/2207.01780}
}
Paper | Github | AceCode-87K | AceCodePair-300K | RM/RL Models
We introduce AceCoder, the first work to propose a fully automated pipeline for synthesizing large-scale reliable tests used for the reward model training and reinforcement learning in the coding scenario. To do this, we curated the dataset AceCode-87K, where we start from a seed code dataset and prompt powerful LLMs to "imagine" proper test cases for the coding question and filter the noisy ones. We sample inferences from existing coder models and compute their pass rate as the reliable and verifiable rewards for both training the reward model and conducting the reinforcement learning for coder LLM.
Id (str): Unique identifier for each questionsource (str): which datasetquestion (str): the questiontest_cases (List[str]): test cases for the questioninferences (List[dict]):
model_name (str): the model namecompletion_id (int): the completion idcompletion (str): the completionpass_rate (float): the pass ratetest_results (List[int]): the test resultscontext_messages (List[List[dict]]): context messages for the question
content (str): the content of the messagerole (str): the role of the messageimport datasets
dataset = datasets.load_dataset("TIGER-Lab/AceCode-87K", split='train')
context_messages as the key.@article{AceCoder,
title={AceCoder: Acing Coder RL via Automated Test-Case Synthesis},
author={Zeng, Huaye and Jiang, Dongfu and Wang, Haozhe and Nie, Ping and Chen, Xiaotong and Chen, Wenhu},
journal={ArXiv},
year={2025},
volume={abs/2207.01780}
}







