
Inst-IT Dataset: An Instruction Tuning Dataset with Multi-level Fine-Grained Annotations
10
12 commits
2 linked in READMEs
updated Mar 1, 2025
README
Inst-IT Dataset: An Instruction Tuning Dataset with Multi-level Fine-Grained Annotations
introduced in the paper Inst-IT: Boosting Multimodal Instance Understanding via Explicit Visual Prompt Instruction Tuning
🌐 Homepage | Code | 🤗 Paper | 📖 arXiv
Inst-IT Dataset Overview
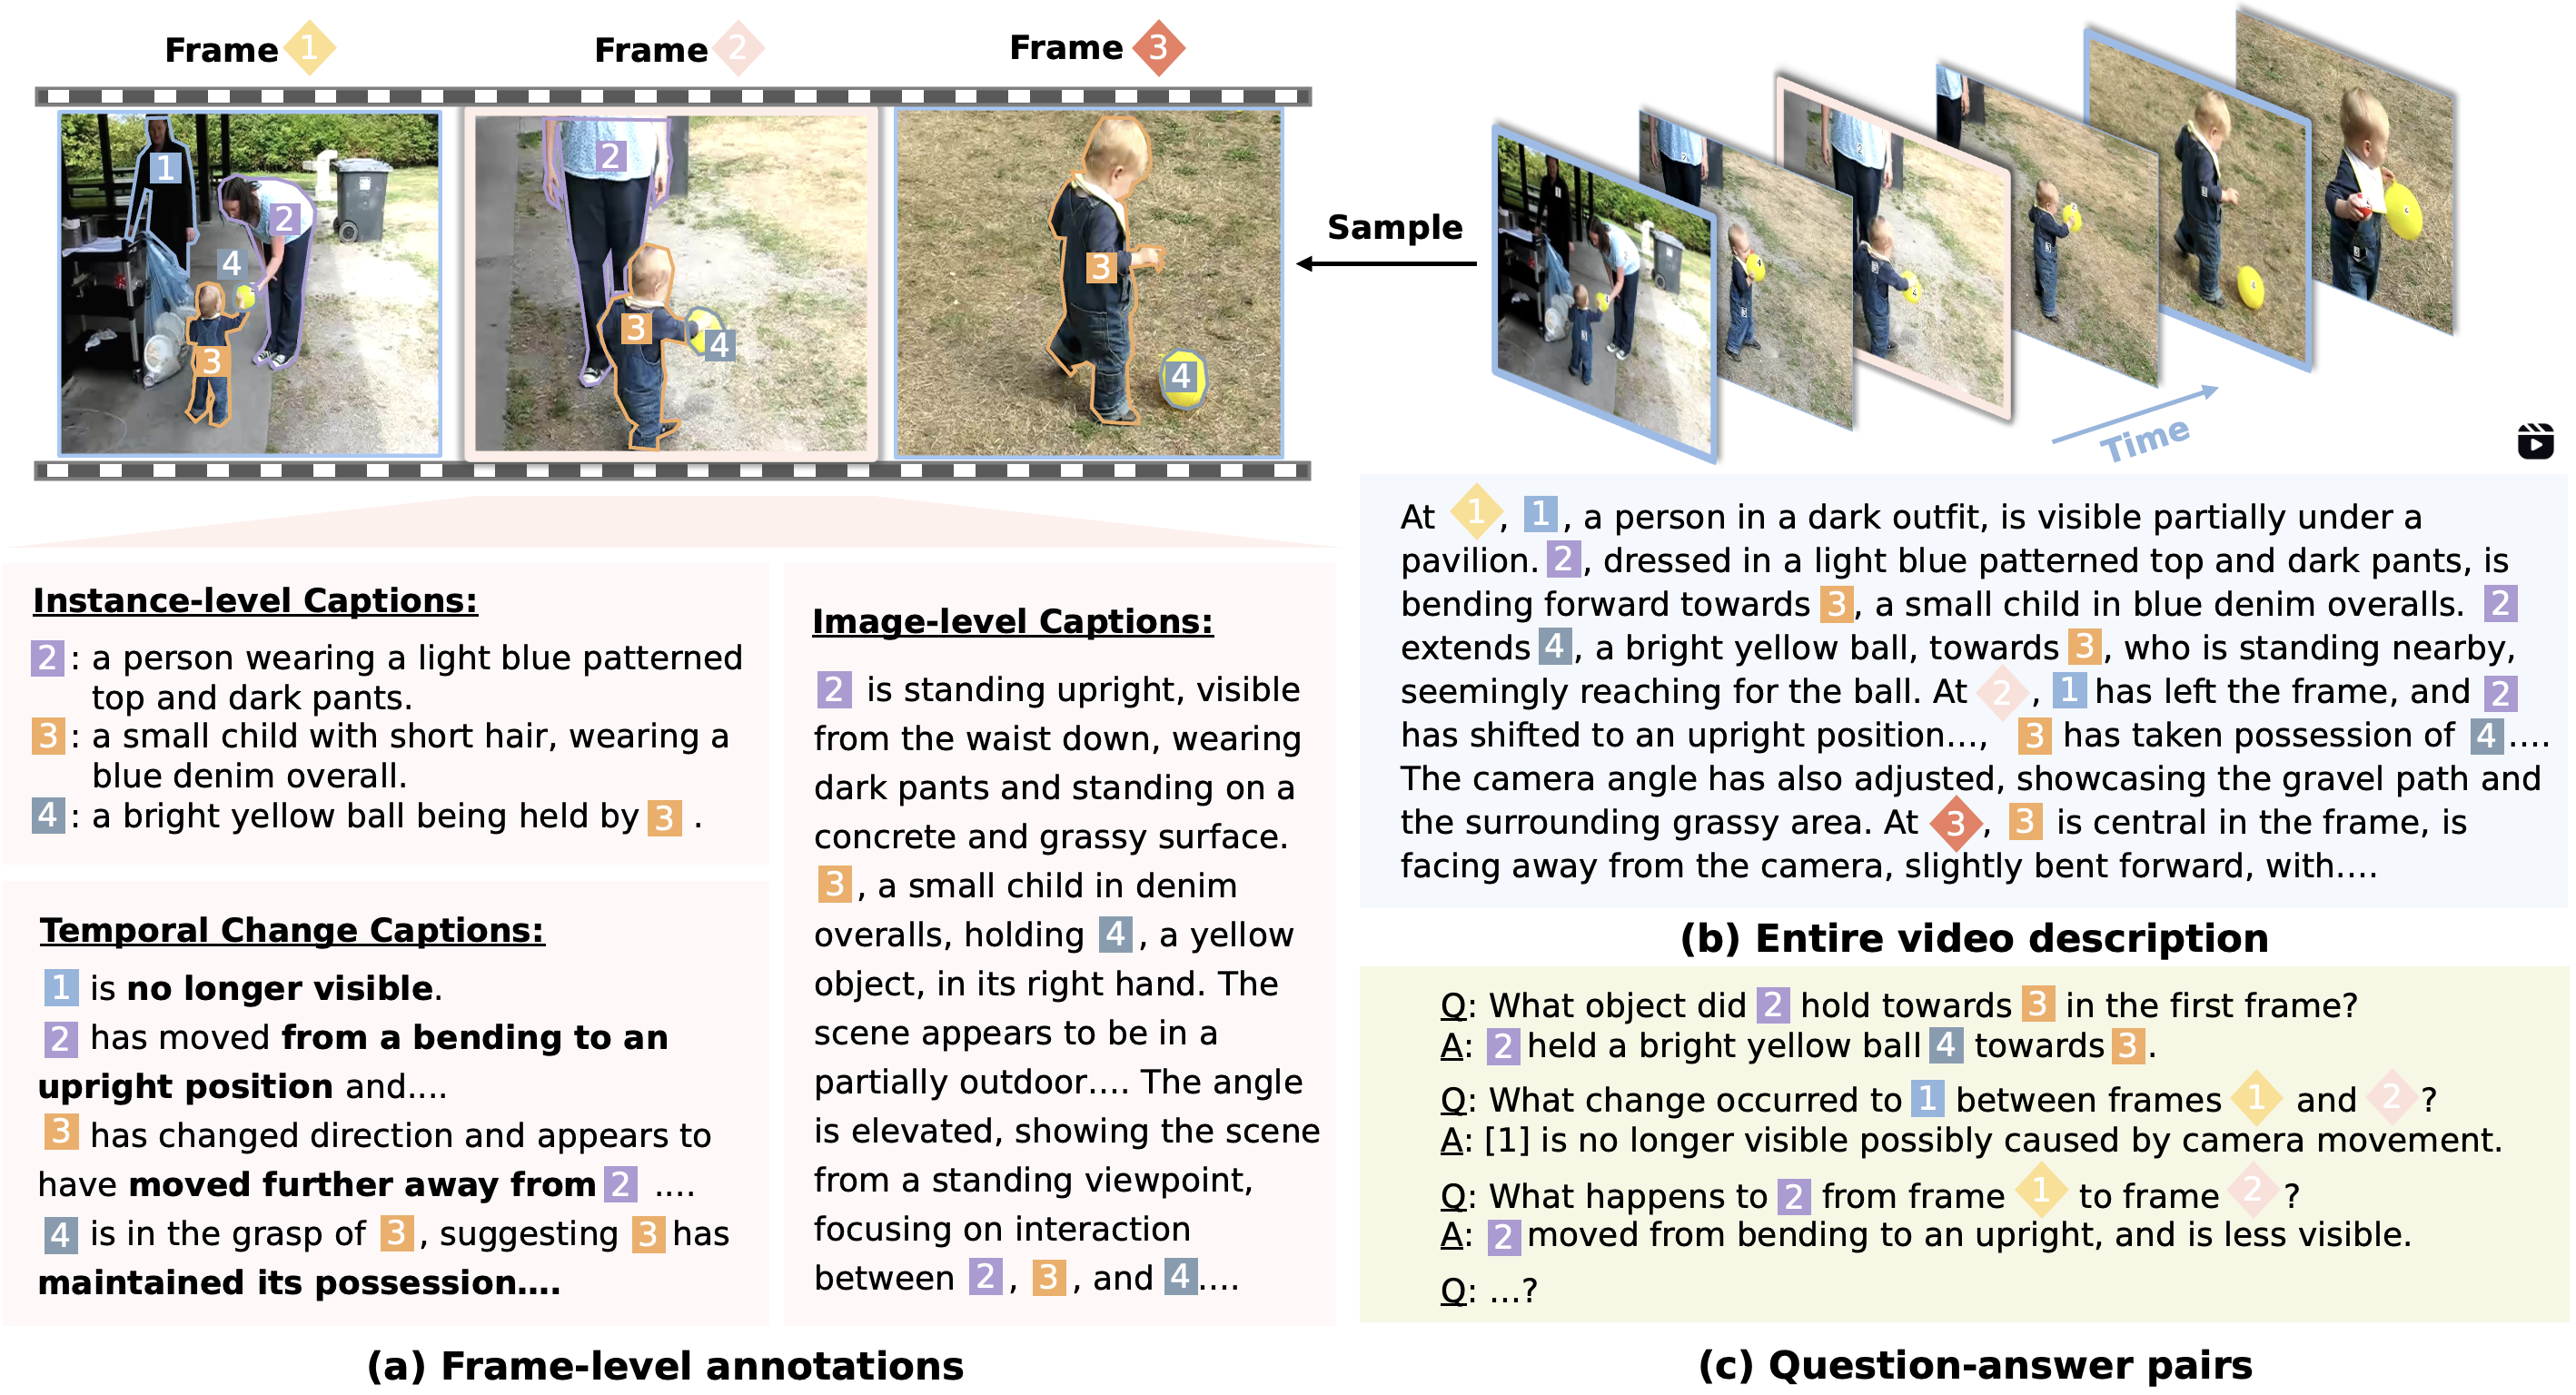
We create a large-scale instruction tuning dataset, the Inst-it Dataset. To the best of our knowledge, this is the first dataset that provides fine-grained annotations centric on specific instances. Inst-it Dataset contains 21k videos and 51k images (we treat images as static, single-frame videos). In total, Inst-it Dataset includes :
- 21k videos
- 51k images
- 21k video-level descriptions
- 207k frame-level descriptions (51k images, 156k video frames) (each frame-level description includes captions of 1)individual instances, 2)the entire image, and 3)the temporal changes.)
- 335k open-ended QA pairs
We visualize the data structure in the figure below, and you can view a more detailed data sample [here].
Download Inst-IT Dataset
To download the Inst-IT Dataset, you can run the following scripts:
pip install -U "huggingface_hub[cli]"
huggingface-cli download --repo-type dataset --resume-download Inst-IT/Inst-IT-Dataset --local-dir Inst-IT-Dataset
cd Inst-IT-Dataset && unzip images_vpt.zip && unzip videos_vpt.zip && unzip images_raw.zip && unzip videos_raw.zip
Then, you will get a folder structure as follows:
Inst-IT-Dataset
|-- README.md
|-- images_vpt # images with set-of-marks visual prompts.
|-- images_raw # images without set-of-marks visual prompts.
|-- videos_vpt # videos with set-of-marks visual prompts.
|-- videos_raw # videos without set-of-marks visual prompts.
|-- inst_it_dataset_image_51k.json # the annotation file of 51k images
`-- inst_it_dataset_video_21k.json # the annotation file of 21k videos
Note!!!We are working on releasing the SFT data in LLaVA format, as in LLaVA-Instruct-150K, please stay tuned! If you have any questions or suggestions, feel free to contact us :)
The annotations in inst_it_dataset_video_21k.json follow the structure as below:
[
    {
        "video_id": int,
        "frame_level_caption": (annotation for each frames within this video)
          [
              {
                  "timestamp": int, (indicate the timestamp of this frame in the video, e.g. <1>)
                  "frame_name": string, (the image filename of this frame)
                  "instance_level": (caption for each instance within this frame)
                    {
                        "1": "caption for instance 1",
                        (more instance level captions ...)
                    },
                  "image_level": string, (caption for the entire frame)
                  "temporal_change": string (caption for the temporal changes relative to the previous frame)
              },
              (more frame level captions ...)
          ],
        "question_answer_pairs": (open ended question answer pairs)
          [
             {
                "question": "the question",
                "answer": "the corresponding answer"
              },
             (more question answer pairs ...)
          ],
        "video_level_caption": string, (a dense caption for the entire video, encompassing all frames)
        "video_path": string (the path to where this video is stored)
    },
    (more annotations for other videos ...)
]
The annotations in inst_it_dataset_image_51k.json follow the structure as below:
[
    {
        "image_id": int,
        "instance_level_caption": (caption for each instance within this image)
          {
              "1": "caption for instance 1",
              (more instance level captions ...)
          },
        "image_level_caption": string, (caption for the entire image)
        "image_path": string (the path to where this image is stored)
    },
    (more annotations for other images ...)
]
Enhance LMMs with Inst-IT Dataset
Based on the Inst-IT Dataset, we propose a continuous instruction-tuning recipe to mix instance understanding datasets with generic instruction-tuning data effectively. By adding this small amount of data, the enhanced models demonstrate strong performance among various benchmarks and our [Inst-IT Bench].
The checkpoints of our model weights can be found:
- results on image benchmarks
| Method | LLM | Vision Encoder | AI2D (test) | MMMU (val) | POPE (test F1) | GQA (val) | MM-Vet (test) |
|---|---|---|---|---|---|---|---|
| LLaVA-1.5 | Vicuna-7B | CLIP-ViT-Large | 54.8 | 35.3 | 85.9 | 62.0 | 30.5 |
| LLaVA-Next | Vicuna-7B | CLIP-ViT-Large | 66.6 | 35.1 | 86.4 | 64.2 | 44.1 |
| DeepStack-L | Vicuna-7B | CLIP-ViT-Large | - | 35.7 | 86.7 | 63.1 | 29.9 |
| DeepStack-L-HD | Vicuna-7B | CLIP-ViT-Large | - | 35.6 | 86.5 | 65.2 | 37.5 |
| VILA | Vicuna-7B | CLIP-ViT-Large | - | - | 85.5 | 62.3 | 34.9 |
| ShareGPT4V | Vicuna-7B | CLIP-ViT-Large | - | - | - | - | 37.6 |
| MM-1.5 | MM-LLM-7B | MM-CLIP | 72.0 | 41.8 | 88.6 | - | 42.2 |
| InternVL2 | InternLM-7B | InternViT-300M | 83.8 | 49.3 | - | - | 60.0 |
| LLaVA-OV (SI) | Qwen2-7B | SigLIP-SO400M | 81.6 | 47.3 | - | - | 58.8 |
| LLaVA-OV | Qwen2-7B | SigLIP-SO400M | 81.4 | 48.8 | - | - | 57.5 |
| Qwen2-VL-Instruct | Qwen2-7B | DFN-CLIP-H | 83.0 | 54.1 | - | - | 62.0 |
| LLaVA-Next-Inst-IT | Vicuna-7B | CLIP-ViT-Large | 71.0 | 37.4 | 87.2 | 65.9 | 38.1 |
| LLaVA-Next-Inst-IT | Qwen2-7B | SigLIP-SO400 | 78.7 | 42.7 | 87.6 | 65.5 | 44.7 |
- results on video benchmarks
| Method | LLM | Vision Encoder | ANet-QA (open-ended) | EgoSchema (subset) | Next-QA (val) | VideoMME (w/o subs) | TempCompass (3 avg) |
|---|---|---|---|---|---|---|---|
| DeepStack-L | Vicuna-7B | CLIP-ViT-Large | 49.3 | 38.4 | 61.0 | - | - |
| IG-VLM | Vicuna-7B | CLIP-ViT-Large | 54.3 | 35.8 | 63.1 | - | - |
| LLaVA-Next | Vicuna-7B | CLIP-ViT-Large | 53.8 | - | - | - | - |
| SF-LLaVA | Vicuna-7B | CLIP-ViT-Large | 55.5 | 47.2 | 64.2 | - | - |
| Video-ChatGPT | Vicuna-7B | CLIP-ViT-Large | 35.2 | 47.3 | - | - | - |
| VideoLLaMA2 | Vicuna-7B | CLIP-ViT-Large | 50.2 | - | 51.7 | - | - |
| LLaVA-Next-Video | Vicuna-7B | CLIP-ViT-Large | 53.5 | 43.9 | - | 46.5 | - |
| LLaVA-Next-Video-DPO | Vicuna-7B | CLIP-ViT-Large | 60.2 | - | - | - | 58.3 |
| LongVA | Qwen2-7B | CLIP-ViT-Large | - | - | 68.3 | 52.4 | 61.3 |
| MM-1.5-Video-SFT | MM-LLM-7B | MM-CLIP | 60.9 | 57.2 | 76.8 | 53.5 | - |
| InternVL2 | InternLM-7B | InternViT-300M | - | - | - | 54.0 | - |
| LLaVA-OV | Qwen2-7B | SigLIP-SO400M | 56.6 | 60.1 | 79.4 | 58.2 | 69.4 |
| LLaVA-Video | Qwen2-7B | SigLIP-SO400M | 56.5 | 57.3 | 83.2 | 63.3 | - |
| Qwen2-VL-Instruct | Qwen2-7B | DFN-CLIP-H | - | 66.7 | - | 63.3 | 72.9 |
| LLaVA-Next-Inst-IT | Vicuna-7B | CLIP-ViT-Large | 53.7 | 57.8 | 70.2 | 44.3 | 59.8 |
| LLaVA-Next-Inst-IT | Qwen2-7B | SigLIP-SO400 | 55.2 | 50.4 | 73.0 | 54.0 | 63.9 |
Contact
Feel free to contact us if you have any questions or suggestions
- Email (Wujian Peng): wjpeng24@m.fudan.edu.cn
- Email (Lingchen Meng): lcmeng20@fudan.edu.cn
Citation
If you find our work helpful, please consider citing our paper ✒️ and like our dataset ❤️ :
 @article{peng2024boosting,
   title={Inst-IT: Boosting Multimodal Instance Understanding via Explicit Visual Prompt Instruction Tuning},
   author={Peng, Wujian and Meng, Lingchen and Chen, Yitong and Xie, Yiweng and Liu, Yang and Gui, Tao and Hang, Xu and Qiu, Xipeng and Wu, Zuxuan and Jiang, Yu-Gang},
   journal={arXiv preprint arXiv:2412.03565},
   year={2024}
 }
Contributors

12 commits
Similar repos





Inst-IT Dataset: An Instruction Tuning Dataset with Multi-level Fine-Grained Annotations
10
12 commits
2 linked in READMEs
updated Mar 1, 2025
README
Inst-IT Dataset: An Instruction Tuning Dataset with Multi-level Fine-Grained Annotations
introduced in the paper Inst-IT: Boosting Multimodal Instance Understanding via Explicit Visual Prompt Instruction Tuning
🌐 Homepage | Code | 🤗 Paper | 📖 arXiv
Inst-IT Dataset Overview
We create a large-scale instruction tuning dataset, the Inst-it Dataset. To the best of our knowledge, this is the first dataset that provides fine-grained annotations centric on specific instances. Inst-it Dataset contains 21k videos and 51k images (we treat images as static, single-frame videos). In total, Inst-it Dataset includes :
- 21k videos
- 51k images
- 21k video-level descriptions
- 207k frame-level descriptions (51k images, 156k video frames) (each frame-level description includes captions of 1)individual instances, 2)the entire image, and 3)the temporal changes.)
- 335k open-ended QA pairs
We visualize the data structure in the figure below, and you can view a more detailed data sample [here].
Download Inst-IT Dataset
To download the Inst-IT Dataset, you can run the following scripts:
pip install -U "huggingface_hub[cli]"
huggingface-cli download --repo-type dataset --resume-download Inst-IT/Inst-IT-Dataset --local-dir Inst-IT-Dataset
cd Inst-IT-Dataset && unzip images_vpt.zip && unzip videos_vpt.zip && unzip images_raw.zip && unzip videos_raw.zip
Then, you will get a folder structure as follows:
Inst-IT-Dataset
|-- README.md
|-- images_vpt # images with set-of-marks visual prompts.
|-- images_raw # images without set-of-marks visual prompts.
|-- videos_vpt # videos with set-of-marks visual prompts.
|-- videos_raw # videos without set-of-marks visual prompts.
|-- inst_it_dataset_image_51k.json # the annotation file of 51k images
`-- inst_it_dataset_video_21k.json # the annotation file of 21k videos
Note!!!We are working on releasing the SFT data in LLaVA format, as in LLaVA-Instruct-150K, please stay tuned! If you have any questions or suggestions, feel free to contact us :)
The annotations in inst_it_dataset_video_21k.json follow the structure as below:
[
    {
        "video_id": int,
        "frame_level_caption": (annotation for each frames within this video)
          [
              {
                  "timestamp": int, (indicate the timestamp of this frame in the video, e.g. <1>)
                  "frame_name": string, (the image filename of this frame)
                  "instance_level": (caption for each instance within this frame)
                    {
                        "1": "caption for instance 1",
                        (more instance level captions ...)
                    },
                  "image_level": string, (caption for the entire frame)
                  "temporal_change": string (caption for the temporal changes relative to the previous frame)
              },
              (more frame level captions ...)
          ],
        "question_answer_pairs": (open ended question answer pairs)
          [
             {
                "question": "the question",
                "answer": "the corresponding answer"
              },
             (more question answer pairs ...)
          ],
        "video_level_caption": string, (a dense caption for the entire video, encompassing all frames)
        "video_path": string (the path to where this video is stored)
    },
    (more annotations for other videos ...)
]
The annotations in inst_it_dataset_image_51k.json follow the structure as below:
[
    {
        "image_id": int,
        "instance_level_caption": (caption for each instance within this image)
          {
              "1": "caption for instance 1",
              (more instance level captions ...)
          },
        "image_level_caption": string, (caption for the entire image)
        "image_path": string (the path to where this image is stored)
    },
    (more annotations for other images ...)
]
Enhance LMMs with Inst-IT Dataset
Based on the Inst-IT Dataset, we propose a continuous instruction-tuning recipe to mix instance understanding datasets with generic instruction-tuning data effectively. By adding this small amount of data, the enhanced models demonstrate strong performance among various benchmarks and our [Inst-IT Bench].
The checkpoints of our model weights can be found:
- results on image benchmarks
| Method | LLM | Vision Encoder | AI2D (test) | MMMU (val) | POPE (test F1) | GQA (val) | MM-Vet (test) |
|---|---|---|---|---|---|---|---|
| LLaVA-1.5 | Vicuna-7B | CLIP-ViT-Large | 54.8 | 35.3 | 85.9 | 62.0 | 30.5 |
| LLaVA-Next | Vicuna-7B | CLIP-ViT-Large | 66.6 | 35.1 | 86.4 | 64.2 | 44.1 |
| DeepStack-L | Vicuna-7B | CLIP-ViT-Large | - | 35.7 | 86.7 | 63.1 | 29.9 |
| DeepStack-L-HD | Vicuna-7B | CLIP-ViT-Large | - | 35.6 | 86.5 | 65.2 | 37.5 |
| VILA | Vicuna-7B | CLIP-ViT-Large | - | - | 85.5 | 62.3 | 34.9 |
| ShareGPT4V | Vicuna-7B | CLIP-ViT-Large | - | - | - | - | 37.6 |
| MM-1.5 | MM-LLM-7B | MM-CLIP | 72.0 | 41.8 | 88.6 | - | 42.2 |
| InternVL2 | InternLM-7B | InternViT-300M | 83.8 | 49.3 | - | - | 60.0 |
| LLaVA-OV (SI) | Qwen2-7B | SigLIP-SO400M | 81.6 | 47.3 | - | - | 58.8 |
| LLaVA-OV | Qwen2-7B | SigLIP-SO400M | 81.4 | 48.8 | - | - | 57.5 |
| Qwen2-VL-Instruct | Qwen2-7B | DFN-CLIP-H | 83.0 | 54.1 | - | - | 62.0 |
| LLaVA-Next-Inst-IT | Vicuna-7B | CLIP-ViT-Large | 71.0 | 37.4 | 87.2 | 65.9 | 38.1 |
| LLaVA-Next-Inst-IT | Qwen2-7B | SigLIP-SO400 | 78.7 | 42.7 | 87.6 | 65.5 | 44.7 |
- results on video benchmarks
| Method | LLM | Vision Encoder | ANet-QA (open-ended) | EgoSchema (subset) | Next-QA (val) | VideoMME (w/o subs) | TempCompass (3 avg) |
|---|---|---|---|---|---|---|---|
| DeepStack-L | Vicuna-7B | CLIP-ViT-Large | 49.3 | 38.4 | 61.0 | - | - |
| IG-VLM | Vicuna-7B | CLIP-ViT-Large | 54.3 | 35.8 | 63.1 | - | - |
| LLaVA-Next | Vicuna-7B | CLIP-ViT-Large | 53.8 | - | - | - | - |
| SF-LLaVA | Vicuna-7B | CLIP-ViT-Large | 55.5 | 47.2 | 64.2 | - | - |
| Video-ChatGPT | Vicuna-7B | CLIP-ViT-Large | 35.2 | 47.3 | - | - | - |
| VideoLLaMA2 | Vicuna-7B | CLIP-ViT-Large | 50.2 | - | 51.7 | - | - |
| LLaVA-Next-Video | Vicuna-7B | CLIP-ViT-Large | 53.5 | 43.9 | - | 46.5 | - |
| LLaVA-Next-Video-DPO | Vicuna-7B | CLIP-ViT-Large | 60.2 | - | - | - | 58.3 |
| LongVA | Qwen2-7B | CLIP-ViT-Large | - | - | 68.3 | 52.4 | 61.3 |
| MM-1.5-Video-SFT | MM-LLM-7B | MM-CLIP | 60.9 | 57.2 | 76.8 | 53.5 | - |
| InternVL2 | InternLM-7B | InternViT-300M | - | - | - | 54.0 | - |
| LLaVA-OV | Qwen2-7B | SigLIP-SO400M | 56.6 | 60.1 | 79.4 | 58.2 | 69.4 |
| LLaVA-Video | Qwen2-7B | SigLIP-SO400M | 56.5 | 57.3 | 83.2 | 63.3 | - |
| Qwen2-VL-Instruct | Qwen2-7B | DFN-CLIP-H | - | 66.7 | - | 63.3 | 72.9 |
| LLaVA-Next-Inst-IT | Vicuna-7B | CLIP-ViT-Large | 53.7 | 57.8 | 70.2 | 44.3 | 59.8 |
| LLaVA-Next-Inst-IT | Qwen2-7B | SigLIP-SO400 | 55.2 | 50.4 | 73.0 | 54.0 | 63.9 |
Contact
Feel free to contact us if you have any questions or suggestions
- Email (Wujian Peng): wjpeng24@m.fudan.edu.cn
- Email (Lingchen Meng): lcmeng20@fudan.edu.cn
Citation
If you find our work helpful, please consider citing our paper ✒️ and like our dataset ❤️ :
 @article{peng2024boosting,
   title={Inst-IT: Boosting Multimodal Instance Understanding via Explicit Visual Prompt Instruction Tuning},
   author={Peng, Wujian and Meng, Lingchen and Chen, Yitong and Xie, Yiweng and Liu, Yang and Gui, Tao and Hang, Xu and Qiu, Xipeng and Wu, Zuxuan and Jiang, Yu-Gang},
   journal={arXiv preprint arXiv:2412.03565},
   year={2024}
 }
Similar repos
Linked in READMEs
Contributors
12 commits