
README
SpeechEditBench
SpeechEditBench is a bilingual multi-attribute benchmark for instruction-guided speech editing. Each example provides source speech and a natural-language editing instruction, and the benchmark evaluates whether a system can apply the requested edit while preserving the expected lexical content.
- Paper: SpeechEditBench: A Bilingual Multi-Attribute Benchmark for Instruction-Guided Speech Editing
- Code and evaluator: github.com/daxintan-cuhk/SpeechEditBench
- Dataset: huggingface.co/datasets/DiscreteSpeech/SpeechEditBench
Benchmark Overview
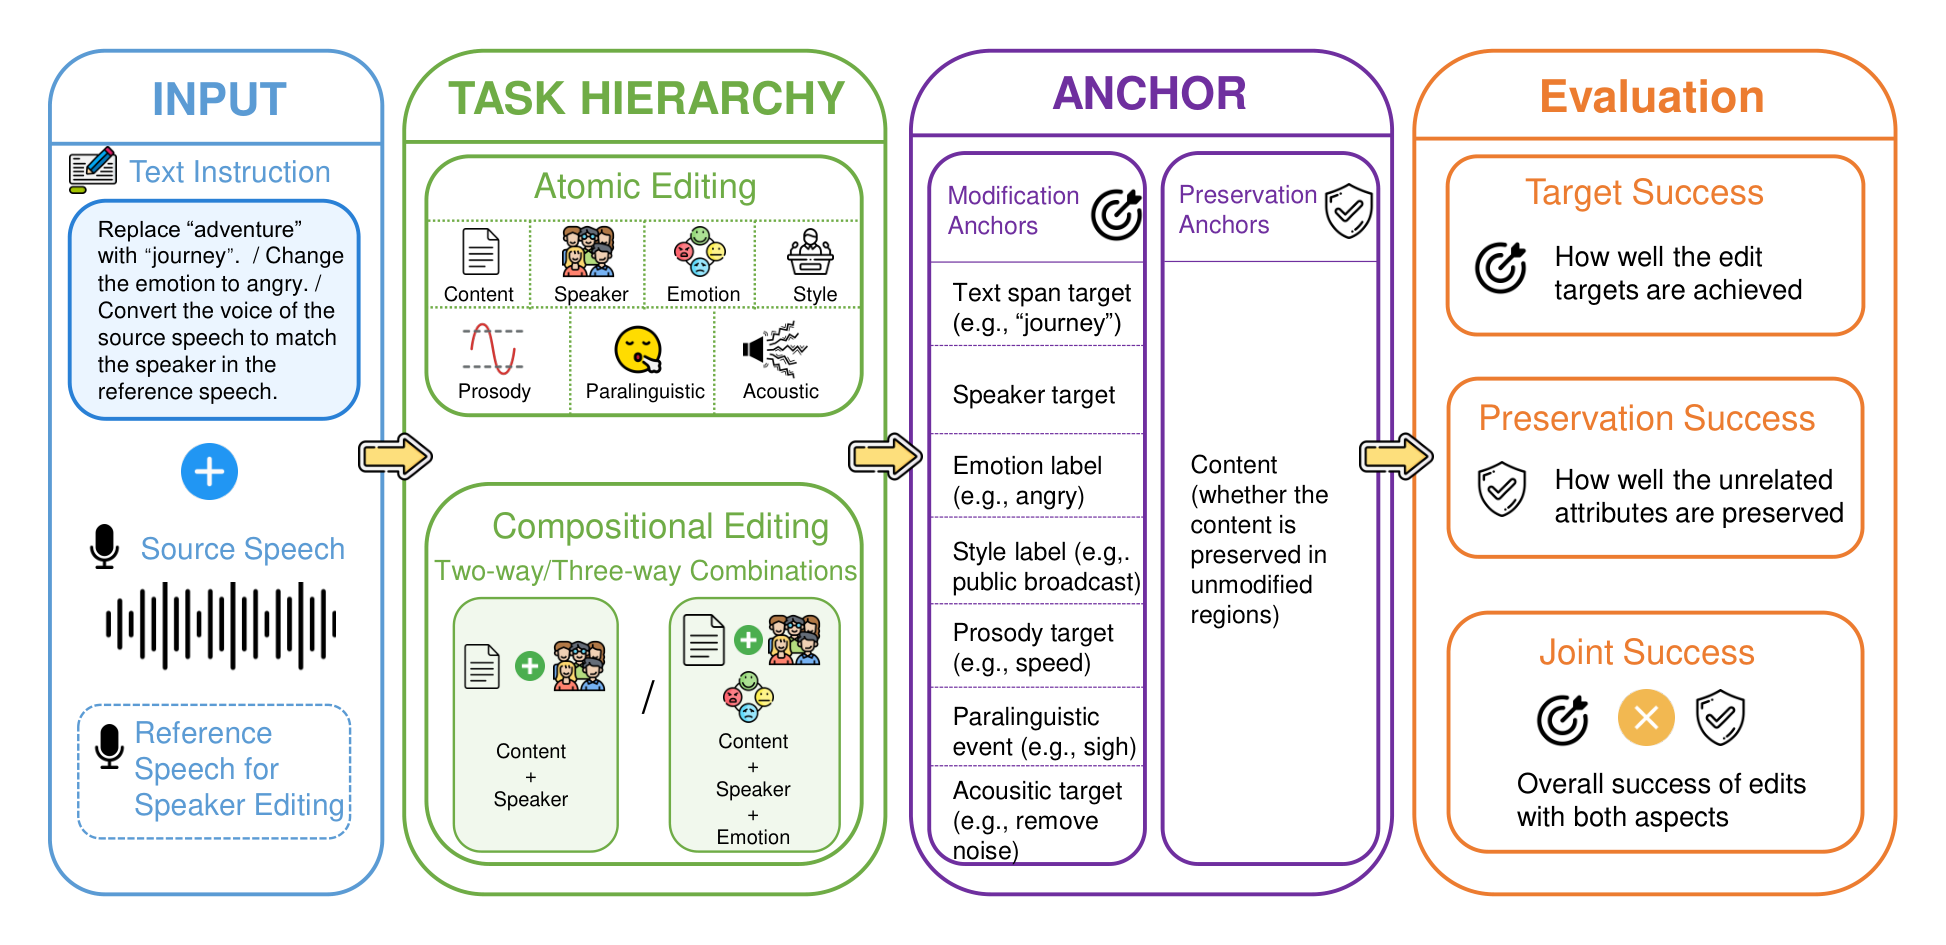
SpeechEditBench contains seven atomic editing tasks and a compositional editing split:
| Task | Goal |
|---|---|
content_editing | Replace, insert, or delete lexical content. |
speaker_editing | Convert the source speech to match a target speaker reference. |
emotion_editing | Change the expressed emotion. |
style_editing | Change the speaking style, such as public-broadcast, intimate, dramatic, restrained-flat, storytelling, or conversational. |
prosody_editing | Modify speed, pitch, or word stress. |
paralinguistic_editing | Add or remove breath, laugh, cough, or sigh events. |
acoustic_editing | Perform speech enhancement or acoustic environment transfer. |
compositional_editing | Combine multiple editing goals in a single instruction. |
Dataset Composition
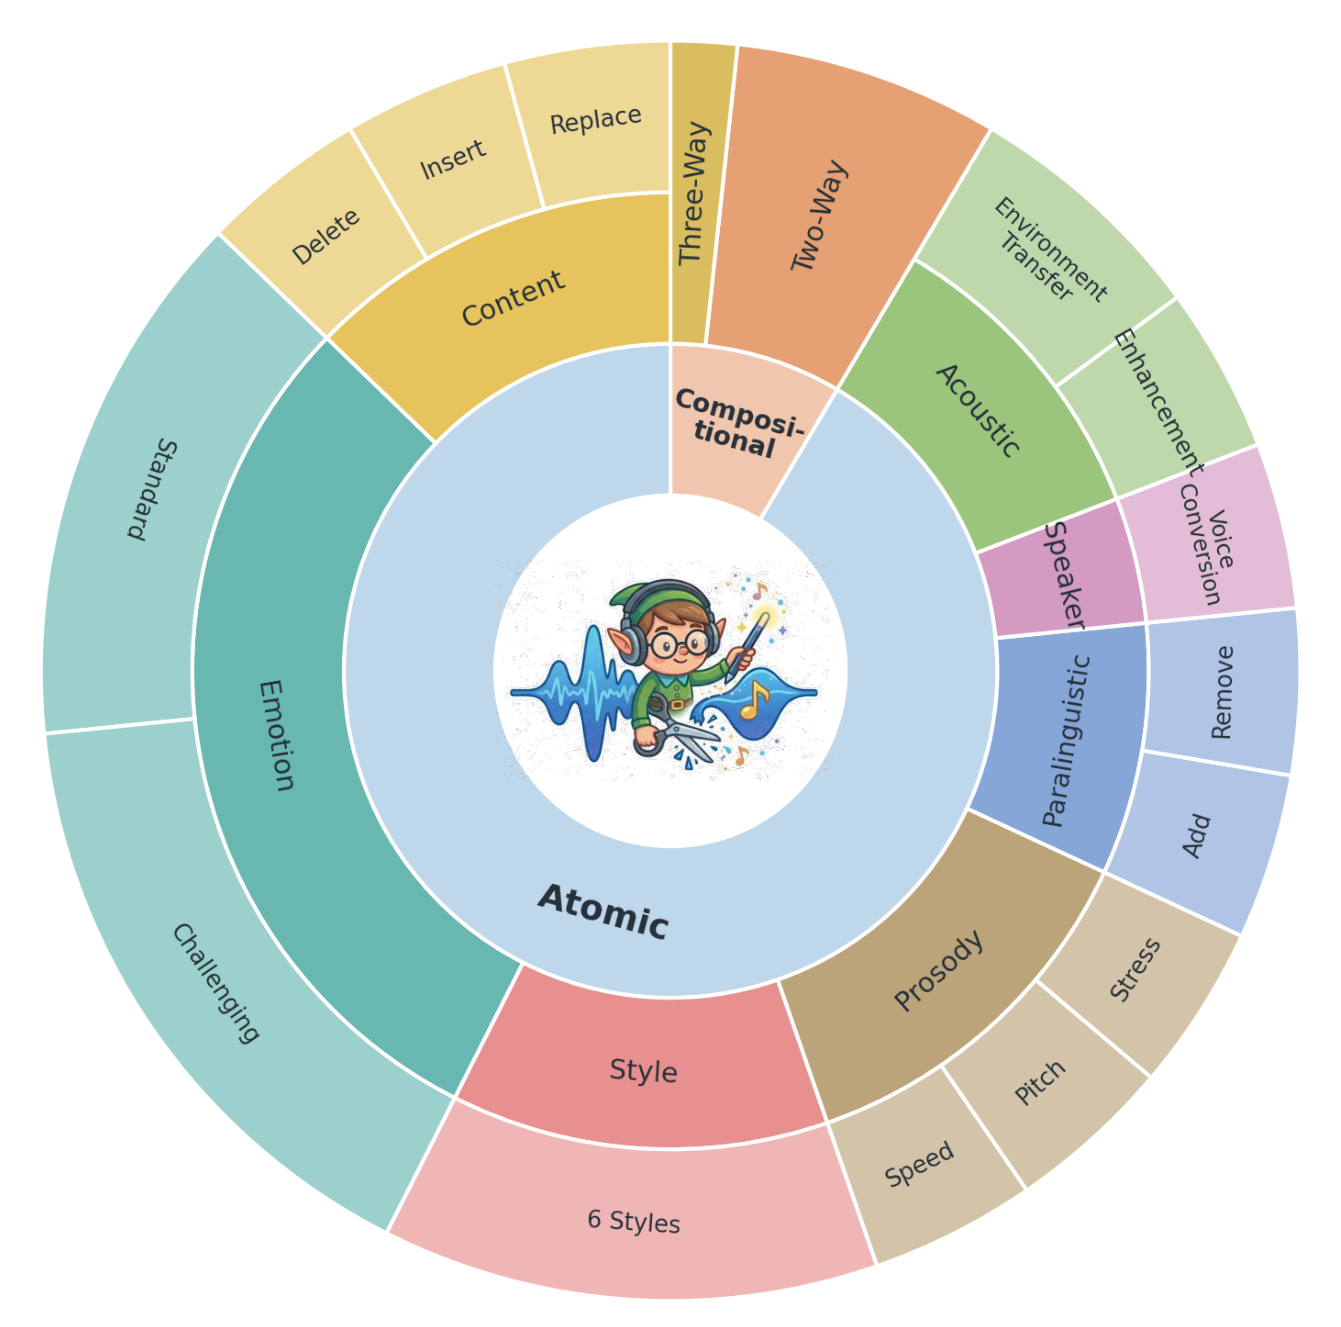
The v1.1 release contains 4,700 benchmark samples and 5,400 released audio
files across the full task set. The authoritative sample metadata is stored in
data/<task_id>/samples.jsonl.
Download
We recommend downloading the dataset with the script provided in the GitHub repository, which preserves the expected directory layout for evaluation:
git clone https://github.com/daxintan-cuhk/SpeechEditBench.git
cd SpeechEditBench

python scripts/download_hf_dataset.py \
  --repo-id DiscreteSpeech/SpeechEditBench \
  --revision v1.1
By default, the helper downloads the benchmark metadata and audio files
referenced by the released samples.jsonl files, rather than every extra file
stored in the Hugging Face repository.
After download, the repository should contain:
data/<task_id>/samples.jsonl
data/<task_id>/audio/**
The GitHub repository also includes the evaluation runner:
python scripts/run_eval.py \
  --task content_editing \
  --output-dir outputs/my_model/content_editing \
  --model-name my_model
See the GitHub documentation for evaluator dependencies, output naming conventions, and task-specific metrics.
Data Format
Each samples.jsonl row is a JSON object. Common fields include:
sample_id: unique sample identifiertask: task idaudio_path: path to source audioinstruction: natural-language editing instructiontranscript: source transcript when availableanchor: task-specific target metadata used by the evaluatorlanguage:enorzhsource_dataset: source corpus tagbenchmark_version: release version
Some tasks include additional fields such as reference_audio_path for
speaker editing or anchor.target_reference_path for acoustic editing.
Evaluation Summary
SpeechEditBench reports:
- Target success: whether the requested edit is achieved.
- Content preservation: whether the expected transcript is preserved, using ASR-based WER/CER.
- Joint success: whether both target and preservation criteria pass.
Task-specific target metrics include speaker similarity, Gemini-compatible multimodal judges for expressive/paralinguistic attributes, prosody measures, DNSMOS, RT60, and acoustic scene matching. Full evaluator details are available in the GitHub repository.
Citation
@article{zhang2026speecheditbench,
  title={SpeechEditBench: A Bilingual Multi-Attribute Benchmark for Instruction-Guided Speech Editing},
  author={Zhang, Hanlin and Tan, Daxin and Tao, Dehua and Chen, Xiao and Tan, Haochen and Song, Linqi},
  journal={arXiv preprint arXiv:2606.01804},
  year={2026}
}
License
This dataset is released under the Apache 2.0 license. Users should also respect the licenses and terms of the original speech corpora used to construct the benchmark.
Contributors

68 commits
Similar repos





README
SpeechEditBench
SpeechEditBench is a bilingual multi-attribute benchmark for instruction-guided speech editing. Each example provides source speech and a natural-language editing instruction, and the benchmark evaluates whether a system can apply the requested edit while preserving the expected lexical content.
- Paper: SpeechEditBench: A Bilingual Multi-Attribute Benchmark for Instruction-Guided Speech Editing
- Code and evaluator: github.com/daxintan-cuhk/SpeechEditBench
- Dataset: huggingface.co/datasets/DiscreteSpeech/SpeechEditBench
Benchmark Overview
SpeechEditBench contains seven atomic editing tasks and a compositional editing split:
| Task | Goal |
|---|---|
content_editing | Replace, insert, or delete lexical content. |
speaker_editing | Convert the source speech to match a target speaker reference. |
emotion_editing | Change the expressed emotion. |
style_editing | Change the speaking style, such as public-broadcast, intimate, dramatic, restrained-flat, storytelling, or conversational. |
prosody_editing | Modify speed, pitch, or word stress. |
paralinguistic_editing | Add or remove breath, laugh, cough, or sigh events. |
acoustic_editing | Perform speech enhancement or acoustic environment transfer. |
compositional_editing | Combine multiple editing goals in a single instruction. |
Dataset Composition
The v1.1 release contains 4,700 benchmark samples and 5,400 released audio
files across the full task set. The authoritative sample metadata is stored in
data/<task_id>/samples.jsonl.
Download
We recommend downloading the dataset with the script provided in the GitHub repository, which preserves the expected directory layout for evaluation:
git clone https://github.com/daxintan-cuhk/SpeechEditBench.git
cd SpeechEditBench

python scripts/download_hf_dataset.py \
  --repo-id DiscreteSpeech/SpeechEditBench \
  --revision v1.1
By default, the helper downloads the benchmark metadata and audio files
referenced by the released samples.jsonl files, rather than every extra file
stored in the Hugging Face repository.
After download, the repository should contain:
data/<task_id>/samples.jsonl
data/<task_id>/audio/**
The GitHub repository also includes the evaluation runner:
python scripts/run_eval.py \
  --task content_editing \
  --output-dir outputs/my_model/content_editing \
  --model-name my_model
See the GitHub documentation for evaluator dependencies, output naming conventions, and task-specific metrics.
Data Format
Each samples.jsonl row is a JSON object. Common fields include:
sample_id: unique sample identifiertask: task idaudio_path: path to source audioinstruction: natural-language editing instructiontranscript: source transcript when availableanchor: task-specific target metadata used by the evaluatorlanguage:enorzhsource_dataset: source corpus tagbenchmark_version: release version
Some tasks include additional fields such as reference_audio_path for
speaker editing or anchor.target_reference_path for acoustic editing.
Evaluation Summary
SpeechEditBench reports:
- Target success: whether the requested edit is achieved.
- Content preservation: whether the expected transcript is preserved, using ASR-based WER/CER.
- Joint success: whether both target and preservation criteria pass.
Task-specific target metrics include speaker similarity, Gemini-compatible multimodal judges for expressive/paralinguistic attributes, prosody measures, DNSMOS, RT60, and acoustic scene matching. Full evaluator details are available in the GitHub repository.
Citation
@article{zhang2026speecheditbench,
  title={SpeechEditBench: A Bilingual Multi-Attribute Benchmark for Instruction-Guided Speech Editing},
  author={Zhang, Hanlin and Tan, Daxin and Tao, Dehua and Chen, Xiao and Tan, Haochen and Song, Linqi},
  journal={arXiv preprint arXiv:2606.01804},
  year={2026}
}
License
This dataset is released under the Apache 2.0 license. Users should also respect the licenses and terms of the original speech corpora used to construct the benchmark.
Similar repos
Linked in READMEs
Contributors
68 commits