
README
Learn Agent Architecture
Learn how modern AI agents are built around the LLM.


English · 繁體中文 · 简体中文 · 日本語 · 한국어
The model reasons. The harness turns that reasoning into controlled action: it runs tools, keeps state across calls, gates side effects, and coordinates loops. A model call cannot do any of those things by itself.
This repo explains the harness section by section: loop, tools, memory, permissions, context, tasks, and interfaces. Learn it once and you can read many agents, since a coding tool, chat assistant, and autonomous runner mostly differ in harness choices.
Three companion repos go deeper than one section can:
- learn-agent-memory: scales the memory loop into a production memory subsystem.
- learn-deepseek-harness: learns deepseek-harness from scratch, one plugin seam at a time.
- EvalGrill: turns real cases from agent applications into reproducible, verifiable eval sets.
Contents: Loop · Method · Systems · Sections · Structure · Running
The Agent Loop
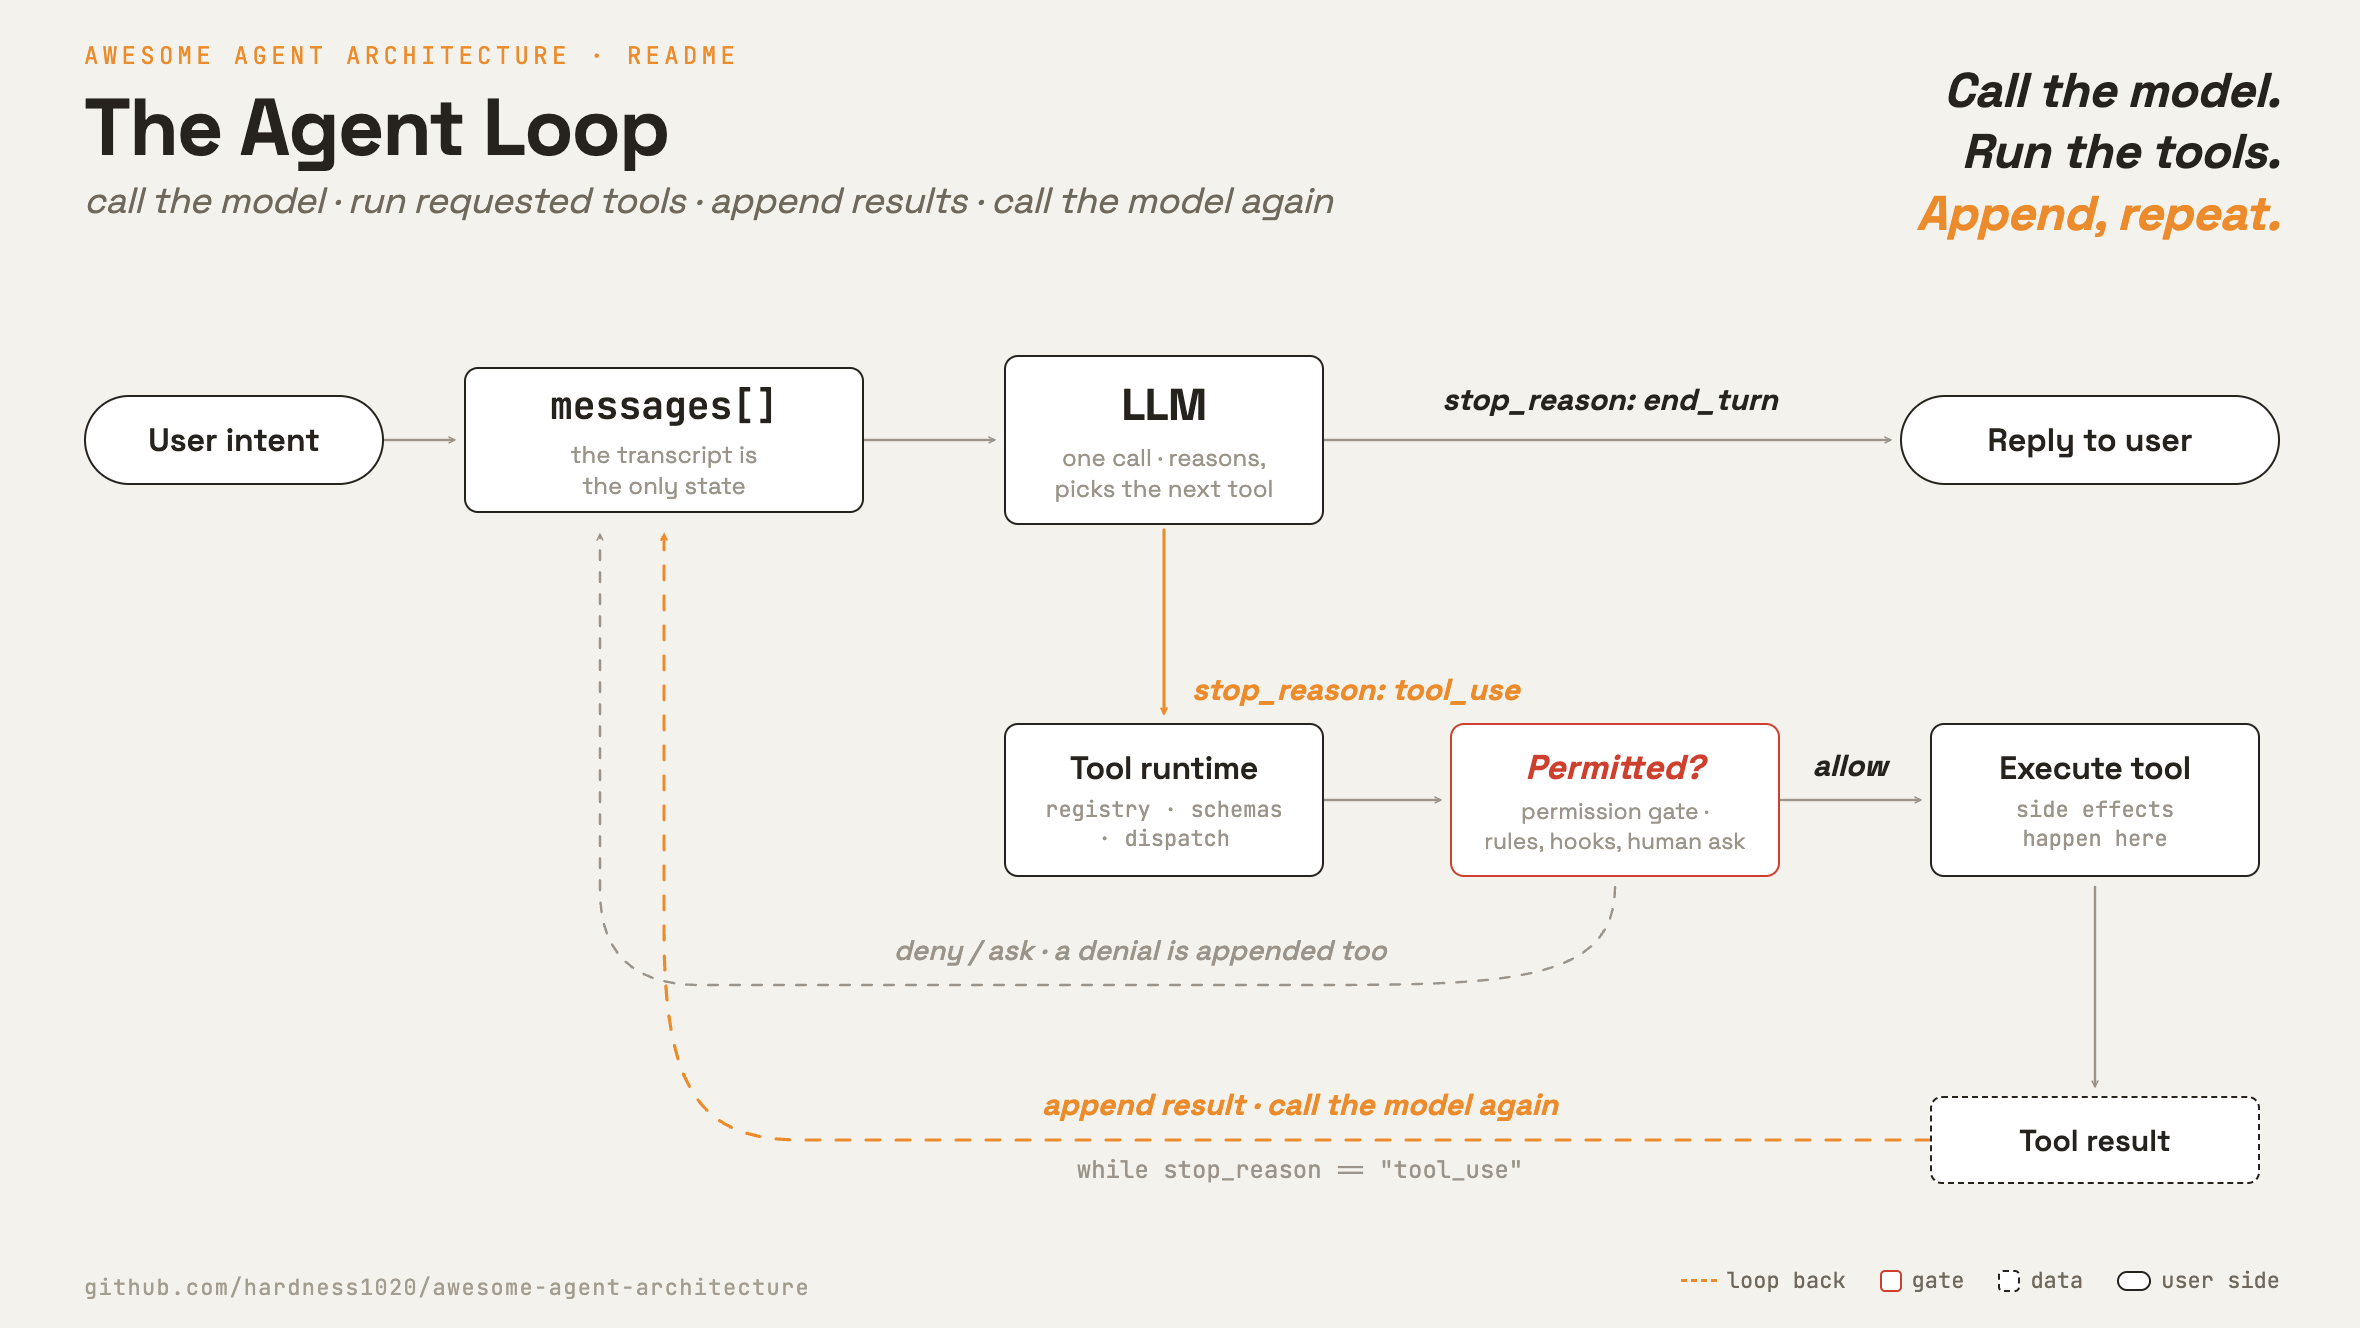
Most agents share the same control flow: call the model, run requested tools, append results, and call the model again.
The loop is small. Most engineering is around it: dispatch tools, gate side effects, manage context, persist state, and coordinate other loops.
How to learn
Every section is self-contained and uses the same four-part lens:
- Opening. What problem this layer solves.
- Mechanism. The general design and control flow.
- Per system. How real systems implement it.
- Failure modes. What breaks and how to mitigate it.
To learn from this repo:
- Read the sections in order. Each builds on the layer before it.
- For a runnable section, read
src/loop.py, then run itsdemo.py. - Diff a section's
src/against the section before it. The diff is the one mechanism that section adds.
Systems Under Study
Each system is a worked example for the sections below.
| System | Why people use it | Read it for | Sections | Version studied |
|---|---|---|---|---|
| Claude Code | Frontier coding agent: edits files, runs commands, ships changes in real repos. | The full harness, start here | 0 to 23 (all) | v2.1.88 |
| Hermes Agent | Long-term assistant: remembers you, learns workflows, runs anywhere. | Memory, skills, always-on channels | 7, 9, 14, 16, 19, 21, 22 | v2026.7.1 |
| mini-swe-agent | Research baseline: one bash tool, about 150 lines. | The smallest complete loop, budgets, eval harness | 0 to 3, 8, 10, 11, 20 to 23 | v2.4.5 |
| deepseek-harness | Plugin-first harness: even the loop is a replaceable plugin. | Plugin seams, durable session log, ACP | 1 to 8, 10 to 14, 16 to 21 | dsh-v0.1.0-rc.7 |
| (more soon) |
More systems can be added later, including OpenClaw and aider. Two companion repos go deeper: learn-agent-memory for the memory layer, and learn-deepseek-harness for learning deepseek-harness from scratch.
Sections
Eight layers, from the basic loop to a harness that runs itself. Each row links to one self-contained writeup.
Section 9 continues in learn-agent-memory: ten more stages that scale its memory loop to production.
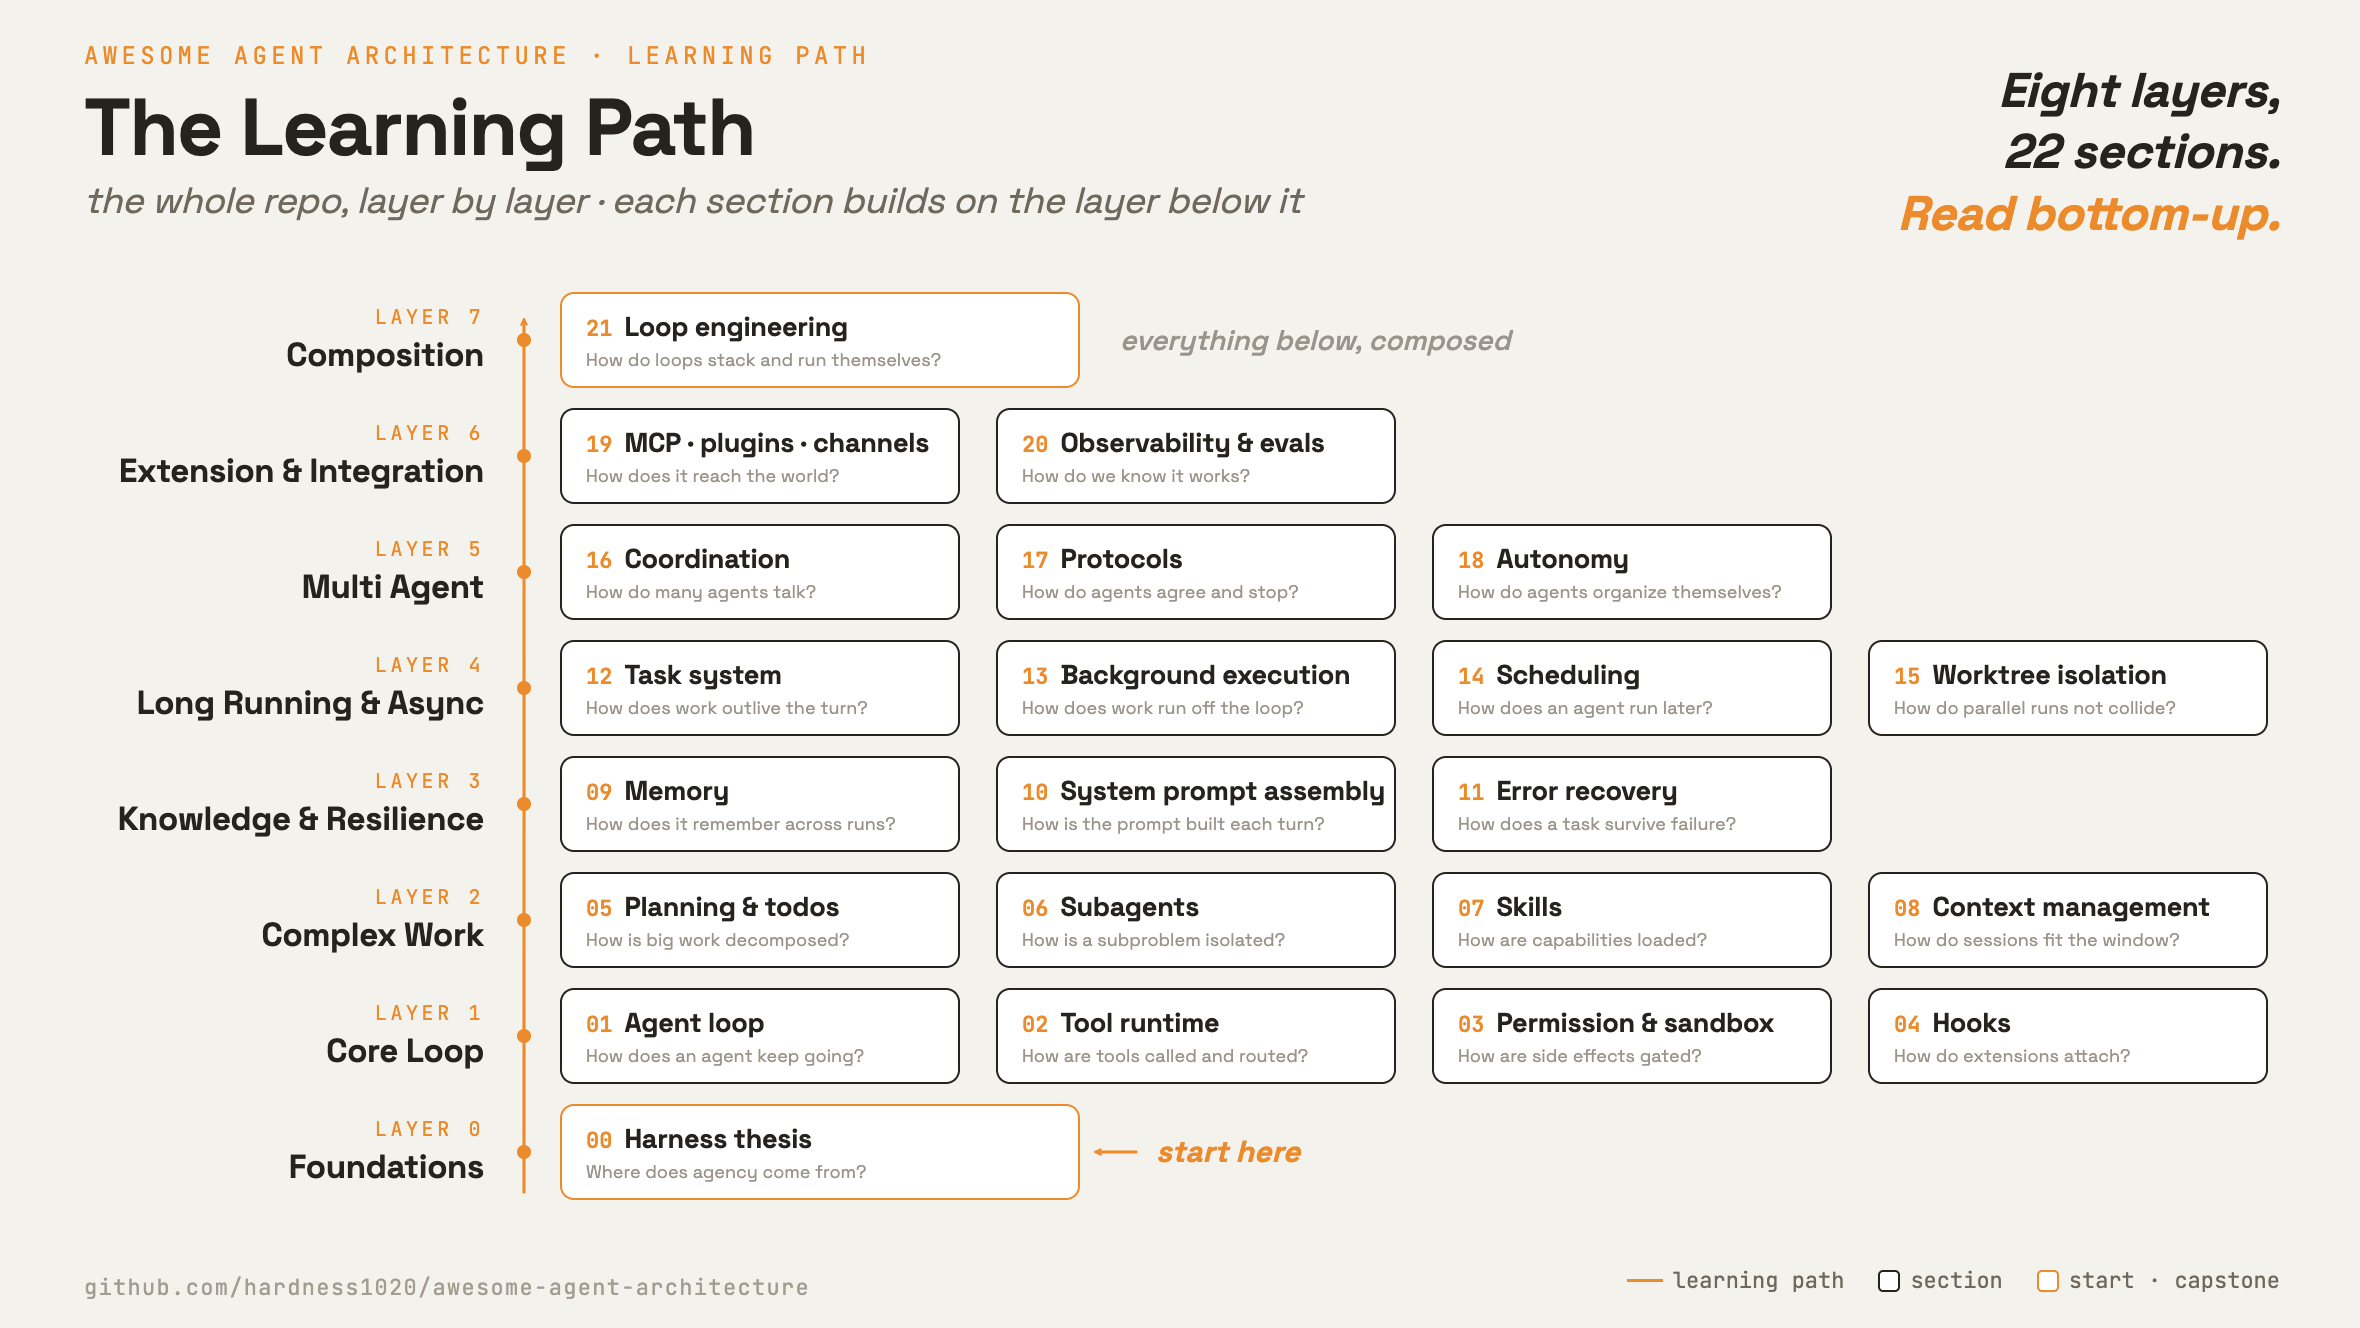
| # | Section | Question | Key mechanisms |
|---|---|---|---|
| Layer 0 · Foundations | |||
| 0 | Harness thesis | Where does agency come from? | Model vs harness, actions, observations, permissions |
| Layer 1 · Core Loop | |||
| 1 | Agent loop | How does an agent keep going? | messages[], loop, stop_reason |
| 2 | Tool runtime | How are tools called and routed? | Registry, schemas, dispatch, deferred search |
| 3 | Permission & sandbox | How are side effects gated? | Permission modes, approvals, sandboxing |
| 4 | Hooks | How do extensions attach to the loop? | PreToolUse, PostToolUse, lifecycle events |
| Layer 2 · Complex Work | |||
| 5 | Planning & todos | How is big work decomposed? | Plan mode, todo list, approval before edits |
| 6 | Subagents | How is a subproblem isolated? | Fresh messages[], delegation, child loop |
| 7 | Skills | How are capabilities loaded on demand? | SKILL.md, catalog, progressive disclosure |
| 8 | Context management | How do long sessions fit the window? | Budgeting, stubs, compaction, summaries |
| Layer 3 · Knowledge & Resilience | |||
| 9 | Memory | How does it remember across runs? | Selection, recall, extraction, consolidation |
| 10 | System prompt assembly | How is the prompt built each turn? | Prompt sections, live state, cache boundaries |
| 11 | Error recovery | How does a long task survive failure? | Retries, overflow recovery, fallback model |
| Layer 4 · Long Running & Async | |||
| 12 | Task system | How does work persist beyond a turn? | Task records, dependencies, locks |
| 13 | Background execution | How does work run off the main loop? | Handles, task state, notification queue |
| 14 | Scheduling | How does an agent run later? | Cron, sleep, remote triggers, queues |
| 15 | Worktree isolation | How does parallel work avoid collisions? | Git worktrees, cwd binding, safe cleanup |
| Layer 5 · Multi Agent | |||
| 16 | Coordination | How do many agents talk? | Inboxes, broadcasts, permission bubbling |
| 17 | Protocols | How do agents agree and stop cleanly? | Plan approval, shutdown handshakes |
| 18 | Autonomy | How do agents organize themselves? | Idle cycle, task claiming, self organization |
| Layer 6 · Extension & Integration | |||
| 19 | MCP / plugins / channels | How does the harness reach the world? | Transports, channels, tool pool assembly |
| 20 | Observability & evaluation | How do we know it works? | Tracing, metrics, evals, failure analysis |
| 23 | Evaluation | How do we know a change made it better? | Eval environments, resets, judges, Pass^k |
| Layer 7 · Composition | |||
| 21 | Loop engineering | How do loops stack into a system that runs itself? | Verification loop, triggers, budgets, maturity levels |
| 22 | Graph engineering | When does control flow move from the model to code? | Nodes, coded edges, cycles, agent nodes, typed decision edges |
Repository Structure
All 24 section writeups are present, from 00-harness-thesis/ through 23-evaluation/.
learn-agent-architecture/
├── README.md                  # top-level map
├── sections/                  # one folder per section
│   ├── 00-harness-thesis/     # README.md per section
│   ├── 01-agent-loop/src/     # runnable chain starts here
│   ├── ...
│   └── 23-evaluation/
└── references/                # primary sources and prior art
Each section folder is NN-name/ and contains a README.md.
Sections 1 to 23 also carry a runnable src/. The code accumulates section by section.
Each section adds one mechanism and evolves loop.py, so a diff between adjacent sections shows what changed.
Deep dives that outgrow one section live in their own repos. learn-agent-memory scales the section 9 loop into a full memory subsystem. learn-deepseek-harness learns deepseek-harness from scratch, one plugin seam at a time.
Running the Demos
Sections 1 to 23 ship runnable demos. Set up once from the repo root:
uv venv
uv pip install -r requirements.txt
cp .env.example .env        # then add your ANTHROPIC_API_KEY
Pinned dependencies are in requirements.txt. .env is gitignored and holds:
ANTHROPIC_API_KEY- optional
ANTHROPIC_MODEL - optional
ANTHROPIC_BASE_URL
Each runnable section has:
test.py: offline checks, no key needed.demo.py: live demo against the API.
python sections/01-agent-loop/src/test.py         # offline
uv run python sections/01-agent-loop/src/demo.py  # live
Contributing
- Add a system. Slot a new agent into the same section structure.
- Deepen a section. Add a mechanism, clearer diagram, or sharper failure mode.
- Correct the record. These are reconstructions from source, docs, and behavior. Sourced corrections are welcome.
Favor named, verifiable mechanisms over speculation. Cite sources. See CONTRIBUTING.md for the full PR checklist.
References
- claude-code: Claude Code source backup used for mechanism names and implementation paths.
- hermes-agent: Open-source agent harness (MIT) used as the second system under study.
- mini-swe-agent: Minimal SWE agent (MIT) used as the third system under study.
- deepseek-harness: Plugin-based agent harness (MIT) used as the fourth system under study.
- learn-claude-code: Code-first harness reconstruction and section framing.
- EvalGrill: companion tool (Apache-2.0) that applies section 23, building eval sets from real agent-application cases.
- Anthropic Agent Skills best practices: Progressive disclosure levels for skills.
- Anthropic prompt caching: Cache breakpoints, TTLs, pricing, and token minimums.
- cobusgreyling/loop-engineering: Loop building blocks and readiness levels.
- LangChain · The art of loop engineering: The four stacked loops.
- Addy Osmani · Loop engineering: Composed building blocks for agent loops.
- MindStudio · What is loop engineering: Goal conditions for autonomous workflows.
- Lilian Weng · Harness engineering for self-improvement: The improvement loop, with gates outside the loop.
- LangChain · 3 years of graph engineering: Nodes, edges, cycles, and agents as nodes.
- Anthropic · Building effective agents: Workflows vs agents and the five workflow shapes.
- Google · Why we built ADK 2.0: Routing in code and context isolation between nodes.
- TypeSafe Jev docs: the request contract and answer shape of a typed decision model.
Section 22 wires one into a graph edge in
decide.py. - ai-agent-book: 《深入理解 AI Agent》 by 李博杰 (Apache-2.0). Chapter 6 grounds the evaluation section.
Acknowledgements
Thanks to these collections for listing this project:
Contributors

194 commits
Similar repos


Languages
Python
100.0%
README
Learn Agent Architecture
Learn how modern AI agents are built around the LLM.
English · 繁體中文 · 简体中文 · 日本語 · 한국어
The model reasons. The harness turns that reasoning into controlled action: it runs tools, keeps state across calls, gates side effects, and coordinates loops. A model call cannot do any of those things by itself.
This repo explains the harness section by section: loop, tools, memory, permissions, context, tasks, and interfaces. Learn it once and you can read many agents, since a coding tool, chat assistant, and autonomous runner mostly differ in harness choices.
Three companion repos go deeper than one section can:
- learn-agent-memory: scales the memory loop into a production memory subsystem.
- learn-deepseek-harness: learns deepseek-harness from scratch, one plugin seam at a time.
- EvalGrill: turns real cases from agent applications into reproducible, verifiable eval sets.
Contents: Loop · Method · Systems · Sections · Structure · Running
The Agent Loop
Most agents share the same control flow: call the model, run requested tools, append results, and call the model again.
The loop is small. Most engineering is around it: dispatch tools, gate side effects, manage context, persist state, and coordinate other loops.
How to learn
Every section is self-contained and uses the same four-part lens:
- Opening. What problem this layer solves.
- Mechanism. The general design and control flow.
- Per system. How real systems implement it.
- Failure modes. What breaks and how to mitigate it.
To learn from this repo:
- Read the sections in order. Each builds on the layer before it.
- For a runnable section, read
src/loop.py, then run itsdemo.py. - Diff a section's
src/against the section before it. The diff is the one mechanism that section adds.
Systems Under Study
Each system is a worked example for the sections below.
| System | Why people use it | Read it for | Sections | Version studied |
|---|---|---|---|---|
| Claude Code | Frontier coding agent: edits files, runs commands, ships changes in real repos. | The full harness, start here | 0 to 23 (all) | v2.1.88 |
| Hermes Agent | Long-term assistant: remembers you, learns workflows, runs anywhere. | Memory, skills, always-on channels | 7, 9, 14, 16, 19, 21, 22 | v2026.7.1 |
| mini-swe-agent | Research baseline: one bash tool, about 150 lines. | The smallest complete loop, budgets, eval harness | 0 to 3, 8, 10, 11, 20 to 23 | v2.4.5 |
| deepseek-harness | Plugin-first harness: even the loop is a replaceable plugin. | Plugin seams, durable session log, ACP | 1 to 8, 10 to 14, 16 to 21 | dsh-v0.1.0-rc.7 |
| (more soon) |
More systems can be added later, including OpenClaw and aider. Two companion repos go deeper: learn-agent-memory for the memory layer, and learn-deepseek-harness for learning deepseek-harness from scratch.
Sections
Eight layers, from the basic loop to a harness that runs itself. Each row links to one self-contained writeup.
Section 9 continues in learn-agent-memory: ten more stages that scale its memory loop to production.
| # | Section | Question | Key mechanisms |
|---|---|---|---|
| Layer 0 · Foundations | |||
| 0 | Harness thesis | Where does agency come from? | Model vs harness, actions, observations, permissions |
| Layer 1 · Core Loop | |||
| 1 | Agent loop | How does an agent keep going? | messages[], loop, stop_reason |
| 2 | Tool runtime | How are tools called and routed? | Registry, schemas, dispatch, deferred search |
| 3 | Permission & sandbox | How are side effects gated? | Permission modes, approvals, sandboxing |
| 4 | Hooks | How do extensions attach to the loop? | PreToolUse, PostToolUse, lifecycle events |
| Layer 2 · Complex Work | |||
| 5 | Planning & todos | How is big work decomposed? | Plan mode, todo list, approval before edits |
| 6 | Subagents | How is a subproblem isolated? | Fresh messages[], delegation, child loop |
| 7 | Skills | How are capabilities loaded on demand? | SKILL.md, catalog, progressive disclosure |
| 8 | Context management | How do long sessions fit the window? | Budgeting, stubs, compaction, summaries |
| Layer 3 · Knowledge & Resilience | |||
| 9 | Memory | How does it remember across runs? | Selection, recall, extraction, consolidation |
| 10 | System prompt assembly | How is the prompt built each turn? | Prompt sections, live state, cache boundaries |
| 11 | Error recovery | How does a long task survive failure? | Retries, overflow recovery, fallback model |
| Layer 4 · Long Running & Async | |||
| 12 | Task system | How does work persist beyond a turn? | Task records, dependencies, locks |
| 13 | Background execution | How does work run off the main loop? | Handles, task state, notification queue |
| 14 | Scheduling | How does an agent run later? | Cron, sleep, remote triggers, queues |
| 15 | Worktree isolation | How does parallel work avoid collisions? | Git worktrees, cwd binding, safe cleanup |
| Layer 5 · Multi Agent | |||
| 16 | Coordination | How do many agents talk? | Inboxes, broadcasts, permission bubbling |
| 17 | Protocols | How do agents agree and stop cleanly? | Plan approval, shutdown handshakes |
| 18 | Autonomy | How do agents organize themselves? | Idle cycle, task claiming, self organization |
| Layer 6 · Extension & Integration | |||
| 19 | MCP / plugins / channels | How does the harness reach the world? | Transports, channels, tool pool assembly |
| 20 | Observability & evaluation | How do we know it works? | Tracing, metrics, evals, failure analysis |
| 23 | Evaluation | How do we know a change made it better? | Eval environments, resets, judges, Pass^k |
| Layer 7 · Composition | |||
| 21 | Loop engineering | How do loops stack into a system that runs itself? | Verification loop, triggers, budgets, maturity levels |
| 22 | Graph engineering | When does control flow move from the model to code? | Nodes, coded edges, cycles, agent nodes, typed decision edges |
Repository Structure
All 24 section writeups are present, from 00-harness-thesis/ through 23-evaluation/.
learn-agent-architecture/
├── README.md                  # top-level map
├── sections/                  # one folder per section
│   ├── 00-harness-thesis/     # README.md per section
│   ├── 01-agent-loop/src/     # runnable chain starts here
│   ├── ...
│   └── 23-evaluation/
└── references/                # primary sources and prior art
Each section folder is NN-name/ and contains a README.md.
Sections 1 to 23 also carry a runnable src/. The code accumulates section by section.
Each section adds one mechanism and evolves loop.py, so a diff between adjacent sections shows what changed.
Deep dives that outgrow one section live in their own repos. learn-agent-memory scales the section 9 loop into a full memory subsystem. learn-deepseek-harness learns deepseek-harness from scratch, one plugin seam at a time.
Running the Demos
Sections 1 to 23 ship runnable demos. Set up once from the repo root:
uv venv
uv pip install -r requirements.txt
cp .env.example .env        # then add your ANTHROPIC_API_KEY
Pinned dependencies are in requirements.txt. .env is gitignored and holds:
ANTHROPIC_API_KEY- optional
ANTHROPIC_MODEL - optional
ANTHROPIC_BASE_URL
Each runnable section has:
test.py: offline checks, no key needed.demo.py: live demo against the API.
python sections/01-agent-loop/src/test.py         # offline
uv run python sections/01-agent-loop/src/demo.py  # live
Contributing
- Add a system. Slot a new agent into the same section structure.
- Deepen a section. Add a mechanism, clearer diagram, or sharper failure mode.
- Correct the record. These are reconstructions from source, docs, and behavior. Sourced corrections are welcome.
Favor named, verifiable mechanisms over speculation. Cite sources. See CONTRIBUTING.md for the full PR checklist.
References
- claude-code: Claude Code source backup used for mechanism names and implementation paths.
- hermes-agent: Open-source agent harness (MIT) used as the second system under study.
- mini-swe-agent: Minimal SWE agent (MIT) used as the third system under study.
- deepseek-harness: Plugin-based agent harness (MIT) used as the fourth system under study.
- learn-claude-code: Code-first harness reconstruction and section framing.
- EvalGrill: companion tool (Apache-2.0) that applies section 23, building eval sets from real agent-application cases.
- Anthropic Agent Skills best practices: Progressive disclosure levels for skills.
- Anthropic prompt caching: Cache breakpoints, TTLs, pricing, and token minimums.
- cobusgreyling/loop-engineering: Loop building blocks and readiness levels.
- LangChain · The art of loop engineering: The four stacked loops.
- Addy Osmani · Loop engineering: Composed building blocks for agent loops.
- MindStudio · What is loop engineering: Goal conditions for autonomous workflows.
- Lilian Weng · Harness engineering for self-improvement: The improvement loop, with gates outside the loop.
- LangChain · 3 years of graph engineering: Nodes, edges, cycles, and agents as nodes.
- Anthropic · Building effective agents: Workflows vs agents and the five workflow shapes.
- Google · Why we built ADK 2.0: Routing in code and context isolation between nodes.
- TypeSafe Jev docs: the request contract and answer shape of a typed decision model.
Section 22 wires one into a graph edge in
decide.py. - ai-agent-book: 《深入理解 AI Agent》 by 李博杰 (Apache-2.0). Chapter 6 grounds the evaluation section.
Acknowledgements
Thanks to these collections for listing this project:
Similar repos
Contributors
194 commits
Languages
Python
100.0%