
The official GitHub page for the paper "Agent Systems with Harness Engineering"
See the codeREADME
Agent Systems with Harness Engineering
A Curated Reading List and Structured Roadmap



A curated list of papers and resources on agent systems with harness engineering, based on our paper:
"Agent Systems with Harness Engineering".
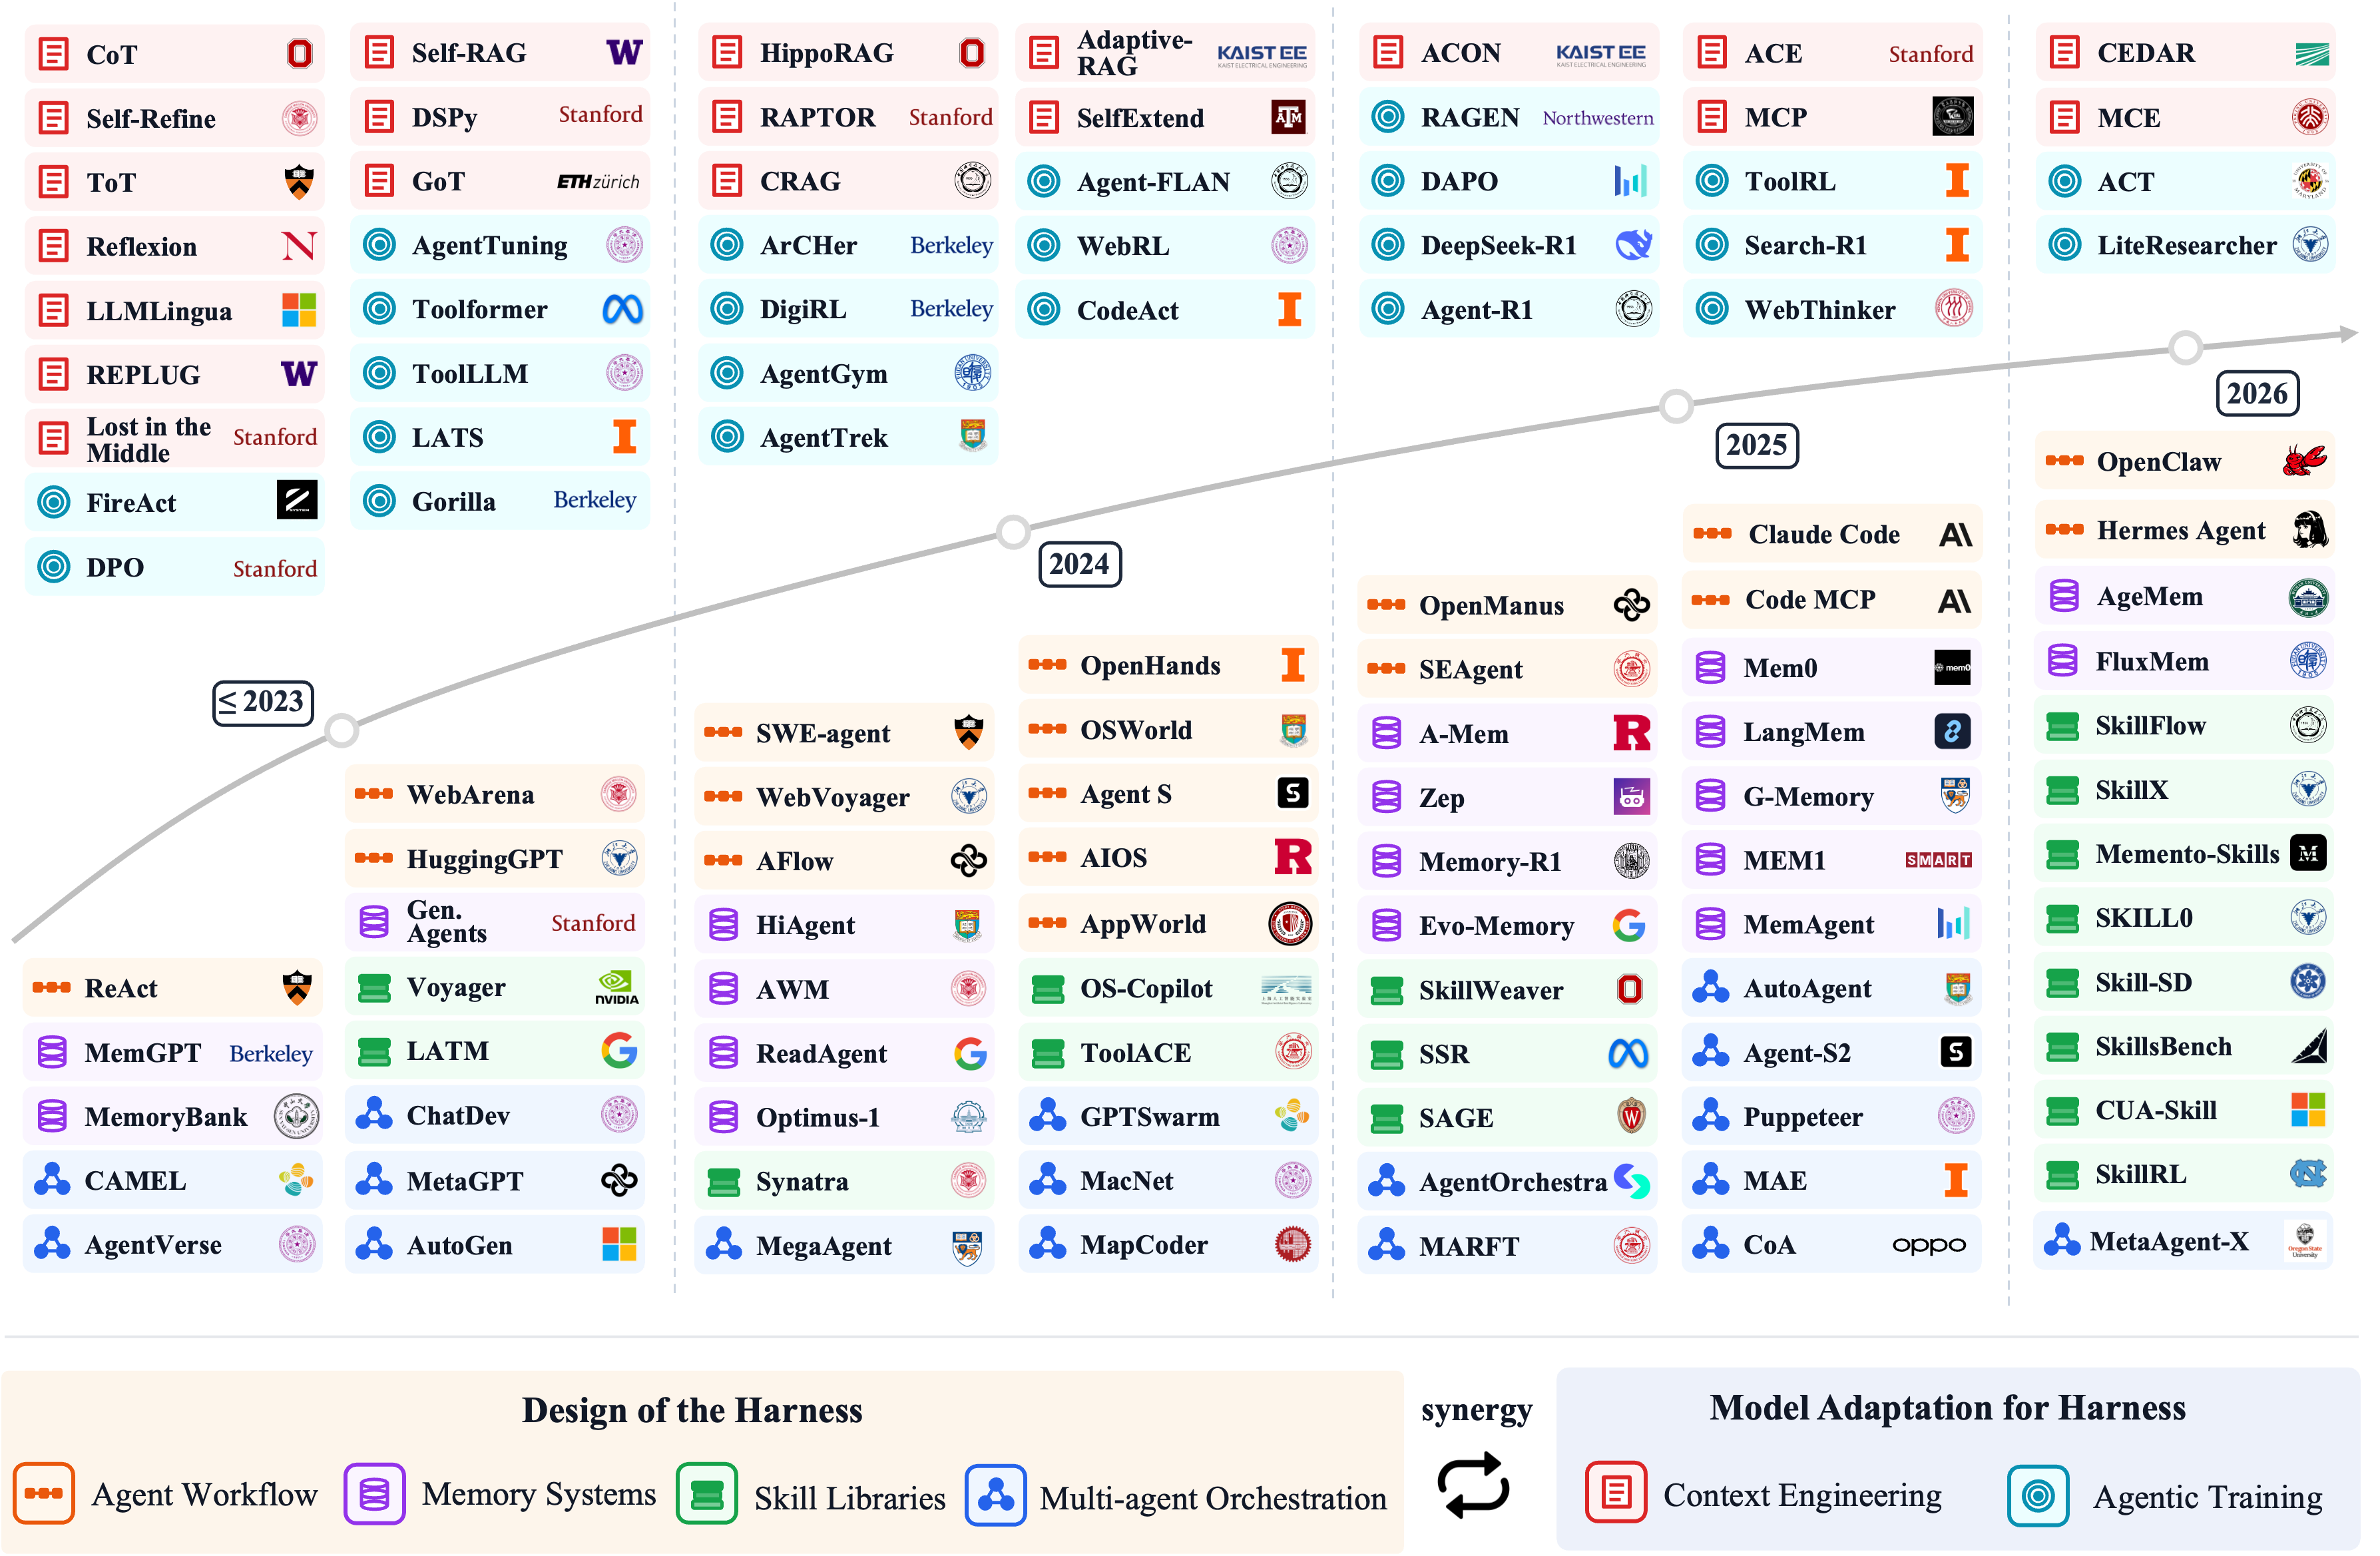
Timeline of agent systems with harness engineering.
Tip: If you have any questions for our paper, please send an email to txy20010310@163.com.
Table of Contents
- 1. Evolution of Harness Engineering
- 2. The Design of the Harness
- 3. Model Adaptation for Harness
- 4. Representative Benchmarks by Task Domain
- 5. Future Directions
- Citation
1. Evolution of Harness Engineering
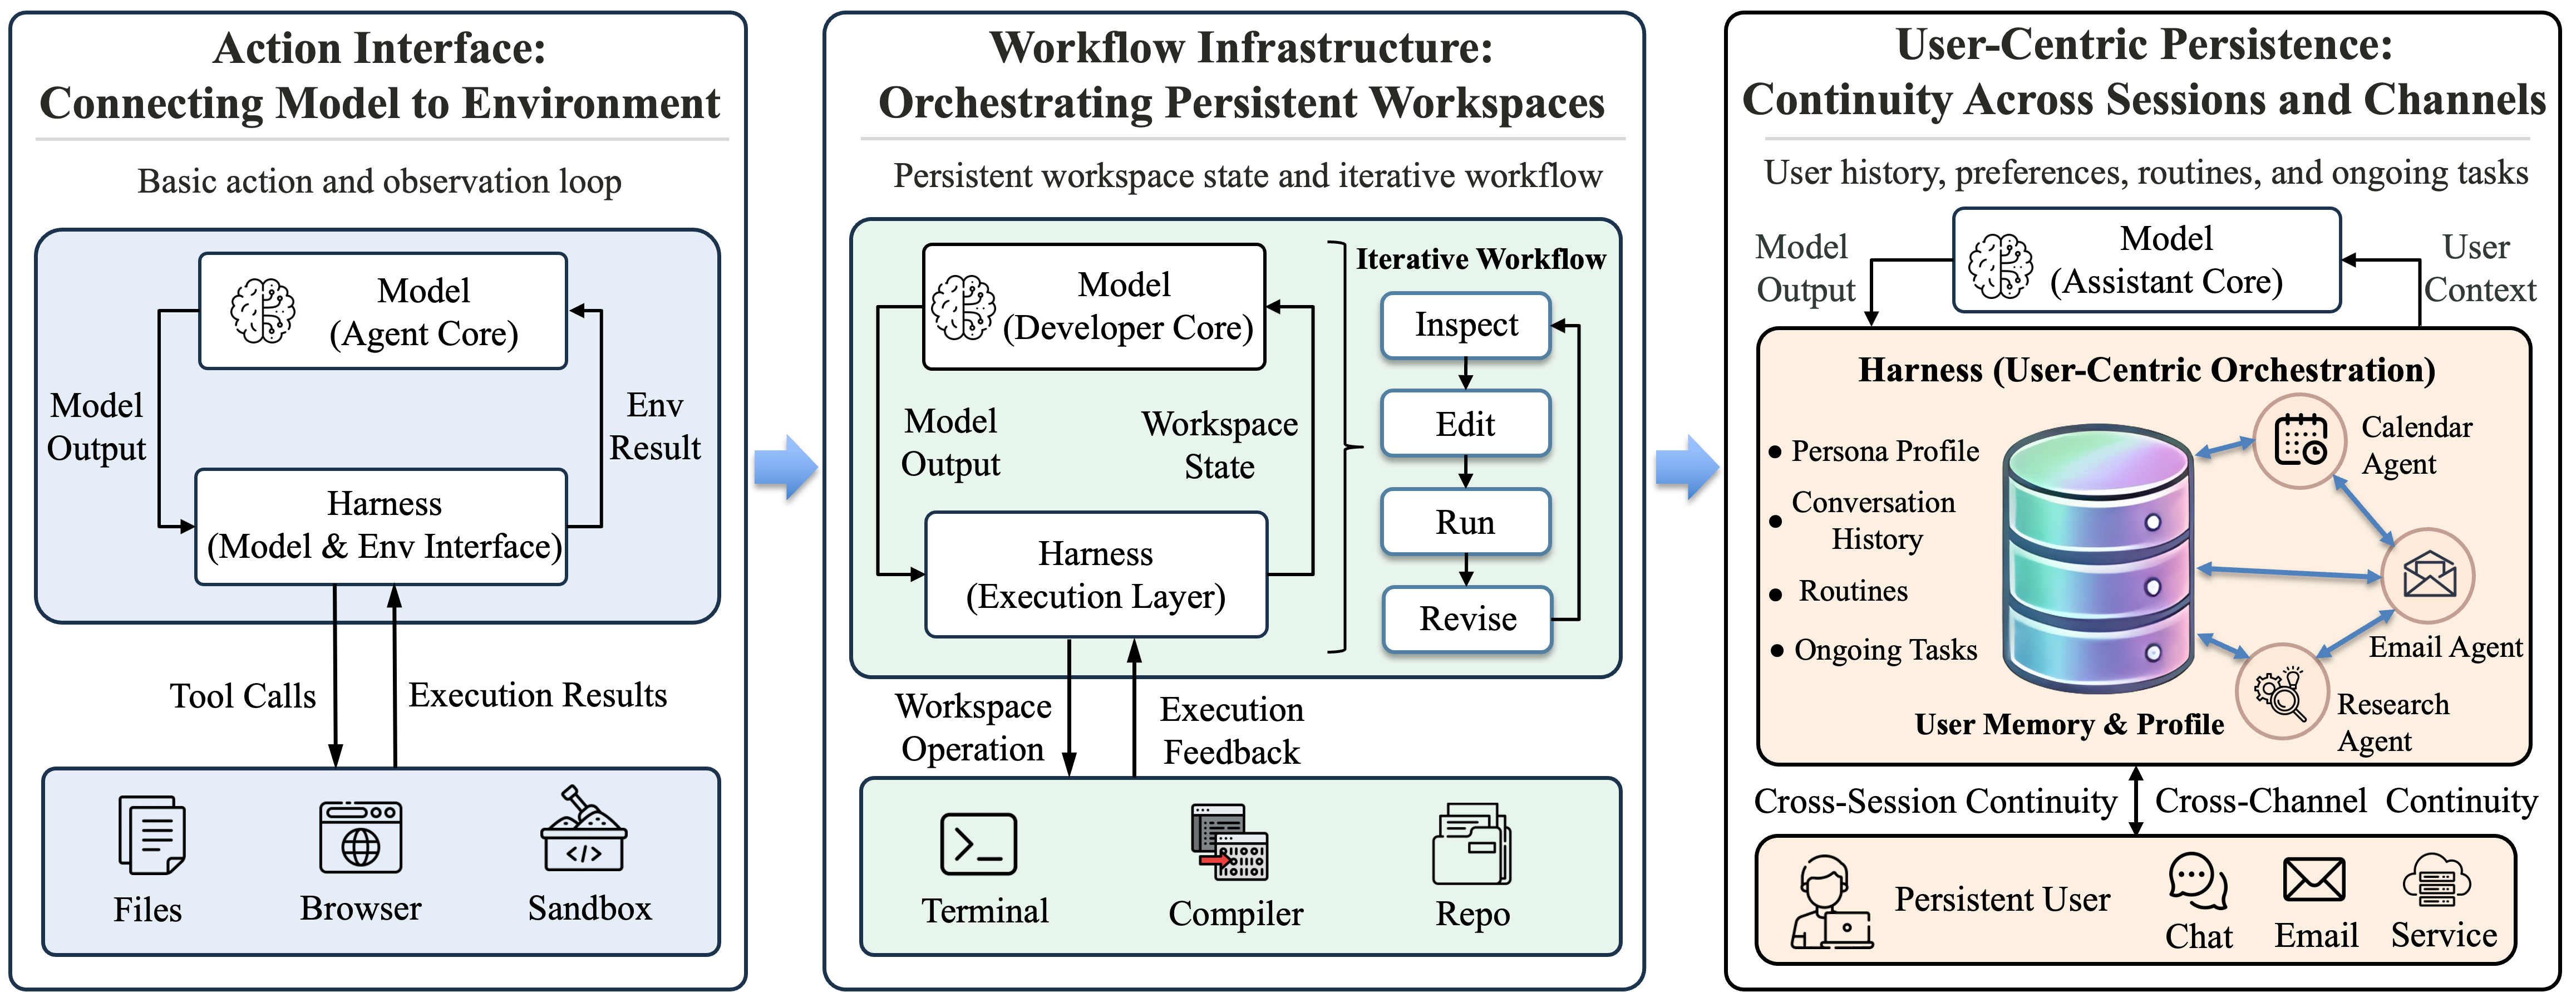
Three layers in the evolution of harness architecture.
1.1. Action Interface: Connecting Model to Environment
- Quine: Realizing LLM Agents as Native POSIX Processes. [Paper]
arXiv 2026 - ceLLMate: Sandboxing Browser AI Agents. [Paper]
arXiv 2025 - Executable Code Actions Elicit Better LLM Agents. [Paper]
ICML 2024 - DeepAgent: A General Reasoning Agent with Scalable Toolsets. [Paper]
arXiv 2025 - ReAct: Synergizing Reasoning and Acting in Language Models. [Paper] [Code]
ICLR 2023 - Toolformer: Language Models Can Teach Themselves to Use Tools. [Paper]
NeurIPS 2023 - Tool learning with large language models: a survey. [Paper]
FCS 2025 - AIOS: LLM Agent Operating System. [Paper]
COLM 2025
1.2. Workflow Infrastructure: Orchestrating Persistent Workspaces
- SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering. [Paper] [Code]
NeurIPS 2024 - Engineering Pitfalls in AI Coding Tools: An Empirical Study of Bugs in Claude Code, Codex, and Gemini CLI. [Paper]
arXiv 2026 - Building Effective AI Coding Agents for the Terminal: Scaffolding, Harness, Context Engineering, and Lessons Learned. [Paper]
arXiv 2026 - SWE-Master: Unleashing the Potential of Software Engineering Agents via Post-Training. [Paper]
arXiv 2026 - VeRO: An Evaluation Harness for Agents to Optimize Agents. [Paper]
ICML 2026 - OpenHands: An Open Platform for AI Software Developers as Generalist Agents. [Paper]
ICLR 2025 - Claude Code Overview. [Docs]
Docs 2026
1.3. User-Centric Persistence: Continuity Across Sessions and Channels
- Toward Personalized LLM-Powered Agents: Foundations, Evaluation, and Future Directions. [Paper]
arXiv 2026 - Enabling Personalized Long-term Interactions in LLM-based Agents through Persistent Memory and User Profiles. [Paper]
arXiv 2025 - User Preference Modeling for Conversational LLM Agents: Weak Rewards from Retrieval-Augmented Interaction. [Paper]
arXiv 2026 - From Human Memory to AI Memory: A Survey on Memory Mechanisms in the Era of LLMs. [Paper]
arXiv 2025 - Persistent Assistant: Seamless Everyday AI Interactions via Intent Grounding and Multimodal Feedback. [Paper]
CHI 2025 - Introducing OpenClaw. [Blog]
Blog 2026
2. The Design of the Harness
2.1. Agent Workflow
- HuggingGPT: Solving AI Tasks with ChatGPT and its Friends in Hugging Face. [Paper] [Code]
NeurIPS 2023 - OpenManus: An Open-source Framework for Building General AI Agents. [Code]
Repo 2025 - Unrolling the Codex agent loop. [Blog]
Blog 2026 - OpenClaw. [Code] [Website]
Repo 2026 - Hermes Agent. [Website]
Website 2026
2.1.1. Environment Perception
Observation Extraction
- Mind2Web: Towards a Generalist Agent for the Web. [Paper] [Code]
NeurIPS 2023 - WebArena: A Realistic Web Environment for Building Autonomous Agents. [Paper] [Code]
ICLR 2024 - WebVoyager: Building an End-to-End Web Agent with Large Multimodal Models. [Paper] [Code]
ACL 2024 - VisualWebArena: Evaluating Multimodal Agents on Realistic Visual Web Tasks. [Paper] [Code]
ACL 2024 - GPT-4V(ision) is a Generalist Web Agent, if Grounded. [Paper]
ICML 2024 - SeeClick: Harnessing GUI Grounding for Advanced Visual GUI Agents. [Paper]
ACL 2024 - OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments. [Paper] [Code]
NeurIPS 2024 - DigiRL: Training In-The-Wild Device-Control Agents with Autonomous Reinforcement Learning. [Paper] [Code]
NeurIPS 2024 - AgentOccam: A Simple Yet Strong Baseline for LLM-Based Web Agents. [Paper]
ICLR 2025 - Agent S: An Open Agentic Framework that Uses Computers Like a Human. [Paper] [Code]
ICLR 2025 Workshop - AndroidWorld: A Dynamic Benchmarking Environment for Autonomous Agents. [Paper] [Code]
ICLR 2025 - GUI-Actor: Coordinate-Free Visual Grounding for GUI Agents. [Paper] [Code]
NeurIPS 2025 - VAGEN: Reinforcing World Model Reasoning for Multi-Turn VLM Agents. [Paper]
NeurIPS 2025
State Representation
- ToolLLM: Facilitating Large Language Models to Master 16000+ Real-world APIs. [Paper] [Code]
ICLR 2024 - WebArena: A Realistic Web Environment for Building Autonomous Agents. [Paper] [Code]
ICLR 2024 - SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering. [Paper] [Code]
NeurIPS 2024 - Do LLMs Build World Representations? Probing Through the Lens of State Abstraction. [Paper] [Code]
NeurIPS 2024 - AgentOccam: A Simple Yet Strong Baseline for LLM-Based Web Agents. [Paper]
ICLR 2025 - AgentTrek: Agent Trajectory Synthesis via Guiding Replay with Web Tutorials. [Paper] [Code]
ICLR 2025 - GRAPHGPT-O: Synergistic Multimodal Comprehension and Generation on Graphs. [Paper] [Code]
CVPR 2025 - The Complexity Trap: Simple Observation Masking Is as Efficient as LLM Summarization for Agent Context Management. [Paper]
arXiv 2025 - ESCA: Contextualizing Embodied Agents via Scene-Graph Generation. [Paper] [Code]
NeurIPS 2025 - Evaluating LLM Planning in Partially Observable Environments via Observation Representations and Action Sequences. [Paper]
NeurIPS 2025 Workshop - DynaWeb: Model-Based Reinforcement Learning of Web Agents. [Paper]
arXiv 2026 - Building a C compiler with a team of parallel Claudes. [Blog]
Blog 2026
2.1.2. Task Planning
Task Decomposition
- Chain-of-Thought Prompting Elicits Reasoning in Large Language Models. [Paper] [Code]
NeurIPS 2022 - Least-to-Most Prompting Enables Complex Reasoning in Large Language Models. [Paper]
ICLR 2023 - Tree of Thoughts: Deliberate Problem Solving with Large Language Models. [Paper] [Code]
NeurIPS 2023 - Graph of Thoughts: Solving Elaborate Problems with Large Language Models. [Paper] [Code]
AAAI 2024 - Agentic Reasoning: A Streamlined Framework for Enhancing LLM Reasoning with Agentic Tools. [Paper]
ACL 2025 - Agentic Reasoning for Large Language Models. [Paper]
arXiv 2026 - Building a C compiler with a team of parallel Claudes. [Blog]
Blog 2026
Plan Generation
- AvaTaR: Optimizing LLM Agents for Tool Usage via Contrastive Reasoning. [Paper] [Code]
NeurIPS 2024 - AFlow: Automating Agentic Workflow Generation. [Paper] [Code]
ICLR 2025 - GAP: Graph-Based Agent Planning with Parallel Tool Use and Reinforcement Learning. [Paper] [Code]
arXiv 2025
2.1.3. Action Execution
Tool Invocation
- Toolformer: Language Models Can Teach Themselves to Use Tools. [Paper]
NeurIPS 2023 - Code as Policies: Language Model Programs for Embodied Control. [Paper] [Code]
ICRA 2023 - SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering. [Paper] [Code]
NeurIPS 2024 - AppWorld: A Controllable World of Apps and People for Benchmarking Interactive Coding Agents. [Paper] [Code]
ACL 2024 - Code execution with MCP: building more efficient AI agents. [Blog]
Blog 2025 - Agent0-VL: Exploring Self-Evolving Agent for Tool-Integrated Vision-Language Reasoning. [Paper]
arXiv 2025 - Scaling Agentic Reinforcement Learning for Tool-Integrated Reasoning in VLMs. [Paper]
arXiv 2025 - Robust Tool Use via Fission-GRPO: Learning to Recover from Execution Errors. [Paper]
arXiv 2026
Environment Interaction
- ReAct: Synergizing Reasoning and Acting in Language Models. [Paper] [Code]
ICLR 2023 - SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering. [Paper] [Code]
NeurIPS 2024 - Grounding Multimodal Large Language Models in Actions. [Paper]
NeurIPS 2024 - ceLLMate: Sandboxing Browser AI Agents. [Paper]
arXiv 2025 - Agent-Fence: Mapping Security Vulnerabilities Across Deep Research Agents. [Paper]
arXiv 2026 - Quine: Realizing LLM Agents as Native POSIX Processes. [Paper]
arXiv 2026
2.2. Memory Systems
2.2.1. Short-term Memory
Working Memory
- ReAct: Synergizing Reasoning and Acting in Language Models. [Paper] [Code]
ICLR 2023 - ReadAgent: A Human-Inspired Reading Agent with Gist Memory of Very Long Contexts. [Paper] [Code]
ICML 2024 - Agent Workflow Memory. [Paper] [Code]
ICML 2025 - Understanding Software Engineering Agents: A Study of Thought-Action-Result Trajectories. [Paper]
ASE 2025 - Memo: Training Memory-Efficient Embodied Agents with Reinforcement Learning. [Paper] [Code]
NeurIPS 2025 - Managing Context on the Claude Developer Platform. [Blog]
Blog 2025 - Graph-based Agent Memory: Taxonomy, Techniques, and Applications. [Paper]
arXiv 2026
Conversational Memory
- MemGPT: Towards LLMs as Operating Systems. [Paper] [Code]
arXiv 2023 - Zep: A Temporal Knowledge Graph Architecture for Agent Memory. [Paper]
arXiv 2025 - From Isolated Conversations to Hierarchical Schemas: Dynamic Tree Memory Representation for LLMs. [Paper]
ICLR 2025 - SeCom: On Memory Construction and Retrieval for Personalized Conversational Agents. [Paper]
ICLR 2025 - Hello Again! LLM-powered Personalized Agent for Long-term Dialogue. [Paper]
NAACL 2025 - SGMem: Sentence Graph Memory for Long-Term Conversational Agents. [Paper]
arXiv 2025 - Managing Context on the Claude Developer Platform. [Blog]
Blog 2025 - Agentic Memory: Learning Unified Long-Term and Short-Term Memory Management for Large Language Model Agents. [Paper]
arXiv 2026 - From Single to Multi-Granularity: Toward Long-Term Memory Association and Selection of Conversational Agents. [Paper]
ICLR 2026 - FluxMem: Adaptive Hierarchical Memory for Streaming Video Understanding. [Paper]
CVPR 2026
2.2.2. Long-term Memory
Structured Memory
- Generative Agents: Interactive Simulacra of Human Behavior. [Paper] [Code]
UIST 2023 - Optimus-1: Hybrid Multimodal Memory Empowered Agents Excel in Long-Horizon Tasks. [Paper] [Code]
NeurIPS 2024 - A-Mem: Agentic Memory for LLM Agents. [Paper] [Code]
NeurIPS 2025 - Bridging Intuitive Associations and Deliberate Recall: Empowering LLM Personal Assistant with Graph-Structured Long-term Memory. [Paper]
Findings of ACL 2025 - CarMem: Enhancing Long-Term Memory in LLM Voice Assistants through Category-Bounding. [Paper]
COLING 2025 - Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory. [Paper] [Code]
ECAI 2025 - G-Memory: Tracing Hierarchical Memory for Multi-Agent Systems. [Paper] [Code]
NeurIPS 2025 - Graph-Native Cognitive Memory for AI Agents: Formal Belief Revision Semantics for Versioned Memory Architectures. [Paper]
arXiv 2026
Unstructured Memory
- MemGPT: Towards LLMs as Operating Systems. [Paper] [Code]
arXiv 2023 - Reflexion: language agents with verbal reinforcement learning. [Paper] [Code]
NeurIPS 2023 - MemoryBank: Enhancing Large Language Models with Long-Term Memory. [Paper] [Code]
AAAI 2024 - Memory-R1: Enhancing Large Language Model Agents to Manage and Utilize Memories via Reinforcement Learning. [Paper] [Code]
arXiv 2025 - MOOM: Maintenance, Organization and Optimization of Memory in Ultra-Long Role-Playing Dialogues. [Paper]
arXiv 2025 - O-Mem: Omni Memory System for Personalized, Long Horizon, Self-Evolving Agents. [Paper]
arXiv 2025 - General Agentic Memory Via Deep Research. [Paper]
arXiv 2025 - Evo-Memory: Benchmarking LLM Agent Test-time Learning with Self-Evolving Memory. [Paper] [Code]
arXiv 2025 - MEM1: Learning to Synergize Memory and Reasoning for Efficient Long-Horizon Agents. [Paper] [Code]
ICLR 2026 - MemAgent: Reshaping Long-Context LLM with Multi-Conv RL-based Memory Agent. [Paper] [Code]
ICLR 2026 - RetroAgent: From Solving to Evolving via Retrospective Dual Intrinsic Feedback. [Paper]
arXiv 2026 - Agentic Memory: Learning Unified Long-Term and Short-Term Memory Management for Large Language Model Agents. [Paper]
arXiv 2026 - Mem0: Universal Memory Layer for AI Agents. [Code]
Repo 2026 - OpenMemory: AI Memory MCP Server for Coding Agents. [Website]
Web 2026 - Memory - Docs by LangChain. [Docs]
Docs 2026 - Context Engineering: Memory, Compaction, and Tool Clearing. [Docs]
Docs 2026
2.3. Skill Libraries
- SkillsBench: Benchmarking How Well Agent Skills Work Across Diverse Tasks. [Paper] [Code]
arXiv 2026 - Memory - Docs by LangChain. [Docs]
Docs 2026 - SkillX: Automatically Constructing Skill Knowledge Bases for Agents. [Paper]
arXiv 2026
2.3.1. Skill Acquisition
Learning from Demonstration
- Toolformer: Language Models Can Teach Themselves to Use Tools. [Paper]
NeurIPS 2023 - Large Language Models as Tool Makers. [Paper] [Code]
ICLR 2024 - Gorilla: Large Language Model Connected with Massive APIs. [Paper]
NeurIPS 2024 - Voyager: An Open-Ended Embodied Agent with Large Language Models. [Paper] [Code]
TMLR 2024 - Synatra: Turning Indirect Knowledge into Direct Demonstrations for Digital Agents at Scale. [Paper]
NeurIPS 2024 - ToolACE: Winning the Points of LLM Function Calling. [Paper] [Code]
ICLR 2025 - SkillWeaver: Web Agents can Self-Improve by Discovering and Honing Skills. [Paper]
arXiv 2025 - Agent Skill Acquisition for Large Language Models via CycleQD. [Paper] [Code]
arXiv 2025 - Inducing Programmatic Skills for Agentic Tasks. [Paper]
COLM 2025 - SoK: Agentic Skills - Beyond Tool Use in LLM Agents. [Paper]
arXiv 2026 - Agent Skills for Large Language Models: Architecture, Acquisition, Security, and the Path Forward. [Paper]
arXiv 2026 - SkillCraft: Can LLM Agents Learn to Use Tools Skillfully? [Paper] [Code]
arXiv 2026 - Trace2Skill: Distill Trajectory-Local Lessons into Transferable Agent Skills. [Paper]
arXiv 2026 - Go-Browse: Training Web Agents with Structured Exploration. [Paper]
ICLR 2026 - ContractSkill: Repairable Contract-Based Skills for Multimodal Web Agents. [Paper]
arXiv 2026
Learning from Experience
- Hierarchical Reinforcement Learning: A Survey and Open Research Challenges. [Paper]
MAKE 2022 - ExpeL: LLM Agents Are Experiential Learners. [Paper] [Code]
AAAI 2024 - OS-Copilot: Towards Generalist Computer Agents with Self-Improvement. [Paper] [Code]
ICLR 2024 - SEAgent: Self-Evolving Computer Use Agent with Autonomous Learning from Experience. [Paper] [Code]
arXiv 2025 - Leveraging Skills from Unlabeled Prior Data for Efficient Online Exploration. [Paper] [Code]
ICML 2025 - Reinforcement Learning for Self-Improving Agent with Skill Library. [Paper] [Code]
arXiv 2025 - Toward Training Superintelligent Software Agents through Self-Play SWE-RL. [Paper] [Code]
ICML 2026 - Evolving Programmatic Skill Networks. [Paper]
arXiv 2026 - SkillRL: Evolving Agents via Recursive Skill-Augmented Reinforcement Learning. [Paper] [Code]
ICLR 2026 Workshop - Tool-R0: Self-Evolving LLM Agents for Tool-Learning from Zero Data. [Paper]
arXiv 2026 - AutoSkill: Experience-Driven Lifelong Learning via Skill Self-Evolution. [Paper]
arXiv 2026 - Memento-Skills: Let Agents Design Agents. [Paper]
arXiv 2026 - ELITE: Experiential Learning and Intent-Aware Transfer for Self-improving Embodied Agents. [Paper]
arXiv 2026 - SKILL0: In-Context Agentic Reinforcement Learning for Skill Internalization. [Paper] [Code]
arXiv 2026 - Skill-SD: Skill-Conditioned Self-Distillation for Multi-turn LLM Agents. [Paper] [Project]
arXiv 2026
Learning from External Resources
- Equipping Agents for the Real World with Agent Skills. [Blog]
Blog 2025 - Agent Skills. [Docs]
Docs 2025 - Skills in OpenAI API. [Docs]
Docs 2026 - SKILLFOUNDRY: Building Self-Evolving Agent Skill Libraries from Heterogeneous Scientific Resources. [Paper]
arXiv 2026
2.3.2. Skill Management
Skill Representation
- Voyager: An Open-Ended Embodied Agent with Large Language Models. [Paper] [Code]
TMLR 2024 - Inducing Programmatic Skills for Agentic Tasks. [Paper]
COLM 2025 - ToolGen: Unified Tool Retrieval and Calling via Generation. [Paper] [Code]
ICLR 2025 - Equipping Agents for the Real World with Agent Skills. [Blog]
Blog 2025 - SoK: Agentic Skills - Beyond Tool Use in LLM Agents. [Paper]
arXiv 2026 - Evolving Programmatic Skill Networks. [Paper]
arXiv 2026 - CUA-Skill: Develop Skills for Computer Using Agent. [Paper] [Code]
arXiv 2026 - Trace2Skill: Distill Trajectory-Local Lessons into Transferable Agent Skills. [Paper]
arXiv 2026 - Memento-Skills: Let Agents Design Agents. [Paper]
arXiv 2026 - SkillFlow: Scalable and Efficient Agent Skill Retrieval System. [Paper]
arXiv 2026 - Graph of Skills: Dependency-Aware Structural Retrieval for Massive Agent Skills. [Paper]
arXiv 2026 - SkillRouter: Skill Routing for LLM Agents at Scale. [Paper]
arXiv 2026 - Skills in OpenAI API. [Docs]
Docs 2026 - Agent Skills. [Docs]
Docs 2026
Skill Retrieval
- Voyager: An Open-Ended Embodied Agent with Large Language Models. [Paper] [Code]
TMLR 2024 - SRSA: Skill Retrieval and Adaptation for Robotic Assembly Tasks. [Paper]
ICLR 2025 - EvolveR: Self-Evolving LLM Agents through an Experience-Driven Lifecycle. [Paper] [Code]
arXiv 2025 - Memento-Skills: Let Agents Design Agents. [Paper]
arXiv 2026 - IntentCUA: Learning Intent-level Representations for Skill Abstraction and Multi-Agent Planning in Computer-Use Agents. [Paper]
arXiv 2026 - GraphSkill: Documentation-Guided Hierarchical Retrieval-Augmented Coding for Complex Graph Reasoning. [Paper]
arXiv 2026 - SkillRouter: Skill Routing for LLM Agents at Scale. [Paper]
arXiv 2026 - SkillFlow: Scalable and Efficient Agent Skill Retrieval System. [Paper]
arXiv 2026 - Graph of Skills: Dependency-Aware Structural Retrieval for Massive Agent Skills. [Paper]
arXiv 2026 - WebXSkill: Skill Learning for Autonomous Web Agents. [Paper]
arXiv 2026 - Skill Retrieval Augmentation for Agentic AI. [Paper]
arXiv 2026
2.3.3. Skill Maintenance
Library Curation
- Using Skills to Accelerate OSS Maintenance. [Blog]
Blog 2026 - Shell + Skills + Compaction: Tips for Long-Running Agents that Do Real Work. [Blog]
Blog 2026 - SkillRouter: Skill Routing for LLM Agents at Scale. [Paper]
arXiv 2026 - Graph of Skills: Dependency-Aware Structural Retrieval for Massive Agent Skills. [Paper]
arXiv 2026
Skill Governance
- Equipping Agents for the Real World with Agent Skills. [Blog]
Blog 2025 - Skills in OpenAI API. [Docs]
Docs 2026 - Testing Agent Skills Systematically with Evals. [Blog]
Blog 2026 - Towards Secure Agent Skills: Architecture, Threat Taxonomy, and Security Analysis. [Paper]
arXiv 2026
2.4. Multi-agent Orchestration
2.4.1. Coordination Architectures
Centralized Architectures
- ChatDev: Communicative Agents for Software Development. [Paper] [Code]
ACL 2024 - MetaGPT: Meta Programming for A Multi-Agent Collaborative Framework. [Paper] [Code]
ICLR 2024 - AutoGen: Enabling Next-Gen LLM Applications via Multi-Agent Conversations. [Paper] [Code]
COLM 2024 - AutoAgents: A Framework for Automatic Agent Generation. [Paper] [Code]
IJCAI 2024 - Scaling Large Language Model-based Multi-Agent Collaboration. [Paper] [Code]
ICLR 2025 - AutoAgent: A Fully-Automated and Zero-Code Framework for LLM Agents. [Paper] [Code]
arXiv 2025 - Agent S2: A Compositional Generalist-Specialist Framework for Computer Use Agents. [Paper] [Code]
COLM 2025 - MegaAgent: A Large-Scale Autonomous LLM-based Multi-Agent System Without Predefined SOPs. [Paper] [Code]
Findings of ACL 2025 - Multi-Agent Collaboration via Evolving Orchestration. [Paper] [Code]
NeurIPS 2025
Decentralized Architectures
- CAMEL: Communicative Agents for "Mind" Exploration of Large Language Model Society. [Paper] [Code]
NeurIPS 2023 - AgentVerse: Facilitating Multi-Agent Collaboration and Exploring Emergent Behaviors in Agents. [Paper] [Code]
arXiv 2023 - ProAgent: Building Proactive Cooperative Agents with Large Language Models. [Paper]
AAAI 2024 - A Dynamic LLM-Powered Agent Network for Task-Oriented Agent Collaboration. [Paper] [Code]
COLM 2024 - CONSENSAGENT: Towards Efficient and Effective Consensus in Multi-Agent LLM Interactions Through Sycophancy Mitigation. [Paper] [Code]
Findings of ACL 2025 - AgentOrchestra: Orchestrating Multi-Agent Intelligence with the Tool-Environment-Agent(TEA) Protocol. [Paper]
arXiv 2025 - LLM-Driven Multi-Agent Architectures for Intelligent Self-Organizing Networks. [Paper]
IEEE Network 2025 - Building a C Compiler with a Team of Parallel Claudes. [Blog]
Blog 2026
2.4.2. Communication Mechanisms
Debate-based Methods
- Encouraging Divergent Thinking in Large Language Models through Multi-Agent Debate. [Paper] [Code]
EMNLP 2024 - Should we be going MAD? A Look at Multi-Agent Debate Strategies for LLMs. [Paper]
ICML 2024 - MetaGPT: Meta Programming for A Multi-Agent Collaborative Framework. [Paper] [Code]
ICLR 2024 - RoleLLM: Benchmarking, Eliciting, and Enhancing Role-Playing Abilities of Large Language Models. [Paper] [Code]
Findings of ACL 2024 - Debate-to-Write: A Persona-Driven Multi-Agent Framework for Diverse Argument Generation. [Paper] [Code]
COLING 2025 - Table-Critic: A Multi-Agent Framework for Collaborative Criticism and Refinement in Table Reasoning. [Paper]
ACL 2025 - Reinforce LLM Reasoning through Multi-Agent Reflection. [Paper]
ICML 2025 - CONSENSAGENT: Towards Efficient and Effective Consensus in Multi-Agent LLM Interactions Through Sycophancy Mitigation. [Paper] [Code]
Findings of ACL 2025 - Player-Coach Teamwork: Multi-agent Collaboration for Improving LLM Reasoning. [Paper]
NeurIPS 2025 Workshop
Collaboration-based Methods
- ChatDev: Communicative Agents for Software Development. [Paper] [Code]
ACL 2024 - MetaGPT: Meta Programming for A Multi-Agent Collaborative Framework. [Paper] [Code]
ICLR 2024 - GPTSwarm: Language Agents as Optimizable Graphs. [Paper]
ICML 2024 - Long-Horizon Planning for Multi-Agent Robots in Partially Observable Environments. [Paper] [Code]
NeurIPS 2024 - MapCoder: Multi-Agent Code Generation for Competitive Problem Solving. [Paper] [Code]
ACL 2024 - Flow-of-Action: SOP Enhanced LLM-Based Multi-Agent System for Root Cause Analysis. [Paper]
WWW 2025 - MAPoRL: Multi-Agent Post-Co-Training for Collaborative Large Language Models with Reinforcement Learning. [Paper] [Code]
ACL 2025 - MARFT: Multi-Agent Reinforcement Fine-Tuning. [Paper] [Code]
arXiv 2025 - Multi-Agent Collaboration via Evolving Orchestration. [Paper] [Code]
NeurIPS 2025 - AgentOrchestra: Orchestrating Multi-Agent Intelligence with the Tool-Environment-Agent(TEA) Protocol. [Paper]
arXiv 2025 - Chain-of-Agents: End-to-End Agent Foundation Models via Multi-Agent Distillation and Agentic RL. [Paper] [Code]
arXiv 2025 - Multi-Agent Evolve: LLM Self-Improve through Co-evolution. [Paper] [Code]
arXiv 2025 - InstructFlow: Adaptive Symbolic Constraint-Guided Code Generation for Long-Horizon Planning. [Paper] [Code]
NeurIPS 2025 - How and When to Build Multi-Agent Systems. [Blog]
Blog 2025 - Don't Build Multi-Agents. [Blog]
Blog 2025 - Toward Autonomous Long-Horizon Engineering for ML Research. [Paper]
arXiv 2026
3. Model Adaptation for Harness
3.1. Context Engineering
3.1.1. Context Design
Prompt Engineering
- Chain-of-Thought Prompting Elicits Reasoning in Large Language Models. [Paper] [Code]
NeurIPS 2022 - Large Language Models are Zero-Shot Reasoners. [Paper]
NeurIPS 2022 - Tree of Thoughts: Deliberate Problem Solving with Large Language Models. [Paper] [Code]
NeurIPS 2023 - Graph of Thoughts: Solving Elaborate Problems with Large Language Models. [Paper] [Code]
AAAI 2024 - Role play with large language models. [Paper]
Nature 2023 - CAMEL: Communicative Agents for "Mind" Exploration of Large Language Model Society. [Paper] [Code]
NeurIPS 2023 - Generative Agents: Interactive Simulacra of Human Behavior. [Paper] [Code]
UIST 2023 - CoSER: A Comprehensive Literary Dataset and Framework for Training and Evaluating LLM Role-Playing and Persona Simulation. [Paper] [Code]
ICML 2025 - Large Language Models Are Human-Level Prompt Engineers. [Paper]
ICLR 2023 - Making Pre-trained Language Models Better Few-shot Learners. [Paper]
ACL 2021 - Self-Refine: Iterative Refinement with Self-Feedback. [Paper] [Code]
NeurIPS 2023 - Promptbreeder: Self-Referential Self-Improvement Via Prompt Evolution. [Paper]
ICML 2024
Context Retrieval
- Interleaving Retrieval with Chain-of-Thought Reasoning for Knowledge-Intensive Multi-Step Questions. [Paper]
ACL 2023 - ReAct: Synergizing Reasoning and Acting in Language Models. [Paper] [Code]
ICLR 2023 - REPLUG: Retrieval-Augmented Black-Box Language Models. [Paper] [Code]
NAACL 2024 - Self-RAG: Learning to Retrieve, Generate, and Critique through Self-Reflection. [Paper] [Code]
ICLR 2024 - CRAG: Corrective Retrieval Augmented Generation. [Paper] [Code]
arXiv 2024 - RAPTOR: Recursive Abstractive Processing for Tree-Organized Retrieval. [Paper] [Code]
ICLR 2024 - Adaptive-RAG: Learning to Adapt Retrieval-Augmented Large Language Models through Question Complexity. [Paper] [Code]
NAACL 2024 - HippoRAG: Neurobiologically Inspired Long-Term Memory for Large Language Models. [Paper]
NeurIPS 2024 - Think-on-Graph: Deep and Responsible Reasoning of Large Language Model on Knowledge Graph. [Paper]
ICLR 2024 - DSPy: Compiling Declarative Language Model Calls into Self-Improving Pipelines. [Paper]
ICLR 2024 - StructRAG: Boosting Knowledge Intensive Reasoning of LLMs via Inference-time Hybrid Information Structurization. [Paper]
ICLR 2025 - Search-o1: Agentic Search-Enhanced Large Reasoning Models. [Paper] [Code]
EMNLP 2025 - Deeprag: Thinking to retrieve step by step for large language models. [Paper] [Code]
arXiv 2025 - Model Context Protocol (MCP): Landscape, Security Threats, and Future Research Directions. [Paper] [Code]
arXiv 2025 - MA-RAG: Multi-Agent Retrieval-Augmented Generation via Collaborative Chain-of-Thought Reasoning. [Paper]
arXiv 2025 - A-RAG: Scaling Agentic Retrieval-Augmented Generation via Hierarchical Retrieval Interfaces. [Paper]
arXiv 2026
3.1.2. Context Management
Context Processing
- Lost in the Middle: How Language Models Use Long Contexts. [Paper] [Code]
TACL 2024 - LLMLingua: Compressing Prompts for Accelerated Inference of Large Language Models. [Paper]
EMNLP 2023 - Compressing Context to Enhance Inference Efficiency of Large Language Models. [Paper] [Code]
EMNLP 2023 - LLM Maybe LongLM: Self-Extend LLM Context Window Without Tuning. [Paper] [Code]
ICML 2024 - ACON: Optimizing Context Compression for Long-horizon LLM Agents. [Paper] [Code]
arXiv 2025 - Reducing Cost of LLM Agents with Trajectory Reduction. [Paper]
arXiv 2025 - AgentFold: Long-Horizon Web Agents with Proactive Context Management. [Paper]
arXiv 2025 - SWE-Pruner: Self-Adaptive Context Pruning for Coding Agents. [Paper]
arXiv 2026 - CEDAR: Context Engineering for Agentic Data Science. [Paper] [Code]
arXiv 2026 - IterResearch: Rethinking Long-Horizon Agents with Interaction Scaling. [Paper]
ICLR 2026
Context Updating
- Reflexion: language agents with verbal reinforcement learning. [Paper] [Code]
NeurIPS 2023 - MemGPT: Towards LLMs as Operating Systems. [Paper] [Code]
arXiv 2023 - Efficient Streaming Language Models with Attention Sinks. [Paper] [Code]
ICLR 2024 - MemoryBank: Enhancing Large Language Models with Long-Term Memory. [Paper] [Code]
AAAI 2024 - Agent Workflow Memory. [Paper] [Code]
ICML 2025 - Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory. [Paper] [Code]
ECAI 2025 - A-Mem: Agentic Memory for LLM Agents. [Paper] [Code]
NeurIPS 2025 - HiAgent: Hierarchical Working Memory Management for Solving Long-Horizon Agent Tasks with Large Language Model. [Paper]
ACL 2025 - Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models. [Paper] [Code]
ICLR 2026 - Dynamic Affective Memory Management for Personalized LLM Agents. [Paper]
arXiv 2025 - Meta Context Engineering via Agentic Skill Evolution. [Paper] [Code]
ICML 2026 - AgentSys: Secure and Dynamic LLM Agents Through Explicit Hierarchical Memory Management. [Paper]
arXiv 2026
3.2. Agentic Training
3.2.1. Environment Construction
Rule-Based Environments
- ALFWorld: Aligning Text and Embodied Environments for Interactive Learning. [Paper] [Code]
ICLR 2021 - ScienceWorld: Is your Agent Smarter than a 5th Grader? [Paper] [Code]
EMNLP 2022 - WebShop: Towards Scalable Real-World Web Interaction with Grounded Language Agents. [Paper] [Code]
NeurIPS 2022 - InterCode: Standardizing and Benchmarking Interactive Coding with Execution Feedback. [Paper] [Code]
NeurIPS 2023 - AlphaMath Almost Zero: Process Supervision without Process. [Paper]
NeurIPS 2024 - Step-level Value Preference Optimization for Mathematical Reasoning. [Paper]
Findings of EMNLP 2024 - AppWorld: A Controllable World of Apps and People for Benchmarking Interactive Coding Agents. [Paper] [Code]
ACL 2024 - ScienceAgentBench: Toward Rigorous Assessment of Language Agents for Data-Driven Scientific Discovery. [Paper] [Code]
ICLR 2025 - MLGym: A New Framework and Benchmark for Advancing AI Research Agents. [Paper]
arXiv 2025 - Reinforcement Learning for Reasoning in Large Language Models with One Training Example. [Paper]
arXiv 2025 - FormalMATH: Benchmarking Formal Mathematical Reasoning of Large Language Models. [Paper]
arXiv 2025 - REASONING GYM: Reasoning Environments for Reinforcement Learning with Verifiable Rewards. [Paper]
arXiv 2025 - R-Zero: Self-Evolving Reasoning LLM from Zero Data. [Paper]
arXiv 2025 - Immersion in the GitHub Universe: Scaling Coding Agents to Mastery. [Paper]
arXiv 2026 - EnterpriseOps-Gym: Environments and Evaluations for Stateful Agentic Planning and Tool Use in Enterprise Settings. [Paper]
arXiv 2026
Simulation-Based Environments
- Reasoning with Language Model is Planning with World Model. [Paper]
EMNLP 2023 - NeuralOS: Towards Simulating Operating Systems via Neural Generative Models. [Paper]
arXiv 2025 - BuilderBench: The Building Blocks of Intelligent Agents. [Paper]
arXiv 2025 - MEAL: A Benchmark for Continual Multi-Agent Reinforcement Learning. [Paper]
arXiv 2025 - Agent World Model: Infinity Synthetic Environments for Agentic Reinforcement Learning. [Paper]
arXiv 2026 - WebWorld: A Large-Scale World Model for Web Agent Training. [Paper]
arXiv 2026
Real-World Environments
- PaLM-E: An Embodied Multimodal Language Model. [Paper]
ICML 2023 - RT-2: Vision-Language-Action Models Transfer Web Knowledge to Robotic Control. [Paper]
CoRL 2023 - WebArena: A Realistic Web Environment for Building Autonomous Agents. [Paper] [Code]
ICLR 2024 - AgentBench: Evaluating LLMs as Agents. [Paper] [Code]
ICLR 2024 - DigiRL: Training In-The-Wild Device-Control Agents with Autonomous Reinforcement Learning. [Paper] [Code]
NeurIPS 2024 - The BrowserGym Ecosystem for Web Agent Research. [Paper]
TMLR 2025 - Digi-Q: Learning Q-Value Functions for Training Device-Control Agents. [Paper]
ICLR 2025 - WebRL: Training LLM Web Agents via Self-Evolving Online Curriculum Reinforcement Learning. [Paper] [Code]
ICLR 2025 - DeepResearcher: Scaling Deep Research via Reinforcement Learning in Real-world Environments. [Paper] [Code]
EMNLP 2025 - PhysiAgent: An Embodied Agent Framework in Physical World. [Paper]
arXiv 2025 - BrowseComp-V^3: A Visual, Vertical, and Verifiable Benchmark for Multimodal Browsing Agents. [Paper]
arXiv 2026 - EnterpriseBench Corecraft: Training Generalizable Agents on High-Fidelity RL Environments. [Paper]
arXiv 2026 - MolmoWeb: Open Visual Web Agent and Open Data for the Open Web. [Paper]
arXiv 2026
3.2.2. Reward Design
Outcome-Level Rewards
- DeepSeek-Prover-V1.5: Harnessing Proof Assistant Feedback for Reinforcement Learning and Monte-Carlo Tree Search. [Paper]
ICLR 2025 - ACECODER: Acing Coder RL via Automated Test-Case Synthesis. [Paper]
ACL 2025 - Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning. [Paper] [Code]
COLM 2025 - TTRL: Test-Time Reinforcement Learning. [Paper]
arXiv 2025 - Agentic Reasoning and Tool Integration for LLMs via Reinforcement Learning. [Paper]
arXiv 2025 - Agent RL Scaling Law: Agent RL with Spontaneous Code Execution for Mathematical Problem Solving. [Paper]
arXiv 2025 - Qwen3 Technical Report. [Paper]
arXiv 2025 - Outcome-based Reinforcement Learning to Predict the Future. [Paper]
TMLR 2025 - DeepResearcher: Scaling Deep Research via Reinforcement Learning in Real-world Environments. [Paper] [Code]
EMNLP 2025 - DeepCoder: A Fully Open-Source 14B Coder at O3-mini Level. [Blog]
Blog 2025 - DeepSWE: Training a Fully Open-sourced, State-of-the-Art Coding Agent by Scaling RL. [Blog]
Blog 2025
Process-Level Rewards
- Let's Verify Step by Step. [Paper] [Code]
ICLR 2024 - Math-Shepherd: Verify and Reinforce LLMs Step-by-step without Human Annotations. [Paper]
ACL 2024 - Improve Mathematical Reasoning in Language Models by Automated Process Supervision. [Paper]
arXiv 2024 - ToolRL: Reward is All Tool Learning Needs. [Paper] [Code]
NeurIPS 2025 - GUI-G^2: Gaussian Reward Modeling for GUI Grounding. [Paper]
AAAI 2026 - Process Reward Models That Think. [Paper] [Code]
TMLR 2026
3.2.3. Training Optimization Algorithms
Supervised Fine-Tuning
- Toolformer: Language Models Can Teach Themselves to Use Tools. [Paper]
NeurIPS 2023 - Gorilla: Large Language Model Connected with Massive APIs. [Paper] [Code]
NeurIPS 2024 - ToolLLM: Facilitating Large Language Models to Master 16000+ Real-world APIs. [Paper] [Code]
ICLR 2024 - FireAct: Toward Language Agent Fine-tuning. [Paper] [Code]
arXiv 2023 - AgentTuning: Enabling Generalized Agent Abilities for LLMs. [Paper] [Code]
Findings of ACL 2024 - AgentOhana: Design Unified Data and Training Pipeline for Effective Agent Learning. [Paper] [Code]
arXiv 2024 - CodeAct: Executable Code Actions Elicit Better LLM Agents. [Paper] [Code]
ICML 2024 - Agent-FLAN: Designing Data and Methods of Effective Agent Tuning for Large Language Models. [Paper] [Code]
Findings of ACL 2024 - MAGDi: Structured Distillation of Multi-Agent Interaction Graphs Improves Reasoning in Smaller Language Models. [Paper]
ICML 2024 - On-Policy Distillation of Language Models: Learning from Self-Generated Mistakes. [Paper]
ICLR 2024 - MiniLLM: On-Policy Distillation of Large Language Models. [Paper]
ICLR 2024 - AgentTrek: Agent Trajectory Synthesis via Guiding Replay with Web Tutorials. [Paper] [Code]
ICLR 2025 - Efficient Agent Training for Computer Use. [Paper]
arXiv 2025 - Structured Agent Distillation for Large Language Model. [Paper]
arXiv 2025 - Merge-of-Thought Distillation. [Paper]
arXiv 2025 - Black-Box On-Policy Distillation of Large Language Models. [Paper]
arXiv 2025 - Expanding the Capability Frontier of LLM Agents with ZPD-Guided Data Synthesis. [Paper]
ICLR 2026 - Stable On-Policy Distillation through Adaptive Target Reformulation. [Paper]
arXiv 2026 - Learning beyond Teacher: Generalized On-Policy Distillation with Reward Extrapolation. [Paper]
arXiv 2026 - On Data Engineering for Scaling LLM Terminal Capabilities. [Paper]
arXiv 2026 - Scaling Reasoning Efficiently via Relaxed On-Policy Distillation. [Paper]
arXiv 2026 - Immersion in the GitHub Universe: Scaling Coding Agents to Mastery. [Paper]
arXiv 2026 - ClawGym: A Scalable Framework for Building Effective Claw Agents. [Paper]
arXiv 2026
Reinforcement Learning Approaches
- Proximal Policy Optimization Algorithms. [Paper]
arXiv 2017 - Direct Preference Optimization: Your Language Model is Secretly a Reward Model. [Paper] [Code]
NeurIPS 2023 - Secrets of RLHF in Large Language Models Part I: PPO. [Paper] [Code]
arXiv 2023 - LATS: Language Agent Tree Search Unifies Reasoning, Acting, and Planning. [Paper] [Code]
ICML 2024 - Secrets of RLHF in Large Language Models Part II: Reward Modeling. [Paper] [Code]
arXiv 2024 - KTO: Model Alignment as Prospect Theoretic Optimization. [Paper] [Code]
arXiv 2024 - ArCHer: Training Language Model Agents via Hierarchical Multi-Turn RL. [Paper] [Code]
ICML 2024 - DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models. [Paper] [Code]
arXiv 2024 - ORPO: Monolithic Preference Optimization without Reference Model. [Paper] [Code]
EMNLP 2024 - SimPO: Simple Preference Optimization with a Reference-Free Reward. [Paper] [Code]
NeurIPS 2024 - WARP: On the Benefits of Weight Averaged Rewarded Policies. [Paper]
arXiv 2024 - ReMax: A Simple, Effective, and Efficient Reinforcement Learning Method for Aligning Large Language Models. [Paper]
ICML 2024 - VinePPO: Refining Credit Assignment in RL Training of LLMs. [Paper]
ICML 2025 - Kimi k1.5: Scaling Reinforcement Learning with LLMs. [Paper]
arXiv 2025 - DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning. [Paper]
Nature 2025 - DAPO: An Open-Source LLM Reinforcement Learning System at Scale. [Paper] [Code]
arXiv 2025 - RAGEN: Understanding Self-Evolution in LLM Agents via Multi-Turn Reinforcement Learning. [Paper] [Code]
arXiv 2025 - WebThinker: Empowering Large Reasoning Models with Deep Research Capability. [Paper] [Code]
NeurIPS 2025 - Group-in-Group Policy Optimization for LLM Agent Training. [Paper] [Code]
arXiv 2025 - Agentic Reinforced Policy Optimization. [Paper] [Code]
arXiv 2025 - LLM Collaboration with Multi-Agent Reinforcement Learning. [Paper]
AAAI 2026 - Tree Search for LLM Agent Reinforcement Learning. [Paper]
arXiv 2025 - ML-Agent: Reinforcing LLM Agents for Autonomous Machine Learning Engineering. [Paper]
arXiv 2025 - ACT: Agentic Critical Training. [Paper]
arXiv 2026
3.2.4. Infrastructure
General-Purpose Frameworks
- OpenRLHF: An Easy-to-use, Scalable and High-performance RLHF Framework. [Paper] [Code]
arXiv 2024 - NeMo-Aligner: Scalable Toolkit for Efficient Model Alignment. [Paper] [Code]
arXiv 2024 - ReaL: Efficient RLHF Training of Large Language Models with Parameter Reallocation. [Paper] [Code]
arXiv 2024 - AgentGym: Evolving Large Language Model-based Agents across Diverse Environments. [Paper] [Code]
arXiv 2024 - HybridFlow: A Flexible and Efficient RLHF Framework. [Paper] [Code]
EuroSys 2025 - Open-Reasoner-Zero: An Open Source Approach to Scaling Up Reinforcement Learning on the Base Model. [Paper]
arXiv 2025 - RAGEN: Understanding Self-Evolution in LLM Agents via Multi-Turn Reinforcement Learning. [Paper] [Code]
arXiv 2025 - Group-in-Group Policy Optimization for LLM Agent Training. [Paper] [Code]
arXiv 2025 - AReaL: A Large-Scale Asynchronous Reinforcement Learning System for Language Reasoning. [Paper] [Code]
arXiv 2025 - Agent Lightning: Train ANY AI Agents with Reinforcement Learning. [Paper] [Code]
arXiv 2025 - AgentGym-RL: Training LLM Agents for Long-Horizon Decision Making through Multi-Turn Reinforcement Learning. [Paper]
arXiv 2025 - GEM: A Gym for Agentic LLMs. [Paper] [Code]
arXiv 2025 - AgentRL: Scaling Agentic Reinforcement Learning with a Multi-Turn, Multi-Task Framework. [Paper]
arXiv 2025 - SkyRL-Agent: Efficient RL Training for Multi-turn LLM Agent. [Paper] [Code]
arXiv 2025 - Agent-R1: Training Powerful LLM Agents with End-to-End Reinforcement Learning. [Paper] [Code]
arXiv 2025 - RollArt: Scaling Agentic RL Training via Disaggregated Infrastructure. [Paper]
arXiv 2025
Specialized Frameworks
- Multimodal Reinforcement Learning with Agentic Verifier for AI Agents. [Paper]
arXiv 2025 - Dr. MAS: Stable Reinforcement Learning for Multi-Agent LLM Systems. [Paper]
arXiv 2026 - MARTI: A Framework for Multi-Agent LLM Systems Reinforced Training and Inference. [Paper]
ICLR 2026 - LLM Collaboration with Multi-Agent Reinforcement Learning. [Paper]
AAAI 2026 - WideSeek-R1: Exploring Width Scaling for Broad Information Seeking via Multi-Agent Reinforcement Learning. [Paper]
arXiv 2026 - MM-DeepResearch: A Simple and Effective Multimodal Agentic Search Baseline. [Paper]
arXiv 2026 - GrandCode: Achieving Grandmaster Level in Competitive Programming via Agentic Reinforcement Learning. [Paper]
arXiv 2026 - LiteResearcher: A Scalable Agentic RL Training Framework for Deep Research Agent. [Paper] [Code]
arXiv 2026
4. Representative Benchmarks by Task Domain
4.1. Deep Research
- BrowseComp: A Simple Yet Challenging Benchmark for Browsing Agents. [Paper] [Code]
arXiv 2025 - IDRBench: Interactive Deep Research Benchmark. [Paper]
arXiv 2026 - ReportBench: Evaluating Deep Research Agents via Academic Survey Tasks. [Paper] [Code]
arXiv 2025 - Characterizing Deep Research: A Benchmark and Formal Definition. [Paper] [Code]
ICLR 2026 - WideSearch: Benchmarking Agentic Broad Info-Seeking. [Paper] [Code]
ICLR 2026 - LiveResearchBench: A Live Benchmark for User-Centric Deep Research in the Wild. [Paper] [Code]
ICLR 2026 - ResearchRubrics: A Benchmark of Prompts and Rubrics For Evaluating Deep Research Agents. [Paper] [Code]
ICLR 2026 - DeepSynth-Eval: Objectively Evaluating Information Consolidation in Deep Survey Writing. [Paper]
arXiv 2026 - DeepResearch Bench II: Diagnosing Deep Research Agents via Rubrics from Expert Report. [Paper] [Code]
arXiv 2026 - MMDeepResearch-Bench: A Benchmark for Multimodal Deep Research Agents. [Paper] [Code]
arXiv 2026 - DeepSurvey-Bench: Evaluating Academic Value of Automatically Generated Scientific Survey. [Paper]
arXiv 2026
4.2. Software Engineering
- RepoBench: Benchmarking Repository-Level Code Auto-Completion Systems. [Paper] [Code]
ICLR 2024 - SWE-bench: Can Language Models Resolve Real-world Github Issues? [Paper] [Code]
ICLR 2024 - LiveCodeBench: Holistic and Contamination Free Evaluation of Large Language Models for Code. [Paper] [Code]
ICLR 2025 - Can Language Models Replace Programmers for Coding? REPOCOD Says 'Not Yet'. [Paper] [Code]
ACL 2025 - SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks? [Paper] [Code]
arXiv 2025 - SWE-Sharp-Bench: A Reproducible Benchmark for C# Software Engineering Tasks. [Paper] [Code]
AIware 2025 - LoCoBench-Agent: An Interactive Benchmark for LLM Agents in Long-Context Software Engineering. [Paper] [Code]
arXiv 2025 - NL2Repo-Bench: Towards Long-Horizon Repository Generation Evaluation of Coding Agents. [Paper] [Code]
ICML 2026 - OmniCode: A Benchmark for Evaluating Software Engineering Agents. [Paper] [Code]
arXiv 2026 - SWE-Universe: Scale Real-World Verifiable Environments to Millions. [Paper]
arXiv 2026 - FeatureBench: Benchmarking Agentic Coding for Complex Feature Development. [Paper] [Code]
ICLR 2026
4.3. Tool Use and Function Calling
- API-Bank: A Comprehensive Benchmark for Tool-Augmented LLMs. [Paper] [Code]
EMNLP 2023 - AgentBench: Evaluating LLMs as Agents. [Paper] [Code]
ICLR 2024 - GAIA: a benchmark for General AI Assistants. [Paper] [Code]
ICLR 2024 - tau-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains. [Paper] [Code]
ICLR 2025 - AppWorld: A Controllable World of Apps and People for Benchmarking Interactive Coding Agents. [Paper] [Code]
ACL 2024 - AssistantBench: Can Web Agents Solve Realistic and Time-Consuming Tasks? [Paper] [Code]
EMNLP 2024 - Toolsandbox: A stateful, conversational, interactive evaluation benchmark for llm tool use capabilities. [Paper] [Code]
Findings of NAACL 2025 - ToolHop: A Query-Driven Benchmark for Evaluating Large Language Models in Multi-Hop Tool Use. [Paper] [Code]
ACL 2025 - DICE-BENCH: Evaluating the Tool-Use Capabilities of Large Language Models in Multi-Round, Multi-Party Dialogues. [Paper] [Code]
Findings of ACL 2025 - tau^2-Bench: Evaluating Conversational Agents in a Dual-Control Environment. [Paper] [Code]
arXiv 2025 - The Berkeley Function Calling Leaderboard (BFCL): From Tool Use to Agentic Evaluation of Large Language Models. [Paper] [Code]
ICML 2025 - CCTU: A Benchmark for Tool Use under Complex Constraints. [Paper] [Code]
arXiv 2026
4.4. Computer Use and GUI Grounding
- Mind2Web: Towards a Generalist Agent for the Web. [Paper] [Code]
NeurIPS 2023 - WebArena: A Realistic Web Environment for Building Autonomous Agents. [Paper] [Code]
ICLR 2024 - Android in the Wild: A Large-Scale Dataset for Android Device Control. [Paper] [Code]
NeurIPS 2023 - VisualWebArena: Evaluating Multimodal Agents on Realistic Visual Web Tasks. [Paper] [Code]
ACL 2024 - WorkArena: How Capable are Web Agents at Solving Common Knowledge Work Tasks? [Paper] [Code]
ICML 2024 - AndroidWorld: A Dynamic Benchmarking Environment for Autonomous Agents. [Paper] [Code]
ICLR 2025 - Windows Agent Arena: Evaluating Multi-Modal OS Agents at Scale. [Paper] [Code]
ICML 2025 - WorldGUI: An Interactive Benchmark for Desktop GUI Automation from Any Starting Point. [Paper] [Code]
arXiv 2025 - ScreenSpot-Pro: GUI Grounding for Professional High-Resolution Computer Use. [Paper] [Code]
ICLR 2025 Workshop - MMBench-GUI: Hierarchical Multi-Platform Evaluation Framework for GUI Agents. [Paper] [Code]
arXiv 2025 - Osworld-mcp: Benchmarking mcp tool invocation in computer-use agents. [Paper] [Code]
ICLR 2026 - VenusBench-GD: A Comprehensive Multi-Platform GUI Benchmark for Diverse Grounding Tasks. [Paper] [Code]
arXiv 2025
4.5. ML Engineering and Scientific Research
- DS-1000: A Natural and Reliable Benchmark for Data Science Code Generation. [Paper] [Code]
ICML 2023 - MLAgentBench: Evaluating Language Agents on Machine Learning Experimentation. [Paper] [Code]
ICML 2024 - DA-Code: Agent Data Science Code Generation Benchmark for Large Language Models. [Paper] [Code]
EMNLP 2024 - ScienceAgentBench: Toward Rigorous Assessment of Language Agents for Data-Driven Scientific Discovery. [Paper] [Code]
ICLR 2025 - MLE-bench: Evaluating Machine Learning Agents on Machine Learning Engineering. [Paper] [Code]
ICLR 2025 - PaperBench: Evaluating AI's Ability to Replicate AI Research. [Paper] [Code]
ICML 2025 - TimeSeriesGym: A Scalable Benchmark for (Time Series) Machine Learning Engineering Agents. [Paper] [Code]
NeurIPS 2025 Workshop - MLR-Bench: Evaluating AI Agents on Open-Ended Machine Learning Research. [Paper] [Code]
NeurIPS 2025 - FML-bench: Benchmarking Machine Learning Agents for Scientific Research. [Paper] [Code]
arXiv 2025 - ReplicatorBench: Benchmarking LLM Agents for Replicability in Social and Behavioral Sciences. [Paper] [Code]
MSLD 2026
5. Future Directions
5.1. Efficiency
- RouteLLM: Learning to Route LLMs from Preference Data. [Paper]
ICLR 2025 - Chain of Thoughtlessness? An Analysis of CoT in Planning. [Paper] [Code]
NeurIPS 2024 - ACON: Optimizing Context Compression for Long-horizon LLM Agents. [Paper] [Code]
arXiv 2025 - Reducing Cost of LLM Agents with Trajectory Reduction. [Paper]
arXiv 2025 - ARC: Active and Reflection-driven Context Management for Long-Horizon Information Seeking Agents. [Paper]
arXiv 2026 - Context as a Tool: Context Management for Long-Horizon SWE-Agents. [Paper]
arXiv 2025 - Robust and Efficient Tool Orchestration via Layered Execution Structures with Reflective Correction. [Paper]
arXiv 2026
5.2. Safety
- AgentDojo: A Dynamic Environment to Evaluate Prompt Injection Attacks and Defenses for LLM Agents. [Paper]
NeurIPS 2024 - MCPTox: A Benchmark for Tool Poisoning Attack on Real-World MCP Servers. [Paper]
arXiv 2025 - AgentSys: Secure and Dynamic LLM Agents Through Explicit Hierarchical Memory Management. [Paper]
arXiv 2026 - OpenPort Protocol: A Security Governance Specification for AI Agent Tool Access. [Paper]
arXiv 2026 - Runtime Governance for AI Agents: Policies on Paths. [Paper]
arXiv 2026 - AgentSpec: Customizable runtime enforcement for safe and reliable LLM agents.(2026). [Paper]
ICSE 2026 - Autonomous Action Runtime Management(AARM):A System Specification for Securing AI-Driven Actions at Runtime. [Paper]
arXiv 2026 - SafeHarness: Lifecycle-Integrated Security Architecture for LLM-based Agent Deployment. [Paper]
arXiv 2026
5.3. Continual Learning
- MemGPT: Towards LLMs as Operating Systems. [Paper] [Code]
arXiv 2023 - A-Mem: Agentic Memory for LLM Agents. [Paper] [Code]
NeurIPS 2025 - Memory as Action: Autonomous Context Curation for Long-Horizon Agentic Tasks. [Paper]
arXiv 2025 - Context Engineering: Memory, Compaction, and Tool Clearing. [Docs]
Docs 2026 - Agent Workflow Memory. [Paper] [Code]
ICML 2025
5.4. State and Environment Modeling
- WorldCoder, a Model-Based LLM Agent: Building World Models by Writing Code and Interacting with the Environment. [Paper]
NeurIPS 2024 - PABU: Progress-Aware Belief Update for Efficient LLM Agents. [Paper]
arXiv 2026 - Agent-World: Scaling Real-World Environment Synthesis for Evolving General Agent Intelligence. [Paper]
arXiv 2026
5.5. Embodied Harnesses
- PaLM-E: An Embodied Multimodal Language Model. [Paper]
ICML 2023 - RT-2: Vision-Language-Action Models Transfer Web Knowledge to Robotic Control. [Paper]
CoRL 2023 - Green-VLA: Staged Vision-Language-Action Model for Generalist Robots. [Paper]
arXiv 2026 - ACoT-VLA: Action Chain-of-Thought for Vision-Language-Action Models. [Paper]
arXiv 2026 - ST4VLA: Spatially Guided Training for Vision-Language-Action Models. [Paper]
arXiv 2026 - RoboAgent: Chaining Basic Capabilities for Embodied Task Planning. [Paper]
CVPR 2026 - EmbodiedBench: Comprehensive Benchmarking Multi-modal Large Language Models for Vision-Driven Embodied Agents. [Paper]
ICML 2025 - AgentSpec: Customizable Runtime Enforcement for Safe and Reliable LLM Agents. [Paper]
ICSE 2026
5.6. Evaluation
- BrowseComp-V^3: A Visual, Vertical, and Verifiable Benchmark for Multimodal Browsing Agents. [Paper]
arXiv 2026 - OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments. [Paper] [Code]
NeurIPS 2024 - PaperBench: Evaluating AI's Ability to Replicate AI Research. [Paper] [Code]
ICML 2025 - ReplicatorBench: Benchmarking LLM Agents for Replicability in Social and Behavioral Sciences. [Paper] [Code]
MSLD 2026 - BeyondSWE: Can Current Code Agent Survive Beyond Single-Repo Bug Fixing? [Paper]
arXiv 2026 - Gaia-2: A controllable multi-view generative world model for autonomous driving. [Paper]
arXiv 2025 - Claw-Eval-Live: A Live Agent Benchmark for Evolving Real-World Workflows. [Paper]
arXiv 2026 - ResearchRubrics: A Benchmark of Prompts and Rubrics For Evaluating Deep Research Agents. [Paper] [Code]
ICLR 2026 - Osworld-mcp: Benchmarking mcp tool invocation in computer-use agents. [Paper] [Code]
ICLR 2026 - AgentLongBench: A Controllable Long Benchmark For Long-Contexts Agents via Environment Rollouts. [Paper]
arXiv 2026 - ATBench: A Diverse and Realistic Agent Trajectory Benchmark for Safety Evaluation and Diagnosis. [Paper]
arXiv 2026 - AgentLeak: A Full-Stack Benchmark for Privacy Leakage in Multi-Agent LLM Systems. [Paper]
arXiv 2026 - Benchmark Test-Time Scaling of General LLM Agents. [Paper]
arXiv 2026
Citation
If you find our paper useful for your research, please consider citing the paper and starring this repository.
@misc{tang2026agent,
  title={Agent Systems with Harness Engineering},
  author={Xinyu Tang and Han Peng and Guoxin Chen and Yuze Shi and
          Zitao Su and Peiyu Liu and Wayne Xin Zhao and Yawen Li and
          Zhe Xue},
  url={https://openreview.net/pdf?id=nM5tDHrQsx},
  year={2026}
}
Contributors


Similar repos


The official GitHub page for the paper "Agent Systems with Harness Engineering"
See the codeREADME
Agent Systems with Harness Engineering
A Curated Reading List and Structured Roadmap
A curated list of papers and resources on agent systems with harness engineering, based on our paper:
"Agent Systems with Harness Engineering".
Timeline of agent systems with harness engineering.
Tip: If you have any questions for our paper, please send an email to txy20010310@163.com.
Table of Contents
- 1. Evolution of Harness Engineering
- 2. The Design of the Harness
- 3. Model Adaptation for Harness
- 4. Representative Benchmarks by Task Domain
- 5. Future Directions
- Citation
1. Evolution of Harness Engineering
Three layers in the evolution of harness architecture.
1.1. Action Interface: Connecting Model to Environment
- Quine: Realizing LLM Agents as Native POSIX Processes. [Paper]
arXiv 2026 - ceLLMate: Sandboxing Browser AI Agents. [Paper]
arXiv 2025 - Executable Code Actions Elicit Better LLM Agents. [Paper]
ICML 2024 - DeepAgent: A General Reasoning Agent with Scalable Toolsets. [Paper]
arXiv 2025 - ReAct: Synergizing Reasoning and Acting in Language Models. [Paper] [Code]
ICLR 2023 - Toolformer: Language Models Can Teach Themselves to Use Tools. [Paper]
NeurIPS 2023 - Tool learning with large language models: a survey. [Paper]
FCS 2025 - AIOS: LLM Agent Operating System. [Paper]
COLM 2025
1.2. Workflow Infrastructure: Orchestrating Persistent Workspaces
- SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering. [Paper] [Code]
NeurIPS 2024 - Engineering Pitfalls in AI Coding Tools: An Empirical Study of Bugs in Claude Code, Codex, and Gemini CLI. [Paper]
arXiv 2026 - Building Effective AI Coding Agents for the Terminal: Scaffolding, Harness, Context Engineering, and Lessons Learned. [Paper]
arXiv 2026 - SWE-Master: Unleashing the Potential of Software Engineering Agents via Post-Training. [Paper]
arXiv 2026 - VeRO: An Evaluation Harness for Agents to Optimize Agents. [Paper]
ICML 2026 - OpenHands: An Open Platform for AI Software Developers as Generalist Agents. [Paper]
ICLR 2025 - Claude Code Overview. [Docs]
Docs 2026
1.3. User-Centric Persistence: Continuity Across Sessions and Channels
- Toward Personalized LLM-Powered Agents: Foundations, Evaluation, and Future Directions. [Paper]
arXiv 2026 - Enabling Personalized Long-term Interactions in LLM-based Agents through Persistent Memory and User Profiles. [Paper]
arXiv 2025 - User Preference Modeling for Conversational LLM Agents: Weak Rewards from Retrieval-Augmented Interaction. [Paper]
arXiv 2026 - From Human Memory to AI Memory: A Survey on Memory Mechanisms in the Era of LLMs. [Paper]
arXiv 2025 - Persistent Assistant: Seamless Everyday AI Interactions via Intent Grounding and Multimodal Feedback. [Paper]
CHI 2025 - Introducing OpenClaw. [Blog]
Blog 2026
2. The Design of the Harness
2.1. Agent Workflow
- HuggingGPT: Solving AI Tasks with ChatGPT and its Friends in Hugging Face. [Paper] [Code]
NeurIPS 2023 - OpenManus: An Open-source Framework for Building General AI Agents. [Code]
Repo 2025 - Unrolling the Codex agent loop. [Blog]
Blog 2026 - OpenClaw. [Code] [Website]
Repo 2026 - Hermes Agent. [Website]
Website 2026
2.1.1. Environment Perception
Observation Extraction
- Mind2Web: Towards a Generalist Agent for the Web. [Paper] [Code]
NeurIPS 2023 - WebArena: A Realistic Web Environment for Building Autonomous Agents. [Paper] [Code]
ICLR 2024 - WebVoyager: Building an End-to-End Web Agent with Large Multimodal Models. [Paper] [Code]
ACL 2024 - VisualWebArena: Evaluating Multimodal Agents on Realistic Visual Web Tasks. [Paper] [Code]
ACL 2024 - GPT-4V(ision) is a Generalist Web Agent, if Grounded. [Paper]
ICML 2024 - SeeClick: Harnessing GUI Grounding for Advanced Visual GUI Agents. [Paper]
ACL 2024 - OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments. [Paper] [Code]
NeurIPS 2024 - DigiRL: Training In-The-Wild Device-Control Agents with Autonomous Reinforcement Learning. [Paper] [Code]
NeurIPS 2024 - AgentOccam: A Simple Yet Strong Baseline for LLM-Based Web Agents. [Paper]
ICLR 2025 - Agent S: An Open Agentic Framework that Uses Computers Like a Human. [Paper] [Code]
ICLR 2025 Workshop - AndroidWorld: A Dynamic Benchmarking Environment for Autonomous Agents. [Paper] [Code]
ICLR 2025 - GUI-Actor: Coordinate-Free Visual Grounding for GUI Agents. [Paper] [Code]
NeurIPS 2025 - VAGEN: Reinforcing World Model Reasoning for Multi-Turn VLM Agents. [Paper]
NeurIPS 2025
State Representation
- ToolLLM: Facilitating Large Language Models to Master 16000+ Real-world APIs. [Paper] [Code]
ICLR 2024 - WebArena: A Realistic Web Environment for Building Autonomous Agents. [Paper] [Code]
ICLR 2024 - SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering. [Paper] [Code]
NeurIPS 2024 - Do LLMs Build World Representations? Probing Through the Lens of State Abstraction. [Paper] [Code]
NeurIPS 2024 - AgentOccam: A Simple Yet Strong Baseline for LLM-Based Web Agents. [Paper]
ICLR 2025 - AgentTrek: Agent Trajectory Synthesis via Guiding Replay with Web Tutorials. [Paper] [Code]
ICLR 2025 - GRAPHGPT-O: Synergistic Multimodal Comprehension and Generation on Graphs. [Paper] [Code]
CVPR 2025 - The Complexity Trap: Simple Observation Masking Is as Efficient as LLM Summarization for Agent Context Management. [Paper]
arXiv 2025 - ESCA: Contextualizing Embodied Agents via Scene-Graph Generation. [Paper] [Code]
NeurIPS 2025 - Evaluating LLM Planning in Partially Observable Environments via Observation Representations and Action Sequences. [Paper]
NeurIPS 2025 Workshop - DynaWeb: Model-Based Reinforcement Learning of Web Agents. [Paper]
arXiv 2026 - Building a C compiler with a team of parallel Claudes. [Blog]
Blog 2026
2.1.2. Task Planning
Task Decomposition
- Chain-of-Thought Prompting Elicits Reasoning in Large Language Models. [Paper] [Code]
NeurIPS 2022 - Least-to-Most Prompting Enables Complex Reasoning in Large Language Models. [Paper]
ICLR 2023 - Tree of Thoughts: Deliberate Problem Solving with Large Language Models. [Paper] [Code]
NeurIPS 2023 - Graph of Thoughts: Solving Elaborate Problems with Large Language Models. [Paper] [Code]
AAAI 2024 - Agentic Reasoning: A Streamlined Framework for Enhancing LLM Reasoning with Agentic Tools. [Paper]
ACL 2025 - Agentic Reasoning for Large Language Models. [Paper]
arXiv 2026 - Building a C compiler with a team of parallel Claudes. [Blog]
Blog 2026
Plan Generation
- AvaTaR: Optimizing LLM Agents for Tool Usage via Contrastive Reasoning. [Paper] [Code]
NeurIPS 2024 - AFlow: Automating Agentic Workflow Generation. [Paper] [Code]
ICLR 2025 - GAP: Graph-Based Agent Planning with Parallel Tool Use and Reinforcement Learning. [Paper] [Code]
arXiv 2025
2.1.3. Action Execution
Tool Invocation
- Toolformer: Language Models Can Teach Themselves to Use Tools. [Paper]
NeurIPS 2023 - Code as Policies: Language Model Programs for Embodied Control. [Paper] [Code]
ICRA 2023 - SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering. [Paper] [Code]
NeurIPS 2024 - AppWorld: A Controllable World of Apps and People for Benchmarking Interactive Coding Agents. [Paper] [Code]
ACL 2024 - Code execution with MCP: building more efficient AI agents. [Blog]
Blog 2025 - Agent0-VL: Exploring Self-Evolving Agent for Tool-Integrated Vision-Language Reasoning. [Paper]
arXiv 2025 - Scaling Agentic Reinforcement Learning for Tool-Integrated Reasoning in VLMs. [Paper]
arXiv 2025 - Robust Tool Use via Fission-GRPO: Learning to Recover from Execution Errors. [Paper]
arXiv 2026
Environment Interaction
- ReAct: Synergizing Reasoning and Acting in Language Models. [Paper] [Code]
ICLR 2023 - SWE-agent: Agent-Computer Interfaces Enable Automated Software Engineering. [Paper] [Code]
NeurIPS 2024 - Grounding Multimodal Large Language Models in Actions. [Paper]
NeurIPS 2024 - ceLLMate: Sandboxing Browser AI Agents. [Paper]
arXiv 2025 - Agent-Fence: Mapping Security Vulnerabilities Across Deep Research Agents. [Paper]
arXiv 2026 - Quine: Realizing LLM Agents as Native POSIX Processes. [Paper]
arXiv 2026
2.2. Memory Systems
2.2.1. Short-term Memory
Working Memory
- ReAct: Synergizing Reasoning and Acting in Language Models. [Paper] [Code]
ICLR 2023 - ReadAgent: A Human-Inspired Reading Agent with Gist Memory of Very Long Contexts. [Paper] [Code]
ICML 2024 - Agent Workflow Memory. [Paper] [Code]
ICML 2025 - Understanding Software Engineering Agents: A Study of Thought-Action-Result Trajectories. [Paper]
ASE 2025 - Memo: Training Memory-Efficient Embodied Agents with Reinforcement Learning. [Paper] [Code]
NeurIPS 2025 - Managing Context on the Claude Developer Platform. [Blog]
Blog 2025 - Graph-based Agent Memory: Taxonomy, Techniques, and Applications. [Paper]
arXiv 2026
Conversational Memory
- MemGPT: Towards LLMs as Operating Systems. [Paper] [Code]
arXiv 2023 - Zep: A Temporal Knowledge Graph Architecture for Agent Memory. [Paper]
arXiv 2025 - From Isolated Conversations to Hierarchical Schemas: Dynamic Tree Memory Representation for LLMs. [Paper]
ICLR 2025 - SeCom: On Memory Construction and Retrieval for Personalized Conversational Agents. [Paper]
ICLR 2025 - Hello Again! LLM-powered Personalized Agent for Long-term Dialogue. [Paper]
NAACL 2025 - SGMem: Sentence Graph Memory for Long-Term Conversational Agents. [Paper]
arXiv 2025 - Managing Context on the Claude Developer Platform. [Blog]
Blog 2025 - Agentic Memory: Learning Unified Long-Term and Short-Term Memory Management for Large Language Model Agents. [Paper]
arXiv 2026 - From Single to Multi-Granularity: Toward Long-Term Memory Association and Selection of Conversational Agents. [Paper]
ICLR 2026 - FluxMem: Adaptive Hierarchical Memory for Streaming Video Understanding. [Paper]
CVPR 2026
2.2.2. Long-term Memory
Structured Memory
- Generative Agents: Interactive Simulacra of Human Behavior. [Paper] [Code]
UIST 2023 - Optimus-1: Hybrid Multimodal Memory Empowered Agents Excel in Long-Horizon Tasks. [Paper] [Code]
NeurIPS 2024 - A-Mem: Agentic Memory for LLM Agents. [Paper] [Code]
NeurIPS 2025 - Bridging Intuitive Associations and Deliberate Recall: Empowering LLM Personal Assistant with Graph-Structured Long-term Memory. [Paper]
Findings of ACL 2025 - CarMem: Enhancing Long-Term Memory in LLM Voice Assistants through Category-Bounding. [Paper]
COLING 2025 - Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory. [Paper] [Code]
ECAI 2025 - G-Memory: Tracing Hierarchical Memory for Multi-Agent Systems. [Paper] [Code]
NeurIPS 2025 - Graph-Native Cognitive Memory for AI Agents: Formal Belief Revision Semantics for Versioned Memory Architectures. [Paper]
arXiv 2026
Unstructured Memory
- MemGPT: Towards LLMs as Operating Systems. [Paper] [Code]
arXiv 2023 - Reflexion: language agents with verbal reinforcement learning. [Paper] [Code]
NeurIPS 2023 - MemoryBank: Enhancing Large Language Models with Long-Term Memory. [Paper] [Code]
AAAI 2024 - Memory-R1: Enhancing Large Language Model Agents to Manage and Utilize Memories via Reinforcement Learning. [Paper] [Code]
arXiv 2025 - MOOM: Maintenance, Organization and Optimization of Memory in Ultra-Long Role-Playing Dialogues. [Paper]
arXiv 2025 - O-Mem: Omni Memory System for Personalized, Long Horizon, Self-Evolving Agents. [Paper]
arXiv 2025 - General Agentic Memory Via Deep Research. [Paper]
arXiv 2025 - Evo-Memory: Benchmarking LLM Agent Test-time Learning with Self-Evolving Memory. [Paper] [Code]
arXiv 2025 - MEM1: Learning to Synergize Memory and Reasoning for Efficient Long-Horizon Agents. [Paper] [Code]
ICLR 2026 - MemAgent: Reshaping Long-Context LLM with Multi-Conv RL-based Memory Agent. [Paper] [Code]
ICLR 2026 - RetroAgent: From Solving to Evolving via Retrospective Dual Intrinsic Feedback. [Paper]
arXiv 2026 - Agentic Memory: Learning Unified Long-Term and Short-Term Memory Management for Large Language Model Agents. [Paper]
arXiv 2026 - Mem0: Universal Memory Layer for AI Agents. [Code]
Repo 2026 - OpenMemory: AI Memory MCP Server for Coding Agents. [Website]
Web 2026 - Memory - Docs by LangChain. [Docs]
Docs 2026 - Context Engineering: Memory, Compaction, and Tool Clearing. [Docs]
Docs 2026
2.3. Skill Libraries
- SkillsBench: Benchmarking How Well Agent Skills Work Across Diverse Tasks. [Paper] [Code]
arXiv 2026 - Memory - Docs by LangChain. [Docs]
Docs 2026 - SkillX: Automatically Constructing Skill Knowledge Bases for Agents. [Paper]
arXiv 2026
2.3.1. Skill Acquisition
Learning from Demonstration
- Toolformer: Language Models Can Teach Themselves to Use Tools. [Paper]
NeurIPS 2023 - Large Language Models as Tool Makers. [Paper] [Code]
ICLR 2024 - Gorilla: Large Language Model Connected with Massive APIs. [Paper]
NeurIPS 2024 - Voyager: An Open-Ended Embodied Agent with Large Language Models. [Paper] [Code]
TMLR 2024 - Synatra: Turning Indirect Knowledge into Direct Demonstrations for Digital Agents at Scale. [Paper]
NeurIPS 2024 - ToolACE: Winning the Points of LLM Function Calling. [Paper] [Code]
ICLR 2025 - SkillWeaver: Web Agents can Self-Improve by Discovering and Honing Skills. [Paper]
arXiv 2025 - Agent Skill Acquisition for Large Language Models via CycleQD. [Paper] [Code]
arXiv 2025 - Inducing Programmatic Skills for Agentic Tasks. [Paper]
COLM 2025 - SoK: Agentic Skills - Beyond Tool Use in LLM Agents. [Paper]
arXiv 2026 - Agent Skills for Large Language Models: Architecture, Acquisition, Security, and the Path Forward. [Paper]
arXiv 2026 - SkillCraft: Can LLM Agents Learn to Use Tools Skillfully? [Paper] [Code]
arXiv 2026 - Trace2Skill: Distill Trajectory-Local Lessons into Transferable Agent Skills. [Paper]
arXiv 2026 - Go-Browse: Training Web Agents with Structured Exploration. [Paper]
ICLR 2026 - ContractSkill: Repairable Contract-Based Skills for Multimodal Web Agents. [Paper]
arXiv 2026
Learning from Experience
- Hierarchical Reinforcement Learning: A Survey and Open Research Challenges. [Paper]
MAKE 2022 - ExpeL: LLM Agents Are Experiential Learners. [Paper] [Code]
AAAI 2024 - OS-Copilot: Towards Generalist Computer Agents with Self-Improvement. [Paper] [Code]
ICLR 2024 - SEAgent: Self-Evolving Computer Use Agent with Autonomous Learning from Experience. [Paper] [Code]
arXiv 2025 - Leveraging Skills from Unlabeled Prior Data for Efficient Online Exploration. [Paper] [Code]
ICML 2025 - Reinforcement Learning for Self-Improving Agent with Skill Library. [Paper] [Code]
arXiv 2025 - Toward Training Superintelligent Software Agents through Self-Play SWE-RL. [Paper] [Code]
ICML 2026 - Evolving Programmatic Skill Networks. [Paper]
arXiv 2026 - SkillRL: Evolving Agents via Recursive Skill-Augmented Reinforcement Learning. [Paper] [Code]
ICLR 2026 Workshop - Tool-R0: Self-Evolving LLM Agents for Tool-Learning from Zero Data. [Paper]
arXiv 2026 - AutoSkill: Experience-Driven Lifelong Learning via Skill Self-Evolution. [Paper]
arXiv 2026 - Memento-Skills: Let Agents Design Agents. [Paper]
arXiv 2026 - ELITE: Experiential Learning and Intent-Aware Transfer for Self-improving Embodied Agents. [Paper]
arXiv 2026 - SKILL0: In-Context Agentic Reinforcement Learning for Skill Internalization. [Paper] [Code]
arXiv 2026 - Skill-SD: Skill-Conditioned Self-Distillation for Multi-turn LLM Agents. [Paper] [Project]
arXiv 2026
Learning from External Resources
- Equipping Agents for the Real World with Agent Skills. [Blog]
Blog 2025 - Agent Skills. [Docs]
Docs 2025 - Skills in OpenAI API. [Docs]
Docs 2026 - SKILLFOUNDRY: Building Self-Evolving Agent Skill Libraries from Heterogeneous Scientific Resources. [Paper]
arXiv 2026
2.3.2. Skill Management
Skill Representation
- Voyager: An Open-Ended Embodied Agent with Large Language Models. [Paper] [Code]
TMLR 2024 - Inducing Programmatic Skills for Agentic Tasks. [Paper]
COLM 2025 - ToolGen: Unified Tool Retrieval and Calling via Generation. [Paper] [Code]
ICLR 2025 - Equipping Agents for the Real World with Agent Skills. [Blog]
Blog 2025 - SoK: Agentic Skills - Beyond Tool Use in LLM Agents. [Paper]
arXiv 2026 - Evolving Programmatic Skill Networks. [Paper]
arXiv 2026 - CUA-Skill: Develop Skills for Computer Using Agent. [Paper] [Code]
arXiv 2026 - Trace2Skill: Distill Trajectory-Local Lessons into Transferable Agent Skills. [Paper]
arXiv 2026 - Memento-Skills: Let Agents Design Agents. [Paper]
arXiv 2026 - SkillFlow: Scalable and Efficient Agent Skill Retrieval System. [Paper]
arXiv 2026 - Graph of Skills: Dependency-Aware Structural Retrieval for Massive Agent Skills. [Paper]
arXiv 2026 - SkillRouter: Skill Routing for LLM Agents at Scale. [Paper]
arXiv 2026 - Skills in OpenAI API. [Docs]
Docs 2026 - Agent Skills. [Docs]
Docs 2026
Skill Retrieval
- Voyager: An Open-Ended Embodied Agent with Large Language Models. [Paper] [Code]
TMLR 2024 - SRSA: Skill Retrieval and Adaptation for Robotic Assembly Tasks. [Paper]
ICLR 2025 - EvolveR: Self-Evolving LLM Agents through an Experience-Driven Lifecycle. [Paper] [Code]
arXiv 2025 - Memento-Skills: Let Agents Design Agents. [Paper]
arXiv 2026 - IntentCUA: Learning Intent-level Representations for Skill Abstraction and Multi-Agent Planning in Computer-Use Agents. [Paper]
arXiv 2026 - GraphSkill: Documentation-Guided Hierarchical Retrieval-Augmented Coding for Complex Graph Reasoning. [Paper]
arXiv 2026 - SkillRouter: Skill Routing for LLM Agents at Scale. [Paper]
arXiv 2026 - SkillFlow: Scalable and Efficient Agent Skill Retrieval System. [Paper]
arXiv 2026 - Graph of Skills: Dependency-Aware Structural Retrieval for Massive Agent Skills. [Paper]
arXiv 2026 - WebXSkill: Skill Learning for Autonomous Web Agents. [Paper]
arXiv 2026 - Skill Retrieval Augmentation for Agentic AI. [Paper]
arXiv 2026
2.3.3. Skill Maintenance
Library Curation
- Using Skills to Accelerate OSS Maintenance. [Blog]
Blog 2026 - Shell + Skills + Compaction: Tips for Long-Running Agents that Do Real Work. [Blog]
Blog 2026 - SkillRouter: Skill Routing for LLM Agents at Scale. [Paper]
arXiv 2026 - Graph of Skills: Dependency-Aware Structural Retrieval for Massive Agent Skills. [Paper]
arXiv 2026
Skill Governance
- Equipping Agents for the Real World with Agent Skills. [Blog]
Blog 2025 - Skills in OpenAI API. [Docs]
Docs 2026 - Testing Agent Skills Systematically with Evals. [Blog]
Blog 2026 - Towards Secure Agent Skills: Architecture, Threat Taxonomy, and Security Analysis. [Paper]
arXiv 2026
2.4. Multi-agent Orchestration
2.4.1. Coordination Architectures
Centralized Architectures
- ChatDev: Communicative Agents for Software Development. [Paper] [Code]
ACL 2024 - MetaGPT: Meta Programming for A Multi-Agent Collaborative Framework. [Paper] [Code]
ICLR 2024 - AutoGen: Enabling Next-Gen LLM Applications via Multi-Agent Conversations. [Paper] [Code]
COLM 2024 - AutoAgents: A Framework for Automatic Agent Generation. [Paper] [Code]
IJCAI 2024 - Scaling Large Language Model-based Multi-Agent Collaboration. [Paper] [Code]
ICLR 2025 - AutoAgent: A Fully-Automated and Zero-Code Framework for LLM Agents. [Paper] [Code]
arXiv 2025 - Agent S2: A Compositional Generalist-Specialist Framework for Computer Use Agents. [Paper] [Code]
COLM 2025 - MegaAgent: A Large-Scale Autonomous LLM-based Multi-Agent System Without Predefined SOPs. [Paper] [Code]
Findings of ACL 2025 - Multi-Agent Collaboration via Evolving Orchestration. [Paper] [Code]
NeurIPS 2025
Decentralized Architectures
- CAMEL: Communicative Agents for "Mind" Exploration of Large Language Model Society. [Paper] [Code]
NeurIPS 2023 - AgentVerse: Facilitating Multi-Agent Collaboration and Exploring Emergent Behaviors in Agents. [Paper] [Code]
arXiv 2023 - ProAgent: Building Proactive Cooperative Agents with Large Language Models. [Paper]
AAAI 2024 - A Dynamic LLM-Powered Agent Network for Task-Oriented Agent Collaboration. [Paper] [Code]
COLM 2024 - CONSENSAGENT: Towards Efficient and Effective Consensus in Multi-Agent LLM Interactions Through Sycophancy Mitigation. [Paper] [Code]
Findings of ACL 2025 - AgentOrchestra: Orchestrating Multi-Agent Intelligence with the Tool-Environment-Agent(TEA) Protocol. [Paper]
arXiv 2025 - LLM-Driven Multi-Agent Architectures for Intelligent Self-Organizing Networks. [Paper]
IEEE Network 2025 - Building a C Compiler with a Team of Parallel Claudes. [Blog]
Blog 2026
2.4.2. Communication Mechanisms
Debate-based Methods
- Encouraging Divergent Thinking in Large Language Models through Multi-Agent Debate. [Paper] [Code]
EMNLP 2024 - Should we be going MAD? A Look at Multi-Agent Debate Strategies for LLMs. [Paper]
ICML 2024 - MetaGPT: Meta Programming for A Multi-Agent Collaborative Framework. [Paper] [Code]
ICLR 2024 - RoleLLM: Benchmarking, Eliciting, and Enhancing Role-Playing Abilities of Large Language Models. [Paper] [Code]
Findings of ACL 2024 - Debate-to-Write: A Persona-Driven Multi-Agent Framework for Diverse Argument Generation. [Paper] [Code]
COLING 2025 - Table-Critic: A Multi-Agent Framework for Collaborative Criticism and Refinement in Table Reasoning. [Paper]
ACL 2025 - Reinforce LLM Reasoning through Multi-Agent Reflection. [Paper]
ICML 2025 - CONSENSAGENT: Towards Efficient and Effective Consensus in Multi-Agent LLM Interactions Through Sycophancy Mitigation. [Paper] [Code]
Findings of ACL 2025 - Player-Coach Teamwork: Multi-agent Collaboration for Improving LLM Reasoning. [Paper]
NeurIPS 2025 Workshop
Collaboration-based Methods
- ChatDev: Communicative Agents for Software Development. [Paper] [Code]
ACL 2024 - MetaGPT: Meta Programming for A Multi-Agent Collaborative Framework. [Paper] [Code]
ICLR 2024 - GPTSwarm: Language Agents as Optimizable Graphs. [Paper]
ICML 2024 - Long-Horizon Planning for Multi-Agent Robots in Partially Observable Environments. [Paper] [Code]
NeurIPS 2024 - MapCoder: Multi-Agent Code Generation for Competitive Problem Solving. [Paper] [Code]
ACL 2024 - Flow-of-Action: SOP Enhanced LLM-Based Multi-Agent System for Root Cause Analysis. [Paper]
WWW 2025 - MAPoRL: Multi-Agent Post-Co-Training for Collaborative Large Language Models with Reinforcement Learning. [Paper] [Code]
ACL 2025 - MARFT: Multi-Agent Reinforcement Fine-Tuning. [Paper] [Code]
arXiv 2025 - Multi-Agent Collaboration via Evolving Orchestration. [Paper] [Code]
NeurIPS 2025 - AgentOrchestra: Orchestrating Multi-Agent Intelligence with the Tool-Environment-Agent(TEA) Protocol. [Paper]
arXiv 2025 - Chain-of-Agents: End-to-End Agent Foundation Models via Multi-Agent Distillation and Agentic RL. [Paper] [Code]
arXiv 2025 - Multi-Agent Evolve: LLM Self-Improve through Co-evolution. [Paper] [Code]
arXiv 2025 - InstructFlow: Adaptive Symbolic Constraint-Guided Code Generation for Long-Horizon Planning. [Paper] [Code]
NeurIPS 2025 - How and When to Build Multi-Agent Systems. [Blog]
Blog 2025 - Don't Build Multi-Agents. [Blog]
Blog 2025 - Toward Autonomous Long-Horizon Engineering for ML Research. [Paper]
arXiv 2026
3. Model Adaptation for Harness
3.1. Context Engineering
3.1.1. Context Design
Prompt Engineering
- Chain-of-Thought Prompting Elicits Reasoning in Large Language Models. [Paper] [Code]
NeurIPS 2022 - Large Language Models are Zero-Shot Reasoners. [Paper]
NeurIPS 2022 - Tree of Thoughts: Deliberate Problem Solving with Large Language Models. [Paper] [Code]
NeurIPS 2023 - Graph of Thoughts: Solving Elaborate Problems with Large Language Models. [Paper] [Code]
AAAI 2024 - Role play with large language models. [Paper]
Nature 2023 - CAMEL: Communicative Agents for "Mind" Exploration of Large Language Model Society. [Paper] [Code]
NeurIPS 2023 - Generative Agents: Interactive Simulacra of Human Behavior. [Paper] [Code]
UIST 2023 - CoSER: A Comprehensive Literary Dataset and Framework for Training and Evaluating LLM Role-Playing and Persona Simulation. [Paper] [Code]
ICML 2025 - Large Language Models Are Human-Level Prompt Engineers. [Paper]
ICLR 2023 - Making Pre-trained Language Models Better Few-shot Learners. [Paper]
ACL 2021 - Self-Refine: Iterative Refinement with Self-Feedback. [Paper] [Code]
NeurIPS 2023 - Promptbreeder: Self-Referential Self-Improvement Via Prompt Evolution. [Paper]
ICML 2024
Context Retrieval
- Interleaving Retrieval with Chain-of-Thought Reasoning for Knowledge-Intensive Multi-Step Questions. [Paper]
ACL 2023 - ReAct: Synergizing Reasoning and Acting in Language Models. [Paper] [Code]
ICLR 2023 - REPLUG: Retrieval-Augmented Black-Box Language Models. [Paper] [Code]
NAACL 2024 - Self-RAG: Learning to Retrieve, Generate, and Critique through Self-Reflection. [Paper] [Code]
ICLR 2024 - CRAG: Corrective Retrieval Augmented Generation. [Paper] [Code]
arXiv 2024 - RAPTOR: Recursive Abstractive Processing for Tree-Organized Retrieval. [Paper] [Code]
ICLR 2024 - Adaptive-RAG: Learning to Adapt Retrieval-Augmented Large Language Models through Question Complexity. [Paper] [Code]
NAACL 2024 - HippoRAG: Neurobiologically Inspired Long-Term Memory for Large Language Models. [Paper]
NeurIPS 2024 - Think-on-Graph: Deep and Responsible Reasoning of Large Language Model on Knowledge Graph. [Paper]
ICLR 2024 - DSPy: Compiling Declarative Language Model Calls into Self-Improving Pipelines. [Paper]
ICLR 2024 - StructRAG: Boosting Knowledge Intensive Reasoning of LLMs via Inference-time Hybrid Information Structurization. [Paper]
ICLR 2025 - Search-o1: Agentic Search-Enhanced Large Reasoning Models. [Paper] [Code]
EMNLP 2025 - Deeprag: Thinking to retrieve step by step for large language models. [Paper] [Code]
arXiv 2025 - Model Context Protocol (MCP): Landscape, Security Threats, and Future Research Directions. [Paper] [Code]
arXiv 2025 - MA-RAG: Multi-Agent Retrieval-Augmented Generation via Collaborative Chain-of-Thought Reasoning. [Paper]
arXiv 2025 - A-RAG: Scaling Agentic Retrieval-Augmented Generation via Hierarchical Retrieval Interfaces. [Paper]
arXiv 2026
3.1.2. Context Management
Context Processing
- Lost in the Middle: How Language Models Use Long Contexts. [Paper] [Code]
TACL 2024 - LLMLingua: Compressing Prompts for Accelerated Inference of Large Language Models. [Paper]
EMNLP 2023 - Compressing Context to Enhance Inference Efficiency of Large Language Models. [Paper] [Code]
EMNLP 2023 - LLM Maybe LongLM: Self-Extend LLM Context Window Without Tuning. [Paper] [Code]
ICML 2024 - ACON: Optimizing Context Compression for Long-horizon LLM Agents. [Paper] [Code]
arXiv 2025 - Reducing Cost of LLM Agents with Trajectory Reduction. [Paper]
arXiv 2025 - AgentFold: Long-Horizon Web Agents with Proactive Context Management. [Paper]
arXiv 2025 - SWE-Pruner: Self-Adaptive Context Pruning for Coding Agents. [Paper]
arXiv 2026 - CEDAR: Context Engineering for Agentic Data Science. [Paper] [Code]
arXiv 2026 - IterResearch: Rethinking Long-Horizon Agents with Interaction Scaling. [Paper]
ICLR 2026
Context Updating
- Reflexion: language agents with verbal reinforcement learning. [Paper] [Code]
NeurIPS 2023 - MemGPT: Towards LLMs as Operating Systems. [Paper] [Code]
arXiv 2023 - Efficient Streaming Language Models with Attention Sinks. [Paper] [Code]
ICLR 2024 - MemoryBank: Enhancing Large Language Models with Long-Term Memory. [Paper] [Code]
AAAI 2024 - Agent Workflow Memory. [Paper] [Code]
ICML 2025 - Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory. [Paper] [Code]
ECAI 2025 - A-Mem: Agentic Memory for LLM Agents. [Paper] [Code]
NeurIPS 2025 - HiAgent: Hierarchical Working Memory Management for Solving Long-Horizon Agent Tasks with Large Language Model. [Paper]
ACL 2025 - Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models. [Paper] [Code]
ICLR 2026 - Dynamic Affective Memory Management for Personalized LLM Agents. [Paper]
arXiv 2025 - Meta Context Engineering via Agentic Skill Evolution. [Paper] [Code]
ICML 2026 - AgentSys: Secure and Dynamic LLM Agents Through Explicit Hierarchical Memory Management. [Paper]
arXiv 2026
3.2. Agentic Training
3.2.1. Environment Construction
Rule-Based Environments
- ALFWorld: Aligning Text and Embodied Environments for Interactive Learning. [Paper] [Code]
ICLR 2021 - ScienceWorld: Is your Agent Smarter than a 5th Grader? [Paper] [Code]
EMNLP 2022 - WebShop: Towards Scalable Real-World Web Interaction with Grounded Language Agents. [Paper] [Code]
NeurIPS 2022 - InterCode: Standardizing and Benchmarking Interactive Coding with Execution Feedback. [Paper] [Code]
NeurIPS 2023 - AlphaMath Almost Zero: Process Supervision without Process. [Paper]
NeurIPS 2024 - Step-level Value Preference Optimization for Mathematical Reasoning. [Paper]
Findings of EMNLP 2024 - AppWorld: A Controllable World of Apps and People for Benchmarking Interactive Coding Agents. [Paper] [Code]
ACL 2024 - ScienceAgentBench: Toward Rigorous Assessment of Language Agents for Data-Driven Scientific Discovery. [Paper] [Code]
ICLR 2025 - MLGym: A New Framework and Benchmark for Advancing AI Research Agents. [Paper]
arXiv 2025 - Reinforcement Learning for Reasoning in Large Language Models with One Training Example. [Paper]
arXiv 2025 - FormalMATH: Benchmarking Formal Mathematical Reasoning of Large Language Models. [Paper]
arXiv 2025 - REASONING GYM: Reasoning Environments for Reinforcement Learning with Verifiable Rewards. [Paper]
arXiv 2025 - R-Zero: Self-Evolving Reasoning LLM from Zero Data. [Paper]
arXiv 2025 - Immersion in the GitHub Universe: Scaling Coding Agents to Mastery. [Paper]
arXiv 2026 - EnterpriseOps-Gym: Environments and Evaluations for Stateful Agentic Planning and Tool Use in Enterprise Settings. [Paper]
arXiv 2026
Simulation-Based Environments
- Reasoning with Language Model is Planning with World Model. [Paper]
EMNLP 2023 - NeuralOS: Towards Simulating Operating Systems via Neural Generative Models. [Paper]
arXiv 2025 - BuilderBench: The Building Blocks of Intelligent Agents. [Paper]
arXiv 2025 - MEAL: A Benchmark for Continual Multi-Agent Reinforcement Learning. [Paper]
arXiv 2025 - Agent World Model: Infinity Synthetic Environments for Agentic Reinforcement Learning. [Paper]
arXiv 2026 - WebWorld: A Large-Scale World Model for Web Agent Training. [Paper]
arXiv 2026
Real-World Environments
- PaLM-E: An Embodied Multimodal Language Model. [Paper]
ICML 2023 - RT-2: Vision-Language-Action Models Transfer Web Knowledge to Robotic Control. [Paper]
CoRL 2023 - WebArena: A Realistic Web Environment for Building Autonomous Agents. [Paper] [Code]
ICLR 2024 - AgentBench: Evaluating LLMs as Agents. [Paper] [Code]
ICLR 2024 - DigiRL: Training In-The-Wild Device-Control Agents with Autonomous Reinforcement Learning. [Paper] [Code]
NeurIPS 2024 - The BrowserGym Ecosystem for Web Agent Research. [Paper]
TMLR 2025 - Digi-Q: Learning Q-Value Functions for Training Device-Control Agents. [Paper]
ICLR 2025 - WebRL: Training LLM Web Agents via Self-Evolving Online Curriculum Reinforcement Learning. [Paper] [Code]
ICLR 2025 - DeepResearcher: Scaling Deep Research via Reinforcement Learning in Real-world Environments. [Paper] [Code]
EMNLP 2025 - PhysiAgent: An Embodied Agent Framework in Physical World. [Paper]
arXiv 2025 - BrowseComp-V^3: A Visual, Vertical, and Verifiable Benchmark for Multimodal Browsing Agents. [Paper]
arXiv 2026 - EnterpriseBench Corecraft: Training Generalizable Agents on High-Fidelity RL Environments. [Paper]
arXiv 2026 - MolmoWeb: Open Visual Web Agent and Open Data for the Open Web. [Paper]
arXiv 2026
3.2.2. Reward Design
Outcome-Level Rewards
- DeepSeek-Prover-V1.5: Harnessing Proof Assistant Feedback for Reinforcement Learning and Monte-Carlo Tree Search. [Paper]
ICLR 2025 - ACECODER: Acing Coder RL via Automated Test-Case Synthesis. [Paper]
ACL 2025 - Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning. [Paper] [Code]
COLM 2025 - TTRL: Test-Time Reinforcement Learning. [Paper]
arXiv 2025 - Agentic Reasoning and Tool Integration for LLMs via Reinforcement Learning. [Paper]
arXiv 2025 - Agent RL Scaling Law: Agent RL with Spontaneous Code Execution for Mathematical Problem Solving. [Paper]
arXiv 2025 - Qwen3 Technical Report. [Paper]
arXiv 2025 - Outcome-based Reinforcement Learning to Predict the Future. [Paper]
TMLR 2025 - DeepResearcher: Scaling Deep Research via Reinforcement Learning in Real-world Environments. [Paper] [Code]
EMNLP 2025 - DeepCoder: A Fully Open-Source 14B Coder at O3-mini Level. [Blog]
Blog 2025 - DeepSWE: Training a Fully Open-sourced, State-of-the-Art Coding Agent by Scaling RL. [Blog]
Blog 2025
Process-Level Rewards
- Let's Verify Step by Step. [Paper] [Code]
ICLR 2024 - Math-Shepherd: Verify and Reinforce LLMs Step-by-step without Human Annotations. [Paper]
ACL 2024 - Improve Mathematical Reasoning in Language Models by Automated Process Supervision. [Paper]
arXiv 2024 - ToolRL: Reward is All Tool Learning Needs. [Paper] [Code]
NeurIPS 2025 - GUI-G^2: Gaussian Reward Modeling for GUI Grounding. [Paper]
AAAI 2026 - Process Reward Models That Think. [Paper] [Code]
TMLR 2026
3.2.3. Training Optimization Algorithms
Supervised Fine-Tuning
- Toolformer: Language Models Can Teach Themselves to Use Tools. [Paper]
NeurIPS 2023 - Gorilla: Large Language Model Connected with Massive APIs. [Paper] [Code]
NeurIPS 2024 - ToolLLM: Facilitating Large Language Models to Master 16000+ Real-world APIs. [Paper] [Code]
ICLR 2024 - FireAct: Toward Language Agent Fine-tuning. [Paper] [Code]
arXiv 2023 - AgentTuning: Enabling Generalized Agent Abilities for LLMs. [Paper] [Code]
Findings of ACL 2024 - AgentOhana: Design Unified Data and Training Pipeline for Effective Agent Learning. [Paper] [Code]
arXiv 2024 - CodeAct: Executable Code Actions Elicit Better LLM Agents. [Paper] [Code]
ICML 2024 - Agent-FLAN: Designing Data and Methods of Effective Agent Tuning for Large Language Models. [Paper] [Code]
Findings of ACL 2024 - MAGDi: Structured Distillation of Multi-Agent Interaction Graphs Improves Reasoning in Smaller Language Models. [Paper]
ICML 2024 - On-Policy Distillation of Language Models: Learning from Self-Generated Mistakes. [Paper]
ICLR 2024 - MiniLLM: On-Policy Distillation of Large Language Models. [Paper]
ICLR 2024 - AgentTrek: Agent Trajectory Synthesis via Guiding Replay with Web Tutorials. [Paper] [Code]
ICLR 2025 - Efficient Agent Training for Computer Use. [Paper]
arXiv 2025 - Structured Agent Distillation for Large Language Model. [Paper]
arXiv 2025 - Merge-of-Thought Distillation. [Paper]
arXiv 2025 - Black-Box On-Policy Distillation of Large Language Models. [Paper]
arXiv 2025 - Expanding the Capability Frontier of LLM Agents with ZPD-Guided Data Synthesis. [Paper]
ICLR 2026 - Stable On-Policy Distillation through Adaptive Target Reformulation. [Paper]
arXiv 2026 - Learning beyond Teacher: Generalized On-Policy Distillation with Reward Extrapolation. [Paper]
arXiv 2026 - On Data Engineering for Scaling LLM Terminal Capabilities. [Paper]
arXiv 2026 - Scaling Reasoning Efficiently via Relaxed On-Policy Distillation. [Paper]
arXiv 2026 - Immersion in the GitHub Universe: Scaling Coding Agents to Mastery. [Paper]
arXiv 2026 - ClawGym: A Scalable Framework for Building Effective Claw Agents. [Paper]
arXiv 2026
Reinforcement Learning Approaches
- Proximal Policy Optimization Algorithms. [Paper]
arXiv 2017 - Direct Preference Optimization: Your Language Model is Secretly a Reward Model. [Paper] [Code]
NeurIPS 2023 - Secrets of RLHF in Large Language Models Part I: PPO. [Paper] [Code]
arXiv 2023 - LATS: Language Agent Tree Search Unifies Reasoning, Acting, and Planning. [Paper] [Code]
ICML 2024 - Secrets of RLHF in Large Language Models Part II: Reward Modeling. [Paper] [Code]
arXiv 2024 - KTO: Model Alignment as Prospect Theoretic Optimization. [Paper] [Code]
arXiv 2024 - ArCHer: Training Language Model Agents via Hierarchical Multi-Turn RL. [Paper] [Code]
ICML 2024 - DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models. [Paper] [Code]
arXiv 2024 - ORPO: Monolithic Preference Optimization without Reference Model. [Paper] [Code]
EMNLP 2024 - SimPO: Simple Preference Optimization with a Reference-Free Reward. [Paper] [Code]
NeurIPS 2024 - WARP: On the Benefits of Weight Averaged Rewarded Policies. [Paper]
arXiv 2024 - ReMax: A Simple, Effective, and Efficient Reinforcement Learning Method for Aligning Large Language Models. [Paper]
ICML 2024 - VinePPO: Refining Credit Assignment in RL Training of LLMs. [Paper]
ICML 2025 - Kimi k1.5: Scaling Reinforcement Learning with LLMs. [Paper]
arXiv 2025 - DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning. [Paper]
Nature 2025 - DAPO: An Open-Source LLM Reinforcement Learning System at Scale. [Paper] [Code]
arXiv 2025 - RAGEN: Understanding Self-Evolution in LLM Agents via Multi-Turn Reinforcement Learning. [Paper] [Code]
arXiv 2025 - WebThinker: Empowering Large Reasoning Models with Deep Research Capability. [Paper] [Code]
NeurIPS 2025 - Group-in-Group Policy Optimization for LLM Agent Training. [Paper] [Code]
arXiv 2025 - Agentic Reinforced Policy Optimization. [Paper] [Code]
arXiv 2025 - LLM Collaboration with Multi-Agent Reinforcement Learning. [Paper]
AAAI 2026 - Tree Search for LLM Agent Reinforcement Learning. [Paper]
arXiv 2025 - ML-Agent: Reinforcing LLM Agents for Autonomous Machine Learning Engineering. [Paper]
arXiv 2025 - ACT: Agentic Critical Training. [Paper]
arXiv 2026
3.2.4. Infrastructure
General-Purpose Frameworks
- OpenRLHF: An Easy-to-use, Scalable and High-performance RLHF Framework. [Paper] [Code]
arXiv 2024 - NeMo-Aligner: Scalable Toolkit for Efficient Model Alignment. [Paper] [Code]
arXiv 2024 - ReaL: Efficient RLHF Training of Large Language Models with Parameter Reallocation. [Paper] [Code]
arXiv 2024 - AgentGym: Evolving Large Language Model-based Agents across Diverse Environments. [Paper] [Code]
arXiv 2024 - HybridFlow: A Flexible and Efficient RLHF Framework. [Paper] [Code]
EuroSys 2025 - Open-Reasoner-Zero: An Open Source Approach to Scaling Up Reinforcement Learning on the Base Model. [Paper]
arXiv 2025 - RAGEN: Understanding Self-Evolution in LLM Agents via Multi-Turn Reinforcement Learning. [Paper] [Code]
arXiv 2025 - Group-in-Group Policy Optimization for LLM Agent Training. [Paper] [Code]
arXiv 2025 - AReaL: A Large-Scale Asynchronous Reinforcement Learning System for Language Reasoning. [Paper] [Code]
arXiv 2025 - Agent Lightning: Train ANY AI Agents with Reinforcement Learning. [Paper] [Code]
arXiv 2025 - AgentGym-RL: Training LLM Agents for Long-Horizon Decision Making through Multi-Turn Reinforcement Learning. [Paper]
arXiv 2025 - GEM: A Gym for Agentic LLMs. [Paper] [Code]
arXiv 2025 - AgentRL: Scaling Agentic Reinforcement Learning with a Multi-Turn, Multi-Task Framework. [Paper]
arXiv 2025 - SkyRL-Agent: Efficient RL Training for Multi-turn LLM Agent. [Paper] [Code]
arXiv 2025 - Agent-R1: Training Powerful LLM Agents with End-to-End Reinforcement Learning. [Paper] [Code]
arXiv 2025 - RollArt: Scaling Agentic RL Training via Disaggregated Infrastructure. [Paper]
arXiv 2025
Specialized Frameworks
- Multimodal Reinforcement Learning with Agentic Verifier for AI Agents. [Paper]
arXiv 2025 - Dr. MAS: Stable Reinforcement Learning for Multi-Agent LLM Systems. [Paper]
arXiv 2026 - MARTI: A Framework for Multi-Agent LLM Systems Reinforced Training and Inference. [Paper]
ICLR 2026 - LLM Collaboration with Multi-Agent Reinforcement Learning. [Paper]
AAAI 2026 - WideSeek-R1: Exploring Width Scaling for Broad Information Seeking via Multi-Agent Reinforcement Learning. [Paper]
arXiv 2026 - MM-DeepResearch: A Simple and Effective Multimodal Agentic Search Baseline. [Paper]
arXiv 2026 - GrandCode: Achieving Grandmaster Level in Competitive Programming via Agentic Reinforcement Learning. [Paper]
arXiv 2026 - LiteResearcher: A Scalable Agentic RL Training Framework for Deep Research Agent. [Paper] [Code]
arXiv 2026
4. Representative Benchmarks by Task Domain
4.1. Deep Research
- BrowseComp: A Simple Yet Challenging Benchmark for Browsing Agents. [Paper] [Code]
arXiv 2025 - IDRBench: Interactive Deep Research Benchmark. [Paper]
arXiv 2026 - ReportBench: Evaluating Deep Research Agents via Academic Survey Tasks. [Paper] [Code]
arXiv 2025 - Characterizing Deep Research: A Benchmark and Formal Definition. [Paper] [Code]
ICLR 2026 - WideSearch: Benchmarking Agentic Broad Info-Seeking. [Paper] [Code]
ICLR 2026 - LiveResearchBench: A Live Benchmark for User-Centric Deep Research in the Wild. [Paper] [Code]
ICLR 2026 - ResearchRubrics: A Benchmark of Prompts and Rubrics For Evaluating Deep Research Agents. [Paper] [Code]
ICLR 2026 - DeepSynth-Eval: Objectively Evaluating Information Consolidation in Deep Survey Writing. [Paper]
arXiv 2026 - DeepResearch Bench II: Diagnosing Deep Research Agents via Rubrics from Expert Report. [Paper] [Code]
arXiv 2026 - MMDeepResearch-Bench: A Benchmark for Multimodal Deep Research Agents. [Paper] [Code]
arXiv 2026 - DeepSurvey-Bench: Evaluating Academic Value of Automatically Generated Scientific Survey. [Paper]
arXiv 2026
4.2. Software Engineering
- RepoBench: Benchmarking Repository-Level Code Auto-Completion Systems. [Paper] [Code]
ICLR 2024 - SWE-bench: Can Language Models Resolve Real-world Github Issues? [Paper] [Code]
ICLR 2024 - LiveCodeBench: Holistic and Contamination Free Evaluation of Large Language Models for Code. [Paper] [Code]
ICLR 2025 - Can Language Models Replace Programmers for Coding? REPOCOD Says 'Not Yet'. [Paper] [Code]
ACL 2025 - SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks? [Paper] [Code]
arXiv 2025 - SWE-Sharp-Bench: A Reproducible Benchmark for C# Software Engineering Tasks. [Paper] [Code]
AIware 2025 - LoCoBench-Agent: An Interactive Benchmark for LLM Agents in Long-Context Software Engineering. [Paper] [Code]
arXiv 2025 - NL2Repo-Bench: Towards Long-Horizon Repository Generation Evaluation of Coding Agents. [Paper] [Code]
ICML 2026 - OmniCode: A Benchmark for Evaluating Software Engineering Agents. [Paper] [Code]
arXiv 2026 - SWE-Universe: Scale Real-World Verifiable Environments to Millions. [Paper]
arXiv 2026 - FeatureBench: Benchmarking Agentic Coding for Complex Feature Development. [Paper] [Code]
ICLR 2026
4.3. Tool Use and Function Calling
- API-Bank: A Comprehensive Benchmark for Tool-Augmented LLMs. [Paper] [Code]
EMNLP 2023 - AgentBench: Evaluating LLMs as Agents. [Paper] [Code]
ICLR 2024 - GAIA: a benchmark for General AI Assistants. [Paper] [Code]
ICLR 2024 - tau-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains. [Paper] [Code]
ICLR 2025 - AppWorld: A Controllable World of Apps and People for Benchmarking Interactive Coding Agents. [Paper] [Code]
ACL 2024 - AssistantBench: Can Web Agents Solve Realistic and Time-Consuming Tasks? [Paper] [Code]
EMNLP 2024 - Toolsandbox: A stateful, conversational, interactive evaluation benchmark for llm tool use capabilities. [Paper] [Code]
Findings of NAACL 2025 - ToolHop: A Query-Driven Benchmark for Evaluating Large Language Models in Multi-Hop Tool Use. [Paper] [Code]
ACL 2025 - DICE-BENCH: Evaluating the Tool-Use Capabilities of Large Language Models in Multi-Round, Multi-Party Dialogues. [Paper] [Code]
Findings of ACL 2025 - tau^2-Bench: Evaluating Conversational Agents in a Dual-Control Environment. [Paper] [Code]
arXiv 2025 - The Berkeley Function Calling Leaderboard (BFCL): From Tool Use to Agentic Evaluation of Large Language Models. [Paper] [Code]
ICML 2025 - CCTU: A Benchmark for Tool Use under Complex Constraints. [Paper] [Code]
arXiv 2026
4.4. Computer Use and GUI Grounding
- Mind2Web: Towards a Generalist Agent for the Web. [Paper] [Code]
NeurIPS 2023 - WebArena: A Realistic Web Environment for Building Autonomous Agents. [Paper] [Code]
ICLR 2024 - Android in the Wild: A Large-Scale Dataset for Android Device Control. [Paper] [Code]
NeurIPS 2023 - VisualWebArena: Evaluating Multimodal Agents on Realistic Visual Web Tasks. [Paper] [Code]
ACL 2024 - WorkArena: How Capable are Web Agents at Solving Common Knowledge Work Tasks? [Paper] [Code]
ICML 2024 - AndroidWorld: A Dynamic Benchmarking Environment for Autonomous Agents. [Paper] [Code]
ICLR 2025 - Windows Agent Arena: Evaluating Multi-Modal OS Agents at Scale. [Paper] [Code]
ICML 2025 - WorldGUI: An Interactive Benchmark for Desktop GUI Automation from Any Starting Point. [Paper] [Code]
arXiv 2025 - ScreenSpot-Pro: GUI Grounding for Professional High-Resolution Computer Use. [Paper] [Code]
ICLR 2025 Workshop - MMBench-GUI: Hierarchical Multi-Platform Evaluation Framework for GUI Agents. [Paper] [Code]
arXiv 2025 - Osworld-mcp: Benchmarking mcp tool invocation in computer-use agents. [Paper] [Code]
ICLR 2026 - VenusBench-GD: A Comprehensive Multi-Platform GUI Benchmark for Diverse Grounding Tasks. [Paper] [Code]
arXiv 2025
4.5. ML Engineering and Scientific Research
- DS-1000: A Natural and Reliable Benchmark for Data Science Code Generation. [Paper] [Code]
ICML 2023 - MLAgentBench: Evaluating Language Agents on Machine Learning Experimentation. [Paper] [Code]
ICML 2024 - DA-Code: Agent Data Science Code Generation Benchmark for Large Language Models. [Paper] [Code]
EMNLP 2024 - ScienceAgentBench: Toward Rigorous Assessment of Language Agents for Data-Driven Scientific Discovery. [Paper] [Code]
ICLR 2025 - MLE-bench: Evaluating Machine Learning Agents on Machine Learning Engineering. [Paper] [Code]
ICLR 2025 - PaperBench: Evaluating AI's Ability to Replicate AI Research. [Paper] [Code]
ICML 2025 - TimeSeriesGym: A Scalable Benchmark for (Time Series) Machine Learning Engineering Agents. [Paper] [Code]
NeurIPS 2025 Workshop - MLR-Bench: Evaluating AI Agents on Open-Ended Machine Learning Research. [Paper] [Code]
NeurIPS 2025 - FML-bench: Benchmarking Machine Learning Agents for Scientific Research. [Paper] [Code]
arXiv 2025 - ReplicatorBench: Benchmarking LLM Agents for Replicability in Social and Behavioral Sciences. [Paper] [Code]
MSLD 2026
5. Future Directions
5.1. Efficiency
- RouteLLM: Learning to Route LLMs from Preference Data. [Paper]
ICLR 2025 - Chain of Thoughtlessness? An Analysis of CoT in Planning. [Paper] [Code]
NeurIPS 2024 - ACON: Optimizing Context Compression for Long-horizon LLM Agents. [Paper] [Code]
arXiv 2025 - Reducing Cost of LLM Agents with Trajectory Reduction. [Paper]
arXiv 2025 - ARC: Active and Reflection-driven Context Management for Long-Horizon Information Seeking Agents. [Paper]
arXiv 2026 - Context as a Tool: Context Management for Long-Horizon SWE-Agents. [Paper]
arXiv 2025 - Robust and Efficient Tool Orchestration via Layered Execution Structures with Reflective Correction. [Paper]
arXiv 2026
5.2. Safety
- AgentDojo: A Dynamic Environment to Evaluate Prompt Injection Attacks and Defenses for LLM Agents. [Paper]
NeurIPS 2024 - MCPTox: A Benchmark for Tool Poisoning Attack on Real-World MCP Servers. [Paper]
arXiv 2025 - AgentSys: Secure and Dynamic LLM Agents Through Explicit Hierarchical Memory Management. [Paper]
arXiv 2026 - OpenPort Protocol: A Security Governance Specification for AI Agent Tool Access. [Paper]
arXiv 2026 - Runtime Governance for AI Agents: Policies on Paths. [Paper]
arXiv 2026 - AgentSpec: Customizable runtime enforcement for safe and reliable LLM agents.(2026). [Paper]
ICSE 2026 - Autonomous Action Runtime Management(AARM):A System Specification for Securing AI-Driven Actions at Runtime. [Paper]
arXiv 2026 - SafeHarness: Lifecycle-Integrated Security Architecture for LLM-based Agent Deployment. [Paper]
arXiv 2026
5.3. Continual Learning
- MemGPT: Towards LLMs as Operating Systems. [Paper] [Code]
arXiv 2023 - A-Mem: Agentic Memory for LLM Agents. [Paper] [Code]
NeurIPS 2025 - Memory as Action: Autonomous Context Curation for Long-Horizon Agentic Tasks. [Paper]
arXiv 2025 - Context Engineering: Memory, Compaction, and Tool Clearing. [Docs]
Docs 2026 - Agent Workflow Memory. [Paper] [Code]
ICML 2025
5.4. State and Environment Modeling
- WorldCoder, a Model-Based LLM Agent: Building World Models by Writing Code and Interacting with the Environment. [Paper]
NeurIPS 2024 - PABU: Progress-Aware Belief Update for Efficient LLM Agents. [Paper]
arXiv 2026 - Agent-World: Scaling Real-World Environment Synthesis for Evolving General Agent Intelligence. [Paper]
arXiv 2026
5.5. Embodied Harnesses
- PaLM-E: An Embodied Multimodal Language Model. [Paper]
ICML 2023 - RT-2: Vision-Language-Action Models Transfer Web Knowledge to Robotic Control. [Paper]
CoRL 2023 - Green-VLA: Staged Vision-Language-Action Model for Generalist Robots. [Paper]
arXiv 2026 - ACoT-VLA: Action Chain-of-Thought for Vision-Language-Action Models. [Paper]
arXiv 2026 - ST4VLA: Spatially Guided Training for Vision-Language-Action Models. [Paper]
arXiv 2026 - RoboAgent: Chaining Basic Capabilities for Embodied Task Planning. [Paper]
CVPR 2026 - EmbodiedBench: Comprehensive Benchmarking Multi-modal Large Language Models for Vision-Driven Embodied Agents. [Paper]
ICML 2025 - AgentSpec: Customizable Runtime Enforcement for Safe and Reliable LLM Agents. [Paper]
ICSE 2026
5.6. Evaluation
- BrowseComp-V^3: A Visual, Vertical, and Verifiable Benchmark for Multimodal Browsing Agents. [Paper]
arXiv 2026 - OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments. [Paper] [Code]
NeurIPS 2024 - PaperBench: Evaluating AI's Ability to Replicate AI Research. [Paper] [Code]
ICML 2025 - ReplicatorBench: Benchmarking LLM Agents for Replicability in Social and Behavioral Sciences. [Paper] [Code]
MSLD 2026 - BeyondSWE: Can Current Code Agent Survive Beyond Single-Repo Bug Fixing? [Paper]
arXiv 2026 - Gaia-2: A controllable multi-view generative world model for autonomous driving. [Paper]
arXiv 2025 - Claw-Eval-Live: A Live Agent Benchmark for Evolving Real-World Workflows. [Paper]
arXiv 2026 - ResearchRubrics: A Benchmark of Prompts and Rubrics For Evaluating Deep Research Agents. [Paper] [Code]
ICLR 2026 - Osworld-mcp: Benchmarking mcp tool invocation in computer-use agents. [Paper] [Code]
ICLR 2026 - AgentLongBench: A Controllable Long Benchmark For Long-Contexts Agents via Environment Rollouts. [Paper]
arXiv 2026 - ATBench: A Diverse and Realistic Agent Trajectory Benchmark for Safety Evaluation and Diagnosis. [Paper]
arXiv 2026 - AgentLeak: A Full-Stack Benchmark for Privacy Leakage in Multi-Agent LLM Systems. [Paper]
arXiv 2026 - Benchmark Test-Time Scaling of General LLM Agents. [Paper]
arXiv 2026
Citation
If you find our paper useful for your research, please consider citing the paper and starring this repository.
@misc{tang2026agent,
  title={Agent Systems with Harness Engineering},
  author={Xinyu Tang and Han Peng and Guoxin Chen and Yuze Shi and
          Zitao Su and Peiyu Liu and Wayne Xin Zhao and Yawen Li and
          Zhe Xue},
  url={https://openreview.net/pdf?id=nM5tDHrQsx},
  year={2026}
}