Benchmarks of approximate nearest neighbor libraries in Python
See the codeAt this point, ann-benchmarks is no longer actively maintained. Please consider submitting your work to different benchmarks, such as VIBE.
Doing fast searching of nearest neighbors in high dimensional spaces is an increasingly important problem with notably few empirical attempts at comparing approaches in an objective way, despite a clear need for such to drive optimization forward.
This project contains tools to benchmark various implementations of approximate nearest neighbor (ANN) search for selected metrics. We have pre-generated datasets (in HDF5 format) and prepared Docker containers for each algorithm, as well as a test suite to verify function integrity.


 : SWGraph, HNSW, BallTree, MPLSH


 : ONNG, PANNG, QG


 : HNSW


 : Vamana, Vamana-PQ


 : Knowhere


We have a number of precomputed data sets in HDF5 format. All data sets have been pre-split into train/test and include ground truth data for the top-100 nearest neighbors.
| Dataset | Dimensions | Train size | Test size | Neighbors | Distance | Download |
|---|---|---|---|---|---|---|
| DEEP1B | 96 | 9,990,000 | 10,000 | 100 | Angular | HDF5 (3.6GB) |
| Fashion-MNIST | 784 | 60,000 | 10,000 | 100 | Euclidean | HDF5 (217MB) |
| GIST | 960 | 1,000,000 | 1,000 | 100 | Euclidean | HDF5 (3.6GB) |
| GloVe | 25 | 1,183,514 | 10,000 | 100 | Angular | HDF5 (121MB) |
| GloVe | 50 | 1,183,514 | 10,000 | 100 | Angular | HDF5 (235MB) |
| GloVe | 100 | 1,183,514 | 10,000 | 100 | Angular | HDF5 (463MB) |
| GloVe | 200 | 1,183,514 | 10,000 | 100 | Angular | HDF5 (918MB) |
| Kosarak | 27,983 | 74,962 | 500 | 100 | Jaccard | HDF5 (33MB) |
| MNIST | 784 | 60,000 | 10,000 | 100 | Euclidean | HDF5 (217MB) |
| MovieLens-10M | 65,134 | 69,363 | 500 | 100 | Jaccard | HDF5 (63MB) |
| NYTimes | 256 | 290,000 | 10,000 | 100 | Angular | HDF5 (301MB) |
| SIFT | 128 | 1,000,000 | 10,000 | 100 | Euclidean | HDF5 (501MB) |
| Last.fm | 65 | 292,385 | 50,000 | 100 | Angular | HDF5 (135MB) |
| COCO-I2I | 512 | 113,287 | 10,000 | 100 | Angular | HDF5 (136MB) |
| COCO-T2I | 512 | 113,287 | 10,000 | 100 | Angular | HDF5 (136MB) |
These are all as of April 2025, running all benchmarks on a r6i.16xlarge machine on AWS with --parallelism 31 and hyperthreading disabled. All benchmarks are single-CPU.


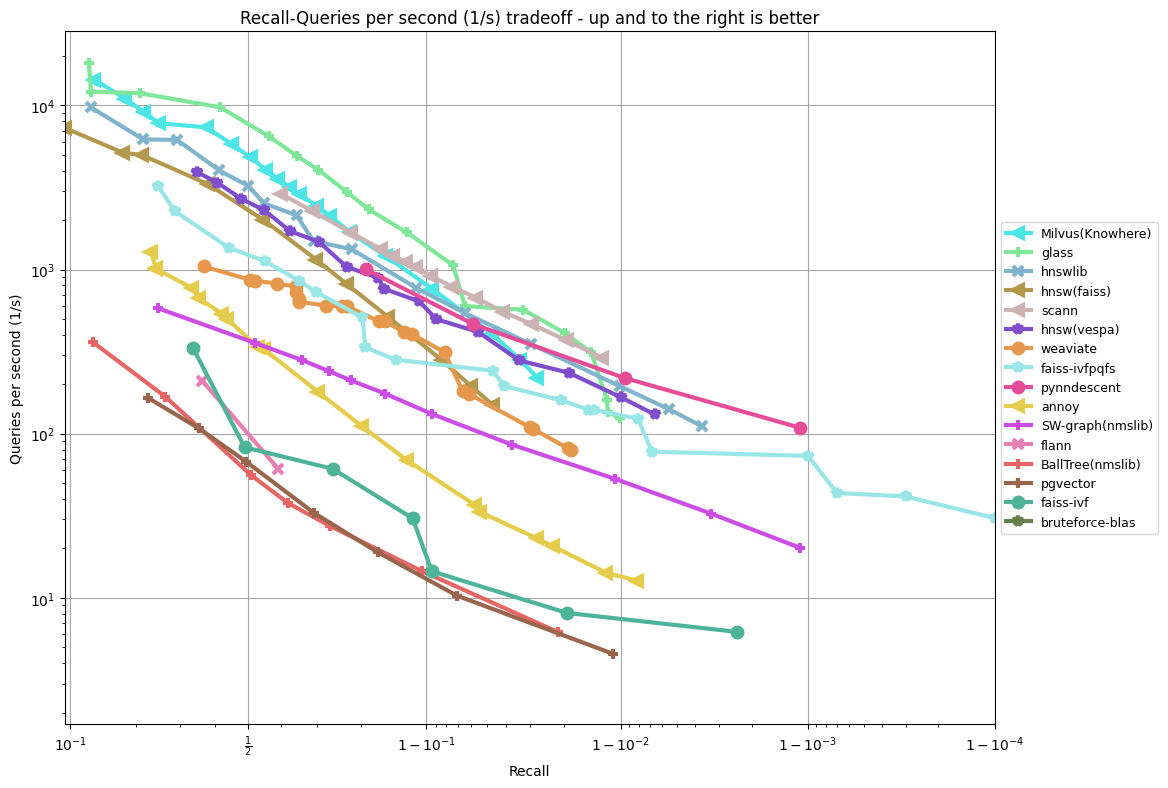

TODO: update plots on http://ann-benchmarks.com.
The only prerequisite is Python (tested with 3.10.6) and Docker.
pip install -r requirements.txt.python install.py to build all the libraries inside Docker containers (this can take a while, like 10-30 minutes).python run.py (this can take an extremely long time, potentially days).python plot.py --x-scale logit --y-scale log to plot results.python create_website.py to create a website with lots of plots.You can customize the algorithms and datasets as follows:
ann_benchmarks/algorithms/{YOUR_IMPLEMENTATION}/config.yml contains the parameter settings that you want to testpython run.py --dataset glove-100-angular. See python run.py --help for more information on possible settings. Note that experiments can take a long time.python plot.py --dataset glove-100-angular or python create_website.py. An example call: python create_website.py --plottype recall/time --latex --scatter --outputdir website/.Add your algorithm in the folder ann_benchmarks/algorithms/{YOUR_IMPLEMENTATION}/ by providing
module.pyDockerfileconfig.yml.github/workflows/benchmarks.ymlCheck the available implementations for inspiration.
--batch to run.py and plot.py to enable batch mode.--local --batch.Built by Erik Bernhardsson with significant contributions from Martin Aumüller and Alexander Faithfull.
Design principles behind the benchmarking framework are described in the following publications:
(top 24 of 73)
13,894 followers · starred Apr 2023
1,004 followers · starred Apr 2025
288 followers · starred Nov 2024
7,962 followers · starred Mar 2021
Benchmarks of approximate nearest neighbor libraries in Python
See the codeAt this point, ann-benchmarks is no longer actively maintained. Please consider submitting your work to different benchmarks, such as VIBE.
Doing fast searching of nearest neighbors in high dimensional spaces is an increasingly important problem with notably few empirical attempts at comparing approaches in an objective way, despite a clear need for such to drive optimization forward.
This project contains tools to benchmark various implementations of approximate nearest neighbor (ANN) search for selected metrics. We have pre-generated datasets (in HDF5 format) and prepared Docker containers for each algorithm, as well as a test suite to verify function integrity.
: SWGraph, HNSW, BallTree, MPLSH: ONNG, PANNG, QG: HNSW: Vamana, Vamana-PQ: Knowhere
We have a number of precomputed data sets in HDF5 format. All data sets have been pre-split into train/test and include ground truth data for the top-100 nearest neighbors.
| Dataset | Dimensions | Train size | Test size | Neighbors | Distance | Download |
|---|---|---|---|---|---|---|
| DEEP1B | 96 | 9,990,000 | 10,000 | 100 | Angular | HDF5 (3.6GB) |
| Fashion-MNIST | 784 | 60,000 | 10,000 | 100 | Euclidean | HDF5 (217MB) |
| GIST | 960 | 1,000,000 | 1,000 | 100 | Euclidean | HDF5 (3.6GB) |
| GloVe | 25 | 1,183,514 | 10,000 | 100 | Angular | HDF5 (121MB) |
| GloVe | 50 | 1,183,514 | 10,000 | 100 | Angular | HDF5 (235MB) |
| GloVe | 100 | 1,183,514 | 10,000 | 100 | Angular | HDF5 (463MB) |
| GloVe | 200 | 1,183,514 | 10,000 | 100 | Angular | HDF5 (918MB) |
| Kosarak | 27,983 | 74,962 | 500 | 100 | Jaccard | HDF5 (33MB) |
| MNIST | 784 | 60,000 | 10,000 | 100 | Euclidean | HDF5 (217MB) |
| MovieLens-10M | 65,134 | 69,363 | 500 | 100 | Jaccard | HDF5 (63MB) |
| NYTimes | 256 | 290,000 | 10,000 | 100 | Angular | HDF5 (301MB) |
| SIFT | 128 | 1,000,000 | 10,000 | 100 | Euclidean | HDF5 (501MB) |
| Last.fm | 65 | 292,385 | 50,000 | 100 | Angular | HDF5 (135MB) |
| COCO-I2I | 512 | 113,287 | 10,000 | 100 | Angular | HDF5 (136MB) |
| COCO-T2I | 512 | 113,287 | 10,000 | 100 | Angular | HDF5 (136MB) |
These are all as of April 2025, running all benchmarks on a r6i.16xlarge machine on AWS with --parallelism 31 and hyperthreading disabled. All benchmarks are single-CPU.
TODO: update plots on http://ann-benchmarks.com.
The only prerequisite is Python (tested with 3.10.6) and Docker.
pip install -r requirements.txt.python install.py to build all the libraries inside Docker containers (this can take a while, like 10-30 minutes).python run.py (this can take an extremely long time, potentially days).python plot.py --x-scale logit --y-scale log to plot results.python create_website.py to create a website with lots of plots.You can customize the algorithms and datasets as follows:
ann_benchmarks/algorithms/{YOUR_IMPLEMENTATION}/config.yml contains the parameter settings that you want to testpython run.py --dataset glove-100-angular. See python run.py --help for more information on possible settings. Note that experiments can take a long time.python plot.py --dataset glove-100-angular or python create_website.py. An example call: python create_website.py --plottype recall/time --latex --scatter --outputdir website/.Add your algorithm in the folder ann_benchmarks/algorithms/{YOUR_IMPLEMENTATION}/ by providing
module.pyDockerfileconfig.yml.github/workflows/benchmarks.ymlCheck the available implementations for inspiration.
--batch to run.py and plot.py to enable batch mode.--local --batch.Built by Erik Bernhardsson with significant contributions from Martin Aumüller and Alexander Faithfull.
Design principles behind the benchmarking framework are described in the following publications:
(top 24 of 73)
13,894 followers · starred Apr 2023
1,004 followers · starred Apr 2025
288 followers · starred Nov 2024
7,962 followers · starred Mar 2021



