
The official repo of the Comics Survey: "A missing piece in Vision and Language: A Survey on Comics Understanding"
See the codeREADME
Awesome Comics Understanding 
This repository contains a curated list of research papers and resources focusing on Comics Understanding.

🔥 One missing piece in Vision and Language: A Survey on Comics Understanding 🔥
Authors: Emanuele Vivoli, Andrey Barsky, Mohamed Ali Souibgui, Artemis Llabrés, Marco Bertini, Dimosthenis Karatzas
📣 Latest News 📣
- 🚧 This repo is a work in progress, please contribute here
14 September 2024Our survey paper have dropped in arXiv !!
📚 Table of Contents
Overview of Vision-Language Tasks of the Layers of Comics Understanding. The ranking is based on input and output modalities and dimensions, as illustrated in the paper.
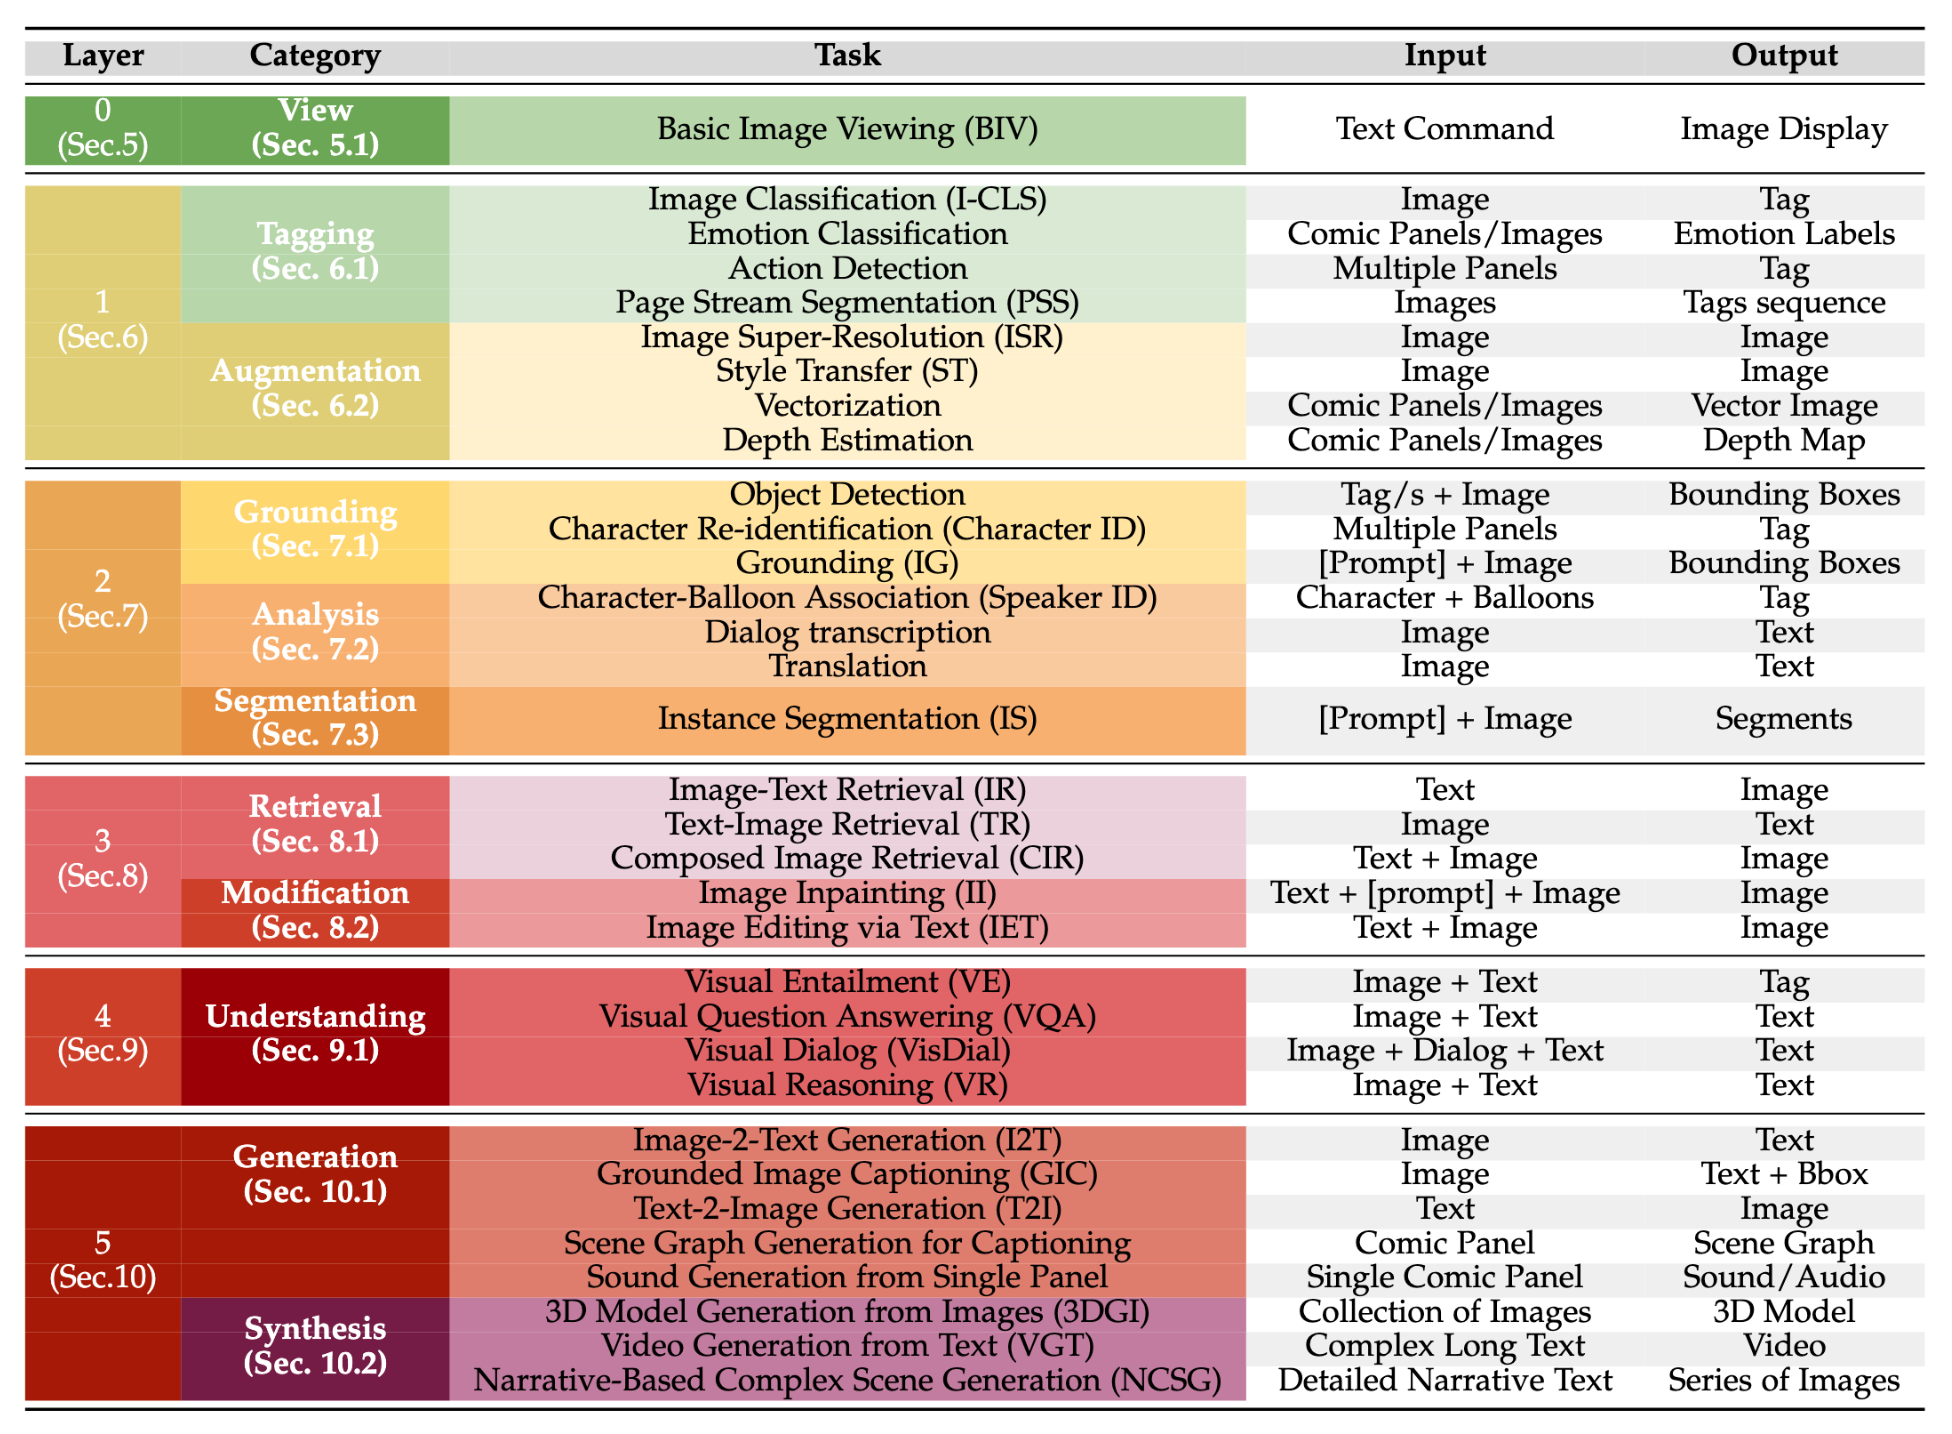
Layers of Comics Understanding
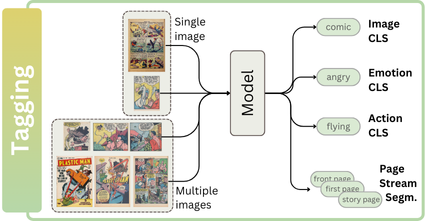
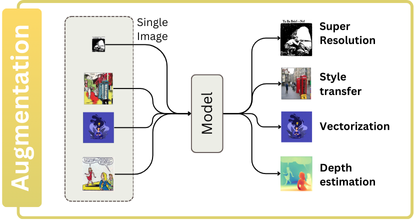
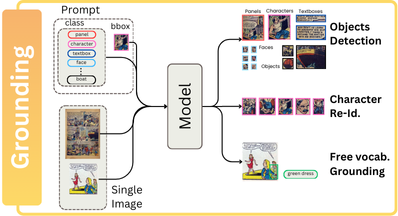
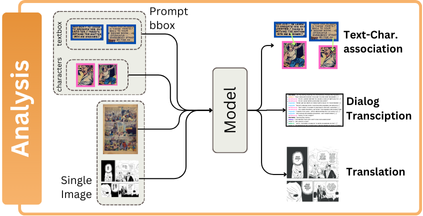
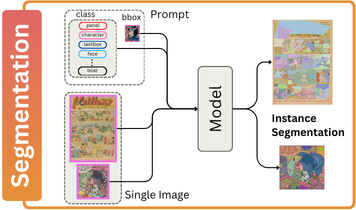
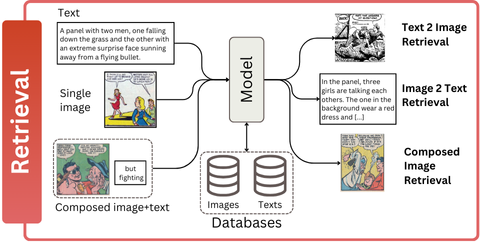
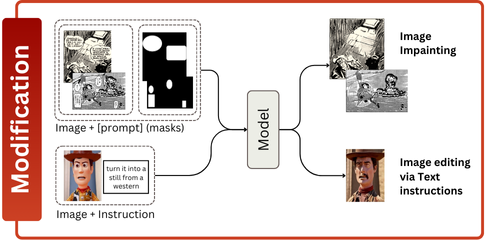
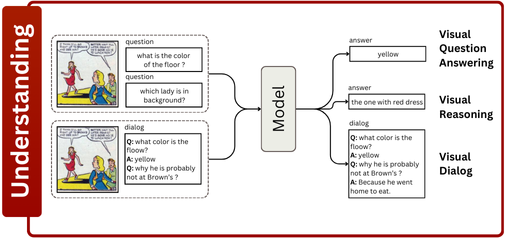
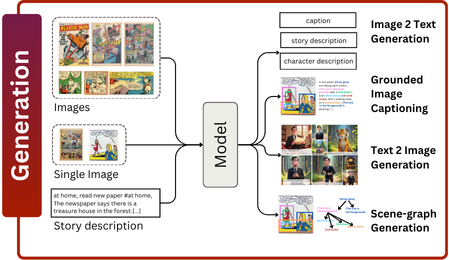
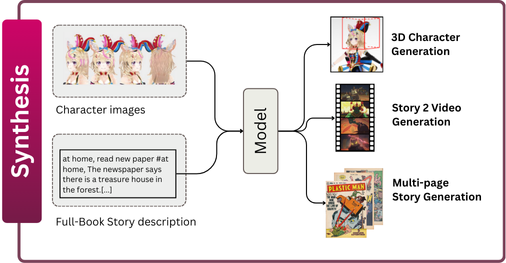
Every survey worthy of the name includes illustrative visuals to enhance understanding. We've followed this approach by providing examples for each task in the Layer of Comics Understanding.
Go check every Layer's tasks image ⬇️.
Layer 1: Tagging and Augmentation
-
Tagging
-
Image classification
Year Conference / Journal Title Authors Links 2023 TIP Panel-Page-Aware Comic Genre Understanding Xu, Chenshu et al. 📜 Paper 2019 ICDAR Workshop Analysis Based on Distributed Representations of Various Parts Images in Four-Scene Comics Story Dataset Terauchi, Akira et al. 📜 Paper 2018 TPAMI Learning Consensus Representation for Weak Style Classification Jiang, Shuhui et al. 📜 Paper 2018 ICDAR Comic Story Analysis Based on Genre Classification Daiku, Yuki et al. 📜 Paper 2017 ICDAR Histogram of Exclamation Marks and Its Application for Comics Analysis Hiroe, Sotaro et al. 📜 Paper 2014 ACM Multimedia Line-Based Drawing Style Description for Manga Classification Chu, Wei-Ta et al. 📜 Paper
-
Emotion classification
Year Conference / Journal Title Authors Links 2023 MMM Manga Text Detection with Manga-Specific Data Augmentation and Its Applications on Emotion Analysis Yang, Yi-Ting et al. 📜 Paper 2021 ICDAR Competition on Multimodal Emotion Recognition on Comics Scenes Nguyen, Nhu-Van et al. 📜 Paper, 👨💻 Code 2016 MANPU (ICPR) Manga Content Analysis Using Physiological Signals Sanches, Charles Lima et al. 📜 Paper 2015 IIAI-AAI Relation Analysis between Speech Balloon Shapes and Their Serif Descriptions in Comic Tanaka, Hideki et al. 📜 Paper
-
Action Detection
Year Conference / Journal Title Authors Links 2024 Arxiv MangaUB: A Manga Understanding Benchmark for Large Multimodal Models Ikuta, Hikaru et al. 📜 Paper 2024 MANPU (ICDAR) ComicBERT: A Transformer Model and Pre-training Strategy for Contextual Understanding in Comics Soykan, Gurkan et al. 📜 Paper, 👨💻 Code 2024 ICDAR Multimodal Transformer for Comics Text-Cloze Vivoli, Emanuele et al. 📜 Paper 2020 Arxiv A Comprehensive Study of Deep Video Action Recognition Zhu, Yi et al. 📜 Paper, 👨💻 Code 2017 CVPR The Amazing Mysteries of the Gutter: Drawing Inferences Between Panels in Comic Book Narratives Iyyer, Mohit et al. 📜 Paper
-
Page Stream Segmentation
Year Conference / Journal Title Authors Links 2022 ICPR Semantic Parsing of Interpage Relations Demirtaş, Mehmet Arif et al. 📜 Paper 2018 LREC Page Stream Segmentation with Convolutional Neural Nets Combining Textual and Visual Features Wiedemann, Gregor et al. 📜 Paper 2013 ICDAR Document Classification and Page Stream Segmentation for Digital Mailroom Applications Gordo, Albert et al. 📜 Paper
-
-
Augmentation ( Image-2-Image )
-
Image Super-Resolution
Year Conference / Journal Title Authors Links 2023 MTA Automatic Dewarping of Camera-Captured Comic Document Images Garai, Arpan et al. 📜 Paper
-
Style Transfer
Year Conference / Journal Title Authors Links 2023 Arxiv Inkn'hue: Enhancing Manga Colorization from Multiple Priors with Alignment Multi-Encoder VAE Jiramahapokee, Tawin 📜 Paper, 👨💻 Code 2023 IEEE Access Robust Manga Page Colorization via Coloring Latent Space Golyadkin, Maksim et al. 📜 Paper 2023 TVCG Shading-Guided Manga Screening from Reference Wu, Huisi et al. 📜 Paper 2022 Arxiv DASS-Detector: Domain-Adaptive Self-Supervised Pre-Training for Face & Body Detection in Drawings Topal, Barış Batuhan et al. 📜 Paper, 👨💻 Code 2021 CVPR Generating Manga from Illustrations via Mimicking Manga Creation Workflow Zhang, LM et al.* 📜 Paper, 👨💻 Code 2021 CVPR Unbiased Mean Teacher for Cross-domain Object Detection Deng, Jinhong et al. 📜 Paper, 👨💻 Code 2021 CVPR Encoding in Style: A StyleGAN Encoder for Image-to-Image Translation Richardson, Elad et al. 📜 Paper, 👨💻 Code 2021 AAAI MangaGAN: Unpaired Photo-to-Manga Translation Based on The Methodology of Manga Drawing Su, Hao et al. 📜 Paper 2019 ISM Synthesis of Screentone Patterns of Manga Characters Tsubota, K. et al. 📜 Paper, 👨💻 Code 2018 SciVis Color Interpolation for Non-Euclidean Color Spaces Zeyen, Max et al. 📜 Paper 2017 ACM-SIGGRAPH Asia Comicolorization: Semi-automatic Manga Colorization Furusawa, Chie et al. 📜 Paper, 👨💻 Code 2017 ICDAR CGAN-Based Manga Colorization Using a Single Training Image Hensman, Paulina et al. 📜 Paper, 👨💻 Code 2017 CVPR Image-to-Image Translation with Conditional Adversarial Networks Isola, Phillip et al. 📜 Paper 2017 ACM-TG Deep Extraction of Manga Structural Lines Li, Chengze et al. 📜 Paper, 👨💻 Code
-
Vectorization
Year Conference / Journal Title Authors Links 2023 TCSVT MARVEL: Raster Gray-level Manga Vectorization via Primitive-wise Deep Reinforcement Learning H. Su et al. 📜 Paper, 👨💻 Code 2022 CVPR Towards Layer-wise Image Vectorization Ma, Xu et al. 📜 Paper, 👨💻 Code 2017 ACM-TG Deep Extraction of Manga Structural Lines Li, Chengze et al. 📜 Paper, 👨💻 Code 2017 TVCG Manga Vectorization and Manipulation with Procedural Simple Screentone Yao, Chih-Yuan et al. 📜 Paper 2011 ACM-SIGGRAPH Depixelizing Pixel Art Kopf, Johannes et al. 📜 Paper 2003 N/A Potrace : A Polygon-Based Tracing Algorithm Selinger, Peter 📜 Paper, 👨💻 Code
-
Depth Estimation
Year Conference / Journal Title Authors Links 2023 CVPR Workshop Dense Multitask Learning to Reconfigure Comics Bhattacharjee, Deblina et al. 📜 Paper 2022 WACV Estimating Image Depth in the Comics Domain Bhattacharjee, Deblina et al. 📜 Paper, 👨💻 Code 2022 CVPR MulT: An End-to-End Multitask Learning Transformer Bhattacharjee, Deblina et al. 📜 Paper, 👨💻 Code
-
Layer 2: Grounding, Analysis and Segmentation
-
Grounding
-
Object detection
Year Conference / Journal Title Authors Links 2024 MANPU (ICDAR) Comics Datasets Framework: Mix of Comics datasets for detection benchmarking Vivoli, Emanuele et al. 📜 Paper 2024 MANPU (ICDAR) A Comprehensive Gold Standard and Benchmark for Comics Text Detection and Recognition Gurkan Soykan et al. 📜 Paper, 👨💻 Code 2023 MMM Manga Text Detection with Manga-Specific Data Augmentation and Its Applications on Emotion Analysis Yang, \relax YT et al. 📜 Paper 2023 CSNT CPD: Faster RCNN-based DragonBall Comic Panel Detection Sharma, Rishabh et al. 📜 Paper 2022 IJDAR BCBId: First Bangla Comic Dataset and Its Applications Dutta, Arpita et al. 📜 Paper 2022 ECCV COO/ Comic Onomatopoeia Dataset for Recognizing Arbitrary or Truncated Texts Baek, Jeonghun et al. 📜 Paper, 👨💻 Code 2019 ICDAR Workshop What Do We Expect from Comic Panel Extraction? Nguyen Nhu, Van et al. 📜 Paper 2019 ICDAR Workshop CNN Based Extraction of Panels/Characters from Bengali Comic Book Page Images Dutta, Arpita et al. 📜 Paper 2018 VCIP Text Detection in Manga by Deep Region Proposal, Classification, and Regression Chu, Wei-Ta et al. 📜 Paper 2018 IWAIT A Study on Object Detection Method from Manga Images Using CNN Yanagisawa, Hideaki et al. 📜 Paper 2018 IWAIT A Study on Object Detection Method from Manga Images Using CNN Yanagisawa, Hideaki et al. 📜 Paper 2017 ICDAR A Faster R-CNN Based Method for Comic Characters Face Detection Qin, Xiaoran et al. 📜 Paper 2016 IJCG Text-Aware Balloon Extraction from Manga Liu, Xueting et al. 📜 Paper 2016 IJCNN Line-Wise Text Identification in Comic Books: A Support Vector Machine-Based Approach Pal, Srikanta et al. 📜 Paper 2016 ICIP Text Detection in Manga by Combining Connected-Component-Based and Region-Based Classifications Aramaki, Yuji et al. 📜 Paper 2015 ICIAP Panel Tracking for the Extraction and the Classification of Speech Balloons Jomaa, Hadi S. et al. 📜 Paper 2012 DAS Panel and Speech Balloon Extraction from Comic Books Ho, Anh Khoi Ngo et al. 📜 Paper 2011 IJI Method for Real Time Text Extraction of Digital Manga Comic Arai, Kohei et al. 📜 Paper 2011 ICDAR Recognizing Text Elements for SVG Comic Compression and Its Novel Applications Su, Chung-Yuan et al. 📜 Paper 2010 ICIT Method for Automatic E-Comic Scene Frame Extraction for Reading Comic on Mobile Devices Arai, Kohei et al. 📜 Paper 2009 IJHCI Enhancing the Accessibility for All of Digital Comic Books Ponsard, Christophe 📜 Paper
-
Character Re-Identification
Year Conference / Journal Title Authors Links 2024 Arxiv Tails Tell Tales: Chapter-Wide Manga Transcriptions with Character Names Ragav Sachdeva et al. 📜 Paper, 👨💻 Code 2024 NeurIPS CoMix: A Comprehensive Benchmark for Multi-Task Comic Understanding Emanuele Vivoli et al. 📜 Paper, 👨💻 Code 2024 CVPR The Manga Whisperer: Automatically Generating Transcriptions for Comics Sachdeva, Ragav et al. 📜 Paper, 👨💻 Code 2023 IET Image Processing Toward Cross-Domain Object Detection in Artwork Images Using Improved YoloV5 and XGBoosting Ahmad, Tasweer et al. 📜 Paper 2023 Arxiv Identity-Aware Semi-Supervised Learning for Comic Character Re-Identification Soykan, Gürkan et al. 📜 Paper 2023 ACM-MM Asia Occlusion-Aware Manga Character Re-Identification with Self-Paced Contrastive Learning Zhang, Ci-Yin et al. 📜 Paper 2022 Arxiv Unsupervised Manga Character Re-Identification via Face-Body and Spatial-Temporal Associated Clustering Zhang, Z et al. 📜 Paper 2022 ICIR CAST: Character Labeling in Animation Using Self‐supervision by Tracking Nir, Oron et al. 📜 Paper 2020 ICPR Dual Loss for Manga Character Recognition with Imbalanced Training Data Li, Yonggang et al. 📜 Paper 2020 ICML A Simple Framework for Contrastive Learning of Visual Representations Chen, Ting et al. 📜 Paper 2015 ACPR Similarity Learning Based on Pool-Based Active Learning for Manga Character Retrieval Iwata, Motoi et al. 📜 Paper 2014 DAS A Study to Achieve Manga Character Retrieval Method for Manga Images Iwata, M. et al. 📜 Paper 2012 CVPR Color Attributes for Object Detection Khan, Fahad Shahbaz et al. 📜 Paper 2012 ECCV PHOG Analysis of Self-Similarity in Aesthetic Images Redies, Christoph et al. 📜 Paper 2011 ICDAR Similar Manga Retrieval Using Visual Vocabulary Based on Regions of Interest Sun, Weihan et al. 📜 Paper
-
Sentence-based Grounding
Year Conference / Journal Title Authors Links 2024 AAAI GroundVLP: Harnessing Zero-shot Visual Grounding from Vision-Language Pre-training and Open-Vocabulary Object Detection Shen, Haozhan et al. 📜 Paper, 👨💻 Code 2024 ECCV Grounding DINO: Marrying DINO with Grounded Pre-Training for Open-Set Object Detection Liu, Shilong et al. 📜 Paper, 👨💻 Code 2020 CVPR Workshop Exploring Phrase Grounding without Training: Contextualisation and Extension to Text-Based Image Retrieval Parcalabescu, Letitia et al. 📜 Paper 2019 AAAI Zero-Shot Object Detection with Textual Descriptions Li, Zhihui et al. 📜 Paper
-
-
Analysis
-
Text-Character association
Year Conference / Journal Title Authors Links 2024 Arxiv Tails Tell Tales: Chapter-Wide Manga Transcriptions with Character Names Ragav Sachdeva et al. 📜 Paper, 👨💻 Code 2024 NeurIPS CoMix: A Comprehensive Benchmark for Multi-Task Comic Understanding Emanuele Vivoli et al. 📜 Paper, 👨💻 Code 2024 MANPU (ICDAR) Spatially Augmented Speech Bubble to Character Association via Comic Multi-task Learning Soykan, Gurkan et al. 📜 Paper 💻 Code 2024 CVPR The Manga Whisperer: Automatically Generating Transcriptions for Comics Sachdeva, Ragav et al. 📜 Paper, 👨💻 Code 2023 arXiv Manga109Dialog A Large-scale Dialogue Dataset for Comics Speaker Detection Li, Yingxuan et al. 📜 Paper 2022 IIAI-AAI Algorithms for Estimation of Comic Speakers Considering Reading Order of Frames and Texts Omori, Yuga et al. 📜 Paper 2019 IJDAR Comic MTL: Optimized Multi-Task Learning for Comic Book Image Analysis Nguyen, Nhu-Van et al. 📜 Paper 2015 ICDAR Speech Balloon and Speaker Association for Comics and Manga Understanding Rigaud, Christophe et al. 📜 Paper
-
Panel Sorting
Year Conference / Journal Title Authors Links 2017 ICDAR Story Pattern Analysis Based on Scene Order Information in Four-Scene Comics Ueno, Miki et al. 📜 Paper
-
Dialog transcription
Year Conference / Journal Title Authors Links 2024 Arxiv Tails Tell Tales: Chapter-Wide Manga Transcriptions with Character Names Ragav Sachdeva et al. 📜 Paper, 👨💻 Code 2024 NeurIPS CoMix: A Comprehensive Benchmark for Multi-Task Comic Understanding Emanuele Vivoli et al. 📜 Paper, 👨💻 Code 2024 CVPR The Manga Whisperer: Automatically Generating Transcriptions for Comics Sachdeva, Ragav et al. 📜 Paper, 👨💻 Code 2023 arXiv Manga109Dialog A Large-scale Dialogue Dataset for Comics Speaker Detection Li, Yingxuan et al. 📜 Paper
-
Translation
Year Conference / Journal Title Authors Links 2024 ArXiv Context-Informed Machine Translation of Manga using Multimodal Large Language Models Lippmann, Philip et al. 📜 Paper, 👨💻 Code 2024 ArXiv Large Language Models as Manga Translators: A Case Study Zhishen Yang et al. paper 2024 ArXiv Generating Visual Stories with Grounded and Coreferent Characters Danyang Liu et al. paper 2024 ICKECS The Future of Graphic Novel Translation: Fully Automated Systems Sandeep Singh et al. paper 2024 ACM Multimedia Zero-Shot Character Identification and Speaker Prediction in Comics via Iterative Multimodal Fusion Yingxuan Li et al. paper 2023 ArXiv Multi-Teacher Knowledge Distillation For Text Image Machine Translation Cong Ma et al. paper 2020 ArXiv Towards Fully Automated Manga Translation Ryota Hinami et al. paper 2014 inTRAlinea Visual adaptation in translated comics Federico, Zanettin paper
-
-
Segmentation
-
Instance Segmentation
Year Conference / Journal Title Authors Links 2024 AI4VA (ECCV) Unlocking Comics: The AI4VA Dataset for Visual Understanding Grönquist, Peter et al. 📜 Paper,👨💻 Code 2024 ICDAR Investigating Neural Networks and Transformer Models for Enhanced Comic Decoding Kouletou, Eleanna et al. 📜 Paper 2022 DataverseNL The Visual Language Research Corpus (VLRC) Project Cohn, Neil 📜 Paper
-
Layer 3: Retrieval and Modification
-
Retrieval
-
Image-Text Retrieval
Year Conference / Journal Title Authors Links 2014 DAS A Study to Achieve Manga Character Retrieval Method for Manga Images Iwata, M. et al. 📜 Paper 2011 ICDAR Similar Manga Retrieval Using Visual Vocabulary Based on Regions of Interest Sun, Weihan et al. 📜 Paper 2011 CAVW Comic Character Animation Using Bayesian Estimation Chou, Yun-Feng et al. 📜 Paper 2010 ICGC Searching Digital Political Cartoons Wu, Yejun 📜 Paper
-
Text-Image Retrieval
Year Conference / Journal Title Authors Links 2014 ICIP Sketch2Manga: Sketch-based Manga Retrieval Matsui, Yusuke et al. 📜 Paper
-
Composed Image Retrieval
Year Conference / Journal Title Authors Links 2023 Arxiv MaRU: A Manga Retrieval and Understanding System Connecting Vision and Language Shen, Conghao Tom et al. 📜 Paper 2022 DICTA ComicLib: A New Large-Scale Comic Dataset for Sketch Understanding Wei, Xin et al. 📜 Paper 2021 ICDAR Manga-MMTL: Multimodal Multitask Transfer Learning for Manga Character Analysis Nguyen, Nhu-Van et al. 📜 Paper 2017 ICDAR Sketch-Based Manga Retrieval Using Deep Features Narita, Rei et al. 📜 Paper 2017 Arxiv A Neural Representation of Sketch Drawings Ha, David et al. 📜 Paper 2017 Arxiv Style Transfer for Anime Sketches with Enhanced Residual U-net and Auxiliary Classifier GAN Zhang, Lvmin et al. 📜 Paper 2015 MM-TA Sketch-Based Manga Retrieval Using Manga109 Dataset Matsui, Yusuke et al. 📜 Paper
-
Personalized Image Retrieval
Year Conference / Journal Title Authors Links 2022 BMVC Personalised CLIP or: How to Find Your Vacation Videos Korbar, Bruno et al. 📜 Paper
-
-
Modification
Layer 4: Understanding
-
Understanding
-
Visual Entailment
Year Conference / Journal Title Authors Links
-
Visual-Question Answer
Year Conference / Journal Title Authors Links 2022 WACV Challenges in Procedural Multimodal Machine Comprehension: A Novel Way To Benchmark Sahu, Pritish et al. 📜 Paper 2021 Arxiv Towards Solving Multimodal Comprehension Sahu, Pritish et al. 📜 Paper 2020 MDPI-AS A Survey on Machine Reading Comprehension—Tasks, Evaluation Metrics and Benchmark Datasets Zeng, Changchang et al. 📜 Paper 2017 IIWAS ComicQA: Contextual Navigation Aid by Hyper-Comic Representation Sumi, Yasuyuki et al. 📜 Paper 2016 MANPU (ICPR) Designing a Question-Answering System for Comic Contents Moriyama, Yukihiro et al. 📜 Paper
-
Visual-Dialog
Year Conference / Journal Title Authors Links
-
Visual Reasoning
Year Conference / Journal Title Authors Links
-
Layer 5: Generation and Synthesis
-
Generation
-
Comics generation from other media
Year Conference / Journal Title Authors Links 2023 SIGCSE Developing Comic-based Learning Toolkits for Teaching Computing to Elementary School Learners Castro, Francico et al. 📜 Paper 2022 THMS Augmenting Conversations With Comic-Style Word Balloons Zhang, H. et al. 📜 Paper 2022 LACLO Comics as a Pedagogical Tool for Teaching Lima, Antonio Alexandre et al. 📜 Paper 2021 TVCG ChartStory: Automated Partitioning, Layout, and Captioning of Charts into Comic-Style Narratives Zhao, Jian et al. 📜 Paper 2021 SIGCSE Using Comics to Introduce and Reinforce Programming Concepts in CS1 Suh, Sangho et al. 📜 Paper 2021 MM-CCA Automatic Comic Generation with Stylistic Multi-page Layouts and Emotion-driven Text Balloon Generation Yang, Xin et al. 📜 Paper 2018 ACM Comixify: Transform Video into a Comics Pesko, Maciej et al. 📜 Paper 2015 TOMM Content-Aware Video2Comics With Manga-Style Layout Jing, Guangmei et al. 📜 Paper 2012 TOMM Movie2Comics: Towards a Lively Video Content Presentation Wang, Meng et al. 📜 Paper 2012 ACM-TG Automatic Stylistic Manga Layout Cao, Ying et al. 📜 Paper 2012 TOMM Scalable Comic-like Video Summaries and Layout Disturbance Herranz, Luis et al. 📜 Paper 2011 ACM-MM Automatic Preview Generation of Comic Episodes for Digitized Comic Search Hoashi, Keiichiro et al. 📜 Paper 2011 ISPACS Automatic Comic Strip Generation Using Extracted Keyframes from Cartoon Animation Tanapichet, Pakpoom et al. 📜 Paper 2011 ICMLC Caricaturation for Human Face Pictures Chang, I-Cheng et al. 📜 Paper 2010 SICE Comic Live Chat Communication Tool Based on Concept of Downgrading Matsuda, Misaki et al. 📜 Paper 2010 CAIDCD Research and Development of the Generation in Japanese Manga Based on Frontal Face Image Xuexiong, Deng et al. 📜 Paper
-
Comics to Scene graph
Year Conference / Journal Title Authors Links
-
Image-2-Text Generation
Year Conference / Journal Title Authors Links 2024 NeurIPS Cracking the Code of Juxtaposition: Can AI Models Understand the Humorous Contradictions Hu, Zhe et al. 📜 Paper 2024 AI4VA (ECCV) ComiCap: A VLMs pipeline for dense captioning of Comic Panels Vivoli, Emanuele et al. 📜 Paper 2024 ICDAR Multimodal Transformer for Comics Text-Cloze Vivoli, Emanuele et al. 📜 Paper 2024 MANPU (ICDAR) Toward Accessible Comics for Blind and Low Vision Readers Rigaud, Christophe et al. 📜 Paper 2024 CVPR The Manga Whisperer: Automatically Generating Transcriptions for Comics Sachdeva, Ragav et al. 📜 Paper, 👨💻 Code 2023 Arxiv Comics for Everyone: Generating Accessible Text Descriptions for Comic Strips Ramaprasad, Reshma et al. 📜 Paper 2023 ACL Multimodal Persona Based Generation of Comic Dialogs Agrawal, Harsh et al. 📜 Paper 2023 Arxiv M2C: Towards Automatic Multimodal Manga Complement Guo, Hongcheng et al. 📜 Paper
-
Text-2-Image Generation
Year Conference / Journal Title Authors Links 2023 ICCV Diffusion in Style Everaert, Martin Nicolas et al. 📜 Paper, 👨💻 Code 2023 MDPI-AS A Study on Generating Webtoons Using Multilingual Text-to-Image Models Yu, Kyungho et al. 📜 Paper 2023 Arxiv Generating Coherent Comic with Rich Story Using ChatGPT and Stable Diffusion Jin, Ze et al. 📜 Paper 2022 ISM Conditional GAN for Small Datasets Hiruta, Komei et al. 📜 Paper 2021 NAACL Improving Generation and Evaluation of Visual Stories via Semantic Consistency Maharana, Adyasha et al. 📜 Paper, 👨💻 Code 2021 CoRR Integrating Visuospatial, Linguistic and Commonsense Structure intoStory Visualization Maharana, Adyasha et al. 📜 Paper, 👨💻 Code 2021 ICCC A Deep Learning Pipeline for the Synthesis of Graphic Novels Melistas, Thomas et al. 📜 Paper 2021 Arxiv ComicGAN: Text-to-Comic Generative Adversarial Network Proven-Bessel, Ben et al. 📜 Paper, 👨💻 Code 2019 CVPR StoryGAN: A Sequential Conditional GAN for Story Visualization Li, Yitong et al. 📜 Paper, 👨💻 Code 2018 CVPR Cross-Domain Weakly-Supervised Object Detection through Progressive Domain Adaptation Inoue, Naoto et al. 📜 Paper, 👨💻 Code 2017 Arxiv Towards the Automatic Anime Characters Creation with Generative Adversarial Networks Jin, Yanghua et al. 📜 Paper, 👨💻 Code
-
Scene-graph Generation for captioning
Year Conference / Journal Title Authors Links
-
-
Synthesis
-
3D Generation from Images
Year Conference / Journal Title Authors Links 2023 ECCV AnimeCeleb: Large-Scale Animation CelebHeads Dataset for Head Reenactment Kim, Kangyeol et al. 📜 Paper, 👨💻 Code 2023 IJCAI Collaborative Neural Rendering Using Anime Character Sheets Lin, Zuzeng et al. 📜 Paper, 👨💻 Code 2023 CVPR PAniC-3D: Stylized Single-view 3D Reconstruction from Portraits of Anime Characters Chen, Shuhong et al. 📜 Paper 2023 Arxiv Sketch-A-Shape: Zero-Shot Sketch-to-3D Shape Generation Sanghi, Aditya et al. 📜 Paper 2021 N/A Talking Head Anime from a Single Image 2: More Expressive Khungurn, Pramook et al. 👨💻 Code 2020 ICLR U-GAT-IT: Unsupervised Generative Attentional Networks with Adaptive Layer-Instance Normalization for Image-to-Image Translation Kim, Junho et al. 📜 Paper, 👨💻 Code 2017 3DV 3D Shape Reconstruction from Sketches via Multi-view Convolutional Networks Lun, Zhaoliang et al. 📜 Paper
-
Video generation
Year Conference / Journal Title Authors Links 2023 Arxiv DreamVideo: High-Fidelity Image-to-Video Generation with Image Retention and Text Guidance Wang, Cong et al. 📜 Paper, 👨💻 Code 2023 Arxiv Photorealistic Video Generation with Diffusion Models Gupta, Agrim et al. 📜 Paper 2023 Arxiv Motion-Conditioned Image Animation for Video Editing Yan, Wilson et al. 📜 Paper, 👨💻 Code 2021 ICDAR C2VNet: A Deep Learning Framework Towards Comic Strip to Audio-Visual Scene Synthesis Gupta, Vaibhavi et al. 📜 Paper, 👨💻 Code 2016 TOMM Dynamic Manga: Animating Still Manga via Camera Movement Cao, Ying et al. 📜 Paper
-
Narrative-based complex scene generation
Year Conference / Journal Title Authors Links 2024 WACV Synthesizing Coherent Story with Auto-Regressive Latent Diffusion Models Pan, Xichen et al. 📜 Paper, 👨💻 Code 2023 CVPR Make-A-Story: Visual Memory Conditioned Consistent Story Generation Rahman, Tanzila et al. 📜 Paper 2023 NeurIPS Workshop Personalized Comic Story Generation Peng, Wenxuan et al. 📜 Paper 2022 ECCV StoryDALL-E: Adapting Pretrained Text-to-Image Transformers for Story Continuation Maharana, Adyasha et al. 📜 Paper, 👨💻 Code 2022 EMNLP Character-Centric Story Visualization via Visual Planning and Token Alignment Chen, Hong et al. 📜 Paper, 👨💻 Code 2021 NAACL Improving Generation and Evaluation of Visual Stories via Semantic Consistency Maharana, Adyasha et al. 📜 Paper, 👨💻 Code 2018 CoRR StoryGAN: A Sequential Conditional GAN for Story Visualization Yitong Li et al. 📜 Paper
-
Datasets & Benchmarks 📂📎
-
Datasets
Overview of Comic/Manga Datasets and Tasks
This table provides an overview of Comic/Manga datasets and tasks, including information on their availability, published year, source, and properties such as languages, number of comic/manga books, and pages. The rows are repeated according to the supported tasks. Accessibility is indicated with ⚠️ for no longer existing datasets, ❌ indicates existing but not accessible, and ✅ means existing and accessible. The link [proj] directs to the project websites, while [data] directs to dataset websites. For CoMix, mix means that it inherits from a mixture of four datasets.
Task Name Year Access. Language Origin # books # pages Image Classification Sequencity [proj] 2017 ⚠️ EN, JP - - 140000 BAM! [proj] 2017 ⚠️ - - - 2500000 Manga109 [proj][data] 2018 ✅ JP 1970-2010 109 21142 EmoRecCom [proj][data] 2021 ✅ EN 1938-1954 - - Object Detection Fahad18 [proj] 2012 ❌ - - - 586 eBDtheque [proj][data] 2013 ✅ EN, FR, JP 1905-2012 25 100 sun70 [proj] 2013 ❌ FR - 6 60 COMICS [proj][data] 2017 ✅ EN 1938-1954 3948 198657 BAM! [proj] 2017 ⚠️ - - - 2500000 JC2463 [proj] 2017 ❌ JP - 14 2463 AEC912 [proj] 2017 ❌ EN, FR - - 912 GCN [proj][data] 2017 ❌ EN, JP 1978-2013 253 38000 Sequencity612 [proj] 2017 ⚠️ EN, JP - - 612 SSGCI [proj][data] 2016 ❌ EN, FR, JP 1905-2012 - 500 Comics3w [proj] 2017 ❌ JP, EN - 103 29845 comics2k [proj][data] 2018 ⚠️ - - - - DCM772 [proj][data] 2018 ✅ EN 1938-1954 27 772 Manga109 [proj][data] 2018 ✅ JP 1970-2010 109 21142 BCBId [proj][data] 2022 ✅ BN - 64 3327 COO [proj][data] 2022 ✅ JP 1970-2010 109 10602 COMICS-Text+ [proj][data] 2022 ✅ EN 1938-1954 3948 198657 PopManga [proj][data] 2024 ✅ EN 1990-2020 25 1925 CoMix [proj][data] 2024 ✅ EN, FR 1938-2023 100 3800 Re-Identification Fahad18 [proj] 2012 ❌ - - - 586 Ho42 2013 ❌ - - - 42 Manga109 [proj][data] 2018 ✅ JP 1970-2010 109 21142 PopManga [proj][data] 2024 ✅ EN 1990-2020 25 1925 CoMix [proj][data] 2024 ✅ EN, FR 1938-2023 100 3800 Linking eBDtheque [proj][data] 2013 ✅ EN, FR, JP 1905-2012 25 100 sun70 2013 ❌ FR - 6 60 GCN [proj][data] 2017 ❌ EN, JP 1978-2013 253 38000 Manga109 [proj][data] 2018 ✅ JP 1970-2010 109 21142 PopManga [proj][data] 2024 ✅ EN 1990-2020 25 1925 CoMix [proj][data] 2024 ✅ EN, FR 1938-2023 100 3800 Segmentation Sequencity4k [proj] 2020 ⚠️ EN, FR, JP - - 4479 Dialog Generation PopManga [proj][data] 2024 ✅ EN 1990-2020 25 1925 CoMix [proj][data] 2024 ✅ EN, FR 1938-2023 100 3800 Unknown VLRC [proj][data] 2023 ❌ JP, FR, EN, 6+ 1940-present 376 7773
Venues
-
Journals
- TPAMI: IEEE Transactions on Pattern Analysis and Machine Intelligence
- TIP: IEEE Transactions on Image Processing
- TOMM: IEEE Transactions on Multimedia
- TVCG: IEEE Transactions on Visualization and Computer Graphics
- TCSVT: IEEE Transactions on Circuits and Systems for Video Technology
- THMS: IEEE Transactions on Human-Machine Systems
- ACM-TG: Transactions on Graphics
- ACM-TAC: Transactions on Accessible Computing
- IJHCI: International Journal on Human-Computer Interaction
- IJI: The International Journal on the Image
- IJCG: The Visual Computer: International Journal of Computer Graphics
- IJDAR: International Journal on Document Analysis and Recognition
- MM-CCA: Transaction on Multimedia Computing, Communication and Applications
-
Conferences
- NeurIPS: Neural Information Processing Systems
- ICML: International Conference on Machine Learning
- CVPR: IEEE/CVF Conference on Computer Vision and Pattern Recognition
- ICCV: IEEE/CVF International Conference of Computer Vision
- ECCV: IEEE/CVF European Conference of Computer Vision
- WACV: IEEE/CVF Winter Conference on Applications of Computer Vision
- SciVis: IEEE Scientific Visualization Conference
- ICIP: IEEE International Conference on Image Processing
- VCIP: IEEE International Conference Visual Communication Image Process
- CSNT: IEEE International Conference on Communication Systems and Network Technologies
- CAIDCD: IEEE International Conference on Computer-Aided Industrial Design and Conceptual Design
- ACM: Association for Computing Machinery
- ICDAR: IAPR International Conference on Document Analysis and Recognition
- ICPR: International Conference on Pattern Recognition
- ICIR: International Conference on Intelligent Reality
- IIAI-AAI: International Congress on Advanced Applied Informatics
- MMM: Multimedia Modeling
- LREC: International Conference on Language Resources and Evaluation
- MTA: Multimedia Tools and Applications
- ICIT: International Conference on Information Technology
- ICIAP: International Conference on Image Analysis and Processing
- IJCNN: International Joint Conference on Neural Networks
- ACPR: IAPR Asian Conference on Pattern Recognition
- ICGC: IEEE International Conference on Granular Computing
- CAVW: Computer Animation and Virtual Worlds
- MM-TA: Multimedia Tools and Applications
- DICTA: International Conference on Digital Image Computing: Techniques and Applications
- UIST: ACM Symposium on User Interface Software and Technology
- EMNLP: ACM Conference on Empirical Methods in Natural Language Processing
- IIWAS: International Conference on Information Integration and Web-based Applications and Services
- MDPI-AS: MDPI Applied Science
- ICMLC: International Conference on Machine Learning and Cybernetics
- LACLO: Latin American Conference on Learning Technologies
- ACL: Association for Computational Linguistics
- ICCC: International Conference on Computational Creativity
- 3DV: International Conference on 3D Vision
-
Workshops
- MANPU: IAPR International Workshop on Comics Analysis, Processing and Understanding
- DAS: IAPR International Workshop on Document Analysis Systems
- IWAIT: International Workshop on Advanced Image Technology
- ISPACS: Symposium on Intelligent Signal Processing and Communication Systems
- SIGCSE: ACM Technical Symposium on Computer Science Education
- ISM: IEEE International Symposium in Multimedia
Links
🔧 Tools & Repositories
- CoMix - Framework for managing and benchmarking comics datasets
- ImageTrans - Image translation for manga
- Manga Image Translator - Manga image translation
- Comic Translate - Comic translation
How to Contribute 🚀
You can contribute in two ways:
- The easiest is to open an Issue (see an example in issue #1) and we can discuss if there are missing papers, wrong associations or links, or misspelled venues.
- The second one is making a pull request with the implemented changes, following the steps:
- Fork this repository and clone it locally.
- Create a new branch for your changes:
git checkout -b feature-name. - Make your changes and commit them:
git commit -m 'Description of the changes'. - Push to your fork:
git push origin feature-name. - Open a pull request on the original repository by providing a description of your changes.
This project is in constant development, and we welcome contributions to include the latest research papers in the field or report issues 💥💥.
Star History ⭐
Acknowledge
Many thanks to my co-authors for taking the time to help me with the various refactoring of the survey. Thanks to Beppe Folder for its Awesome Human Visual Attention repo that inspired the ✨style✨ of this repository.
Significant stargazers

192 followers · starred Sep 2024
Similar repos


The official repo of the Comics Survey: "A missing piece in Vision and Language: A Survey on Comics Understanding"
See the codeREADME
Awesome Comics Understanding
This repository contains a curated list of research papers and resources focusing on Comics Understanding.
🔥 One missing piece in Vision and Language: A Survey on Comics Understanding 🔥
Authors: Emanuele Vivoli, Andrey Barsky, Mohamed Ali Souibgui, Artemis Llabrés, Marco Bertini, Dimosthenis Karatzas
📣 Latest News 📣
- 🚧 This repo is a work in progress, please contribute here
14 September 2024Our survey paper have dropped in arXiv !!
📚 Table of Contents
Overview of Vision-Language Tasks of the Layers of Comics Understanding. The ranking is based on input and output modalities and dimensions, as illustrated in the paper.
Layers of Comics Understanding
Every survey worthy of the name includes illustrative visuals to enhance understanding. We've followed this approach by providing examples for each task in the Layer of Comics Understanding.
Go check every Layer's tasks image ⬇️.
Layer 1: Tagging and Augmentation
-
Tagging
-
Image classification
Year Conference / Journal Title Authors Links 2023 TIP Panel-Page-Aware Comic Genre Understanding Xu, Chenshu et al. 📜 Paper 2019 ICDAR Workshop Analysis Based on Distributed Representations of Various Parts Images in Four-Scene Comics Story Dataset Terauchi, Akira et al. 📜 Paper 2018 TPAMI Learning Consensus Representation for Weak Style Classification Jiang, Shuhui et al. 📜 Paper 2018 ICDAR Comic Story Analysis Based on Genre Classification Daiku, Yuki et al. 📜 Paper 2017 ICDAR Histogram of Exclamation Marks and Its Application for Comics Analysis Hiroe, Sotaro et al. 📜 Paper 2014 ACM Multimedia Line-Based Drawing Style Description for Manga Classification Chu, Wei-Ta et al. 📜 Paper
-
Emotion classification
Year Conference / Journal Title Authors Links 2023 MMM Manga Text Detection with Manga-Specific Data Augmentation and Its Applications on Emotion Analysis Yang, Yi-Ting et al. 📜 Paper 2021 ICDAR Competition on Multimodal Emotion Recognition on Comics Scenes Nguyen, Nhu-Van et al. 📜 Paper, 👨💻 Code 2016 MANPU (ICPR) Manga Content Analysis Using Physiological Signals Sanches, Charles Lima et al. 📜 Paper 2015 IIAI-AAI Relation Analysis between Speech Balloon Shapes and Their Serif Descriptions in Comic Tanaka, Hideki et al. 📜 Paper
-
Action Detection
Year Conference / Journal Title Authors Links 2024 Arxiv MangaUB: A Manga Understanding Benchmark for Large Multimodal Models Ikuta, Hikaru et al. 📜 Paper 2024 MANPU (ICDAR) ComicBERT: A Transformer Model and Pre-training Strategy for Contextual Understanding in Comics Soykan, Gurkan et al. 📜 Paper, 👨💻 Code 2024 ICDAR Multimodal Transformer for Comics Text-Cloze Vivoli, Emanuele et al. 📜 Paper 2020 Arxiv A Comprehensive Study of Deep Video Action Recognition Zhu, Yi et al. 📜 Paper, 👨💻 Code 2017 CVPR The Amazing Mysteries of the Gutter: Drawing Inferences Between Panels in Comic Book Narratives Iyyer, Mohit et al. 📜 Paper
-
Page Stream Segmentation
Year Conference / Journal Title Authors Links 2022 ICPR Semantic Parsing of Interpage Relations Demirtaş, Mehmet Arif et al. 📜 Paper 2018 LREC Page Stream Segmentation with Convolutional Neural Nets Combining Textual and Visual Features Wiedemann, Gregor et al. 📜 Paper 2013 ICDAR Document Classification and Page Stream Segmentation for Digital Mailroom Applications Gordo, Albert et al. 📜 Paper
-
-
Augmentation ( Image-2-Image )
-
Image Super-Resolution
Year Conference / Journal Title Authors Links 2023 MTA Automatic Dewarping of Camera-Captured Comic Document Images Garai, Arpan et al. 📜 Paper
-
Style Transfer
Year Conference / Journal Title Authors Links 2023 Arxiv Inkn'hue: Enhancing Manga Colorization from Multiple Priors with Alignment Multi-Encoder VAE Jiramahapokee, Tawin 📜 Paper, 👨💻 Code 2023 IEEE Access Robust Manga Page Colorization via Coloring Latent Space Golyadkin, Maksim et al. 📜 Paper 2023 TVCG Shading-Guided Manga Screening from Reference Wu, Huisi et al. 📜 Paper 2022 Arxiv DASS-Detector: Domain-Adaptive Self-Supervised Pre-Training for Face & Body Detection in Drawings Topal, Barış Batuhan et al. 📜 Paper, 👨💻 Code 2021 CVPR Generating Manga from Illustrations via Mimicking Manga Creation Workflow Zhang, LM et al.* 📜 Paper, 👨💻 Code 2021 CVPR Unbiased Mean Teacher for Cross-domain Object Detection Deng, Jinhong et al. 📜 Paper, 👨💻 Code 2021 CVPR Encoding in Style: A StyleGAN Encoder for Image-to-Image Translation Richardson, Elad et al. 📜 Paper, 👨💻 Code 2021 AAAI MangaGAN: Unpaired Photo-to-Manga Translation Based on The Methodology of Manga Drawing Su, Hao et al. 📜 Paper 2019 ISM Synthesis of Screentone Patterns of Manga Characters Tsubota, K. et al. 📜 Paper, 👨💻 Code 2018 SciVis Color Interpolation for Non-Euclidean Color Spaces Zeyen, Max et al. 📜 Paper 2017 ACM-SIGGRAPH Asia Comicolorization: Semi-automatic Manga Colorization Furusawa, Chie et al. 📜 Paper, 👨💻 Code 2017 ICDAR CGAN-Based Manga Colorization Using a Single Training Image Hensman, Paulina et al. 📜 Paper, 👨💻 Code 2017 CVPR Image-to-Image Translation with Conditional Adversarial Networks Isola, Phillip et al. 📜 Paper 2017 ACM-TG Deep Extraction of Manga Structural Lines Li, Chengze et al. 📜 Paper, 👨💻 Code
-
Vectorization
Year Conference / Journal Title Authors Links 2023 TCSVT MARVEL: Raster Gray-level Manga Vectorization via Primitive-wise Deep Reinforcement Learning H. Su et al. 📜 Paper, 👨💻 Code 2022 CVPR Towards Layer-wise Image Vectorization Ma, Xu et al. 📜 Paper, 👨💻 Code 2017 ACM-TG Deep Extraction of Manga Structural Lines Li, Chengze et al. 📜 Paper, 👨💻 Code 2017 TVCG Manga Vectorization and Manipulation with Procedural Simple Screentone Yao, Chih-Yuan et al. 📜 Paper 2011 ACM-SIGGRAPH Depixelizing Pixel Art Kopf, Johannes et al. 📜 Paper 2003 N/A Potrace : A Polygon-Based Tracing Algorithm Selinger, Peter 📜 Paper, 👨💻 Code
-
Depth Estimation
Year Conference / Journal Title Authors Links 2023 CVPR Workshop Dense Multitask Learning to Reconfigure Comics Bhattacharjee, Deblina et al. 📜 Paper 2022 WACV Estimating Image Depth in the Comics Domain Bhattacharjee, Deblina et al. 📜 Paper, 👨💻 Code 2022 CVPR MulT: An End-to-End Multitask Learning Transformer Bhattacharjee, Deblina et al. 📜 Paper, 👨💻 Code
-
Layer 2: Grounding, Analysis and Segmentation
-
Grounding
-
Object detection
Year Conference / Journal Title Authors Links 2024 MANPU (ICDAR) Comics Datasets Framework: Mix of Comics datasets for detection benchmarking Vivoli, Emanuele et al. 📜 Paper 2024 MANPU (ICDAR) A Comprehensive Gold Standard and Benchmark for Comics Text Detection and Recognition Gurkan Soykan et al. 📜 Paper, 👨💻 Code 2023 MMM Manga Text Detection with Manga-Specific Data Augmentation and Its Applications on Emotion Analysis Yang, \relax YT et al. 📜 Paper 2023 CSNT CPD: Faster RCNN-based DragonBall Comic Panel Detection Sharma, Rishabh et al. 📜 Paper 2022 IJDAR BCBId: First Bangla Comic Dataset and Its Applications Dutta, Arpita et al. 📜 Paper 2022 ECCV COO/ Comic Onomatopoeia Dataset for Recognizing Arbitrary or Truncated Texts Baek, Jeonghun et al. 📜 Paper, 👨💻 Code 2019 ICDAR Workshop What Do We Expect from Comic Panel Extraction? Nguyen Nhu, Van et al. 📜 Paper 2019 ICDAR Workshop CNN Based Extraction of Panels/Characters from Bengali Comic Book Page Images Dutta, Arpita et al. 📜 Paper 2018 VCIP Text Detection in Manga by Deep Region Proposal, Classification, and Regression Chu, Wei-Ta et al. 📜 Paper 2018 IWAIT A Study on Object Detection Method from Manga Images Using CNN Yanagisawa, Hideaki et al. 📜 Paper 2018 IWAIT A Study on Object Detection Method from Manga Images Using CNN Yanagisawa, Hideaki et al. 📜 Paper 2017 ICDAR A Faster R-CNN Based Method for Comic Characters Face Detection Qin, Xiaoran et al. 📜 Paper 2016 IJCG Text-Aware Balloon Extraction from Manga Liu, Xueting et al. 📜 Paper 2016 IJCNN Line-Wise Text Identification in Comic Books: A Support Vector Machine-Based Approach Pal, Srikanta et al. 📜 Paper 2016 ICIP Text Detection in Manga by Combining Connected-Component-Based and Region-Based Classifications Aramaki, Yuji et al. 📜 Paper 2015 ICIAP Panel Tracking for the Extraction and the Classification of Speech Balloons Jomaa, Hadi S. et al. 📜 Paper 2012 DAS Panel and Speech Balloon Extraction from Comic Books Ho, Anh Khoi Ngo et al. 📜 Paper 2011 IJI Method for Real Time Text Extraction of Digital Manga Comic Arai, Kohei et al. 📜 Paper 2011 ICDAR Recognizing Text Elements for SVG Comic Compression and Its Novel Applications Su, Chung-Yuan et al. 📜 Paper 2010 ICIT Method for Automatic E-Comic Scene Frame Extraction for Reading Comic on Mobile Devices Arai, Kohei et al. 📜 Paper 2009 IJHCI Enhancing the Accessibility for All of Digital Comic Books Ponsard, Christophe 📜 Paper
-
Character Re-Identification
Year Conference / Journal Title Authors Links 2024 Arxiv Tails Tell Tales: Chapter-Wide Manga Transcriptions with Character Names Ragav Sachdeva et al. 📜 Paper, 👨💻 Code 2024 NeurIPS CoMix: A Comprehensive Benchmark for Multi-Task Comic Understanding Emanuele Vivoli et al. 📜 Paper, 👨💻 Code 2024 CVPR The Manga Whisperer: Automatically Generating Transcriptions for Comics Sachdeva, Ragav et al. 📜 Paper, 👨💻 Code 2023 IET Image Processing Toward Cross-Domain Object Detection in Artwork Images Using Improved YoloV5 and XGBoosting Ahmad, Tasweer et al. 📜 Paper 2023 Arxiv Identity-Aware Semi-Supervised Learning for Comic Character Re-Identification Soykan, Gürkan et al. 📜 Paper 2023 ACM-MM Asia Occlusion-Aware Manga Character Re-Identification with Self-Paced Contrastive Learning Zhang, Ci-Yin et al. 📜 Paper 2022 Arxiv Unsupervised Manga Character Re-Identification via Face-Body and Spatial-Temporal Associated Clustering Zhang, Z et al. 📜 Paper 2022 ICIR CAST: Character Labeling in Animation Using Self‐supervision by Tracking Nir, Oron et al. 📜 Paper 2020 ICPR Dual Loss for Manga Character Recognition with Imbalanced Training Data Li, Yonggang et al. 📜 Paper 2020 ICML A Simple Framework for Contrastive Learning of Visual Representations Chen, Ting et al. 📜 Paper 2015 ACPR Similarity Learning Based on Pool-Based Active Learning for Manga Character Retrieval Iwata, Motoi et al. 📜 Paper 2014 DAS A Study to Achieve Manga Character Retrieval Method for Manga Images Iwata, M. et al. 📜 Paper 2012 CVPR Color Attributes for Object Detection Khan, Fahad Shahbaz et al. 📜 Paper 2012 ECCV PHOG Analysis of Self-Similarity in Aesthetic Images Redies, Christoph et al. 📜 Paper 2011 ICDAR Similar Manga Retrieval Using Visual Vocabulary Based on Regions of Interest Sun, Weihan et al. 📜 Paper
-
Sentence-based Grounding
Year Conference / Journal Title Authors Links 2024 AAAI GroundVLP: Harnessing Zero-shot Visual Grounding from Vision-Language Pre-training and Open-Vocabulary Object Detection Shen, Haozhan et al. 📜 Paper, 👨💻 Code 2024 ECCV Grounding DINO: Marrying DINO with Grounded Pre-Training for Open-Set Object Detection Liu, Shilong et al. 📜 Paper, 👨💻 Code 2020 CVPR Workshop Exploring Phrase Grounding without Training: Contextualisation and Extension to Text-Based Image Retrieval Parcalabescu, Letitia et al. 📜 Paper 2019 AAAI Zero-Shot Object Detection with Textual Descriptions Li, Zhihui et al. 📜 Paper
-
-
Analysis
-
Text-Character association
Year Conference / Journal Title Authors Links 2024 Arxiv Tails Tell Tales: Chapter-Wide Manga Transcriptions with Character Names Ragav Sachdeva et al. 📜 Paper, 👨💻 Code 2024 NeurIPS CoMix: A Comprehensive Benchmark for Multi-Task Comic Understanding Emanuele Vivoli et al. 📜 Paper, 👨💻 Code 2024 MANPU (ICDAR) Spatially Augmented Speech Bubble to Character Association via Comic Multi-task Learning Soykan, Gurkan et al. 📜 Paper 💻 Code 2024 CVPR The Manga Whisperer: Automatically Generating Transcriptions for Comics Sachdeva, Ragav et al. 📜 Paper, 👨💻 Code 2023 arXiv Manga109Dialog A Large-scale Dialogue Dataset for Comics Speaker Detection Li, Yingxuan et al. 📜 Paper 2022 IIAI-AAI Algorithms for Estimation of Comic Speakers Considering Reading Order of Frames and Texts Omori, Yuga et al. 📜 Paper 2019 IJDAR Comic MTL: Optimized Multi-Task Learning for Comic Book Image Analysis Nguyen, Nhu-Van et al. 📜 Paper 2015 ICDAR Speech Balloon and Speaker Association for Comics and Manga Understanding Rigaud, Christophe et al. 📜 Paper
-
Panel Sorting
Year Conference / Journal Title Authors Links 2017 ICDAR Story Pattern Analysis Based on Scene Order Information in Four-Scene Comics Ueno, Miki et al. 📜 Paper
-
Dialog transcription
Year Conference / Journal Title Authors Links 2024 Arxiv Tails Tell Tales: Chapter-Wide Manga Transcriptions with Character Names Ragav Sachdeva et al. 📜 Paper, 👨💻 Code 2024 NeurIPS CoMix: A Comprehensive Benchmark for Multi-Task Comic Understanding Emanuele Vivoli et al. 📜 Paper, 👨💻 Code 2024 CVPR The Manga Whisperer: Automatically Generating Transcriptions for Comics Sachdeva, Ragav et al. 📜 Paper, 👨💻 Code 2023 arXiv Manga109Dialog A Large-scale Dialogue Dataset for Comics Speaker Detection Li, Yingxuan et al. 📜 Paper
-
Translation
Year Conference / Journal Title Authors Links 2024 ArXiv Context-Informed Machine Translation of Manga using Multimodal Large Language Models Lippmann, Philip et al. 📜 Paper, 👨💻 Code 2024 ArXiv Large Language Models as Manga Translators: A Case Study Zhishen Yang et al. paper 2024 ArXiv Generating Visual Stories with Grounded and Coreferent Characters Danyang Liu et al. paper 2024 ICKECS The Future of Graphic Novel Translation: Fully Automated Systems Sandeep Singh et al. paper 2024 ACM Multimedia Zero-Shot Character Identification and Speaker Prediction in Comics via Iterative Multimodal Fusion Yingxuan Li et al. paper 2023 ArXiv Multi-Teacher Knowledge Distillation For Text Image Machine Translation Cong Ma et al. paper 2020 ArXiv Towards Fully Automated Manga Translation Ryota Hinami et al. paper 2014 inTRAlinea Visual adaptation in translated comics Federico, Zanettin paper
-
-
Segmentation
-
Instance Segmentation
Year Conference / Journal Title Authors Links 2024 AI4VA (ECCV) Unlocking Comics: The AI4VA Dataset for Visual Understanding Grönquist, Peter et al. 📜 Paper,👨💻 Code 2024 ICDAR Investigating Neural Networks and Transformer Models for Enhanced Comic Decoding Kouletou, Eleanna et al. 📜 Paper 2022 DataverseNL The Visual Language Research Corpus (VLRC) Project Cohn, Neil 📜 Paper
-
Layer 3: Retrieval and Modification
-
Retrieval
-
Image-Text Retrieval
Year Conference / Journal Title Authors Links 2014 DAS A Study to Achieve Manga Character Retrieval Method for Manga Images Iwata, M. et al. 📜 Paper 2011 ICDAR Similar Manga Retrieval Using Visual Vocabulary Based on Regions of Interest Sun, Weihan et al. 📜 Paper 2011 CAVW Comic Character Animation Using Bayesian Estimation Chou, Yun-Feng et al. 📜 Paper 2010 ICGC Searching Digital Political Cartoons Wu, Yejun 📜 Paper
-
Text-Image Retrieval
Year Conference / Journal Title Authors Links 2014 ICIP Sketch2Manga: Sketch-based Manga Retrieval Matsui, Yusuke et al. 📜 Paper
-
Composed Image Retrieval
Year Conference / Journal Title Authors Links 2023 Arxiv MaRU: A Manga Retrieval and Understanding System Connecting Vision and Language Shen, Conghao Tom et al. 📜 Paper 2022 DICTA ComicLib: A New Large-Scale Comic Dataset for Sketch Understanding Wei, Xin et al. 📜 Paper 2021 ICDAR Manga-MMTL: Multimodal Multitask Transfer Learning for Manga Character Analysis Nguyen, Nhu-Van et al. 📜 Paper 2017 ICDAR Sketch-Based Manga Retrieval Using Deep Features Narita, Rei et al. 📜 Paper 2017 Arxiv A Neural Representation of Sketch Drawings Ha, David et al. 📜 Paper 2017 Arxiv Style Transfer for Anime Sketches with Enhanced Residual U-net and Auxiliary Classifier GAN Zhang, Lvmin et al. 📜 Paper 2015 MM-TA Sketch-Based Manga Retrieval Using Manga109 Dataset Matsui, Yusuke et al. 📜 Paper
-
Personalized Image Retrieval
Year Conference / Journal Title Authors Links 2022 BMVC Personalised CLIP or: How to Find Your Vacation Videos Korbar, Bruno et al. 📜 Paper
-
-
Modification
Layer 4: Understanding
-
Understanding
-
Visual Entailment
Year Conference / Journal Title Authors Links
-
Visual-Question Answer
Year Conference / Journal Title Authors Links 2022 WACV Challenges in Procedural Multimodal Machine Comprehension: A Novel Way To Benchmark Sahu, Pritish et al. 📜 Paper 2021 Arxiv Towards Solving Multimodal Comprehension Sahu, Pritish et al. 📜 Paper 2020 MDPI-AS A Survey on Machine Reading Comprehension—Tasks, Evaluation Metrics and Benchmark Datasets Zeng, Changchang et al. 📜 Paper 2017 IIWAS ComicQA: Contextual Navigation Aid by Hyper-Comic Representation Sumi, Yasuyuki et al. 📜 Paper 2016 MANPU (ICPR) Designing a Question-Answering System for Comic Contents Moriyama, Yukihiro et al. 📜 Paper
-
Visual-Dialog
Year Conference / Journal Title Authors Links
-
Visual Reasoning
Year Conference / Journal Title Authors Links
-
Layer 5: Generation and Synthesis
-
Generation
-
Comics generation from other media
Year Conference / Journal Title Authors Links 2023 SIGCSE Developing Comic-based Learning Toolkits for Teaching Computing to Elementary School Learners Castro, Francico et al. 📜 Paper 2022 THMS Augmenting Conversations With Comic-Style Word Balloons Zhang, H. et al. 📜 Paper 2022 LACLO Comics as a Pedagogical Tool for Teaching Lima, Antonio Alexandre et al. 📜 Paper 2021 TVCG ChartStory: Automated Partitioning, Layout, and Captioning of Charts into Comic-Style Narratives Zhao, Jian et al. 📜 Paper 2021 SIGCSE Using Comics to Introduce and Reinforce Programming Concepts in CS1 Suh, Sangho et al. 📜 Paper 2021 MM-CCA Automatic Comic Generation with Stylistic Multi-page Layouts and Emotion-driven Text Balloon Generation Yang, Xin et al. 📜 Paper 2018 ACM Comixify: Transform Video into a Comics Pesko, Maciej et al. 📜 Paper 2015 TOMM Content-Aware Video2Comics With Manga-Style Layout Jing, Guangmei et al. 📜 Paper 2012 TOMM Movie2Comics: Towards a Lively Video Content Presentation Wang, Meng et al. 📜 Paper 2012 ACM-TG Automatic Stylistic Manga Layout Cao, Ying et al. 📜 Paper 2012 TOMM Scalable Comic-like Video Summaries and Layout Disturbance Herranz, Luis et al. 📜 Paper 2011 ACM-MM Automatic Preview Generation of Comic Episodes for Digitized Comic Search Hoashi, Keiichiro et al. 📜 Paper 2011 ISPACS Automatic Comic Strip Generation Using Extracted Keyframes from Cartoon Animation Tanapichet, Pakpoom et al. 📜 Paper 2011 ICMLC Caricaturation for Human Face Pictures Chang, I-Cheng et al. 📜 Paper 2010 SICE Comic Live Chat Communication Tool Based on Concept of Downgrading Matsuda, Misaki et al. 📜 Paper 2010 CAIDCD Research and Development of the Generation in Japanese Manga Based on Frontal Face Image Xuexiong, Deng et al. 📜 Paper
-
Comics to Scene graph
Year Conference / Journal Title Authors Links
-
Image-2-Text Generation
Year Conference / Journal Title Authors Links 2024 NeurIPS Cracking the Code of Juxtaposition: Can AI Models Understand the Humorous Contradictions Hu, Zhe et al. 📜 Paper 2024 AI4VA (ECCV) ComiCap: A VLMs pipeline for dense captioning of Comic Panels Vivoli, Emanuele et al. 📜 Paper 2024 ICDAR Multimodal Transformer for Comics Text-Cloze Vivoli, Emanuele et al. 📜 Paper 2024 MANPU (ICDAR) Toward Accessible Comics for Blind and Low Vision Readers Rigaud, Christophe et al. 📜 Paper 2024 CVPR The Manga Whisperer: Automatically Generating Transcriptions for Comics Sachdeva, Ragav et al. 📜 Paper, 👨💻 Code 2023 Arxiv Comics for Everyone: Generating Accessible Text Descriptions for Comic Strips Ramaprasad, Reshma et al. 📜 Paper 2023 ACL Multimodal Persona Based Generation of Comic Dialogs Agrawal, Harsh et al. 📜 Paper 2023 Arxiv M2C: Towards Automatic Multimodal Manga Complement Guo, Hongcheng et al. 📜 Paper
-
Text-2-Image Generation
Year Conference / Journal Title Authors Links 2023 ICCV Diffusion in Style Everaert, Martin Nicolas et al. 📜 Paper, 👨💻 Code 2023 MDPI-AS A Study on Generating Webtoons Using Multilingual Text-to-Image Models Yu, Kyungho et al. 📜 Paper 2023 Arxiv Generating Coherent Comic with Rich Story Using ChatGPT and Stable Diffusion Jin, Ze et al. 📜 Paper 2022 ISM Conditional GAN for Small Datasets Hiruta, Komei et al. 📜 Paper 2021 NAACL Improving Generation and Evaluation of Visual Stories via Semantic Consistency Maharana, Adyasha et al. 📜 Paper, 👨💻 Code 2021 CoRR Integrating Visuospatial, Linguistic and Commonsense Structure intoStory Visualization Maharana, Adyasha et al. 📜 Paper, 👨💻 Code 2021 ICCC A Deep Learning Pipeline for the Synthesis of Graphic Novels Melistas, Thomas et al. 📜 Paper 2021 Arxiv ComicGAN: Text-to-Comic Generative Adversarial Network Proven-Bessel, Ben et al. 📜 Paper, 👨💻 Code 2019 CVPR StoryGAN: A Sequential Conditional GAN for Story Visualization Li, Yitong et al. 📜 Paper, 👨💻 Code 2018 CVPR Cross-Domain Weakly-Supervised Object Detection through Progressive Domain Adaptation Inoue, Naoto et al. 📜 Paper, 👨💻 Code 2017 Arxiv Towards the Automatic Anime Characters Creation with Generative Adversarial Networks Jin, Yanghua et al. 📜 Paper, 👨💻 Code
-
Scene-graph Generation for captioning
Year Conference / Journal Title Authors Links
-
-
Synthesis
-
3D Generation from Images
Year Conference / Journal Title Authors Links 2023 ECCV AnimeCeleb: Large-Scale Animation CelebHeads Dataset for Head Reenactment Kim, Kangyeol et al. 📜 Paper, 👨💻 Code 2023 IJCAI Collaborative Neural Rendering Using Anime Character Sheets Lin, Zuzeng et al. 📜 Paper, 👨💻 Code 2023 CVPR PAniC-3D: Stylized Single-view 3D Reconstruction from Portraits of Anime Characters Chen, Shuhong et al. 📜 Paper 2023 Arxiv Sketch-A-Shape: Zero-Shot Sketch-to-3D Shape Generation Sanghi, Aditya et al. 📜 Paper 2021 N/A Talking Head Anime from a Single Image 2: More Expressive Khungurn, Pramook et al. 👨💻 Code 2020 ICLR U-GAT-IT: Unsupervised Generative Attentional Networks with Adaptive Layer-Instance Normalization for Image-to-Image Translation Kim, Junho et al. 📜 Paper, 👨💻 Code 2017 3DV 3D Shape Reconstruction from Sketches via Multi-view Convolutional Networks Lun, Zhaoliang et al. 📜 Paper
-
Video generation
Year Conference / Journal Title Authors Links 2023 Arxiv DreamVideo: High-Fidelity Image-to-Video Generation with Image Retention and Text Guidance Wang, Cong et al. 📜 Paper, 👨💻 Code 2023 Arxiv Photorealistic Video Generation with Diffusion Models Gupta, Agrim et al. 📜 Paper 2023 Arxiv Motion-Conditioned Image Animation for Video Editing Yan, Wilson et al. 📜 Paper, 👨💻 Code 2021 ICDAR C2VNet: A Deep Learning Framework Towards Comic Strip to Audio-Visual Scene Synthesis Gupta, Vaibhavi et al. 📜 Paper, 👨💻 Code 2016 TOMM Dynamic Manga: Animating Still Manga via Camera Movement Cao, Ying et al. 📜 Paper
-
Narrative-based complex scene generation
Year Conference / Journal Title Authors Links 2024 WACV Synthesizing Coherent Story with Auto-Regressive Latent Diffusion Models Pan, Xichen et al. 📜 Paper, 👨💻 Code 2023 CVPR Make-A-Story: Visual Memory Conditioned Consistent Story Generation Rahman, Tanzila et al. 📜 Paper 2023 NeurIPS Workshop Personalized Comic Story Generation Peng, Wenxuan et al. 📜 Paper 2022 ECCV StoryDALL-E: Adapting Pretrained Text-to-Image Transformers for Story Continuation Maharana, Adyasha et al. 📜 Paper, 👨💻 Code 2022 EMNLP Character-Centric Story Visualization via Visual Planning and Token Alignment Chen, Hong et al. 📜 Paper, 👨💻 Code 2021 NAACL Improving Generation and Evaluation of Visual Stories via Semantic Consistency Maharana, Adyasha et al. 📜 Paper, 👨💻 Code 2018 CoRR StoryGAN: A Sequential Conditional GAN for Story Visualization Yitong Li et al. 📜 Paper
-
Datasets & Benchmarks 📂📎
-
Datasets
Overview of Comic/Manga Datasets and Tasks
This table provides an overview of Comic/Manga datasets and tasks, including information on their availability, published year, source, and properties such as languages, number of comic/manga books, and pages. The rows are repeated according to the supported tasks. Accessibility is indicated with ⚠️ for no longer existing datasets, ❌ indicates existing but not accessible, and ✅ means existing and accessible. The link [proj] directs to the project websites, while [data] directs to dataset websites. For CoMix, mix means that it inherits from a mixture of four datasets.
Task Name Year Access. Language Origin # books # pages Image Classification Sequencity [proj] 2017 ⚠️ EN, JP - - 140000 BAM! [proj] 2017 ⚠️ - - - 2500000 Manga109 [proj][data] 2018 ✅ JP 1970-2010 109 21142 EmoRecCom [proj][data] 2021 ✅ EN 1938-1954 - - Object Detection Fahad18 [proj] 2012 ❌ - - - 586 eBDtheque [proj][data] 2013 ✅ EN, FR, JP 1905-2012 25 100 sun70 [proj] 2013 ❌ FR - 6 60 COMICS [proj][data] 2017 ✅ EN 1938-1954 3948 198657 BAM! [proj] 2017 ⚠️ - - - 2500000 JC2463 [proj] 2017 ❌ JP - 14 2463 AEC912 [proj] 2017 ❌ EN, FR - - 912 GCN [proj][data] 2017 ❌ EN, JP 1978-2013 253 38000 Sequencity612 [proj] 2017 ⚠️ EN, JP - - 612 SSGCI [proj][data] 2016 ❌ EN, FR, JP 1905-2012 - 500 Comics3w [proj] 2017 ❌ JP, EN - 103 29845 comics2k [proj][data] 2018 ⚠️ - - - - DCM772 [proj][data] 2018 ✅ EN 1938-1954 27 772 Manga109 [proj][data] 2018 ✅ JP 1970-2010 109 21142 BCBId [proj][data] 2022 ✅ BN - 64 3327 COO [proj][data] 2022 ✅ JP 1970-2010 109 10602 COMICS-Text+ [proj][data] 2022 ✅ EN 1938-1954 3948 198657 PopManga [proj][data] 2024 ✅ EN 1990-2020 25 1925 CoMix [proj][data] 2024 ✅ EN, FR 1938-2023 100 3800 Re-Identification Fahad18 [proj] 2012 ❌ - - - 586 Ho42 2013 ❌ - - - 42 Manga109 [proj][data] 2018 ✅ JP 1970-2010 109 21142 PopManga [proj][data] 2024 ✅ EN 1990-2020 25 1925 CoMix [proj][data] 2024 ✅ EN, FR 1938-2023 100 3800 Linking eBDtheque [proj][data] 2013 ✅ EN, FR, JP 1905-2012 25 100 sun70 2013 ❌ FR - 6 60 GCN [proj][data] 2017 ❌ EN, JP 1978-2013 253 38000 Manga109 [proj][data] 2018 ✅ JP 1970-2010 109 21142 PopManga [proj][data] 2024 ✅ EN 1990-2020 25 1925 CoMix [proj][data] 2024 ✅ EN, FR 1938-2023 100 3800 Segmentation Sequencity4k [proj] 2020 ⚠️ EN, FR, JP - - 4479 Dialog Generation PopManga [proj][data] 2024 ✅ EN 1990-2020 25 1925 CoMix [proj][data] 2024 ✅ EN, FR 1938-2023 100 3800 Unknown VLRC [proj][data] 2023 ❌ JP, FR, EN, 6+ 1940-present 376 7773
Venues
-
Journals
- TPAMI: IEEE Transactions on Pattern Analysis and Machine Intelligence
- TIP: IEEE Transactions on Image Processing
- TOMM: IEEE Transactions on Multimedia
- TVCG: IEEE Transactions on Visualization and Computer Graphics
- TCSVT: IEEE Transactions on Circuits and Systems for Video Technology
- THMS: IEEE Transactions on Human-Machine Systems
- ACM-TG: Transactions on Graphics
- ACM-TAC: Transactions on Accessible Computing
- IJHCI: International Journal on Human-Computer Interaction
- IJI: The International Journal on the Image
- IJCG: The Visual Computer: International Journal of Computer Graphics
- IJDAR: International Journal on Document Analysis and Recognition
- MM-CCA: Transaction on Multimedia Computing, Communication and Applications
-
Conferences
- NeurIPS: Neural Information Processing Systems
- ICML: International Conference on Machine Learning
- CVPR: IEEE/CVF Conference on Computer Vision and Pattern Recognition
- ICCV: IEEE/CVF International Conference of Computer Vision
- ECCV: IEEE/CVF European Conference of Computer Vision
- WACV: IEEE/CVF Winter Conference on Applications of Computer Vision
- SciVis: IEEE Scientific Visualization Conference
- ICIP: IEEE International Conference on Image Processing
- VCIP: IEEE International Conference Visual Communication Image Process
- CSNT: IEEE International Conference on Communication Systems and Network Technologies
- CAIDCD: IEEE International Conference on Computer-Aided Industrial Design and Conceptual Design
- ACM: Association for Computing Machinery
- ICDAR: IAPR International Conference on Document Analysis and Recognition
- ICPR: International Conference on Pattern Recognition
- ICIR: International Conference on Intelligent Reality
- IIAI-AAI: International Congress on Advanced Applied Informatics
- MMM: Multimedia Modeling
- LREC: International Conference on Language Resources and Evaluation
- MTA: Multimedia Tools and Applications
- ICIT: International Conference on Information Technology
- ICIAP: International Conference on Image Analysis and Processing
- IJCNN: International Joint Conference on Neural Networks
- ACPR: IAPR Asian Conference on Pattern Recognition
- ICGC: IEEE International Conference on Granular Computing
- CAVW: Computer Animation and Virtual Worlds
- MM-TA: Multimedia Tools and Applications
- DICTA: International Conference on Digital Image Computing: Techniques and Applications
- UIST: ACM Symposium on User Interface Software and Technology
- EMNLP: ACM Conference on Empirical Methods in Natural Language Processing
- IIWAS: International Conference on Information Integration and Web-based Applications and Services
- MDPI-AS: MDPI Applied Science
- ICMLC: International Conference on Machine Learning and Cybernetics
- LACLO: Latin American Conference on Learning Technologies
- ACL: Association for Computational Linguistics
- ICCC: International Conference on Computational Creativity
- 3DV: International Conference on 3D Vision
-
Workshops
- MANPU: IAPR International Workshop on Comics Analysis, Processing and Understanding
- DAS: IAPR International Workshop on Document Analysis Systems
- IWAIT: International Workshop on Advanced Image Technology
- ISPACS: Symposium on Intelligent Signal Processing and Communication Systems
- SIGCSE: ACM Technical Symposium on Computer Science Education
- ISM: IEEE International Symposium in Multimedia
Links
🔧 Tools & Repositories
- CoMix - Framework for managing and benchmarking comics datasets
- ImageTrans - Image translation for manga
- Manga Image Translator - Manga image translation
- Comic Translate - Comic translation
How to Contribute 🚀
You can contribute in two ways:
- The easiest is to open an Issue (see an example in issue #1) and we can discuss if there are missing papers, wrong associations or links, or misspelled venues.
- The second one is making a pull request with the implemented changes, following the steps:
- Fork this repository and clone it locally.
- Create a new branch for your changes:
git checkout -b feature-name. - Make your changes and commit them:
git commit -m 'Description of the changes'. - Push to your fork:
git push origin feature-name. - Open a pull request on the original repository by providing a description of your changes.
This project is in constant development, and we welcome contributions to include the latest research papers in the field or report issues 💥💥.
Star History ⭐
Acknowledge
Many thanks to my co-authors for taking the time to help me with the various refactoring of the survey. Thanks to Beppe Folder for its Awesome Human Visual Attention repo that inspired the ✨style✨ of this repository.
Similar repos
Significant stargazers
192 followers · starred Sep 2024