Tensorflow implementation of Human-Level Control through Deep Reinforcement Learning
Python
2,589
99 commits
updated Apr 18, 2019
Tensorflow implementation of Human-Level Control through Deep Reinforcement Learning.
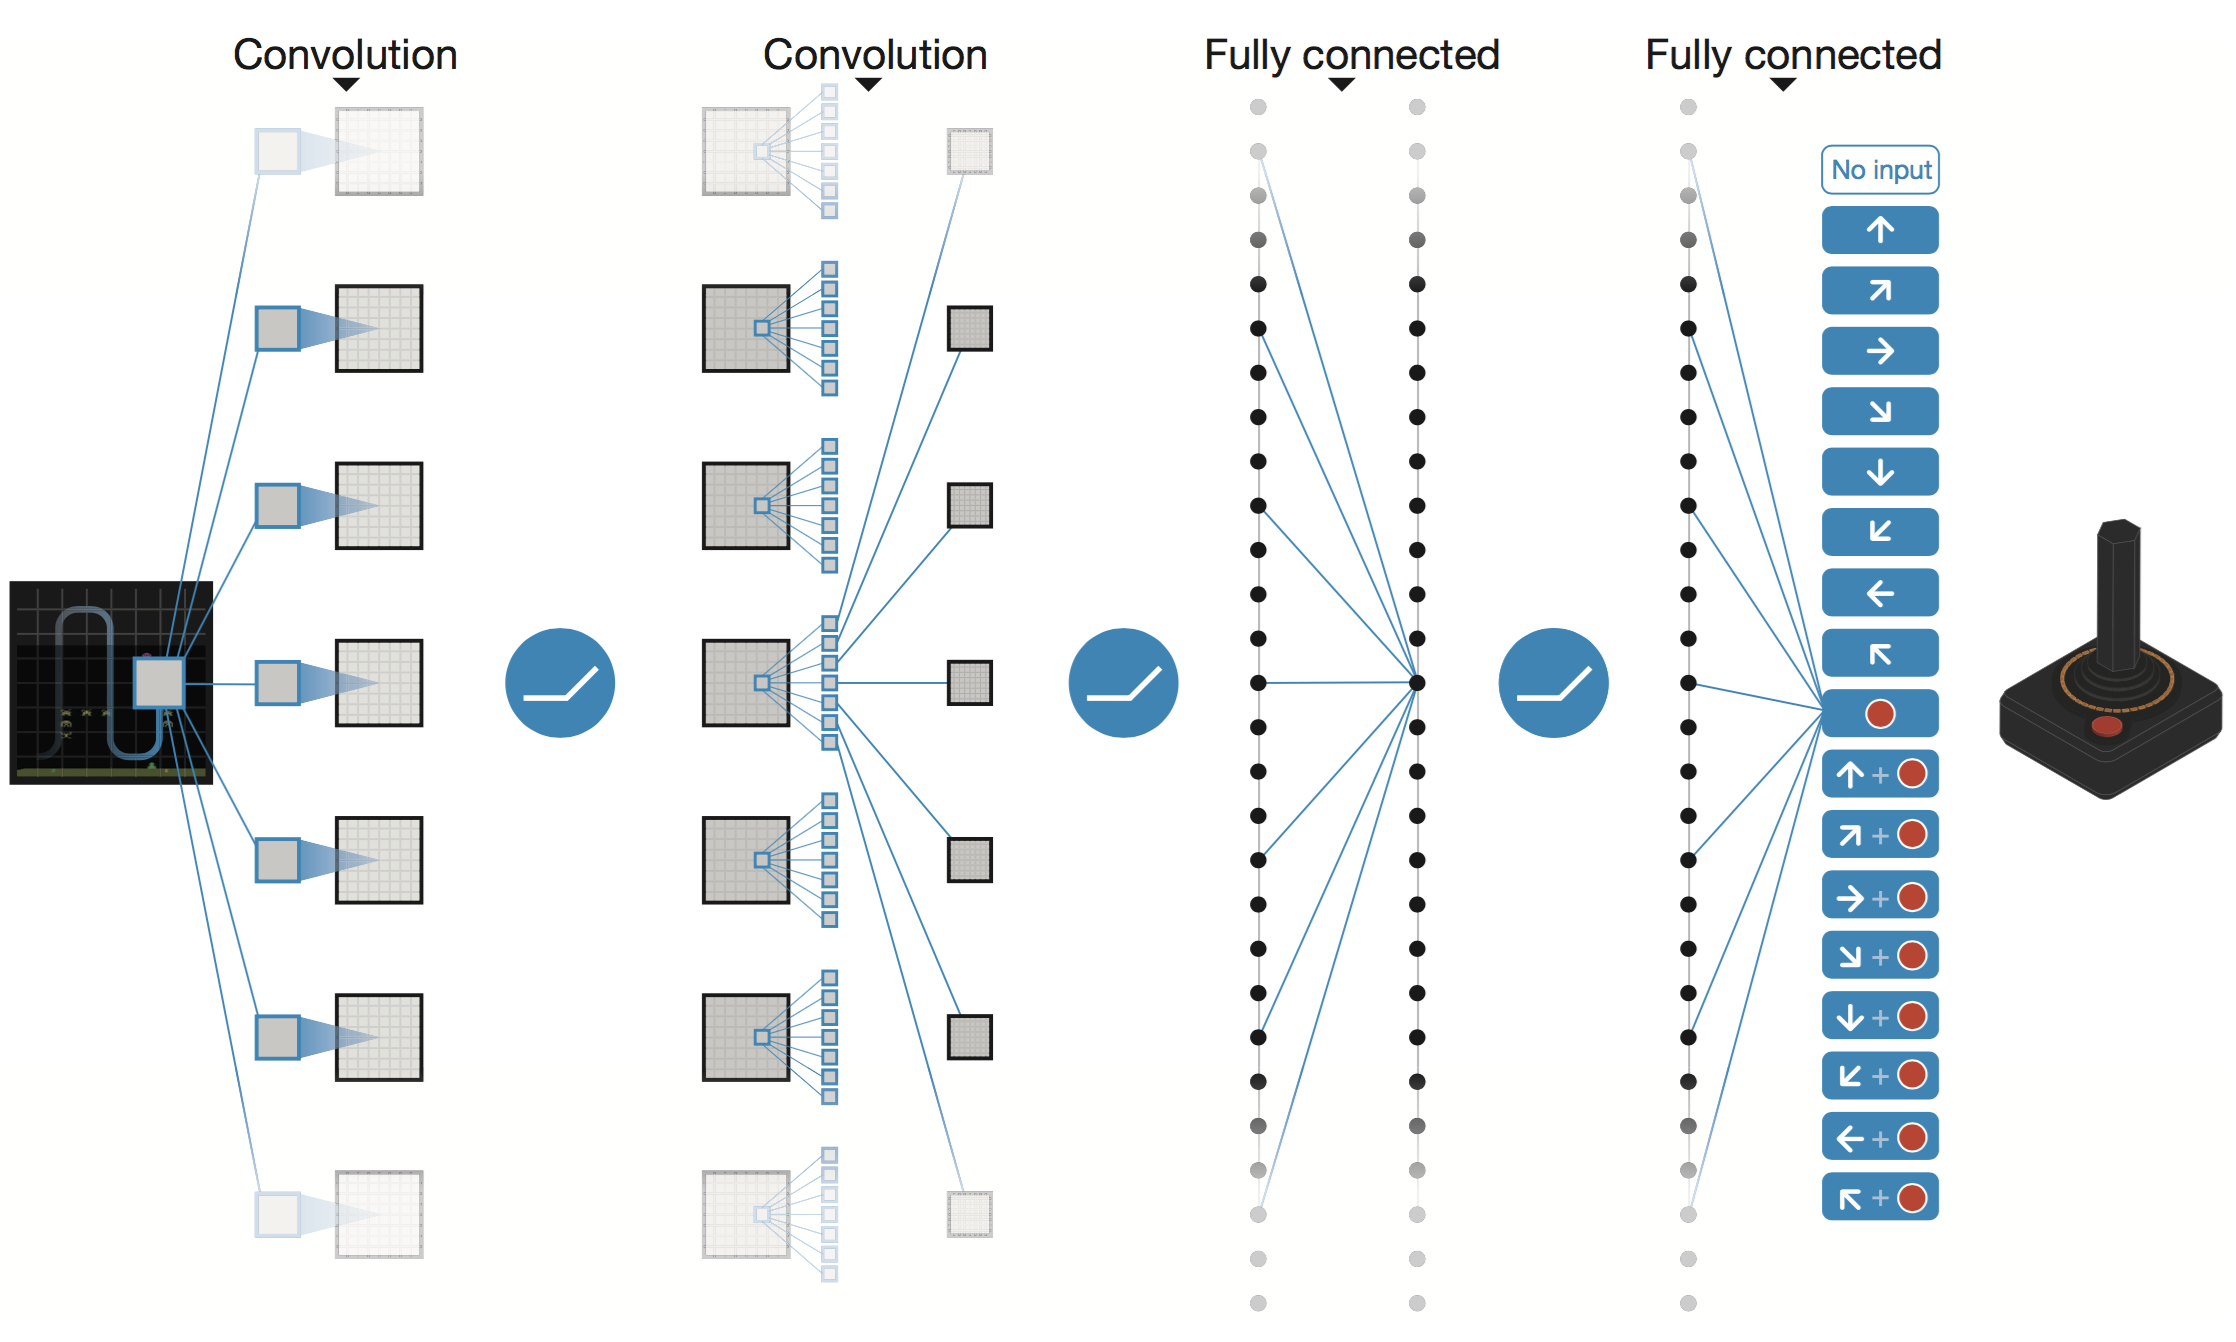
This implementation contains:
First, install prerequisites with:
$ pip install tqdm gym[all]
To train a model for Breakout:
$ python main.py --env_name=Breakout-v0 --is_train=True
$ python main.py --env_name=Breakout-v0 --is_train=True --display=True
To test and record the screen with gym:
$ python main.py --is_train=False
$ python main.py --is_train=False --display=True
Result of training for 24 hours using GTX 980 ti.
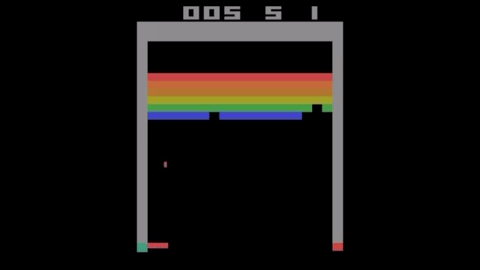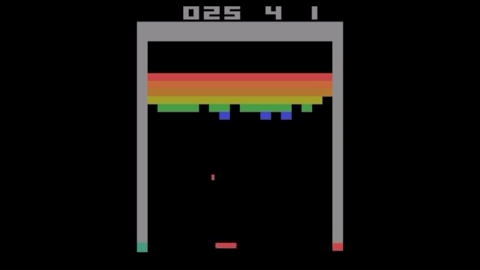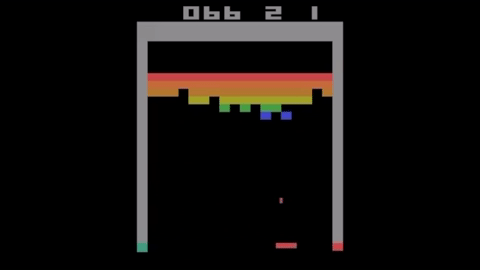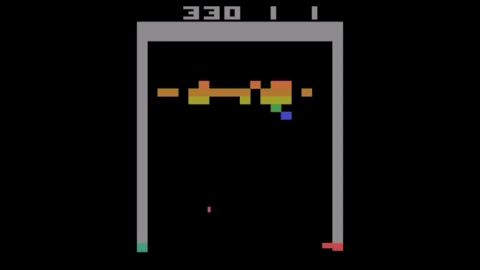
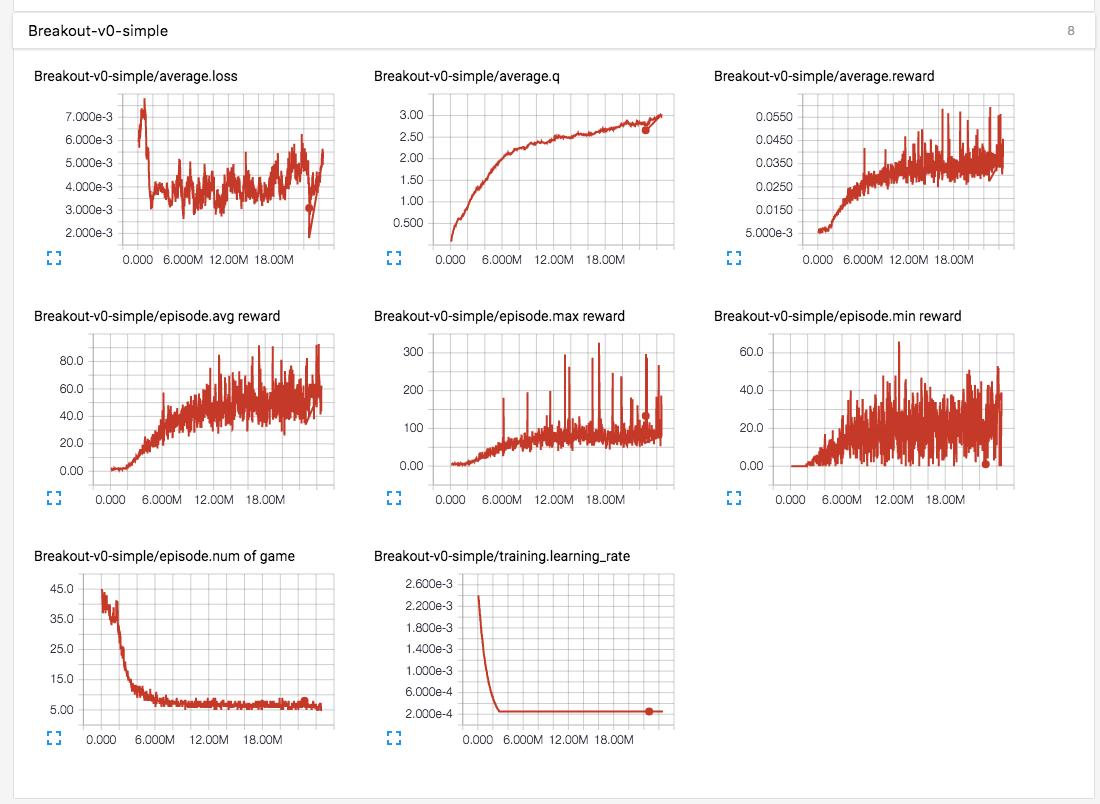
Details of Breakout with model m2(red) for 30 hours using GTX 980 Ti.
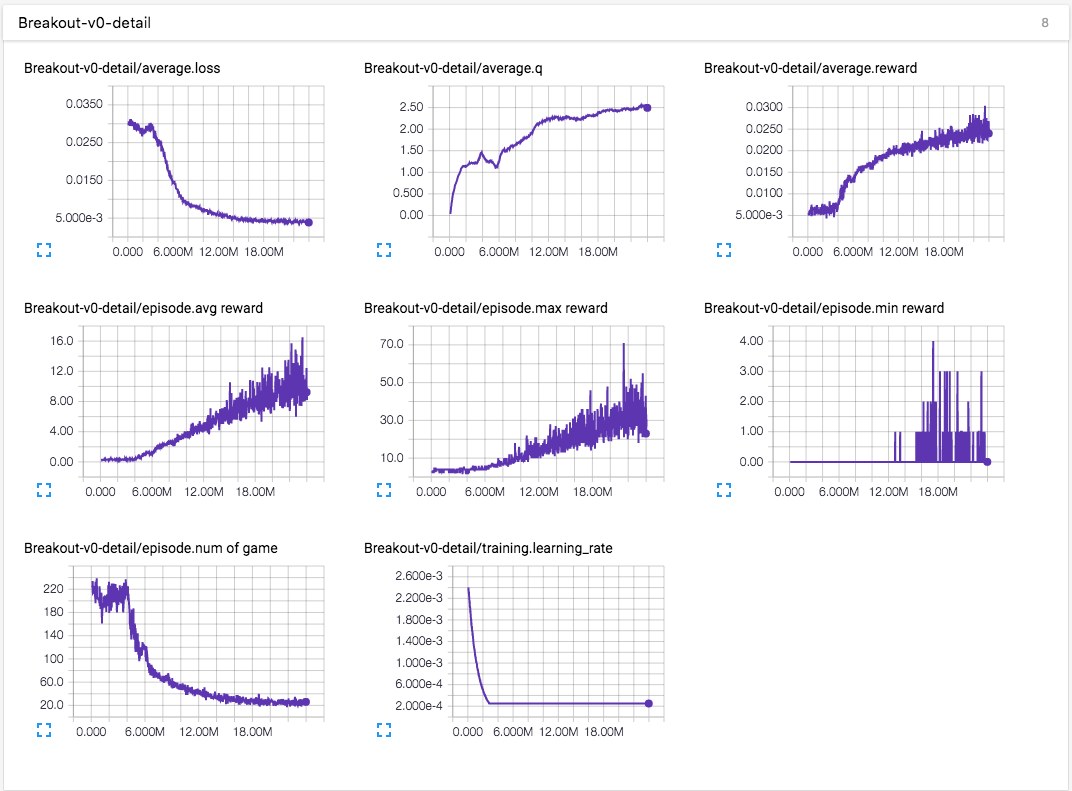
Details of Breakout with model m3(red) for 30 hours using GTX 980 Ti.
[1] Action-repeat (frame-skip) of 1, 2, and 4 without learning rate decay
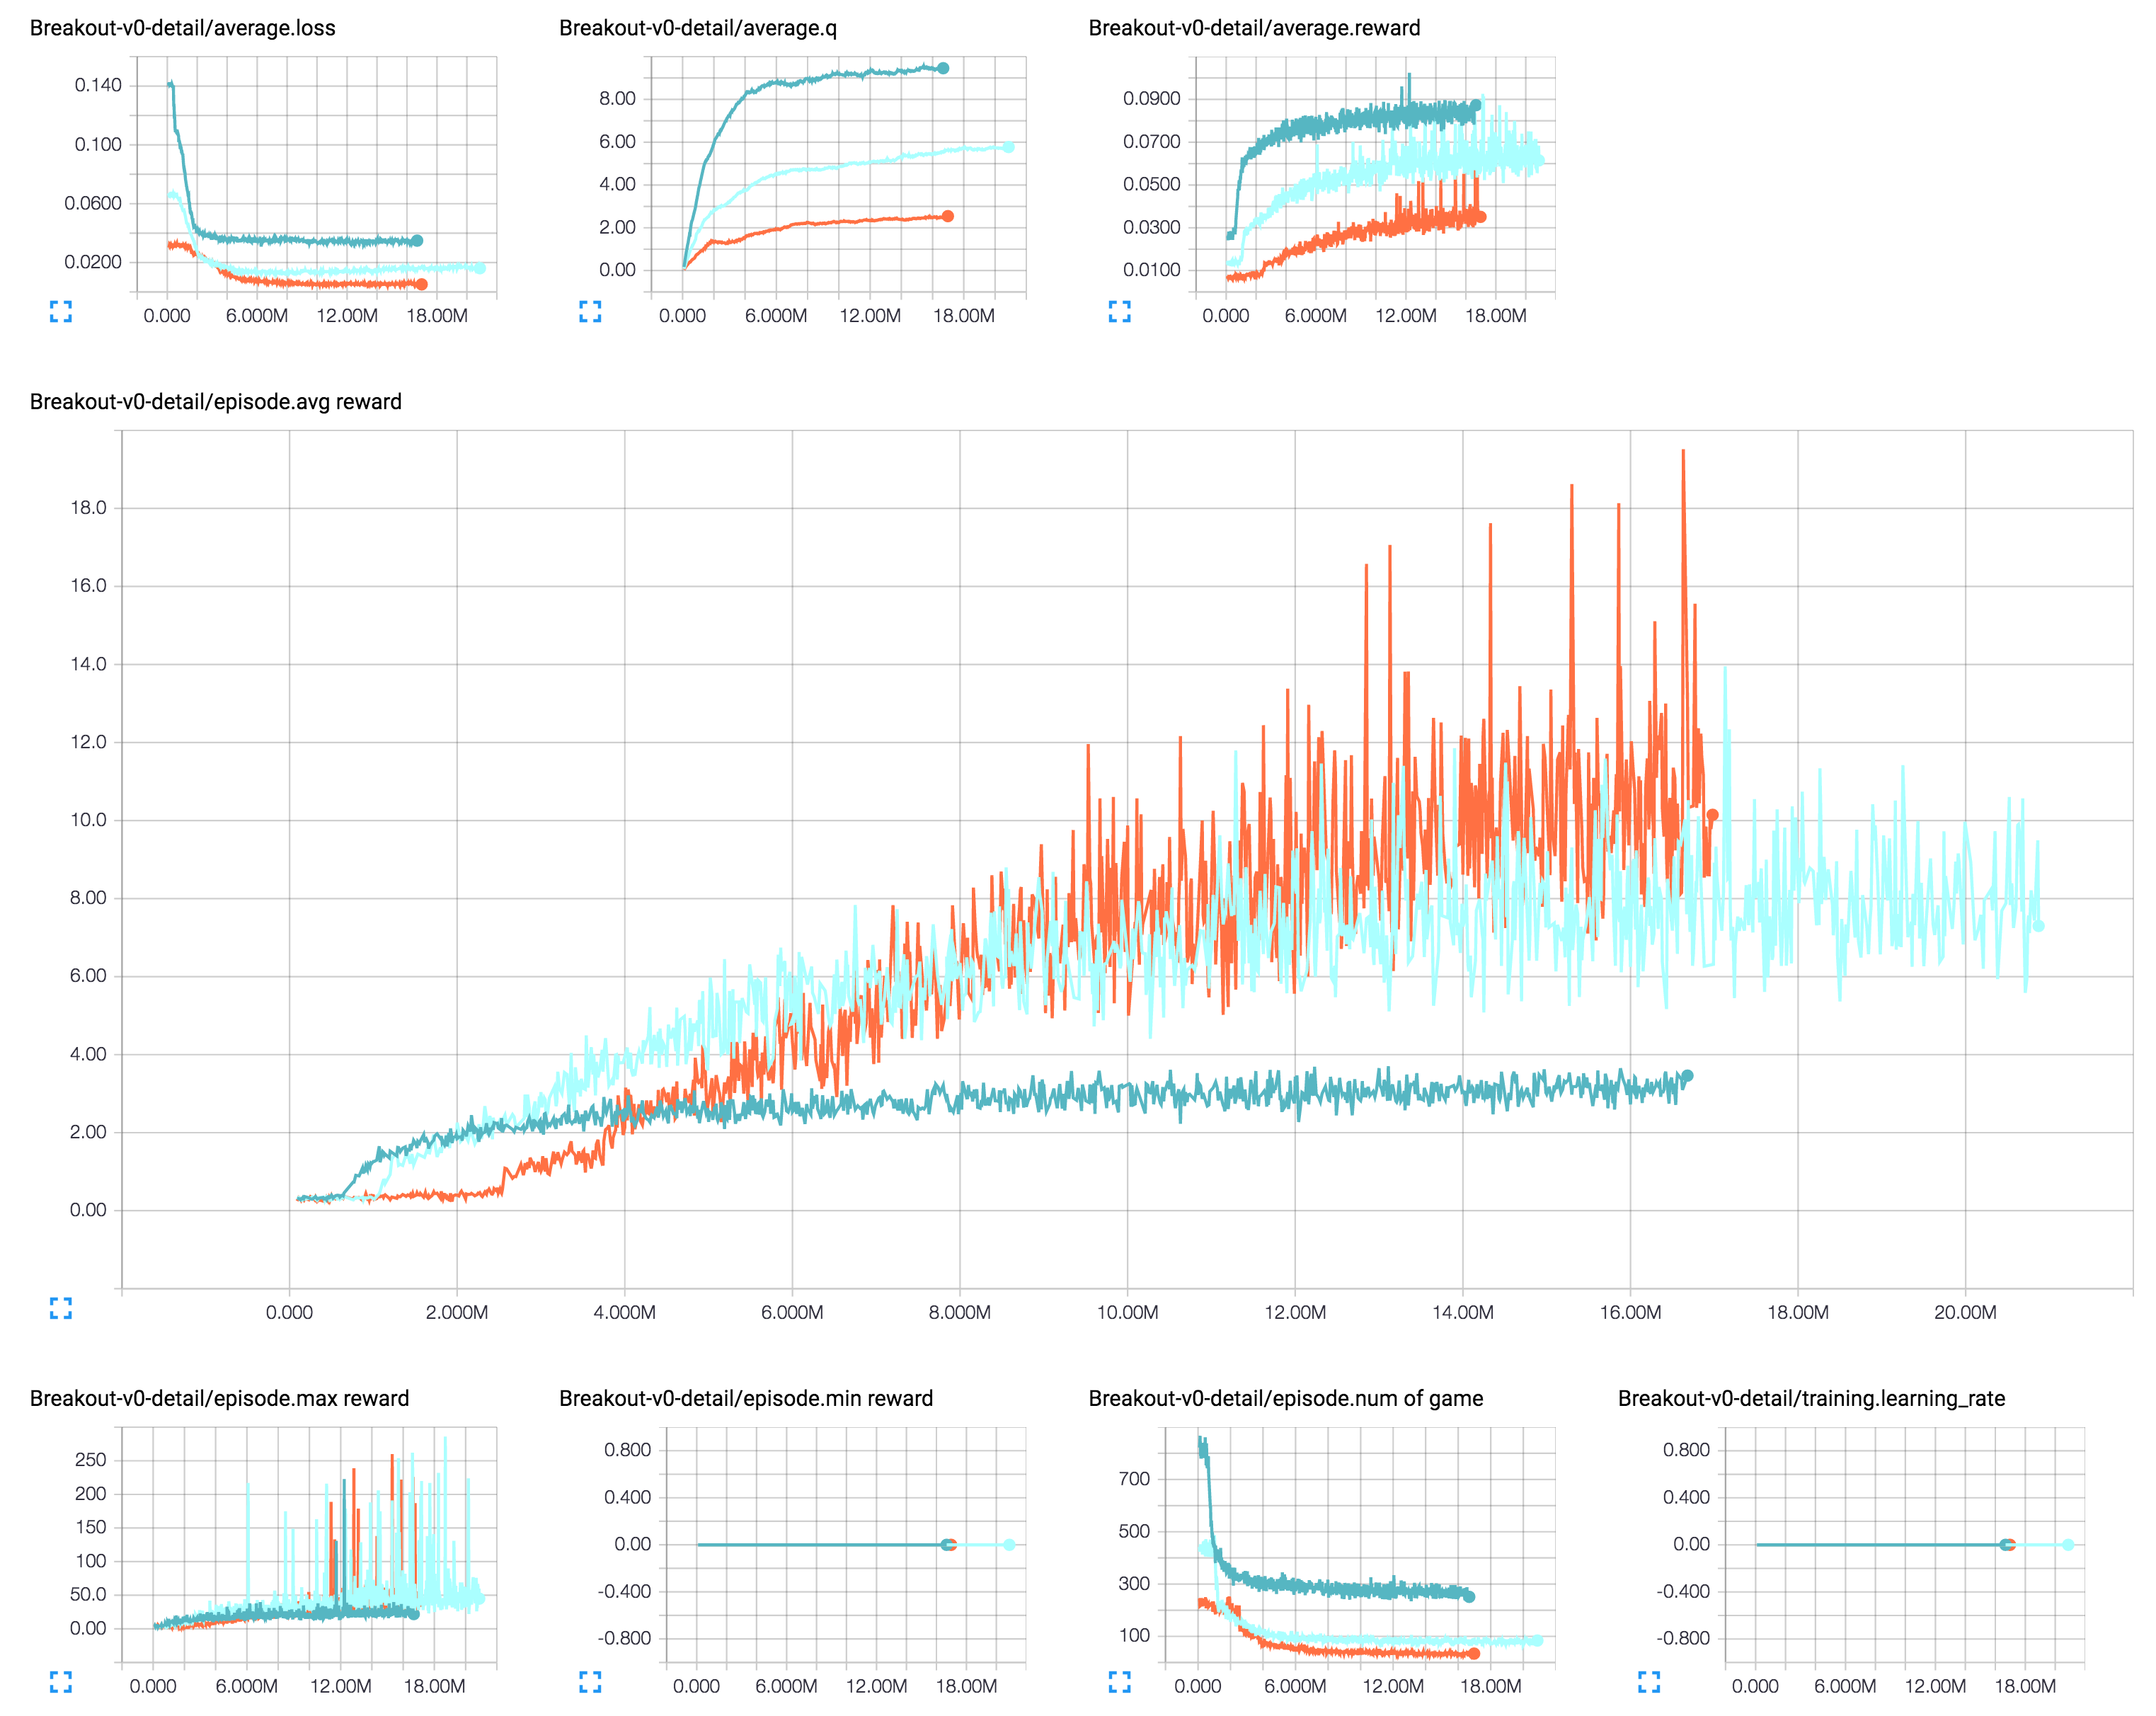
[2] Action-repeat (frame-skip) of 1, 2, and 4 with learning rate decay
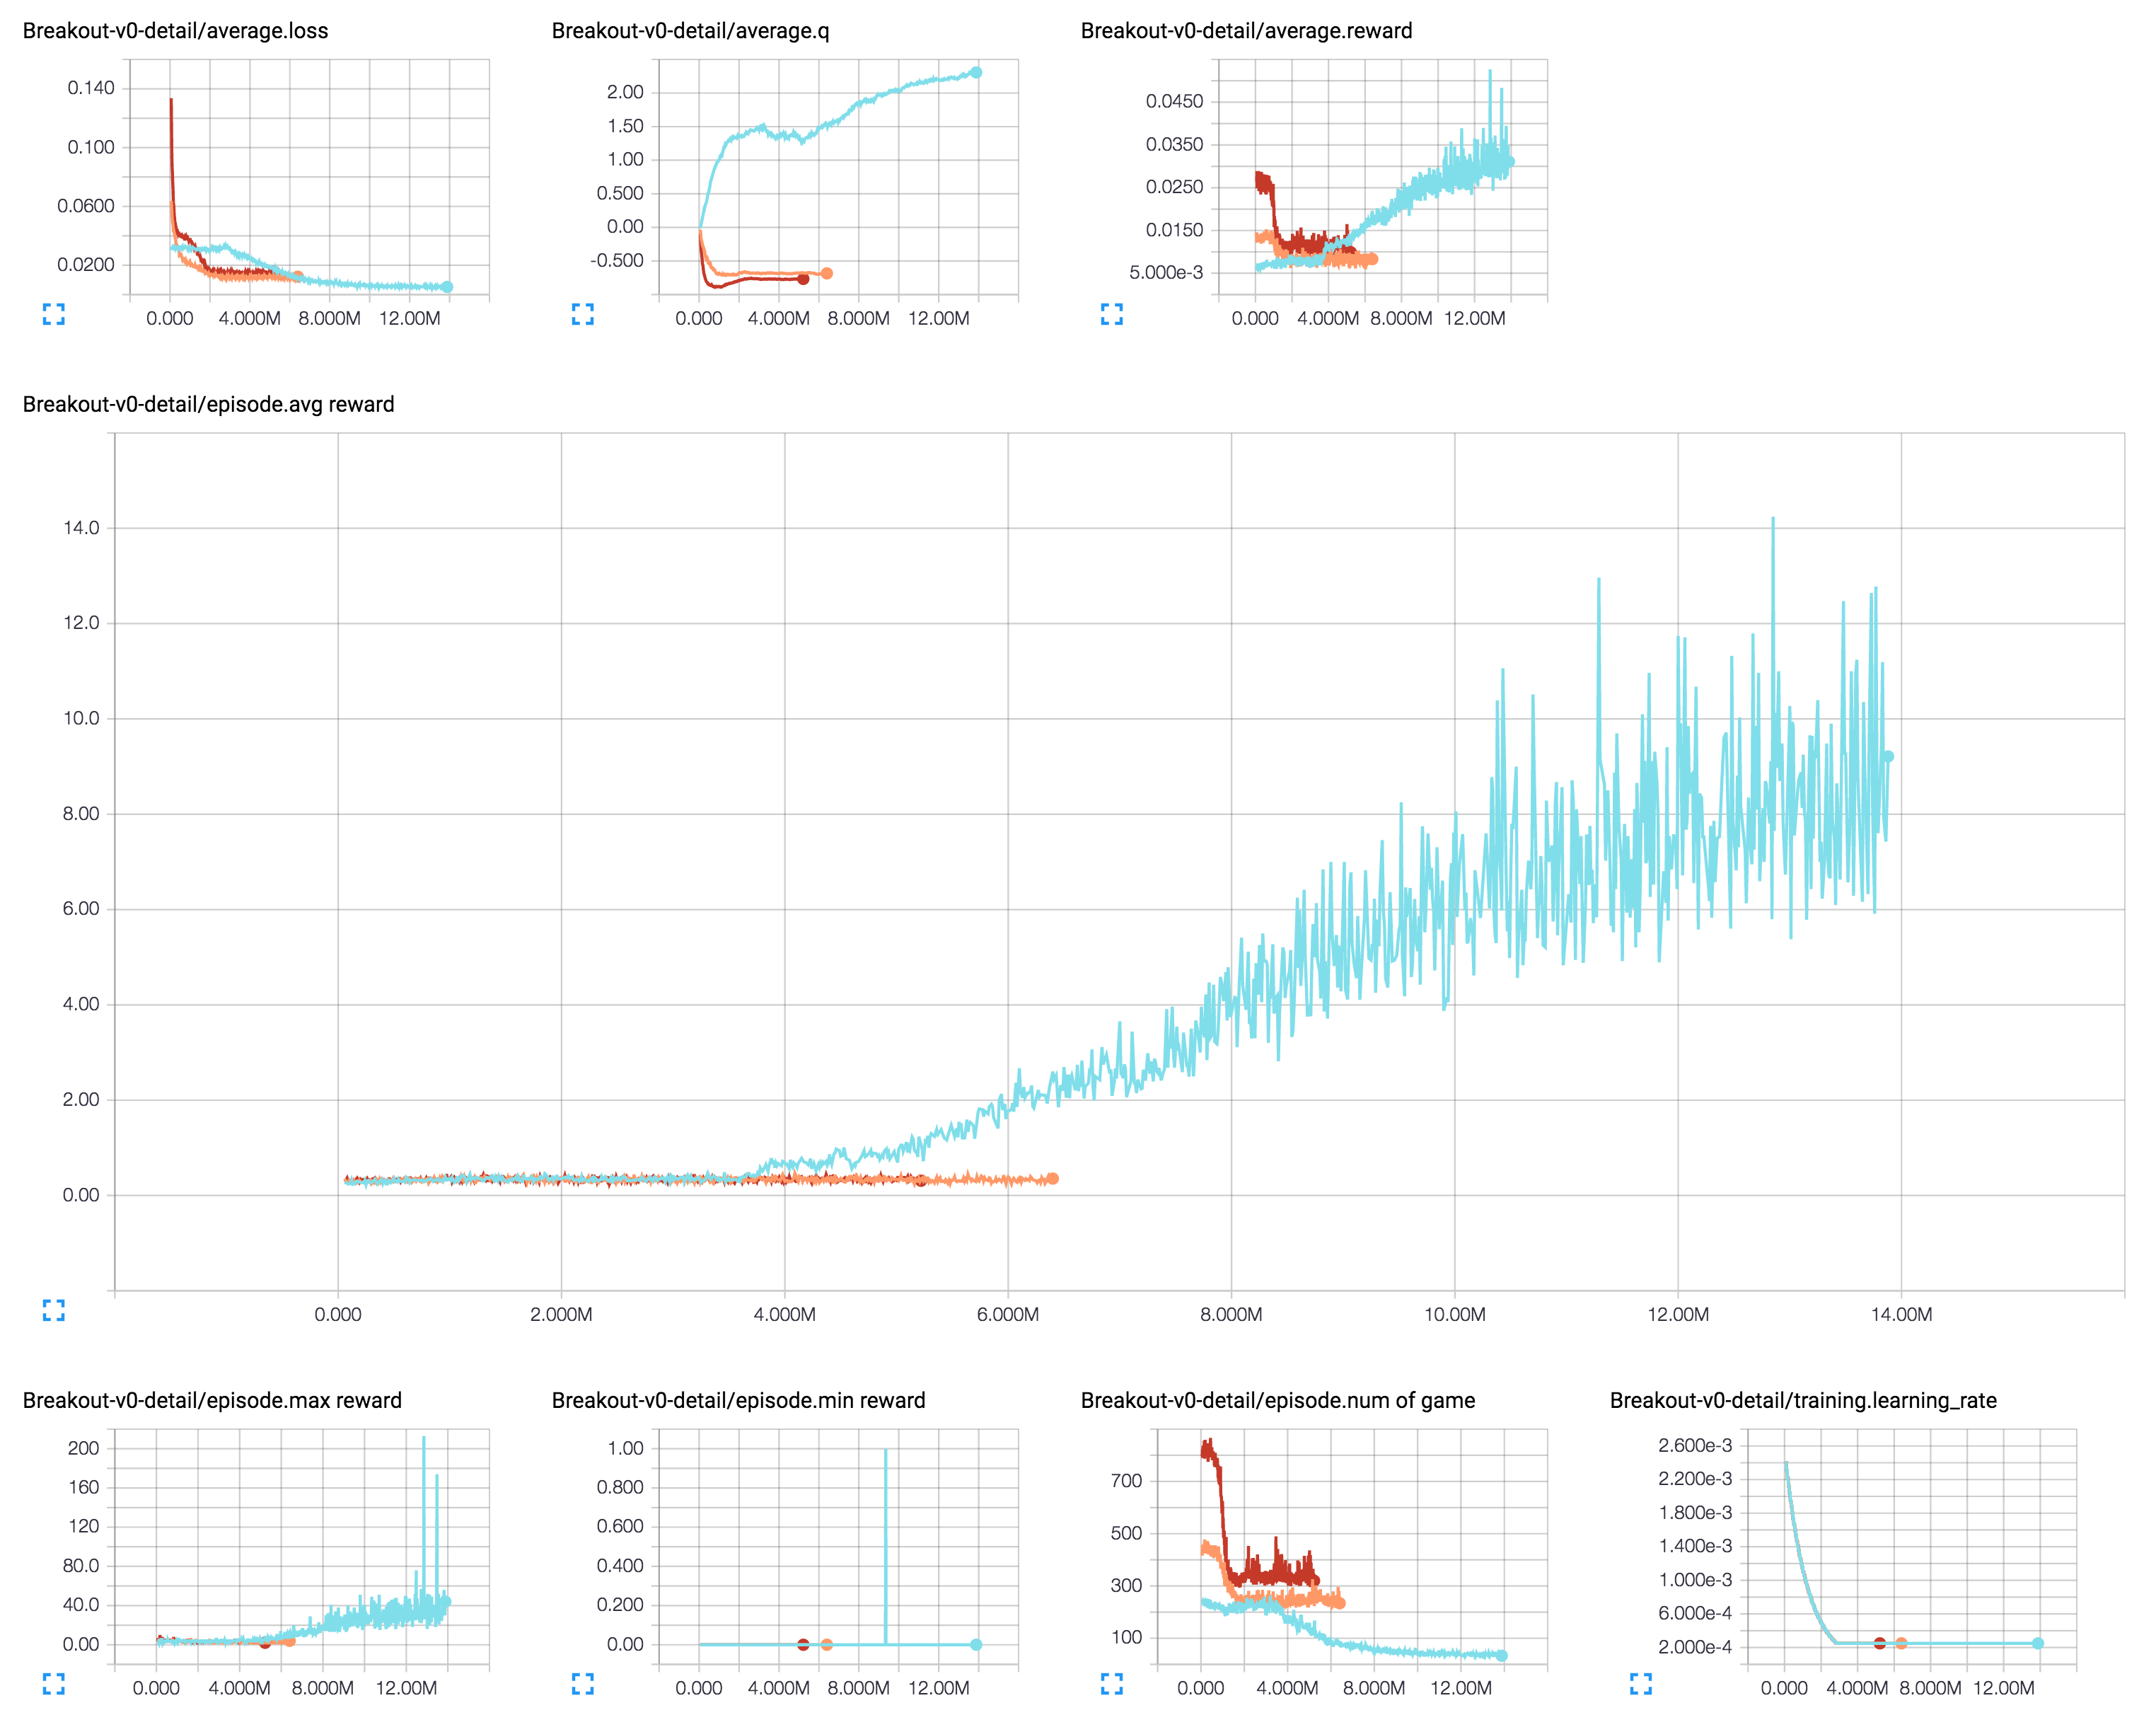
[1] & [2]
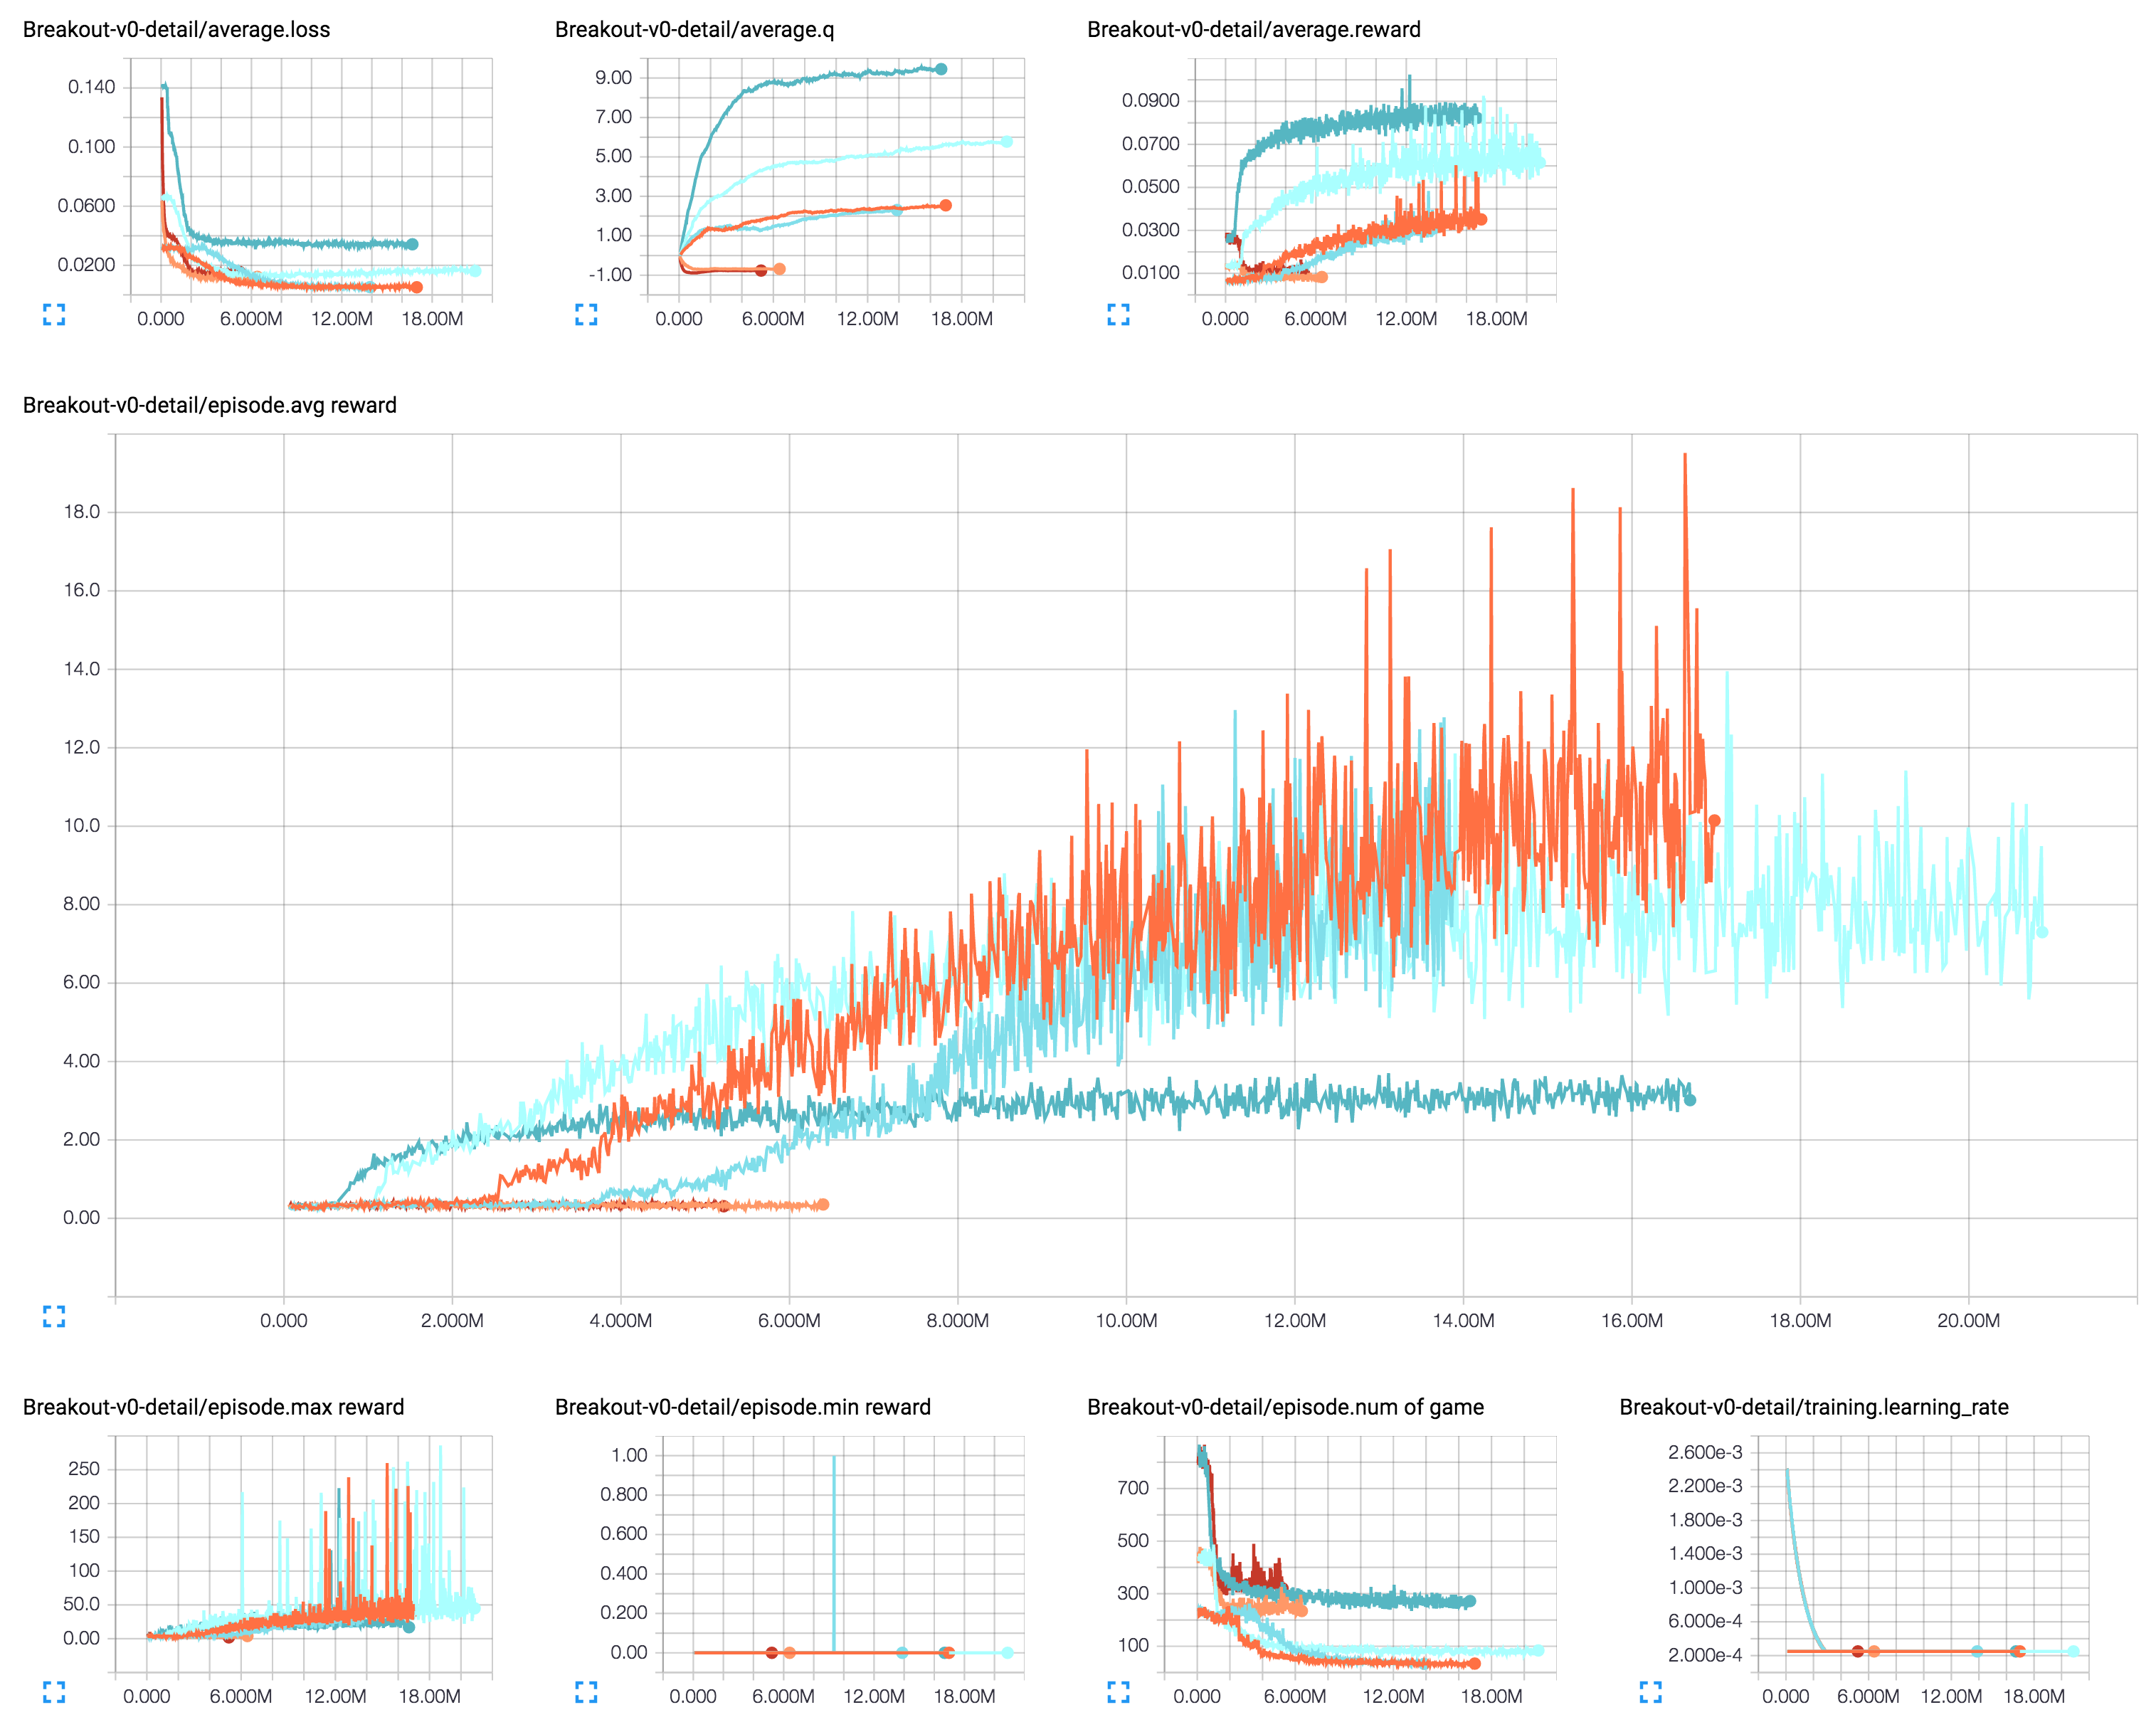
[3] Action-repeat of 4 for DQN (dark blue) Dueling DQN (dark green) DDQN (brown) Dueling DDQN (turquoise)
The current hyper parameters and gradient clipping are not implemented as it is in the paper.
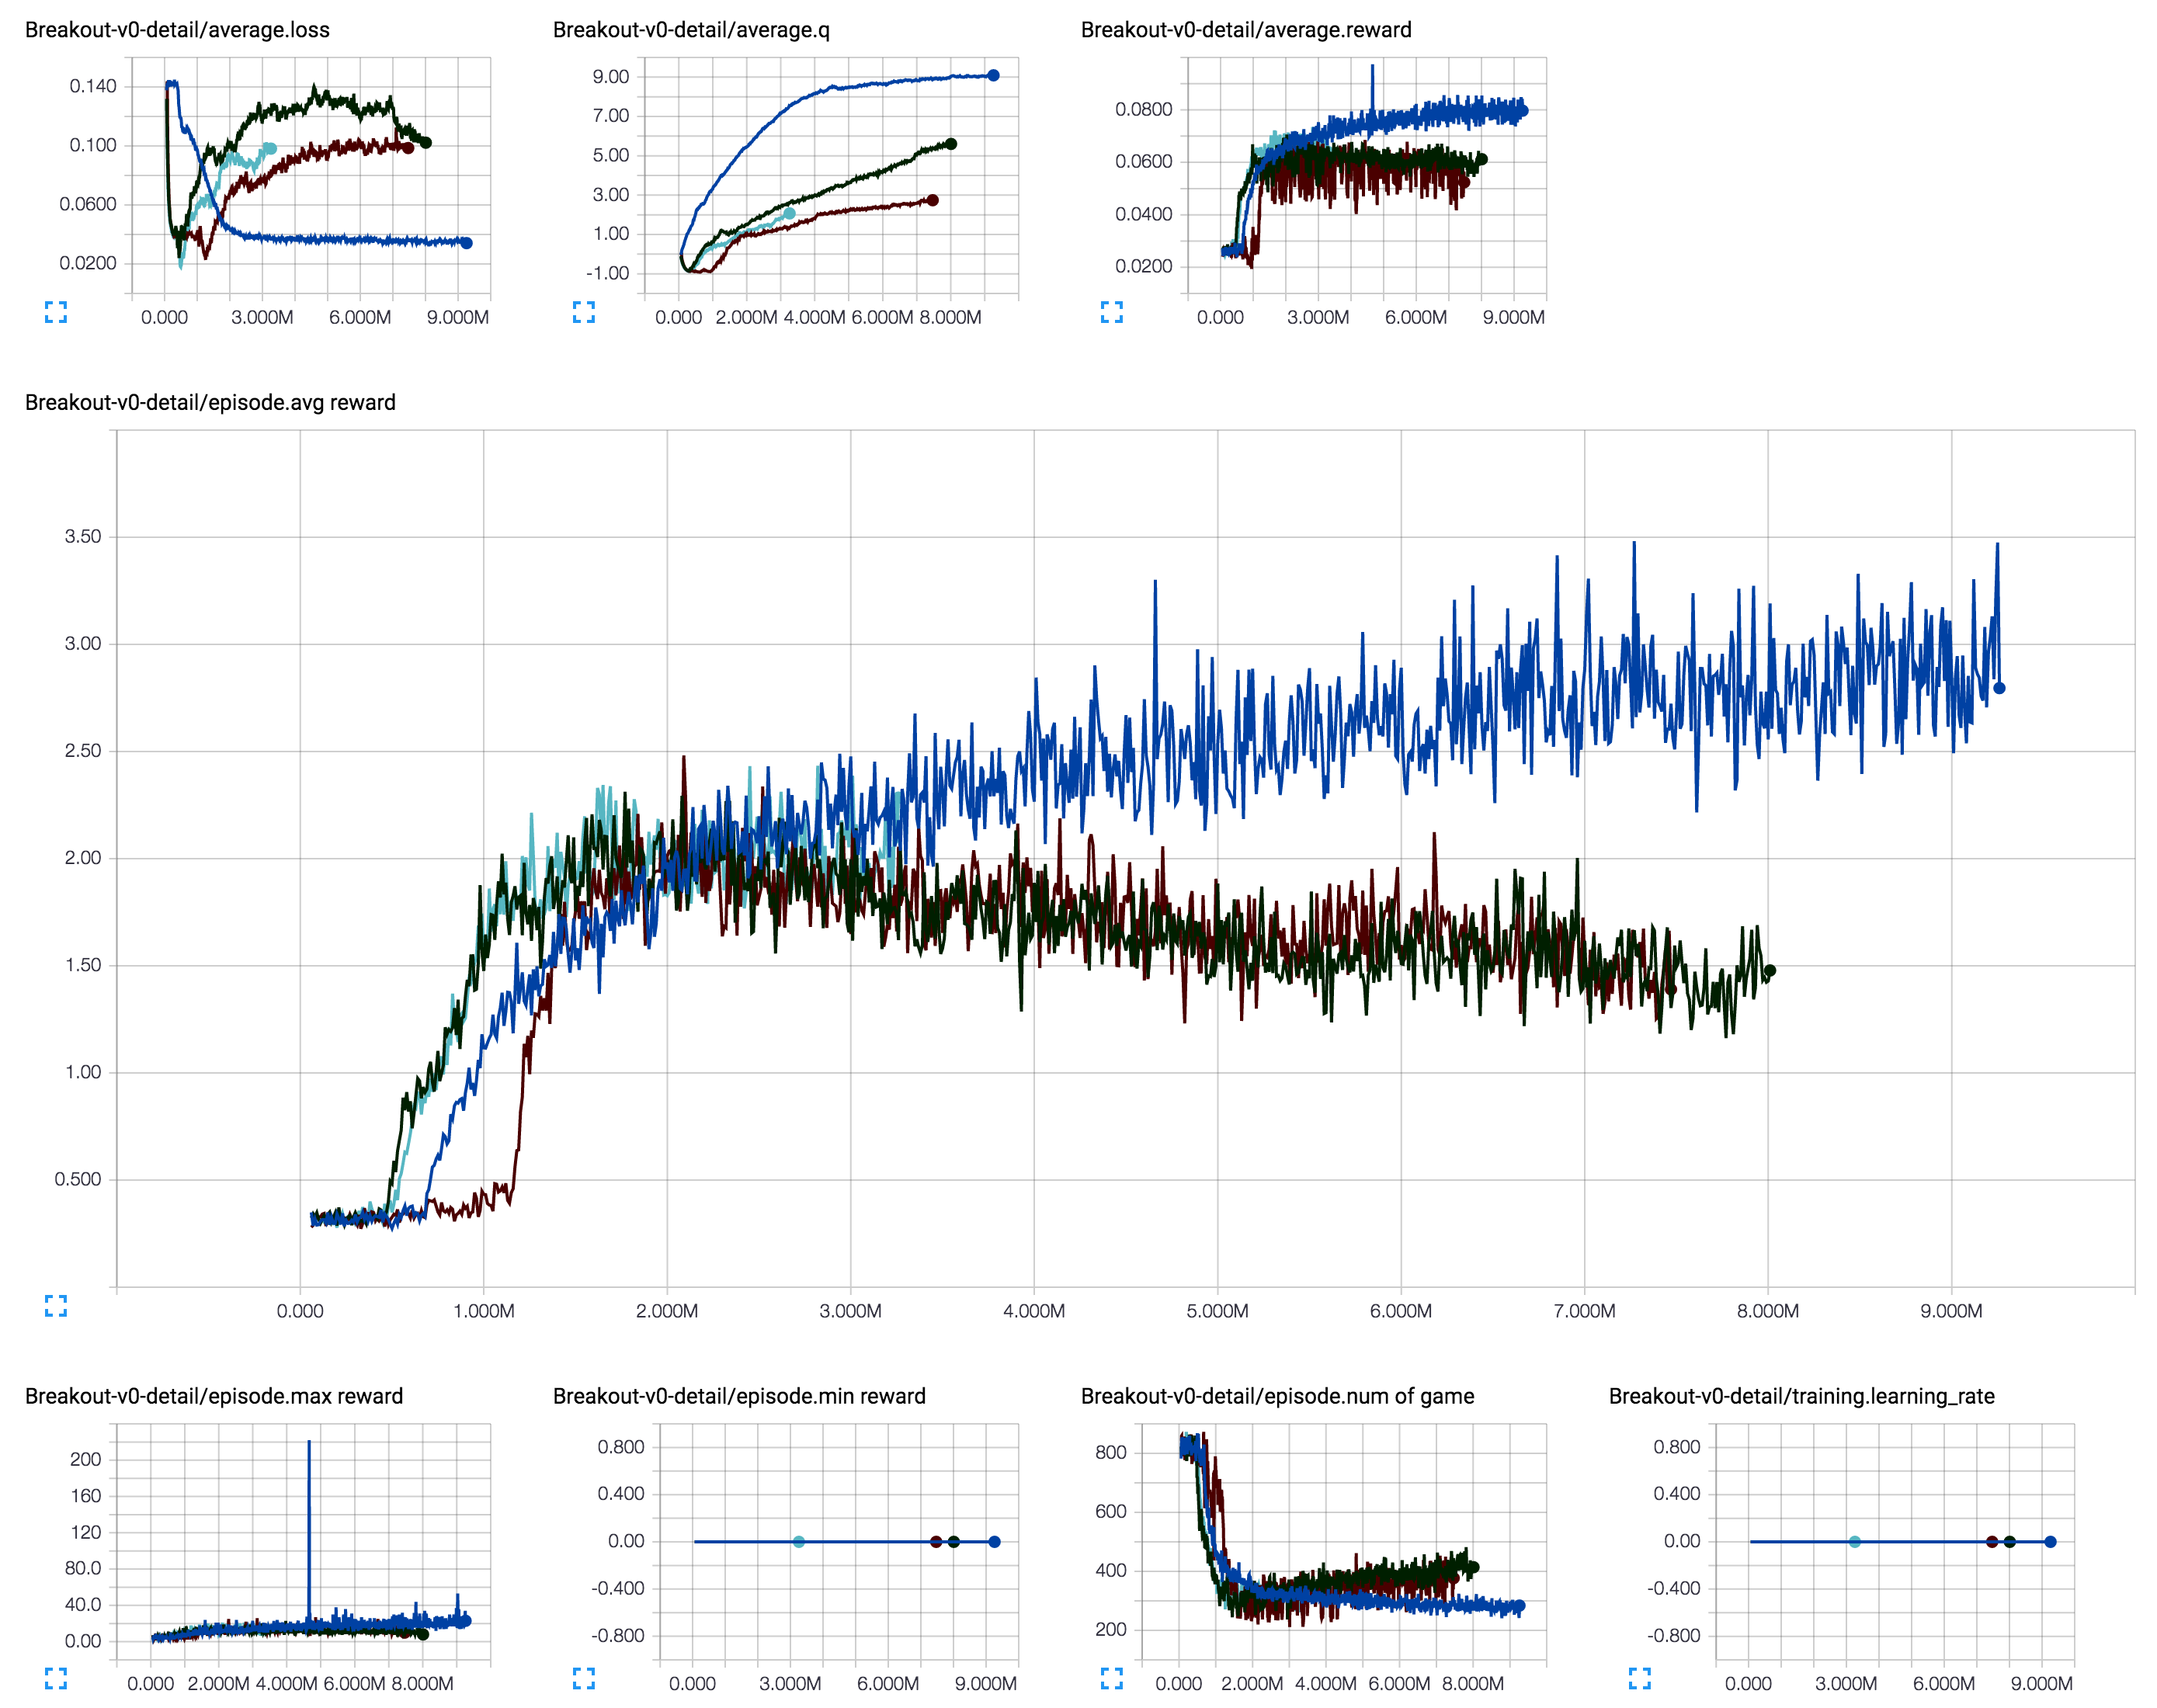
[4] Distributed action-repeat (frame-skip) of 1 without learning rate decay
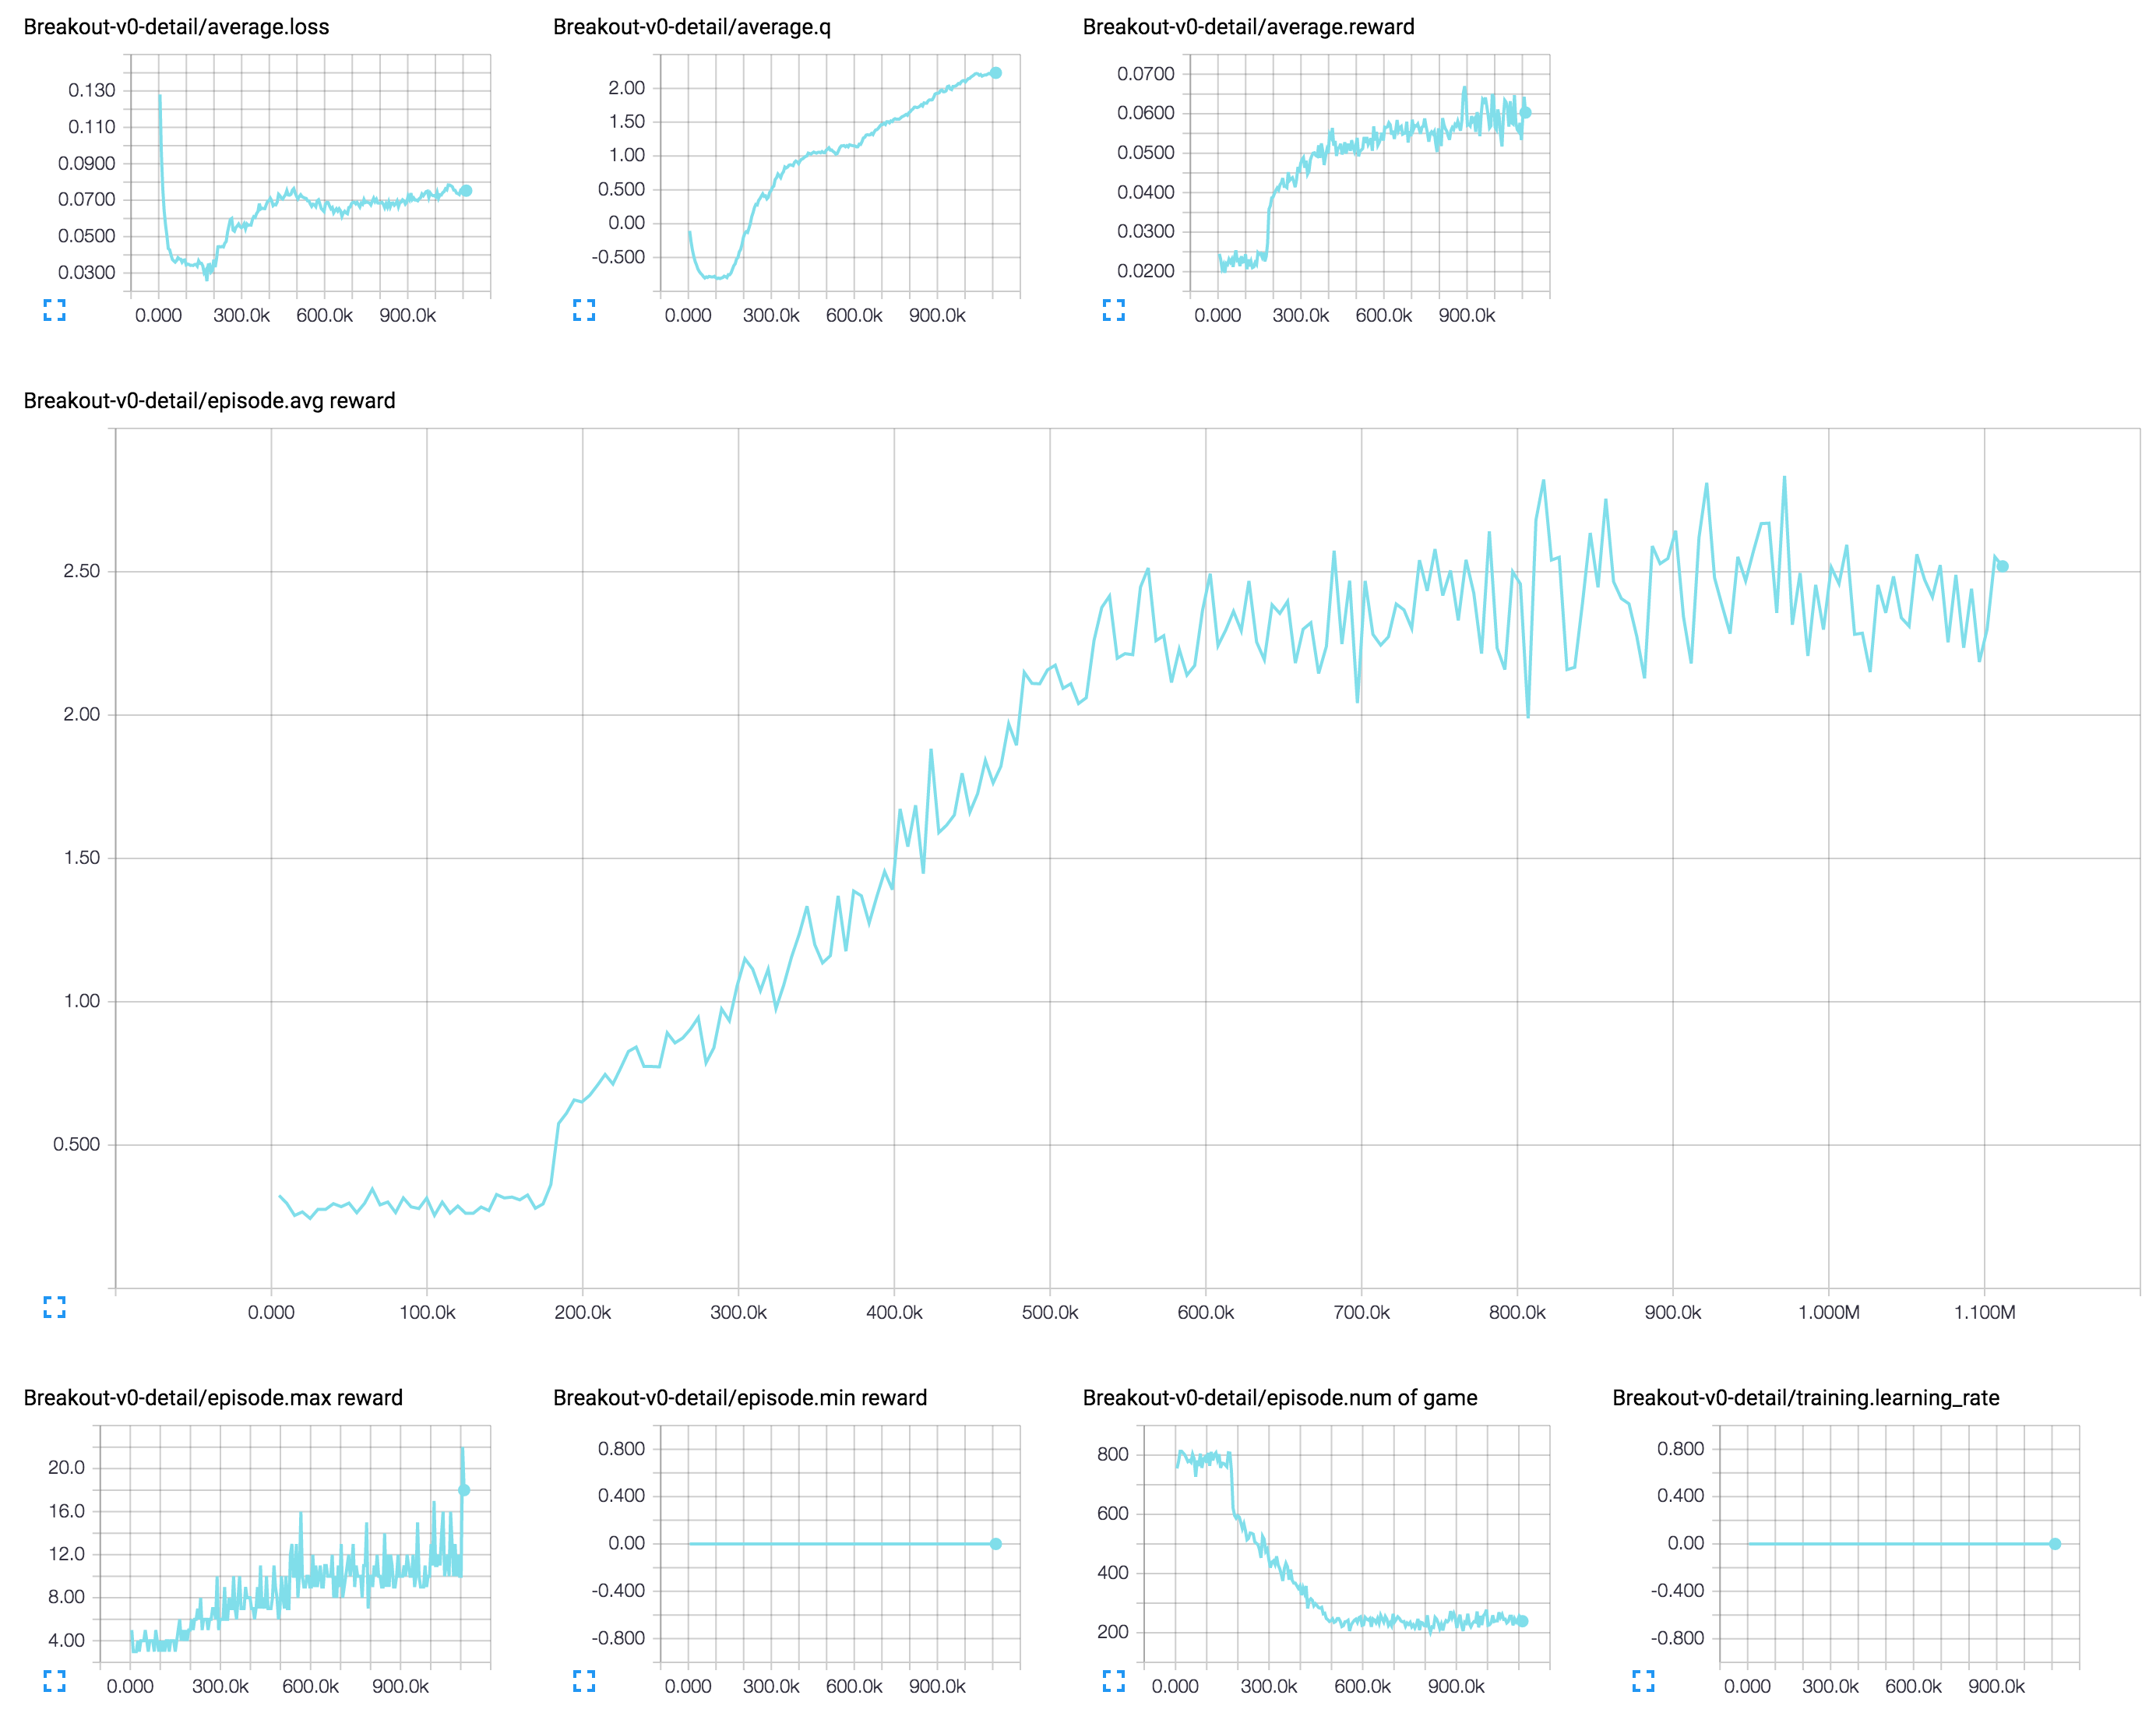
[5] Distributed action-repeat (frame-skip) of 4 without learning rate decay
MIT License.
35 followers · starred Jan 2017
65 followers · starred Aug 2018
49 followers · starred May 2018
167 followers · starred May 2016
Tensorflow implementation of Human-Level Control through Deep Reinforcement Learning
Python
2,589
99 commits
updated Apr 18, 2019
Tensorflow implementation of Human-Level Control through Deep Reinforcement Learning.
This implementation contains:
First, install prerequisites with:
$ pip install tqdm gym[all]
To train a model for Breakout:
$ python main.py --env_name=Breakout-v0 --is_train=True
$ python main.py --env_name=Breakout-v0 --is_train=True --display=True
To test and record the screen with gym:
$ python main.py --is_train=False
$ python main.py --is_train=False --display=True
Result of training for 24 hours using GTX 980 ti.
Details of Breakout with model m2(red) for 30 hours using GTX 980 Ti.
Details of Breakout with model m3(red) for 30 hours using GTX 980 Ti.
[1] Action-repeat (frame-skip) of 1, 2, and 4 without learning rate decay
[2] Action-repeat (frame-skip) of 1, 2, and 4 with learning rate decay
[1] & [2]
[3] Action-repeat of 4 for DQN (dark blue) Dueling DQN (dark green) DDQN (brown) Dueling DDQN (turquoise)
The current hyper parameters and gradient clipping are not implemented as it is in the paper.
[4] Distributed action-repeat (frame-skip) of 1 without learning rate decay
[5] Distributed action-repeat (frame-skip) of 4 without learning rate decay
MIT License.
35 followers · starred Jan 2017
65 followers · starred Aug 2018
49 followers · starred May 2018
167 followers · starred May 2016



