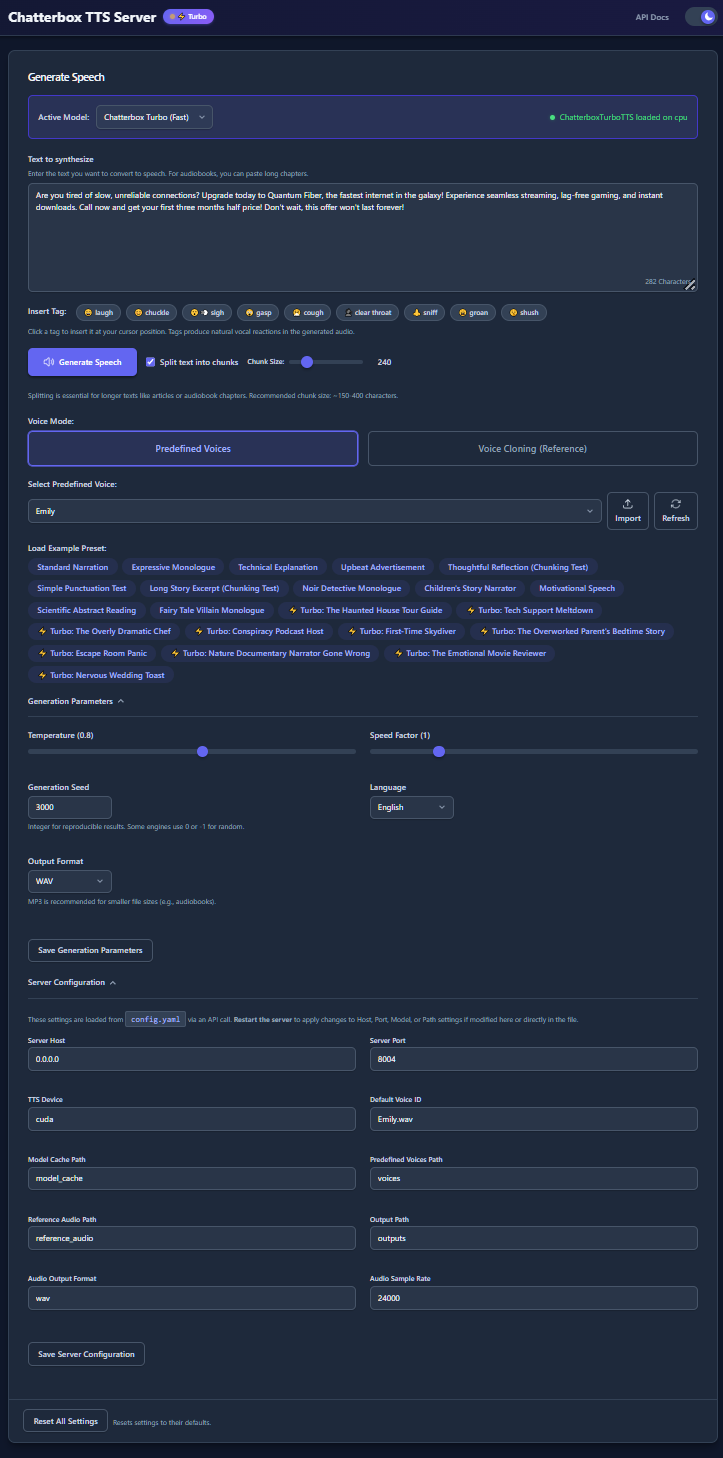
Self-host the powerful Chatterbox TTS model. This server offers a user-friendly Web UI, flexible API endpoints (incl. OpenAI compatible), predefined voices, voice cloning, and large audiobook-scale text processing. Runs accelerated on NVIDIA (CUDA), AMD (ROCm), and CPU.
Python
1,469
180 commits
updated May 26, 2026
Self-host Resemble AI's Chatterbox open-source TTS family (Original + Multilingual + Turbo) behind an OpenAI‑compatible API and a modern Web UI. The complete lineup includes the original high-quality model, multilingual support for 23 languages, and Chatterbox‑Turbo—a streamlined 350M-parameter model with dramatically improved throughput and native paralinguistic tags like [laugh], [cough], and [chuckle] for more expressive voice agents and narration. Features voice cloning, large text processing via intelligent chunking, audiobook generation, and consistent, reproducible voices using built-in ready-to-use voices and a generation seed feature.
🚀 Try it now! Test the full TTS server with voice cloning and audiobook generation in Google Colab - no installation required! To use it, please run cells 1 through 4 one at a time. After running cell 4, click on the "https://localhost:8004" link that appears in the output, and your web browser will open the UI from the .colab.dev domain. Read the instructions here.
This server is based on the architecture and UI of our Dia-TTS-Server project but uses the distinct chatterbox-tts engine. Runs accelerated on NVIDIA (CUDA), AMD (ROCm), and Apple Silicon (MPS) GPUs, with a fallback to CPU. Make sure you also check our Kitten-TTS-Server project.



📦 Portable Mode (Windows): This application supports a fully portable installation — the entire folder, including Python and all dependencies, is self-contained. Copy it to a USB drive, share it as a zip, or move it anywhere. Just double-click
start.bat— no Python installation needed on the target machine. Learn more →
v2.0 ships the complete Chatterbox family on every major GPU stack behind one OpenAI-compatible API and Web UI. The headline themes:
docker-compose-cu130.yml (CUDA 13.0, PyTorch 2.10). RTX 30/40/50 keep using cu121 / cu128.docker-compose-strixhalo.yml (ROCm 7.2, HSA_OVERRIDE_GFX_VERSION=11.0.0)./tts endpoint — opt-in stream: true parameter returns a StreamingResponse that flushes WAV bytes per chunk with 20 ms crossfades. Default behavior unchanged.TTS_BF16=on (or =auto) converts T3 to bfloat16 and runs under autocast for ~40% throughput on bf16-capable GPUs. Default off to preserve existing behavior on upgrade.ssl_certfile and ssl_keyfile in config.yaml for direct HTTPS without a reverse proxy./tts and /v1/audio/speech voice file parameters. Traversal attempts return HTTP 400./api/unload (release GPU memory without restart) and /v1/audio/voices (OpenAI-compatible voice listing).SUPPORTED_LANGUAGES exposed by the multilingual engine.See the v2.0.0 release notes for the full list with contributor credits.
start.bat — no Python installation required on the target machine.--portable to skip the prompt and install in portable mode directly, or --no-portable for a standard virtual environment.…calling you back [chuckle]….[laugh], [cough], and [chuckle], plus text-based prompting for reactions like sigh, gasp, and cough.ui/presets.yaml demonstrating paralinguistic prompting for agent-style scripts and expressive reads.You now have access to the entire Chatterbox lineup:
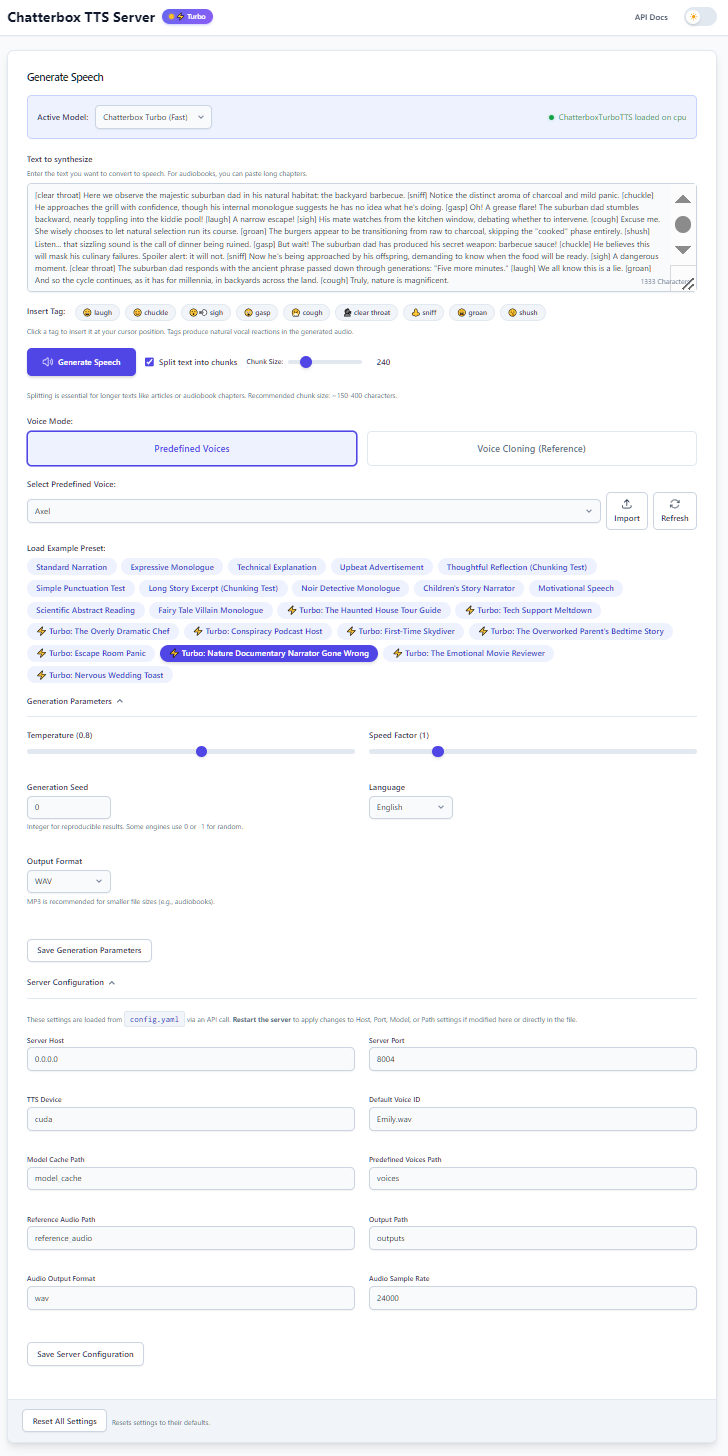
[laugh] and [cough] (350M parameters, 1-step diffusion)Switching models is effortless: Simply select your preferred model from the engine selector dropdown at the top of the Web UI. No restarts, no configuration changes required—just instant hot-swapping to test quality, speed, and language support across the complete Chatterbox family.
--no-deps across all installation paths (CPU, NVIDIA, cu128, ROCm). This eliminates ONNX source build failures, torch version conflicts, and CMake errors that affected many users. Chatterbox's dependencies (conformer, diffusers, transformers, s3tokenizer, etc.) are now listed explicitly in each requirements file with onnx==1.16.0 pinned to guarantee pre-built wheels.start.py for users of other chatterbox versions. Thanks to @jonas3245 (#93).Dockerfile.cpu based on python:3.10-slim instead of the 4GB+ NVIDIA CUDA base image. docker-compose-cpu.yml now uses this smaller image. Removed deprecated version tags from all docker-compose files.cuda to auto for correct auto-detection on all hardware (CUDA, MPS, CPU).requirements-nvidia-cu128.txt to properly install PyTorch 2.9.0 with CUDA 12.8 (sm_120 support) for RTX 5060 Ti, 5070, 5070 Ti, 5080, and 5090 GPUs. The Dockerfile.cu128 now correctly installs chatterbox with --no-deps to prevent PyTorch downgrade.torch==2.5.1+rocm6.1), which resolves the previous torch==2.6.0 / torchaudio==2.5.1 version conflict. A new requirements-rocm-init.txt installs the ROCm PyTorch stack before other dependencies. Both Dockerfile.rocm and start.py now use a two-step install to prevent pip from replacing ROCm torch wheels with CPU-only versions.--upgrade to update code + dependencies.--reinstall for a clean reinstall when environments get messy.The Chatterbox TTS model by Resemble AI provides capabilities for generating high-quality speech. This project builds upon that foundation by providing a robust FastAPI server that makes Chatterbox significantly easier to use and integrate.
🚀 Want to try it instantly? Launch the live demo in Google Colab - no installation needed!
The server expects plain text input for synthesis and we solve the complexity of setting up and running the model by offering:
[laugh], [cough], and [chuckle] for natural non-speech reactions inside the same generated voice.This server is your gateway to leveraging Chatterbox's TTS capabilities seamlessly, with enhanced stability, voice consistency, and large text support for plain text inputs.
🔥 Live Demo Available:
This server application enhances the underlying chatterbox-tts engine with the following:
🚀 Core Functionality:
[laugh], [cough], and [chuckle] directly in your text when using Chatterbox‑Turbo../voices directory..wav or .mp3).seed parameter to UI and API for influencing generation results. Using a fixed integer seed in combination with Predefined Voices or Voice Cloning helps maintain consistency./tts):
split_text, chunk_size), generation settings (temperature, exaggeration, CFG weight, seed, speed factor, language), and output format.config.yaml settings (server, model, paths) and save generation defaults.config.yaml for all runtime configuration, managed via config.py (YamlConfigManager). If config.yaml is missing, it's created with default values from config.py.parselmouth is installed) unvoiced segment removal to improve audio quality. These are configurable.config.yaml (ui_state section).🔧 General Enhancements:
start.bat / start.sh) - One-command setup with automatic hardware detection--upgrade and --reinstall commands--cpu, --nvidia, --nvidia-cu128, --rocm, --portable flagsChatterboxTTS.from_pretrained() for robust model loading from Hugging Face Hub, utilizing the standard HF cache.requirements.txt.utils.py for audio processing, text handling, and file management./tts) as the primary method for programmatic generation, exposing all key parameters./docs)./api/ui/initial-data also serves as a comprehensive status check).[laugh], [cough], [chuckle] and other expressive tags.split_text and chunk_size../voices directory.config.yaml).ui/presets.yaml..wav/.mp3 files.config.yaml) and default generation parameters directly in the UI.config.yaml.ChatterboxTTS.from_pretrained().config.yaml.download_model.py script available to pre-download specific model components to a local directory (this is separate from the main HF cache used at runtime).config.yaml.docker compose up -d).libsndfile1: Audio library needed by soundfile. Install via package manager (e.g., sudo apt install libsndfile1).ffmpeg: For robust audio operations (optional but recommended). Install via package manager (e.g., sudo apt install ffmpeg).| Hardware | Installation Option | Requirements File | Driver Requirement |
|---|---|---|---|
| CPU Only | --cpu | requirements.txt | None |
| NVIDIA RTX 20/30/40 | --nvidia | requirements-nvidia.txt | 525+ |
| NVIDIA RTX 5090 / Blackwell (sm_120) | --nvidia-cu128 | requirements-nvidia-cu128.txt (torch 2.9, CUDA 12.8) | 570+ |
| NVIDIA DGX Spark / GB10 (sm_121) | Docker only | requirements-nvidia-cu130.txt (torch 2.10, CUDA 13.0) | 580+ |
| AMD RX 6000/7000 (Linux) | --rocm | requirements-rocm.txt | ROCm 6.4+ |
| AMD Strix Halo (Ryzen AI MAX+) | Docker only | requirements-strixhalo.txt (ROCm 7.2) | ROCm 7.2+ |
| AMD RX 9000 series / RDNA4 (Linux) | Docker only | requirements-rdna4-init.txt (ROCm 7.2) | ROCm 7.2+ |
| Apple Silicon (M1/M2/M3/M4) | Manual install | See Option 4 | macOS 12.3+ |
This project uses specific dependency files to ensure a smooth installation for your hardware. You can choose between the automated launcher (recommended for most users) or manual installation (for advanced users).
1. Clone the Repository
git clone https://github.com/devnen/Chatterbox-TTS-Server.git
cd Chatterbox-TTS-Server
The automated launcher handles virtual environment creation, hardware detection, dependency installation, and server startup - all in one step.
# Double-click start.bat or run from command prompt:
start.bat
# Make the launcher executable and run it
chmod +x start.sh
./start.sh
--portable to skip this prompt or --no-portable for a standard virtual environment.══════════════════════════════════════════════════════════════
Hardware Detection
══════════════════════════════════════════════════════════════
NVIDIA GPU: Detected (NVIDIA GeForce RTX 4090)
AMD GPU: Not detected
══════════════════════════════════════════════════════════════
Select Installation Type
══════════════════════════════════════════════════════════════
[1] CPU Only
No GPU acceleration - works on any system
[2] NVIDIA GPU (CUDA 12.1) [DEFAULT]
Standard for RTX 20/30/40 series
[3] NVIDIA GPU (CUDA 12.8)
For RTX 5090 / Blackwell GPUs only
[4] AMD GPU (ROCm 6.4)
For AMD GPUs on Linux
Enter choice [2]:
| Option | Description |
|---|---|
--reinstall or -r | Remove existing installation and reinstall fresh (shows menu) |
--upgrade or -u | Upgrade to latest version (keeps current hardware selection) |
--cpu | Install CPU-only version (skip menu) |
--nvidia | Install NVIDIA CUDA 12.1 version (skip menu) |
--nvidia-cu128 | Install NVIDIA CUDA 12.8 version for RTX 5090/Blackwell (skip menu) |
--rocm | Install AMD ROCm version (skip menu) |
--portable | Use portable Python environment on Windows (skip prompt) |
--no-portable | Use standard virtual environment on Windows (skip prompt) |
--verbose or -v | Show detailed installation output |
--help or -h | Show help message |
Examples:
# Skip menu and install NVIDIA CUDA 12.1 directly
python start.py --nvidia

# Reinstall with fresh dependencies
python start.py --reinstall

# Upgrade to latest version (keeps your hardware selection)
python start.py --upgrade

```bash
# Install with verbose output for troubleshooting
python start.py --reinstall --nvidia --verbose

# Install in portable mode (Windows) - skip prompt
python start.py --portable

# Switch from standard to portable mode
python start.py --reinstall --portable

# Force standard virtual environment (skip portable prompt)
python start.py --no-portable
#### Subsequent Runs

After the first installation, simply run the launcher again to start the server:

```bash
# Windows
start.bat

# Linux/macOS
./start.sh
The launcher detects the existing installation and starts the server directly without reinstalling.
On Windows, the launcher offers Portable Mode — a fully self-contained installation where the entire project folder, including its own private Python runtime and all dependencies, lives in one place. Unlike standard Python virtual environments (which use hardcoded absolute paths and break when moved), the portable installation uses only relative paths and works from any location.
Once the first-time setup completes, the entire project folder can be:
start.bat, and it runs.The recipient doesn't need Python installed, doesn't need to run any setup, and doesn't need an internet connection to launch the server (see note about models below).
The TTS models (~2+ GB) are downloaded from Hugging Face Hub into a separate cache folder the first time the server starts on any machine. This is a one-time download per machine, independent of the portable application folder.
If you're sharing a portable installation, the recipient will need an internet connection for this initial model download on their first run. To pre-include models in the portable package, you can set the model_cache path in config.yaml to a folder inside the project directory, then include it when sharing.
During first-time setup on Windows, the launcher offers a choice:
python_embedded/ environment inside the project folder using Python 3.10. Any system Python 3.10+ can bootstrap this process, but the embedded runtime is always Python 3.10.venv/). Requires system Python 3.10 — Python 3.11+ will fail due to missing pre-built wheels for key dependencies.If your system Python is 3.11+, Portable Mode is required on Windows because it uses an embedded Python 3.10 runtime, bypassing the dependency issues entirely.
You can skip the prompt entirely with command-line flags:
python start.py --portable — go straight to portable modepython start.py --no-portable — go straight to standard venvpython start.py --reinstall --portable — switch an existing installation to portable modePortable Mode is Windows-specific. On Linux and macOS, the standard virtual environment is used. Python 3.10 is required on all platforms — the dependency compatibility issues (missing wheels for torchvision, ONNX) affect all operating systems, not just Windows.
Portable Mode includes Python and all Python packages, but GPU drivers are not included. If the target machine has an NVIDIA GPU and you want GPU acceleration, the appropriate NVIDIA drivers must be installed on that machine. CPU mode works without any drivers.
How it works under the hood:
python310._pth file is patched to use relative paths (., .., Lib\site-packages). The .. entry resolves to the project root since python_embedded/ is always one level deep. This is what makes portability work — no absolute paths are written anywhere.activate.bat, no activate.ps1, no hardcoded paths. The launcher simply runs python_embedded/python.exe directly.pip via get-pip.py, explicitly installs setuptools (needed by the perth watermarking library at runtime), generates a sitecustomize.py for DLL search path configuration, and patches the TTS engine's watermarker initialization for resilience.start.bat batch file finds any system Python to launch start.py, which then detects the existing python_embedded/ directory and uses it — regardless of which system Python version invoked the launcher.For users who prefer manual control over the installation process.
2. Create a Python Virtual Environment
Using a virtual environment is crucial to avoid conflicts with other projects.
Windows (PowerShell):
python -m venv venv
.\venv\Scripts\activate
Linux (Bash):
python3 -m venv venv
source venv/bin/activate
Your command prompt should now start with (venv).
3. Choose Your Installation Path
Pick one of the following commands based on your hardware. This single command will install all necessary dependencies with compatible versions.
This is the most straightforward option and works on any machine without a compatible GPU.
# Make sure your (venv) is active
pip install --upgrade pip
pip install -r requirements.txt
pip install --no-deps git+https://github.com/devnen/chatterbox-v2.git@master
For users with NVIDIA GPUs. This provides the best performance for RTX 20/30/40 series.
Prerequisite: Ensure you have the latest NVIDIA drivers installed. Python 3.10 required (3.11+ is not supported — pre-built wheels for torchvision and ONNX are unavailable).
# Make sure your (venv) is active
pip install --upgrade pip
pip install -r requirements-nvidia.txt
pip install --no-deps git+https://github.com/devnen/chatterbox-v2.git@master
After installation, verify that PyTorch can see your GPU:
python -c "import torch; print(f'PyTorch version: {torch.__version__}'); print(f'CUDA available: {torch.cuda.is_available()}'); print(f'Device name: {torch.cuda.get_device_name(0) if torch.cuda.is_available() else None}')"
If CUDA available: shows True, your setup is correct!
Note: Only use this if you have a Blackwell-based GPU (RTX 5060 Ti, 5070, 5070 Ti, 5080, 5090). For RTX 2000/3000/4000 series, use Option 2 above.
For users with NVIDIA Blackwell architecture GPUs that require CUDA 12.8 and sm_120 support.
Prerequisites:
Using Docker (Recommended for RTX 5090):
# Build and start with CUDA 12.8 support
docker compose -f docker-compose-cu128.yml up -d

# Access the web UI at http://localhost:8004
Manual Installation:
# Make sure your (venv) is active
pip install --upgrade pip

# Step 1: Install dependencies with PyTorch 2.9.0+cu128 (includes sm_120 support)
pip install -r requirements-nvidia-cu128.txt

# Step 2: Install chatterbox without dependencies (prevents PyTorch downgrade)
pip install --no-deps git+https://github.com/devnen/chatterbox-v2.git@master
⚠️ Critical: The --no-deps flag is required to prevent PyTorch from being downgraded to a version that doesn't support Blackwell GPUs.
After installation, verify that PyTorch supports sm_120:
python -c "import torch; print(f'PyTorch: {torch.__version__}'); print(f'CUDA: {torch.cuda.is_available()}'); print(f'GPU: {torch.cuda.get_device_name(0)}'); print(f'Architectures: {torch.cuda.get_arch_list()}')"
You should see sm_120 in the architectures list!
NVIDIA's Blackwell GPUs (RTX 5060 Ti, 5070, 5070 Ti, 5080, 5090) use compute capability sm_120. PyTorch 2.9.0 with CUDA 12.8 includes support for this architecture. Earlier versions (including CUDA 12.1) will fail with the error: CUDA error: no kernel image is available for execution on the device.
See README_CUDA128.md for detailed setup instructions and troubleshooting.
Note: Use this for NVIDIA DGX Spark / GB10 hardware (compute capability
sm_121). RTX 5090 stays on cu128 (Option 2b); RTX 30/40 stays on cu121 (Option 2).
For users on the very latest NVIDIA stack who need CUDA 13.0 and PyTorch 2.10.
Prerequisites:
Using Docker (recommended):
docker compose -f docker-compose-cu130.yml up -d

# Access the web UI at http://localhost:8004
The Dockerfile.cu130 installs PyTorch 2.10.0+cu130 with chatterbox-v2 via --no-deps so PyTorch is not downgraded.
For users with modern, ROCm-compatible AMD GPUs.
Prerequisite: Ensure you have the latest ROCm drivers installed on a Linux system.
# Make sure your (venv) is active
pip install --upgrade pip

# Step 1: Install ROCm PyTorch stack first
pip install -r requirements-rocm-init.txt

# Step 2: Install remaining dependencies
pip install -r requirements-rocm.txt

# Step 3: Install chatterbox without dependencies (prevents ROCm torch overwrite)
pip install --no-deps git+https://github.com/devnen/chatterbox-v2.git@master
⚠️ Critical: The --no-deps flag on chatterbox-tts is required to prevent pip from replacing the ROCm PyTorch wheels with CPU-only versions from PyPI. The start.py launcher handles this automatically.
After installation, verify that PyTorch can see your GPU:
python -c "import torch; print(f'PyTorch version: {torch.__version__}'); print(f'ROCm available: {torch.cuda.is_available()}'); print(f'Device name: {torch.cuda.get_device_name(0) if torch.cuda.is_available() else None}')"
If ROCm available: shows True, your setup is correct!
ROCm installation uses a two-step process:
requirements-rocm-init.txt installs PyTorch from the official ROCm 6.1 wheel index (torch==2.5.1+rocm6.1), ensuring you get AMD GPU-accelerated builds.requirements-rocm.txt installs remaining server dependencies without touching PyTorch.--no-deps to prevent pip's dependency resolver from replacing the ROCm torch with a CPU-only version.For APU/iGPU users: If you encounter "HIP error: invalid device function", you may need to set HSA_OVERRIDE_GFX_VERSION. See AMD ROCm Support Details below.
For users with Apple Silicon Macs (M1, M2, M3, M4, etc.).
Prerequisite: Ensure you have macOS 12.3 or later for MPS support.
Step 1: Install PyTorch with MPS support first
# Make sure your (venv) is active
pip install --upgrade pip
pip install torch torchvision torchaudio
Step 2: Configure the server to use MPS
Update your config.yaml to use MPS instead of CUDA:
tts_engine:
  device: mps  # Changed from 'cuda' to 'mps'
Step 3: Install remaining dependencies
# Install chatterbox-tts without its dependencies to avoid conflicts
pip install --no-deps git+https://github.com/devnen/chatterbox-v2.git@master

# Install core server dependencies
pip install fastapi 'uvicorn[standard]' librosa safetensors soundfile pydub audiotsm praat-parselmouth python-multipart requests aiofiles PyYAML watchdog unidecode inflect tqdm

# Install missing chatterbox dependencies
pip install conformer==0.3.2 diffusers==0.29.0 resemble-perth==1.0.1 transformers==4.46.3

# Install s3tokenizer without its problematic dependencies
pip install --no-deps s3tokenizer

# Install a compatible version of ONNX and audio codec
pip install onnx==1.16.0 descript-audio-codec
After installation, verify that PyTorch can see your GPU:
python -c "import torch; print(f'PyTorch version: {torch.__version__}'); print(f'MPS available: {torch.backends.mps.is_available()}'); print(f'Device will use: {\"mps\" if torch.backends.mps.is_available() else \"cpu\"}')"
If MPS available: shows True, your setup is correct!
Note: Use this for AMD Strix Halo APUs (Ryzen AI MAX+ 395 / "Ryzen AI Max" with integrated Radeon 8060S, GFX 11.5.0). Standard discrete Radeon GPUs use Option 3 (ROCm).
Prerequisites:
Using Docker (recommended):
docker compose -f docker-compose-strixhalo.yml up -d

# Access the web UI at http://localhost:8004
The compose file sets HSA_OVERRIDE_GFX_VERSION=11.0.0 and HSA_XNACK=1 so the ROCm 7.2 wheels work on Strix Halo's GFX 11.5.0 silicon, and enables TTS_BF16=on for the throughput win on this hardware.
Note: For AMD RDNA4 discrete GPUs (RX 9070, RX 9070 XT, Radeon AI PRO R9700, gfx1201). ROCm 6.1 wheels do not support gfx1201 — ROCm 7.2 is required. Standard discrete Radeon GPUs (RX 6000/7000) use Option 3.
Prerequisites:
video and render groups: sudo usermod -aG video,render $USERUsing Docker (recommended):
docker compose -f docker-compose-rdna4.yml up -d

# Access the web UI at http://localhost:8004
The compose file sets ROCBLAS_USE_HIPBLASLT=0 (required for stability on gfx1201) and enables TTS_BF16=on for throughput gain. gfx1201 is natively supported by ROCm 7.0+ — no HSA_OVERRIDE_GFX_VERSION needed.
Want to test Chatterbox TTS Server immediately without any installation?
Prefer local installation? Continue reading below for full setup instructions.
The server relies exclusively on config.yaml for runtime configuration.
config.yaml: Located in the project root. This file stores all server settings, model paths, generation defaults, and UI state. It is created automatically on the first run (using defaults from config.py) if it doesn't exist. This is the main file to edit for persistent configuration changes.config.yaml.Key Configuration Areas (in config.yaml or UI):
server: host, port, logging settings.model: repo_id (e.g., "ResembleAI/chatterbox").tts_engine: device ('auto', 'cuda', 'mps', 'cpu'), predefined_voices_path, reference_audio_path, default_voice_id.paths: model_cache (for download_model.py), output.generation_defaults: Default UI values for temperature, exaggeration, cfg_weight, seed, speed_factor, language.audio_output: format, sample_rate, max_reference_duration_sec.ui_state: Stores the last used text, voice mode, file selections, etc., for UI persistence.ui: title, show_language_select, max_predefined_voices_in_dropdown.debug: save_intermediate_audio.⭐ Remember: Changes made to server, model, tts_engine, or paths sections in config.yaml (or via the UI's Server Configuration section) require a server restart to take effect. Changes to generation_defaults or ui_state are applied dynamically or on the next page load.
Model selection: set model.repo_id to one of:
chatterbox (or original) — Original 0.5B English model with emotion exaggeration.chatterbox-turbo (or turbo) — 350M Turbo model with paralinguistic tags ([laugh], [cough], [chuckle]).chatterbox-multilingual (or multilingual) — 0.5B multilingual model with 23-language support.All three are hot-swappable from the Web UI engine dropdown without a server restart.
/tts (predefined_voice_id, reference_audio_filename) and /v1/audio/speech (voice) are sandboxed under their configured directories using utils.safe_resolve_within()..., absolute paths, symlinks pointing outside the sandbox) return HTTP 400 with no filesystem access. The fix addresses CWE-22 and shipped in v2.0.0.The server defaults are tuned for safety and broad compatibility. The following knobs trade safety for speed when you understand your hardware:
TTS_BF16=on (or =auto for "enable only if the GPU reports is_bf16_supported()") to convert T3 to bfloat16 and run generate() under autocast. Roughly 40% throughput on bf16-capable GPUs (RTX 30/40/50, A100, H100, Strix Halo). Default is off to preserve existing behavior on upgrade. Output is numerically slightly different from float32 but typically inaudible.(path, mtime, exaggeration) and is automatically cleared on reload_model() / /api/unload. No config needed.chunk_size parameter on /tts (50–500, default 120). Larger chunks = fewer requests but more VRAM per call. The chunker respects sentence boundaries either way.stream: true on /tts for long-form input (audiobooks, multi-paragraph content). See the API section above for the chunk-level caveat.server.ssl_certfile and server.ssl_keyfile in config.yaml for direct HTTPS without putting a reverse proxy in front.Important Note on Model Downloads (First Run):
The very first time you start the server, it needs to download the chatterbox-tts model files from Hugging Face Hub. This is an automatic, one-time process (per model version, or until your Hugging Face cache is cleared).
You can optionally use the python download_model.py script to pre-download specific model components to the ./model_cache directory defined in config.yaml. However, please note that the runtime engine (engine.py) primarily loads the model from the main Hugging Face Hub cache directly, not this specific local model_cache directory.
The easiest way to run the server is using the automated launcher:
Windows:
start.bat
Linux / macOS:
./start.sh
The launcher automatically:
If you prefer to start the server manually:
Steps to Run:
source venv/bin/activate.\venv\Scripts\activatepython server.py
http://localhost:PORT (e.g., http://localhost:8004 if your configured port is 8004).http://localhost:PORT/docs for interactive API documentation.CTRL+C in the terminal where the server is running.
## 🔄 Updating to the Latest Version

Follow these steps to update your local installation to the latest version from GitHub. This guide provides multiple methods: using the automated launcher, the recommended `git stash` workflow, and a manual backup alternative. All methods preserve your local `config.yaml`.

**First, Navigate to Your Project Directory**

Before starting, open your terminal and go to the project folder.

```bash
cd Chatterbox-TTS-Server
The launcher provides simple upgrade functionality that handles everything automatically.
Upgrade (keeps your hardware selection):
# First, pull the latest code
git pull origin main

# Then upgrade dependencies using the launcher
# Windows
python start.py --upgrade

# Linux/macOS
python3 start.py --upgrade
Full Reinstall (choose new hardware option):
git pull origin main

# Windows
python start.py --reinstall

# Linux/macOS
python3 start.py --reinstall
The --upgrade flag preserves your current hardware selection (CPU, NVIDIA, etc.) and reinstalls dependencies.
The --reinstall flag removes the existing installation completely and shows the hardware selection menu again.
Changing Hardware Configuration:
To switch to a different hardware configuration (e.g., from CPU to NVIDIA, or from CUDA 12.1 to CUDA 12.8):
# Shows menu to select new hardware
python start.py --reinstall

# Or specify directly
python start.py --reinstall --nvidia
python start.py --reinstall --nvidia-cu128
python start.py --reinstall --cpu
python start.py --reinstall --rocm
If you installed manually without using the launcher, this is the standard and safest way to update using Git. It automatically handles your local changes (like to config.yaml) without needing to manually copy files.
First, activate your virtual environment:
# On Windows (PowerShell):
.\venv\Scripts\activate

# On Linux (Bash):
source venv/bin/activate
Step 1: Stash Your Local Changes This command safely stores your modifications on a temporary "shelf."
git stash
Step 2: Pull the Latest Version Now that your local changes are safely stored, you can download the latest code from GitHub.
git pull origin main
Step 3: Re-apply Your Changes This command takes your changes from the shelf and applies them back to the updated code.
git stash pop
Your config.yaml will now have your settings, and the rest of the project files will be up-to-date. You can now proceed to the "Final Steps" section below.
This method involves manually backing up and restoring your configuration file.
First, activate your virtual environment:
# On Windows (PowerShell):
.\venv\Scripts\activate

# On Linux (Bash):
source venv/bin/activate
Step 1: Backup Your Configuration
⚠️ Important: Create a backup of your config.yaml to preserve your custom settings.
# Create a backup of your current configuration
cp config.yaml config.yaml.backup
Step 2: Update the Repository Choose one of the following commands based on your needs:
git pull origin main
config.yaml, you may need to resolve them manually.# Fetch latest changes and reset to match remote exactly
git fetch origin
git reset --hard origin/main
Step 3: Restore Your Configuration
# Restore your backed-up configuration
cp config.yaml.backup config.yaml
Now, proceed to the "Final Steps" section.
After you have updated the code using Method 2 or 3, complete these final steps.
1. Check for New Configuration Options
⭐ Recommended: Compare your restored config.yaml with the new default config to see if there are new options you might want to adopt. The server will add new keys with default values, but you may want to review them.
2. Update Dependencies
⭐ Important: After pulling new code, always update the dependencies to ensure you have the correct versions. Choose the command that matches your hardware:
pip install -r requirements.txt
pip install -r requirements-nvidia.txt
pip install -r requirements-nvidia-cu128.txt
pip install --no-deps git+https://github.com/devnen/chatterbox-v2.git@master
pip install -r requirements-rocm.txt
3. Restart the Server
If the server was running, stop it (CTRL+C) and restart it to apply all the updates.
python server.py
⭐ Note: Your custom settings in config.yaml are preserved with this method. The server will automatically add any new configuration options with default values if needed. You can safely delete config.yaml.backup once you've verified everything works correctly.
⭐ Docker Users: If using Docker and you have a local config.yaml mounted as a volume, the same backup/restore process applies before running:
docker compose down
docker compose pull  # if using pre-built images
docker compose up -d --build
For RTX 5090 / Blackwell GPUs: Use the CUDA 12.8 configuration:
docker compose -f docker-compose-cu128.yml down
docker compose -f docker-compose-cu128.yml pull
docker compose -f docker-compose-cu128.yml up -d --build
http://localhost:PORT)The most intuitive way to use the server:
Predefined Voices: Select a curated voice from the ./voices directory.Voice Cloning: Select an uploaded reference file from ./reference_audio.ui/presets.yaml. New presets demonstrate Turbo's paralinguistic tags.config.yaml.config.yaml (requires server restart for some changes).When the engine selector is set to Chatterbox‑Turbo, you can include paralinguistic tags inline:
Hi there [chuckle] — thanks for calling back.
One moment… [cough] sorry about that. Let's get this fixed.
Turbo supports native tags like [laugh], [cough], and [chuckle] for more realistic, expressive speech. These tags are ignored when using Original Chatterbox.
/docs for interactive details)The primary endpoint for TTS generation is /tts. The OpenAI-compatible /v1/audio/speech and /v1/audio/voices exist for drop-in replacement of OpenAI's TTS API.
| Endpoint | Method | Purpose |
|---|---|---|
/tts | POST | Custom TTS, full param set, supports stream: true (mp3 / wav / opus) |
/v1/audio/speech | POST | OpenAI-compatible TTS |
/v1/audio/voices | GET | OpenAI-compatible voice listing |
/api/ui/initial-data | GET | UI bootstrap + comprehensive health check |
/api/model-info | GET | Loaded model status, type, supported languages |
/api/unload | POST | Release GPU memory without restarting the server |
/save_settings | POST | Persist partial updates to config.yaml |
/reset_settings | POST | Reset config.yaml to defaults |
/get_reference_files | GET | List files in reference_audio/ |
/get_predefined_voices | GET | List formatted voices from voices/ |
/upload_reference | POST | Upload reference audio files |
/upload_predefined_voice | POST | Upload predefined voice files |
/docs | GET | Interactive Swagger UI |
/tts request body (CustomTTSRequest):
text (string, required) — plain text to synthesize.voice_mode ("predefined" | "clone", default "predefined").predefined_voice_id (string) — voice filename when voice_mode=predefined.reference_audio_filename (string) — reference filename when voice_mode=clone.output_format ("wav" | "mp3" | "opus", default "wav"). Ignored when stream=true (streaming always uses WAV).split_text (boolean, default true) — chunk long text by sentence.chunk_size (integer 50–500, default 120).stream (boolean, default false) — if true, returns a StreamingResponse that flushes WAV bytes as each chunk is synthesized.temperature, exaggeration, cfg_weight, seed, speed_factor, language — generation parameters that override defaults.Streaming caveat: the underlying Chatterbox model synthesizes a full chunk in one forward pass, so stream=true is chunk-level, not token-level. For short text (1 chunk) it gives no time-to-first-byte benefit. For long-form / audiobook input (many chunks) the client can start playback as soon as chunk 1 is ready while later chunks render in the background.
Example — streaming TTS:
curl -X POST http://localhost:8004/tts \
  -H "Content-Type: application/json" \
  -d '{"text":"The first chunk arrives quickly, the rest stream behind.","stream":true}' \
  --output stream.wav
Run Chatterbox TTS Server easily using Docker. The recommended method uses Docker Compose, which is pre-configured for different GPU types.
video and render groups.This method uses the provided docker-compose.yml files to manage the container, volumes, and configuration easily.
git clone https://github.com/devnen/Chatterbox-TTS-Server.git
cd Chatterbox-TTS-Server
The default docker-compose.yml is configured for NVIDIA RTX 20/30/40 series (CUDA 12.1).
docker compose up -d --build
For RTX 50 series / Blackwell (sm_120) use the cu128 compose file:
docker compose -f docker-compose-cu128.yml up -d --build
For DGX Spark / GB10 (sm_121) use the cu130 compose file:
docker compose -f docker-compose-cu130.yml up -d --build
Prerequisites: Ensure you have ROCm drivers installed on your host system and your user is in the required groups:
# Add your user to required groups (one-time setup)
sudo usermod -a -G video,render $USER
# Log out and back in for changes to take effect
Start the container:
docker compose -f docker-compose-rocm.yml up -d --build
For AMD Strix Halo (Ryzen AI MAX+) use the dedicated compose file:
docker compose -f docker-compose-strixhalo.yml up -d --build
A dedicated compose file is now provided for CPU-only users to avoid GPU driver errors.
docker compose -f docker-compose-cpu.yml up -d --build
⭐ Note: The first time you run this, Docker will build the image and download model files, which can take some time. Subsequent starts will be much faster.
Open your web browser to http://localhost:PORT (e.g., http://localhost:8004 or the host port you configured).
# Check if container can see NVIDIA GPU
docker compose exec chatterbox-tts-server nvidia-smi

# Verify PyTorch can access the GPU
docker compose exec chatterbox-tts-server python3 -c "import torch; print(f'CUDA available: {torch.cuda.is_available()}'); print(f'GPU count: {torch.cuda.device_count()}')"
# Check if container can see AMD GPU
docker compose -f docker-compose-rocm.yml exec chatterbox-tts-server rocm-smi

# Verify PyTorch can access the GPU
docker compose -f docker-compose-rocm.yml exec chatterbox-tts-server python3 -c "import torch; print(f'ROCm available: {torch.cuda.is_available()}'); print(f'Device name: {torch.cuda.get_device_name(0) if torch.cuda.is_available() else \"No GPU detected\"}')"
docker compose logs -f                                    # For NVIDIA
docker compose -f docker-compose-rocm.yml logs -f         # For AMD
docker compose -f docker-compose-cpu.yml logs -f          # For CPU
docker compose down                                       # For NVIDIA
docker compose -f docker-compose-rocm.yml down            # For AMD
docker compose -f docker-compose-cpu.yml down             # For CPU
docker compose restart chatterbox-tts-server              # For NVIDIA
docker compose -f docker-compose-rocm.yml restart chatterbox-tts-server # For AMD
docker compose -f docker-compose-cpu.yml restart chatterbox-tts-server # For CPU
If your AMD GPU is not officially supported by ROCm but is similar to a supported architecture, you can override the detected architecture:
# For RX 5000/6000 series (gfx10xx) - override to gfx1030
HSA_OVERRIDE_GFX_VERSION=10.3.0 docker compose -f docker-compose-rocm.yml up -d

# For RX 7000 series (gfx11xx) - override to gfx1100
HSA_OVERRIDE_GFX_VERSION=11.0.0 docker compose -f docker-compose-rocm.yml up -d

# For Vega cards - override to gfx906
HSA_OVERRIDE_GFX_VERSION=9.0.6 docker compose -f docker-compose-rocm.yml up -d
Check your GPU architecture:
# Method 1: Using rocminfo (if ROCm installed on host)
rocminfo | grep "Name:"

# Method 2: Using lspci
lspci | grep VGA
Common GPU Architecture Mappings:
docker-compose-rdna4.yml — no HSA_OVERRIDE_GFX_VERSION needed. Setting it when the GPU is natively detected may cause crashes. Only set HSA_OVERRIDE_GFX_VERSION=12.0.1 if using a tool that bundles its own older ROCm runtime without gfx1201 support (e.g. some ollama or LM Studio builds).HSA_OVERRIDE_GFX_VERSION=11.0.0HSA_OVERRIDE_GFX_VERSION=10.3.0HSA_OVERRIDE_GFX_VERSION=10.3.0HSA_OVERRIDE_GFX_VERSION=9.0.6"Python not found" error:
sudo apt install python3 python3-venv python3-pip"venv module not found" (Linux):
sudo apt install python3-venv
Installation hangs or fails:
python start.py --reinstall --verbosePermission errors removing venv (Windows):
rmdir /s /q venvHow do I switch between portable and standard mode?
--reinstall to remove the existing environment and choose againpython start.py --reinstall --portable or python start.py --reinstall --no-portableI shared my portable folder but models are downloading again:
model_cache in config.yaml to a path inside the project folderPortable mode isn't offered / I'm on Linux:
Wrong hardware detected:
nvidia-smi and AMD GPUs via rocm-smi--cpu, --nvidia, --nvidia-cu128, --rocmChecking installation type:
# The installation type is stored in venv/.install_type
cat venv/.install_type  # Linux/macOS
type venv\.install_type  # Windows
python -c "import torch; print(torch.backends.mps.is_available())"start.py launcher also applies this patch automatically.onnx==1.16.0 is pinned in all requirements files to use pre-built wheels. If you still hit issues, ensure you're using Python 3.10.config.yaml has device: auto (or device: mps) in the tts_engine section.nvidia-smi), ensure correct CUDA-enabled PyTorch is installed (see Installation options).--nvidia-cu128 or requirements-nvidia-cu128.txt instead of standard NVIDIA installation--nvidia or requirements-nvidia.txtchunk_size (e.g., 100-150).onnx==1.16.0 is pinned. The updated requirements files handle this automatically.chatterbox-tts, librosa): Ensure virtual environment is active and dependencies installed successfully. Try reinstalling: python start.py --reinstalllibsndfile Error (Linux): Run sudo apt install libsndfile1.ChatterboxTTS.from_pretrained() will attempt to download from Hugging Face Hub. Ensure model.repo_id in config.yaml is correct../reference_audio, ./voices)../config.yaml, ./logs, ./outputs, ./reference_audio, ./voices, and the Hugging Face cache directory if using Docker volumes.config.yaml is writable by the server process.Address already in use): Another process is using the port. Stop it or change server.port in config.yaml (requires server restart).
netstat -ano | findstr :8004 (Windows) or lsof -i :8004 (Linux)Set the CUDA_VISIBLE_DEVICES environment variable before running python server.py (or before running the launcher) to specify which GPU(s) PyTorch should see. The server uses the first visible one (effectively cuda:0 from PyTorch's perspective).
Example (Use only physical GPU 1):
CUDA_VISIBLE_DEVICES="1" python server.pyset CUDA_VISIBLE_DEVICES=1 && python server.py$env:CUDA_VISIBLE_DEVICES="1"; python server.pyExample (Use physical GPUs 6 and 7 - server uses GPU 6):
CUDA_VISIBLE_DEVICES="6,7" python server.pyset CUDA_VISIBLE_DEVICES=6,7 && python server.py$env:CUDA_VISIBLE_DEVICES="6,7"; python server.pyNote: CUDA_VISIBLE_DEVICES selects GPUs; it does not fix OOM errors if the chosen GPU lacks sufficient memory.
Check Python version:
python --version
Check PyTorch and CUDA:
python -c "import torch; print(f'PyTorch: {torch.__version__}'); print(f'CUDA: {torch.cuda.is_available()}')"
Check PyTorch architectures (for Blackwell support):
python -c "import torch; print(torch.cuda.get_arch_list())"
Test server manually:
# Activate venv first, then:
python server.py
config.yaml for settings. The docker-compose files mount your local config.yaml to /app/config.yaml inside the container.config.yaml doesn't exist locally, the application will create a default one with sensible defaults.config.yaml directly. Changes to server/model/path settings require a container restart:
docker compose restart chatterbox-tts-server
Persistent data is stored on your host machine via volume mounts:
./config.yaml:/app/config.yaml - Main application configuration./voices:/app/voices - Predefined voice audio files./reference_audio:/app/reference_audio - Your uploaded reference audio files for cloning./outputs:/app/outputs - Generated audio files saved from UI/API./logs:/app/logs - Server log fileshf_cache:/app/hf_cache - Named volume for Hugging Face model cache (persists downloads)Managing volumes:
# Remove all data (including downloaded models)
docker compose down -v

# Remove only application data (keep model cache)
docker compose down
sudo rm -rf voices/ reference_audio/ outputs/ logs/ config.yaml

# View volume usage
docker system df
python -c "import torch; print(torch.backends.mps.is_available())"pip install onnx==1.16.0 as shown in the installation steps.config.yaml has device: mps in the tts_engine section.nvidia-smi), ensure correct CUDA-enabled PyTorch is installed (Installation Step 4).chunk_size (e.g., 100-150).chatterbox-tts, librosa): Ensure virtual environment is active and pip install -r requirements.txt completed successfully.libsndfile Error (Linux): Run sudo apt install libsndfile1.ChatterboxTTS.from_pretrained() will attempt to download from Hugging Face Hub. Ensure model.repo_id in config.yaml is correct../reference_audio, ./voices)../config.yaml, ./logs, ./outputs, ./reference_audio, ./voices, and the Hugging Face cache directory if using Docker volumes.config.yaml is writable by the server process.Address already in use): Another process is using the port. Stop it or change server.port in config.yaml (requires server restart).Set the CUDA_VISIBLE_DEVICES environment variable before running python server.py to specify which GPU(s) PyTorch should see. The server uses the first visible one (effectively cuda:0 from PyTorch's perspective).
Example (Use only physical GPU 1):
CUDA_VISIBLE_DEVICES="1" python server.pyset CUDA_VISIBLE_DEVICES=1 && python server.py$env:CUDA_VISIBLE_DEVICES="1"; python server.pyExample (Use physical GPUs 6 and 7 - server uses GPU 6):
CUDA_VISIBLE_DEVICES="6,7" python server.pyset CUDA_VISIBLE_DEVICES=6,7 && python server.py$env:CUDA_VISIBLE_DEVICES="6,7"; python server.pyNote: CUDA_VISIBLE_DEVICES selects GPUs; it does not fix OOM errors if the chosen GPU lacks sufficient memory.
Contributions are welcome! Please feel free to open an issue to report bugs or suggest features, or submit a Pull Request for improvements.
This project is licensed under the MIT License.
You can find it here: https://opensource.org/licenses/MIT
609 followers · starred Aug 2026
187 followers · starred Jun 2025
17 followers · starred Jul 2025
1,474 followers · starred Sep 2025
Self-host the powerful Chatterbox TTS model. This server offers a user-friendly Web UI, flexible API endpoints (incl. OpenAI compatible), predefined voices, voice cloning, and large audiobook-scale text processing. Runs accelerated on NVIDIA (CUDA), AMD (ROCm), and CPU.
Python
1,469
180 commits
updated May 26, 2026
Self-host Resemble AI's Chatterbox open-source TTS family (Original + Multilingual + Turbo) behind an OpenAI‑compatible API and a modern Web UI. The complete lineup includes the original high-quality model, multilingual support for 23 languages, and Chatterbox‑Turbo—a streamlined 350M-parameter model with dramatically improved throughput and native paralinguistic tags like [laugh], [cough], and [chuckle] for more expressive voice agents and narration. Features voice cloning, large text processing via intelligent chunking, audiobook generation, and consistent, reproducible voices using built-in ready-to-use voices and a generation seed feature.
🚀 Try it now! Test the full TTS server with voice cloning and audiobook generation in Google Colab - no installation required! To use it, please run cells 1 through 4 one at a time. After running cell 4, click on the "https://localhost:8004" link that appears in the output, and your web browser will open the UI from the .colab.dev domain. Read the instructions here.
This server is based on the architecture and UI of our Dia-TTS-Server project but uses the distinct chatterbox-tts engine. Runs accelerated on NVIDIA (CUDA), AMD (ROCm), and Apple Silicon (MPS) GPUs, with a fallback to CPU. Make sure you also check our Kitten-TTS-Server project.
📦 Portable Mode (Windows): This application supports a fully portable installation — the entire folder, including Python and all dependencies, is self-contained. Copy it to a USB drive, share it as a zip, or move it anywhere. Just double-click
start.bat— no Python installation needed on the target machine. Learn more →
v2.0 ships the complete Chatterbox family on every major GPU stack behind one OpenAI-compatible API and Web UI. The headline themes:
docker-compose-cu130.yml (CUDA 13.0, PyTorch 2.10). RTX 30/40/50 keep using cu121 / cu128.docker-compose-strixhalo.yml (ROCm 7.2, HSA_OVERRIDE_GFX_VERSION=11.0.0)./tts endpoint — opt-in stream: true parameter returns a StreamingResponse that flushes WAV bytes per chunk with 20 ms crossfades. Default behavior unchanged.TTS_BF16=on (or =auto) converts T3 to bfloat16 and runs under autocast for ~40% throughput on bf16-capable GPUs. Default off to preserve existing behavior on upgrade.ssl_certfile and ssl_keyfile in config.yaml for direct HTTPS without a reverse proxy./tts and /v1/audio/speech voice file parameters. Traversal attempts return HTTP 400./api/unload (release GPU memory without restart) and /v1/audio/voices (OpenAI-compatible voice listing).SUPPORTED_LANGUAGES exposed by the multilingual engine.See the v2.0.0 release notes for the full list with contributor credits.
start.bat — no Python installation required on the target machine.--portable to skip the prompt and install in portable mode directly, or --no-portable for a standard virtual environment.…calling you back [chuckle]….[laugh], [cough], and [chuckle], plus text-based prompting for reactions like sigh, gasp, and cough.ui/presets.yaml demonstrating paralinguistic prompting for agent-style scripts and expressive reads.You now have access to the entire Chatterbox lineup:
[laugh] and [cough] (350M parameters, 1-step diffusion)Switching models is effortless: Simply select your preferred model from the engine selector dropdown at the top of the Web UI. No restarts, no configuration changes required—just instant hot-swapping to test quality, speed, and language support across the complete Chatterbox family.
--no-deps across all installation paths (CPU, NVIDIA, cu128, ROCm). This eliminates ONNX source build failures, torch version conflicts, and CMake errors that affected many users. Chatterbox's dependencies (conformer, diffusers, transformers, s3tokenizer, etc.) are now listed explicitly in each requirements file with onnx==1.16.0 pinned to guarantee pre-built wheels.start.py for users of other chatterbox versions. Thanks to @jonas3245 (#93).Dockerfile.cpu based on python:3.10-slim instead of the 4GB+ NVIDIA CUDA base image. docker-compose-cpu.yml now uses this smaller image. Removed deprecated version tags from all docker-compose files.cuda to auto for correct auto-detection on all hardware (CUDA, MPS, CPU).requirements-nvidia-cu128.txt to properly install PyTorch 2.9.0 with CUDA 12.8 (sm_120 support) for RTX 5060 Ti, 5070, 5070 Ti, 5080, and 5090 GPUs. The Dockerfile.cu128 now correctly installs chatterbox with --no-deps to prevent PyTorch downgrade.torch==2.5.1+rocm6.1), which resolves the previous torch==2.6.0 / torchaudio==2.5.1 version conflict. A new requirements-rocm-init.txt installs the ROCm PyTorch stack before other dependencies. Both Dockerfile.rocm and start.py now use a two-step install to prevent pip from replacing ROCm torch wheels with CPU-only versions.--upgrade to update code + dependencies.--reinstall for a clean reinstall when environments get messy.The Chatterbox TTS model by Resemble AI provides capabilities for generating high-quality speech. This project builds upon that foundation by providing a robust FastAPI server that makes Chatterbox significantly easier to use and integrate.
🚀 Want to try it instantly? Launch the live demo in Google Colab - no installation needed!
The server expects plain text input for synthesis and we solve the complexity of setting up and running the model by offering:
[laugh], [cough], and [chuckle] for natural non-speech reactions inside the same generated voice.This server is your gateway to leveraging Chatterbox's TTS capabilities seamlessly, with enhanced stability, voice consistency, and large text support for plain text inputs.
🔥 Live Demo Available:
This server application enhances the underlying chatterbox-tts engine with the following:
🚀 Core Functionality:
[laugh], [cough], and [chuckle] directly in your text when using Chatterbox‑Turbo../voices directory..wav or .mp3).seed parameter to UI and API for influencing generation results. Using a fixed integer seed in combination with Predefined Voices or Voice Cloning helps maintain consistency./tts):
split_text, chunk_size), generation settings (temperature, exaggeration, CFG weight, seed, speed factor, language), and output format.config.yaml settings (server, model, paths) and save generation defaults.config.yaml for all runtime configuration, managed via config.py (YamlConfigManager). If config.yaml is missing, it's created with default values from config.py.parselmouth is installed) unvoiced segment removal to improve audio quality. These are configurable.config.yaml (ui_state section).🔧 General Enhancements:
start.bat / start.sh) - One-command setup with automatic hardware detection--upgrade and --reinstall commands--cpu, --nvidia, --nvidia-cu128, --rocm, --portable flagsChatterboxTTS.from_pretrained() for robust model loading from Hugging Face Hub, utilizing the standard HF cache.requirements.txt.utils.py for audio processing, text handling, and file management./tts) as the primary method for programmatic generation, exposing all key parameters./docs)./api/ui/initial-data also serves as a comprehensive status check).[laugh], [cough], [chuckle] and other expressive tags.split_text and chunk_size../voices directory.config.yaml).ui/presets.yaml..wav/.mp3 files.config.yaml) and default generation parameters directly in the UI.config.yaml.ChatterboxTTS.from_pretrained().config.yaml.download_model.py script available to pre-download specific model components to a local directory (this is separate from the main HF cache used at runtime).config.yaml.docker compose up -d).libsndfile1: Audio library needed by soundfile. Install via package manager (e.g., sudo apt install libsndfile1).ffmpeg: For robust audio operations (optional but recommended). Install via package manager (e.g., sudo apt install ffmpeg).| Hardware | Installation Option | Requirements File | Driver Requirement |
|---|---|---|---|
| CPU Only | --cpu | requirements.txt | None |
| NVIDIA RTX 20/30/40 | --nvidia | requirements-nvidia.txt | 525+ |
| NVIDIA RTX 5090 / Blackwell (sm_120) | --nvidia-cu128 | requirements-nvidia-cu128.txt (torch 2.9, CUDA 12.8) | 570+ |
| NVIDIA DGX Spark / GB10 (sm_121) | Docker only | requirements-nvidia-cu130.txt (torch 2.10, CUDA 13.0) | 580+ |
| AMD RX 6000/7000 (Linux) | --rocm | requirements-rocm.txt | ROCm 6.4+ |
| AMD Strix Halo (Ryzen AI MAX+) | Docker only | requirements-strixhalo.txt (ROCm 7.2) | ROCm 7.2+ |
| AMD RX 9000 series / RDNA4 (Linux) | Docker only | requirements-rdna4-init.txt (ROCm 7.2) | ROCm 7.2+ |
| Apple Silicon (M1/M2/M3/M4) | Manual install | See Option 4 | macOS 12.3+ |
This project uses specific dependency files to ensure a smooth installation for your hardware. You can choose between the automated launcher (recommended for most users) or manual installation (for advanced users).
1. Clone the Repository
git clone https://github.com/devnen/Chatterbox-TTS-Server.git
cd Chatterbox-TTS-Server
The automated launcher handles virtual environment creation, hardware detection, dependency installation, and server startup - all in one step.
# Double-click start.bat or run from command prompt:
start.bat
# Make the launcher executable and run it
chmod +x start.sh
./start.sh
--portable to skip this prompt or --no-portable for a standard virtual environment.══════════════════════════════════════════════════════════════
Hardware Detection
══════════════════════════════════════════════════════════════
NVIDIA GPU: Detected (NVIDIA GeForce RTX 4090)
AMD GPU: Not detected
══════════════════════════════════════════════════════════════
Select Installation Type
══════════════════════════════════════════════════════════════
[1] CPU Only
No GPU acceleration - works on any system
[2] NVIDIA GPU (CUDA 12.1) [DEFAULT]
Standard for RTX 20/30/40 series
[3] NVIDIA GPU (CUDA 12.8)
For RTX 5090 / Blackwell GPUs only
[4] AMD GPU (ROCm 6.4)
For AMD GPUs on Linux
Enter choice [2]:
| Option | Description |
|---|---|
--reinstall or -r | Remove existing installation and reinstall fresh (shows menu) |
--upgrade or -u | Upgrade to latest version (keeps current hardware selection) |
--cpu | Install CPU-only version (skip menu) |
--nvidia | Install NVIDIA CUDA 12.1 version (skip menu) |
--nvidia-cu128 | Install NVIDIA CUDA 12.8 version for RTX 5090/Blackwell (skip menu) |
--rocm | Install AMD ROCm version (skip menu) |
--portable | Use portable Python environment on Windows (skip prompt) |
--no-portable | Use standard virtual environment on Windows (skip prompt) |
--verbose or -v | Show detailed installation output |
--help or -h | Show help message |
Examples:
# Skip menu and install NVIDIA CUDA 12.1 directly
python start.py --nvidia

# Reinstall with fresh dependencies
python start.py --reinstall

# Upgrade to latest version (keeps your hardware selection)
python start.py --upgrade

```bash
# Install with verbose output for troubleshooting
python start.py --reinstall --nvidia --verbose

# Install in portable mode (Windows) - skip prompt
python start.py --portable

# Switch from standard to portable mode
python start.py --reinstall --portable

# Force standard virtual environment (skip portable prompt)
python start.py --no-portable
#### Subsequent Runs

After the first installation, simply run the launcher again to start the server:

```bash
# Windows
start.bat

# Linux/macOS
./start.sh
The launcher detects the existing installation and starts the server directly without reinstalling.
On Windows, the launcher offers Portable Mode — a fully self-contained installation where the entire project folder, including its own private Python runtime and all dependencies, lives in one place. Unlike standard Python virtual environments (which use hardcoded absolute paths and break when moved), the portable installation uses only relative paths and works from any location.
Once the first-time setup completes, the entire project folder can be:
start.bat, and it runs.The recipient doesn't need Python installed, doesn't need to run any setup, and doesn't need an internet connection to launch the server (see note about models below).
The TTS models (~2+ GB) are downloaded from Hugging Face Hub into a separate cache folder the first time the server starts on any machine. This is a one-time download per machine, independent of the portable application folder.
If you're sharing a portable installation, the recipient will need an internet connection for this initial model download on their first run. To pre-include models in the portable package, you can set the model_cache path in config.yaml to a folder inside the project directory, then include it when sharing.
During first-time setup on Windows, the launcher offers a choice:
python_embedded/ environment inside the project folder using Python 3.10. Any system Python 3.10+ can bootstrap this process, but the embedded runtime is always Python 3.10.venv/). Requires system Python 3.10 — Python 3.11+ will fail due to missing pre-built wheels for key dependencies.If your system Python is 3.11+, Portable Mode is required on Windows because it uses an embedded Python 3.10 runtime, bypassing the dependency issues entirely.
You can skip the prompt entirely with command-line flags:
python start.py --portable — go straight to portable modepython start.py --no-portable — go straight to standard venvpython start.py --reinstall --portable — switch an existing installation to portable modePortable Mode is Windows-specific. On Linux and macOS, the standard virtual environment is used. Python 3.10 is required on all platforms — the dependency compatibility issues (missing wheels for torchvision, ONNX) affect all operating systems, not just Windows.
Portable Mode includes Python and all Python packages, but GPU drivers are not included. If the target machine has an NVIDIA GPU and you want GPU acceleration, the appropriate NVIDIA drivers must be installed on that machine. CPU mode works without any drivers.
How it works under the hood:
python310._pth file is patched to use relative paths (., .., Lib\site-packages). The .. entry resolves to the project root since python_embedded/ is always one level deep. This is what makes portability work — no absolute paths are written anywhere.activate.bat, no activate.ps1, no hardcoded paths. The launcher simply runs python_embedded/python.exe directly.pip via get-pip.py, explicitly installs setuptools (needed by the perth watermarking library at runtime), generates a sitecustomize.py for DLL search path configuration, and patches the TTS engine's watermarker initialization for resilience.start.bat batch file finds any system Python to launch start.py, which then detects the existing python_embedded/ directory and uses it — regardless of which system Python version invoked the launcher.For users who prefer manual control over the installation process.
2. Create a Python Virtual Environment
Using a virtual environment is crucial to avoid conflicts with other projects.
Windows (PowerShell):
python -m venv venv
.\venv\Scripts\activate
Linux (Bash):
python3 -m venv venv
source venv/bin/activate
Your command prompt should now start with (venv).
3. Choose Your Installation Path
Pick one of the following commands based on your hardware. This single command will install all necessary dependencies with compatible versions.
This is the most straightforward option and works on any machine without a compatible GPU.
# Make sure your (venv) is active
pip install --upgrade pip
pip install -r requirements.txt
pip install --no-deps git+https://github.com/devnen/chatterbox-v2.git@master
For users with NVIDIA GPUs. This provides the best performance for RTX 20/30/40 series.
Prerequisite: Ensure you have the latest NVIDIA drivers installed. Python 3.10 required (3.11+ is not supported — pre-built wheels for torchvision and ONNX are unavailable).
# Make sure your (venv) is active
pip install --upgrade pip
pip install -r requirements-nvidia.txt
pip install --no-deps git+https://github.com/devnen/chatterbox-v2.git@master
After installation, verify that PyTorch can see your GPU:
python -c "import torch; print(f'PyTorch version: {torch.__version__}'); print(f'CUDA available: {torch.cuda.is_available()}'); print(f'Device name: {torch.cuda.get_device_name(0) if torch.cuda.is_available() else None}')"
If CUDA available: shows True, your setup is correct!
Note: Only use this if you have a Blackwell-based GPU (RTX 5060 Ti, 5070, 5070 Ti, 5080, 5090). For RTX 2000/3000/4000 series, use Option 2 above.
For users with NVIDIA Blackwell architecture GPUs that require CUDA 12.8 and sm_120 support.
Prerequisites:
Using Docker (Recommended for RTX 5090):
# Build and start with CUDA 12.8 support
docker compose -f docker-compose-cu128.yml up -d

# Access the web UI at http://localhost:8004
Manual Installation:
# Make sure your (venv) is active
pip install --upgrade pip

# Step 1: Install dependencies with PyTorch 2.9.0+cu128 (includes sm_120 support)
pip install -r requirements-nvidia-cu128.txt

# Step 2: Install chatterbox without dependencies (prevents PyTorch downgrade)
pip install --no-deps git+https://github.com/devnen/chatterbox-v2.git@master
⚠️ Critical: The --no-deps flag is required to prevent PyTorch from being downgraded to a version that doesn't support Blackwell GPUs.
After installation, verify that PyTorch supports sm_120:
python -c "import torch; print(f'PyTorch: {torch.__version__}'); print(f'CUDA: {torch.cuda.is_available()}'); print(f'GPU: {torch.cuda.get_device_name(0)}'); print(f'Architectures: {torch.cuda.get_arch_list()}')"
You should see sm_120 in the architectures list!
NVIDIA's Blackwell GPUs (RTX 5060 Ti, 5070, 5070 Ti, 5080, 5090) use compute capability sm_120. PyTorch 2.9.0 with CUDA 12.8 includes support for this architecture. Earlier versions (including CUDA 12.1) will fail with the error: CUDA error: no kernel image is available for execution on the device.
See README_CUDA128.md for detailed setup instructions and troubleshooting.
Note: Use this for NVIDIA DGX Spark / GB10 hardware (compute capability
sm_121). RTX 5090 stays on cu128 (Option 2b); RTX 30/40 stays on cu121 (Option 2).
For users on the very latest NVIDIA stack who need CUDA 13.0 and PyTorch 2.10.
Prerequisites:
Using Docker (recommended):
docker compose -f docker-compose-cu130.yml up -d

# Access the web UI at http://localhost:8004
The Dockerfile.cu130 installs PyTorch 2.10.0+cu130 with chatterbox-v2 via --no-deps so PyTorch is not downgraded.
For users with modern, ROCm-compatible AMD GPUs.
Prerequisite: Ensure you have the latest ROCm drivers installed on a Linux system.
# Make sure your (venv) is active
pip install --upgrade pip

# Step 1: Install ROCm PyTorch stack first
pip install -r requirements-rocm-init.txt

# Step 2: Install remaining dependencies
pip install -r requirements-rocm.txt

# Step 3: Install chatterbox without dependencies (prevents ROCm torch overwrite)
pip install --no-deps git+https://github.com/devnen/chatterbox-v2.git@master
⚠️ Critical: The --no-deps flag on chatterbox-tts is required to prevent pip from replacing the ROCm PyTorch wheels with CPU-only versions from PyPI. The start.py launcher handles this automatically.
After installation, verify that PyTorch can see your GPU:
python -c "import torch; print(f'PyTorch version: {torch.__version__}'); print(f'ROCm available: {torch.cuda.is_available()}'); print(f'Device name: {torch.cuda.get_device_name(0) if torch.cuda.is_available() else None}')"
If ROCm available: shows True, your setup is correct!
ROCm installation uses a two-step process:
requirements-rocm-init.txt installs PyTorch from the official ROCm 6.1 wheel index (torch==2.5.1+rocm6.1), ensuring you get AMD GPU-accelerated builds.requirements-rocm.txt installs remaining server dependencies without touching PyTorch.--no-deps to prevent pip's dependency resolver from replacing the ROCm torch with a CPU-only version.For APU/iGPU users: If you encounter "HIP error: invalid device function", you may need to set HSA_OVERRIDE_GFX_VERSION. See AMD ROCm Support Details below.
For users with Apple Silicon Macs (M1, M2, M3, M4, etc.).
Prerequisite: Ensure you have macOS 12.3 or later for MPS support.
Step 1: Install PyTorch with MPS support first
# Make sure your (venv) is active
pip install --upgrade pip
pip install torch torchvision torchaudio
Step 2: Configure the server to use MPS
Update your config.yaml to use MPS instead of CUDA:
tts_engine:
  device: mps  # Changed from 'cuda' to 'mps'
Step 3: Install remaining dependencies
# Install chatterbox-tts without its dependencies to avoid conflicts
pip install --no-deps git+https://github.com/devnen/chatterbox-v2.git@master

# Install core server dependencies
pip install fastapi 'uvicorn[standard]' librosa safetensors soundfile pydub audiotsm praat-parselmouth python-multipart requests aiofiles PyYAML watchdog unidecode inflect tqdm

# Install missing chatterbox dependencies
pip install conformer==0.3.2 diffusers==0.29.0 resemble-perth==1.0.1 transformers==4.46.3

# Install s3tokenizer without its problematic dependencies
pip install --no-deps s3tokenizer

# Install a compatible version of ONNX and audio codec
pip install onnx==1.16.0 descript-audio-codec
After installation, verify that PyTorch can see your GPU:
python -c "import torch; print(f'PyTorch version: {torch.__version__}'); print(f'MPS available: {torch.backends.mps.is_available()}'); print(f'Device will use: {\"mps\" if torch.backends.mps.is_available() else \"cpu\"}')"
If MPS available: shows True, your setup is correct!
Note: Use this for AMD Strix Halo APUs (Ryzen AI MAX+ 395 / "Ryzen AI Max" with integrated Radeon 8060S, GFX 11.5.0). Standard discrete Radeon GPUs use Option 3 (ROCm).
Prerequisites:
Using Docker (recommended):
docker compose -f docker-compose-strixhalo.yml up -d

# Access the web UI at http://localhost:8004
The compose file sets HSA_OVERRIDE_GFX_VERSION=11.0.0 and HSA_XNACK=1 so the ROCm 7.2 wheels work on Strix Halo's GFX 11.5.0 silicon, and enables TTS_BF16=on for the throughput win on this hardware.
Note: For AMD RDNA4 discrete GPUs (RX 9070, RX 9070 XT, Radeon AI PRO R9700, gfx1201). ROCm 6.1 wheels do not support gfx1201 — ROCm 7.2 is required. Standard discrete Radeon GPUs (RX 6000/7000) use Option 3.
Prerequisites:
video and render groups: sudo usermod -aG video,render $USERUsing Docker (recommended):
docker compose -f docker-compose-rdna4.yml up -d

# Access the web UI at http://localhost:8004
The compose file sets ROCBLAS_USE_HIPBLASLT=0 (required for stability on gfx1201) and enables TTS_BF16=on for throughput gain. gfx1201 is natively supported by ROCm 7.0+ — no HSA_OVERRIDE_GFX_VERSION needed.
Want to test Chatterbox TTS Server immediately without any installation?
Prefer local installation? Continue reading below for full setup instructions.
The server relies exclusively on config.yaml for runtime configuration.
config.yaml: Located in the project root. This file stores all server settings, model paths, generation defaults, and UI state. It is created automatically on the first run (using defaults from config.py) if it doesn't exist. This is the main file to edit for persistent configuration changes.config.yaml.Key Configuration Areas (in config.yaml or UI):
server: host, port, logging settings.model: repo_id (e.g., "ResembleAI/chatterbox").tts_engine: device ('auto', 'cuda', 'mps', 'cpu'), predefined_voices_path, reference_audio_path, default_voice_id.paths: model_cache (for download_model.py), output.generation_defaults: Default UI values for temperature, exaggeration, cfg_weight, seed, speed_factor, language.audio_output: format, sample_rate, max_reference_duration_sec.ui_state: Stores the last used text, voice mode, file selections, etc., for UI persistence.ui: title, show_language_select, max_predefined_voices_in_dropdown.debug: save_intermediate_audio.⭐ Remember: Changes made to server, model, tts_engine, or paths sections in config.yaml (or via the UI's Server Configuration section) require a server restart to take effect. Changes to generation_defaults or ui_state are applied dynamically or on the next page load.
Model selection: set model.repo_id to one of:
chatterbox (or original) — Original 0.5B English model with emotion exaggeration.chatterbox-turbo (or turbo) — 350M Turbo model with paralinguistic tags ([laugh], [cough], [chuckle]).chatterbox-multilingual (or multilingual) — 0.5B multilingual model with 23-language support.All three are hot-swappable from the Web UI engine dropdown without a server restart.
/tts (predefined_voice_id, reference_audio_filename) and /v1/audio/speech (voice) are sandboxed under their configured directories using utils.safe_resolve_within()..., absolute paths, symlinks pointing outside the sandbox) return HTTP 400 with no filesystem access. The fix addresses CWE-22 and shipped in v2.0.0.The server defaults are tuned for safety and broad compatibility. The following knobs trade safety for speed when you understand your hardware:
TTS_BF16=on (or =auto for "enable only if the GPU reports is_bf16_supported()") to convert T3 to bfloat16 and run generate() under autocast. Roughly 40% throughput on bf16-capable GPUs (RTX 30/40/50, A100, H100, Strix Halo). Default is off to preserve existing behavior on upgrade. Output is numerically slightly different from float32 but typically inaudible.(path, mtime, exaggeration) and is automatically cleared on reload_model() / /api/unload. No config needed.chunk_size parameter on /tts (50–500, default 120). Larger chunks = fewer requests but more VRAM per call. The chunker respects sentence boundaries either way.stream: true on /tts for long-form input (audiobooks, multi-paragraph content). See the API section above for the chunk-level caveat.server.ssl_certfile and server.ssl_keyfile in config.yaml for direct HTTPS without putting a reverse proxy in front.Important Note on Model Downloads (First Run):
The very first time you start the server, it needs to download the chatterbox-tts model files from Hugging Face Hub. This is an automatic, one-time process (per model version, or until your Hugging Face cache is cleared).
You can optionally use the python download_model.py script to pre-download specific model components to the ./model_cache directory defined in config.yaml. However, please note that the runtime engine (engine.py) primarily loads the model from the main Hugging Face Hub cache directly, not this specific local model_cache directory.
The easiest way to run the server is using the automated launcher:
Windows:
start.bat
Linux / macOS:
./start.sh
The launcher automatically:
If you prefer to start the server manually:
Steps to Run:
source venv/bin/activate.\venv\Scripts\activatepython server.py
http://localhost:PORT (e.g., http://localhost:8004 if your configured port is 8004).http://localhost:PORT/docs for interactive API documentation.CTRL+C in the terminal where the server is running.
## 🔄 Updating to the Latest Version

Follow these steps to update your local installation to the latest version from GitHub. This guide provides multiple methods: using the automated launcher, the recommended `git stash` workflow, and a manual backup alternative. All methods preserve your local `config.yaml`.

**First, Navigate to Your Project Directory**

Before starting, open your terminal and go to the project folder.

```bash
cd Chatterbox-TTS-Server
The launcher provides simple upgrade functionality that handles everything automatically.
Upgrade (keeps your hardware selection):
# First, pull the latest code
git pull origin main

# Then upgrade dependencies using the launcher
# Windows
python start.py --upgrade

# Linux/macOS
python3 start.py --upgrade
Full Reinstall (choose new hardware option):
git pull origin main

# Windows
python start.py --reinstall

# Linux/macOS
python3 start.py --reinstall
The --upgrade flag preserves your current hardware selection (CPU, NVIDIA, etc.) and reinstalls dependencies.
The --reinstall flag removes the existing installation completely and shows the hardware selection menu again.
Changing Hardware Configuration:
To switch to a different hardware configuration (e.g., from CPU to NVIDIA, or from CUDA 12.1 to CUDA 12.8):
# Shows menu to select new hardware
python start.py --reinstall

# Or specify directly
python start.py --reinstall --nvidia
python start.py --reinstall --nvidia-cu128
python start.py --reinstall --cpu
python start.py --reinstall --rocm
If you installed manually without using the launcher, this is the standard and safest way to update using Git. It automatically handles your local changes (like to config.yaml) without needing to manually copy files.
First, activate your virtual environment:
# On Windows (PowerShell):
.\venv\Scripts\activate

# On Linux (Bash):
source venv/bin/activate
Step 1: Stash Your Local Changes This command safely stores your modifications on a temporary "shelf."
git stash
Step 2: Pull the Latest Version Now that your local changes are safely stored, you can download the latest code from GitHub.
git pull origin main
Step 3: Re-apply Your Changes This command takes your changes from the shelf and applies them back to the updated code.
git stash pop
Your config.yaml will now have your settings, and the rest of the project files will be up-to-date. You can now proceed to the "Final Steps" section below.
This method involves manually backing up and restoring your configuration file.
First, activate your virtual environment:
# On Windows (PowerShell):
.\venv\Scripts\activate

# On Linux (Bash):
source venv/bin/activate
Step 1: Backup Your Configuration
⚠️ Important: Create a backup of your config.yaml to preserve your custom settings.
# Create a backup of your current configuration
cp config.yaml config.yaml.backup
Step 2: Update the Repository Choose one of the following commands based on your needs:
git pull origin main
config.yaml, you may need to resolve them manually.# Fetch latest changes and reset to match remote exactly
git fetch origin
git reset --hard origin/main
Step 3: Restore Your Configuration
# Restore your backed-up configuration
cp config.yaml.backup config.yaml
Now, proceed to the "Final Steps" section.
After you have updated the code using Method 2 or 3, complete these final steps.
1. Check for New Configuration Options
⭐ Recommended: Compare your restored config.yaml with the new default config to see if there are new options you might want to adopt. The server will add new keys with default values, but you may want to review them.
2. Update Dependencies
⭐ Important: After pulling new code, always update the dependencies to ensure you have the correct versions. Choose the command that matches your hardware:
pip install -r requirements.txt
pip install -r requirements-nvidia.txt
pip install -r requirements-nvidia-cu128.txt
pip install --no-deps git+https://github.com/devnen/chatterbox-v2.git@master
pip install -r requirements-rocm.txt
3. Restart the Server
If the server was running, stop it (CTRL+C) and restart it to apply all the updates.
python server.py
⭐ Note: Your custom settings in config.yaml are preserved with this method. The server will automatically add any new configuration options with default values if needed. You can safely delete config.yaml.backup once you've verified everything works correctly.
⭐ Docker Users: If using Docker and you have a local config.yaml mounted as a volume, the same backup/restore process applies before running:
docker compose down
docker compose pull  # if using pre-built images
docker compose up -d --build
For RTX 5090 / Blackwell GPUs: Use the CUDA 12.8 configuration:
docker compose -f docker-compose-cu128.yml down
docker compose -f docker-compose-cu128.yml pull
docker compose -f docker-compose-cu128.yml up -d --build
http://localhost:PORT)The most intuitive way to use the server:
Predefined Voices: Select a curated voice from the ./voices directory.Voice Cloning: Select an uploaded reference file from ./reference_audio.ui/presets.yaml. New presets demonstrate Turbo's paralinguistic tags.config.yaml.config.yaml (requires server restart for some changes).When the engine selector is set to Chatterbox‑Turbo, you can include paralinguistic tags inline:
Hi there [chuckle] — thanks for calling back.
One moment… [cough] sorry about that. Let's get this fixed.
Turbo supports native tags like [laugh], [cough], and [chuckle] for more realistic, expressive speech. These tags are ignored when using Original Chatterbox.
/docs for interactive details)The primary endpoint for TTS generation is /tts. The OpenAI-compatible /v1/audio/speech and /v1/audio/voices exist for drop-in replacement of OpenAI's TTS API.
| Endpoint | Method | Purpose |
|---|---|---|
/tts | POST | Custom TTS, full param set, supports stream: true (mp3 / wav / opus) |
/v1/audio/speech | POST | OpenAI-compatible TTS |
/v1/audio/voices | GET | OpenAI-compatible voice listing |
/api/ui/initial-data | GET | UI bootstrap + comprehensive health check |
/api/model-info | GET | Loaded model status, type, supported languages |
/api/unload | POST | Release GPU memory without restarting the server |
/save_settings | POST | Persist partial updates to config.yaml |
/reset_settings | POST | Reset config.yaml to defaults |
/get_reference_files | GET | List files in reference_audio/ |
/get_predefined_voices | GET | List formatted voices from voices/ |
/upload_reference | POST | Upload reference audio files |
/upload_predefined_voice | POST | Upload predefined voice files |
/docs | GET | Interactive Swagger UI |
/tts request body (CustomTTSRequest):
text (string, required) — plain text to synthesize.voice_mode ("predefined" | "clone", default "predefined").predefined_voice_id (string) — voice filename when voice_mode=predefined.reference_audio_filename (string) — reference filename when voice_mode=clone.output_format ("wav" | "mp3" | "opus", default "wav"). Ignored when stream=true (streaming always uses WAV).split_text (boolean, default true) — chunk long text by sentence.chunk_size (integer 50–500, default 120).stream (boolean, default false) — if true, returns a StreamingResponse that flushes WAV bytes as each chunk is synthesized.temperature, exaggeration, cfg_weight, seed, speed_factor, language — generation parameters that override defaults.Streaming caveat: the underlying Chatterbox model synthesizes a full chunk in one forward pass, so stream=true is chunk-level, not token-level. For short text (1 chunk) it gives no time-to-first-byte benefit. For long-form / audiobook input (many chunks) the client can start playback as soon as chunk 1 is ready while later chunks render in the background.
Example — streaming TTS:
curl -X POST http://localhost:8004/tts \
  -H "Content-Type: application/json" \
  -d '{"text":"The first chunk arrives quickly, the rest stream behind.","stream":true}' \
  --output stream.wav
Run Chatterbox TTS Server easily using Docker. The recommended method uses Docker Compose, which is pre-configured for different GPU types.
video and render groups.This method uses the provided docker-compose.yml files to manage the container, volumes, and configuration easily.
git clone https://github.com/devnen/Chatterbox-TTS-Server.git
cd Chatterbox-TTS-Server
The default docker-compose.yml is configured for NVIDIA RTX 20/30/40 series (CUDA 12.1).
docker compose up -d --build
For RTX 50 series / Blackwell (sm_120) use the cu128 compose file:
docker compose -f docker-compose-cu128.yml up -d --build
For DGX Spark / GB10 (sm_121) use the cu130 compose file:
docker compose -f docker-compose-cu130.yml up -d --build
Prerequisites: Ensure you have ROCm drivers installed on your host system and your user is in the required groups:
# Add your user to required groups (one-time setup)
sudo usermod -a -G video,render $USER
# Log out and back in for changes to take effect
Start the container:
docker compose -f docker-compose-rocm.yml up -d --build
For AMD Strix Halo (Ryzen AI MAX+) use the dedicated compose file:
docker compose -f docker-compose-strixhalo.yml up -d --build
A dedicated compose file is now provided for CPU-only users to avoid GPU driver errors.
docker compose -f docker-compose-cpu.yml up -d --build
⭐ Note: The first time you run this, Docker will build the image and download model files, which can take some time. Subsequent starts will be much faster.
Open your web browser to http://localhost:PORT (e.g., http://localhost:8004 or the host port you configured).
# Check if container can see NVIDIA GPU
docker compose exec chatterbox-tts-server nvidia-smi

# Verify PyTorch can access the GPU
docker compose exec chatterbox-tts-server python3 -c "import torch; print(f'CUDA available: {torch.cuda.is_available()}'); print(f'GPU count: {torch.cuda.device_count()}')"
# Check if container can see AMD GPU
docker compose -f docker-compose-rocm.yml exec chatterbox-tts-server rocm-smi

# Verify PyTorch can access the GPU
docker compose -f docker-compose-rocm.yml exec chatterbox-tts-server python3 -c "import torch; print(f'ROCm available: {torch.cuda.is_available()}'); print(f'Device name: {torch.cuda.get_device_name(0) if torch.cuda.is_available() else \"No GPU detected\"}')"
docker compose logs -f                                    # For NVIDIA
docker compose -f docker-compose-rocm.yml logs -f         # For AMD
docker compose -f docker-compose-cpu.yml logs -f          # For CPU
docker compose down                                       # For NVIDIA
docker compose -f docker-compose-rocm.yml down            # For AMD
docker compose -f docker-compose-cpu.yml down             # For CPU
docker compose restart chatterbox-tts-server              # For NVIDIA
docker compose -f docker-compose-rocm.yml restart chatterbox-tts-server # For AMD
docker compose -f docker-compose-cpu.yml restart chatterbox-tts-server # For CPU
If your AMD GPU is not officially supported by ROCm but is similar to a supported architecture, you can override the detected architecture:
# For RX 5000/6000 series (gfx10xx) - override to gfx1030
HSA_OVERRIDE_GFX_VERSION=10.3.0 docker compose -f docker-compose-rocm.yml up -d

# For RX 7000 series (gfx11xx) - override to gfx1100
HSA_OVERRIDE_GFX_VERSION=11.0.0 docker compose -f docker-compose-rocm.yml up -d

# For Vega cards - override to gfx906
HSA_OVERRIDE_GFX_VERSION=9.0.6 docker compose -f docker-compose-rocm.yml up -d
Check your GPU architecture:
# Method 1: Using rocminfo (if ROCm installed on host)
rocminfo | grep "Name:"

# Method 2: Using lspci
lspci | grep VGA
Common GPU Architecture Mappings:
docker-compose-rdna4.yml — no HSA_OVERRIDE_GFX_VERSION needed. Setting it when the GPU is natively detected may cause crashes. Only set HSA_OVERRIDE_GFX_VERSION=12.0.1 if using a tool that bundles its own older ROCm runtime without gfx1201 support (e.g. some ollama or LM Studio builds).HSA_OVERRIDE_GFX_VERSION=11.0.0HSA_OVERRIDE_GFX_VERSION=10.3.0HSA_OVERRIDE_GFX_VERSION=10.3.0HSA_OVERRIDE_GFX_VERSION=9.0.6"Python not found" error:
sudo apt install python3 python3-venv python3-pip"venv module not found" (Linux):
sudo apt install python3-venv
Installation hangs or fails:
python start.py --reinstall --verbosePermission errors removing venv (Windows):
rmdir /s /q venvHow do I switch between portable and standard mode?
--reinstall to remove the existing environment and choose againpython start.py --reinstall --portable or python start.py --reinstall --no-portableI shared my portable folder but models are downloading again:
model_cache in config.yaml to a path inside the project folderPortable mode isn't offered / I'm on Linux:
Wrong hardware detected:
nvidia-smi and AMD GPUs via rocm-smi--cpu, --nvidia, --nvidia-cu128, --rocmChecking installation type:
# The installation type is stored in venv/.install_type
cat venv/.install_type  # Linux/macOS
type venv\.install_type  # Windows
python -c "import torch; print(torch.backends.mps.is_available())"start.py launcher also applies this patch automatically.onnx==1.16.0 is pinned in all requirements files to use pre-built wheels. If you still hit issues, ensure you're using Python 3.10.config.yaml has device: auto (or device: mps) in the tts_engine section.nvidia-smi), ensure correct CUDA-enabled PyTorch is installed (see Installation options).--nvidia-cu128 or requirements-nvidia-cu128.txt instead of standard NVIDIA installation--nvidia or requirements-nvidia.txtchunk_size (e.g., 100-150).onnx==1.16.0 is pinned. The updated requirements files handle this automatically.chatterbox-tts, librosa): Ensure virtual environment is active and dependencies installed successfully. Try reinstalling: python start.py --reinstalllibsndfile Error (Linux): Run sudo apt install libsndfile1.ChatterboxTTS.from_pretrained() will attempt to download from Hugging Face Hub. Ensure model.repo_id in config.yaml is correct../reference_audio, ./voices)../config.yaml, ./logs, ./outputs, ./reference_audio, ./voices, and the Hugging Face cache directory if using Docker volumes.config.yaml is writable by the server process.Address already in use): Another process is using the port. Stop it or change server.port in config.yaml (requires server restart).
netstat -ano | findstr :8004 (Windows) or lsof -i :8004 (Linux)Set the CUDA_VISIBLE_DEVICES environment variable before running python server.py (or before running the launcher) to specify which GPU(s) PyTorch should see. The server uses the first visible one (effectively cuda:0 from PyTorch's perspective).
Example (Use only physical GPU 1):
CUDA_VISIBLE_DEVICES="1" python server.pyset CUDA_VISIBLE_DEVICES=1 && python server.py$env:CUDA_VISIBLE_DEVICES="1"; python server.pyExample (Use physical GPUs 6 and 7 - server uses GPU 6):
CUDA_VISIBLE_DEVICES="6,7" python server.pyset CUDA_VISIBLE_DEVICES=6,7 && python server.py$env:CUDA_VISIBLE_DEVICES="6,7"; python server.pyNote: CUDA_VISIBLE_DEVICES selects GPUs; it does not fix OOM errors if the chosen GPU lacks sufficient memory.
Check Python version:
python --version
Check PyTorch and CUDA:
python -c "import torch; print(f'PyTorch: {torch.__version__}'); print(f'CUDA: {torch.cuda.is_available()}')"
Check PyTorch architectures (for Blackwell support):
python -c "import torch; print(torch.cuda.get_arch_list())"
Test server manually:
# Activate venv first, then:
python server.py
config.yaml for settings. The docker-compose files mount your local config.yaml to /app/config.yaml inside the container.config.yaml doesn't exist locally, the application will create a default one with sensible defaults.config.yaml directly. Changes to server/model/path settings require a container restart:
docker compose restart chatterbox-tts-server
Persistent data is stored on your host machine via volume mounts:
./config.yaml:/app/config.yaml - Main application configuration./voices:/app/voices - Predefined voice audio files./reference_audio:/app/reference_audio - Your uploaded reference audio files for cloning./outputs:/app/outputs - Generated audio files saved from UI/API./logs:/app/logs - Server log fileshf_cache:/app/hf_cache - Named volume for Hugging Face model cache (persists downloads)Managing volumes:
# Remove all data (including downloaded models)
docker compose down -v

# Remove only application data (keep model cache)
docker compose down
sudo rm -rf voices/ reference_audio/ outputs/ logs/ config.yaml

# View volume usage
docker system df
python -c "import torch; print(torch.backends.mps.is_available())"pip install onnx==1.16.0 as shown in the installation steps.config.yaml has device: mps in the tts_engine section.nvidia-smi), ensure correct CUDA-enabled PyTorch is installed (Installation Step 4).chunk_size (e.g., 100-150).chatterbox-tts, librosa): Ensure virtual environment is active and pip install -r requirements.txt completed successfully.libsndfile Error (Linux): Run sudo apt install libsndfile1.ChatterboxTTS.from_pretrained() will attempt to download from Hugging Face Hub. Ensure model.repo_id in config.yaml is correct../reference_audio, ./voices)../config.yaml, ./logs, ./outputs, ./reference_audio, ./voices, and the Hugging Face cache directory if using Docker volumes.config.yaml is writable by the server process.Address already in use): Another process is using the port. Stop it or change server.port in config.yaml (requires server restart).Set the CUDA_VISIBLE_DEVICES environment variable before running python server.py to specify which GPU(s) PyTorch should see. The server uses the first visible one (effectively cuda:0 from PyTorch's perspective).
Example (Use only physical GPU 1):
CUDA_VISIBLE_DEVICES="1" python server.pyset CUDA_VISIBLE_DEVICES=1 && python server.py$env:CUDA_VISIBLE_DEVICES="1"; python server.pyExample (Use physical GPUs 6 and 7 - server uses GPU 6):
CUDA_VISIBLE_DEVICES="6,7" python server.pyset CUDA_VISIBLE_DEVICES=6,7 && python server.py$env:CUDA_VISIBLE_DEVICES="6,7"; python server.pyNote: CUDA_VISIBLE_DEVICES selects GPUs; it does not fix OOM errors if the chosen GPU lacks sufficient memory.
Contributions are welcome! Please feel free to open an issue to report bugs or suggest features, or submit a Pull Request for improvements.
This project is licensed under the MIT License.
You can find it here: https://opensource.org/licenses/MIT
609 followers · starred Aug 2026
187 followers · starred Jun 2025
17 followers · starred Jul 2025
1,474 followers · starred Sep 2025