
One Mac process. Many models. Real speed. Multi-model LLM serving with prefix reuse, MTP acceleration, and OpenAI APIs — built for Apple Silicon, measured against mlx-lm and llama.cpp.
See the codeREADME
AX Engine
AX Engine is a Mac-first Apple Silicon inference runtime optimized first for Qwen 3.8 27B AXQ, with maintained support for additional Qwen, Gemma, GLM, and other certified families. Install with Homebrew, download the pinned 27B pack, and serve OpenAI-compatible endpoints locally.
Primary optimization target. Checkpoint Tier 1. MTP Tier 2 pending. AX certification record: Candidate (gates open).
The default pack is qwen3.8-27b:axq
(AutomatosX/AX-Qwen3.8-27B-MLX-AXQ-6bit-MTP
@ 3e290738e96972307c6aeb9934ab170ca0eae1c1). Other families stay supported;
they are not the first-run or qualification center. Super-class Qwen 3.8 (2.4T)
is experimental only.
NVIDIA/CUDA fleet serving lives in AX Serving. AX Engine remains the local Apple Silicon runtime and no longer ships the former vLLM or TensorRT provider bridges, runtime package, container, or CUDA qualification scripts.
Browse AutomatosX serve-ready chat / coding / embedding snapshots in the AutomatosX model collection on Hugging Face. Additional native families (GLM 4.7 Flash, Nemotron Omni, Unlimited-OCR, Whisper, MiniCPM-V, and others) are documented under Supported Models.
Requires macOS 26 (Tahoe)+ on Apple Silicon (M2 or newer). Product SKUs:
- Mac mini M4 Pro 64 GB — best experience for Qwen 3.8 27B AXQ (
qwen3.8-27b:axq) - MacBook Pro M5 Max 128 GB — qualification target for Qwen 3.8 Flash Next MXFP4 MTP
(125B-A6B). Second SKU. MXFP4 MTP target; native support and checkpoint qualification pending. MTP Tier 2 pending. AX certification record: Candidate (gates open). The existing
qwen3.8-flash-next:axqalias selects affine 4-bit, not MXFP4.
Compact single models (Qwen 3.5 9B 4-bit preferred) still fit 16 GB. Prefer 4-bit for headroom on that class.
Why AX Engine
- Optimized first for Qwen 3.8 27B AXQ — one download of
qwen3.8-27b:axqis the default serve path. Direct and MTP refresh rows live in Performance; MTP speedup is workload-dependent and MTP Tier 2 is still pending - Speculative decode on the default pack — product-path MTP on
qwen3.8-27b:axqis the number in Performance. MTP Tier 2 is still pending. Same-package peers that cannot load this AXQ snapshot are listed as unsupported rather than substituted with another checkpoint - Multi-model on one process — keep a scoped set of Qwen 3.5/3.6,
Qwen3-Coder-Next, Gemma 4, and embedding models resident (
load_mode=add), route by requestmodel(chat + embeddings together), with fair Metal turn arbitration, memory preflight, and optional idle eviction. Exact-prompt prefix reuse is the S1 differentiator: official dual-model campaign (Qwen stream + Gemma 13.8k prefill) clears all locked gates at 5.03× median throughput vs a multi-process peer MLX server — see Performance and Server: Multi-model - You own the stack you serve — AX runs the MLX graph, KV/runtime, and
OpenAI-compatible server for supported Gemma / Qwen / GLM (and other direct
families);
mlx-lmandllama.cppstay optional compatibility adapters - Engine-owned scheduling and KV — continuous batched decode
(certification-gated), chunked prefill, preempt-and-recompute, and a paged
KV ledger with cross-request prefix sharing run inside the engine, with a
published
ax_runtime_*saturation contract for fleet routers — see Scheduling and KV runtime - Native media and speech — image/video chat, mixed image+audio reasoning, OCR, and Whisper transcription/translation run through repo-owned MLX graphs with capability-gated OpenAI endpoints (checkpoint-authoritative; see media table below)
- Clear fleet boundary — AX Engine owns local Apple Silicon inference; AX Serving owns fleet orchestration and NVIDIA/CUDA workers
- Claims you can audit — public rows ship with checked-in artifacts (route, model snapshot, sampler, accept rate, provenance)
Quick Start
Homebrew (primary)
brew install defai-digital/tap/ax-engine
ax-engine doctor
Homebrew is the primary install path for the CLI, server, and bench tools.
The self-contained release formula installs the release's pinned
libmlx.dylib, libjaccl.dylib, and precompiled mlx.metallib; it does not
build MLX from source. End users therefore do not need Python, Xcode, or the
Metal Toolchain.
Python SDK (pip)
Use the wheel for Python applications that import ax_engine, optional Python
integrations, or systems where Homebrew is unavailable. Install it in a virtual
environment:
python3 -m venv .venv
source .venv/bin/activate
python3 -m pip install --upgrade pip
python3 -m pip install --upgrade "ax-engine[download]>=7.4.0,<8"
ax-engine doctor
The wheel also exposes ax-engine and ax-engine-server and bundles the bench
binary used by diagnostics. If both Homebrew and pip are installed, an active
virtual environment normally wins on PATH; use which -a ax-engine to see
every copy and prefer one installation channel in each shell. See
Getting Started for the full channel comparison and
troubleshooting.
Run AX Engine
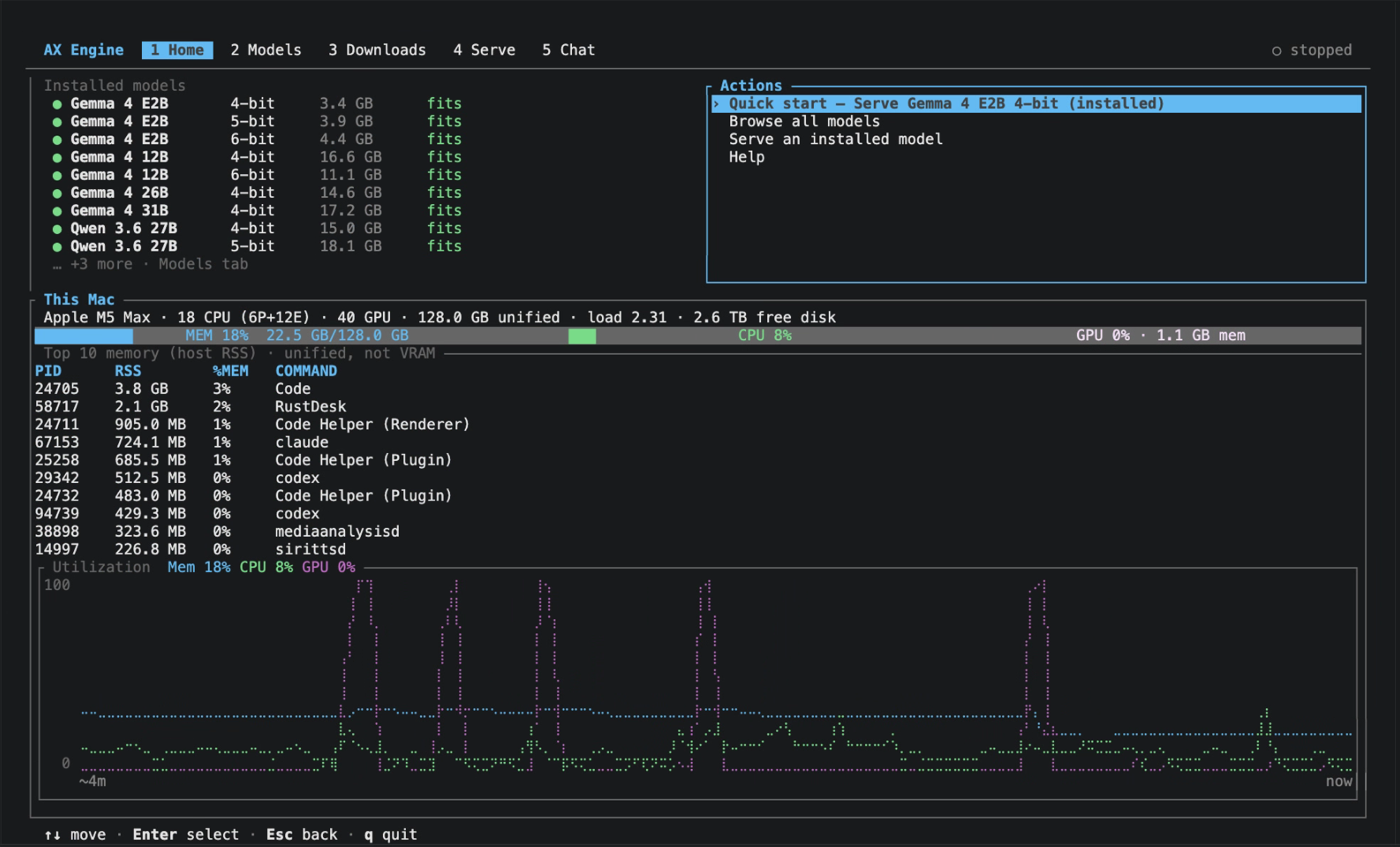
Option A — interactive TUI (pick a model, download, serve, chat):
ax-engine tui
Option B — serve Qwen 3.8 27B AXQ 6-bit MTP, then request from another
terminal. qwen3.8-27b:axq is the pinned AutomatosX 6-bit MTP pack (same
checkpoint as ax-qwen3.8-27b). The command reuses the cached snapshot when
present and downloads it otherwise. Listen defaults to 127.0.0.1:31418:
ax-engine serve qwen3.8-27b:axq

curl http://127.0.0.1:31418/v1/chat/completions \
  -H 'content-type: application/json' \
  -d '{"model":"qwen3.8-27b","messages":[{"role":"user","content":"Say hello in one sentence."}],"max_tokens":64}'
Option C — coding model (resolve + serve):
ax-engine serve ax-qwen3-coder-next --port 31418
Python wheel, source builds, and troubleshooting: Getting Started.
Models
Managed AutomatosX catalog (download / TUI)
ax-engine download --list and the TUI expose the curated public
AutomatosX model collection
only — not every community MLX weight. Qwen 3.8 27B AXQ (6-bit MTP default),
Qwen 3.6, Qwen 3.5, and Gemma 4 variants published there (plain 4-bit/6-bit,
QAT, OptiQ, AXQ where available) are first-class serve targets. Other native families (for example GLM 4.7 Flash, Nemotron
Omni, Unlimited-OCR, Whisper, MiniCPM-V) use the repo-owned runtime via serve
aliases, presets, or manual model directories; they are not all AutomatosX-managed
packages. Full matrix:
Supported Models.
Qwen 3.8 Super-class (2.4T) is experimental only, not a production target.
Those packs can technically load through the SSD expert-stream path
(--stream-experts, default auto), but local inference is too slow even at
2-bit to recommend or certify. Start local serving on Qwen 3.8 27B AXQ
6-bit MTP (qwen3.8-27b:axq).
Recommended starting packages (serve-ready, match published benches):
| Goal | Alias / family | Why |
|---|---|---|
| Default dense chat + MTP | qwen3.8-27b:axq (pinned AXQ 6-bit MTP) | Production-size Qwen 3.8 27B; AutomatosX AXQ 6-bit with MTP sidecar |
| Fastest MoE chat + MTP | ax-qwen3.6-35b-a3b (4-bit or 6-bit MTP) | Strongest serving and MTP peer decode rows |
| Dense chat + MTP (3.6) | ax-qwen3.6-27b (6-bit MTP preferred) | High same-package MTP speedup; solid serving |
| AXQ evaluation candidate | qwen3.6-27b:axq (pinned 6-bit) | Qwen 3.6 27B AXQ candidate; explicit until its checkpoint certification gates pass |
| Vision MoE Instruct AXQ | ax-qwen3-vl-30b / ax-qwen3-vl-30b-4bit | Qwen3-VL 30B-A3B Instruct AXQ packs; candidate, no MTP |
| Holo3 GUI-agent AXQ | holo3-35b / holo3-35b:axq | Qwen3.5-class 35B-A3B MoE; Tier 1 certified text path; no MTP |
| Ornith coding AXQ | ornith-35b / ornith-35b:axq | Qwen3.5-class 35B-A3B MoE coding agent; Tier 1 AXQ; no MTP |
| Ornith 1.5 MTP | ornith-1.5-35b:axq | Qwen3.5-class 35B-A3B MoE with HF per-expert MTP sidecar; development pack |
| GPT-OSS AXQ | gpt-oss-20b:axq / gpt-oss-120b:axq | AutomatosX AXQ; bare aliases stay mlx-community MXFP4-Q4 |
| Nemotron 3 Nano AXQ | nemotron-3-nano / nemotron-3-nano:axq | nemotron_h 30B-A3B; development AXQ |
| Muse-Glimmer image-text AXQ | muse-glimmer-30b / muse-glimmer-30b:axq | Meta dense 30B image-text agent; ATEM chat; development AXQ; no MTP |
| Multimodal chat + MTP | ax-gemma4-12b / 26B / 31B Assistant-MTP | Image/audio/video + assistant draft package |
| Coding agent | ax-qwen3-coder-next | Coding-focused MoE; multi-model friendly |
| Embeddings | ax-embeddinggemma-300m or Qwen3-Embedding aliases | Batched ingest scale in full results |
Repositories ending in -MTP or -Assistant-MTP already contain the prepared
sidecar or assistant artifacts and model-manifest.json. Download them with
the standard flow; do not run download-mtp afterward.
Native multimodal and speech support is checkpoint-authoritative: AX advertises
only modalities whose required tower tensors are present in
model-manifest.json.
| Model family | Inputs | Native API surface | Current scope |
|---|---|---|---|
| Qwen3-VL; visual Qwen3.5; Qwen 3.6 | Image, video | Chat/generate | Conv3D visual patches, full ViT/merger, MRoPE, multi-image/video ordering; Qwen 3.6 27B image/video smoke-tested on M3 Max |
| Standard Gemma 4 E4B/26B/31B | Image, video | Chat/generate | Full bidirectional ViT, 2-D RoPE, spatial pooling, checkpoint standardization, and vision projection; catalogued sizes are E4B/26B/31B. E2B still loads from an explicit directory. Conformer audio is not yet native |
| Gemma 4 unified 12B | Image, audio, video | Chat/generate | Encoder-free image/audio connector and sampled per-frame video path; requires the unified connector roles |
| MiniCPM-V 4.6 | One or more images | Chat/generate | Dynamic SigLIP grid, mid-tower merger, OCR/document prompts |
| Nemotron 3 Nano Omni | Image, audio, or both | Chat/generate | RADIO vision plus Parakeet audio with ordered mixed-media spans |
| Unlimited-OCR | Image | Native processed-input runtime; delegated OpenAI OCR profile | Full prefill KV is protected; only generated-token KV uses the decode ring |
| Whisper large-v3-turbo | Audio | /v1/audio/transcriptions, /v1/audio/translations, Rust SDK | WAV/MP3 to 16 kHz; multilingual transcribe/translate; text-generation routes fail closed |
GLM-OCR is not supported.
Download helpers inspect the source tensor index and automatically rebuild
older packaged manifests that omitted a declared Qwen or Gemma vision tower.
For an existing manual model directory, run
ax-engine-bench generate-manifest --force /path/to/model.
The default Hugging Face cache layout is
models--AutomatosX--<repository>/snapshots/<revision>. Use the shorter
ax-* aliases shown by ax-engine download --list; for example:
ax-engine serve qwen3.8-27b:axq
ax-engine serve qwen3.8-27b:axq --offline  # require the pinned 6-bit MTP cache
Aliases, hardware sizing, and legacy MTP packaging targets: Supported Models · Qwen 3.6 27B AXQ certification · Hardware FAQ · CLI.
AXQ endurance evidence
AX Engine 6.13.5 completed an 8-hour endurance test with 8.87 hours of continuous measured runtime for the pinned Qwen 3.6 27B AXQ 6-bit model on a 64 GB M4 Pro Mac mini: 437/437 requests succeeded, the owned server did not restart, and no retained-RSS growth, swap, lifecycle-drain failure, or performance guardrail breach was observed. The operator stopped this run to add deeper vLLM-style leak attribution before restarting the full 72-hour qualification, so it is short-duration evidence, not a 72-hour pass. Read the 8-hour endurance report or use the reusable AXQ endurance utility and detached launch procedure to verify another local AXQ package.
Multi-model serving
One process can keep several allowlisted models loaded and route each
request by model (OpenAI, gRPC, Ollama, Anthropic). Add mode is limited to
Qwen 3.5 9B, Qwen 3.6 27B/35B, Qwen3-Coder-Next, Gemma 4 12B/26B/31B, and the
EmbeddingGemma 300M / Qwen3-Embedding 0.6B–8B embedding models (chat +
embeddings from one process); AutomatosX AX- package names resolve to the
same targets. Each model owns its own session and scheduler while a process
arbiter fair-rotates Metal turns (no fused cross-model batch).
# After a first model is already serving on :31418
curl -s http://127.0.0.1:31418/v1/model/load -H 'content-type: application/json' -d '{
  "model_id": "gemma-4-12b-it",
  "model_path": "/path/to/gemma-4-12b-artifacts",
  "load_mode": "add",
  "make_default": false
}'

curl -s http://127.0.0.1:31418/v1/chat/completions -H 'content-type: application/json' -d '{
  "model": "gemma-4-12b-it",
  "messages": [{"role": "user", "content": "Hi"}],
  "max_tokens": 32
}'
Full contract (load/unload, memory preflight, idle eviction, metrics labels): Server: Multi-model serving · Supported Models.
Scheduling and KV runtime
Token-level scheduling is owned by the engine, not a gateway: each step the scheduler builds a decode-first, token-budgeted batch with chunked prefill and mixed prefill+decode routes, backed by a paged logical KV ledger. Full design: Scheduler · KV Cache · Serving Invariants.
- Continuous batched decode — structurally eligible decode requests share
one batched forward (default on;
AX_MLX_BATCHED_DECODE=0is the kill switch) behind a fail-closed bit-exact certification gate; host-sampled batching is a separate opt-in - Paged KV ledger with prefix sharing — per-request block tables, ref-counted cross-request prefix reuse, tiered eviction, and an optional disk-durable prefix cache that survives restarts
- Pressure handling — KV memory-pressure throttling, preempt-and-recompute
(newest in-flight prefill only, never decode), and server admission control
(global and per-model concurrency caps →
429) - Fleet telemetry contract —
/metricspublishes versionedax_runtime_*saturation series (KV utilization, queue depth, batch headroom, TTFT p95, decode tok/s, error rate) that AX Serving and other routers consume for node selection; token scheduling itself stays on-box
Current dense batched-decode ceiling. On the strict M5 Max projection probe, the default Shared policy reaches 328.9 aggregate tok/s at B=8 (4.01× its B=1 throughput), versus 102.6 tok/s / 1.25× for the RowExact fallback. The paired Shared/RowExact ratio is 3.20× with five of five wins and identical full-cohort greedy hashes. This is a dense Llama-3.1-8B, 32-token-prefill microbenchmark—not an end-to-end serving, long-prompt, or MoE claim. Production continuous-batching claims still require matching serving evidence—see Batched decode ceiling and Long Context claim boundaries.
Performance
Qualification SKU: Mac mini M4 Pro 64 GB (2026-09-17)
Same-pack measurements on the selected SKU (Mac16,11, macOS 26.6.2) with the
installed bundled wheel built from clean ad999f3f, which includes the
target-head and low-precision SwiGLU corrections. Same flappy contract as
below (four cases, 256 gen, greedy, thinking disabled, 2 warmups, 5 measured
reps, 3 s cooldown); decode and prefill are 20-run medians. Evidence:
benchmarks/results/mtp-axq-peer/2026-09-17-mac-mini-m4-pro-64gb/.
| Runtime | Latest checked 2026-09-17 | Decode | Prefill |
|---|---|---|---|
AX Engine 7.4.0 (product-path MTP, depth 3, clean ad999f3f) | installed wheel | 31.05 tok/s | 120.3 tok/s |
| MTPLX 2.11.3 | PyPI Latest | 28.16 tok/s | 114.0 tok/s |
| OMLX 0.6.4 (imported sidecar, Lightning depth 1) | GitHub Latest release | 15.02 tok/s | — |
| mlx-lm 0.31.3 (direct AR baseline) | PyPI Latest | 12.78 tok/s | — |
Two host daemons held about 1.2 CPU cores throughout; every lane ran under that condition and the AX lane was repeated with agreement within 0.4%. These are throughput numbers on the qualification SKU, not a quality or certification claim; the record stays Candidate.
Why the M4 Pro and M5 Max numbers differ: memory bandwidth
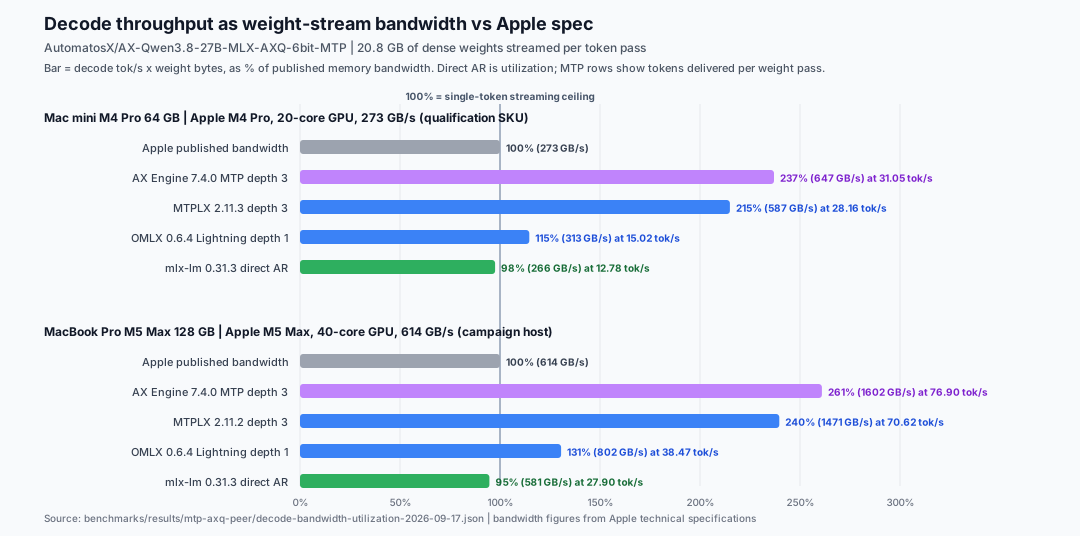
Decode on this 6-bit 27B pack streams 20.84 GB of dense weights per token. Direct autoregressive decode (mlx-lm) already uses 97.5% of the Mac mini M4 Pro's published 273 GB/s and 94.7% of the M5 Max's 614 GB/s, so the 2.2x decode gap is the 2.25x bandwidth gap. MTP moves past that ceiling by emitting about 3.9 tokens per weight pass. Prefill is compute-bound and the M5 Max has twice the GPU cores plus per-core neural accelerators, which is why its prefill lead is 6x for both AX and MTPLX. Full analysis: docs/performance/decode-bandwidth-utilization.md.
| Host | Published bandwidth | mlx-lm direct AR | Weight stream | Utilization | AX Engine MTP | Equivalent stream |
|---|---|---|---|---|---|---|
| Mac mini M4 Pro 64 GB | 273 GB/s | 12.78 tok/s | 266 GB/s | 97.5% | 31.05 tok/s | 647 GB/s (237%) |
| MacBook Pro M5 Max 128 GB | 614 GB/s | 27.90 tok/s | 581 GB/s | 94.7% | 76.90 tok/s | 1602 GB/s (261%) |
Campaign host: Apple M5 Max 128 GB (2026-09-15)
Historical same-pack measurements with the runtimes available on 2026-09-15:
qwen3.8-27b:axq
@ 3e290738e96972307c6aeb9934ab170ca0eae1c1. Apple M5 Max, 128 GB
(campaign host, not the Mac mini M4 Pro 64 GB SKU). flappy suite, four cases,
256 gen, greedy, 2 warmups, 5 measured reps, 3 s cooldown. Decode is the
median of 20 measured runs. Same snapshot directory for every runtime;
no GGUF or community-4-bit substitute.
These measurements predate the target-head precision fix that removes the automatic 2-bit decode cache and the low-precision SwiGLU correction that replaces the fused dense activation with the split MLX operations. They do not establish throughput or numerical parity for the corrected runtime. A same-session A/B on this campaign host (recorded under the 2026-09-17 SwiGLU consistency evidence) measured decode within 0.3% and prefill 0.5-1.4% below the 2026-09-15 binary after both corrections. The corrected runtime's peer numbers with a recorded build commit are the qualification-SKU table above; a refresh of this M5 Max table is still pending.
| Runtime | Latest checked | Decode | Prefill |
|---|---|---|---|
| AX Engine 7.4.0 (product-path MTP, depth 3) | 2026-09-15 campaign | 76.90 tok/s | 795.3 tok/s |
| MTPLX 2.11.2 | PyPI / mtplx.com Latest | 70.62 tok/s | 686.6 tok/s |
| mlx-lm 0.31.3 (direct AR baseline) | PyPI Latest | 27.90 tok/s | — |
| mlxcel 0.7.0 | GitHub Latest (2026-09-09) | unsupported (AXQ 6-bit affine group layout) | — |
| OMLX 0.6.4 (imported sidecar, Lightning depth 1) | GitHub Latest release | 38.47 tok/s | — |
| llama.cpp 0.4.0 (formula 0.4.1) | Homebrew | unsupported (not GGUF) | — |
| mistral.rs 0.9.3 | GitHub Latest | unsupported (no AXQ MLX loader on host) | — |
| exo 1.0.71 | GitHub Latest | unsupported (cluster runtime) | — |
| rMLX 0.4.1 | GitHub Latest | unsupported (no campaign binary) | — |
| uzu 0.5.26 | PyPI | unsupported (Mirai checkpoints, not this pack) | — |
| vLLM 0.29.0 | PyPI | unsupported (CUDA, not Apple Silicon) | — |
AX and MTPLX loaded the snapshot and completed the MTP contract. Decode and
prefill are 20-run medians on the same flappy prompts (prompt lengths
264–432 tokens). mlx-lm 0.31.3 is a direct-AR decode baseline (first generated
token excluded; prefill not split in that harness). OMLX 0.6.4 required a
writable snapshot plus import_mtplx_sidecar; Lightning MTP ran at draft
depth 1 and the OMLX runner reports generate-wall tok/s (prefill not split).
mlxcel 0.7.0 still fails to load this AXQ affine layout.
Unsupported is not replaced with another checkpoint. MTP Tier 2 remains
pending. Artifacts:
2026-09-15 campaign.
Archived Qwen 3.6 serving, multi-model S1, embeddings, and the 2026-08-31 depth-1 AX / MTPLX 2.9.0 / OMLX 0.6.4 table stay in Performance Results and Benchmarks.
SDKs
Most clients use the OpenAI-compatible HTTP server. Python also has an in-process session API.
| SDK | Docs |
|---|---|
| Rust | docs/sdk/rust.md |
| Python | docs/sdk/python.md |
| JavaScript / TypeScript | docs/sdk/javascript.md |
| Go | docs/sdk/go.md |
| Ruby | docs/sdk/ruby.md |
| Swift | docs/sdk/swift.md |
| Mojo (experimental) | docs/sdk/mojo.md |
Server
ax-engine serve is the normal entrypoint (see Quick Start). Default listen is
127.0.0.1:31418 (not AX Serving’s 18080). Port map, LAN bind, and
Serving vs Engine:
curl http://127.0.0.1:31418/v1/runtime
Auth, streaming, embeddings, Ollama-shaped routes: Server · API Compatibility · OpenClaw. Fleet / NVIDIA serving: AX Serving.
Documentation
| Need | Read |
|---|---|
| Docs hub | docs/README.md |
| Install and first request | Getting Started |
| Ports, bind host, Engine vs Serving | Ports |
| Models and MTP packages | Supported Models · MTP Docs |
| Hardware / FAQ | FAQ |
| Full performance tables | Performance Results |
| Serving peer (newest) | Serving peer detail |
| Reproduce benchmarks | Benchmarks |
| Server / API / SDKs | Server · API · OpenClaw · SDKs |
| Fleet / NVIDIA (AX Serving) | AX Serving |
| Architecture | Architecture |
| Scheduler / KV internals | Scheduler · KV Cache · Serving Invariants |
Development
cargo build --workspace
cargo test --quiet
cargo clippy --all-targets --all-features -- -D warnings
cargo fmt --check
maturin develop
python -m unittest discover -s python/tests -v
Crate layout and conventions: AGENTS.md · Architecture.
Limitations
- Qwen3.5 long-prompt prefill can trail upstream MLX references on longer prompts
- Raw HuggingFace / mlx-community snapshots load directly:
model-manifest.jsonis auto-generated fromconfig.json+ safetensors headers on first load and weight sanitization is auto-detected, somlx_lm.convertis not required - N-gram acceleration is workload-dependent, not a raw kernel speedup
- NVIDIA/CUDA serving requires the separate AX Serving product
Details: FAQ limitations.
Contributing
Issues, wishlist items, reproducible benchmarks, and docs feedback are welcome. Unsolicited code PRs for runtime, kernel, scheduler, or performance paths are generally not accepted — open an issue first. See CONTRIBUTING.md.
Community
- Website: automatosx.com
- Discord: Join us
- Email: enquiry@defai.digital
Acknowledgments
AX Engine is grateful to the open-source foundations, benchmarking peers, and community contributors listed in Acknowledgments.
License
Apache License, Version 2.0. See LICENSE.
Copyright (c) 2026 DEFAI Private Limited
Contributors


Similar repos


Languages
Rust
65.5%
Python
27.5%
HTML
2.7%
Shell
1.8%
One Mac process. Many models. Real speed. Multi-model LLM serving with prefix reuse, MTP acceleration, and OpenAI APIs — built for Apple Silicon, measured against mlx-lm and llama.cpp.
See the codeREADME
AX Engine
AX Engine is a Mac-first Apple Silicon inference runtime optimized first for Qwen 3.8 27B AXQ, with maintained support for additional Qwen, Gemma, GLM, and other certified families. Install with Homebrew, download the pinned 27B pack, and serve OpenAI-compatible endpoints locally.
Primary optimization target. Checkpoint Tier 1. MTP Tier 2 pending. AX certification record: Candidate (gates open).
The default pack is qwen3.8-27b:axq
(AutomatosX/AX-Qwen3.8-27B-MLX-AXQ-6bit-MTP
@ 3e290738e96972307c6aeb9934ab170ca0eae1c1). Other families stay supported;
they are not the first-run or qualification center. Super-class Qwen 3.8 (2.4T)
is experimental only.
NVIDIA/CUDA fleet serving lives in AX Serving. AX Engine remains the local Apple Silicon runtime and no longer ships the former vLLM or TensorRT provider bridges, runtime package, container, or CUDA qualification scripts.
Browse AutomatosX serve-ready chat / coding / embedding snapshots in the AutomatosX model collection on Hugging Face. Additional native families (GLM 4.7 Flash, Nemotron Omni, Unlimited-OCR, Whisper, MiniCPM-V, and others) are documented under Supported Models.
Requires macOS 26 (Tahoe)+ on Apple Silicon (M2 or newer). Product SKUs:
- Mac mini M4 Pro 64 GB — best experience for Qwen 3.8 27B AXQ (
qwen3.8-27b:axq) - MacBook Pro M5 Max 128 GB — qualification target for Qwen 3.8 Flash Next MXFP4 MTP
(125B-A6B). Second SKU. MXFP4 MTP target; native support and checkpoint qualification pending. MTP Tier 2 pending. AX certification record: Candidate (gates open). The existing
qwen3.8-flash-next:axqalias selects affine 4-bit, not MXFP4.
Compact single models (Qwen 3.5 9B 4-bit preferred) still fit 16 GB. Prefer 4-bit for headroom on that class.
Why AX Engine
- Optimized first for Qwen 3.8 27B AXQ — one download of
qwen3.8-27b:axqis the default serve path. Direct and MTP refresh rows live in Performance; MTP speedup is workload-dependent and MTP Tier 2 is still pending - Speculative decode on the default pack — product-path MTP on
qwen3.8-27b:axqis the number in Performance. MTP Tier 2 is still pending. Same-package peers that cannot load this AXQ snapshot are listed as unsupported rather than substituted with another checkpoint - Multi-model on one process — keep a scoped set of Qwen 3.5/3.6,
Qwen3-Coder-Next, Gemma 4, and embedding models resident (
load_mode=add), route by requestmodel(chat + embeddings together), with fair Metal turn arbitration, memory preflight, and optional idle eviction. Exact-prompt prefix reuse is the S1 differentiator: official dual-model campaign (Qwen stream + Gemma 13.8k prefill) clears all locked gates at 5.03× median throughput vs a multi-process peer MLX server — see Performance and Server: Multi-model - You own the stack you serve — AX runs the MLX graph, KV/runtime, and
OpenAI-compatible server for supported Gemma / Qwen / GLM (and other direct
families);
mlx-lmandllama.cppstay optional compatibility adapters - Engine-owned scheduling and KV — continuous batched decode
(certification-gated), chunked prefill, preempt-and-recompute, and a paged
KV ledger with cross-request prefix sharing run inside the engine, with a
published
ax_runtime_*saturation contract for fleet routers — see Scheduling and KV runtime - Native media and speech — image/video chat, mixed image+audio reasoning, OCR, and Whisper transcription/translation run through repo-owned MLX graphs with capability-gated OpenAI endpoints (checkpoint-authoritative; see media table below)
- Clear fleet boundary — AX Engine owns local Apple Silicon inference; AX Serving owns fleet orchestration and NVIDIA/CUDA workers
- Claims you can audit — public rows ship with checked-in artifacts (route, model snapshot, sampler, accept rate, provenance)
Quick Start
Homebrew (primary)
brew install defai-digital/tap/ax-engine
ax-engine doctor
Homebrew is the primary install path for the CLI, server, and bench tools.
The self-contained release formula installs the release's pinned
libmlx.dylib, libjaccl.dylib, and precompiled mlx.metallib; it does not
build MLX from source. End users therefore do not need Python, Xcode, or the
Metal Toolchain.
Python SDK (pip)
Use the wheel for Python applications that import ax_engine, optional Python
integrations, or systems where Homebrew is unavailable. Install it in a virtual
environment:
python3 -m venv .venv
source .venv/bin/activate
python3 -m pip install --upgrade pip
python3 -m pip install --upgrade "ax-engine[download]>=7.4.0,<8"
ax-engine doctor
The wheel also exposes ax-engine and ax-engine-server and bundles the bench
binary used by diagnostics. If both Homebrew and pip are installed, an active
virtual environment normally wins on PATH; use which -a ax-engine to see
every copy and prefer one installation channel in each shell. See
Getting Started for the full channel comparison and
troubleshooting.
Run AX Engine
Option A — interactive TUI (pick a model, download, serve, chat):
ax-engine tui
Option B — serve Qwen 3.8 27B AXQ 6-bit MTP, then request from another
terminal. qwen3.8-27b:axq is the pinned AutomatosX 6-bit MTP pack (same
checkpoint as ax-qwen3.8-27b). The command reuses the cached snapshot when
present and downloads it otherwise. Listen defaults to 127.0.0.1:31418:
ax-engine serve qwen3.8-27b:axq

curl http://127.0.0.1:31418/v1/chat/completions \
  -H 'content-type: application/json' \
  -d '{"model":"qwen3.8-27b","messages":[{"role":"user","content":"Say hello in one sentence."}],"max_tokens":64}'
Option C — coding model (resolve + serve):
ax-engine serve ax-qwen3-coder-next --port 31418
Python wheel, source builds, and troubleshooting: Getting Started.
Models
Managed AutomatosX catalog (download / TUI)
ax-engine download --list and the TUI expose the curated public
AutomatosX model collection
only — not every community MLX weight. Qwen 3.8 27B AXQ (6-bit MTP default),
Qwen 3.6, Qwen 3.5, and Gemma 4 variants published there (plain 4-bit/6-bit,
QAT, OptiQ, AXQ where available) are first-class serve targets. Other native families (for example GLM 4.7 Flash, Nemotron
Omni, Unlimited-OCR, Whisper, MiniCPM-V) use the repo-owned runtime via serve
aliases, presets, or manual model directories; they are not all AutomatosX-managed
packages. Full matrix:
Supported Models.
Qwen 3.8 Super-class (2.4T) is experimental only, not a production target.
Those packs can technically load through the SSD expert-stream path
(--stream-experts, default auto), but local inference is too slow even at
2-bit to recommend or certify. Start local serving on Qwen 3.8 27B AXQ
6-bit MTP (qwen3.8-27b:axq).
Recommended starting packages (serve-ready, match published benches):
| Goal | Alias / family | Why |
|---|---|---|
| Default dense chat + MTP | qwen3.8-27b:axq (pinned AXQ 6-bit MTP) | Production-size Qwen 3.8 27B; AutomatosX AXQ 6-bit with MTP sidecar |
| Fastest MoE chat + MTP | ax-qwen3.6-35b-a3b (4-bit or 6-bit MTP) | Strongest serving and MTP peer decode rows |
| Dense chat + MTP (3.6) | ax-qwen3.6-27b (6-bit MTP preferred) | High same-package MTP speedup; solid serving |
| AXQ evaluation candidate | qwen3.6-27b:axq (pinned 6-bit) | Qwen 3.6 27B AXQ candidate; explicit until its checkpoint certification gates pass |
| Vision MoE Instruct AXQ | ax-qwen3-vl-30b / ax-qwen3-vl-30b-4bit | Qwen3-VL 30B-A3B Instruct AXQ packs; candidate, no MTP |
| Holo3 GUI-agent AXQ | holo3-35b / holo3-35b:axq | Qwen3.5-class 35B-A3B MoE; Tier 1 certified text path; no MTP |
| Ornith coding AXQ | ornith-35b / ornith-35b:axq | Qwen3.5-class 35B-A3B MoE coding agent; Tier 1 AXQ; no MTP |
| Ornith 1.5 MTP | ornith-1.5-35b:axq | Qwen3.5-class 35B-A3B MoE with HF per-expert MTP sidecar; development pack |
| GPT-OSS AXQ | gpt-oss-20b:axq / gpt-oss-120b:axq | AutomatosX AXQ; bare aliases stay mlx-community MXFP4-Q4 |
| Nemotron 3 Nano AXQ | nemotron-3-nano / nemotron-3-nano:axq | nemotron_h 30B-A3B; development AXQ |
| Muse-Glimmer image-text AXQ | muse-glimmer-30b / muse-glimmer-30b:axq | Meta dense 30B image-text agent; ATEM chat; development AXQ; no MTP |
| Multimodal chat + MTP | ax-gemma4-12b / 26B / 31B Assistant-MTP | Image/audio/video + assistant draft package |
| Coding agent | ax-qwen3-coder-next | Coding-focused MoE; multi-model friendly |
| Embeddings | ax-embeddinggemma-300m or Qwen3-Embedding aliases | Batched ingest scale in full results |
Repositories ending in -MTP or -Assistant-MTP already contain the prepared
sidecar or assistant artifacts and model-manifest.json. Download them with
the standard flow; do not run download-mtp afterward.
Native multimodal and speech support is checkpoint-authoritative: AX advertises
only modalities whose required tower tensors are present in
model-manifest.json.
| Model family | Inputs | Native API surface | Current scope |
|---|---|---|---|
| Qwen3-VL; visual Qwen3.5; Qwen 3.6 | Image, video | Chat/generate | Conv3D visual patches, full ViT/merger, MRoPE, multi-image/video ordering; Qwen 3.6 27B image/video smoke-tested on M3 Max |
| Standard Gemma 4 E4B/26B/31B | Image, video | Chat/generate | Full bidirectional ViT, 2-D RoPE, spatial pooling, checkpoint standardization, and vision projection; catalogued sizes are E4B/26B/31B. E2B still loads from an explicit directory. Conformer audio is not yet native |
| Gemma 4 unified 12B | Image, audio, video | Chat/generate | Encoder-free image/audio connector and sampled per-frame video path; requires the unified connector roles |
| MiniCPM-V 4.6 | One or more images | Chat/generate | Dynamic SigLIP grid, mid-tower merger, OCR/document prompts |
| Nemotron 3 Nano Omni | Image, audio, or both | Chat/generate | RADIO vision plus Parakeet audio with ordered mixed-media spans |
| Unlimited-OCR | Image | Native processed-input runtime; delegated OpenAI OCR profile | Full prefill KV is protected; only generated-token KV uses the decode ring |
| Whisper large-v3-turbo | Audio | /v1/audio/transcriptions, /v1/audio/translations, Rust SDK | WAV/MP3 to 16 kHz; multilingual transcribe/translate; text-generation routes fail closed |
GLM-OCR is not supported.
Download helpers inspect the source tensor index and automatically rebuild
older packaged manifests that omitted a declared Qwen or Gemma vision tower.
For an existing manual model directory, run
ax-engine-bench generate-manifest --force /path/to/model.
The default Hugging Face cache layout is
models--AutomatosX--<repository>/snapshots/<revision>. Use the shorter
ax-* aliases shown by ax-engine download --list; for example:
ax-engine serve qwen3.8-27b:axq
ax-engine serve qwen3.8-27b:axq --offline  # require the pinned 6-bit MTP cache
Aliases, hardware sizing, and legacy MTP packaging targets: Supported Models · Qwen 3.6 27B AXQ certification · Hardware FAQ · CLI.
AXQ endurance evidence
AX Engine 6.13.5 completed an 8-hour endurance test with 8.87 hours of continuous measured runtime for the pinned Qwen 3.6 27B AXQ 6-bit model on a 64 GB M4 Pro Mac mini: 437/437 requests succeeded, the owned server did not restart, and no retained-RSS growth, swap, lifecycle-drain failure, or performance guardrail breach was observed. The operator stopped this run to add deeper vLLM-style leak attribution before restarting the full 72-hour qualification, so it is short-duration evidence, not a 72-hour pass. Read the 8-hour endurance report or use the reusable AXQ endurance utility and detached launch procedure to verify another local AXQ package.
Multi-model serving
One process can keep several allowlisted models loaded and route each
request by model (OpenAI, gRPC, Ollama, Anthropic). Add mode is limited to
Qwen 3.5 9B, Qwen 3.6 27B/35B, Qwen3-Coder-Next, Gemma 4 12B/26B/31B, and the
EmbeddingGemma 300M / Qwen3-Embedding 0.6B–8B embedding models (chat +
embeddings from one process); AutomatosX AX- package names resolve to the
same targets. Each model owns its own session and scheduler while a process
arbiter fair-rotates Metal turns (no fused cross-model batch).
# After a first model is already serving on :31418
curl -s http://127.0.0.1:31418/v1/model/load -H 'content-type: application/json' -d '{
  "model_id": "gemma-4-12b-it",
  "model_path": "/path/to/gemma-4-12b-artifacts",
  "load_mode": "add",
  "make_default": false
}'

curl -s http://127.0.0.1:31418/v1/chat/completions -H 'content-type: application/json' -d '{
  "model": "gemma-4-12b-it",
  "messages": [{"role": "user", "content": "Hi"}],
  "max_tokens": 32
}'
Full contract (load/unload, memory preflight, idle eviction, metrics labels): Server: Multi-model serving · Supported Models.
Scheduling and KV runtime
Token-level scheduling is owned by the engine, not a gateway: each step the scheduler builds a decode-first, token-budgeted batch with chunked prefill and mixed prefill+decode routes, backed by a paged logical KV ledger. Full design: Scheduler · KV Cache · Serving Invariants.
- Continuous batched decode — structurally eligible decode requests share
one batched forward (default on;
AX_MLX_BATCHED_DECODE=0is the kill switch) behind a fail-closed bit-exact certification gate; host-sampled batching is a separate opt-in - Paged KV ledger with prefix sharing — per-request block tables, ref-counted cross-request prefix reuse, tiered eviction, and an optional disk-durable prefix cache that survives restarts
- Pressure handling — KV memory-pressure throttling, preempt-and-recompute
(newest in-flight prefill only, never decode), and server admission control
(global and per-model concurrency caps →
429) - Fleet telemetry contract —
/metricspublishes versionedax_runtime_*saturation series (KV utilization, queue depth, batch headroom, TTFT p95, decode tok/s, error rate) that AX Serving and other routers consume for node selection; token scheduling itself stays on-box
Current dense batched-decode ceiling. On the strict M5 Max projection probe, the default Shared policy reaches 328.9 aggregate tok/s at B=8 (4.01× its B=1 throughput), versus 102.6 tok/s / 1.25× for the RowExact fallback. The paired Shared/RowExact ratio is 3.20× with five of five wins and identical full-cohort greedy hashes. This is a dense Llama-3.1-8B, 32-token-prefill microbenchmark—not an end-to-end serving, long-prompt, or MoE claim. Production continuous-batching claims still require matching serving evidence—see Batched decode ceiling and Long Context claim boundaries.
Performance
Qualification SKU: Mac mini M4 Pro 64 GB (2026-09-17)
Same-pack measurements on the selected SKU (Mac16,11, macOS 26.6.2) with the
installed bundled wheel built from clean ad999f3f, which includes the
target-head and low-precision SwiGLU corrections. Same flappy contract as
below (four cases, 256 gen, greedy, thinking disabled, 2 warmups, 5 measured
reps, 3 s cooldown); decode and prefill are 20-run medians. Evidence:
benchmarks/results/mtp-axq-peer/2026-09-17-mac-mini-m4-pro-64gb/.
| Runtime | Latest checked 2026-09-17 | Decode | Prefill |
|---|---|---|---|
AX Engine 7.4.0 (product-path MTP, depth 3, clean ad999f3f) | installed wheel | 31.05 tok/s | 120.3 tok/s |
| MTPLX 2.11.3 | PyPI Latest | 28.16 tok/s | 114.0 tok/s |
| OMLX 0.6.4 (imported sidecar, Lightning depth 1) | GitHub Latest release | 15.02 tok/s | — |
| mlx-lm 0.31.3 (direct AR baseline) | PyPI Latest | 12.78 tok/s | — |
Two host daemons held about 1.2 CPU cores throughout; every lane ran under that condition and the AX lane was repeated with agreement within 0.4%. These are throughput numbers on the qualification SKU, not a quality or certification claim; the record stays Candidate.
Why the M4 Pro and M5 Max numbers differ: memory bandwidth
Decode on this 6-bit 27B pack streams 20.84 GB of dense weights per token. Direct autoregressive decode (mlx-lm) already uses 97.5% of the Mac mini M4 Pro's published 273 GB/s and 94.7% of the M5 Max's 614 GB/s, so the 2.2x decode gap is the 2.25x bandwidth gap. MTP moves past that ceiling by emitting about 3.9 tokens per weight pass. Prefill is compute-bound and the M5 Max has twice the GPU cores plus per-core neural accelerators, which is why its prefill lead is 6x for both AX and MTPLX. Full analysis: docs/performance/decode-bandwidth-utilization.md.
| Host | Published bandwidth | mlx-lm direct AR | Weight stream | Utilization | AX Engine MTP | Equivalent stream |
|---|---|---|---|---|---|---|
| Mac mini M4 Pro 64 GB | 273 GB/s | 12.78 tok/s | 266 GB/s | 97.5% | 31.05 tok/s | 647 GB/s (237%) |
| MacBook Pro M5 Max 128 GB | 614 GB/s | 27.90 tok/s | 581 GB/s | 94.7% | 76.90 tok/s | 1602 GB/s (261%) |
Campaign host: Apple M5 Max 128 GB (2026-09-15)
Historical same-pack measurements with the runtimes available on 2026-09-15:
qwen3.8-27b:axq
@ 3e290738e96972307c6aeb9934ab170ca0eae1c1. Apple M5 Max, 128 GB
(campaign host, not the Mac mini M4 Pro 64 GB SKU). flappy suite, four cases,
256 gen, greedy, 2 warmups, 5 measured reps, 3 s cooldown. Decode is the
median of 20 measured runs. Same snapshot directory for every runtime;
no GGUF or community-4-bit substitute.
These measurements predate the target-head precision fix that removes the automatic 2-bit decode cache and the low-precision SwiGLU correction that replaces the fused dense activation with the split MLX operations. They do not establish throughput or numerical parity for the corrected runtime. A same-session A/B on this campaign host (recorded under the 2026-09-17 SwiGLU consistency evidence) measured decode within 0.3% and prefill 0.5-1.4% below the 2026-09-15 binary after both corrections. The corrected runtime's peer numbers with a recorded build commit are the qualification-SKU table above; a refresh of this M5 Max table is still pending.
| Runtime | Latest checked | Decode | Prefill |
|---|---|---|---|
| AX Engine 7.4.0 (product-path MTP, depth 3) | 2026-09-15 campaign | 76.90 tok/s | 795.3 tok/s |
| MTPLX 2.11.2 | PyPI / mtplx.com Latest | 70.62 tok/s | 686.6 tok/s |
| mlx-lm 0.31.3 (direct AR baseline) | PyPI Latest | 27.90 tok/s | — |
| mlxcel 0.7.0 | GitHub Latest (2026-09-09) | unsupported (AXQ 6-bit affine group layout) | — |
| OMLX 0.6.4 (imported sidecar, Lightning depth 1) | GitHub Latest release | 38.47 tok/s | — |
| llama.cpp 0.4.0 (formula 0.4.1) | Homebrew | unsupported (not GGUF) | — |
| mistral.rs 0.9.3 | GitHub Latest | unsupported (no AXQ MLX loader on host) | — |
| exo 1.0.71 | GitHub Latest | unsupported (cluster runtime) | — |
| rMLX 0.4.1 | GitHub Latest | unsupported (no campaign binary) | — |
| uzu 0.5.26 | PyPI | unsupported (Mirai checkpoints, not this pack) | — |
| vLLM 0.29.0 | PyPI | unsupported (CUDA, not Apple Silicon) | — |
AX and MTPLX loaded the snapshot and completed the MTP contract. Decode and
prefill are 20-run medians on the same flappy prompts (prompt lengths
264–432 tokens). mlx-lm 0.31.3 is a direct-AR decode baseline (first generated
token excluded; prefill not split in that harness). OMLX 0.6.4 required a
writable snapshot plus import_mtplx_sidecar; Lightning MTP ran at draft
depth 1 and the OMLX runner reports generate-wall tok/s (prefill not split).
mlxcel 0.7.0 still fails to load this AXQ affine layout.
Unsupported is not replaced with another checkpoint. MTP Tier 2 remains
pending. Artifacts:
2026-09-15 campaign.
Archived Qwen 3.6 serving, multi-model S1, embeddings, and the 2026-08-31 depth-1 AX / MTPLX 2.9.0 / OMLX 0.6.4 table stay in Performance Results and Benchmarks.
SDKs
Most clients use the OpenAI-compatible HTTP server. Python also has an in-process session API.
| SDK | Docs |
|---|---|
| Rust | docs/sdk/rust.md |
| Python | docs/sdk/python.md |
| JavaScript / TypeScript | docs/sdk/javascript.md |
| Go | docs/sdk/go.md |
| Ruby | docs/sdk/ruby.md |
| Swift | docs/sdk/swift.md |
| Mojo (experimental) | docs/sdk/mojo.md |
Server
ax-engine serve is the normal entrypoint (see Quick Start). Default listen is
127.0.0.1:31418 (not AX Serving’s 18080). Port map, LAN bind, and
Serving vs Engine:
curl http://127.0.0.1:31418/v1/runtime
Auth, streaming, embeddings, Ollama-shaped routes: Server · API Compatibility · OpenClaw. Fleet / NVIDIA serving: AX Serving.
Documentation
| Need | Read |
|---|---|
| Docs hub | docs/README.md |
| Install and first request | Getting Started |
| Ports, bind host, Engine vs Serving | Ports |
| Models and MTP packages | Supported Models · MTP Docs |
| Hardware / FAQ | FAQ |
| Full performance tables | Performance Results |
| Serving peer (newest) | Serving peer detail |
| Reproduce benchmarks | Benchmarks |
| Server / API / SDKs | Server · API · OpenClaw · SDKs |
| Fleet / NVIDIA (AX Serving) | AX Serving |
| Architecture | Architecture |
| Scheduler / KV internals | Scheduler · KV Cache · Serving Invariants |
Development
cargo build --workspace
cargo test --quiet
cargo clippy --all-targets --all-features -- -D warnings
cargo fmt --check
maturin develop
python -m unittest discover -s python/tests -v
Crate layout and conventions: AGENTS.md · Architecture.
Limitations
- Qwen3.5 long-prompt prefill can trail upstream MLX references on longer prompts
- Raw HuggingFace / mlx-community snapshots load directly:
model-manifest.jsonis auto-generated fromconfig.json+ safetensors headers on first load and weight sanitization is auto-detected, somlx_lm.convertis not required - N-gram acceleration is workload-dependent, not a raw kernel speedup
- NVIDIA/CUDA serving requires the separate AX Serving product
Details: FAQ limitations.
Contributing
Issues, wishlist items, reproducible benchmarks, and docs feedback are welcome. Unsolicited code PRs for runtime, kernel, scheduler, or performance paths are generally not accepted — open an issue first. See CONTRIBUTING.md.
Community
- Website: automatosx.com
- Discord: Join us
- Email: enquiry@defai.digital
Acknowledgments
AX Engine is grateful to the open-source foundations, benchmarking peers, and community contributors listed in Acknowledgments.
License
Apache License, Version 2.0. See LICENSE.
Copyright (c) 2026 DEFAI Private Limited
Similar repos
Contributors
Languages
Rust
65.5%
Python
27.5%
HTML
2.7%
Shell
1.8%