
TUI multiline fuzzy document finder
See the codeREADME
Docfd
TUI multiline fuzzy document finder
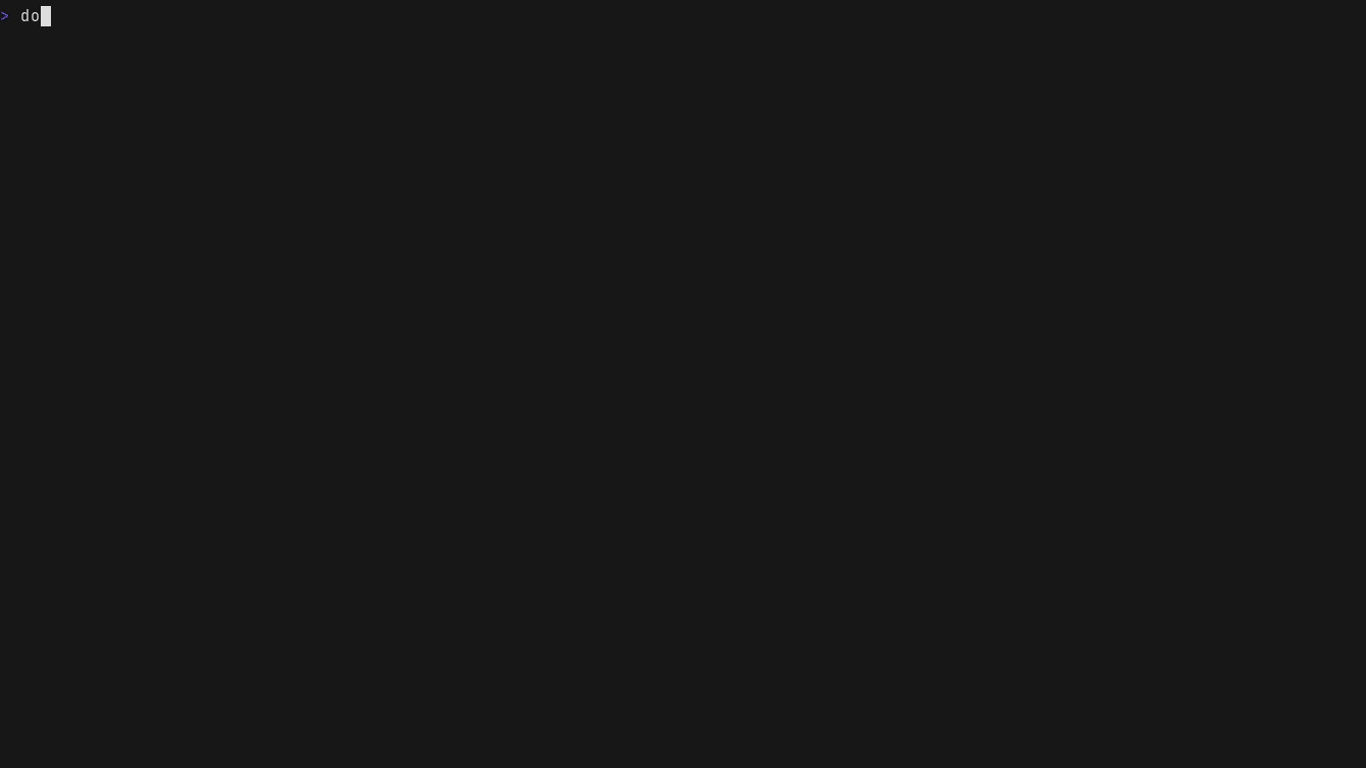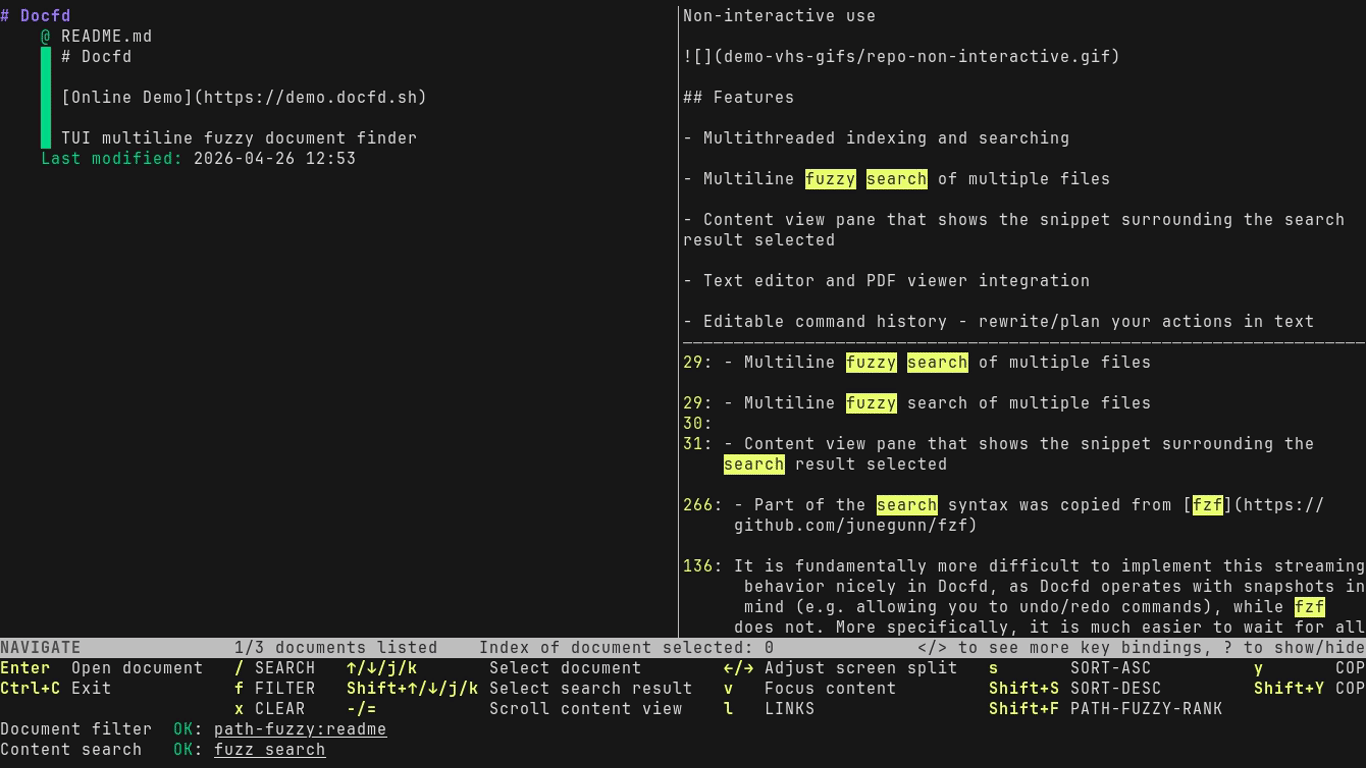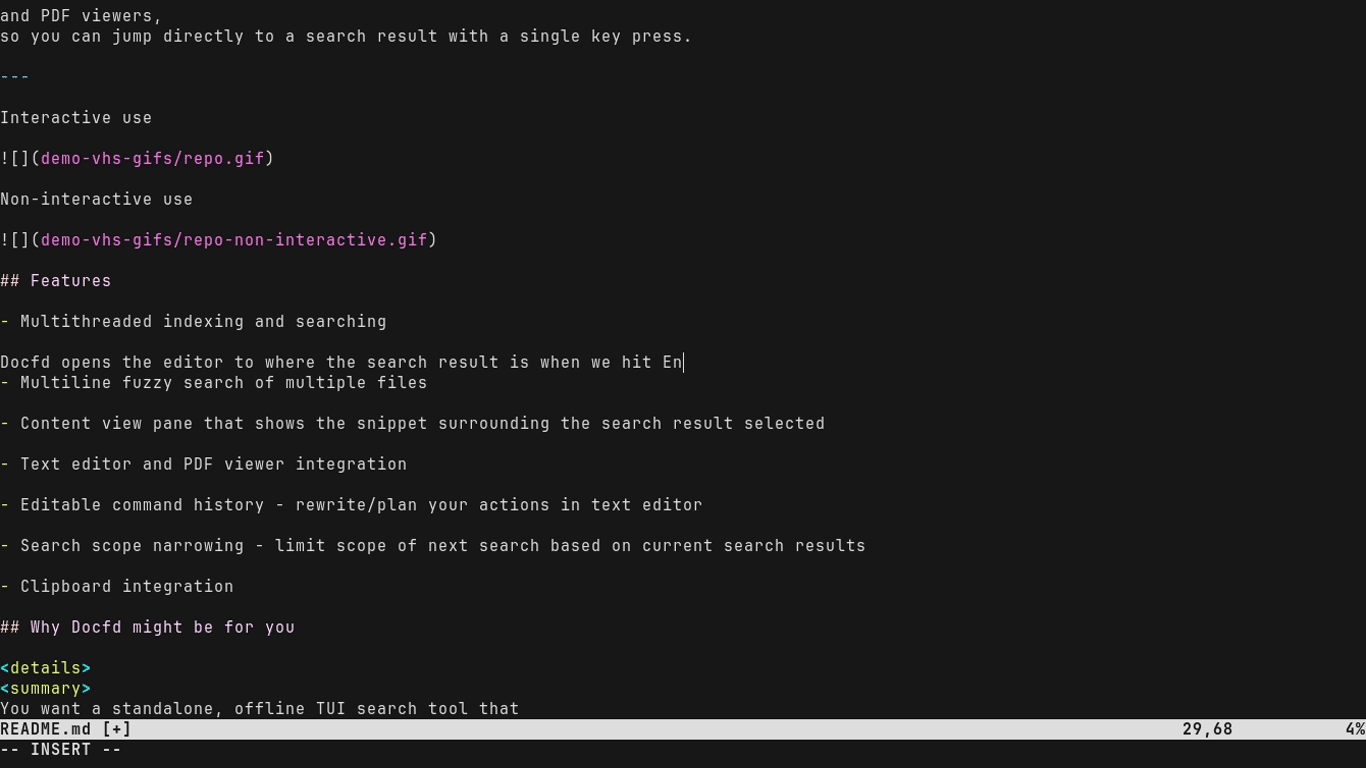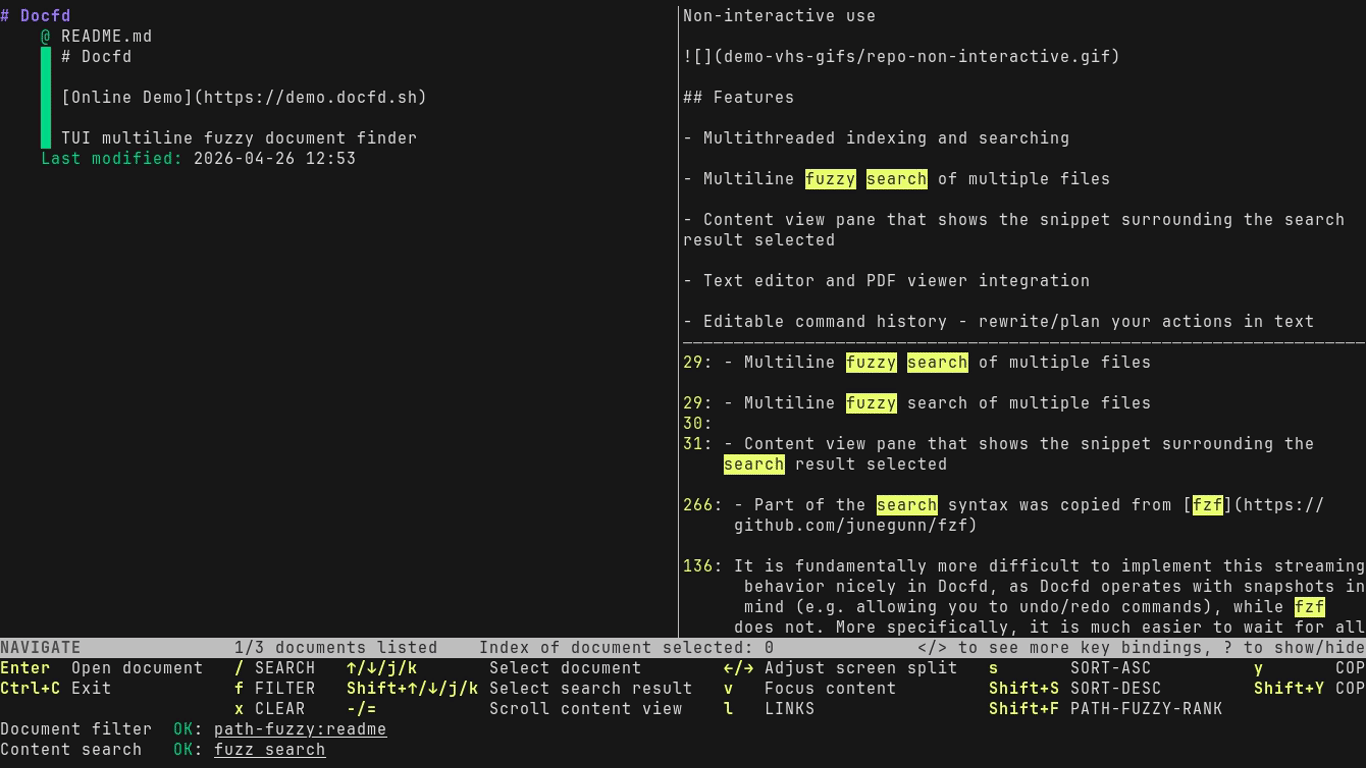
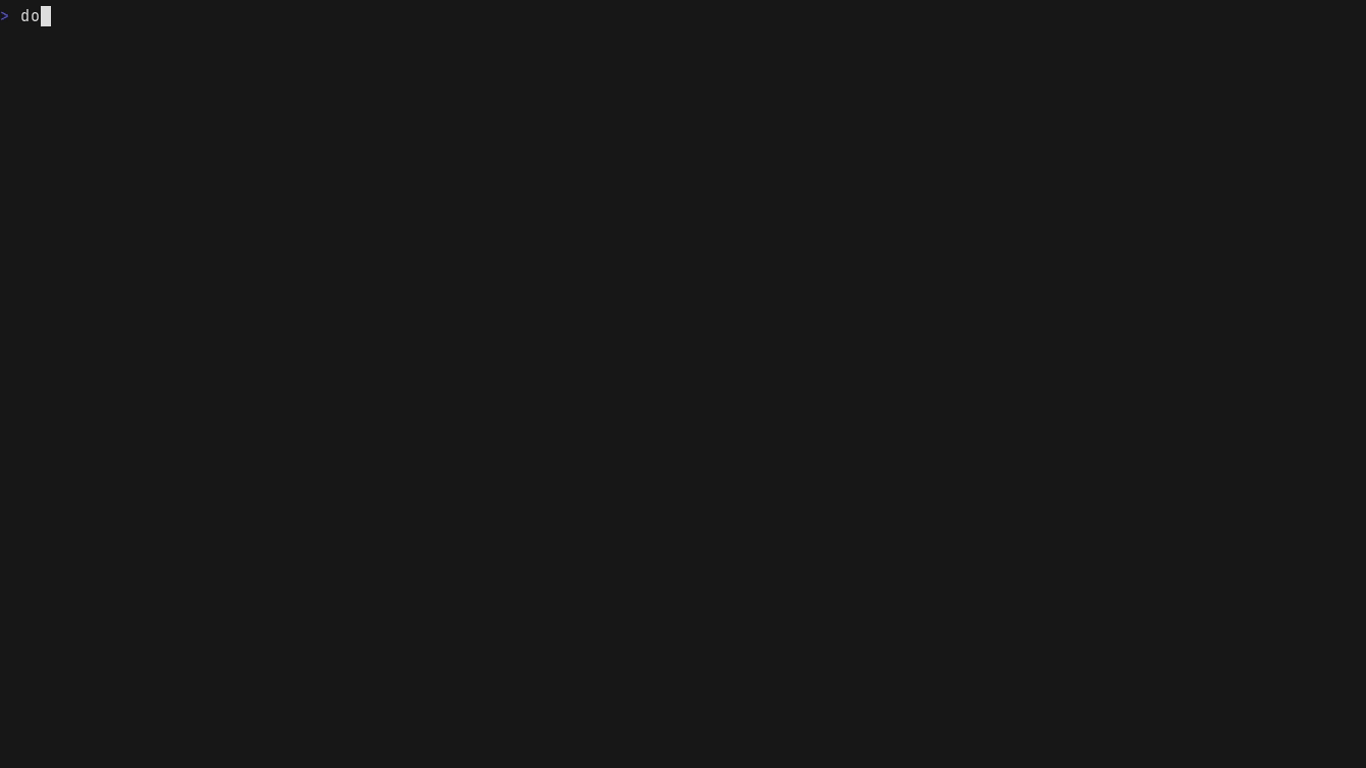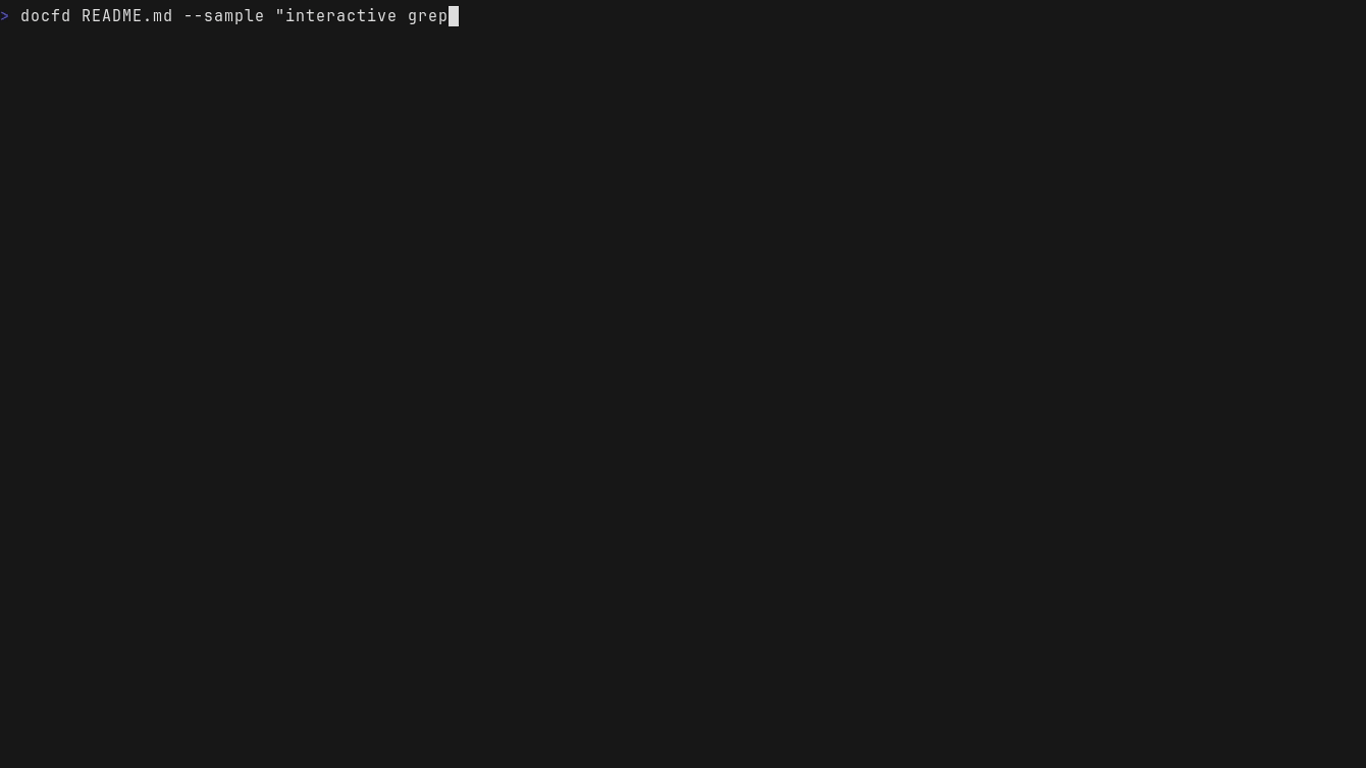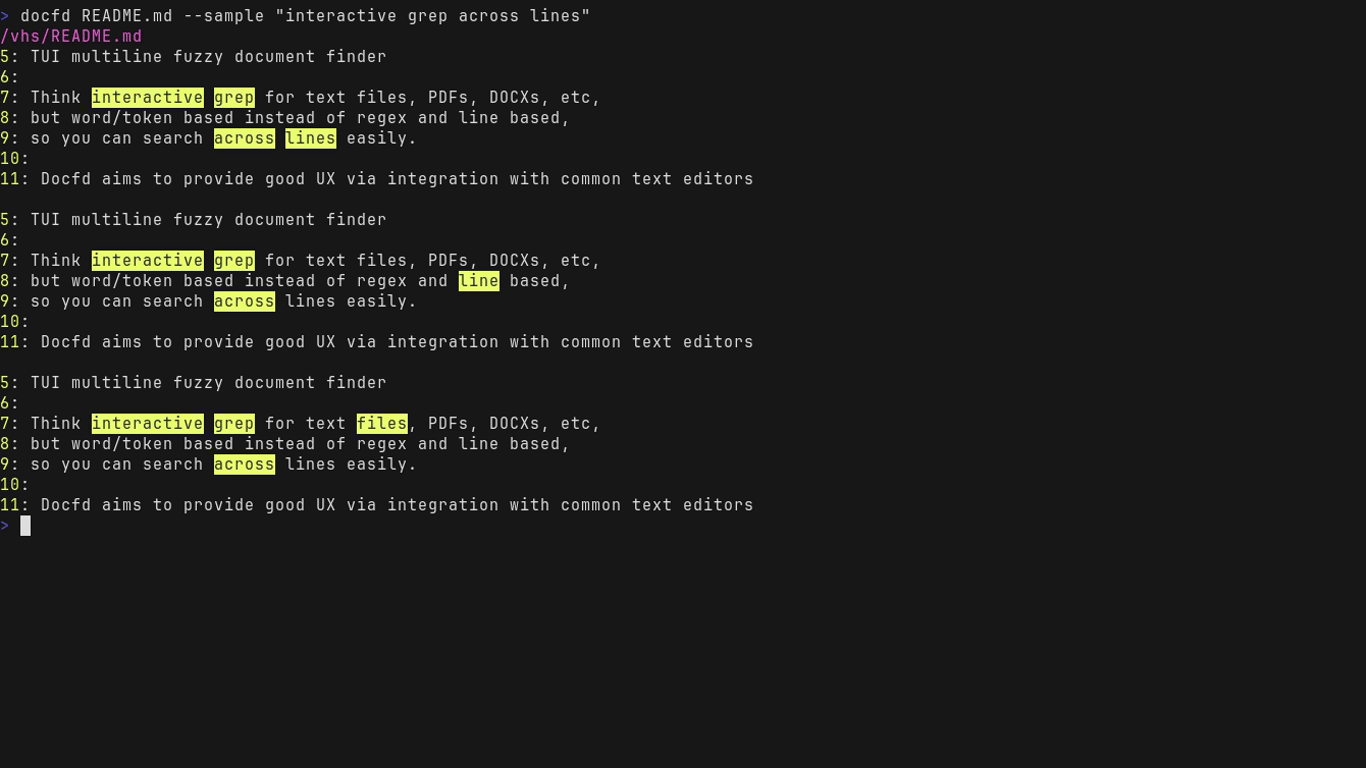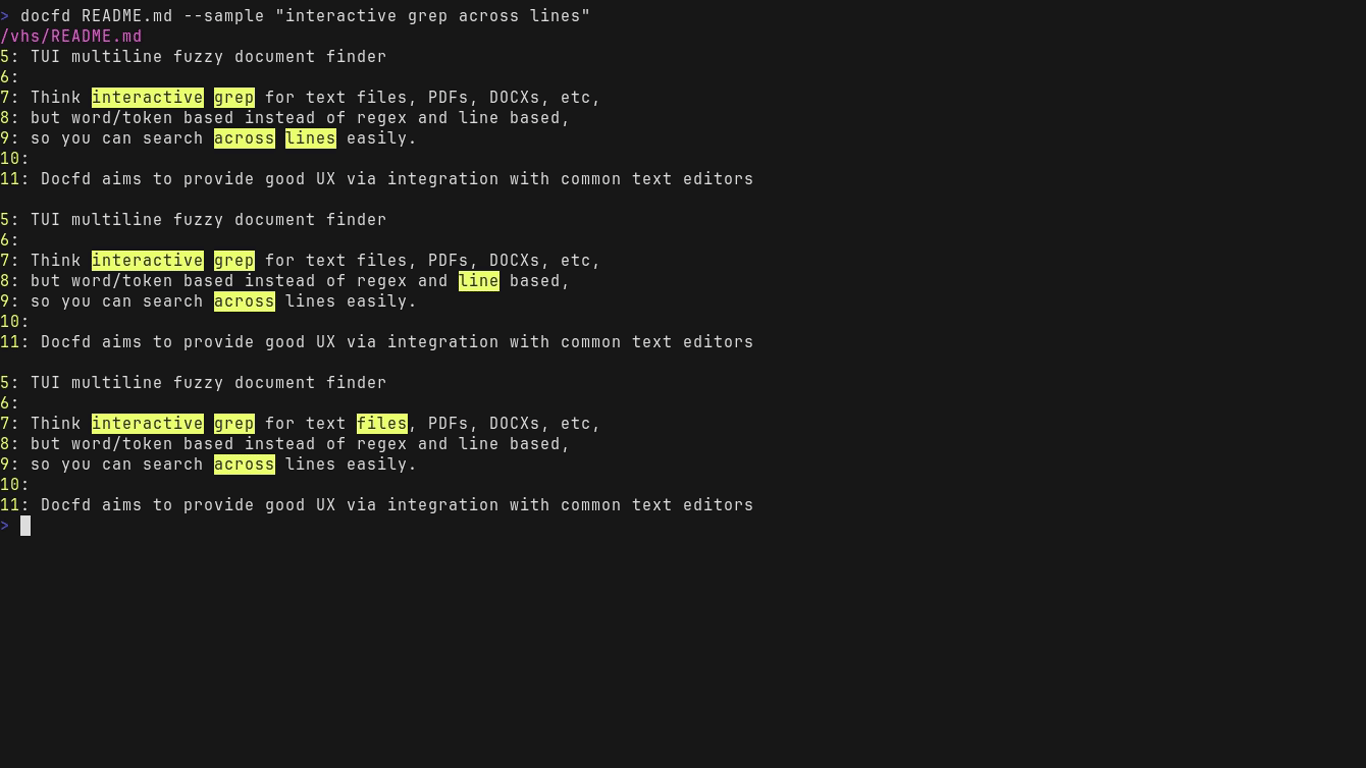
Think interactive grep for text files, PDFs, DOCXs, etc, but word/token based instead of regex and line based, so you can search across lines easily.
Docfd aims to provide good UX via integration with common text editors and PDF viewers, so you can jump directly to a search result with a single key press.
Interactive use
Non-interactive use
Features
-
Multithreaded indexing and searching
-
Multiline fuzzy search of multiple files
-
Content view pane that shows the snippet surrounding the search result selected
-
Text editor and PDF viewer integration
-
Editable command history - rewrite/plan your actions in text editor
-
Search scope narrowing - limit scope of next search based on current search results
-
Clipboard integration
Why Docfd might be for you
You want a standalone, offline TUI search tool that allows you to immediately start searching without any complicated setup.
Docfd only starts processing the current directory or specified directories/files upon start. Hashing is used to pick out files that have not been indexed yet.
There is no need to wait for a background indexer to refresh before you get up-to-date results.
You don't want to move everything into a central storage, and want to just keep your current folder structure
There are no strings attached with using Docfd. Docfd does not require you to import your files into any special storage system, so you can continue mix and match tools to best handle your files.
You want to script or record your search
Docfd comes with a simple scripting language, which is already used to capture your actions in the TUI.
Finally found what you need after many steps?
Save the session as a script with Ctrl+S!
Then open it next time with Ctrl+O.
Why Docfd might not be for you
Docfd is not all-encompassing
Docfd does not try to be a full blown document management system such as Paperless-ngx. While there may be significant overlaps in terms of the search functionality, Docfd will fall short for almost any other kind of features, such as storage management, tagging, web interface, OCR, email ingestion.
Docfd is not a "proper" search engine
Docfd is a search engine in the sense that it uses the same fundamental principles, i.e. inverted indices, but it lacks features that you would expect from a "proper" search engine solution, e.g. Apache Lucene, Tantivy, Lnx.
Here are some of the fundamental features which I think are crucial to a proper search engine, but Docfd lacks:
- You cannot customize what are indexed by Docfd
- You cannot add a new type of ranking
- Docfd lacks support for languages other than English
- Docfd does not scale very well to very large quantity of documents
- Search should still be serviceable when you reach beyond, say, 10k documents, but it will be noticeably more sluggish
Some of these shortcomings are fundamental to the goals of Docfd. For instance, Docfd is primarily a standalone desktop TUI tool with quick startup and should not impact other desktop applications. As such, some performance related engineering choices typical for a proper search engine are difficult to accommodate as they require longer startup and significantly more memory usage.
Other shortcomings are due to limited time and limited return on efforts - if one is to push Docfd so much to reach the feature parity and performance of a proper search engine, then one might as well just use an existing search engine to begin with.
If your notes are consistently very short, and you only want to do simple searches, then there are better options
If you follow note taking methodologies such as Zettelkasten, where each note consists of very few lines, then using a combination of grep and file preview tool can yield a much faster search experience by skipping out on indexing and consideration of word proximity.
Docfd does not "stream" its search results
One user feedback received was that searching felt slow when Docfd is still conducting the search as UI is not updated result by result. By comparison, fzf felt faster as results start to immediately pop into the screen.
It is fundamentally more difficult to implement this streaming behavior nicely in Docfd, as Docfd operates with snapshots in mind (e.g. allowing you to undo/redo commands), while fzf does not. More specifically, it is much easier to wait for all search results to be ready, and finalize as a snapshot before presenting onto Docfd UI.
So while possible to implement in Docfd, it is unclear if the effort is worthwhile with the additional system complexity in mind.
Installation
Statically linked binaries for Linux and macOS are available via GitHub releases.
Docfd is also packaged on the following platforms for Linux:
- opam
- AUR (as
docfd-bin)- First packaged by @kseistrup, now maintained by Dominiquini
- Nix (as
docfd)- Packaged by @chewblacka
The only way to use Docfd on Windows right now is via WSL.
Notes for packagers: Outside of the OCaml toolchain for building (if you are packaging from source), Docfd also requires the following external tools at run time for full functionality:
pdftotextfrompoppler-utilsfor PDF supportpandocfor support of.epub,.odt,.docx,.fb2,.ipynb,.html, and.htmfileswl-clibpardfor clipboard support on Waylandxclipfor clipboard support on X11
Basic usage
The typical usage of Docfd is to either cd into the directory of interest
and launch docfd directly, or specify the paths as arguments:
docfd [PATH]...
The list of paths can contain directories. Each directory in the list is scanned recursively for files with the following extensions by default:
- For multiline search mode:
.txt,.md,.pdf,.epub,.odt,.docx,.fb2,.ipynb,.html,.htm
- For single line search mode:
.log,.csv,.tsv
You can change the file extensions to use via
--exts and --single-line-exts,
or add onto the list of extensions via
--add-exts and --single-line-add-exts.
If the list PATHs is empty,
then Docfd defaults to scanning the
current directory .
unless any of the following is used:
--paths-from, --glob, --single-line-glob.
Documentation
See https://darrenldl.github.io/docfd/
Changelog
Limitations
-
Docfd generally expects one intance per index DB
-
You should pick a different cache directory (which houses the index DB) via
--cache-dirif you need multiple instances -
There are safe guards to avoid corruptions even if you do run multiple instances of Docfd, but note that the instances of Docfd may exit unexpectedly
-
That being said, running multiple instances of Docfd which are only reading the index DB and not updating it should be fine
-
-
File auto-reloading is not supported for PDF files, as PDF viewers are invoked in the background via shell. It is possible to support this properly in the ways listed below, but requires a lot of engineering for potentially very little gain:
-
Docfd waits for PDF viewer to terminate fully before resuming, but this prohibits viewing multiple search results simultaneously in different PDF viewer instances.
-
Docfd manages the launched PDF viewers completely, but these viewers are closed when Docfd terminates.
-
Docfd invokes the PDF viewers via shell so they stay open when Docfd terminates. Docfd instead periodically checks if they are still running via the PDF viewers' process IDs, but this requires handling forks.
-
Outside of tracking whether the PDF viewer instances interacting with the files are still running, Docfd also needs to set up file update handling either via
inotifyor via checking file modification times periodically.
-
Acknowledgement
- Big thanks to @lunacookies and @jthvai for the many UI/UX discussions and suggestions
- Demo gifs and some screenshots are made using vhs.
- ripgrep-all was used as reference for text extraction software choices
- Marc Coquand (author of Stitch) for discussions and inspiration of results narrowing functionality
- Part of the search syntax was copied from fzf
- Command history editing workflow was inspired by Git interactive rebase workflow, e.g.
git rebase -i - PDF Corpora from PDF Association was used to stress test performance


Similar repos


Languages
OCaml
81.1%
Terra
14.5%
Raku
3.1%
TUI multiline fuzzy document finder
See the codeREADME
Docfd
TUI multiline fuzzy document finder
Think interactive grep for text files, PDFs, DOCXs, etc, but word/token based instead of regex and line based, so you can search across lines easily.
Docfd aims to provide good UX via integration with common text editors and PDF viewers, so you can jump directly to a search result with a single key press.
Interactive use
Non-interactive use
Features
-
Multithreaded indexing and searching
-
Multiline fuzzy search of multiple files
-
Content view pane that shows the snippet surrounding the search result selected
-
Text editor and PDF viewer integration
-
Editable command history - rewrite/plan your actions in text editor
-
Search scope narrowing - limit scope of next search based on current search results
-
Clipboard integration
Why Docfd might be for you
You want a standalone, offline TUI search tool that allows you to immediately start searching without any complicated setup.
Docfd only starts processing the current directory or specified directories/files upon start. Hashing is used to pick out files that have not been indexed yet.
There is no need to wait for a background indexer to refresh before you get up-to-date results.
You don't want to move everything into a central storage, and want to just keep your current folder structure
There are no strings attached with using Docfd. Docfd does not require you to import your files into any special storage system, so you can continue mix and match tools to best handle your files.
You want to script or record your search
Docfd comes with a simple scripting language, which is already used to capture your actions in the TUI.
Finally found what you need after many steps?
Save the session as a script with Ctrl+S!
Then open it next time with Ctrl+O.
Why Docfd might not be for you
Docfd is not all-encompassing
Docfd does not try to be a full blown document management system such as Paperless-ngx. While there may be significant overlaps in terms of the search functionality, Docfd will fall short for almost any other kind of features, such as storage management, tagging, web interface, OCR, email ingestion.
Docfd is not a "proper" search engine
Docfd is a search engine in the sense that it uses the same fundamental principles, i.e. inverted indices, but it lacks features that you would expect from a "proper" search engine solution, e.g. Apache Lucene, Tantivy, Lnx.
Here are some of the fundamental features which I think are crucial to a proper search engine, but Docfd lacks:
- You cannot customize what are indexed by Docfd
- You cannot add a new type of ranking
- Docfd lacks support for languages other than English
- Docfd does not scale very well to very large quantity of documents
- Search should still be serviceable when you reach beyond, say, 10k documents, but it will be noticeably more sluggish
Some of these shortcomings are fundamental to the goals of Docfd. For instance, Docfd is primarily a standalone desktop TUI tool with quick startup and should not impact other desktop applications. As such, some performance related engineering choices typical for a proper search engine are difficult to accommodate as they require longer startup and significantly more memory usage.
Other shortcomings are due to limited time and limited return on efforts - if one is to push Docfd so much to reach the feature parity and performance of a proper search engine, then one might as well just use an existing search engine to begin with.
If your notes are consistently very short, and you only want to do simple searches, then there are better options
If you follow note taking methodologies such as Zettelkasten, where each note consists of very few lines, then using a combination of grep and file preview tool can yield a much faster search experience by skipping out on indexing and consideration of word proximity.
Docfd does not "stream" its search results
One user feedback received was that searching felt slow when Docfd is still conducting the search as UI is not updated result by result. By comparison, fzf felt faster as results start to immediately pop into the screen.
It is fundamentally more difficult to implement this streaming behavior nicely in Docfd, as Docfd operates with snapshots in mind (e.g. allowing you to undo/redo commands), while fzf does not. More specifically, it is much easier to wait for all search results to be ready, and finalize as a snapshot before presenting onto Docfd UI.
So while possible to implement in Docfd, it is unclear if the effort is worthwhile with the additional system complexity in mind.
Installation
Statically linked binaries for Linux and macOS are available via GitHub releases.
Docfd is also packaged on the following platforms for Linux:
- opam
- AUR (as
docfd-bin)- First packaged by @kseistrup, now maintained by Dominiquini
- Nix (as
docfd)- Packaged by @chewblacka
The only way to use Docfd on Windows right now is via WSL.
Notes for packagers: Outside of the OCaml toolchain for building (if you are packaging from source), Docfd also requires the following external tools at run time for full functionality:
pdftotextfrompoppler-utilsfor PDF supportpandocfor support of.epub,.odt,.docx,.fb2,.ipynb,.html, and.htmfileswl-clibpardfor clipboard support on Waylandxclipfor clipboard support on X11
Basic usage
The typical usage of Docfd is to either cd into the directory of interest
and launch docfd directly, or specify the paths as arguments:
docfd [PATH]...
The list of paths can contain directories. Each directory in the list is scanned recursively for files with the following extensions by default:
- For multiline search mode:
.txt,.md,.pdf,.epub,.odt,.docx,.fb2,.ipynb,.html,.htm
- For single line search mode:
.log,.csv,.tsv
You can change the file extensions to use via
--exts and --single-line-exts,
or add onto the list of extensions via
--add-exts and --single-line-add-exts.
If the list PATHs is empty,
then Docfd defaults to scanning the
current directory .
unless any of the following is used:
--paths-from, --glob, --single-line-glob.
Documentation
See https://darrenldl.github.io/docfd/
Changelog
Limitations
-
Docfd generally expects one intance per index DB
-
You should pick a different cache directory (which houses the index DB) via
--cache-dirif you need multiple instances -
There are safe guards to avoid corruptions even if you do run multiple instances of Docfd, but note that the instances of Docfd may exit unexpectedly
-
That being said, running multiple instances of Docfd which are only reading the index DB and not updating it should be fine
-
-
File auto-reloading is not supported for PDF files, as PDF viewers are invoked in the background via shell. It is possible to support this properly in the ways listed below, but requires a lot of engineering for potentially very little gain:
-
Docfd waits for PDF viewer to terminate fully before resuming, but this prohibits viewing multiple search results simultaneously in different PDF viewer instances.
-
Docfd manages the launched PDF viewers completely, but these viewers are closed when Docfd terminates.
-
Docfd invokes the PDF viewers via shell so they stay open when Docfd terminates. Docfd instead periodically checks if they are still running via the PDF viewers' process IDs, but this requires handling forks.
-
Outside of tracking whether the PDF viewer instances interacting with the files are still running, Docfd also needs to set up file update handling either via
inotifyor via checking file modification times periodically.
-
Acknowledgement
- Big thanks to @lunacookies and @jthvai for the many UI/UX discussions and suggestions
- Demo gifs and some screenshots are made using vhs.
- ripgrep-all was used as reference for text extraction software choices
- Marc Coquand (author of Stitch) for discussions and inspiration of results narrowing functionality
- Part of the search syntax was copied from fzf
- Command history editing workflow was inspired by Git interactive rebase workflow, e.g.
git rebase -i - PDF Corpora from PDF Association was used to stress test performance
Similar repos
Languages
OCaml
81.1%
Terra
14.5%
Raku
3.1%