Official repository for RePro: Training Language Models to Faithfully Recycle the Web for Pretraining
Python
11
16 commits
updated Feb 18, 2026


Recycled data coming soon...
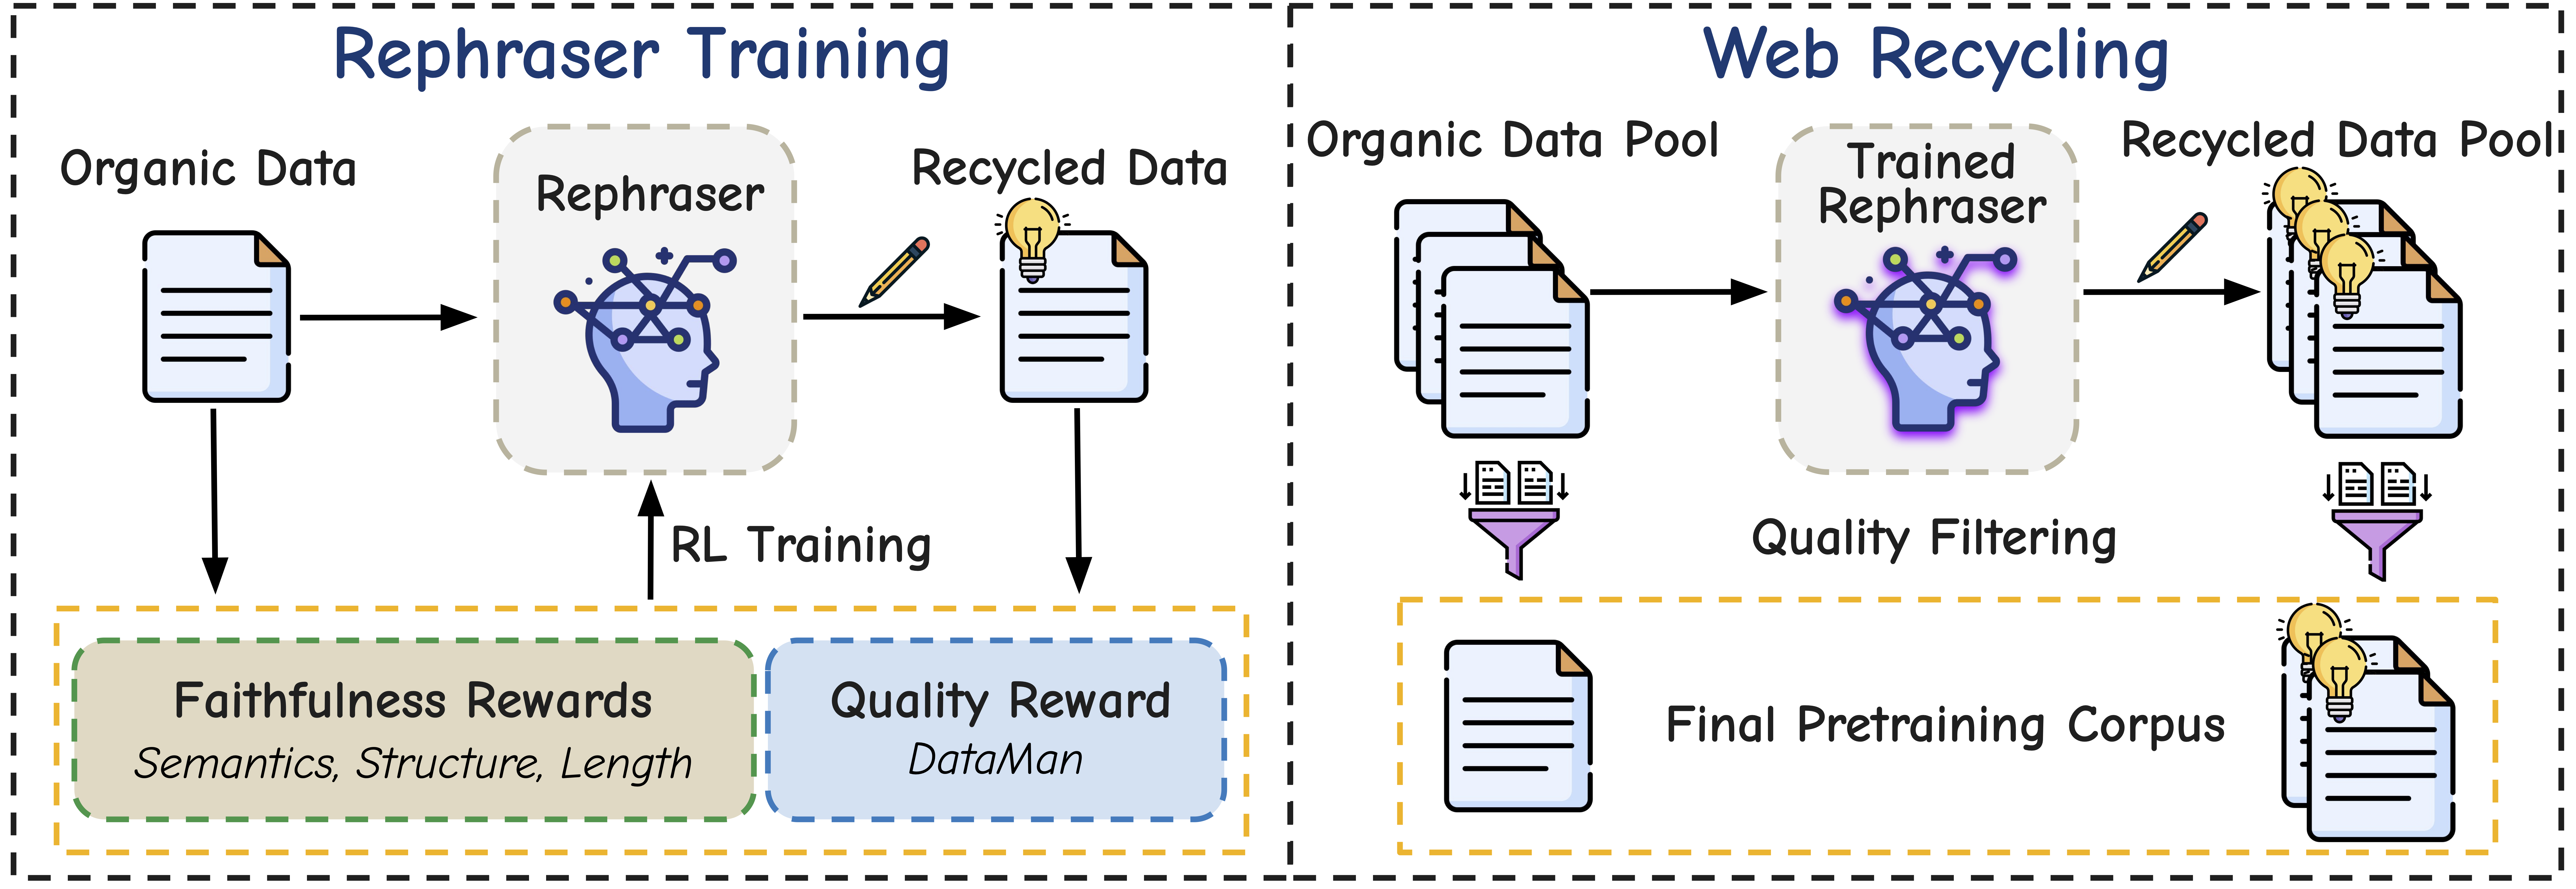
Our RL code is based on Open R1, and our pretraining code is based on DCLM. Please refer to their repos for more details.
The code is tested on Python 3.10.16. Install basic dependencies:
pip install -r requirements.txt
Run setup.py to download necessary files:
cd pretrain
python setup.py install
Run scripts/rl.sh.
rl/1000_sample_low_score.jsonl) for testing purposes. The full dataset can be found here.bash scripts/infer.sh 0 7
Run scripts/filter.sh:
source_ref_paths: data pool pathoutput_dir: filtered data dirPlease install rust in your conda environment.
Run scripts/tokenize.sh:
input: the original text data diroutput: the tokenized data dirRun scripts/pretrain.sh:
scale: DCLM running scale, please find the supported ones in training/configsdata-config: specify the run name ("name") and the tokenized data location ("manifest_url"), create one when you have a new datasetlogs: where to store the checkpointmultiple-data-passes: used to allow multiple epochsRun scripts/eval.sh:
method: the generated checkpoint dir namecheckpoint: the specific epoch you want to evaluatemodel: model scale config in training/open_lm_configsoutput-file: where to store the evaluation resultIf you find this work useful, please consider citing:
@article{yu2025repro,
  title={{RePro}: Training Language Models to Faithfully Recycle the Web for Pretraining},
  author={Yu, Zichun and Xiong, Chenyan},
  journal={ArXiv preprint},
  year={2025}
}
108 followers · starred Oct 2025
Official repository for RePro: Training Language Models to Faithfully Recycle the Web for Pretraining
Python
11
16 commits
updated Feb 18, 2026
Recycled data coming soon...
Our RL code is based on Open R1, and our pretraining code is based on DCLM. Please refer to their repos for more details.
The code is tested on Python 3.10.16. Install basic dependencies:
pip install -r requirements.txt
Run setup.py to download necessary files:
cd pretrain
python setup.py install
Run scripts/rl.sh.
rl/1000_sample_low_score.jsonl) for testing purposes. The full dataset can be found here.bash scripts/infer.sh 0 7
Run scripts/filter.sh:
source_ref_paths: data pool pathoutput_dir: filtered data dirPlease install rust in your conda environment.
Run scripts/tokenize.sh:
input: the original text data diroutput: the tokenized data dirRun scripts/pretrain.sh:
scale: DCLM running scale, please find the supported ones in training/configsdata-config: specify the run name ("name") and the tokenized data location ("manifest_url"), create one when you have a new datasetlogs: where to store the checkpointmultiple-data-passes: used to allow multiple epochsRun scripts/eval.sh:
method: the generated checkpoint dir namecheckpoint: the specific epoch you want to evaluatemodel: model scale config in training/open_lm_configsoutput-file: where to store the evaluation resultIf you find this work useful, please consider citing:
@article{yu2025repro,
  title={{RePro}: Training Language Models to Faithfully Recycle the Web for Pretraining},
  author={Yu, Zichun and Xiong, Chenyan},
  journal={ArXiv preprint},
  year={2025}
}
108 followers · starred Oct 2025