
BLSP-Emo: Towards Empathetic Large Speech-Language Models
Python
61
9 commits
updated Jun 7, 2024
README
BLSP-Emo: Towards Empathetic Large Language-Speech Models
Chen Wang, Minpeng Liao, Zhongqiang Huang, Junhong Wu, Chenqing Zong, Jiajun Zhang
Institute of Automation, Chinese Academy of Sciences
Alibaba Group


Introduction
- BLSP-Emo is designed to enable an instruction-following LLM to understand both linguistic content and paralinguistic emotion cues in speech and generate empathetic responses, using only existing ASR and SER data.
- BLSP-Emo is built based on Whisper-large-v2 and Qwen-7B-Chat.
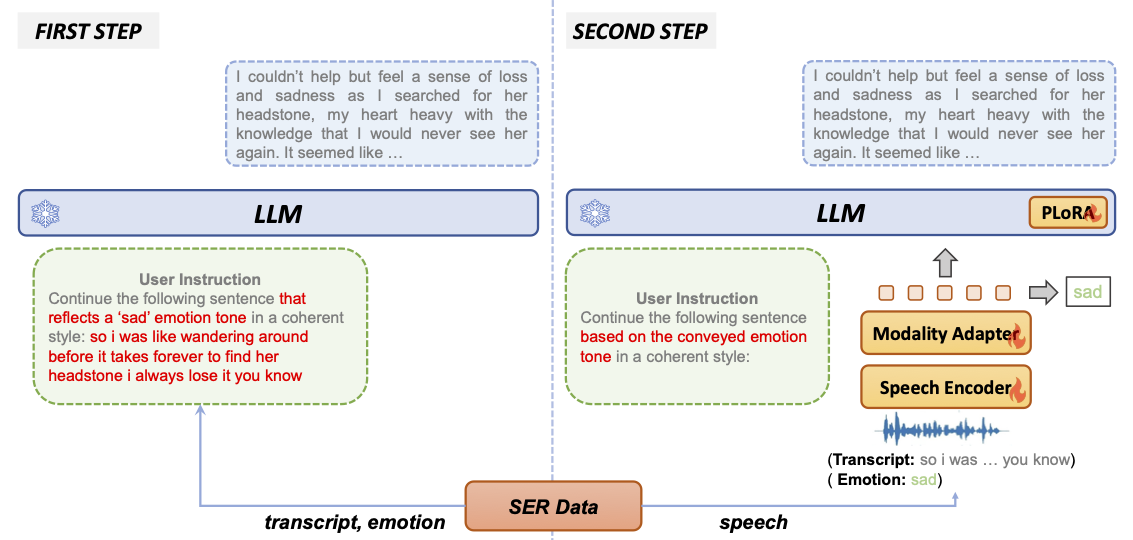
Example
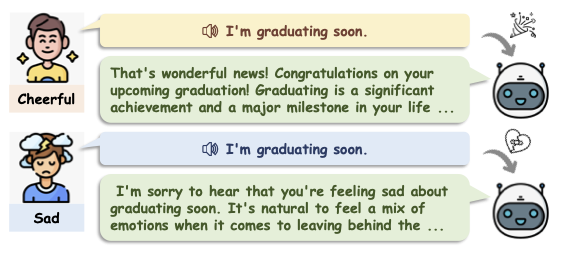
More examples can be found in the project page. You can also try our model online at modelscope.
Usage
Setup
pip install requirements.txt
Prepare the pretrained BLSP-Emo checkpoint
Download the pretrained BLSP model from modelscope or huggingface.
Inference & Evaluation
We provide examples of the input and output format in examples/test/
For SER task
instruction="Please identify the emotion tone of the speech provided below. Select from the following options: neutral, sad, angry, happy, or surprise.

Speech: "

python3 generate.py \
    --input_file "examples/test/test_iemocap.jsonl" \
    --output_file "examples/test/output_iemocap.jsonl" \
    --blsp_model $blsp_path \
    --instruction "$instruction" \
    --audio_field "audio" \
    --reference_field "emotion"
For SpeechAlpaca
python3 generate.py \
    --input_file "examples/test/test_alpaca.jsonl" \
    --output_file "examples/test/output_alpaca.jsonl" \
    --blsp_model $blsp_path \
    --instruction "" \
    --audio_field "audio" \
    --max_new_tokens 256 \
    --batch_size 4 \
    --use_emotion True
We release the synthesized SpeechAlpaca at Baidu YunPan and GoogleDrive
Launching Demo Locally
You can try out our demo locally by
python chat_demo.py \
    --blsp_model $blsp_path \
    --use_emotion
### use the flag --use_emotion to enable empathetic response
Training from Scratch
The training of BLSP-Emo contains two stages.
Stage 1: Semantic Alignment
-
Obtain Qwen-7B-Chat Model to
~/pretrained_models/qwen-7b-chat. Obtain whisper-large-v2 to~/pretrained_models/whisper-large-v2 -
Suppose you have processed ASR data manifest files. Leverage Qwen-7B to generate the continuation.
export qwen_path=~/pretrained_models/qwen-7b-chat

mkdir -p examples/train/cw_labels
python -u emotion_text_generation.py generate \
    --qwen_path ${qwen_path} \
    --manifest examples/train/train_gigaspeech.jsonl \
    --lab_dir examples/train/cw_labels \
    --instruction "Continue the following sentence in a coherent style: " \
    --nshard 1 \
    --rank 0
- Offline process
python src/instruction_dataset.py offline \
    --dataroot examples/train/cw_labels \
    --manifest_files "*.jsonl" \
    --lm_path ${qwen_path} \
    --save_dir examples/train/cw_labels/processed \
    --instruction "" \
    --instruction_field "instruction" \
    --audio_field "audio" \
    --input_field "text" \
    --output_field "output" \
    --max_length 256 \
    --max_duration 30.0 \
    --num_proc 64
- train the BLSP model
export whisper_path=~/pretrained_models/whisper-large-v2
export DATA_ROOT=examples/train/cw_labels/processed
export SAVE_ROOT=~/pretrain_checkpoints

bash scripts/train_pretrain.sh
Stage 2: Emotion Alignment
- Suppose you have processed SER data manifest files. Leverage Qwen-7B to generate the continuation.
mkdir -p examples/train/emotion_labels
python -u emotion_text_generation.py generate \
    --qwen_path ${qwen_path} \
    --manifest examples/train/train_iemocap.jsonl \
    --lab_dir examples/train/emotion_labels \
    --nshard 1 \
    --rank 0 \
    --use_emotion True
Clean the continuations
python data_process/clean_noise_examples.py \
    --input_dir examples/train/emotion_labels
- Offline process
emotion_instruction="Continue the following sentence based on the conveyed emotion tone in a coherent style: "

python src/instruction_dataset.py offline \
    --dataroot examples/train/emotion_labels \
    --manifest_files "*_clean.jsonl" \
    --lm_path ${qwen_path} \
    --save_dir examples/train/emotion_labels/processed \
    --instruction_field "instruction" \
    --audio_instruction "$emotion_instruction" \
    --audio_field "audio" \
    --input_field "text" \
    --output_field "output" \
    --max_length 256 \
    --max_duration 30.0 \
    --num_proc 64 \
    --use_emotion True
- train the BLSP-Emo model
export blsp_path=~/pretrain_checkpoints
export DATA_ROOT=examples/train/emotion_labels/processed
export SAVE_ROOT=~/sft_checkpoints

bash scripts/train_emotion.sh
License
- The license of our project is Apache License 2.0
- Our models are based on Qwen and Whisper. If you want to use our models, please do not violate the MIT License of whisper and the License of Qwen
Citation
If you find our project useful, hope you can star our repo and cite our paper as follows:
@misc{wang2024blspemo,
    title={BLSP-Emo: Towards Empathetic Large Speech-Language Models},
    author={Chen Wang and Minpeng Liao and Zhongqiang Huang and Junhong Wu and Chengqing Zong and Jiajun Zhang},
    year={2024},
    eprint={2406.03872},
    archivePrefix={arXiv},
    primaryClass={cs.CL}
}
Similar repos




Languages
Python
82.2%
Cuda
14.9%
C++
2.4%
BLSP-Emo: Towards Empathetic Large Speech-Language Models
Python
61
9 commits
updated Jun 7, 2024
README
BLSP-Emo: Towards Empathetic Large Language-Speech Models
Chen Wang, Minpeng Liao, Zhongqiang Huang, Junhong Wu, Chenqing Zong, Jiajun Zhang
Institute of Automation, Chinese Academy of Sciences
Alibaba Group
Introduction
- BLSP-Emo is designed to enable an instruction-following LLM to understand both linguistic content and paralinguistic emotion cues in speech and generate empathetic responses, using only existing ASR and SER data.
- BLSP-Emo is built based on Whisper-large-v2 and Qwen-7B-Chat.
Example
More examples can be found in the project page. You can also try our model online at modelscope.
Usage
Setup
pip install requirements.txt
Prepare the pretrained BLSP-Emo checkpoint
Download the pretrained BLSP model from modelscope or huggingface.
Inference & Evaluation
We provide examples of the input and output format in examples/test/
For SER task
instruction="Please identify the emotion tone of the speech provided below. Select from the following options: neutral, sad, angry, happy, or surprise.

Speech: "

python3 generate.py \
    --input_file "examples/test/test_iemocap.jsonl" \
    --output_file "examples/test/output_iemocap.jsonl" \
    --blsp_model $blsp_path \
    --instruction "$instruction" \
    --audio_field "audio" \
    --reference_field "emotion"
For SpeechAlpaca
python3 generate.py \
    --input_file "examples/test/test_alpaca.jsonl" \
    --output_file "examples/test/output_alpaca.jsonl" \
    --blsp_model $blsp_path \
    --instruction "" \
    --audio_field "audio" \
    --max_new_tokens 256 \
    --batch_size 4 \
    --use_emotion True
We release the synthesized SpeechAlpaca at Baidu YunPan and GoogleDrive
Launching Demo Locally
You can try out our demo locally by
python chat_demo.py \
    --blsp_model $blsp_path \
    --use_emotion
### use the flag --use_emotion to enable empathetic response
Training from Scratch
The training of BLSP-Emo contains two stages.
Stage 1: Semantic Alignment
-
Obtain Qwen-7B-Chat Model to
~/pretrained_models/qwen-7b-chat. Obtain whisper-large-v2 to~/pretrained_models/whisper-large-v2 -
Suppose you have processed ASR data manifest files. Leverage Qwen-7B to generate the continuation.
export qwen_path=~/pretrained_models/qwen-7b-chat

mkdir -p examples/train/cw_labels
python -u emotion_text_generation.py generate \
    --qwen_path ${qwen_path} \
    --manifest examples/train/train_gigaspeech.jsonl \
    --lab_dir examples/train/cw_labels \
    --instruction "Continue the following sentence in a coherent style: " \
    --nshard 1 \
    --rank 0
- Offline process
python src/instruction_dataset.py offline \
    --dataroot examples/train/cw_labels \
    --manifest_files "*.jsonl" \
    --lm_path ${qwen_path} \
    --save_dir examples/train/cw_labels/processed \
    --instruction "" \
    --instruction_field "instruction" \
    --audio_field "audio" \
    --input_field "text" \
    --output_field "output" \
    --max_length 256 \
    --max_duration 30.0 \
    --num_proc 64
- train the BLSP model
export whisper_path=~/pretrained_models/whisper-large-v2
export DATA_ROOT=examples/train/cw_labels/processed
export SAVE_ROOT=~/pretrain_checkpoints

bash scripts/train_pretrain.sh
Stage 2: Emotion Alignment
- Suppose you have processed SER data manifest files. Leverage Qwen-7B to generate the continuation.
mkdir -p examples/train/emotion_labels
python -u emotion_text_generation.py generate \
    --qwen_path ${qwen_path} \
    --manifest examples/train/train_iemocap.jsonl \
    --lab_dir examples/train/emotion_labels \
    --nshard 1 \
    --rank 0 \
    --use_emotion True
Clean the continuations
python data_process/clean_noise_examples.py \
    --input_dir examples/train/emotion_labels
- Offline process
emotion_instruction="Continue the following sentence based on the conveyed emotion tone in a coherent style: "

python src/instruction_dataset.py offline \
    --dataroot examples/train/emotion_labels \
    --manifest_files "*_clean.jsonl" \
    --lm_path ${qwen_path} \
    --save_dir examples/train/emotion_labels/processed \
    --instruction_field "instruction" \
    --audio_instruction "$emotion_instruction" \
    --audio_field "audio" \
    --input_field "text" \
    --output_field "output" \
    --max_length 256 \
    --max_duration 30.0 \
    --num_proc 64 \
    --use_emotion True
- train the BLSP-Emo model
export blsp_path=~/pretrain_checkpoints
export DATA_ROOT=examples/train/emotion_labels/processed
export SAVE_ROOT=~/sft_checkpoints

bash scripts/train_emotion.sh
License
- The license of our project is Apache License 2.0
- Our models are based on Qwen and Whisper. If you want to use our models, please do not violate the MIT License of whisper and the License of Qwen
Citation
If you find our project useful, hope you can star our repo and cite our paper as follows:
@misc{wang2024blspemo,
    title={BLSP-Emo: Towards Empathetic Large Speech-Language Models},
    author={Chen Wang and Minpeng Liao and Zhongqiang Huang and Junhong Wu and Chengqing Zong and Jiajun Zhang},
    year={2024},
    eprint={2406.03872},
    archivePrefix={arXiv},
    primaryClass={cs.CL}
}
Similar repos
Languages
Python
82.2%
Cuda
14.9%
C++
2.4%