
Official implementation of PointACT: Vision-Language-Action Models with Multi-Scale Point-Action Interaction (RSS'26).
See the codeREADME
PointAct
Official implementation of PointACT: Vision-Language-Action Models with Multi-Scale Point-Action Interaction.
Monolithic 3D-aware VLA |
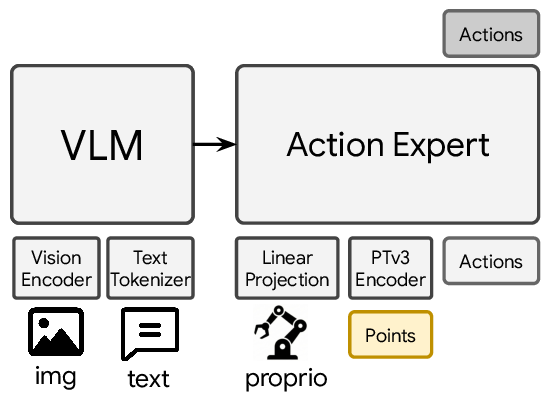
Dual-system 3D-aware VLA |
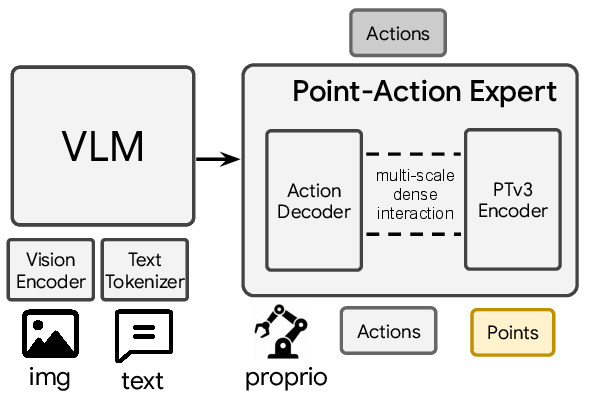
PointAct |
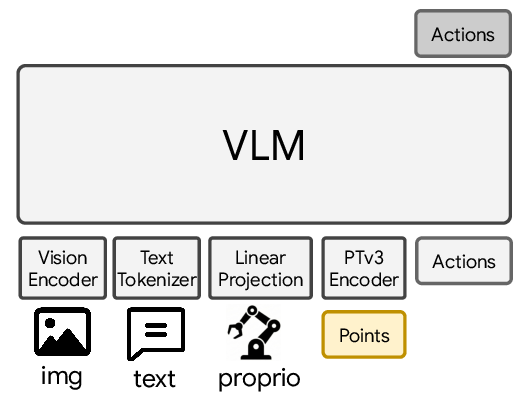
PointAct is a 3D-aware vision-language-action policy for robot manipulation. It keeps a pretrained vision-language backbone for semantic understanding and adds a dedicated point-action expert so that multi-scale 3D geometry can directly shape action decoding.
Installation
Please follow the main setup guide in INSTALLATION.md. The recommended workflow is:
- Create the core
pointactenvironment for training, checkpoint loading, preprocessing, and the policy server. - Create separate simulator environments.
- Use the server-client evaluation pipeline since the policy and simulator usually need different environments.
Supported Benchmarks
This repository currently supports three simulators:
| Benchmark | Simulator | Experiment Path |
|---|---|---|
| LIBERO | LIBERO | experiments/2_libero |
| RLBench | RLBench | experiments/10_rlbench |
| RoboCASA365 | RoboCASA | experiments/13_robocasa365 |
Supported Models
This repository includes PointAct and several comparison VLA policies used in our experiments:
| Model | Directory | Notes |
|---|---|---|
PointAct | pointact/model/vla_pointact | Supports both Concerto and Utonia Point Transformer backbones |
EO1 | pointact/model/eo1 | Monolithic VLA baseline |
EO1-Point | pointact/model/eo1 | EO-1 variant with point-cloud input |
QwenGR00T | pointact/model/vla_dual | Dual-system VLA baseline |
QwenGR00T-Point | pointact/model/vla_dual | VLA-Dual variant with point-cloud input |
Pi0 | pointact/model/pi0 | PI0 baseline |
Pi0.5 | pointact/model/pi05 | PI0.5 baseline |
Acknowledgements
This codebase builds on several excellent open-source projects, especially EO-1, GR00T, and LeRobot. We thank the authors and maintainers of these libraries for making their work available to the community.
Citation
If you find PointAct useful in your research, or if you use this code, please cite:
@InProceedings{Chen_2026_PointACT,
    author    = {Chen, Shizhe and Pacaud, Paul and Schmid, Cordelia},
    title     = {PointACT: Vision-Language-Action Models with Multi-Scale Point-Action Interaction},
    booktitle = {Robotics: Science and Systems (RSS)},
    year      = {2026}
}
Similar repos


Languages
Python
95.2%
Shell
4.8%
Official implementation of PointACT: Vision-Language-Action Models with Multi-Scale Point-Action Interaction (RSS'26).
See the codeREADME
PointAct
Official implementation of PointACT: Vision-Language-Action Models with Multi-Scale Point-Action Interaction.
|
Monolithic 3D-aware VLA |
Dual-system 3D-aware VLA |
PointAct |
PointAct is a 3D-aware vision-language-action policy for robot manipulation. It keeps a pretrained vision-language backbone for semantic understanding and adds a dedicated point-action expert so that multi-scale 3D geometry can directly shape action decoding.
Installation
Please follow the main setup guide in INSTALLATION.md. The recommended workflow is:
- Create the core
pointactenvironment for training, checkpoint loading, preprocessing, and the policy server. - Create separate simulator environments.
- Use the server-client evaluation pipeline since the policy and simulator usually need different environments.
Supported Benchmarks
This repository currently supports three simulators:
| Benchmark | Simulator | Experiment Path |
|---|---|---|
| LIBERO | LIBERO | experiments/2_libero |
| RLBench | RLBench | experiments/10_rlbench |
| RoboCASA365 | RoboCASA | experiments/13_robocasa365 |
Supported Models
This repository includes PointAct and several comparison VLA policies used in our experiments:
| Model | Directory | Notes |
|---|---|---|
PointAct | pointact/model/vla_pointact | Supports both Concerto and Utonia Point Transformer backbones |
EO1 | pointact/model/eo1 | Monolithic VLA baseline |
EO1-Point | pointact/model/eo1 | EO-1 variant with point-cloud input |
QwenGR00T | pointact/model/vla_dual | Dual-system VLA baseline |
QwenGR00T-Point | pointact/model/vla_dual | VLA-Dual variant with point-cloud input |
Pi0 | pointact/model/pi0 | PI0 baseline |
Pi0.5 | pointact/model/pi05 | PI0.5 baseline |
Acknowledgements
This codebase builds on several excellent open-source projects, especially EO-1, GR00T, and LeRobot. We thank the authors and maintainers of these libraries for making their work available to the community.
Citation
If you find PointAct useful in your research, or if you use this code, please cite:
@InProceedings{Chen_2026_PointACT,
    author    = {Chen, Shizhe and Pacaud, Paul and Schmid, Cordelia},
    title     = {PointACT: Vision-Language-Action Models with Multi-Scale Point-Action Interaction},
    booktitle = {Robotics: Science and Systems (RSS)},
    year      = {2026}
}
Similar repos
Languages
Python
95.2%
Shell
4.8%