
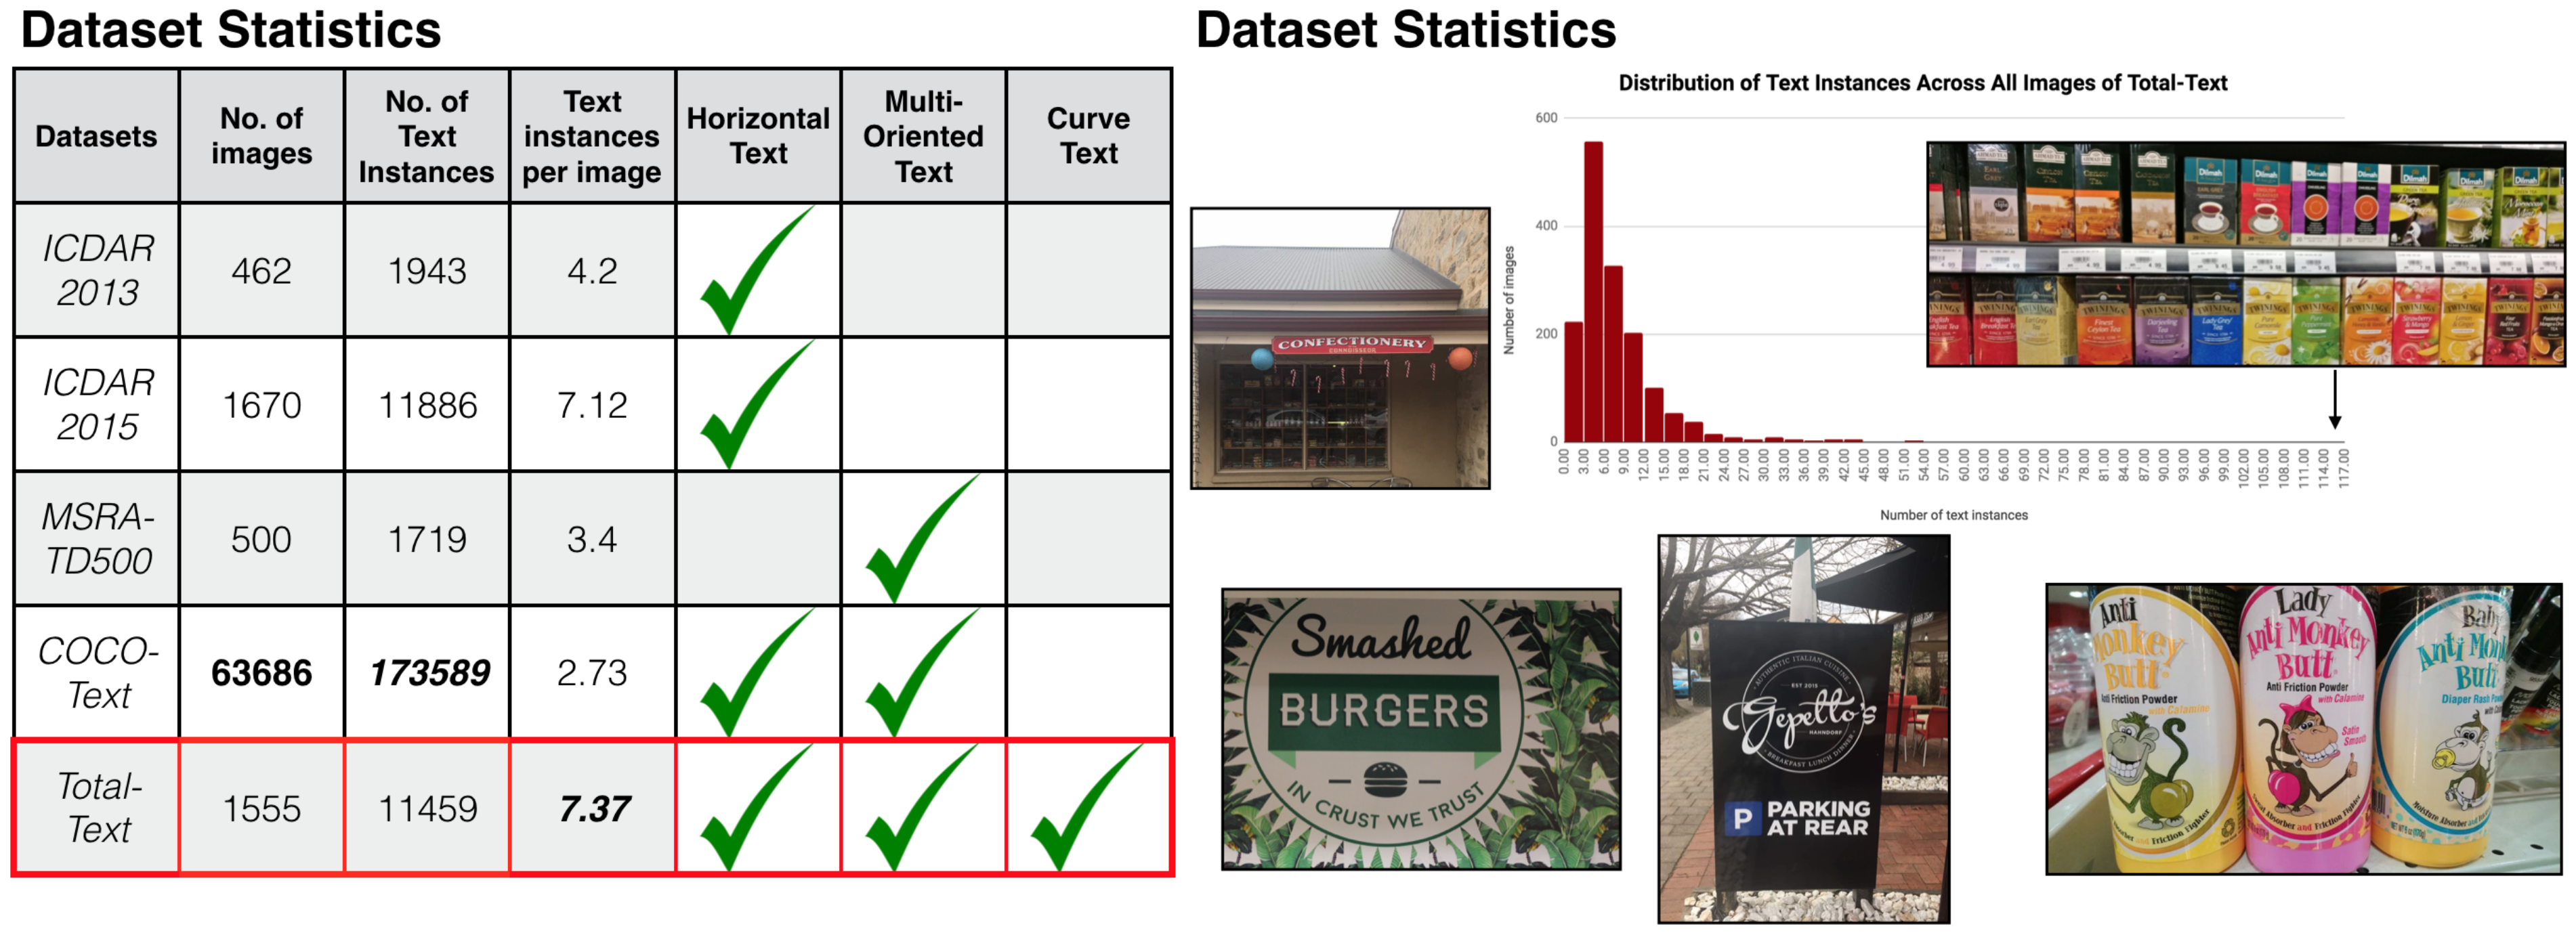
Total Text Dataset. It consists of 1555 images with more than 3 different text orientations: Horizontal, Multi-Oriented, and Curved, one of a kind.
MATLAB
772
323 commits
updated Sep 30, 2026
README
Total-Text-Dataset (Official site)
Updated on September 30, 2026 (Updated README.md & LICENSE. Added DATASET_TERMS.md & RIGHTS_NOTICE.md)
Updated on April 06, 2022 (Detection leaderboard is updated with FCE, ABPNet, PCR, CentripetalText & HierText)
Updated on April 29, 2020 (Detection leaderboard is updated - highlighted E2E methods. Thank you shine-lcy.)
Updated on March 19, 2020 (Query on the new groundtruth of test set)
Updated on Sept. 08, 2019 (New training groundtruth of Total-Text is now available)
Updated on Sept. 07, 2019 (Updated Guided Annotation toolbox for scene text image annotation)
Updated on Sept. 07, 2019 (Updated baseline as to our IJDAR)
Updated on August 01, 2019 (Extended version with new baseline + annotation tool is accepted at IJDAR)
Updated on May 30, 2019 (Important announcement on Total-Text vs. ArT dataset)
Updated on April 02, 2019 (Updated table ranking with default vs. our proposed DetEval)
Updated on March 31, 2019 (Faster version DetEval.py, support Python3. Thank you princewang1994.)
Updated on March 14, 2019 (Updated table ranking with evaluation protocol info.)
Updated on November 26, 2018 (Table ranking is included for reference.)
Updated on August 24, 2018 (Newly added Guided Annotation toolbox folder.)
Updated on May 15, 2018 (Added groundtruth in '.txt' format.)
Updated on May 14, 2018 (Added feature - 'Do not care' candidates filtering is now available in the latest python scripts.)
Updated on April 03, 2018 (Added pixel level groundtruth)
Updated on November 04, 2017 (Added text level groundtruth)
Released on October 27, 2017
News
-
We received some questions in regard to the new groundtruth for the test set of Total-Text. Here is an update. We do not release a new version of the test set groundtruth because
 1) there is no need of standardising the length of the groundtruth vertices for testing purpose, it was proposed to facilitate training only, and
 2) a new version of groundtruth would make the previous benchmarks irrelevant.
Do contact us if you think there is a valid reason to require the new groundtruth for the test set, we shall discuss about it.
- TOTAL-TEXT is a word-level based English curve text dataset. If you are interested in text-line based dataset with both English and Chinese instances, we highly recommend you to refer SCUT-CTW1500. In addition, a Robust Reading Challenge on Arbitrary-Shaped Text (RRC-ArT), which is extended from Total-Text and SCUT-CTW1500, was held at ICDAR2019 to stimulate more innovative ideas on the arbitrary-shaped text reading task. Congratulations to all winners and challengers. The technical report of ArT can be found on at this https URL.
Important Announcement
Total-Text and SCUT-CTW1500 are now part of the training set of the largest curved text dataset - ArT (Arbitrary-Shaped Text dataset). In order to retain the validity of future benchmarking on Total-Text datasets, the test-set images of Total-Text should be removed (with the corresponding ID provided HERE) from the ArT dataset shall one intend to leverage the extra training data from the ArT dataset. We count on the trust of the research community to perform such removal operation to attain the fairness of the benchmarking.
Table Ranking
- The results from recent papers on Total-Text dataset are listed below where P=Precision, R=Recall & F=F-score.
- If your result is missing or incorrect, please do not hesisate to contact us.
- The baseline scores are based on our proposed [Poly-FRCNN-3] in this folder.
- *Pascal VOC IoU metric; **Polygon Regression
Detection Leaderboard
| Method | Reported on paper | DetEval (tp=0.4, tr=0.8) (Default) | DetEval (tp=0.6, tr=0.7) (New Proposal) | Published at | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| P | R | F | P | R | F | P | R | F | ||
| Our Baseline [paper] | 78.0 | 68.0 | 73.0 | - | - | - | 78.0 | 68.0 | 73.0 | IJDAR2020 |
| CentripetalText [paper] | 90.67 | 85.19 | 87.85 | - | - | - | - | - | - | NeurIPS2021 |
| ABPNet [paper] | 90.6 | 82.5 | 86.3 | - | - | - | - | - | - | ICCV2021 |
| CRAFTS [paper] | 89.5 | 85.4 | 87.4 | - | - | - | - | - | - | ECCV2020 |
| FCE [paper] | 89.3 | 82.5 | 85.8 | - | - | - | - | - | - | CVPR2021 |
| #ASTS_Weakly-ResNet101 (E2E) [paper] | - | - | 87.3 | - | - | - | - | - | - | TIP2020 |
| TextFuseNet [paper] | 89.0 | 85.3 | 87.1 | - | - | - | - | - | - | IJCAI2020 |
| #Boundary (E2E) [paper] | 88.9 | 85.0 | 87.0 | - | - | - | - | - | - | AAAI2020 |
| PCR [paper] | 88.5 | 82.0 | 85.2 | - | - | - | - | - | - | CVPR2021 |
| PolyPRNet [paper] | 88.1 | 85.3 | 86.7 | - | - | - | - | - | - | ACCV2020 |
| #Qin et al. (E2E) [paper] | 87.8 | 85.0 | 86.4 | - | - | - | - | - | - | ICCV2019 |
| 100%Poly [paper] | 88.2 | 83.3 | 85.6 | - | - | - | - | - | - | arXiv:2012 |
| ContourNet [paper] | 86.9 | 83.9 | 85.4 | - | - | - | - | - | - | CVPR2020 |
| #Text Perceptron (E2E) [paper] | 88.8 | 81.8 | 85.2 | - | - | - | - | - | - | AAAI2020 |
| PAN-640 [paper] | 89.3 | 81.0 | 85.0 | - | - | - | - | - | - | ICCV2019 |
| DB-ResNet50 (800) [paper] | 87.1 | 82.5 | 84.7 | - | - | - | - | - | - | AAAI2020 |
| TextCohesion [paper] | 88.1 | 81.4 | 84.6 | - | - | - | - | - | - | arXiv:1904 |
| Feng et al. [paper] | 87.3 | 81.1 | 84.1 | - | - | - | - | - | - | IJCV2020 |
| HierText [paper] | 85.49 | 90.53 | 87.94 | - | - | - | - | - | - | CVPR2022 |
| ReLaText [paper] | 84.8 | 83.1 | 84.0 | - | - | - | - | - | - | arXiv:2003 |
| CRAFT [paper] | 87.6 | 79.9 | 83.6 | - | - | - | - | - | - | CVPR2019 |
| LOMO MS [paper] | 87.6 | 79.3 | 83.3 | - | - | - | - | - | - | CVPR2019 |
| SPCNet [paper] | 83.0 | 82.8 | 82.9 | - | - | - | - | - | - | AAAI2019 |
| #ABCNet (E2E) [paper] | 85.4 | 80.1 | 82.7 | - | - | - | - | - | - | CVPR2020 |
| ICG [paper] | 82.1 | 80.9 | 81.5 | - | - | - | - | - | - | PR2019 |
| FTSN [paper] | *84.7 | *78.0 | *81.3 | - | - | - | - | - | - | ICPR2018 |
| PSENet-1s [paper] | 84.02 | 77.96 | 80.87 | - | - | - | - | - | - | CVPR2019 |
| 1TextField [paper] | 81.2 | 79.9 | 80.6 | 76.1 | 75.1 | 75.6 | 83.0 | 82.0 | 82.5 | TIP2019 |
| #TextDragon (E2E) [paper] | 85.6 | 75.7 | 80.3 | - | - | - | - | - | - | ICCV2019 |
| CSE [paper] | 81.4 (**80.9) | 79.7 (**80.3) | 80.2 (**80.6) | - | - | - | - | - | - | CVPR2019 |
| MSR [paper] | 85.2 | 73.0 | 78.6 | 82.7 | 68.3 | 74.9 | 81.4 | 72.5 | 76.7 | arXiv:1901 |
| ATTR [paper] | 80.9 | 76.2 | 78.5 | - | - | - | - | - | - | CVPR2019 |
| TextSnake [paper] | 82.7 | 74.5 | 78.4 | - | - | - | - | - | - | ECCV2018 |
| 1CTD [paper] | 74.0 | 71.0 | 73.0 | 60.7 | 58.8 | 59.8 | 76.5 | 73.8 | 75.2 | PR2019 |
| #TextNet (E2E) [paper] | 68.2 | 59.5 | 63.5 | - | - | - | - | - | - | ACCV2018 |
| #,2Mask TextSpotter (E2E) [paper] | 69.0 | 55.0 | 61.3 | 68.9 | 62.5 | 65.5 | 82.5 | 75.2 | 78.6 | ECCV2018 |
| CENet [paper] | 59.9 | 54.4 | 57.0 | - | - | - | - | - | - | ACCV2018 |
| #Textboxes (E2E) [paper] | 62.1 | 45.5 | 52.5 | - | - | - | - | - | - | AAAI2017 |
| EAST [paper] | 50.0 | 36.2 | 42.0 | - | - | - | - | - | - | CVPR2017 |
| SegLink [paper] | 30.3 | 23.8 | 26.7 | - | - | - | - | - | - | CVPR2017 |
Note:
# Framework that does end-to-end training (i.e. detection + recognition).
1For the results of TextField and CTD, the improved versions of their original paper were used, and this explains why the performance is better.
2For Mask-TextSpotter, the relatively poor performance reported in their paper was due to a bug in the input reading module (which was fixed recently). The authors were informed about this issue.
End-to-end Recognition Leaderboard
(None refers to recognition without any lexicon; Full lexicon contains all words in test set.)
| Method | Backbone | None (%) | Full (%) | FPS | Published at |
|---|---|---|---|---|---|
| CRAFTS [paper] | ResNet50-FPN | 78.7 | - | - | ECCV2020 |
| MANGO [paper] | ResNet50-FPN | 72.9 | 83.6 | 4.3 | AAAI2021 |
| Text Perceptron [paper] | ResNet50-FPN | 69.7 | 78.3 | - | AAAI2020 |
| ABCNet-MS [paper] | ResNet50-FPN | 69.5 | 78.4 | 6.9 | CVPR2020 |
| CharNet H-88 MS [paper] | ResNet50-Hourglass57 | 69.2 | - | 1.2 | ICCV2019 |
| Qin et al. [paper] | ResNet50-MSF | 67.8 | - | - | ICCV2019 |
| ASTS_Weakly [paper] | ResNet101-FPN | 65.3 | 84.2 | 2.5 | TIP2020 |
| Boundary [paper] | ResNet50-FPN | 65.0 | 76.1 | - | AAAI2020 |
| ABCNet [paper] | ResNet50-FPN | 64.2 | 75.7 | 17.9 | CVPR2020 |
| CAPNet [paper] | ResNet50-FPN | 62.7 | - | - | ICASSP2020 |
| Feng et al. [paper] | VGG | 55.8 | 79.2 | - | IJCV2020 |
| TextNet [paper] | ResNet50-SAM | 54.0 | - | 2.7 | ACCV2018 |
| Mask TextSpotter [paper] | ResNet50-FPN | 52.9 | 71.8 | 4.8 | ECCV2018 |
| TextDragon [paper] | VGG16 | 48.8 | 74.8 | - | ICCV2019 |
| Textboxes [paper] | ResNet50-FPN | 36.3 | 48.9 | 1.4 | AAAI2017 |
Description
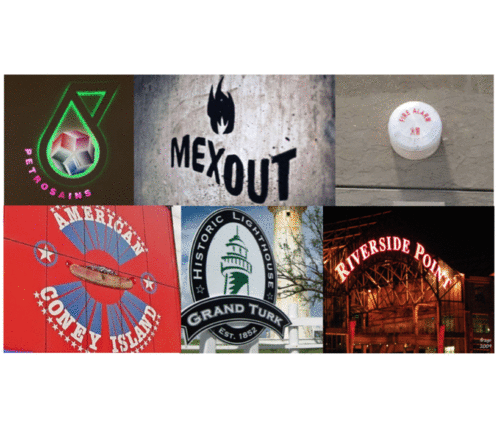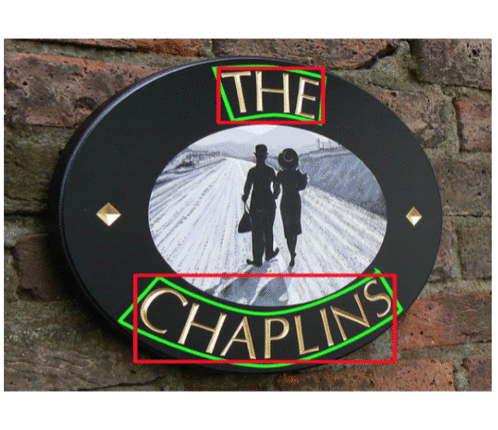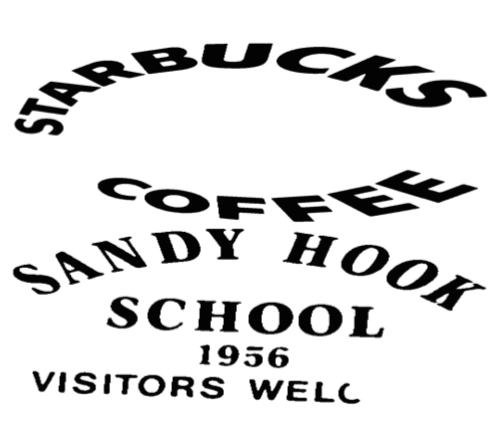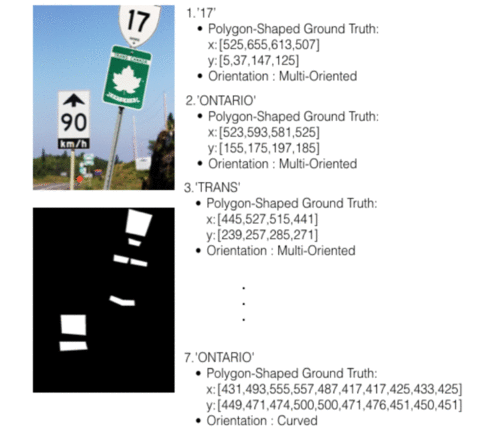
In order to facilitate a new text detection research, we introduce Total-Text dataset (IJDAR)(ICDAR-17 paper) (presentation slides), which is more comprehensive than the existing text datasets. The Total-Text consists of 1555 images with more than 3 different text orientations: Horizontal, Multi-Oriented, and Curved, one of a kind.
Contributors:
Chee Kheng Chng, Chun Chet Ng, Chee Seng Chan
Feedback
Suggestions and opinions of this dataset (both positive and negative) are greatly welcome. Please contact the authors by sending email to
chngcheekheng at gmail.com or cs.chan at um.edu.my.
License, Dataset Terms and Copyright
Total-Text contains different categories of material. Different terms apply to different components:
| Material | Applicable terms |
|---|---|
| Software code, evaluation scripts, baseline code and annotation tools | BSD-3-Clause. See LICENSE. |
| Total-Text annotations, ground-truth files, transcriptions, masks, metadata and dataset splits created for Total-Text | See DATASET_TERMS.md. |
| Underlying images and other third-party material, if any | Not licensed under the BSD-3-Clause software licence. Separate rights may apply. |
Academic research use
The Total-Text dataset materials may be used for non-commercial academic research, education, benchmarking and scholarly publication subject to DATASET_TERMS.md.
If a project is affiliated with or supported by a for-profit company but is intended solely for scholarly research and publication and is segregated from commercial product or model development, please obtain written confirmation from us before relying on the academic-use permission.
Commercial use
Commercial use of the Total-Text dataset materials requires prior written permission from the applicable rights holder. Commercial use includes, for example, use of the dataset to support product or service development, commercial model training or fine-tuning, internal commercial benchmarking or validation, deployment, or other business-facing R&D.
For permission requests, contact:
Dr. Chee Seng Chan at cs.chan at um.edu.my.
Attribution
Academic publications using Total-Text should cite:
@article{CK2019,
  author    = {Chee Kheng Ch’ng and
               Chee Seng Chan and
               Chenglin Liu},
  title     = {Total-Text: Towards Orientation Robustness in Scene Text Detection},
  journal   = {International Journal on Document Analysis and Recognition (IJDAR)},
  volume    = {23},
  pages     = {31-52},
  year      = {2020},
  doi       = {10.1007/s10032-019-00334-z},
}

@inproceedings{ch2017total,
  title={Total-text: A comprehensive dataset for scene text detection and recognition},
  author={Ch'Ng, Chee Kheng and Chan, Chee Seng},
  booktitle={2017 14th IAPR international conference on document analysis and recognition (ICDAR)},
  volume={1},
  pages={935--942},
  year={2017},
  organization={IEEE}
}
Rights notice
Permissions are granted only to the extent that the applicable licensor is authorised to grant them. Nothing in this repository grants rights in third-party material beyond the rights held by the applicable rights holder.
These clarified terms apply prospectively from 01 Oct 2026. They do not purport to revoke or determine the scope of any rights that may have been validly granted under an earlier version of this repository.
©2017-2026 Chee Seng Chan. Developed at Universiti Malaya.
Significant stargazers

21 followers · starred Jan 2025
Similar repos


Total Text Dataset. It consists of 1555 images with more than 3 different text orientations: Horizontal, Multi-Oriented, and Curved, one of a kind.
MATLAB
772
323 commits
updated Sep 30, 2026
README
Total-Text-Dataset (Official site)
Updated on September 30, 2026 (Updated README.md & LICENSE. Added DATASET_TERMS.md & RIGHTS_NOTICE.md)
Updated on April 06, 2022 (Detection leaderboard is updated with FCE, ABPNet, PCR, CentripetalText & HierText)
Updated on April 29, 2020 (Detection leaderboard is updated - highlighted E2E methods. Thank you shine-lcy.)
Updated on March 19, 2020 (Query on the new groundtruth of test set)
Updated on Sept. 08, 2019 (New training groundtruth of Total-Text is now available)
Updated on Sept. 07, 2019 (Updated Guided Annotation toolbox for scene text image annotation)
Updated on Sept. 07, 2019 (Updated baseline as to our IJDAR)
Updated on August 01, 2019 (Extended version with new baseline + annotation tool is accepted at IJDAR)
Updated on May 30, 2019 (Important announcement on Total-Text vs. ArT dataset)
Updated on April 02, 2019 (Updated table ranking with default vs. our proposed DetEval)
Updated on March 31, 2019 (Faster version DetEval.py, support Python3. Thank you princewang1994.)
Updated on March 14, 2019 (Updated table ranking with evaluation protocol info.)
Updated on November 26, 2018 (Table ranking is included for reference.)
Updated on August 24, 2018 (Newly added Guided Annotation toolbox folder.)
Updated on May 15, 2018 (Added groundtruth in '.txt' format.)
Updated on May 14, 2018 (Added feature - 'Do not care' candidates filtering is now available in the latest python scripts.)
Updated on April 03, 2018 (Added pixel level groundtruth)
Updated on November 04, 2017 (Added text level groundtruth)
Released on October 27, 2017
News
-
We received some questions in regard to the new groundtruth for the test set of Total-Text. Here is an update. We do not release a new version of the test set groundtruth because
 1) there is no need of standardising the length of the groundtruth vertices for testing purpose, it was proposed to facilitate training only, and
 2) a new version of groundtruth would make the previous benchmarks irrelevant.
Do contact us if you think there is a valid reason to require the new groundtruth for the test set, we shall discuss about it.
- TOTAL-TEXT is a word-level based English curve text dataset. If you are interested in text-line based dataset with both English and Chinese instances, we highly recommend you to refer SCUT-CTW1500. In addition, a Robust Reading Challenge on Arbitrary-Shaped Text (RRC-ArT), which is extended from Total-Text and SCUT-CTW1500, was held at ICDAR2019 to stimulate more innovative ideas on the arbitrary-shaped text reading task. Congratulations to all winners and challengers. The technical report of ArT can be found on at this https URL.
Important Announcement
Total-Text and SCUT-CTW1500 are now part of the training set of the largest curved text dataset - ArT (Arbitrary-Shaped Text dataset). In order to retain the validity of future benchmarking on Total-Text datasets, the test-set images of Total-Text should be removed (with the corresponding ID provided HERE) from the ArT dataset shall one intend to leverage the extra training data from the ArT dataset. We count on the trust of the research community to perform such removal operation to attain the fairness of the benchmarking.
Table Ranking
- The results from recent papers on Total-Text dataset are listed below where P=Precision, R=Recall & F=F-score.
- If your result is missing or incorrect, please do not hesisate to contact us.
- The baseline scores are based on our proposed [Poly-FRCNN-3] in this folder.
- *Pascal VOC IoU metric; **Polygon Regression
Detection Leaderboard
| Method | Reported on paper | DetEval (tp=0.4, tr=0.8) (Default) | DetEval (tp=0.6, tr=0.7) (New Proposal) | Published at | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| P | R | F | P | R | F | P | R | F | ||
| Our Baseline [paper] | 78.0 | 68.0 | 73.0 | - | - | - | 78.0 | 68.0 | 73.0 | IJDAR2020 |
| CentripetalText [paper] | 90.67 | 85.19 | 87.85 | - | - | - | - | - | - | NeurIPS2021 |
| ABPNet [paper] | 90.6 | 82.5 | 86.3 | - | - | - | - | - | - | ICCV2021 |
| CRAFTS [paper] | 89.5 | 85.4 | 87.4 | - | - | - | - | - | - | ECCV2020 |
| FCE [paper] | 89.3 | 82.5 | 85.8 | - | - | - | - | - | - | CVPR2021 |
| #ASTS_Weakly-ResNet101 (E2E) [paper] | - | - | 87.3 | - | - | - | - | - | - | TIP2020 |
| TextFuseNet [paper] | 89.0 | 85.3 | 87.1 | - | - | - | - | - | - | IJCAI2020 |
| #Boundary (E2E) [paper] | 88.9 | 85.0 | 87.0 | - | - | - | - | - | - | AAAI2020 |
| PCR [paper] | 88.5 | 82.0 | 85.2 | - | - | - | - | - | - | CVPR2021 |
| PolyPRNet [paper] | 88.1 | 85.3 | 86.7 | - | - | - | - | - | - | ACCV2020 |
| #Qin et al. (E2E) [paper] | 87.8 | 85.0 | 86.4 | - | - | - | - | - | - | ICCV2019 |
| 100%Poly [paper] | 88.2 | 83.3 | 85.6 | - | - | - | - | - | - | arXiv:2012 |
| ContourNet [paper] | 86.9 | 83.9 | 85.4 | - | - | - | - | - | - | CVPR2020 |
| #Text Perceptron (E2E) [paper] | 88.8 | 81.8 | 85.2 | - | - | - | - | - | - | AAAI2020 |
| PAN-640 [paper] | 89.3 | 81.0 | 85.0 | - | - | - | - | - | - | ICCV2019 |
| DB-ResNet50 (800) [paper] | 87.1 | 82.5 | 84.7 | - | - | - | - | - | - | AAAI2020 |
| TextCohesion [paper] | 88.1 | 81.4 | 84.6 | - | - | - | - | - | - | arXiv:1904 |
| Feng et al. [paper] | 87.3 | 81.1 | 84.1 | - | - | - | - | - | - | IJCV2020 |
| HierText [paper] | 85.49 | 90.53 | 87.94 | - | - | - | - | - | - | CVPR2022 |
| ReLaText [paper] | 84.8 | 83.1 | 84.0 | - | - | - | - | - | - | arXiv:2003 |
| CRAFT [paper] | 87.6 | 79.9 | 83.6 | - | - | - | - | - | - | CVPR2019 |
| LOMO MS [paper] | 87.6 | 79.3 | 83.3 | - | - | - | - | - | - | CVPR2019 |
| SPCNet [paper] | 83.0 | 82.8 | 82.9 | - | - | - | - | - | - | AAAI2019 |
| #ABCNet (E2E) [paper] | 85.4 | 80.1 | 82.7 | - | - | - | - | - | - | CVPR2020 |
| ICG [paper] | 82.1 | 80.9 | 81.5 | - | - | - | - | - | - | PR2019 |
| FTSN [paper] | *84.7 | *78.0 | *81.3 | - | - | - | - | - | - | ICPR2018 |
| PSENet-1s [paper] | 84.02 | 77.96 | 80.87 | - | - | - | - | - | - | CVPR2019 |
| 1TextField [paper] | 81.2 | 79.9 | 80.6 | 76.1 | 75.1 | 75.6 | 83.0 | 82.0 | 82.5 | TIP2019 |
| #TextDragon (E2E) [paper] | 85.6 | 75.7 | 80.3 | - | - | - | - | - | - | ICCV2019 |
| CSE [paper] | 81.4 (**80.9) | 79.7 (**80.3) | 80.2 (**80.6) | - | - | - | - | - | - | CVPR2019 |
| MSR [paper] | 85.2 | 73.0 | 78.6 | 82.7 | 68.3 | 74.9 | 81.4 | 72.5 | 76.7 | arXiv:1901 |
| ATTR [paper] | 80.9 | 76.2 | 78.5 | - | - | - | - | - | - | CVPR2019 |
| TextSnake [paper] | 82.7 | 74.5 | 78.4 | - | - | - | - | - | - | ECCV2018 |
| 1CTD [paper] | 74.0 | 71.0 | 73.0 | 60.7 | 58.8 | 59.8 | 76.5 | 73.8 | 75.2 | PR2019 |
| #TextNet (E2E) [paper] | 68.2 | 59.5 | 63.5 | - | - | - | - | - | - | ACCV2018 |
| #,2Mask TextSpotter (E2E) [paper] | 69.0 | 55.0 | 61.3 | 68.9 | 62.5 | 65.5 | 82.5 | 75.2 | 78.6 | ECCV2018 |
| CENet [paper] | 59.9 | 54.4 | 57.0 | - | - | - | - | - | - | ACCV2018 |
| #Textboxes (E2E) [paper] | 62.1 | 45.5 | 52.5 | - | - | - | - | - | - | AAAI2017 |
| EAST [paper] | 50.0 | 36.2 | 42.0 | - | - | - | - | - | - | CVPR2017 |
| SegLink [paper] | 30.3 | 23.8 | 26.7 | - | - | - | - | - | - | CVPR2017 |
Note:
# Framework that does end-to-end training (i.e. detection + recognition).
1For the results of TextField and CTD, the improved versions of their original paper were used, and this explains why the performance is better.
2For Mask-TextSpotter, the relatively poor performance reported in their paper was due to a bug in the input reading module (which was fixed recently). The authors were informed about this issue.
End-to-end Recognition Leaderboard
(None refers to recognition without any lexicon; Full lexicon contains all words in test set.)
| Method | Backbone | None (%) | Full (%) | FPS | Published at |
|---|---|---|---|---|---|
| CRAFTS [paper] | ResNet50-FPN | 78.7 | - | - | ECCV2020 |
| MANGO [paper] | ResNet50-FPN | 72.9 | 83.6 | 4.3 | AAAI2021 |
| Text Perceptron [paper] | ResNet50-FPN | 69.7 | 78.3 | - | AAAI2020 |
| ABCNet-MS [paper] | ResNet50-FPN | 69.5 | 78.4 | 6.9 | CVPR2020 |
| CharNet H-88 MS [paper] | ResNet50-Hourglass57 | 69.2 | - | 1.2 | ICCV2019 |
| Qin et al. [paper] | ResNet50-MSF | 67.8 | - | - | ICCV2019 |
| ASTS_Weakly [paper] | ResNet101-FPN | 65.3 | 84.2 | 2.5 | TIP2020 |
| Boundary [paper] | ResNet50-FPN | 65.0 | 76.1 | - | AAAI2020 |
| ABCNet [paper] | ResNet50-FPN | 64.2 | 75.7 | 17.9 | CVPR2020 |
| CAPNet [paper] | ResNet50-FPN | 62.7 | - | - | ICASSP2020 |
| Feng et al. [paper] | VGG | 55.8 | 79.2 | - | IJCV2020 |
| TextNet [paper] | ResNet50-SAM | 54.0 | - | 2.7 | ACCV2018 |
| Mask TextSpotter [paper] | ResNet50-FPN | 52.9 | 71.8 | 4.8 | ECCV2018 |
| TextDragon [paper] | VGG16 | 48.8 | 74.8 | - | ICCV2019 |
| Textboxes [paper] | ResNet50-FPN | 36.3 | 48.9 | 1.4 | AAAI2017 |
Description
In order to facilitate a new text detection research, we introduce Total-Text dataset (IJDAR)(ICDAR-17 paper) (presentation slides), which is more comprehensive than the existing text datasets. The Total-Text consists of 1555 images with more than 3 different text orientations: Horizontal, Multi-Oriented, and Curved, one of a kind.
Contributors:
Chee Kheng Chng, Chun Chet Ng, Chee Seng Chan
Feedback
Suggestions and opinions of this dataset (both positive and negative) are greatly welcome. Please contact the authors by sending email to
chngcheekheng at gmail.com or cs.chan at um.edu.my.
License, Dataset Terms and Copyright
Total-Text contains different categories of material. Different terms apply to different components:
| Material | Applicable terms |
|---|---|
| Software code, evaluation scripts, baseline code and annotation tools | BSD-3-Clause. See LICENSE. |
| Total-Text annotations, ground-truth files, transcriptions, masks, metadata and dataset splits created for Total-Text | See DATASET_TERMS.md. |
| Underlying images and other third-party material, if any | Not licensed under the BSD-3-Clause software licence. Separate rights may apply. |
Academic research use
The Total-Text dataset materials may be used for non-commercial academic research, education, benchmarking and scholarly publication subject to DATASET_TERMS.md.
If a project is affiliated with or supported by a for-profit company but is intended solely for scholarly research and publication and is segregated from commercial product or model development, please obtain written confirmation from us before relying on the academic-use permission.
Commercial use
Commercial use of the Total-Text dataset materials requires prior written permission from the applicable rights holder. Commercial use includes, for example, use of the dataset to support product or service development, commercial model training or fine-tuning, internal commercial benchmarking or validation, deployment, or other business-facing R&D.
For permission requests, contact:
Dr. Chee Seng Chan at cs.chan at um.edu.my.
Attribution
Academic publications using Total-Text should cite:
@article{CK2019,
  author    = {Chee Kheng Ch’ng and
               Chee Seng Chan and
               Chenglin Liu},
  title     = {Total-Text: Towards Orientation Robustness in Scene Text Detection},
  journal   = {International Journal on Document Analysis and Recognition (IJDAR)},
  volume    = {23},
  pages     = {31-52},
  year      = {2020},
  doi       = {10.1007/s10032-019-00334-z},
}

@inproceedings{ch2017total,
  title={Total-text: A comprehensive dataset for scene text detection and recognition},
  author={Ch'Ng, Chee Kheng and Chan, Chee Seng},
  booktitle={2017 14th IAPR international conference on document analysis and recognition (ICDAR)},
  volume={1},
  pages={935--942},
  year={2017},
  organization={IEEE}
}
Rights notice
Permissions are granted only to the extent that the applicable licensor is authorised to grant them. Nothing in this repository grants rights in third-party material beyond the rights held by the applicable rights holder.
These clarified terms apply prospectively from 01 Oct 2026. They do not purport to revoke or determine the scope of any rights that may have been validly granted under an earlier version of this repository.
©2017-2026 Chee Seng Chan. Developed at Universiti Malaya.
Similar repos
Significant stargazers
21 followers · starred Jan 2025