
UX review for apps built with AI, inside the agent you already use. Keeps your design, cuts the overcoding.
See the codeSee what people are saying
README
Phyll
UX review for apps built with AI, inside the agent you already use.
Phyll walks through your app the way a first-time user would. It collects screenshots, measurements from the live page and the clicks each job took, then tells you what makes the product hard to understand or use. It knows the defaults that code generators leave behind, in how an app looks and in how its flows work, and it can fix them for you.
Phyll keeps your design. Colors, gradients, fonts and layout stay as they are. The changes go where people get stuck: forms that ask for more than the job needs, steps that fit on one screen, buttons that lead nowhere and text too faint to read.
The review runs in Codex or Claude Code, on your own plan. Phyll adds a browser, a scanner and its review engine, and never charges for AI tokens.
To try it with no account, run the scanner in your project. It gives an AI tell index from 0 to 100, lower is better, and points to each tell by file and line:
npx phyll scan
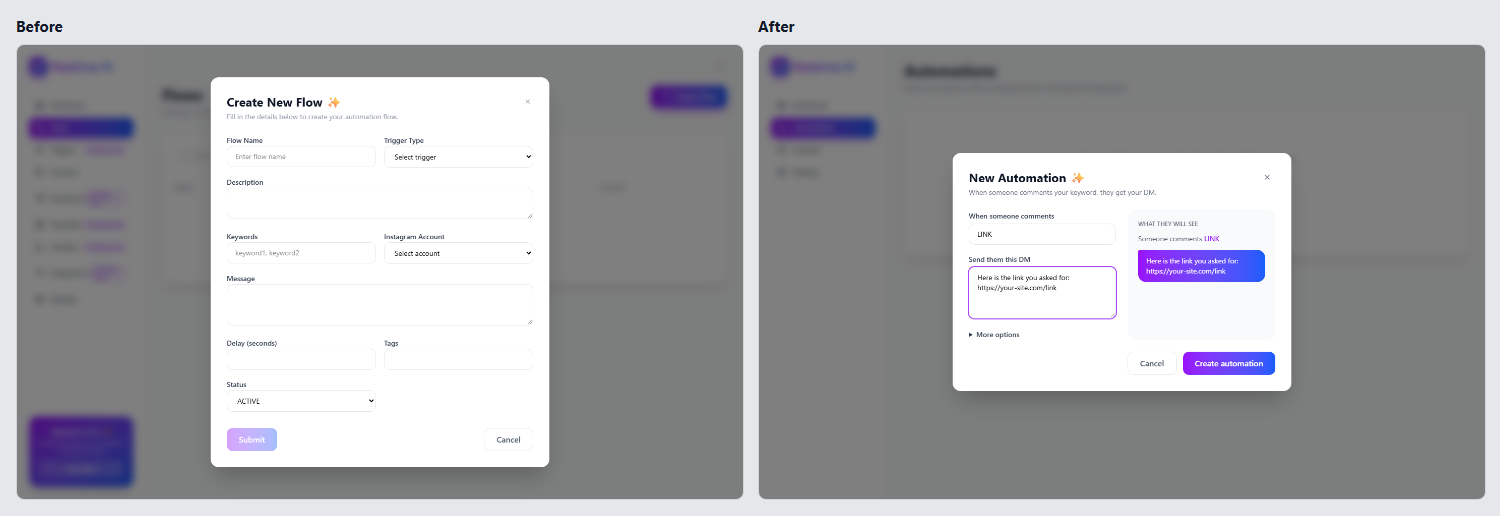
The same app, a ManyChat-style tool for Instagram creators, before and after a Phyll review. The review of the left side is in examples/dm-automation/review/report.md: 12 findings, an AI tell index of 79, and a first job that could not be finished.
Start
Create a free account at agentphyll.com, or from the terminal, and connect Phyll to your agent:
npx phyll signup you@example.com
npx phyll setup codex        # or: npx phyll setup claude
Then ask your agent: "review my app at http://localhost:3000". It opens the app, walks the core jobs, writes the report in .phyll/reports/<time>/ and gives you a link to it.
Every report, your keys and your plan are also at agentphyll.com/account, and npx phyll account opens it already signed in. If you lose the key, sign in there with your email and create a new one.
In Claude Code you can also install the plugin, which adds /phyll:review, /phyll:fix and /phyll:scan:
/plugin marketplace add carlosphyll/phyll
/plugin install phyll@carlosphyll
The plugin starts the connector by itself, so with it you skip npx phyll setup claude. You need Node 20 or newer. setup installs the Chromium build that Phyll's browser uses.
Free and Phyll Pro
| Free | Phyll Pro, R$ 9 a month | |
|---|---|---|
| The source scanner, here and in CI | Unlimited | Unlimited |
| Full reviews in your agent, with fixes | 5 | Unlimited |
| A link to each report, history, before and after | Yes | Yes |
| Specialized rule packs | No | As they come out |
The price is in Brazilian reais, and checkout shows it in your currency. npx phyll pro opens the checkout, and npx phyll billing changes the card or cancels. The AI work always runs on your agent's plan.
Four apps, before and after
Each example is a small app written the way a code generator tends to write it, the same app after the review, and the full review of the first version. Three of them are Brazilian businesses, reviewed in Portuguese.
| Example | The first job | Fields | Clicks | AI tell index | Style kept |
|---|---|---|---|---|---|
| Replyloop | Send a DM to everyone who comments a keyword | 9 before, 2 after | 9 before, 3 after | 75 before, 7 after | 10 of 10 traits |
| Navalha Barbearia | Book a haircut | 20 before, 4 after | 18 before, 4 after | 54 before, 6 after | 9 of 9 traits |
| Orça Já | Write a quote and send it to the client | 41 before, 4 after | 10 before, 2 after | 66 before, 6 after | 9 of 10 traits |
| Brasa Burger | Order a burger for delivery | 33 before, 4 after | 15 before, 5 after | 53 before, 6 after | 8 of 8 traits |
Fields and clicks count what a first-time user had to do for the first job, and none of the before apps got that person to the result. The AI tell index comes from the scanner, and lower is better. Style kept counts the visual traits of the before app, such as gradients, glass and emoji, that are still there after the fixes.
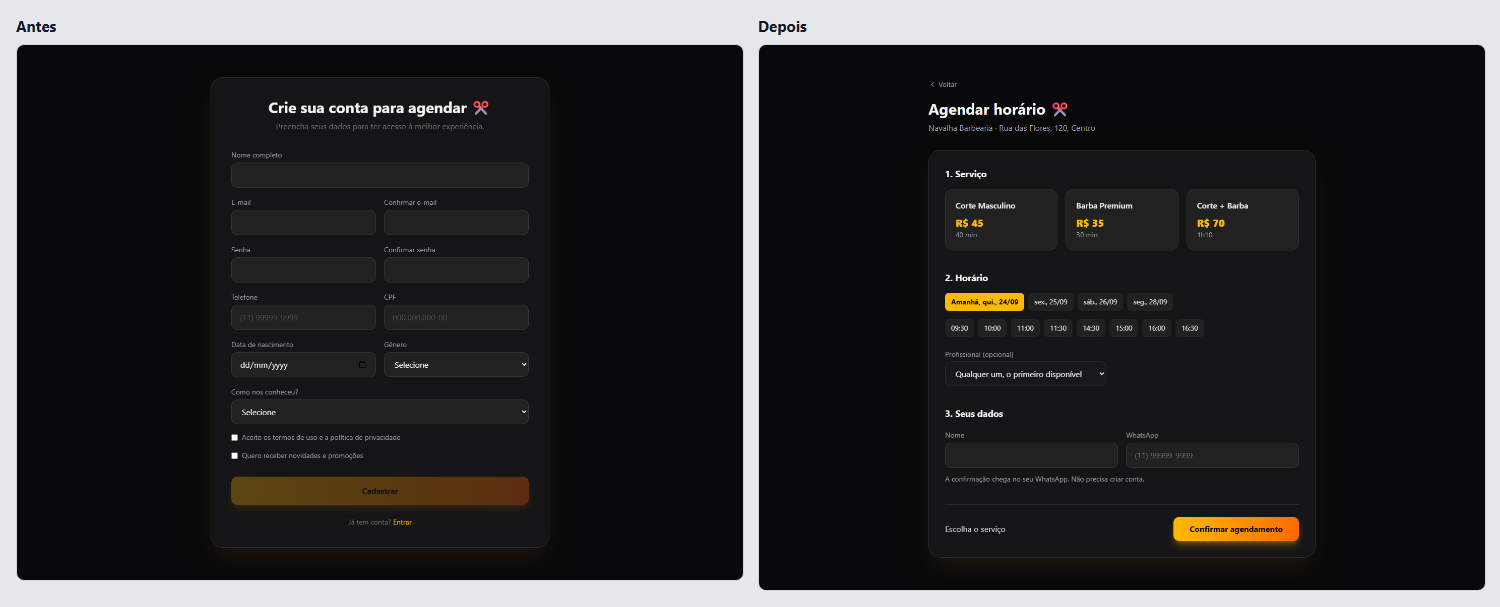
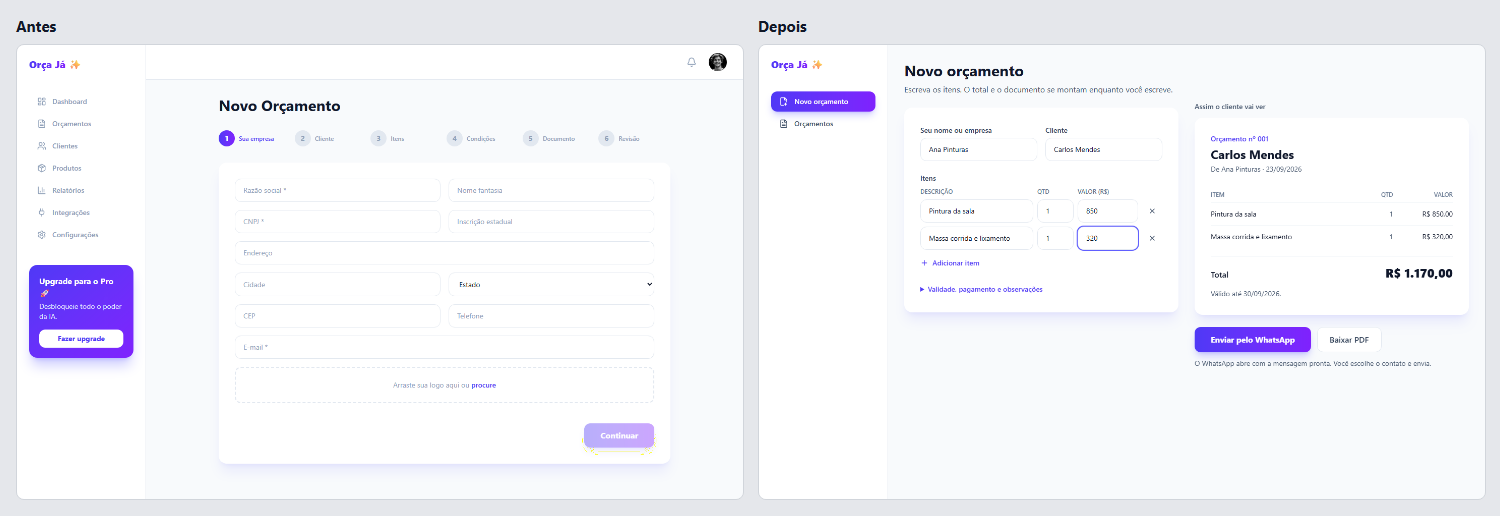
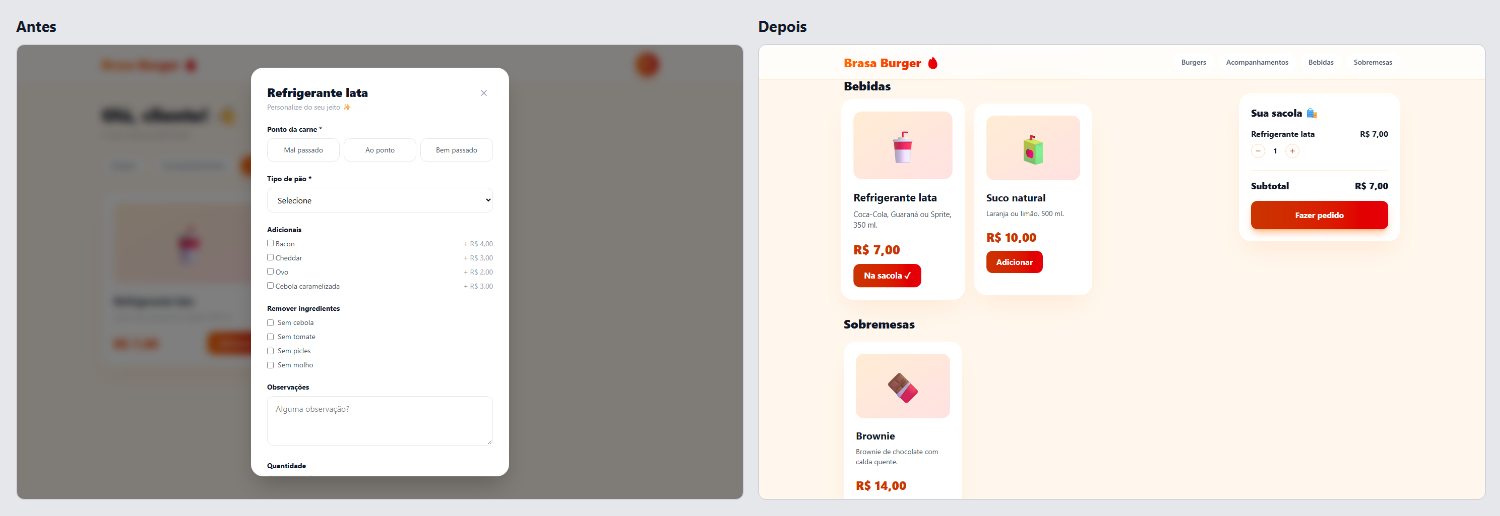
Every example folder has its review in review/report.md and more comparisons in screenshots/. examples/README.md explains how to run them.
What it catches
- Purpose. A first screen that does not say what the product does, a sales page in front of the tool, a dashboard of invented numbers for someone who just signed up.
- Flow. A login before the menu, a CPF to book a haircut, 39 fields for a quote, a modal for everything, buttons that do nothing, a "Success!" that leads nowhere.
- Actions. The main button far from the content it acts on, icon buttons with no name, delete without undo, actions that only appear on hover, choices the keyboard cannot reach.
- Look. Gray text below the contrast minimum, white text on bright orange buttons, layouts that break on a phone. Gradients, glass, emoji and centered heroes are listed as style notes and left as they are.
- Copy. "Supercharge your workflow", "Get Started", "Trusted by 10,000+", John Doe or João da Silva,
COMMENT_KEYWORDon screen, "Something went wrong". - States. Empty states that only say "No data", errors that only reach the console, a confirmation that shows someone else's appointment, invisible keyboard focus.
Each of these is one of 53 tells in Phyll's catalog. The catalog as data, with the detectors that find tells in source code, is in skills/phyll/data/tells.json, and the test suite checks every detector against real code and the four example apps.
How a review works
- Frame. Your agent works out who uses the product and the two or three jobs they come to do.
- Collect evidence. Phyll scans the source, captures every screen at laptop and phone sizes, and runs a probe in the page that measures contrast, button sizes and positions, and form fields. Then your agent walks each job as a first-time user and counts clicks, screens and dead ends.
- Judge. Findings are sorted into six dimensions, backed by principles such as Fitts's law, Nielsen's heuristics and WCAG, and ranked by how much they block the end user. For each job, the review also compares the fields and clicks it asks for with what the job needs, and marks what can get a default, wait until later or go.
- Report. Phyll's engine checks the report, scores it and keeps it with a link. You get
report.md, which opens with the three findings that block people most and a table of what can be cut. The report also gives an AI tell index from 0 to 100, which you can watch go down. - Fix, when you ask. Your agent applies the fixes one finding at a time, with a commit and a before and after screenshot for each. New buttons and messages reuse the product's own classes, so the design stays.
The scanner, free and on its own
The scanner reads the source for AI tells, with no account and no AI:
npx phyll scan .
The repository is also a GitHub Action that scans every pull request and puts the AI tell index in the job summary:
- uses: actions/checkout@v4
- uses: carlosphyll/phyll@v0.4.3
  with:
    path: .
    fail-above: 40
fail-above is optional. Without it the job reports the index and never fails.
What leaves your computer
Your source code, your screenshots and your agent's conversation stay on your computer. When a review starts, the connector sends Phyll's engine the app's address, the project name, and a summary of the scan: which tells it found, how many times, and the paths of routes and forms. When the review ends, it sends report.json, the findings your agent wrote, which the engine keeps so the link works. Nothing else is sent, and the scanner sends nothing at all.
What is in this repository
packages/connector: thephyllpackage on npm. The commands, and the MCP server your agent starts, with the browser, the probe and the scanner.skills/phyll: the skill that tells agents how to use the connector, the scanner's code and the catalog as data.examples: the four apps, their reviews and the comparisons.action.yml: the GitHub Action for the scan.
The review method and the engine run on Phyll's server and are not in this repository.
Contributing
The most useful contribution is a tell you keep seeing in generated apps, with an example that shows it. CONTRIBUTING.md explains how to add a detector; the tests check that it catches your example. A new example app helps too. Bug reports and support for more frameworks are welcome.
License
MIT, including for commercial use. The Phyll name and logo are not covered by the license; see TRADEMARK.md.
Contributors

8 commits
Similar repos


Languages
JavaScript
100.0%
UX review for apps built with AI, inside the agent you already use. Keeps your design, cuts the overcoding.
See the codeSee what people are saying
README
Phyll
UX review for apps built with AI, inside the agent you already use.
Phyll walks through your app the way a first-time user would. It collects screenshots, measurements from the live page and the clicks each job took, then tells you what makes the product hard to understand or use. It knows the defaults that code generators leave behind, in how an app looks and in how its flows work, and it can fix them for you.
Phyll keeps your design. Colors, gradients, fonts and layout stay as they are. The changes go where people get stuck: forms that ask for more than the job needs, steps that fit on one screen, buttons that lead nowhere and text too faint to read.
The review runs in Codex or Claude Code, on your own plan. Phyll adds a browser, a scanner and its review engine, and never charges for AI tokens.
To try it with no account, run the scanner in your project. It gives an AI tell index from 0 to 100, lower is better, and points to each tell by file and line:
npx phyll scan
The same app, a ManyChat-style tool for Instagram creators, before and after a Phyll review. The review of the left side is in examples/dm-automation/review/report.md: 12 findings, an AI tell index of 79, and a first job that could not be finished.
Start
Create a free account at agentphyll.com, or from the terminal, and connect Phyll to your agent:
npx phyll signup you@example.com
npx phyll setup codex        # or: npx phyll setup claude
Then ask your agent: "review my app at http://localhost:3000". It opens the app, walks the core jobs, writes the report in .phyll/reports/<time>/ and gives you a link to it.
Every report, your keys and your plan are also at agentphyll.com/account, and npx phyll account opens it already signed in. If you lose the key, sign in there with your email and create a new one.
In Claude Code you can also install the plugin, which adds /phyll:review, /phyll:fix and /phyll:scan:
/plugin marketplace add carlosphyll/phyll
/plugin install phyll@carlosphyll
The plugin starts the connector by itself, so with it you skip npx phyll setup claude. You need Node 20 or newer. setup installs the Chromium build that Phyll's browser uses.
Free and Phyll Pro
| Free | Phyll Pro, R$ 9 a month | |
|---|---|---|
| The source scanner, here and in CI | Unlimited | Unlimited |
| Full reviews in your agent, with fixes | 5 | Unlimited |
| A link to each report, history, before and after | Yes | Yes |
| Specialized rule packs | No | As they come out |
The price is in Brazilian reais, and checkout shows it in your currency. npx phyll pro opens the checkout, and npx phyll billing changes the card or cancels. The AI work always runs on your agent's plan.
Four apps, before and after
Each example is a small app written the way a code generator tends to write it, the same app after the review, and the full review of the first version. Three of them are Brazilian businesses, reviewed in Portuguese.
| Example | The first job | Fields | Clicks | AI tell index | Style kept |
|---|---|---|---|---|---|
| Replyloop | Send a DM to everyone who comments a keyword | 9 before, 2 after | 9 before, 3 after | 75 before, 7 after | 10 of 10 traits |
| Navalha Barbearia | Book a haircut | 20 before, 4 after | 18 before, 4 after | 54 before, 6 after | 9 of 9 traits |
| Orça Já | Write a quote and send it to the client | 41 before, 4 after | 10 before, 2 after | 66 before, 6 after | 9 of 10 traits |
| Brasa Burger | Order a burger for delivery | 33 before, 4 after | 15 before, 5 after | 53 before, 6 after | 8 of 8 traits |
Fields and clicks count what a first-time user had to do for the first job, and none of the before apps got that person to the result. The AI tell index comes from the scanner, and lower is better. Style kept counts the visual traits of the before app, such as gradients, glass and emoji, that are still there after the fixes.
Every example folder has its review in review/report.md and more comparisons in screenshots/. examples/README.md explains how to run them.
What it catches
- Purpose. A first screen that does not say what the product does, a sales page in front of the tool, a dashboard of invented numbers for someone who just signed up.
- Flow. A login before the menu, a CPF to book a haircut, 39 fields for a quote, a modal for everything, buttons that do nothing, a "Success!" that leads nowhere.
- Actions. The main button far from the content it acts on, icon buttons with no name, delete without undo, actions that only appear on hover, choices the keyboard cannot reach.
- Look. Gray text below the contrast minimum, white text on bright orange buttons, layouts that break on a phone. Gradients, glass, emoji and centered heroes are listed as style notes and left as they are.
- Copy. "Supercharge your workflow", "Get Started", "Trusted by 10,000+", John Doe or João da Silva,
COMMENT_KEYWORDon screen, "Something went wrong". - States. Empty states that only say "No data", errors that only reach the console, a confirmation that shows someone else's appointment, invisible keyboard focus.
Each of these is one of 53 tells in Phyll's catalog. The catalog as data, with the detectors that find tells in source code, is in skills/phyll/data/tells.json, and the test suite checks every detector against real code and the four example apps.
How a review works
- Frame. Your agent works out who uses the product and the two or three jobs they come to do.
- Collect evidence. Phyll scans the source, captures every screen at laptop and phone sizes, and runs a probe in the page that measures contrast, button sizes and positions, and form fields. Then your agent walks each job as a first-time user and counts clicks, screens and dead ends.
- Judge. Findings are sorted into six dimensions, backed by principles such as Fitts's law, Nielsen's heuristics and WCAG, and ranked by how much they block the end user. For each job, the review also compares the fields and clicks it asks for with what the job needs, and marks what can get a default, wait until later or go.
- Report. Phyll's engine checks the report, scores it and keeps it with a link. You get
report.md, which opens with the three findings that block people most and a table of what can be cut. The report also gives an AI tell index from 0 to 100, which you can watch go down. - Fix, when you ask. Your agent applies the fixes one finding at a time, with a commit and a before and after screenshot for each. New buttons and messages reuse the product's own classes, so the design stays.
The scanner, free and on its own
The scanner reads the source for AI tells, with no account and no AI:
npx phyll scan .
The repository is also a GitHub Action that scans every pull request and puts the AI tell index in the job summary:
- uses: actions/checkout@v4
- uses: carlosphyll/phyll@v0.4.3
  with:
    path: .
    fail-above: 40
fail-above is optional. Without it the job reports the index and never fails.
What leaves your computer
Your source code, your screenshots and your agent's conversation stay on your computer. When a review starts, the connector sends Phyll's engine the app's address, the project name, and a summary of the scan: which tells it found, how many times, and the paths of routes and forms. When the review ends, it sends report.json, the findings your agent wrote, which the engine keeps so the link works. Nothing else is sent, and the scanner sends nothing at all.
What is in this repository
packages/connector: thephyllpackage on npm. The commands, and the MCP server your agent starts, with the browser, the probe and the scanner.skills/phyll: the skill that tells agents how to use the connector, the scanner's code and the catalog as data.examples: the four apps, their reviews and the comparisons.action.yml: the GitHub Action for the scan.
The review method and the engine run on Phyll's server and are not in this repository.
Contributing
The most useful contribution is a tell you keep seeing in generated apps, with an example that shows it. CONTRIBUTING.md explains how to add a detector; the tests check that it catches your example. A new example app helps too. Bug reports and support for more frameworks are welcome.
License
MIT, including for commercial use. The Phyll name and logo are not covered by the license; see TRADEMARK.md.
Similar repos
Contributors
8 commits
Languages
JavaScript
100.0%