
Find out whether a generated web page actually works.
See the codeSee what people are saying (1)
README
assay


Find out whether a generated web page actually works.
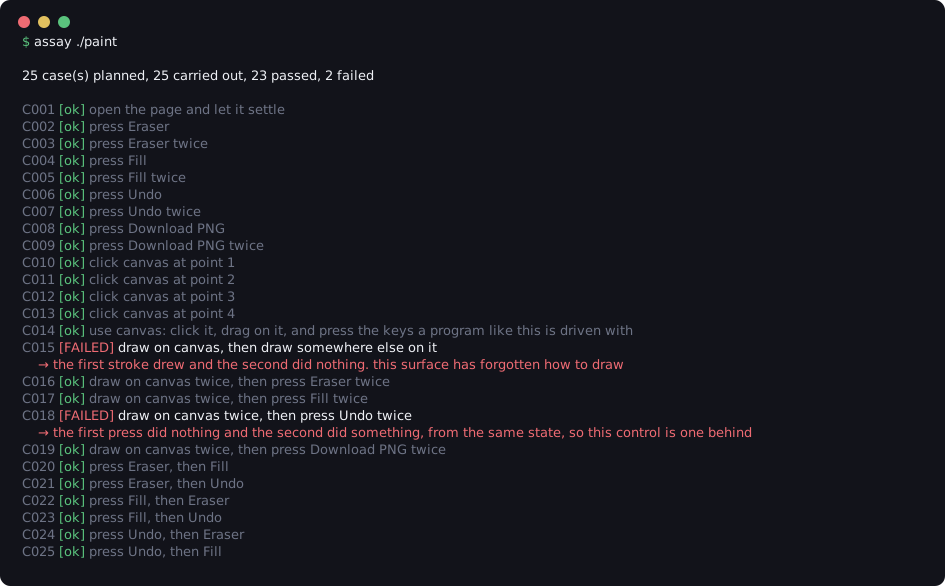
Checking a generated paint program. Nobody wrote a test.
Point it at a page. assay opens it in a real browser, measures every control it renders, works out a test plan from what it finds, drives all of it, and tells you what broke.
Highlights
- No tests to write. The plan comes from the page, so a program written ten seconds ago can be checked ten seconds later.
- No LLM. Purely mechanical. No API key, no tokens, no rate limit, nothing to bill. It gives the same answer twice.
- No baseline images and no recordings. Nothing to capture first, nothing to keep in step with the design.
- It says why. Not case 14 failed, but the first press did nothing and the second did something, so this control is one behind.
Contents
Install
CLI
pip install assay-ui
The command is assay. The first run fetches a browser if there is not one
already, so there is no second command to forget.
To hack on it, clone and install it in place:
git clone https://github.com/awss1i/assay.git && cd assay
pip install -e ".[dev]"
Skills and Plugins
Install steps for fifteen harnesses. All of them want the CLI above first.
Use
CLI
assay ./my-app                    # check the page in this folder
assay ./my-app/todo.html          # check one page by name
assay ./my-app -e app.html        # or name the page inside a folder

assay ./my-app --report out.html  # write an HTML report with screenshots
assay ./my-app --json             # print the whole run as JSON
assay ./my-app --one-line         # print one sentence, for a script to relay
assay ./my-app --surface          # list the controls it found, then stop
There is a broken drawing program in this repository. Run it yourself:
$ assay bench/programs/dsh/gpt-oss-120b/37_draw2
23 case(s) planned, 23 carried out, 22 passed, 1 failed

C013 [ok] use canvas: click it, drag on it, and press the keys a program like this is driven with
C014 [ok] draw on canvas, then draw somewhere else on it
C015 [FAILED] draw on canvas twice, then press Undo twice
    → the first press did nothing and the second did something, from the same state, so this control is one behind
C016 [ok] draw on canvas twice, then press Redo twice
C017 [ok] draw on canvas twice, then press Clear twice
Drawing works. Redo works. Clear works. Undo is one press behind, and nothing about the source says so.
Where the results go. Everything goes to stdout and nothing is written
to disk unless you ask, because a CI check that only cares about the exit
code should not litter. --report FILE writes one self-contained HTML page
plus a shots/ folder of screenshots beside it. --json prints the whole run
for piping. The exit code is non-zero if anything failed.
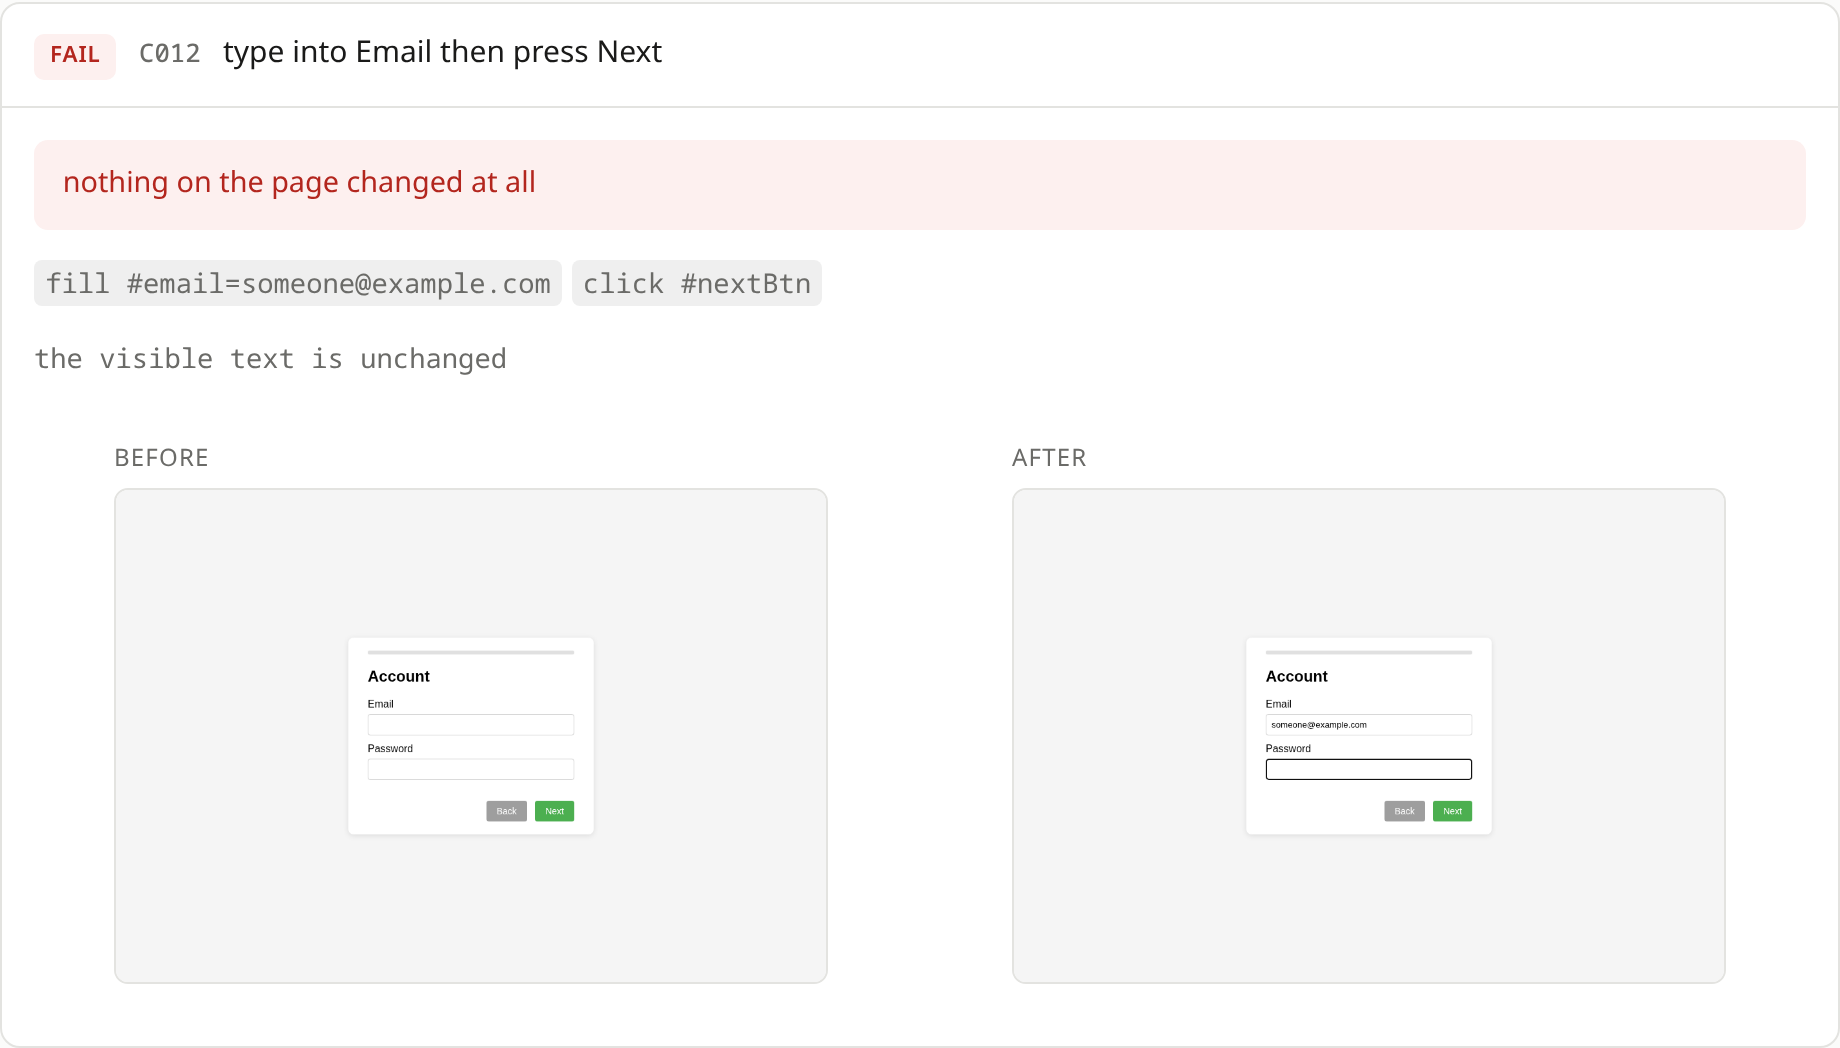
--report gives you every case with the page as the browser drew it, before
and after:
From Python. The same run, as an object.
from assay import check

report = check("./my-app")
print(report.summary())
for result in report.failing:
    print(result.case.what, "->", result.detail)
Skills
Claude Code, DeepSeek Harness, opencode, Antigravity, Codex App, Codex CLI, Cursor, Devin CLI, Factory Droid, Gemini CLI, GitHub Copilot CLI, Grok Build CLI, Kimi Code, Pi, Hermes Agent.
One markdown file. Your agent runs assay when it finishes a page and prints what came back:
assay: checked todo/todo.html, 8 checks, nothing flagged.
One line, every time, whether or not it found anything. It reports and never fixes: the agent hands over what it pressed and what happened, and does not edit code on the strength of it.
Plugins
Claude Code, DeepSeek Harness.
The same skill plus a hook, so the check happens at the end of every turn that touched a page, whether or not the agent thought to run it.
/plugin marketplace add awss1i/assay
/plugin install assay@assay
Benchmarks
A checker nobody has checked is an opinion with a progress bar. Two sets, built differently, both checked in.
Generated Programs
225 programs written to 75 objectives by three harnesses. A person opened every one and drove it before assay saw it. 20 are broken.
Across 225 pages checked by hand, assay found 15 of the 20 real defects and raised 0 false alarms. When it reports a problem it is a real one 15 times out of 15.
Planted Bugs
Ten working programs, and a copy of each with five bugs put in by a different harness and model. Fifty defects known by construction, and the harder set: pages that work and are wrong, not pages that stopped.
assay found 10 of the 50 planted bugs and flagged 0 of the 10 working originals.
Both reproduce with python bench/score.py and python bench/planted/score.py.
No key, no network.
How It Works
It waits until the page stops arriving, watching whether the set of controls is still changing rather than pausing for a fixed time. It measures the surface from the rendered page and never the markup, down to a grid of plain divs, because a pointer cursor is the page saying click this and a handler attached in JavaScript cannot be read any other way. It derives a plan from that and carries all of it out in a fresh tab, measuring painted pixels per canvas, their centroid and mean colour, an exact pixel hash, the visible text, what is in the fields, and a hash over every element's style.
It is deliberately narrow about what counts as a failure. A plan derived from the page cannot know what a control is for, so a button only has to survive being pressed. Demanding that every press change something would fail a working program for having a Clear button on an empty canvas.
What it can judge without knowing the design is whether the program contradicts itself. A surface that took the first stroke has to take the second. A control that does nothing on its first press and something on its second, from the same state, is one press behind. And if nothing on the page responds to anything, the script probably never ran.
The same goes for what a page shows about itself: a counter reading -1 over
an empty list, a total that follows the list up and not down, a Remove that
takes a different row, NaN where a value belongs, two labels pointing at
one control.
It never says a page is broken. It says what it pressed and what happened:
C006 [FAILED] type into Quantity then press +
    → nothing on the page changed at all
A verdict makes you change code. A measurement makes you look first, and sometimes you find the page was right and the check was aimed at the wrong thing. That is the cheaper mistake to make, and it reads the same either way round: a person knows where to start, and an agent gets a precise place to look instead of a whole file to re-read.
It serves the folder and never builds it. The page is served over
loopback rather than opened off the disk, because a file:// origin blocks
every module the page loads. What it will not do is run your build: npm install executes whatever the dependency tree asks for, as whoever typed the
command, and this is a tool for checking code nobody has read. Point it at a
source tree and it says so:
$ assay ./my-vite-app
assay: index.html loads /src/main.jsx, which a browser cannot run. This is a source tree, not a built one.
  Build it first, in your own shell, then check the output:
    npm install && npm run build && assay my-vite-app/dist
  assay will not run that for you: installing dependencies executes their setup scripts, and this is a tool for checking code nobody has read.
Why
A lot of code is written by models now, and "does this actually run?" is mostly still answered by a person opening it and clicking around.
Every existing tool needs something you do not have for a program that was generated ten seconds ago. Playwright and Cypress need tests somebody wrote. Visual regression needs a golden image to compare against. Benchmarks like SWE-bench use the repository's own suite.
So the thing most people reach for instead is another model: paste the code in and ask whether it looks right. That is a reader guessing about code. assay opens the page and drives it, which is the only way to find out that a button does nothing.
| needs tests written | needs a baseline | runs the program | |
|---|---|---|---|
| Playwright / Cypress | yes | no | yes, the parts you wrote |
| Percy / Chromatic | no | yes | it screenshots it |
| ask a model to review it | no | no | no. It reads the source |
| assay | no | no | yes, all of it |
Limits Worth Knowing
- Browser programs. It opens a page. A program with no page is not something it can measure.
- Coverage cannot judge intent. A control that works mechanically and does the wrong thing passes. Criteria are the answer, and you have to write those.
- A game that ends looks like a page that died. When a program finishes and offers no way to start again, it stops responding to anything, and a plan derived from the page cannot tell that apart from a page that broke.
- Built output, not source trees. It will not run your build. Point it at a source tree and it says so and names the command.
- Single-page programs. It checks the page you point it at and does not crawl. A multi-page site means running it per page, and client-side routing is untested.
- Generated pages, not the live web. It is built for programs somebody just generated, not for sites with a login, a cookie banner or live network calls.
- Speed. Most pages take a few seconds to just under a minute. Across the 225 benchmark programs the median is 14 seconds and 220 finish inside a minute. The slowest recorded took about four minutes.
Contributing
Issues and pull requests are welcome. Setup, tests, benchmarks and what a PR needs are in CONTRIBUTING.md.
Licence
MIT.
Contributors

1 commits
Similar repos


Languages
HTML
70.9%
Python
28.9%
Find out whether a generated web page actually works.
See the codeSee what people are saying (1)
README
assay
Find out whether a generated web page actually works.
Checking a generated paint program. Nobody wrote a test.
Point it at a page. assay opens it in a real browser, measures every control it renders, works out a test plan from what it finds, drives all of it, and tells you what broke.
Highlights
- No tests to write. The plan comes from the page, so a program written ten seconds ago can be checked ten seconds later.
- No LLM. Purely mechanical. No API key, no tokens, no rate limit, nothing to bill. It gives the same answer twice.
- No baseline images and no recordings. Nothing to capture first, nothing to keep in step with the design.
- It says why. Not case 14 failed, but the first press did nothing and the second did something, so this control is one behind.
Contents
Install
CLI
pip install assay-ui
The command is assay. The first run fetches a browser if there is not one
already, so there is no second command to forget.
To hack on it, clone and install it in place:
git clone https://github.com/awss1i/assay.git && cd assay
pip install -e ".[dev]"
Skills and Plugins
Install steps for fifteen harnesses. All of them want the CLI above first.
Use
CLI
assay ./my-app                    # check the page in this folder
assay ./my-app/todo.html          # check one page by name
assay ./my-app -e app.html        # or name the page inside a folder

assay ./my-app --report out.html  # write an HTML report with screenshots
assay ./my-app --json             # print the whole run as JSON
assay ./my-app --one-line         # print one sentence, for a script to relay
assay ./my-app --surface          # list the controls it found, then stop
There is a broken drawing program in this repository. Run it yourself:
$ assay bench/programs/dsh/gpt-oss-120b/37_draw2
23 case(s) planned, 23 carried out, 22 passed, 1 failed

C013 [ok] use canvas: click it, drag on it, and press the keys a program like this is driven with
C014 [ok] draw on canvas, then draw somewhere else on it
C015 [FAILED] draw on canvas twice, then press Undo twice
    → the first press did nothing and the second did something, from the same state, so this control is one behind
C016 [ok] draw on canvas twice, then press Redo twice
C017 [ok] draw on canvas twice, then press Clear twice
Drawing works. Redo works. Clear works. Undo is one press behind, and nothing about the source says so.
Where the results go. Everything goes to stdout and nothing is written
to disk unless you ask, because a CI check that only cares about the exit
code should not litter. --report FILE writes one self-contained HTML page
plus a shots/ folder of screenshots beside it. --json prints the whole run
for piping. The exit code is non-zero if anything failed.
--report gives you every case with the page as the browser drew it, before
and after:
From Python. The same run, as an object.
from assay import check

report = check("./my-app")
print(report.summary())
for result in report.failing:
    print(result.case.what, "->", result.detail)
Skills
Claude Code, DeepSeek Harness, opencode, Antigravity, Codex App, Codex CLI, Cursor, Devin CLI, Factory Droid, Gemini CLI, GitHub Copilot CLI, Grok Build CLI, Kimi Code, Pi, Hermes Agent.
One markdown file. Your agent runs assay when it finishes a page and prints what came back:
assay: checked todo/todo.html, 8 checks, nothing flagged.
One line, every time, whether or not it found anything. It reports and never fixes: the agent hands over what it pressed and what happened, and does not edit code on the strength of it.
Plugins
Claude Code, DeepSeek Harness.
The same skill plus a hook, so the check happens at the end of every turn that touched a page, whether or not the agent thought to run it.
/plugin marketplace add awss1i/assay
/plugin install assay@assay
Benchmarks
A checker nobody has checked is an opinion with a progress bar. Two sets, built differently, both checked in.
Generated Programs
225 programs written to 75 objectives by three harnesses. A person opened every one and drove it before assay saw it. 20 are broken.
Across 225 pages checked by hand, assay found 15 of the 20 real defects and raised 0 false alarms. When it reports a problem it is a real one 15 times out of 15.
Planted Bugs
Ten working programs, and a copy of each with five bugs put in by a different harness and model. Fifty defects known by construction, and the harder set: pages that work and are wrong, not pages that stopped.
assay found 10 of the 50 planted bugs and flagged 0 of the 10 working originals.
Both reproduce with python bench/score.py and python bench/planted/score.py.
No key, no network.
How It Works
It waits until the page stops arriving, watching whether the set of controls is still changing rather than pausing for a fixed time. It measures the surface from the rendered page and never the markup, down to a grid of plain divs, because a pointer cursor is the page saying click this and a handler attached in JavaScript cannot be read any other way. It derives a plan from that and carries all of it out in a fresh tab, measuring painted pixels per canvas, their centroid and mean colour, an exact pixel hash, the visible text, what is in the fields, and a hash over every element's style.
It is deliberately narrow about what counts as a failure. A plan derived from the page cannot know what a control is for, so a button only has to survive being pressed. Demanding that every press change something would fail a working program for having a Clear button on an empty canvas.
What it can judge without knowing the design is whether the program contradicts itself. A surface that took the first stroke has to take the second. A control that does nothing on its first press and something on its second, from the same state, is one press behind. And if nothing on the page responds to anything, the script probably never ran.
The same goes for what a page shows about itself: a counter reading -1 over
an empty list, a total that follows the list up and not down, a Remove that
takes a different row, NaN where a value belongs, two labels pointing at
one control.
It never says a page is broken. It says what it pressed and what happened:
C006 [FAILED] type into Quantity then press +
    → nothing on the page changed at all
A verdict makes you change code. A measurement makes you look first, and sometimes you find the page was right and the check was aimed at the wrong thing. That is the cheaper mistake to make, and it reads the same either way round: a person knows where to start, and an agent gets a precise place to look instead of a whole file to re-read.
It serves the folder and never builds it. The page is served over
loopback rather than opened off the disk, because a file:// origin blocks
every module the page loads. What it will not do is run your build: npm install executes whatever the dependency tree asks for, as whoever typed the
command, and this is a tool for checking code nobody has read. Point it at a
source tree and it says so:
$ assay ./my-vite-app
assay: index.html loads /src/main.jsx, which a browser cannot run. This is a source tree, not a built one.
  Build it first, in your own shell, then check the output:
    npm install && npm run build && assay my-vite-app/dist
  assay will not run that for you: installing dependencies executes their setup scripts, and this is a tool for checking code nobody has read.
Why
A lot of code is written by models now, and "does this actually run?" is mostly still answered by a person opening it and clicking around.
Every existing tool needs something you do not have for a program that was generated ten seconds ago. Playwright and Cypress need tests somebody wrote. Visual regression needs a golden image to compare against. Benchmarks like SWE-bench use the repository's own suite.
So the thing most people reach for instead is another model: paste the code in and ask whether it looks right. That is a reader guessing about code. assay opens the page and drives it, which is the only way to find out that a button does nothing.
| needs tests written | needs a baseline | runs the program | |
|---|---|---|---|
| Playwright / Cypress | yes | no | yes, the parts you wrote |
| Percy / Chromatic | no | yes | it screenshots it |
| ask a model to review it | no | no | no. It reads the source |
| assay | no | no | yes, all of it |
Limits Worth Knowing
- Browser programs. It opens a page. A program with no page is not something it can measure.
- Coverage cannot judge intent. A control that works mechanically and does the wrong thing passes. Criteria are the answer, and you have to write those.
- A game that ends looks like a page that died. When a program finishes and offers no way to start again, it stops responding to anything, and a plan derived from the page cannot tell that apart from a page that broke.
- Built output, not source trees. It will not run your build. Point it at a source tree and it says so and names the command.
- Single-page programs. It checks the page you point it at and does not crawl. A multi-page site means running it per page, and client-side routing is untested.
- Generated pages, not the live web. It is built for programs somebody just generated, not for sites with a login, a cookie banner or live network calls.
- Speed. Most pages take a few seconds to just under a minute. Across the 225 benchmark programs the median is 14 seconds and 220 finish inside a minute. The slowest recorded took about four minutes.
Contributing
Issues and pull requests are welcome. Setup, tests, benchmarks and what a PR needs are in CONTRIBUTING.md.
Licence
MIT.
Similar repos
Contributors
1 commits
Languages
HTML
70.9%
Python
28.9%