
README
CVPR 2024
Research Paper with Code
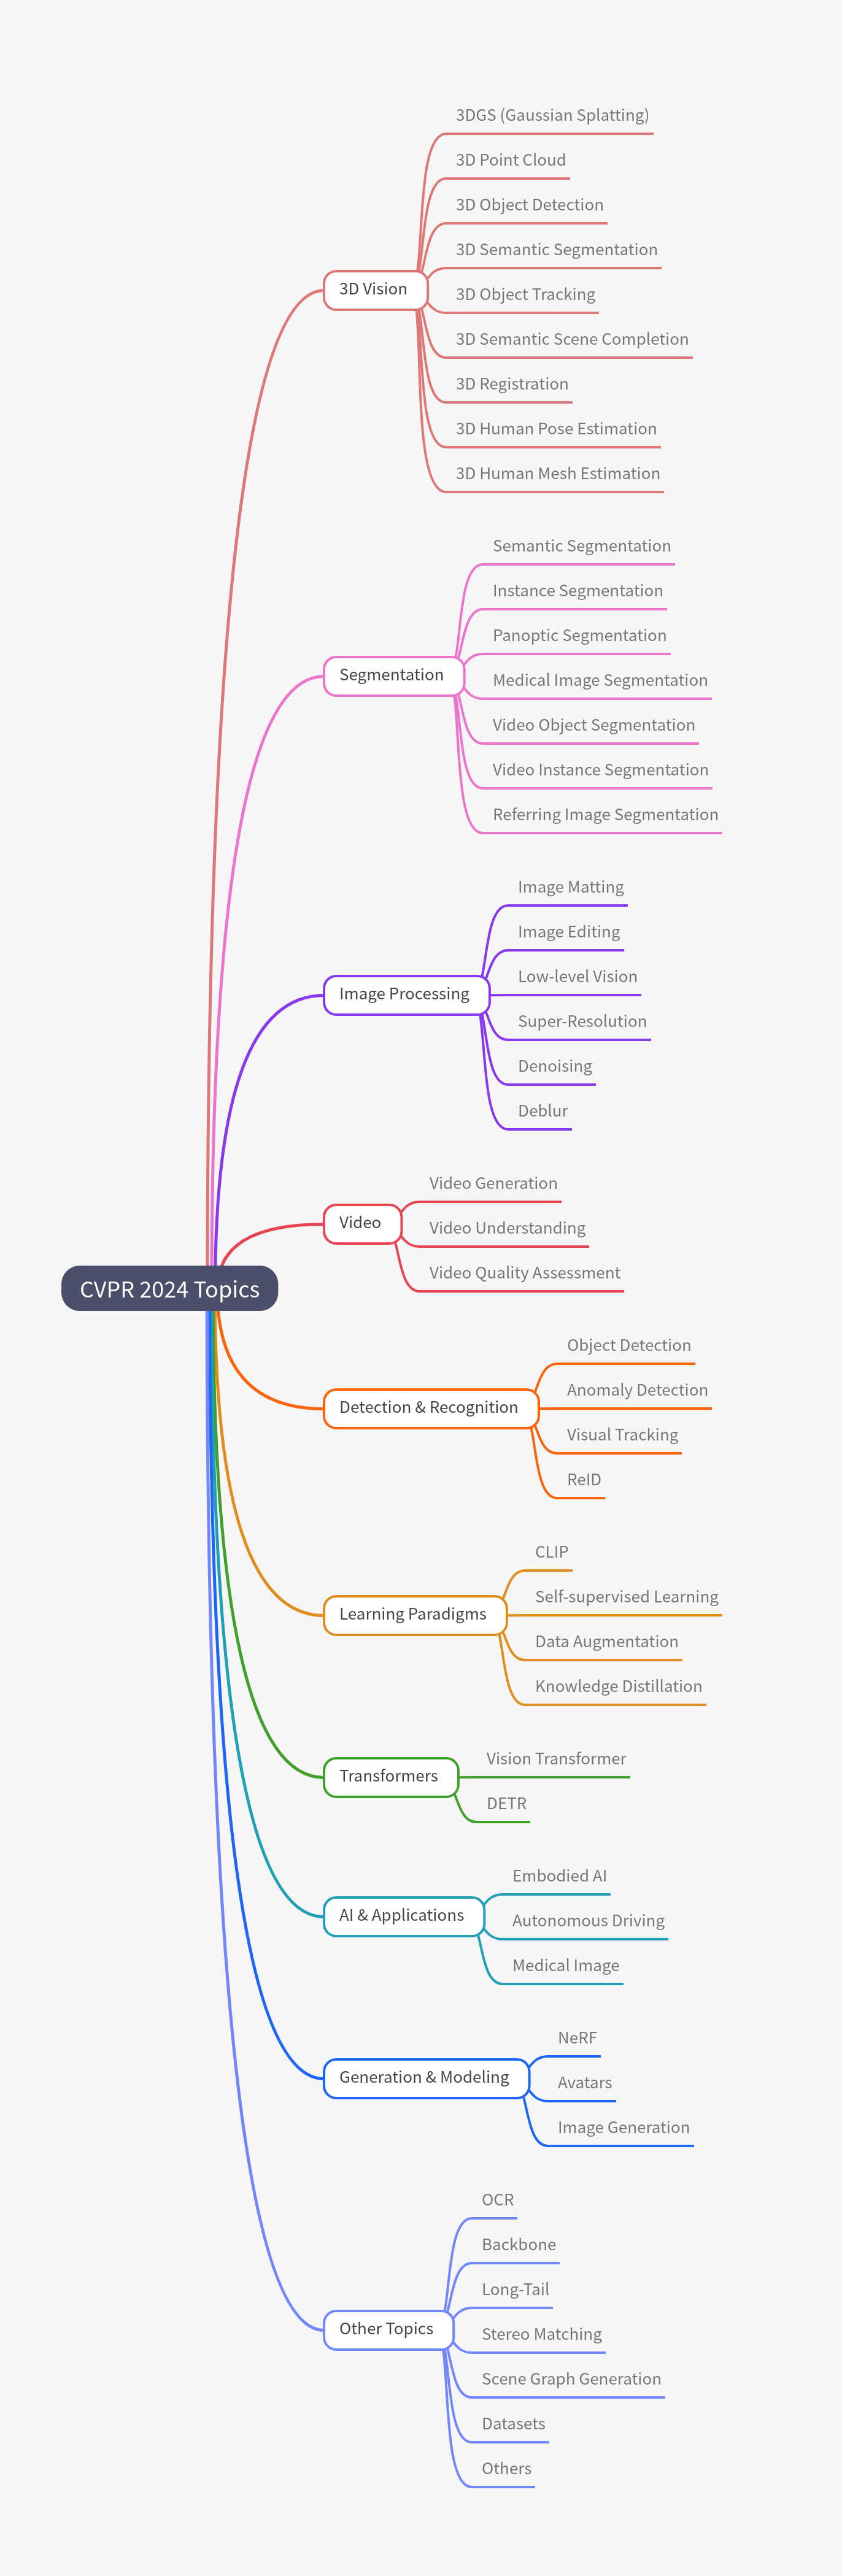
Table of Contents
- 3DGS (Gaussian Splatting)
- Avatars
- Backbone
- CLIP
- Embodied AI
- OCR
- NeRF
- DETR
- ReID
- Long-Tail
- Vision Transformer
- Vision-Language
- Self-supervised Learning
- Data Augmentation
- Object Detection
- Anomaly Detection
- Visual Tracking
- Semantic Segmentation
- Instance Segmentation
- Panoptic Segmentation
- Medical Image
- Medical Image Segmentation
- Video Object Segmentation
- Video Instance Segmentation
- Referring Image Segmentation
- Image Matting
- Image Editing
- Low-level Vision
- Super-Resolution
- Denoising
- Deblur
- Autonomous Driving
- 3D Point Cloud
- 3D Object Detection
- 3D Semantic Segmentation
- 3D Object Tracking
- 3D Semantic Scene Completion
- 3D Registration
- 3D Human Pose Estimation
- 3D Human Mesh Estimation
- Image Generation
- Video Generation
- Video Understanding
- Knowledge Distillation
- Stereo Matching
- Scene Graph Generation
- Video Quality Assessment
- Datasets
- Others
Domain-wise Table
3DGS (Gaussian Splatting)
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 1 | Scaffold-GS: Structured 3D Gaussians for View-Adaptive Rendering | Paper | Code | Homepage |
| 2 | GPS-Gaussian: Generalizable Pixel-wise 3D Gaussian Splatting for Real-time Human Novel View Synthesis | Paper | Code | Homepage |
| 3 | GaussianAvatar: Towards Realistic Human Avatar Modeling from a Single Video via Animatable 3D Gaussians | Paper | Code | N/A |
| 4 | GaussianEditor: Swift and Controllable 3D Editing with Gaussian Splatting | Paper | Code | N/A |
| 5 | Deformable 3D Gaussians for High-Fidelity Monocular Dynamic Scene Reconstruction | Paper | Code | Homepage |
Avatars
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 6 | GaussianAvatar: Towards Realistic Human Avatar Modeling from a Single Video via Animatable 3D Gaussians | Paper | Code | N/A |
| 7 | Real-Time Simulated Avatar from Head-Mounted Sensors | Paper | N/A | Homepage |
Backbone
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 8 | RepViT: Revisiting Mobile CNN From ViT Perspective | Paper | Code | N/A |
| 9 | TransNeXt: Robust Foveal Visual Perception for Vision Transformers | Paper | Code | N/A |
CLIP
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 10 | Alpha-CLIP: A CLIP Model Focusing on Wherever You Want | Paper | Code | N/A |
| 11 | FairCLIP: Harnessing Fairness in Vision-Language Learning | Paper | Code | N/A |
Embodied AI
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 12 | EmbodiedScan: A Holistic Multi-Modal 3D Perception Suite Towards Embodied AI | Paper | Code | Homepage |
| 13 | MP5: A Multi-modal Open-ended Embodied System in Minecraft via Active Perception | Paper | Code | Homepage |
OCR
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 14 | An Empirical Study of Scaling Law for OCR | Paper | Code | N/A |
| 15 | ODM: A Text-Image Further Alignment Pre-training Approach for Scene Text Detection and Spotting | Paper | Code | N/A |
NeRF
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 16 | PIE-NeRF: Physics-based Interactive Elastodynamics with NeRF | Paper | Code | N/A |
DETR
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 17 | DETRs Beat YOLOs on Real-time Object Detection | Paper | Code | N/A |
| 18 | Salience DETR: Enhancing Detection Transformer with Hierarchical Salience Filtering Refinement | Paper | Code | N/A |
ReID
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 19 | Magic Tokens: Select Diverse Tokens for Multi-modal Object Re-Identification | Paper | Code | N/A |
| 20 | Noisy-Correspondence Learning for Text-to-Image Person Re-identification | Paper | Code | N/A |
Long-Tail
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 1 | Delving into the Trajectory Long-tail Distribution for Multi-object Tracking | Paper | Code | N/A |
Vision Transformer
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 2 | TransNeXt: Robust Foveal Visual Perception for Vision Transformers | Paper | Code | N/A |
| 3 | RepViT: Revisiting Mobile CNN From ViT Perspective | Paper | Code | N/A |
Vision-Language
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 4 | PromptKD: Unsupervised Prompt Distillation for Vision-Language Models | Paper | Code | N/A |
| 5 | FairCLIP: Harnessing Fairness in Vision-Language Learning | Paper | Code | N/A |
Self-supervised Learning
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 6 | N/A | N/A | N/A | N/A |
Data Augmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 7 | N/A | N/A | N/A | N/A |
Object Detection
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 8 | DETRs Beat YOLOs on Real-time Object Detection | Paper | Code | N/A |
| 9 | Boosting Object Detection with Zero-Shot Day-Night Domain Adaptation | Paper | Code | N/A |
| 10 | YOLO-World: Real-Time Open-Vocabulary Object Detection | Paper | Code | N/A |
| 11 | Salience DETR: Enhancing Detection Transformer with Hierarchical Salience Filtering Refinement | Paper | Code | N/A |
Anomaly Detection
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 12 | Anomaly Heterogeneity Learning for Open-set Supervised Anomaly Detection | Paper | Code | N/A |
Visual Tracking
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 13 | N/A | N/A | N/A | N/A |
Semantic Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 14 | Stronger, Fewer, & Superior: Harnessing Vision Foundation Models for Domain Generalized Semantic Segmentation | Paper | Code | N/A |
| 15 | SED: A Simple Encoder-Decoder for Open-Vocabulary Semantic Segmentation | Paper | Code | N/A |
Instance Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 16 | N/A | N/A | N/A | N/A |
Panoptic Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 17 | N/A | N/A | N/A | N/A |
Medical Image
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 18 | Feature Re-Embedding: Towards Foundation Model-Level Performance in Computational Pathology | Paper | Code | N/A |
| 19 | VoCo: A Simple-yet-Effective Volume Contrastive Learning Framework for 3D Medical Image Analysis | Paper | Code | N/A |
| 20 | ChAda-ViT : Channel Adaptive Attention for Joint Representation Learning of Heterogeneous Microscopy Images | Paper | Code | N/A |
Medical Image Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 21 | N/A | N/A | N/A | N/A |
Video Object Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 22 | N/A | N/A | N/A | N/A |
Video Instance Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 23 | N/A | N/A | N/A | N/A |
Referring Image Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 24 | N/A | N/A | N/A | N/A |
Image Matting
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 25 | N/A | N/A | N/A | N/A |
Image Editing
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 26 | Edit One for All: Interactive Batch Image Editing | Paper | Code | Homepage |
Low-level Vision
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 27 | Residual Denoising Diffusion Models | Paper | Code | N/A |
| 28 | Boosting Image Restoration via Priors from Pre-trained Models | Paper | N/A | N/A |
Super-Resolution)
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 29 | SeD: Semantic-Aware Discriminator for Image Super-Resolution | Paper | Code | N/A |
| 30 | APISR: Anime Production Inspired Real-World Anime Super-Resolution | Paper | [Code](https://github.com/Kiter### Domain-wise Table |
Denoising
Deblur
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 32 | N/A | N/A | N/A | N/A |
Autonomous Driving
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 33 | UniPAD: A Universal Pre-training Paradigm for Autonomous Driving | Paper | Code | N/A |
| 34 | Cam4DOcc: Benchmark for Camera-Only 4D Occupancy Forecasting in Autonomous Driving Applications | Paper | Code | N/A |
| 35 | Memory-based Adapters for Online 3D Scene Perception | Paper | Code | N/A |
| 36 | Symphonize 3D Semantic Scene Completion with Contextual Instance Queries | Paper | Code | N/A |
| 37 | A Real-world Large-scale Dataset for Roadside Cooperative Perception | Paper | Code | N/A |
| 38 | Adaptive Fusion of Single-View and Multi-View Depth for Autonomous Driving | Paper | Code | N/A |
3D Point Cloud
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 40 | N/A | N/A | N/A | N/A |
3D Object Detection
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 41 | PTT: Point-Trajectory Transformer for Efficient Temporal 3D Object Detection | Paper | Code | N/A |
| 42 | UniMODE: Unified Monocular 3D Object Detection | Paper | N/A | N/A |
3D Semantic Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 43 | N/A | N/A | N/A | N/A |
3D Object Tracking
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 44 | N/A | N/A | N/A | N/A |
3D Semantic Scene Completion
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 45 | Symphonize 3D Semantic Scene Completion with Contextual Instance Queries | Paper | Code | N/A |
3D Registration
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 46 | N/A | N/A | N/A | N/A |
3D Human Pose Estimation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 47 | Hourglass Tokenizer for Efficient Transformer-Based 3D Human Pose Estimation | Paper | Code | N/A |
3D Human Mesh Estimation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 48 | N/A | N/A | N/A | N/A |
Medical Image
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 49 | Feature Re-Embedding: Towards Foundation Model-Level Performance in Computational Pathology | Paper | Code | N/A |
| 50 | VoCo: A Simple-yet-Effective Volume Contrastive Learning Framework for 3D Medical Image Analysis | Paper | Code | N/A |
| 51 | ChAda-ViT : Channel Adaptive Attention for Joint Representation Learning of Heterogeneous Microscopy Images | Paper | Code | N/A |
Image Generation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 52 | InstanceDiffusion: Instance-level Control for Image Generation | Paper | Code | Homepage |
| 53 | ECLIPSE: A Resource-Efficient Text-to-Image Prior for Image Generations | Paper | Code | Homepage |
| 54 | Instruct-Imagen: Image Generation with Multi-modal Instruction | Paper | N/A | N/A |
| 55 | UniGS: Unified Representation for Image Generation and Segmentation | Paper | N/A | N/A |
| 56 | Multi-Instance Generation Controller for Text-to-Image Synthesis | Paper | Code | N/A |
| 57 | SVGDreamer: Text Guided SVG Generation with Diffusion Model | Paper | Code | N/A |
| 58 | InteractDiffusion: Interaction-Control for Text-to-Image Diffusion Model | Paper | Code | N/A |
| 59 | Ranni: Taming Text-to-Image Diffusion for Accurate Prompt Following | Paper | Code | N/A |
Video Generation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 60 | Vlogger: Make Your Dream A Vlog | Paper | Code | N/A |
| 61 | VBench: Comprehensive Benchmark Suite for Video Generative Models | Paper | Code | Homepage |
| 62 | VMC: Video Motion Customization using Temporal Attention Adaption for Text-to-Video Diffusion Models | Paper | Code | Homepage |
Vision Transformer
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 63 | TransNeXt: Robust Foveal Visual Perception for Vision Transformers | Paper | Code | N/A |
| 64 | RepViT: Revisiting Mobile CNN From ViT Perspective | Paper | Code | N/A |
| 65 | A General and Efficient Training for Transformer via Token Expansion | Paper | Code | N/A |
Vision-Language
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 66 | PromptKD: Unsupervised Prompt Distillation for Vision-Language Models | Paper | Code | N/A |
| 67 | FairCLIP: Harnessing Fairness in Vision-Language Learning | Paper | Code | N/A |
Object Detection
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 68 | DETRs Beat YOLOs on Real-time Object Detection | Paper | Code | N/A |
| 69 | Boosting Object Detection with Zero-Shot Day-Night Domain Adaptation | Paper | Code | N/A |
| 70 | YOLO-World: Real-Time Open-Vocabulary Object Detection | Paper | Code | N/A |
| 71 | Salience DETR: Enhancing Detection Transformer with Hierarchical Salience Filtering Refinement | Paper | Code | N/A |
Anomaly Detection
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 72 | Anomaly Heterogeneity Learning for Open-set Supervised Anomaly Detection | Paper | Code | N/A |
Object Tracking
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 73 | Delving into the Trajectory Long-tail Distribution for Multi-object Tracking | Paper | Code | N/A |
Semantic Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 74 | Stronger, Fewer, & Superior: Harnessing Vision Foundation Models for Domain Generalized Semantic Segmentation | Paper | Code | N/A |
| 75 | SED: A Simple Encoder-Decoder for Open-Vocabulary Semantic Segmentation | Paper | Code | N/A |
Medical Image
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 76 | Feature Re-Embedding: Towards Foundation Model-Level Performance in Computational Pathology | Paper | Code | N/A |
| 77 | VoCo: A Simple-yet-Effective Volume Contrastive Learning Framework for 3D Medical Image Analysis | Paper | Code | N/A |
| 78 | ChAda-ViT : Channel Adaptive Attention for Joint Representation Learning of Heterogeneous Microscopy Images | Paper | Code | N/A |
Medical Image Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 76 | N/A | N/A | N/A | N/A |
Autonomous Driving
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 77 | UniPAD: A Universal Pre-training Paradigm for Autonomous Driving | Paper | Code | N/A |
| 78 | Cam4DOcc: Benchmark for Camera-Only 4D Occupancy Forecasting in Autonomous Driving Applications | Paper | Code | N/A |
| 79 | Memory-based Adapters for Online 3D Scene Perception | Paper | Code | N/A |
| 80 | Symphonize 3D Semantic Scene Completion with Contextual Instance Queries | Paper | Code | N/A |
| 81 | A Real-world Large-scale Dataset for Roadside Cooperative Perception | Paper | Code | N/A |
| 82 | Adaptive Fusion of Single-View and Multi-View Depth for Autonomous Driving | Paper | Code | N/A |
| 83 | Traffic Scene Parsing through the TSP6K Dataset | Paper | Code | N/A |
3D Point Cloud
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 84 | N/A | N/A | N/A | N/A |
3D Object Detection
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 85 | PTT: Point-Trajectory Transformer for Efficient Temporal 3D Object Detection | Paper | Code | N/A |
| 86 | UniMODE: Unified Monocular 3D Object Detection | Paper | N/A | N/A |
3D Semantic Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 87 | N/A | N/A | N/A | N/A |
Image Editing
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 88 | Edit One for All: Interactive Batch Image Editing | Paper | Code | Homepage |
Video Editing
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 89 | MaskINT: Video Editing via Interpolative Non-autoregressive Masked Transformers | Paper | N/A | Homepage |
Low-level Vision
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 90 | Residual Denoising Diffusion Models | Paper | Code | N/A |
| 91 | Boosting Image Restoration via Priors from Pre-trained Models | Paper | N/A | N/A |
Super-Resolution
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 92 | SeD: Semantic-Aware Discriminator for Image Super-Resolution | Paper | Code | N/A |
| 93 | APISR: Anime Production Inspired Real-World Anime Super-Resolution | Paper | Code | N/A |
Denoising
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 94 | N/A | N/A | N/A | N/A |
3D Human Pose Estimation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 95 | Hourglass Tokenizer for Efficient Transformer-Based 3D Human Pose Estimation | Paper | Code | N/A |
Image Generation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 96 | InstanceDiffusion: Instance-level Control for Image Generation | Paper | Code | Homepage |
| 97 | ECLIPSE: A Resource-Efficient Text-to-Image Prior for Image Generations | Paper | Code | Homepage |
| 98 | Instruct-Imagen: Image Generation with Multi-modal Instruction | Paper | N/A | N/A |
| 99 | Residual Denoising Diffusion Models | Paper | Code | N/A |
| 100 | UniGS: Unified Representation for Image Generation and Segmentation | Paper | N/A | N/A |
| 101 | Multi-Instance Generation Controller for Text-to-Image Synthesis | Paper | Code | N/A |
| 102 | SVGDreamer: Text Guided SVG Generation with Diffusion Model | Paper | Code | N/A |
| 103 | InteractDiffusion: Interaction-Control for Text-to-Image Diffusion Model | Paper | Code | N/A |
| 104 | Ranni: Taming Text-to-Image Diffusion for Accurate Prompt Following | Paper | Code | N/A |
Video Generation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 105 | Vlogger: Make Your Dream A Vlog | Paper | Code | N/A |
| 106 | VBench: Comprehensive Benchmark Suite for Video Generative Models | Paper | Code | Homepage |
| 107 | VMC: Video Motion Customization using Temporal Attention Adaption for Text-to-Video Diffusion Models | Paper | Code | Homepage |
3D Generation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 108 | CityDreamer: Compositional Generative Model of Unbounded 3D Cities | Paper | Code | Homepage |
| 109 | LucidDreamer: Towards High-Fidelity Text-to-3D Generation via Interval Score Matching | Paper | Code | N/A |
Video Understanding
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 110 | MVBench: A Comprehensive Multi-modal Video Understanding Benchmark | Paper | Code | N/A |
Knowledge Distillation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 111 | Logit Standardization in Knowledge Distillation | Paper | Code | N/A |
| 112 | Efficient Dataset Distillation via Minimax Diffusion | Paper | Code | N/A |
Stereo Matching
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 113 | Neural Markov Random Field for Stereo Matching | Paper | Code | N/A |
Scene Graph Generation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 114 | HiKER-SGG: Hierarchical Knowledge Enhanced Robust Scene Graph Generation | Paper | Code | Homepage |
Video Quality Assessment
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 115 | KVQ: Kaleidoscope Video Quality Assessment for Short-form Videos | Paper | Code | Homepage |
Datasets
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 116 | A Real-world Large-scale Dataset for Roadside Cooperative Perception | Paper | Code | N/A |
| 117 | Traffic Scene Parsing through the TSP6K Dataset | Paper | Code | N/A |
Others
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 118 | Object Recognition as Next Token Prediction | Paper | Code | N/A |
| 119 | ParameterNet: Parameters Are All You Need for Large-scale Visual Pretraining of Mobile Networks | Paper | Code | N/A |
| 120 | Seamless Human Motion Composition with Blended Positional Encodings | Paper | Code | N/A |
| 121 | LL3DA: Visual Interactive Instruction Tuning for Omni-3D Understanding, Reasoning, and Planning | Paper | Code | Homepage |
| 122 | CLOVA: A Closed-LOop Visual Assistant with Tool Usage and Update | Paper | N/A | Homepage |
| 123 | MoMask: Generative Masked Modeling of 3D Human Motions | Paper | Code | N/A |
| 124 | Amodal Ground Truth and Completion in the Wild | Paper | Code | Homepage |
| 125 | Improved Visual Grounding through Self-Consistent Explanations | Paper | Code | N/A |
| 126 | ImageNet-D: Benchmarking Neural Network Robustness on Diffusion Synthetic Object | Paper | Code | Homepage |
| 127 | Learning from Synthetic Human Group Activities | Paper | Code | Homepage |
| 128 | A Cross-Subject Brain Decoding Framework | Paper | Code | Homepage |
| 129 | Multi-Task Dense Prediction via Mixture of Low-Rank Experts | Paper | Code | N/A |
| 130 | Contrastive Mean-Shift Learning for Generalized Category Discovery | Paper | Code | Homepage |
Thank you for Reading
computervision
cvpr
cvpr2024
Similar repos


README
CVPR 2024
Research Paper with Code
Table of Contents
- 3DGS (Gaussian Splatting)
- Avatars
- Backbone
- CLIP
- Embodied AI
- OCR
- NeRF
- DETR
- ReID
- Long-Tail
- Vision Transformer
- Vision-Language
- Self-supervised Learning
- Data Augmentation
- Object Detection
- Anomaly Detection
- Visual Tracking
- Semantic Segmentation
- Instance Segmentation
- Panoptic Segmentation
- Medical Image
- Medical Image Segmentation
- Video Object Segmentation
- Video Instance Segmentation
- Referring Image Segmentation
- Image Matting
- Image Editing
- Low-level Vision
- Super-Resolution
- Denoising
- Deblur
- Autonomous Driving
- 3D Point Cloud
- 3D Object Detection
- 3D Semantic Segmentation
- 3D Object Tracking
- 3D Semantic Scene Completion
- 3D Registration
- 3D Human Pose Estimation
- 3D Human Mesh Estimation
- Image Generation
- Video Generation
- Video Understanding
- Knowledge Distillation
- Stereo Matching
- Scene Graph Generation
- Video Quality Assessment
- Datasets
- Others
Domain-wise Table
3DGS (Gaussian Splatting)
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 1 | Scaffold-GS: Structured 3D Gaussians for View-Adaptive Rendering | Paper | Code | Homepage |
| 2 | GPS-Gaussian: Generalizable Pixel-wise 3D Gaussian Splatting for Real-time Human Novel View Synthesis | Paper | Code | Homepage |
| 3 | GaussianAvatar: Towards Realistic Human Avatar Modeling from a Single Video via Animatable 3D Gaussians | Paper | Code | N/A |
| 4 | GaussianEditor: Swift and Controllable 3D Editing with Gaussian Splatting | Paper | Code | N/A |
| 5 | Deformable 3D Gaussians for High-Fidelity Monocular Dynamic Scene Reconstruction | Paper | Code | Homepage |
Avatars
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 6 | GaussianAvatar: Towards Realistic Human Avatar Modeling from a Single Video via Animatable 3D Gaussians | Paper | Code | N/A |
| 7 | Real-Time Simulated Avatar from Head-Mounted Sensors | Paper | N/A | Homepage |
Backbone
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 8 | RepViT: Revisiting Mobile CNN From ViT Perspective | Paper | Code | N/A |
| 9 | TransNeXt: Robust Foveal Visual Perception for Vision Transformers | Paper | Code | N/A |
CLIP
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 10 | Alpha-CLIP: A CLIP Model Focusing on Wherever You Want | Paper | Code | N/A |
| 11 | FairCLIP: Harnessing Fairness in Vision-Language Learning | Paper | Code | N/A |
Embodied AI
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 12 | EmbodiedScan: A Holistic Multi-Modal 3D Perception Suite Towards Embodied AI | Paper | Code | Homepage |
| 13 | MP5: A Multi-modal Open-ended Embodied System in Minecraft via Active Perception | Paper | Code | Homepage |
OCR
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 14 | An Empirical Study of Scaling Law for OCR | Paper | Code | N/A |
| 15 | ODM: A Text-Image Further Alignment Pre-training Approach for Scene Text Detection and Spotting | Paper | Code | N/A |
NeRF
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 16 | PIE-NeRF: Physics-based Interactive Elastodynamics with NeRF | Paper | Code | N/A |
DETR
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 17 | DETRs Beat YOLOs on Real-time Object Detection | Paper | Code | N/A |
| 18 | Salience DETR: Enhancing Detection Transformer with Hierarchical Salience Filtering Refinement | Paper | Code | N/A |
ReID
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 19 | Magic Tokens: Select Diverse Tokens for Multi-modal Object Re-Identification | Paper | Code | N/A |
| 20 | Noisy-Correspondence Learning for Text-to-Image Person Re-identification | Paper | Code | N/A |
Long-Tail
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 1 | Delving into the Trajectory Long-tail Distribution for Multi-object Tracking | Paper | Code | N/A |
Vision Transformer
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 2 | TransNeXt: Robust Foveal Visual Perception for Vision Transformers | Paper | Code | N/A |
| 3 | RepViT: Revisiting Mobile CNN From ViT Perspective | Paper | Code | N/A |
Vision-Language
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 4 | PromptKD: Unsupervised Prompt Distillation for Vision-Language Models | Paper | Code | N/A |
| 5 | FairCLIP: Harnessing Fairness in Vision-Language Learning | Paper | Code | N/A |
Self-supervised Learning
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 6 | N/A | N/A | N/A | N/A |
Data Augmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 7 | N/A | N/A | N/A | N/A |
Object Detection
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 8 | DETRs Beat YOLOs on Real-time Object Detection | Paper | Code | N/A |
| 9 | Boosting Object Detection with Zero-Shot Day-Night Domain Adaptation | Paper | Code | N/A |
| 10 | YOLO-World: Real-Time Open-Vocabulary Object Detection | Paper | Code | N/A |
| 11 | Salience DETR: Enhancing Detection Transformer with Hierarchical Salience Filtering Refinement | Paper | Code | N/A |
Anomaly Detection
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 12 | Anomaly Heterogeneity Learning for Open-set Supervised Anomaly Detection | Paper | Code | N/A |
Visual Tracking
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 13 | N/A | N/A | N/A | N/A |
Semantic Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 14 | Stronger, Fewer, & Superior: Harnessing Vision Foundation Models for Domain Generalized Semantic Segmentation | Paper | Code | N/A |
| 15 | SED: A Simple Encoder-Decoder for Open-Vocabulary Semantic Segmentation | Paper | Code | N/A |
Instance Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 16 | N/A | N/A | N/A | N/A |
Panoptic Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 17 | N/A | N/A | N/A | N/A |
Medical Image
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 18 | Feature Re-Embedding: Towards Foundation Model-Level Performance in Computational Pathology | Paper | Code | N/A |
| 19 | VoCo: A Simple-yet-Effective Volume Contrastive Learning Framework for 3D Medical Image Analysis | Paper | Code | N/A |
| 20 | ChAda-ViT : Channel Adaptive Attention for Joint Representation Learning of Heterogeneous Microscopy Images | Paper | Code | N/A |
Medical Image Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 21 | N/A | N/A | N/A | N/A |
Video Object Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 22 | N/A | N/A | N/A | N/A |
Video Instance Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 23 | N/A | N/A | N/A | N/A |
Referring Image Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 24 | N/A | N/A | N/A | N/A |
Image Matting
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 25 | N/A | N/A | N/A | N/A |
Image Editing
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 26 | Edit One for All: Interactive Batch Image Editing | Paper | Code | Homepage |
Low-level Vision
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 27 | Residual Denoising Diffusion Models | Paper | Code | N/A |
| 28 | Boosting Image Restoration via Priors from Pre-trained Models | Paper | N/A | N/A |
Super-Resolution)
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 29 | SeD: Semantic-Aware Discriminator for Image Super-Resolution | Paper | Code | N/A |
| 30 | APISR: Anime Production Inspired Real-World Anime Super-Resolution | Paper | [Code](https://github.com/Kiter### Domain-wise Table |
Denoising
Deblur
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 32 | N/A | N/A | N/A | N/A |
Autonomous Driving
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 33 | UniPAD: A Universal Pre-training Paradigm for Autonomous Driving | Paper | Code | N/A |
| 34 | Cam4DOcc: Benchmark for Camera-Only 4D Occupancy Forecasting in Autonomous Driving Applications | Paper | Code | N/A |
| 35 | Memory-based Adapters for Online 3D Scene Perception | Paper | Code | N/A |
| 36 | Symphonize 3D Semantic Scene Completion with Contextual Instance Queries | Paper | Code | N/A |
| 37 | A Real-world Large-scale Dataset for Roadside Cooperative Perception | Paper | Code | N/A |
| 38 | Adaptive Fusion of Single-View and Multi-View Depth for Autonomous Driving | Paper | Code | N/A |
3D Point Cloud
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 40 | N/A | N/A | N/A | N/A |
3D Object Detection
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 41 | PTT: Point-Trajectory Transformer for Efficient Temporal 3D Object Detection | Paper | Code | N/A |
| 42 | UniMODE: Unified Monocular 3D Object Detection | Paper | N/A | N/A |
3D Semantic Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 43 | N/A | N/A | N/A | N/A |
3D Object Tracking
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 44 | N/A | N/A | N/A | N/A |
3D Semantic Scene Completion
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 45 | Symphonize 3D Semantic Scene Completion with Contextual Instance Queries | Paper | Code | N/A |
3D Registration
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 46 | N/A | N/A | N/A | N/A |
3D Human Pose Estimation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 47 | Hourglass Tokenizer for Efficient Transformer-Based 3D Human Pose Estimation | Paper | Code | N/A |
3D Human Mesh Estimation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 48 | N/A | N/A | N/A | N/A |
Medical Image
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 49 | Feature Re-Embedding: Towards Foundation Model-Level Performance in Computational Pathology | Paper | Code | N/A |
| 50 | VoCo: A Simple-yet-Effective Volume Contrastive Learning Framework for 3D Medical Image Analysis | Paper | Code | N/A |
| 51 | ChAda-ViT : Channel Adaptive Attention for Joint Representation Learning of Heterogeneous Microscopy Images | Paper | Code | N/A |
Image Generation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 52 | InstanceDiffusion: Instance-level Control for Image Generation | Paper | Code | Homepage |
| 53 | ECLIPSE: A Resource-Efficient Text-to-Image Prior for Image Generations | Paper | Code | Homepage |
| 54 | Instruct-Imagen: Image Generation with Multi-modal Instruction | Paper | N/A | N/A |
| 55 | UniGS: Unified Representation for Image Generation and Segmentation | Paper | N/A | N/A |
| 56 | Multi-Instance Generation Controller for Text-to-Image Synthesis | Paper | Code | N/A |
| 57 | SVGDreamer: Text Guided SVG Generation with Diffusion Model | Paper | Code | N/A |
| 58 | InteractDiffusion: Interaction-Control for Text-to-Image Diffusion Model | Paper | Code | N/A |
| 59 | Ranni: Taming Text-to-Image Diffusion for Accurate Prompt Following | Paper | Code | N/A |
Video Generation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 60 | Vlogger: Make Your Dream A Vlog | Paper | Code | N/A |
| 61 | VBench: Comprehensive Benchmark Suite for Video Generative Models | Paper | Code | Homepage |
| 62 | VMC: Video Motion Customization using Temporal Attention Adaption for Text-to-Video Diffusion Models | Paper | Code | Homepage |
Vision Transformer
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 63 | TransNeXt: Robust Foveal Visual Perception for Vision Transformers | Paper | Code | N/A |
| 64 | RepViT: Revisiting Mobile CNN From ViT Perspective | Paper | Code | N/A |
| 65 | A General and Efficient Training for Transformer via Token Expansion | Paper | Code | N/A |
Vision-Language
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 66 | PromptKD: Unsupervised Prompt Distillation for Vision-Language Models | Paper | Code | N/A |
| 67 | FairCLIP: Harnessing Fairness in Vision-Language Learning | Paper | Code | N/A |
Object Detection
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 68 | DETRs Beat YOLOs on Real-time Object Detection | Paper | Code | N/A |
| 69 | Boosting Object Detection with Zero-Shot Day-Night Domain Adaptation | Paper | Code | N/A |
| 70 | YOLO-World: Real-Time Open-Vocabulary Object Detection | Paper | Code | N/A |
| 71 | Salience DETR: Enhancing Detection Transformer with Hierarchical Salience Filtering Refinement | Paper | Code | N/A |
Anomaly Detection
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 72 | Anomaly Heterogeneity Learning for Open-set Supervised Anomaly Detection | Paper | Code | N/A |
Object Tracking
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 73 | Delving into the Trajectory Long-tail Distribution for Multi-object Tracking | Paper | Code | N/A |
Semantic Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 74 | Stronger, Fewer, & Superior: Harnessing Vision Foundation Models for Domain Generalized Semantic Segmentation | Paper | Code | N/A |
| 75 | SED: A Simple Encoder-Decoder for Open-Vocabulary Semantic Segmentation | Paper | Code | N/A |
Medical Image
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 76 | Feature Re-Embedding: Towards Foundation Model-Level Performance in Computational Pathology | Paper | Code | N/A |
| 77 | VoCo: A Simple-yet-Effective Volume Contrastive Learning Framework for 3D Medical Image Analysis | Paper | Code | N/A |
| 78 | ChAda-ViT : Channel Adaptive Attention for Joint Representation Learning of Heterogeneous Microscopy Images | Paper | Code | N/A |
Medical Image Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 76 | N/A | N/A | N/A | N/A |
Autonomous Driving
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 77 | UniPAD: A Universal Pre-training Paradigm for Autonomous Driving | Paper | Code | N/A |
| 78 | Cam4DOcc: Benchmark for Camera-Only 4D Occupancy Forecasting in Autonomous Driving Applications | Paper | Code | N/A |
| 79 | Memory-based Adapters for Online 3D Scene Perception | Paper | Code | N/A |
| 80 | Symphonize 3D Semantic Scene Completion with Contextual Instance Queries | Paper | Code | N/A |
| 81 | A Real-world Large-scale Dataset for Roadside Cooperative Perception | Paper | Code | N/A |
| 82 | Adaptive Fusion of Single-View and Multi-View Depth for Autonomous Driving | Paper | Code | N/A |
| 83 | Traffic Scene Parsing through the TSP6K Dataset | Paper | Code | N/A |
3D Point Cloud
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 84 | N/A | N/A | N/A | N/A |
3D Object Detection
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 85 | PTT: Point-Trajectory Transformer for Efficient Temporal 3D Object Detection | Paper | Code | N/A |
| 86 | UniMODE: Unified Monocular 3D Object Detection | Paper | N/A | N/A |
3D Semantic Segmentation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 87 | N/A | N/A | N/A | N/A |
Image Editing
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 88 | Edit One for All: Interactive Batch Image Editing | Paper | Code | Homepage |
Video Editing
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 89 | MaskINT: Video Editing via Interpolative Non-autoregressive Masked Transformers | Paper | N/A | Homepage |
Low-level Vision
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 90 | Residual Denoising Diffusion Models | Paper | Code | N/A |
| 91 | Boosting Image Restoration via Priors from Pre-trained Models | Paper | N/A | N/A |
Super-Resolution
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 92 | SeD: Semantic-Aware Discriminator for Image Super-Resolution | Paper | Code | N/A |
| 93 | APISR: Anime Production Inspired Real-World Anime Super-Resolution | Paper | Code | N/A |
Denoising
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 94 | N/A | N/A | N/A | N/A |
3D Human Pose Estimation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 95 | Hourglass Tokenizer for Efficient Transformer-Based 3D Human Pose Estimation | Paper | Code | N/A |
Image Generation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 96 | InstanceDiffusion: Instance-level Control for Image Generation | Paper | Code | Homepage |
| 97 | ECLIPSE: A Resource-Efficient Text-to-Image Prior for Image Generations | Paper | Code | Homepage |
| 98 | Instruct-Imagen: Image Generation with Multi-modal Instruction | Paper | N/A | N/A |
| 99 | Residual Denoising Diffusion Models | Paper | Code | N/A |
| 100 | UniGS: Unified Representation for Image Generation and Segmentation | Paper | N/A | N/A |
| 101 | Multi-Instance Generation Controller for Text-to-Image Synthesis | Paper | Code | N/A |
| 102 | SVGDreamer: Text Guided SVG Generation with Diffusion Model | Paper | Code | N/A |
| 103 | InteractDiffusion: Interaction-Control for Text-to-Image Diffusion Model | Paper | Code | N/A |
| 104 | Ranni: Taming Text-to-Image Diffusion for Accurate Prompt Following | Paper | Code | N/A |
Video Generation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 105 | Vlogger: Make Your Dream A Vlog | Paper | Code | N/A |
| 106 | VBench: Comprehensive Benchmark Suite for Video Generative Models | Paper | Code | Homepage |
| 107 | VMC: Video Motion Customization using Temporal Attention Adaption for Text-to-Video Diffusion Models | Paper | Code | Homepage |
3D Generation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 108 | CityDreamer: Compositional Generative Model of Unbounded 3D Cities | Paper | Code | Homepage |
| 109 | LucidDreamer: Towards High-Fidelity Text-to-3D Generation via Interval Score Matching | Paper | Code | N/A |
Video Understanding
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 110 | MVBench: A Comprehensive Multi-modal Video Understanding Benchmark | Paper | Code | N/A |
Knowledge Distillation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 111 | Logit Standardization in Knowledge Distillation | Paper | Code | N/A |
| 112 | Efficient Dataset Distillation via Minimax Diffusion | Paper | Code | N/A |
Stereo Matching
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 113 | Neural Markov Random Field for Stereo Matching | Paper | Code | N/A |
Scene Graph Generation
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 114 | HiKER-SGG: Hierarchical Knowledge Enhanced Robust Scene Graph Generation | Paper | Code | Homepage |
Video Quality Assessment
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 115 | KVQ: Kaleidoscope Video Quality Assessment for Short-form Videos | Paper | Code | Homepage |
Datasets
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 116 | A Real-world Large-scale Dataset for Roadside Cooperative Perception | Paper | Code | N/A |
| 117 | Traffic Scene Parsing through the TSP6K Dataset | Paper | Code | N/A |
Others
| Index | Paper Title | Paper Link | Code | Official Repo |
|---|---|---|---|---|
| 118 | Object Recognition as Next Token Prediction | Paper | Code | N/A |
| 119 | ParameterNet: Parameters Are All You Need for Large-scale Visual Pretraining of Mobile Networks | Paper | Code | N/A |
| 120 | Seamless Human Motion Composition with Blended Positional Encodings | Paper | Code | N/A |
| 121 | LL3DA: Visual Interactive Instruction Tuning for Omni-3D Understanding, Reasoning, and Planning | Paper | Code | Homepage |
| 122 | CLOVA: A Closed-LOop Visual Assistant with Tool Usage and Update | Paper | N/A | Homepage |
| 123 | MoMask: Generative Masked Modeling of 3D Human Motions | Paper | Code | N/A |
| 124 | Amodal Ground Truth and Completion in the Wild | Paper | Code | Homepage |
| 125 | Improved Visual Grounding through Self-Consistent Explanations | Paper | Code | N/A |
| 126 | ImageNet-D: Benchmarking Neural Network Robustness on Diffusion Synthetic Object | Paper | Code | Homepage |
| 127 | Learning from Synthetic Human Group Activities | Paper | Code | Homepage |
| 128 | A Cross-Subject Brain Decoding Framework | Paper | Code | Homepage |
| 129 | Multi-Task Dense Prediction via Mixture of Low-Rank Experts | Paper | Code | N/A |
| 130 | Contrastive Mean-Shift Learning for Generalized Category Discovery | Paper | Code | Homepage |
Thank you for Reading
computervision
cvpr
cvpr2024