

Ruixiang Zhang*, Richard He Bai*, Huangjie Zheng*, Navdeep Jaitly, Ronan Collobert, Yizhe Zhang*
*Equal contribution
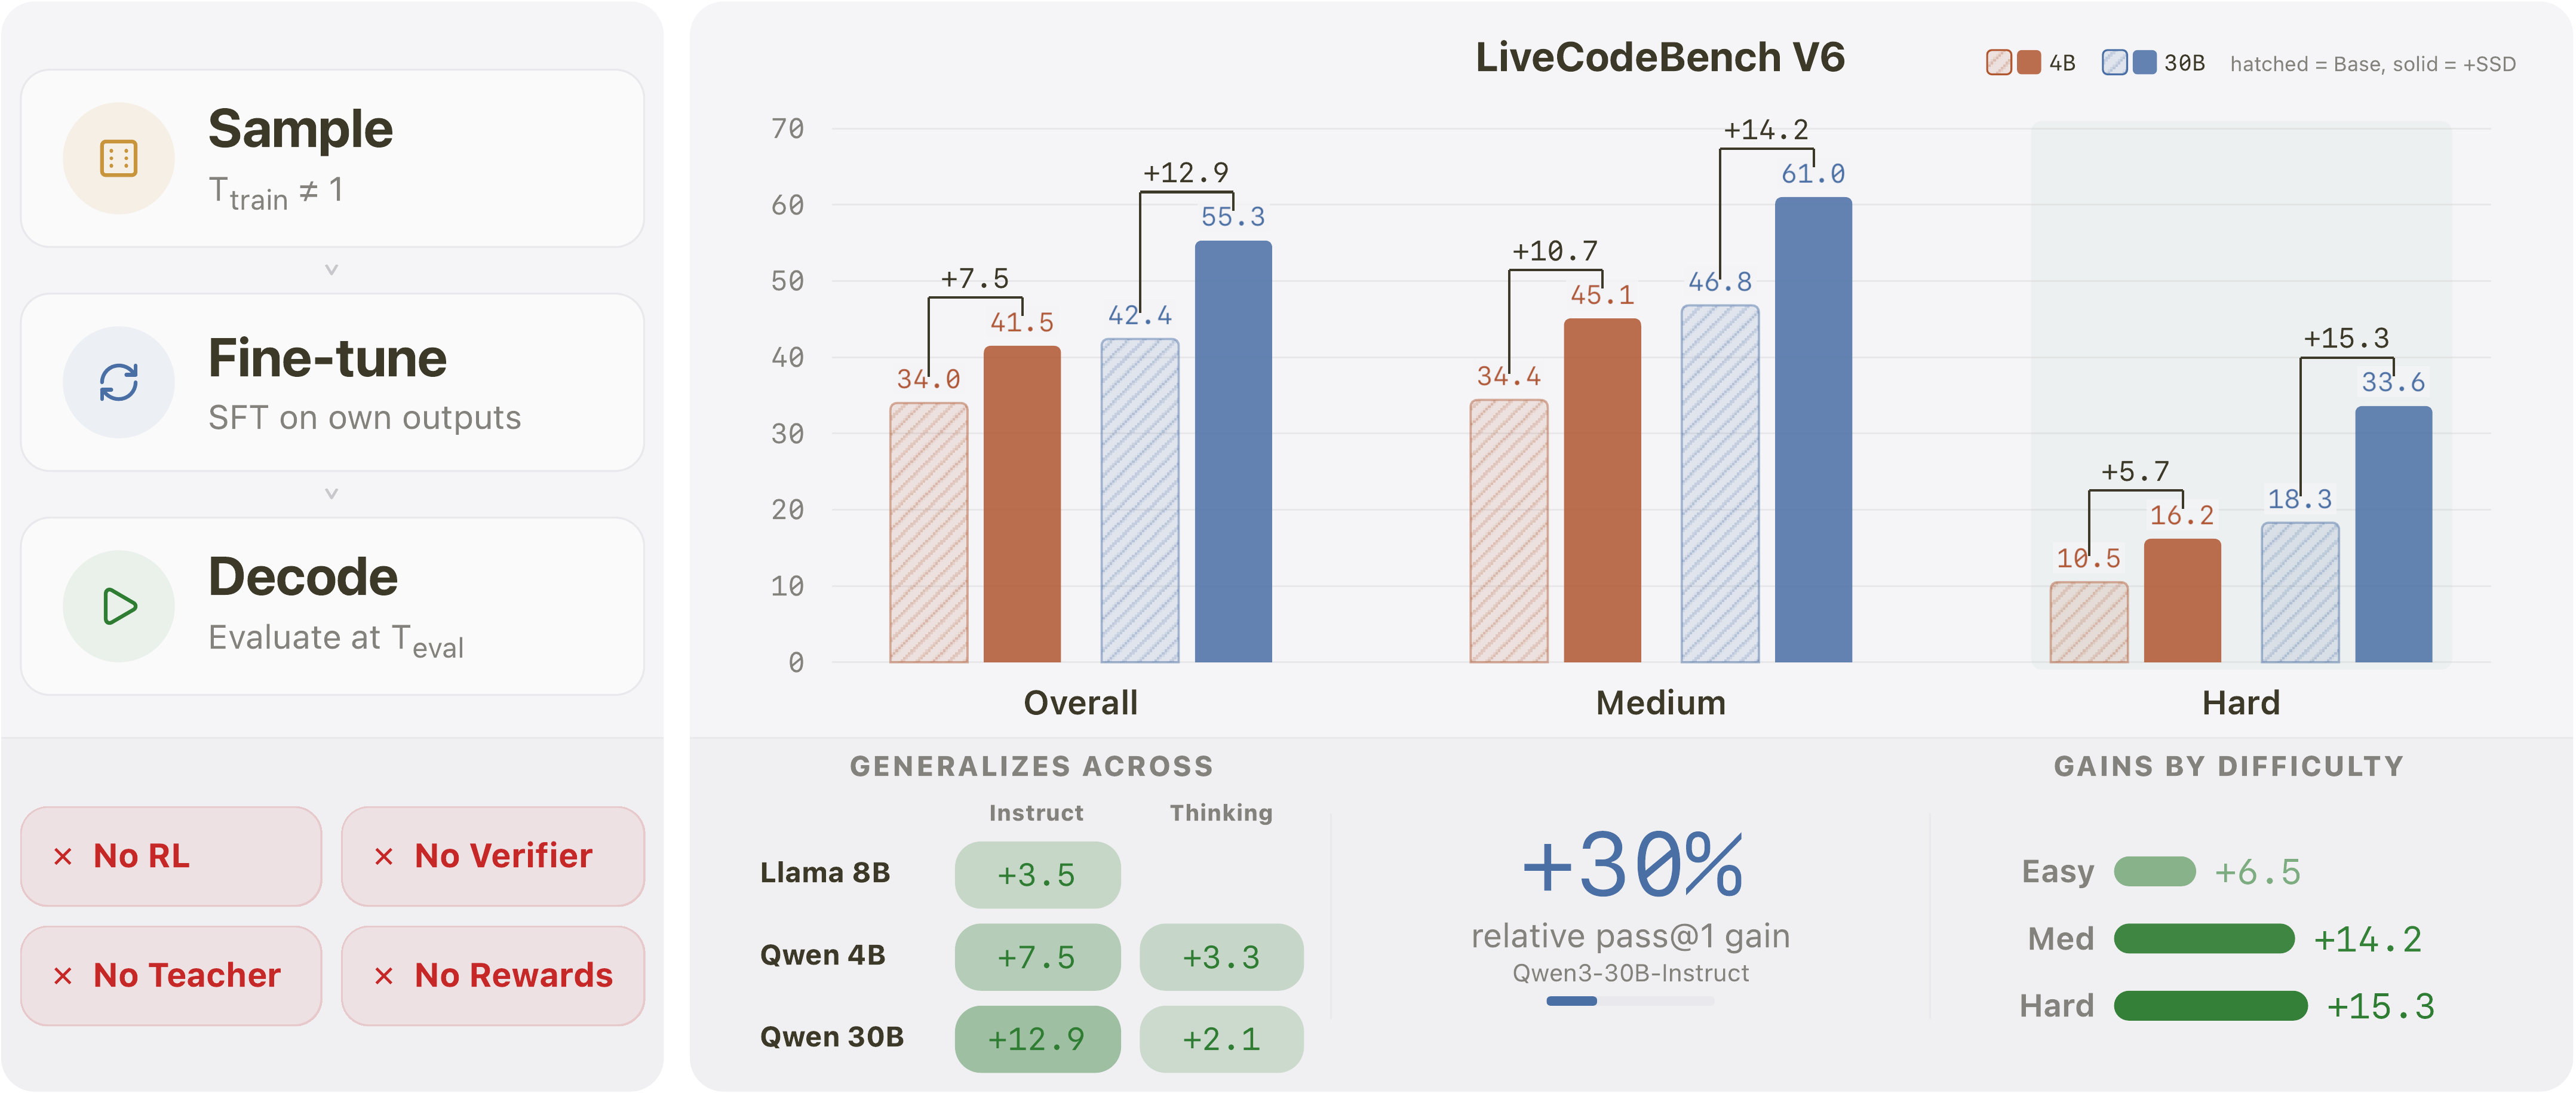
This repository reproduces the method from the paper:
Embarrassingly Simple Self-Distillation Improves Code Generation
The approach consists of three simple steps:
No rewards · No verifier · No teacher · No RL
For full details, see the paper.
git clone https://github.com/apple/ml-ssd.git
cd ml-ssd
uv sync --group evaluation          # for evaluation only
uv sync --group data-generation     # for data generation only
uv sync --group evaluation --group data-generation  # for both
source .venv/bin/activate
python evaluation/eval.py \
    --model <hf_model_name> \
    --tensor_parallel_size 4 \
    --max_tokens 65536 \
    --n_repeat 10 \
    --sampling_params "temperature=0.9,top_p=0.8,top_k=20" \
    --output_path ./results/
Note: The sampling parameters above are illustrative. Please refer to each model's HuggingFace model card for the recommended sampling parameters.
source .venv/bin/activate
python data_generation/generate.py --config data_generation/config.yaml
This runs the full pipeline end-to-end: loads the dataset, generates solutions with vLLM, and post-processes into chat-template JSONL for SFT training. Edit data_generation/config.yaml to change the model, dataset, sampling temperature, etc.
| Model | HuggingFace |
|---|---|
| SSD-4B-Instruct | apple/SimpleSD-4B-instruct |
| SSD-4B-Thinking | apple/SimpleSD-4B-thinking |
| SSD-30B-A3B-Instruct | apple/SimpleSD-30b-a3b-instruct |
├── data_generation/
│   ├── generate.py              # End-to-end data generation pipeline
│   ├── config.yaml              # Generation & post-processing config
│   └── templates/               # Prompt templates
├── evaluation/
│   ├── eval.py                  # CLI entry point
│   ├── benchmark.py             # LiveCodeBench v6 implementation
│   └── livecodebench_utils.py   # Code execution utilities
├── figures/
│   └── fig_teaser.png
├── pyproject.toml
└── README.md
@misc{zhang2026embarrassinglysimpleselfdistillationimproves,
      title={Embarrassingly Simple Self-Distillation Improves Code Generation},
      author={Ruixiang Zhang and Richard He Bai and Huangjie Zheng and Navdeep Jaitly and Ronan Collobert and Yizhe Zhang},
      year={2026},
      eprint={2604.01193},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2604.01193},
}
(top 24 of 25)
4,397 followers · starred Apr 2026
427 followers · starred Jun 2026
587 followers · starred Apr 2026
137 followers · starred Apr 2026
Ruixiang Zhang*, Richard He Bai*, Huangjie Zheng*, Navdeep Jaitly, Ronan Collobert, Yizhe Zhang*
*Equal contribution
This repository reproduces the method from the paper:
Embarrassingly Simple Self-Distillation Improves Code Generation
The approach consists of three simple steps:
No rewards · No verifier · No teacher · No RL
For full details, see the paper.
git clone https://github.com/apple/ml-ssd.git
cd ml-ssd
uv sync --group evaluation          # for evaluation only
uv sync --group data-generation     # for data generation only
uv sync --group evaluation --group data-generation  # for both
source .venv/bin/activate
python evaluation/eval.py \
    --model <hf_model_name> \
    --tensor_parallel_size 4 \
    --max_tokens 65536 \
    --n_repeat 10 \
    --sampling_params "temperature=0.9,top_p=0.8,top_k=20" \
    --output_path ./results/
Note: The sampling parameters above are illustrative. Please refer to each model's HuggingFace model card for the recommended sampling parameters.
source .venv/bin/activate
python data_generation/generate.py --config data_generation/config.yaml
This runs the full pipeline end-to-end: loads the dataset, generates solutions with vLLM, and post-processes into chat-template JSONL for SFT training. Edit data_generation/config.yaml to change the model, dataset, sampling temperature, etc.
| Model | HuggingFace |
|---|---|
| SSD-4B-Instruct | apple/SimpleSD-4B-instruct |
| SSD-4B-Thinking | apple/SimpleSD-4B-thinking |
| SSD-30B-A3B-Instruct | apple/SimpleSD-30b-a3b-instruct |
├── data_generation/
│   ├── generate.py              # End-to-end data generation pipeline
│   ├── config.yaml              # Generation & post-processing config
│   └── templates/               # Prompt templates
├── evaluation/
│   ├── eval.py                  # CLI entry point
│   ├── benchmark.py             # LiveCodeBench v6 implementation
│   └── livecodebench_utils.py   # Code execution utilities
├── figures/
│   └── fig_teaser.png
├── pyproject.toml
└── README.md
@misc{zhang2026embarrassinglysimpleselfdistillationimproves,
      title={Embarrassingly Simple Self-Distillation Improves Code Generation},
      author={Ruixiang Zhang and Richard He Bai and Huangjie Zheng and Navdeep Jaitly and Ronan Collobert and Yizhe Zhang},
      year={2026},
      eprint={2604.01193},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2604.01193},
}
(top 24 of 25)
4,397 followers · starred Apr 2026
427 followers · starred Jun 2026
587 followers · starred Apr 2026
137 followers · starred Apr 2026