
Code for paper: Nullu: Mitigating Object Hallucinations in Large Vision-Language Models via HalluSpace Projection
OpenEdge ABL
64
13 commits
updated Mar 13, 2025
README
Nullu: Mitigating Object Hallucinations in Large Vision-Language Models via HalluSpace Projection
Le Yang*, Ziwei Zheng*, Boxu Chen, Zhengyu Zhao, Chenhao Lin, Chao Shen. *equal contribution.
XJTU AISEC Team.
This repository contains the official code of Nullu, a method for mitigating object hallucinations in LVLMs via HalluSpace Projection.


Overview
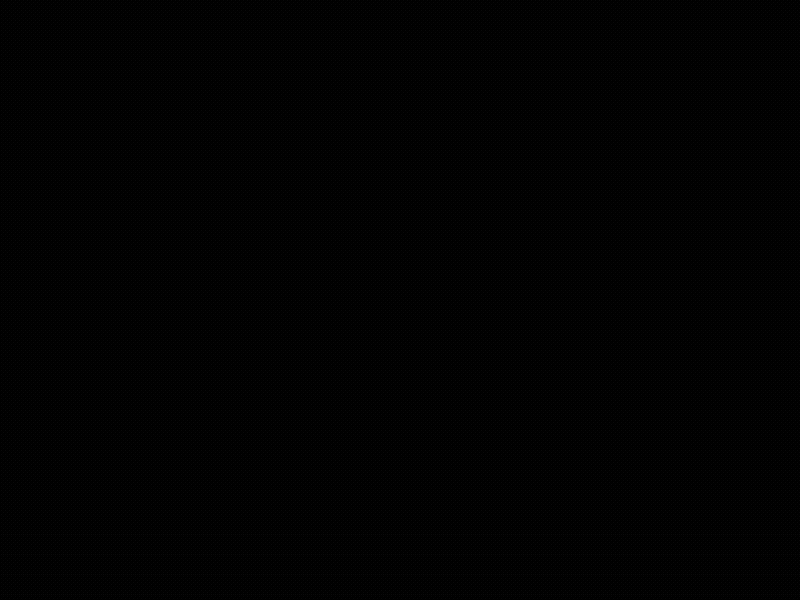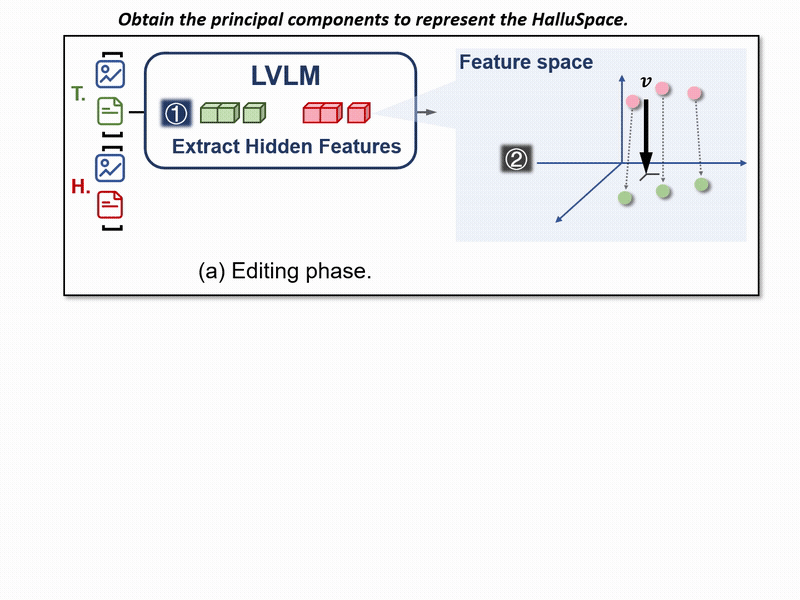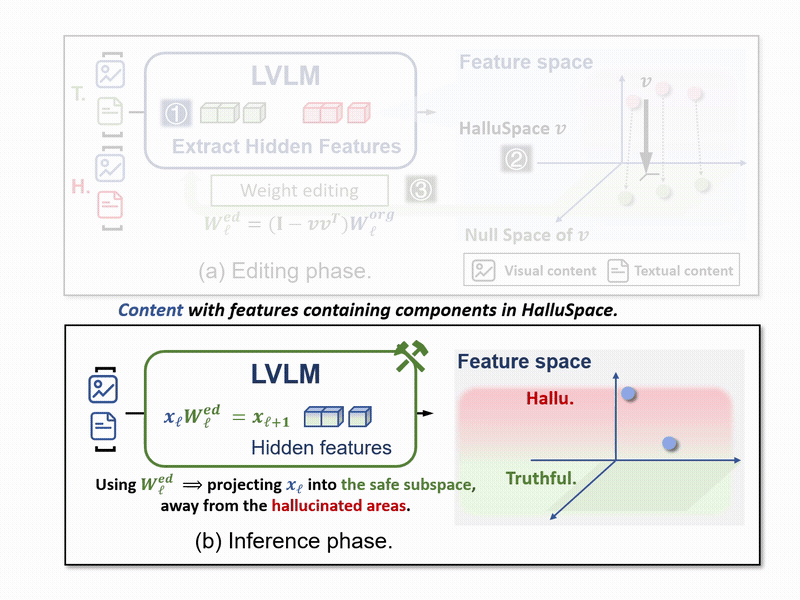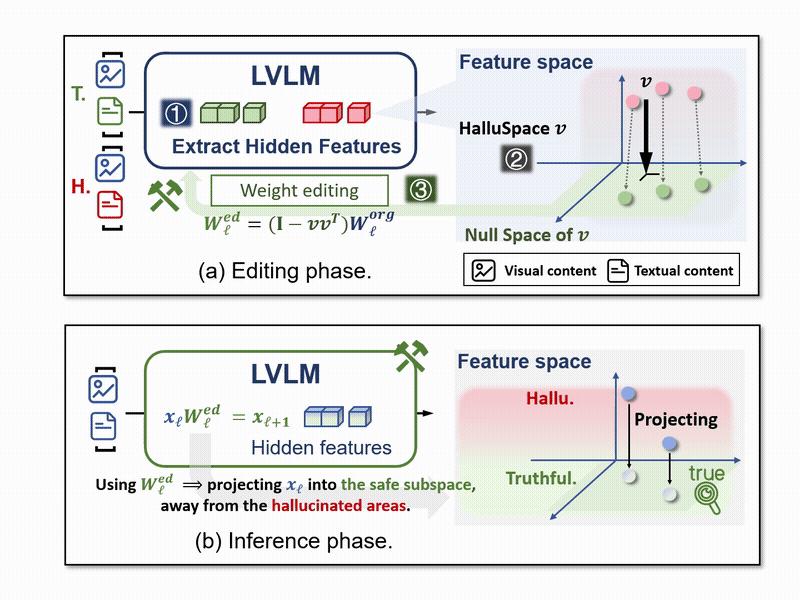
- We introduce a novel method named Nullu, which can effectively mitigate object hallucinations (OH) with no extra inference cost.
- Nullu edit weight by extracting HalluSpaces and orthogonalizing the model weights based on representation learning:
- HalluSpace Extraction: Nullu first calculates the difference matrix of hidden features for the paired truthful and hallucinated samples and then conducts the Singular Value Decomposition (SVD), to find the main directions of the difference as the HalluSpace.
- Weight Projection: Then Nullu projects the original MLP’s weights to the null space of the HalluSpace. This procedure will be repeated for a series of layers, ${\ell}$, in the LLM of an LVLM.
Getting Started
:pushpin: Installation
Git clone our repository, creating a python environment and activate it via the following command.
    git clone https://github.com/Ziwei-Zheng/Nullu.git
    cd Nullu
    conda env create -f environment.yml
    conda activate nullu
Model Setup
Prepare the following model checkpoints:
- LLaVA-1.5 7B model: Download weights from liuhaotian/llava-v1.5-7b.
- MiniGPT-4 (LLaMA-2 Chat 7B): Download pretrained weights from this link. Set the path in
minigpt4/minigpt4_llama2_eval.yaml(Line 8). - MiniGPT-4 corresponding LLM: Download weights from meta-llama/Llama-2-7b-chat-hf.
- mPLUG-Owl2 model: Download from MAGAer13/mplug-owl2-llama2-7b.
To use a specific model, ensure the --model_path argument is set correctly. For LLaVA-1.5 and mPLUG-Owl2, use the path to the model weights, while for MiniGPT-4, set the path to the corresponding LLM weights.
Before model editing, you need to to install a specific version of transformers:
- For LLaVA-1.5 and MiniGPT4:
pip install transformers==4.37.2 - For mPLUG-Owl2:
pip install transformers==4.31.0
Dataset
Model editing and evaluation require the MSCOCO 2014 dataset. Please download here.
:hammer_and_wrench: Model editing
1. Extract Model Activations from paired samples
To extract activations for hallucinated and truthful samples, we use paired samples from LURE/dataset_train, stored in data/LURE.
- Check the value of the key
lurein thedataset_rootswithindataset/__init__.py. This specifies the path of the COCO 2014 dataset. - Run the following command under the root directory:
python scripts/model_run.py --model_name ['LLaVA-7B', 'MiniGPT4', 'mPLUG_Owl2'] --model_path /path/to/raw_model/
The corresponding activations.pkl file will be saved in ./output/{args.model_name}/.
2. Model Editing with Activations
Use the activations stored in emb_path to edit the model. Key parameters include:
- top_k_rank: Specifies the number of singular vectors to select for the editing process. Only the first
top_k_ranksingular vectors are used. - layer_range: Defines the range of layers to apply the editing to, defined as
np.arange(lowest_layer, highest_layer).
Run the following command under the root directory:
python scripts/model_edit.py --model_name ['LLaVA-7B', 'MiniGPT4', 'mPLUG_Owl2'] --model_path [PATH_TO_RAW_MODEL_WEIGHTS] --emb_path /path/to/activation.pkl --top_k_ranks 4 --lowest_layer 16 --highest_layer 32
The edited model weights will be saved in ./output/edited_model/.
:bookmark_tabs: Evalutaion
CHAIR, POPE, OPOPE
Update dataset paths in dataset_roots located in dataset/__init__.py as needed.
Following Evaluating Object Hallucination in Large Vision-Language Models, we used "Please describe this image in detail." as the prompt to query LVLM for captions of the 500 images randomly sampled from COCO 2014 Val datast.
-
CHAIR
Check the path of
data_pathandcaption_file_pathinscripts/calculate_chair.py. Then run the following command under the root directory:python scripts/model_response.py --model_name ['LLaVA-7B', 'MiniGPT4', 'mPLUG_Owl2'] --model_path [PATH_TO_MODEL_WEIGHTS] --dataset chair --num_samples 500 --num_beams 3 --max_length 64The results will be saved in
eval/chair/{os.path.basename(args.model_path)}.
The POPE files built following POPE: Polling-based Object Probing Evaluation for Object Hallucination is stored in data/POPE.
-
POPE
Check the path of
testfilesindataset/POPE.py. Then run the following command under the root directory:python scripts/model_response.py --model_name ['LLaVA-7B', 'MiniGPT4', 'mPLUG_Owl2'] --model_path [PATH_TO_MODEL_WEIGHTS] --dataset pope --num_samples 500 --num_beams 3 --max_length 64The results will be saved in
eval/opope/{os.path.basename(args.model_path)}. -
OPOPE
Check the paths of
testfileindataset/OPOPE.pyandtestfilesinscripts/calculate_opope.py. Then run the following command under the root directory:python scripts/model_response.py --model_name ['LLaVA-7B', 'MiniGPT4', 'mPLUG_Owl2'] --model_path [PATH_TO_MODEL_WEIGHTS] --dataset opope --num_samples 500 --num_beams 3 --max_length 64The results will be saved in
eval/opope/{os.path.basename(args.model_path)}.
MME
Download MME_Benchmark_release_version.zip and eval_tool.zip. Then run the following command under the root directory:
python scripts/mme_response.py --reference_dir eval_tool/Your_Results --base_dir MME_Benchmark_release_version
The response file will be stored in eval/mme/{os.path.basename(args.model_path)}. To calculate the score, run:
python scripts/mme_calculation --results_dir [PATH_TO_RESPONSE_FILE]
LLaVA-Bench
Download LLaVA-Bench (In-the-Wild) and run the following command under the root directory:
python scripts/llavabench_vqa.py --model_name ['LLaVA-7B', 'MiniGPT4', 'mPLUG_Owl2'] --model_path --image-folder liuhaotian/llava-bench-in-the-wild/images --question_file liuhaotian/llava-bench-in-the-wild/questions.jsonl
The response file will be stored in eval/llavabench_answer/{os.path.basename(args.model_path)}. To calculate the score, run:
python scripts/llavabench_gpt_eval.py --raw_answer_path [PATH_TO_RAW_MODEL_RESPONSE] --edit_answer_path [PATH_TO_EDIT_MODEL_RESPONSE] --images_dir [PATH_TO_IMAGES] --api_key [API_KEY] --base_url [URL]
GPT-4V evaluated responses will be saved under eval/llavabench/results/ as .log file.
Experiments
- Nullu mitigates the object hallucination issue across different LVLM families.
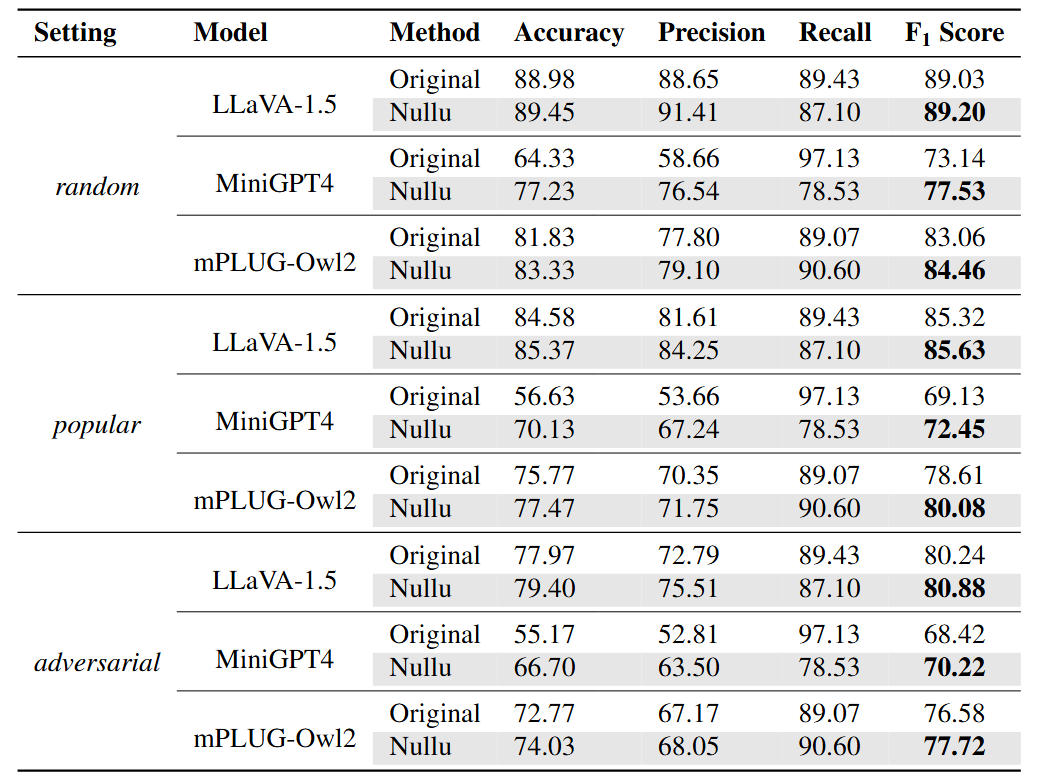
table 12. Results on POPE. Original denotes direct sampling for LVLMs, whereas Nullu refers to edit the model with the proposed method.
- Results in general LVLM benchmarks, highlighting its wide-ranging applicability.
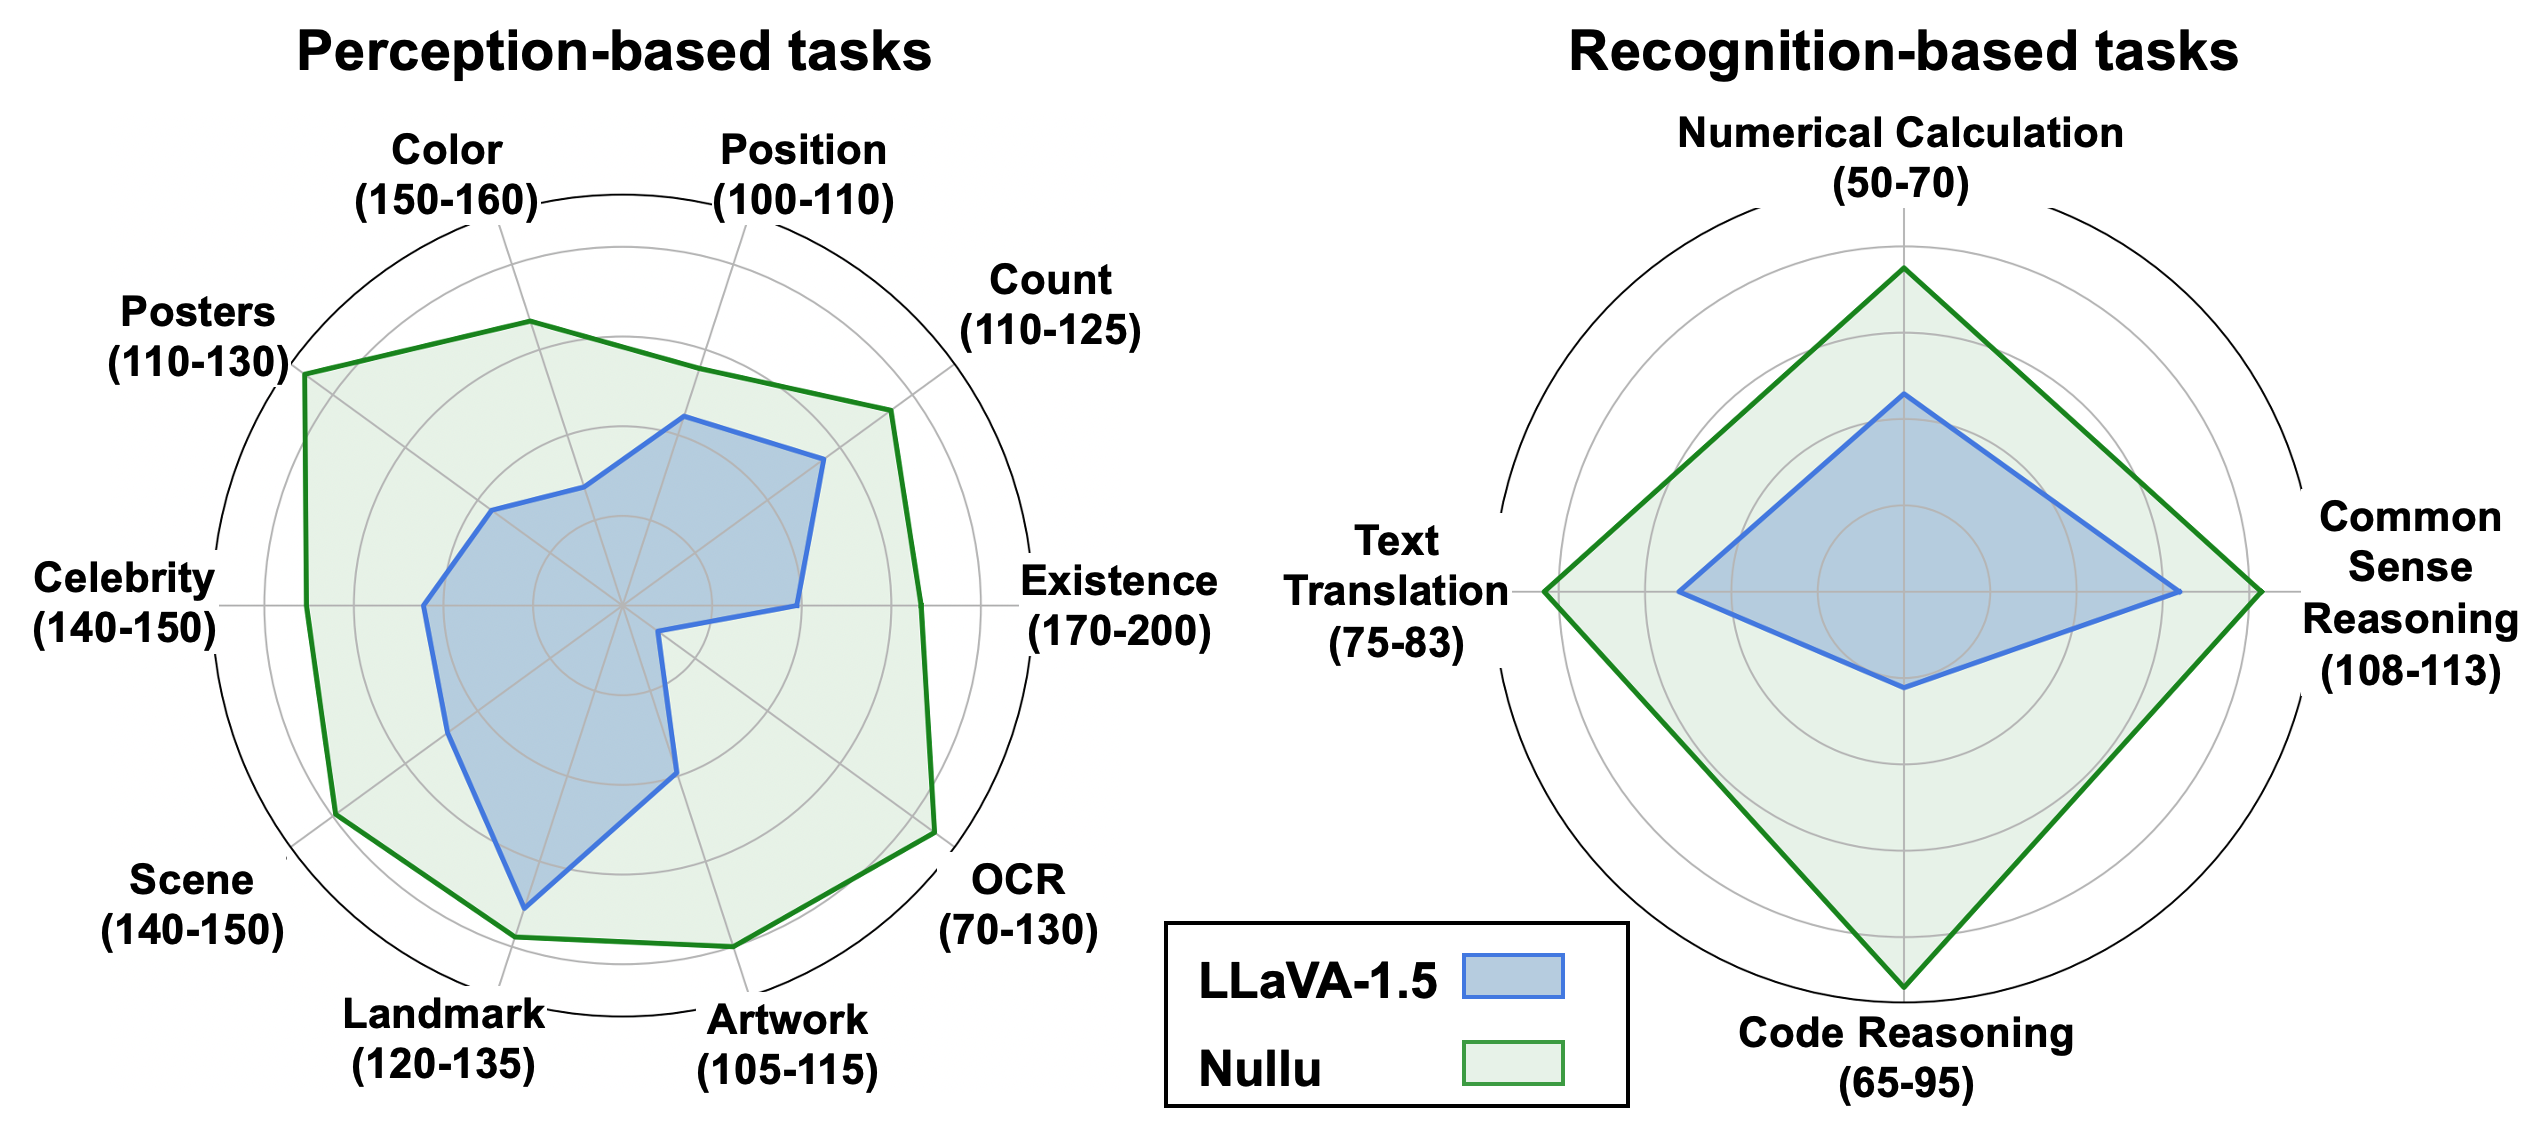
figure 5. MME full set results on LLaVA-1.5. From the results we see that Nullu leads to consistent improvements of LVLM in both perception tasks and recognition capacities.
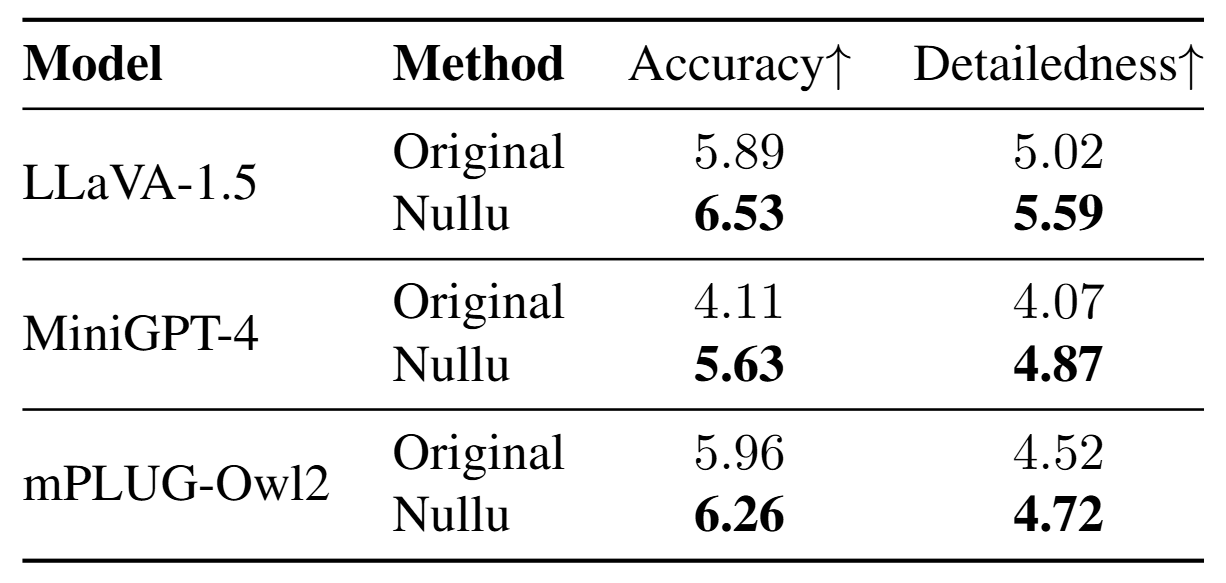
table 4. Results of GPT-4V-aided evaluation on LLaVA-Bench following the setting in VCD. Both metrics are on a scale of 10.
- Please refer to our paper for detailed experimental results.
Citation
If you find this work useful or use our codes in your own research, please use the following bibtex:
@inproceedings{yang2025nullu,
  title={Nullu: Mitigating Object Hallucinations in Large Vision-Language Models via HalluSpace Projection},
  author={Yang, Le and Zheng, Ziwei and Chen, Boxu and Zhao, Zhengyu and Lin, Chenhao and Shen, Chao},
  booktitle={Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition},
  year={2025}
}
Acknowledgement
This repository builds upon the contributions of ProFS, LLaVA 1.5, mPLUG_Owl2, MiniGPT-4. Thanks for their awesome works.
Similar repos


Code for paper: Nullu: Mitigating Object Hallucinations in Large Vision-Language Models via HalluSpace Projection
OpenEdge ABL
64
13 commits
updated Mar 13, 2025
README
Nullu: Mitigating Object Hallucinations in Large Vision-Language Models via HalluSpace Projection
Le Yang*, Ziwei Zheng*, Boxu Chen, Zhengyu Zhao, Chenhao Lin, Chao Shen. *equal contribution.
XJTU AISEC Team.
This repository contains the official code of Nullu, a method for mitigating object hallucinations in LVLMs via HalluSpace Projection.
Overview
- We introduce a novel method named Nullu, which can effectively mitigate object hallucinations (OH) with no extra inference cost.
- Nullu edit weight by extracting HalluSpaces and orthogonalizing the model weights based on representation learning:
- HalluSpace Extraction: Nullu first calculates the difference matrix of hidden features for the paired truthful and hallucinated samples and then conducts the Singular Value Decomposition (SVD), to find the main directions of the difference as the HalluSpace.
- Weight Projection: Then Nullu projects the original MLP’s weights to the null space of the HalluSpace. This procedure will be repeated for a series of layers, ${\ell}$, in the LLM of an LVLM.
Getting Started
:pushpin: Installation
Git clone our repository, creating a python environment and activate it via the following command.
    git clone https://github.com/Ziwei-Zheng/Nullu.git
    cd Nullu
    conda env create -f environment.yml
    conda activate nullu
Model Setup
Prepare the following model checkpoints:
- LLaVA-1.5 7B model: Download weights from liuhaotian/llava-v1.5-7b.
- MiniGPT-4 (LLaMA-2 Chat 7B): Download pretrained weights from this link. Set the path in
minigpt4/minigpt4_llama2_eval.yaml(Line 8). - MiniGPT-4 corresponding LLM: Download weights from meta-llama/Llama-2-7b-chat-hf.
- mPLUG-Owl2 model: Download from MAGAer13/mplug-owl2-llama2-7b.
To use a specific model, ensure the --model_path argument is set correctly. For LLaVA-1.5 and mPLUG-Owl2, use the path to the model weights, while for MiniGPT-4, set the path to the corresponding LLM weights.
Before model editing, you need to to install a specific version of transformers:
- For LLaVA-1.5 and MiniGPT4:
pip install transformers==4.37.2 - For mPLUG-Owl2:
pip install transformers==4.31.0
Dataset
Model editing and evaluation require the MSCOCO 2014 dataset. Please download here.
:hammer_and_wrench: Model editing
1. Extract Model Activations from paired samples
To extract activations for hallucinated and truthful samples, we use paired samples from LURE/dataset_train, stored in data/LURE.
- Check the value of the key
lurein thedataset_rootswithindataset/__init__.py. This specifies the path of the COCO 2014 dataset. - Run the following command under the root directory:
python scripts/model_run.py --model_name ['LLaVA-7B', 'MiniGPT4', 'mPLUG_Owl2'] --model_path /path/to/raw_model/
The corresponding activations.pkl file will be saved in ./output/{args.model_name}/.
2. Model Editing with Activations
Use the activations stored in emb_path to edit the model. Key parameters include:
- top_k_rank: Specifies the number of singular vectors to select for the editing process. Only the first
top_k_ranksingular vectors are used. - layer_range: Defines the range of layers to apply the editing to, defined as
np.arange(lowest_layer, highest_layer).
Run the following command under the root directory:
python scripts/model_edit.py --model_name ['LLaVA-7B', 'MiniGPT4', 'mPLUG_Owl2'] --model_path [PATH_TO_RAW_MODEL_WEIGHTS] --emb_path /path/to/activation.pkl --top_k_ranks 4 --lowest_layer 16 --highest_layer 32
The edited model weights will be saved in ./output/edited_model/.
:bookmark_tabs: Evalutaion
CHAIR, POPE, OPOPE
Update dataset paths in dataset_roots located in dataset/__init__.py as needed.
Following Evaluating Object Hallucination in Large Vision-Language Models, we used "Please describe this image in detail." as the prompt to query LVLM for captions of the 500 images randomly sampled from COCO 2014 Val datast.
-
CHAIR
Check the path of
data_pathandcaption_file_pathinscripts/calculate_chair.py. Then run the following command under the root directory:python scripts/model_response.py --model_name ['LLaVA-7B', 'MiniGPT4', 'mPLUG_Owl2'] --model_path [PATH_TO_MODEL_WEIGHTS] --dataset chair --num_samples 500 --num_beams 3 --max_length 64The results will be saved in
eval/chair/{os.path.basename(args.model_path)}.
The POPE files built following POPE: Polling-based Object Probing Evaluation for Object Hallucination is stored in data/POPE.
-
POPE
Check the path of
testfilesindataset/POPE.py. Then run the following command under the root directory:python scripts/model_response.py --model_name ['LLaVA-7B', 'MiniGPT4', 'mPLUG_Owl2'] --model_path [PATH_TO_MODEL_WEIGHTS] --dataset pope --num_samples 500 --num_beams 3 --max_length 64The results will be saved in
eval/opope/{os.path.basename(args.model_path)}. -
OPOPE
Check the paths of
testfileindataset/OPOPE.pyandtestfilesinscripts/calculate_opope.py. Then run the following command under the root directory:python scripts/model_response.py --model_name ['LLaVA-7B', 'MiniGPT4', 'mPLUG_Owl2'] --model_path [PATH_TO_MODEL_WEIGHTS] --dataset opope --num_samples 500 --num_beams 3 --max_length 64The results will be saved in
eval/opope/{os.path.basename(args.model_path)}.
MME
Download MME_Benchmark_release_version.zip and eval_tool.zip. Then run the following command under the root directory:
python scripts/mme_response.py --reference_dir eval_tool/Your_Results --base_dir MME_Benchmark_release_version
The response file will be stored in eval/mme/{os.path.basename(args.model_path)}. To calculate the score, run:
python scripts/mme_calculation --results_dir [PATH_TO_RESPONSE_FILE]
LLaVA-Bench
Download LLaVA-Bench (In-the-Wild) and run the following command under the root directory:
python scripts/llavabench_vqa.py --model_name ['LLaVA-7B', 'MiniGPT4', 'mPLUG_Owl2'] --model_path --image-folder liuhaotian/llava-bench-in-the-wild/images --question_file liuhaotian/llava-bench-in-the-wild/questions.jsonl
The response file will be stored in eval/llavabench_answer/{os.path.basename(args.model_path)}. To calculate the score, run:
python scripts/llavabench_gpt_eval.py --raw_answer_path [PATH_TO_RAW_MODEL_RESPONSE] --edit_answer_path [PATH_TO_EDIT_MODEL_RESPONSE] --images_dir [PATH_TO_IMAGES] --api_key [API_KEY] --base_url [URL]
GPT-4V evaluated responses will be saved under eval/llavabench/results/ as .log file.
Experiments
- Nullu mitigates the object hallucination issue across different LVLM families.
table 12. Results on POPE. Original denotes direct sampling for LVLMs, whereas Nullu refers to edit the model with the proposed method.
- Results in general LVLM benchmarks, highlighting its wide-ranging applicability.
figure 5. MME full set results on LLaVA-1.5. From the results we see that Nullu leads to consistent improvements of LVLM in both perception tasks and recognition capacities.
table 4. Results of GPT-4V-aided evaluation on LLaVA-Bench following the setting in VCD. Both metrics are on a scale of 10.
- Please refer to our paper for detailed experimental results.
Citation
If you find this work useful or use our codes in your own research, please use the following bibtex:
@inproceedings{yang2025nullu,
  title={Nullu: Mitigating Object Hallucinations in Large Vision-Language Models via HalluSpace Projection},
  author={Yang, Le and Zheng, Ziwei and Chen, Boxu and Zhao, Zhengyu and Lin, Chenhao and Shen, Chao},
  booktitle={Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition},
  year={2025}
}
Acknowledgement
This repository builds upon the contributions of ProFS, LLaVA 1.5, mPLUG_Owl2, MiniGPT-4. Thanks for their awesome works.