
[NeurIPS 2025] DreamVLA: A Vision-Language-Action Model Dreamed with Comprehensive World Knowledge
Python
373
114 commits
updated Jan 6, 2026
README
DreamVLA: A Vision-Language-Action Model
Dreamed with Comprehensive World Knowledge
NeurIPS 2025
⭐ If our project helps you, please give us a star on GitHub to support us!


If you have any questions about the code, feel free to open an issue!
The difference from previous works
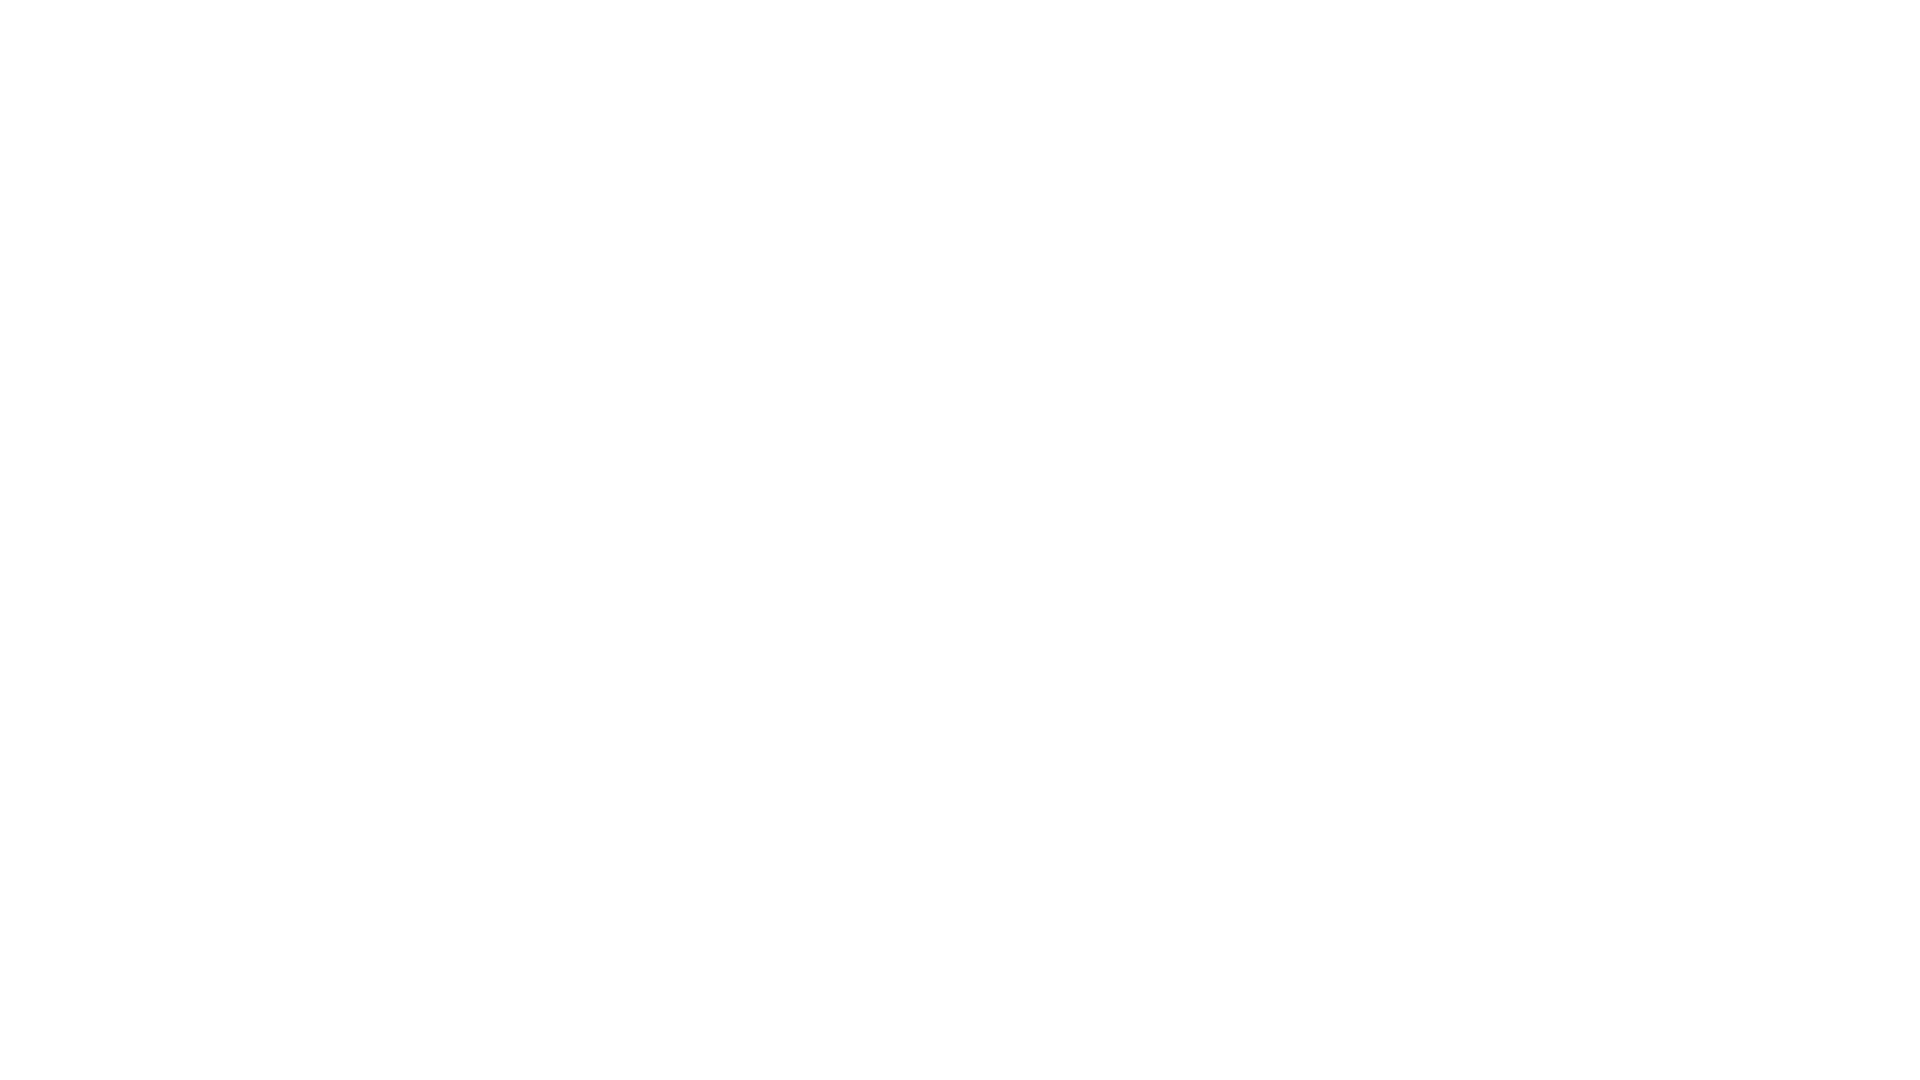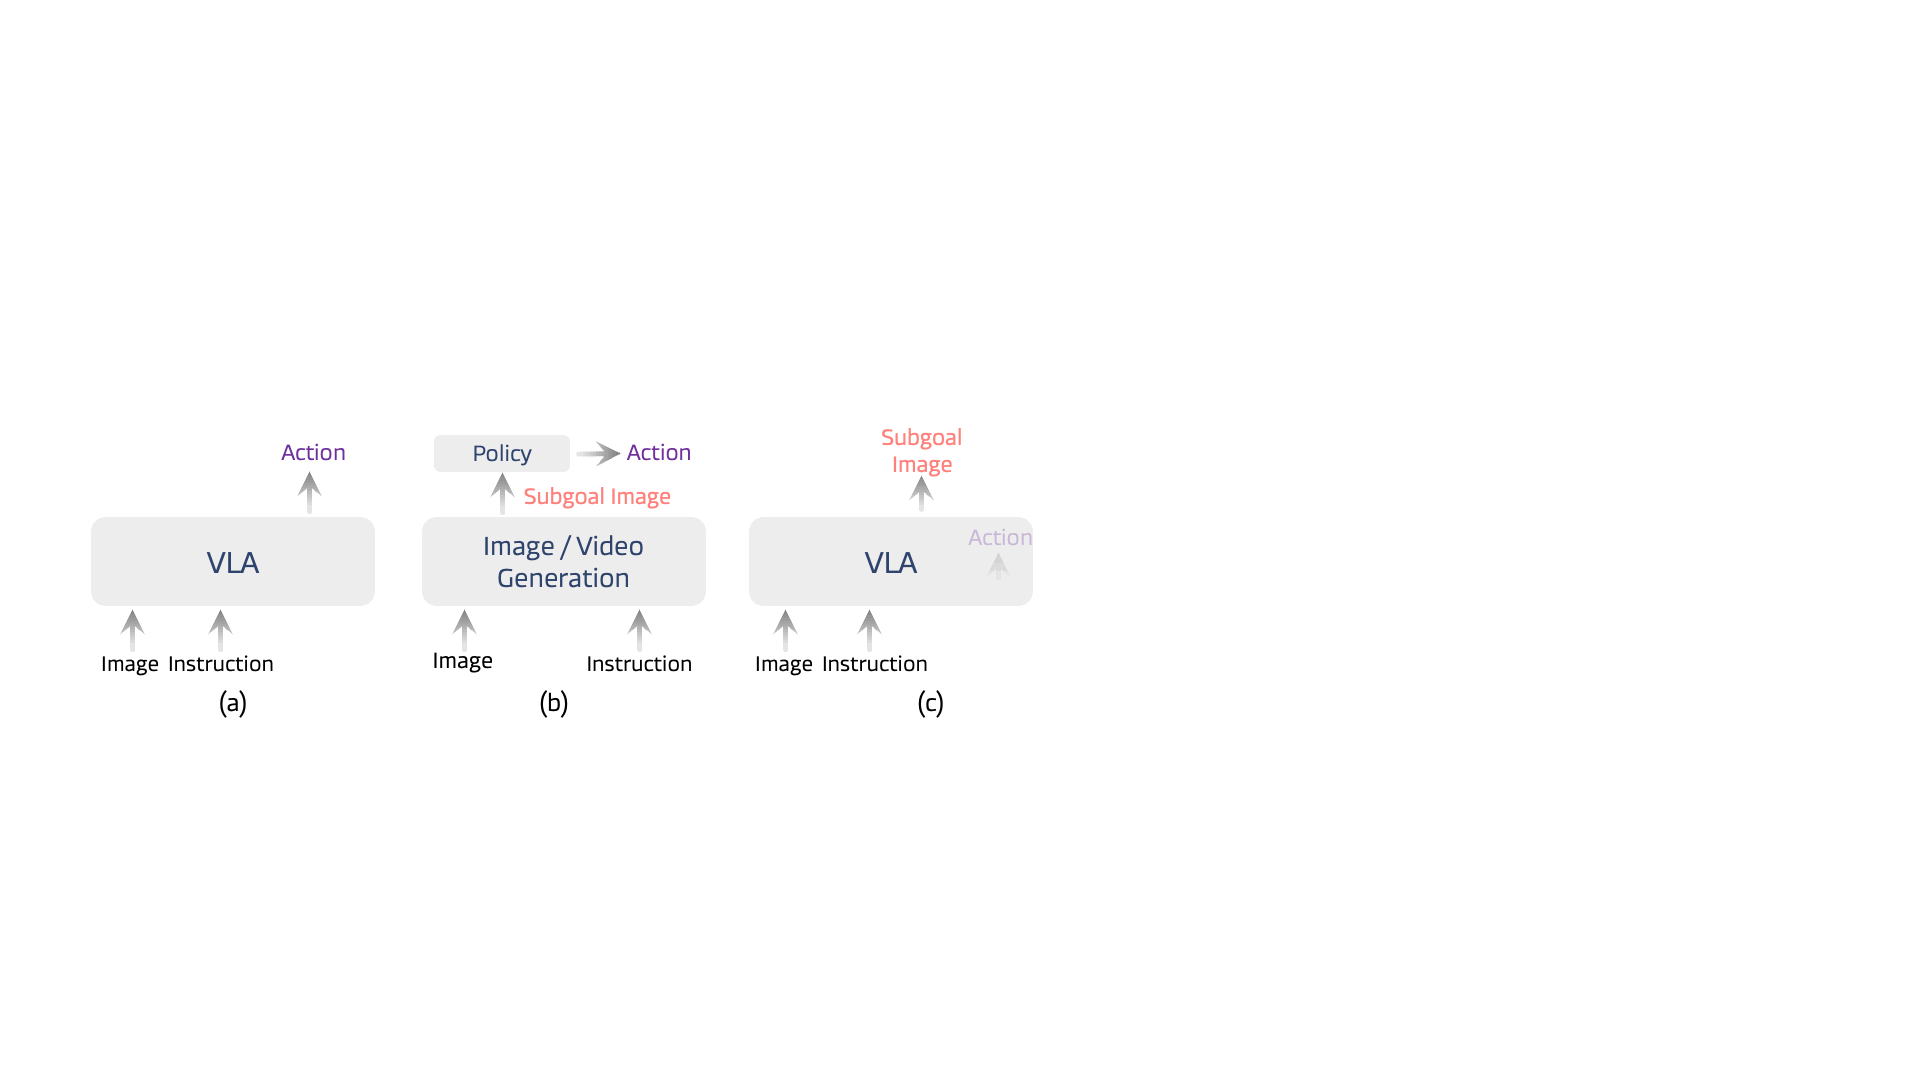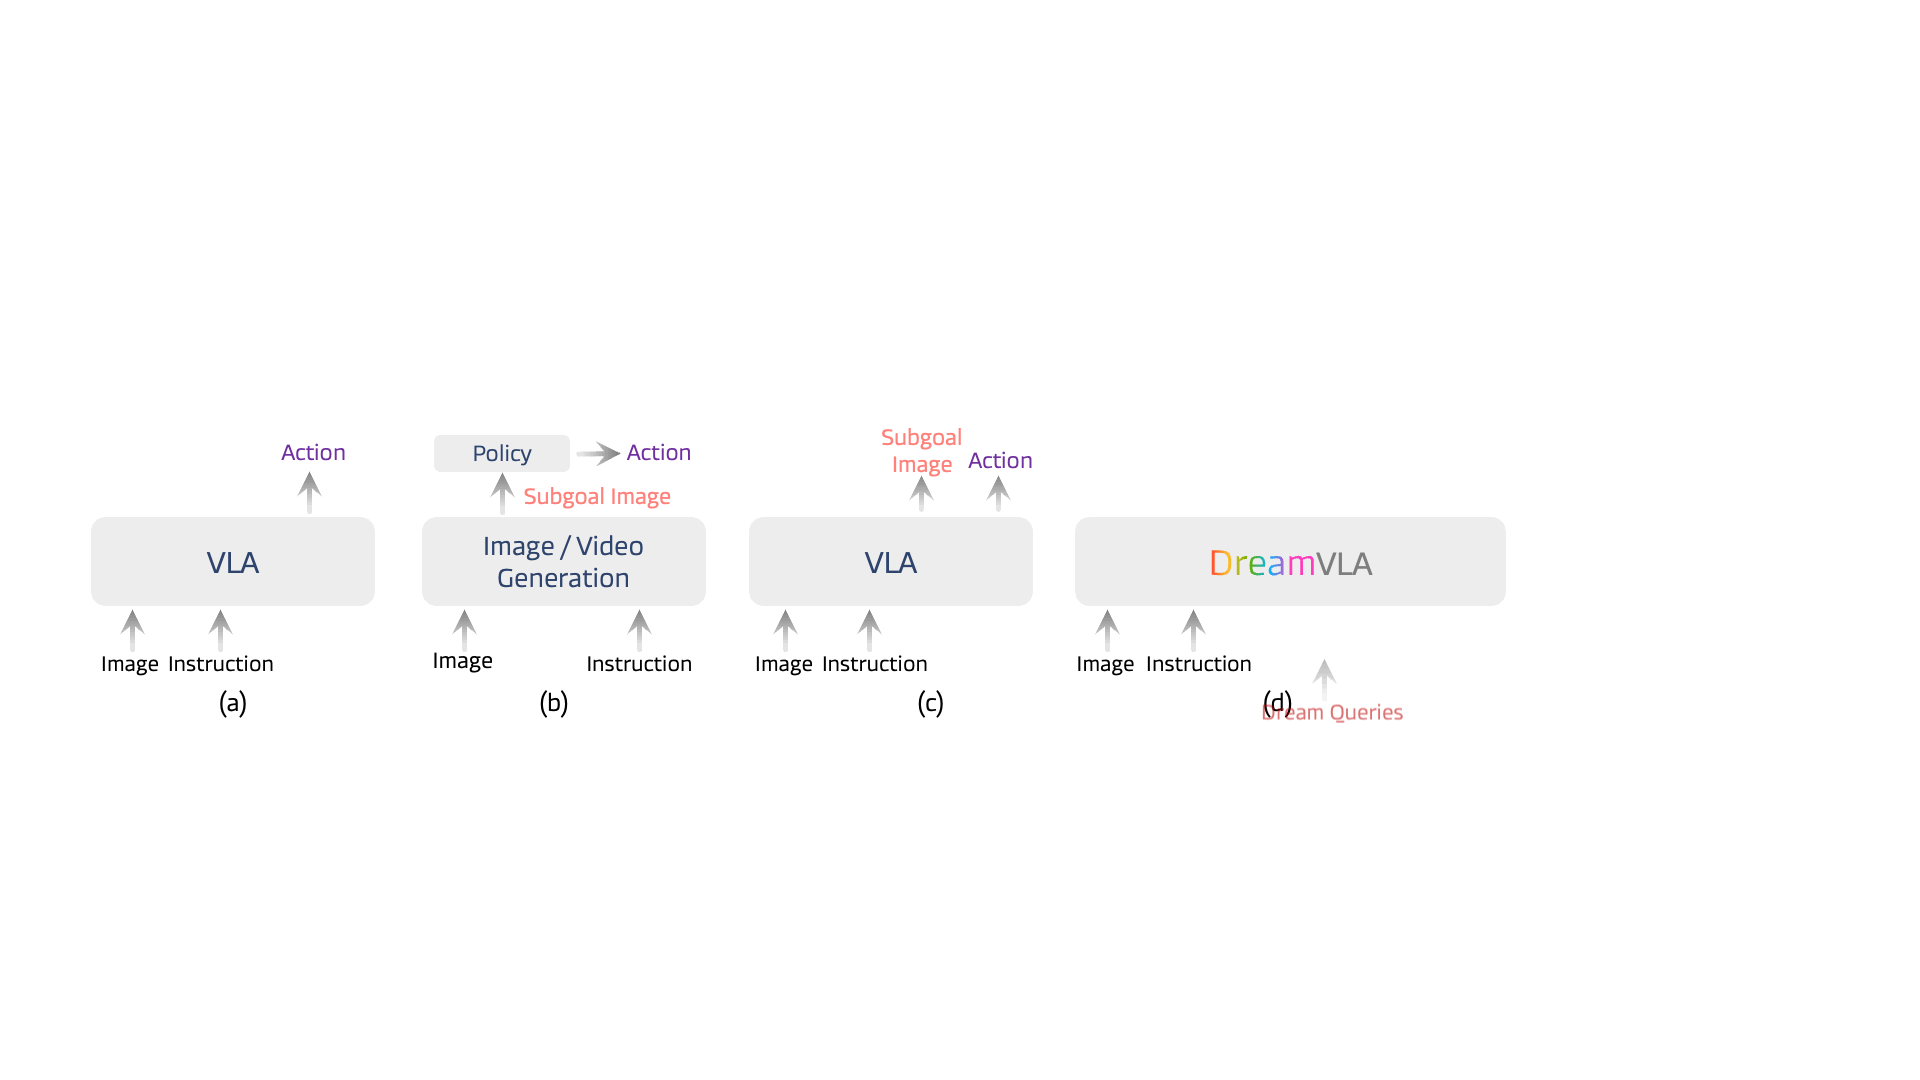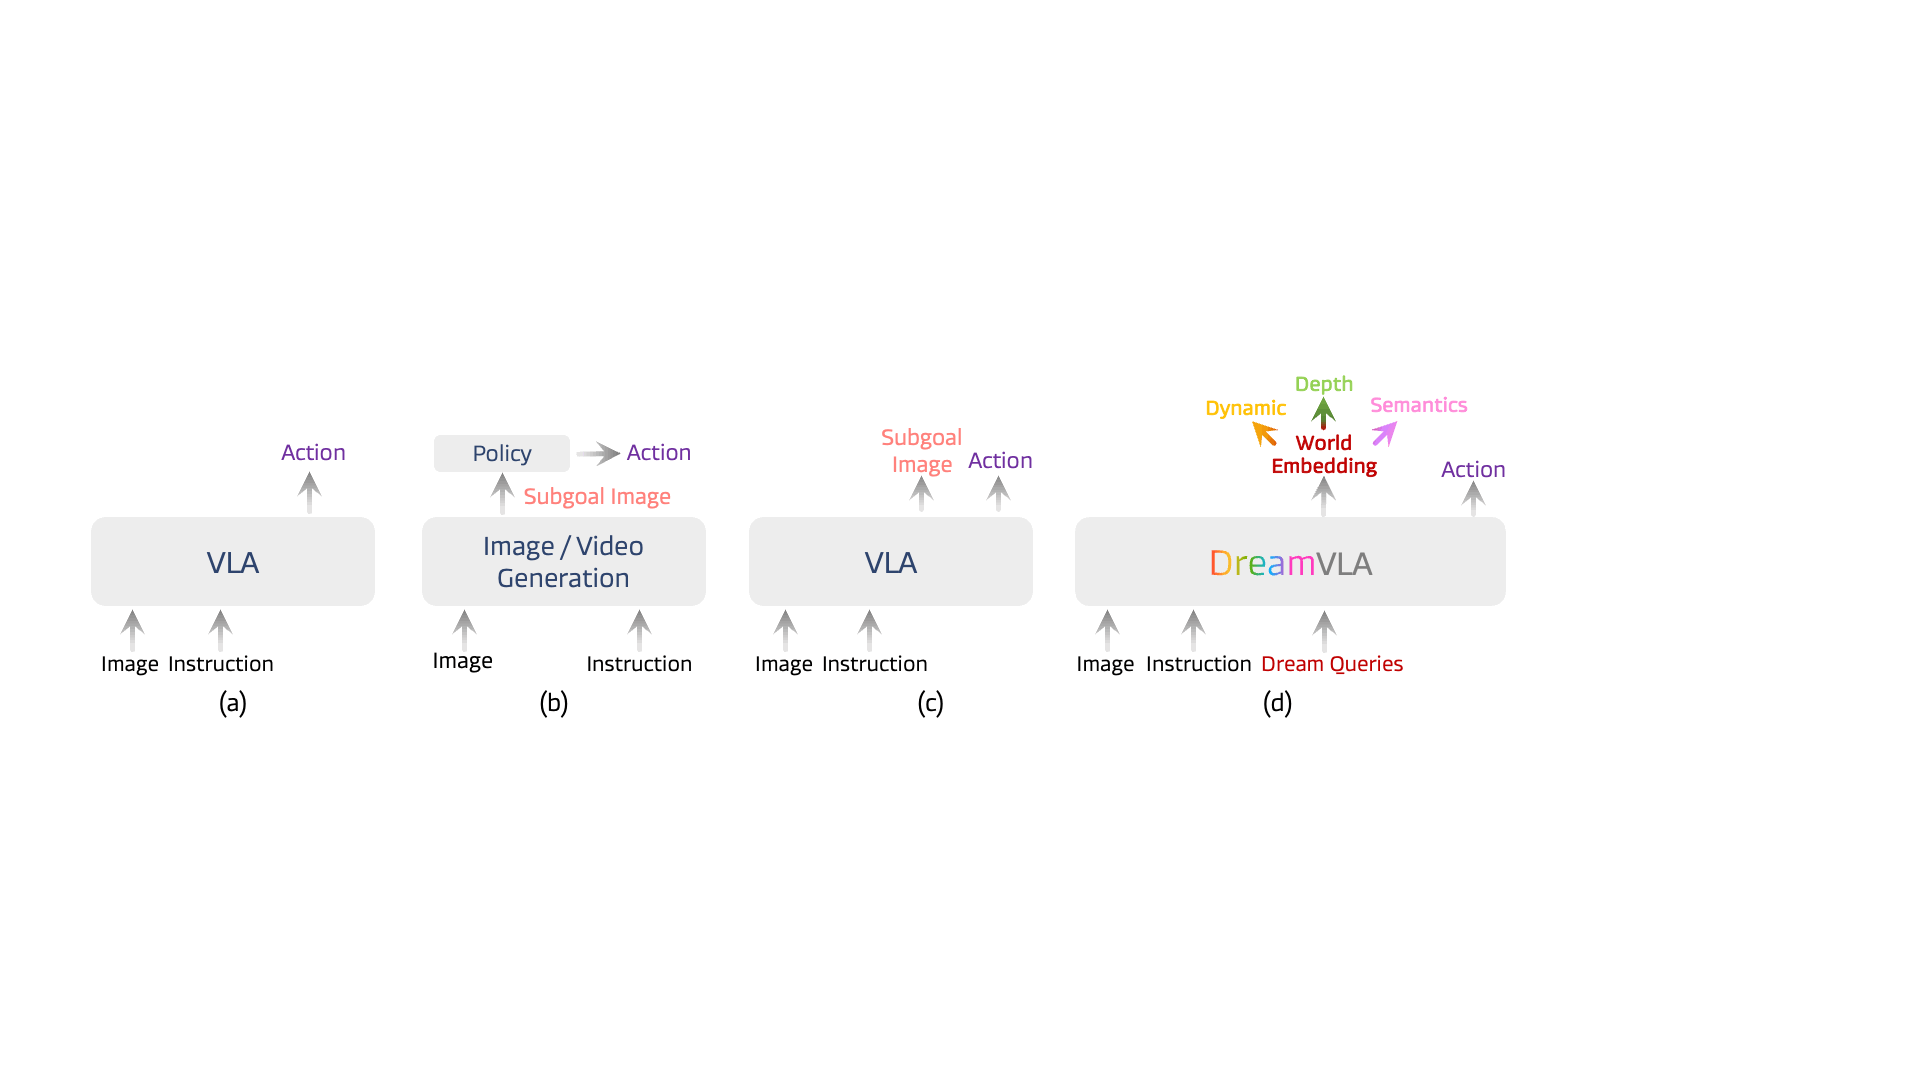
Overall framework of DreamVLA
Clone this repo
git clone https://github.com/Zhangwenyao1/DreamVLA
This repository's code is based on the Seer.
Running on the Benchmark
CALVIN ABC-D
-
CALVIN Result
Method 1 2 3 4 5 Avg. Len. ↑ Roboflamingo [30] 82.4 61.9 46.6 33.1 23.1 2.47 Susie [118] 87.0 69.0 49.0 38.0 26.0 2.69 GR-1 [14] 85.4 71.2 59.6 49.7 40.1 3.06 3D Diffusor Actor [93] 92.2 78.7 63.9 51.2 41.3 3.27 OpenVLA [1] 91.3 77.8 62.0 52.1 43.5 3.27 RoboDual [119] 94.4 82.7 72.1 62.4 54.4 3.66 UNIVLA [120] 95.5 85.8 75.4 66.9 56.5 3.80 Pi0 [32] 93.8 85.0 76.7 68.1 59.9 3.84 CLOVER [121] 96.0 83.5 70.8 57.5 45.4 3.53 UP-VLA [57] 92.8 86.5 81.5 76.9 69.9 4.08 Robovlm [37] 98.0 93.6 85.4 77.8 70.4 4.25 Seer [56] 96.3 91.6 86.1 80.3 74.0 4.28 VPP [49] 95.7 91.2 86.3 81.0 75.0 4.29 DreamVLA (Ours) 98.2 94.6 89.5 83.4 78.1 4.44
LIBERO
- Installation
- Running Code
- LIBERO Result
Methods LIBERO-Spatial LIBERO-OBJECT LIBERO-GOAL LIBERO-LONG Average Diffusion Policy [72] 78.3 92.5 68.3 50.5 72.4 Octo [9] 78.9 85.7 84.6 51.1 75.1 OpenVLA [1] 84.7 88.4 79.2 53.7 76.5 SpatialVLA [31] 88.2 89.9 78.6 55.5 78.1 DreamVLA (Ours) 97.5 94.0 89.5 89.5 92.6
TODO
- Release the code with LIBERO
Acknowledgement
We would like to express our deepest gratitude to Yang Tian for the technique support!!!
Citation
If you find our ideas / environments helpful, please cite our work at
article{dreamvla25,
          author = {Wenyao Zhang and
                    Hongsi Liu and
                    Zekun Qi and
                    Yunan Wang and
                    Xinqiang Yu and
                    Jiazhao Zhang and
                    Runpei Dong and
                    Jiawei He and
                    He Wang and
                    Zhizheng Zhang and
                    Li Yi and
                    Wenjun Zeng and
                    Xin Jin},
          title        = {DreamVLA: A Vision-Language-Action Model Dreamed with Comprehensive World Knowledge},
          journal      = {CoRR},
          volume       = {abs/2507.04447},
          year         = {2025},
          url          = {https://doi.org/10.48550/arXiv.2507.04447},
          doi          = {10.48550/ARXIV.2507.04447},
          eprinttype    = {arXiv},
          eprint       = {2507.04447}
        }



[NeurIPS 2025] DreamVLA: A Vision-Language-Action Model Dreamed with Comprehensive World Knowledge
Python
373
114 commits
updated Jan 6, 2026
README
DreamVLA: A Vision-Language-Action Model
Dreamed with Comprehensive World Knowledge
NeurIPS 2025
⭐ If our project helps you, please give us a star on GitHub to support us!
If you have any questions about the code, feel free to open an issue!
The difference from previous works
Overall framework of DreamVLA
Clone this repo
git clone https://github.com/Zhangwenyao1/DreamVLA
This repository's code is based on the Seer.
Running on the Benchmark
CALVIN ABC-D
-
CALVIN Result
Method 1 2 3 4 5 Avg. Len. ↑ Roboflamingo [30] 82.4 61.9 46.6 33.1 23.1 2.47 Susie [118] 87.0 69.0 49.0 38.0 26.0 2.69 GR-1 [14] 85.4 71.2 59.6 49.7 40.1 3.06 3D Diffusor Actor [93] 92.2 78.7 63.9 51.2 41.3 3.27 OpenVLA [1] 91.3 77.8 62.0 52.1 43.5 3.27 RoboDual [119] 94.4 82.7 72.1 62.4 54.4 3.66 UNIVLA [120] 95.5 85.8 75.4 66.9 56.5 3.80 Pi0 [32] 93.8 85.0 76.7 68.1 59.9 3.84 CLOVER [121] 96.0 83.5 70.8 57.5 45.4 3.53 UP-VLA [57] 92.8 86.5 81.5 76.9 69.9 4.08 Robovlm [37] 98.0 93.6 85.4 77.8 70.4 4.25 Seer [56] 96.3 91.6 86.1 80.3 74.0 4.28 VPP [49] 95.7 91.2 86.3 81.0 75.0 4.29 DreamVLA (Ours) 98.2 94.6 89.5 83.4 78.1 4.44
LIBERO
- Installation
- Running Code
- LIBERO Result
Methods LIBERO-Spatial LIBERO-OBJECT LIBERO-GOAL LIBERO-LONG Average Diffusion Policy [72] 78.3 92.5 68.3 50.5 72.4 Octo [9] 78.9 85.7 84.6 51.1 75.1 OpenVLA [1] 84.7 88.4 79.2 53.7 76.5 SpatialVLA [31] 88.2 89.9 78.6 55.5 78.1 DreamVLA (Ours) 97.5 94.0 89.5 89.5 92.6
TODO
- Release the code with LIBERO
Acknowledgement
We would like to express our deepest gratitude to Yang Tian for the technique support!!!
Citation
If you find our ideas / environments helpful, please cite our work at
article{dreamvla25,
          author = {Wenyao Zhang and
                    Hongsi Liu and
                    Zekun Qi and
                    Yunan Wang and
                    Xinqiang Yu and
                    Jiazhao Zhang and
                    Runpei Dong and
                    Jiawei He and
                    He Wang and
                    Zhizheng Zhang and
                    Li Yi and
                    Wenjun Zeng and
                    Xin Jin},
          title        = {DreamVLA: A Vision-Language-Action Model Dreamed with Comprehensive World Knowledge},
          journal      = {CoRR},
          volume       = {abs/2507.04447},
          year         = {2025},
          url          = {https://doi.org/10.48550/arXiv.2507.04447},
          doi          = {10.48550/ARXIV.2507.04447},
          eprinttype    = {arXiv},
          eprint       = {2507.04447}
        }