[AAAI 2026] The Avengers: A Simple Recipe for Uniting Smaller Language Models to Challenge Proprietary Giants
See the code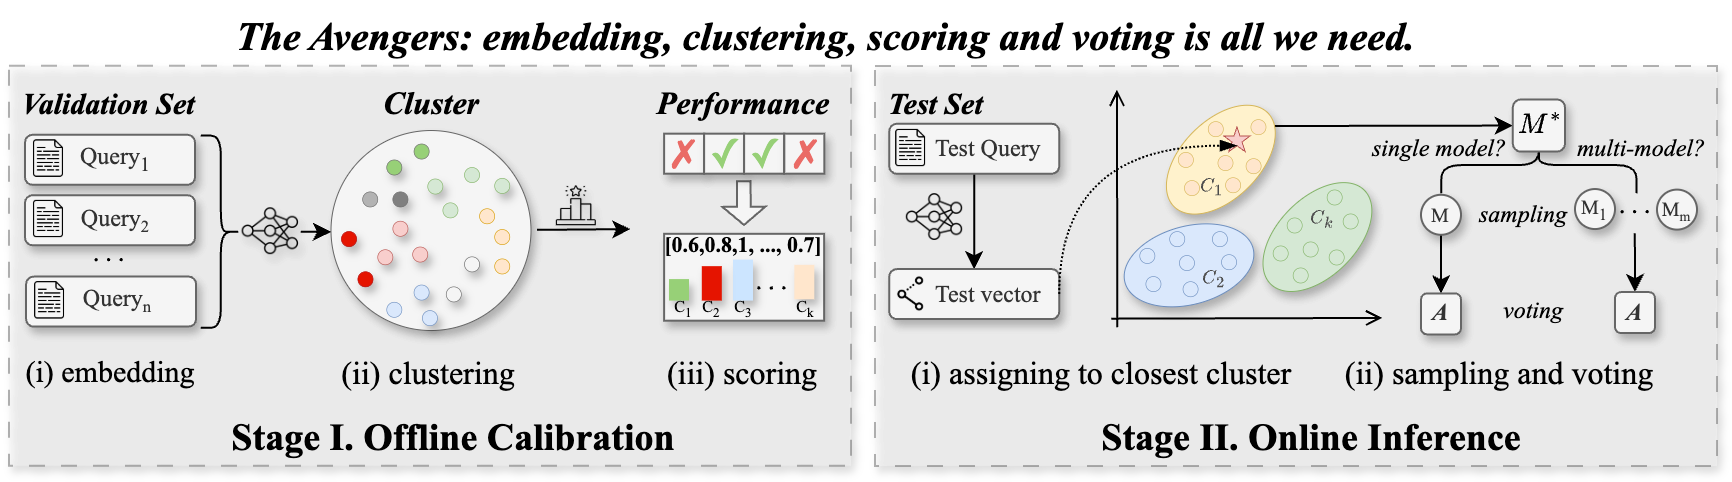


Figure 1: Comparison of proprietary models with our method (the Avengers) across six representative benchmarks. Full results on all 15 benchmarks are reported in Table 2
The Avengers is a simple recipe that effectively leverages the collective intelligence of open-source, smaller language models. Remarkably, with 10 open-source models (∼7B parameters each), the Avengers surpasses GPT-4o, 4.1, and 4.5 in average performance across 15 diverse datasets spanning mathematics, coding, logical reasoning, general knowledge, and affective tasks. As of May 2025, with 10 open-source models (~7B parameters each), the Avengers collectively outperforms GPT-4.1 (OpenAI’s flagship model released on April 14, 2025) on 9 out of 15 representative datasets.
[2025-12-10] 🎉 OpenRouterBench - We have open source all data into OpenRouterBench (huggingface, GitHub)
[2025-11-08] 🎉 AAAI 2026 (Oral) — Our paper was accepted as an Oral presentation at AAAI 2026.
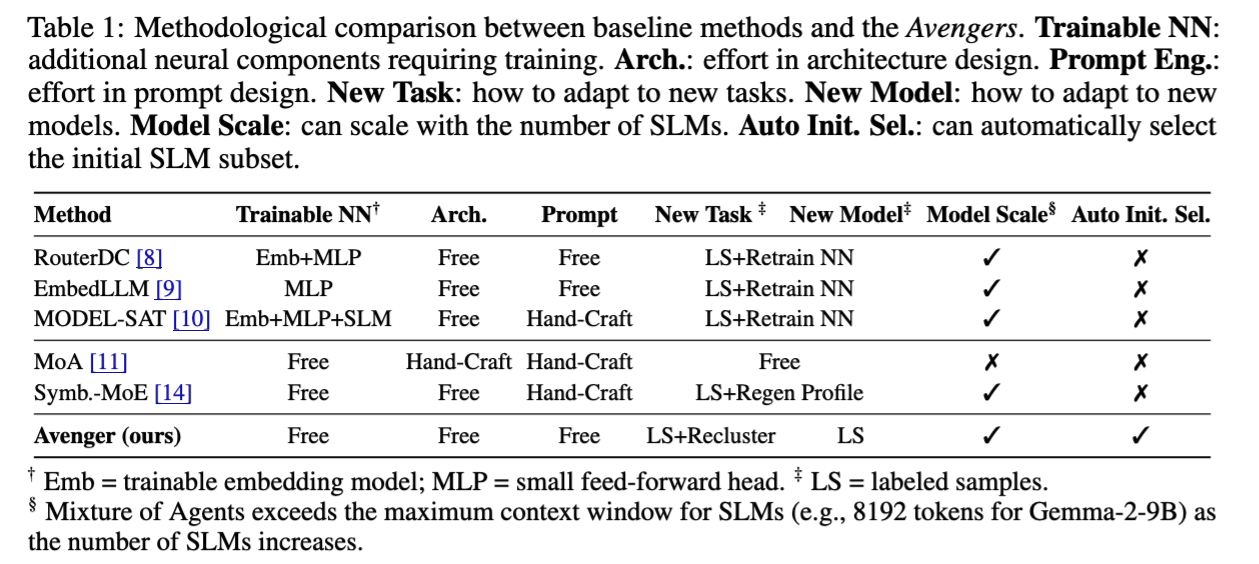
Table 1: Methodological comparison between baseline methods and the Avengers
Key advantages of The Avengers: Unlike other ensemble methods, The Avengers requires no training, introduces no additional parameters, eliminates the need for designing model collaboration structures, and requires no specialized prompt engineering. This makes our approach uniquely lightweight and practical for real-world deployment.
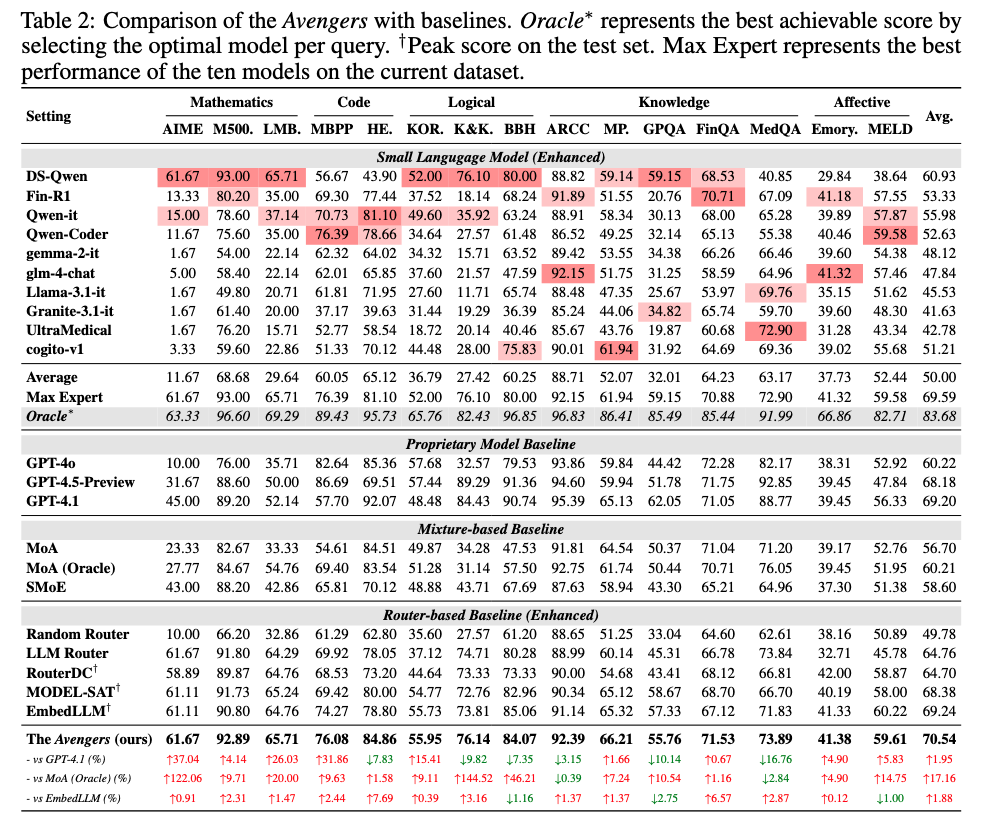
Table 2: Main Results
Outstanding performance: Using approximately 10 models with ~7B parameters each, The Avengers achieves superior performance compared to GPT-4.1 on 10 out of 15 datasets, while also surpassing GPT-4.1 in average performance across all 15 datasets. When compared with baseline router- and mixture-based methods, The Avengers consistently delivers the best results across benchmarks.
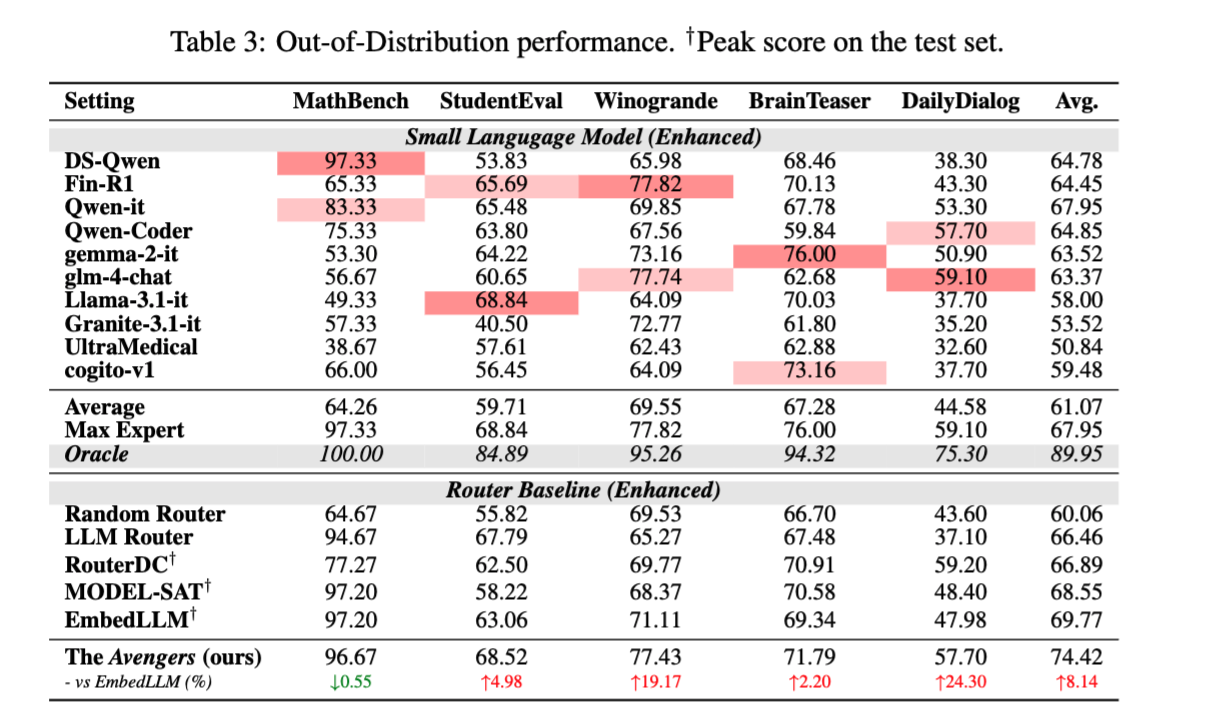
Table 3: Out-of-distribution results
Superior generalization: Compared to routing-based methods, The Avengers demonstrates the best out-of-distribution (OOD) performance thanks to its training-free nature, which prevents overfitting to specific datasets and ensures robust generalization to unseen domains.
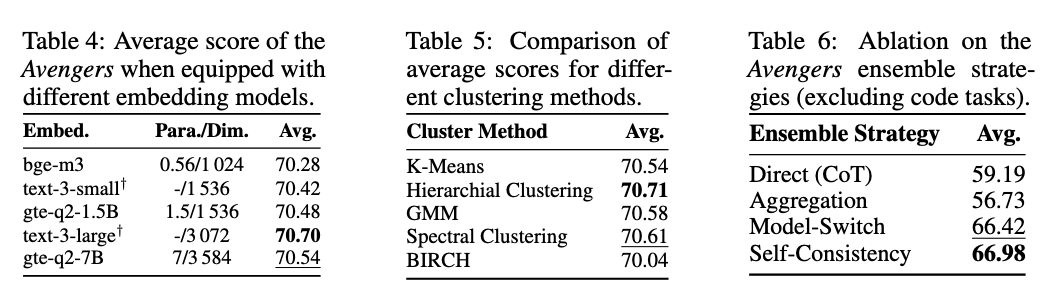
Table 4-6: Ablation studies.
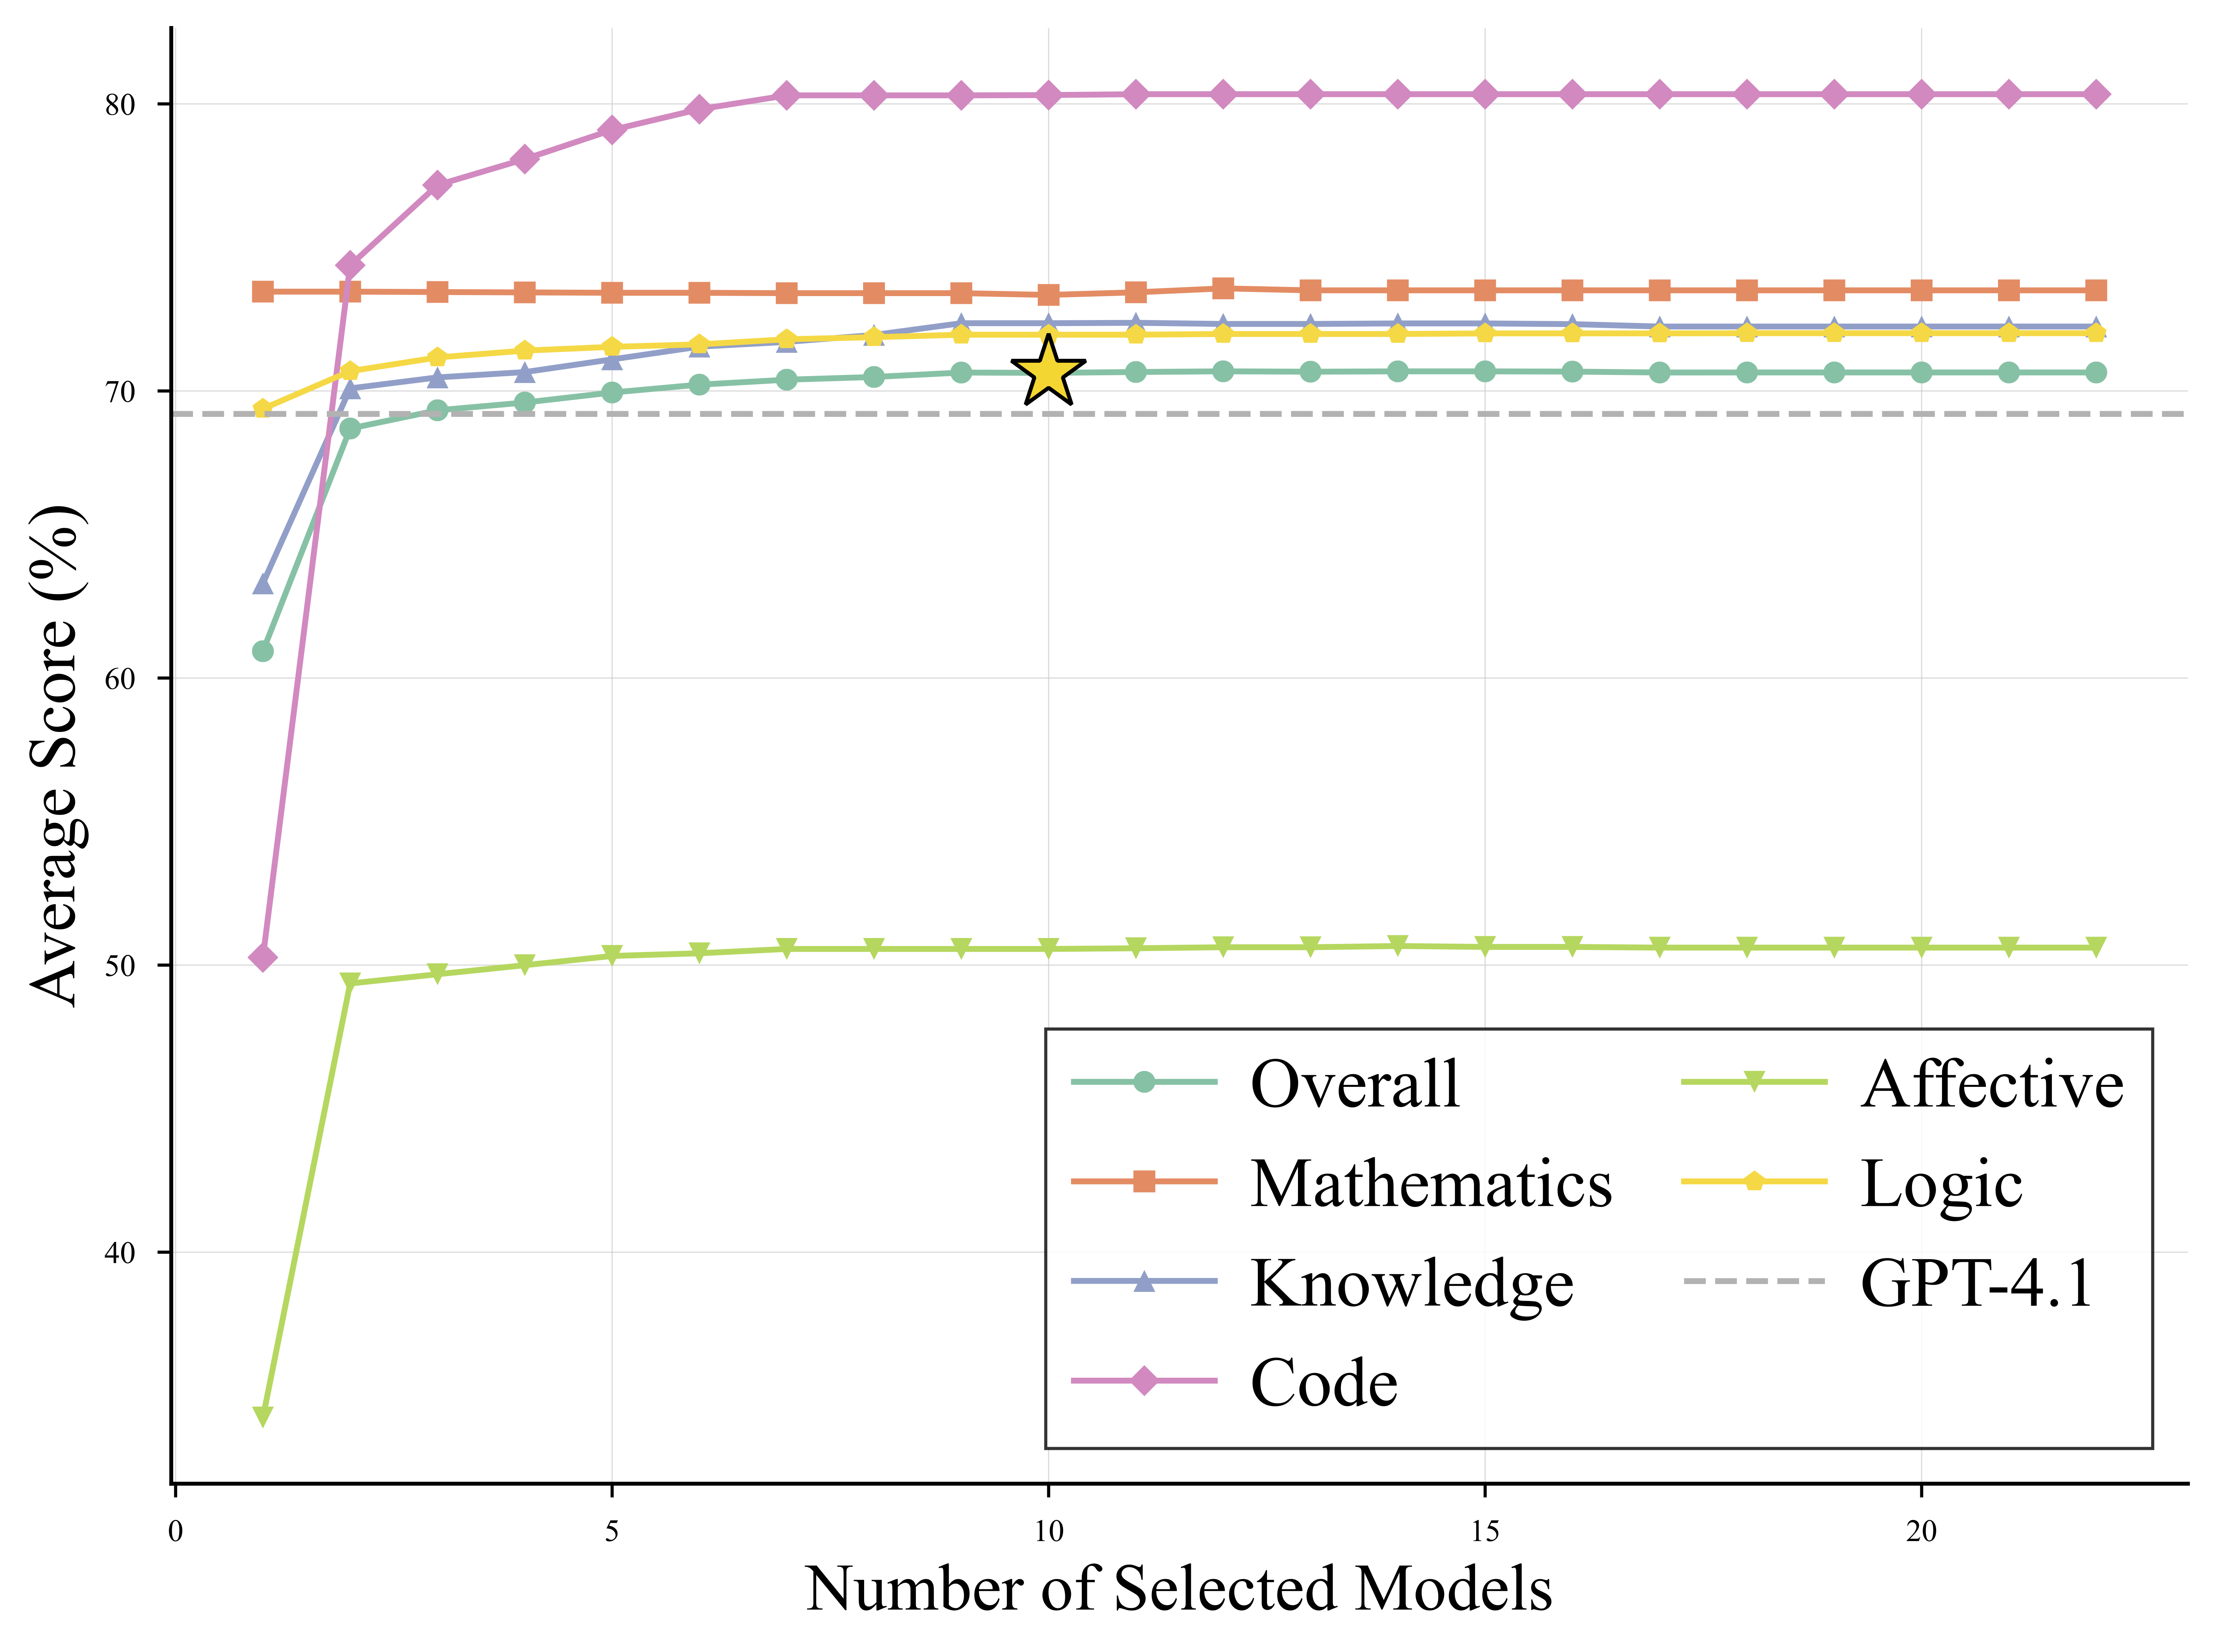
Figure 2: Impact of selected models' number. |
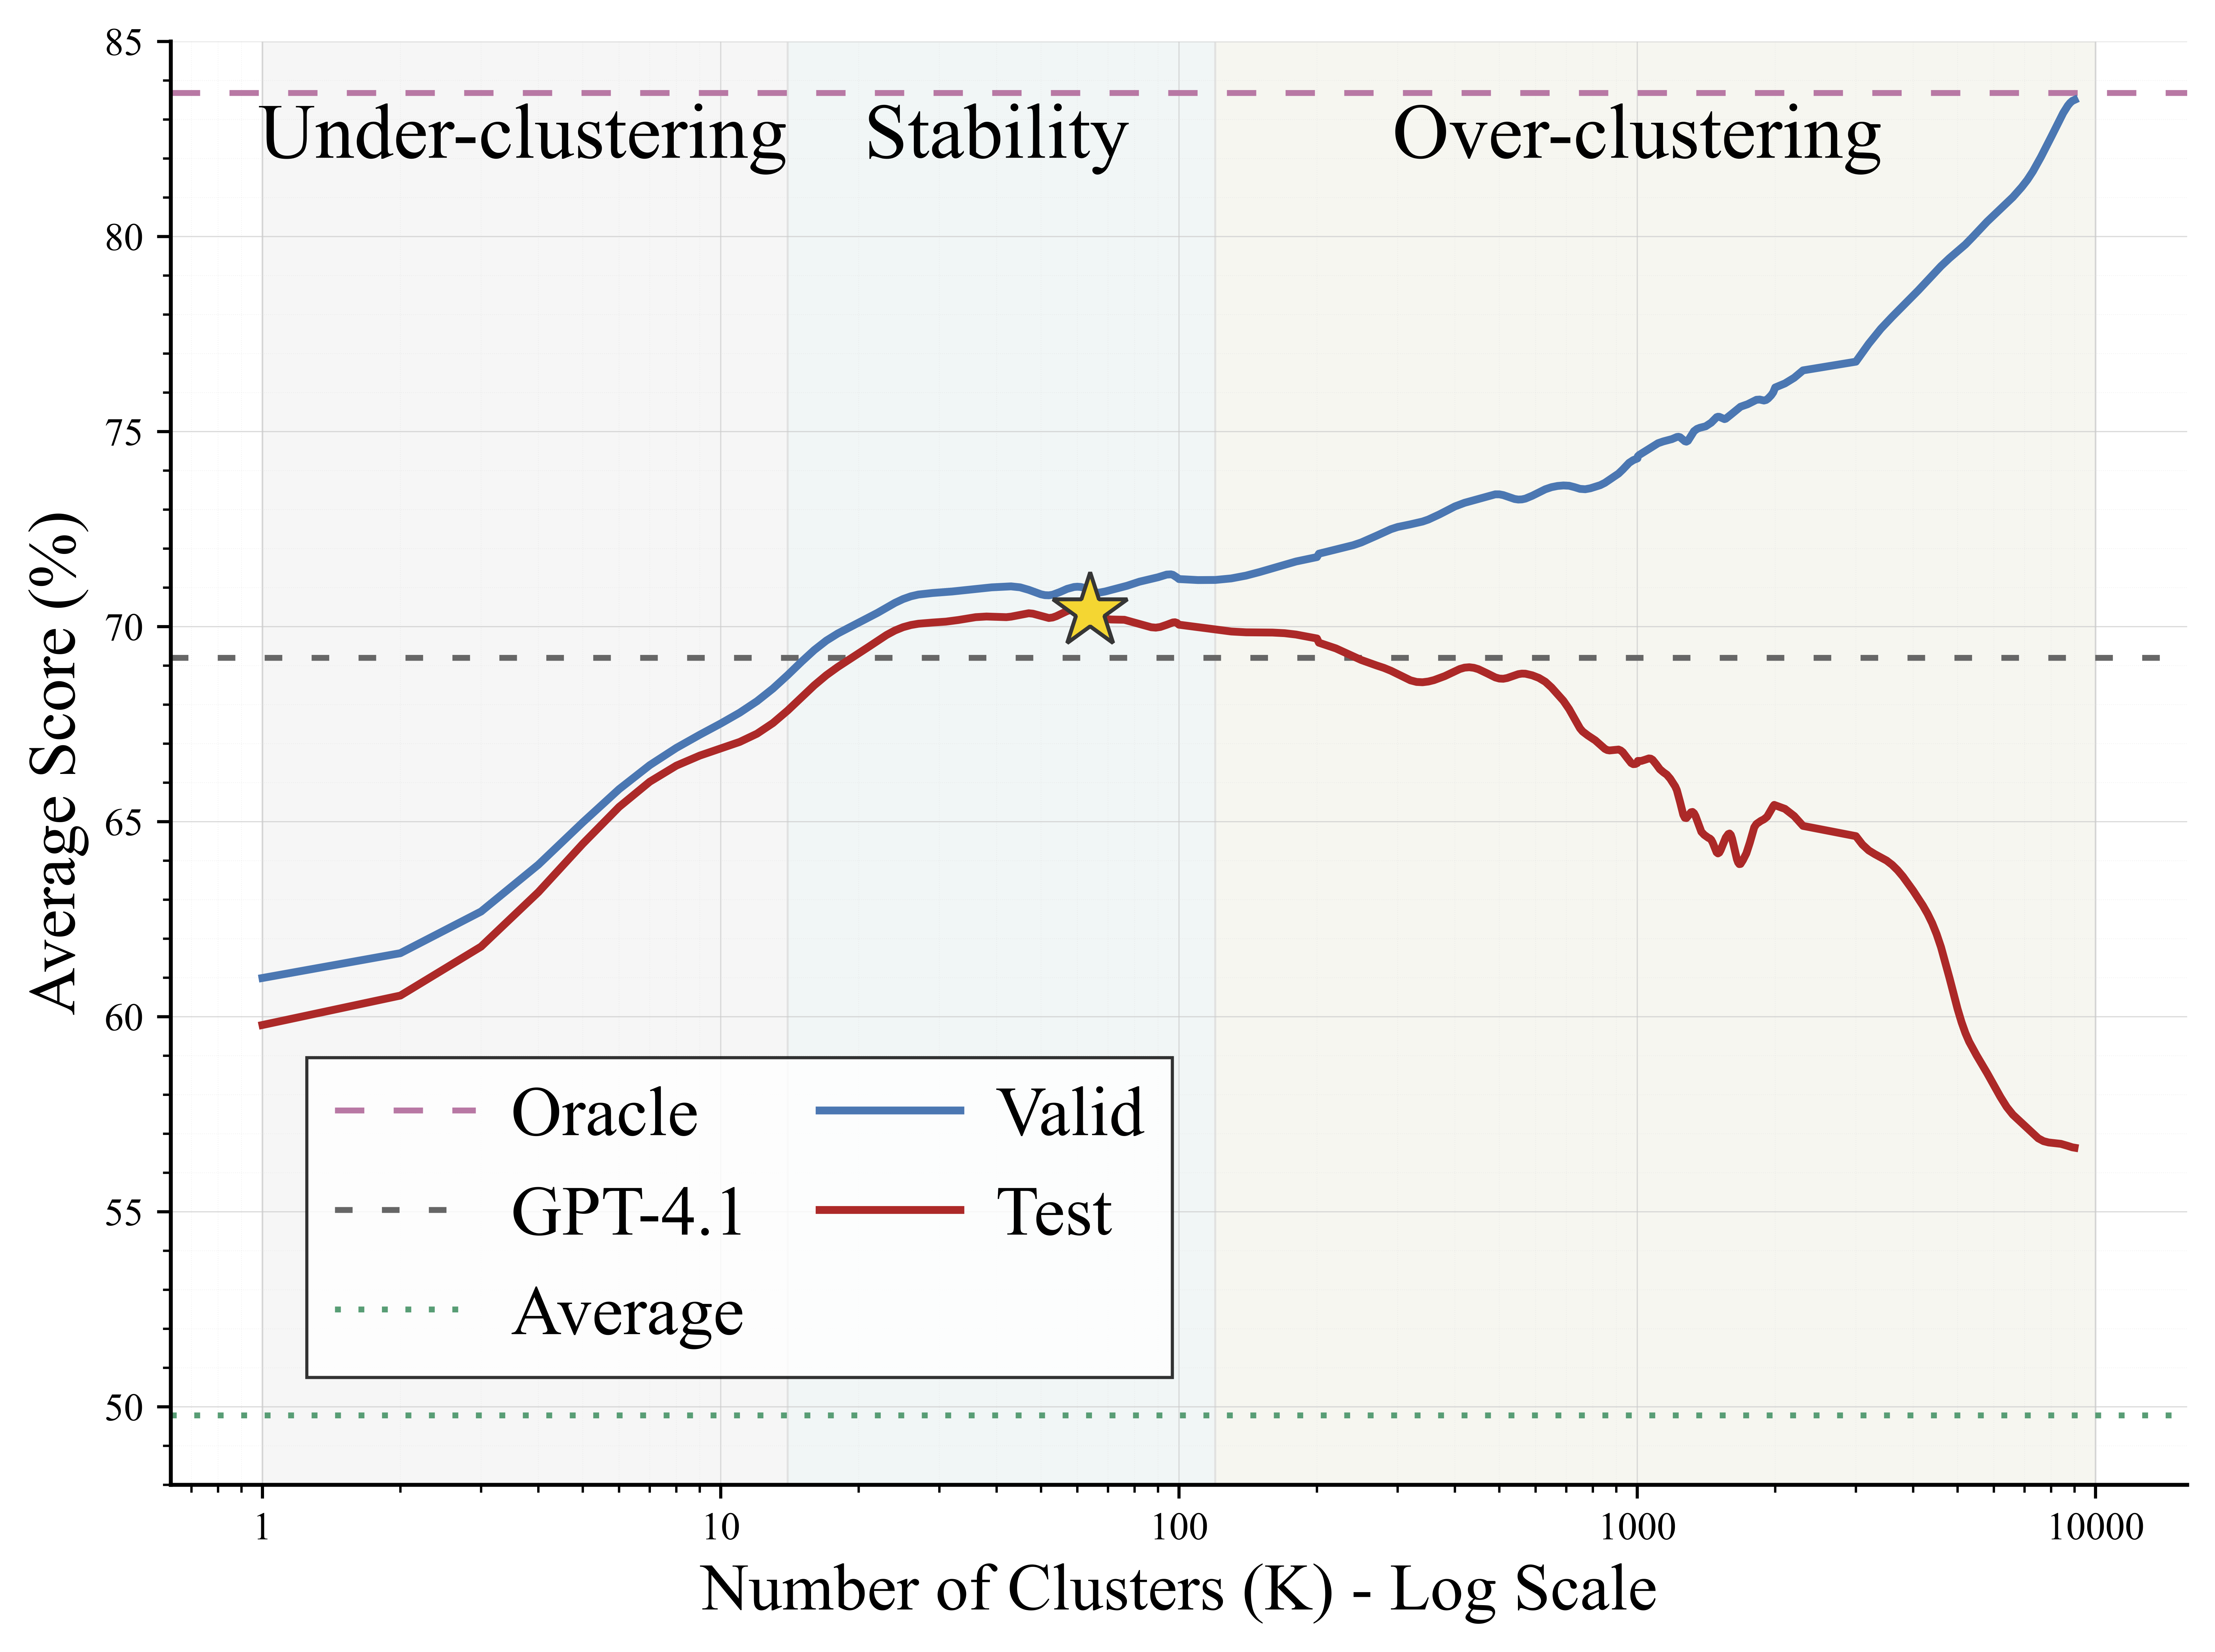
Figure 3: Impact of cluster count K |
Robust to design choices: Ablation studies demonstrate that The Avengers is insensitive to the choice of embedding models, clustering methods (14<K<140), and model selection. With 22 models tested, our automatic model selection based on cluster ranking (scoring) achieves peak performance with ~10 models, while using only 3 models matches GPT-4.1's average performance. Among different ensemble strategies, Self-Consistency shows the best performance.
requirements.txt)# Clone the repository
git clone https://github.com/ZhangYiqun018/Avengers.git
cd Avengers
# Install dependencies
pip install -r requirements.txt
For detailed usage instructions, please refer to our comprehensive Usage Guide.
Quick Start:
# Clone the repository
git clone https://github.com/ZhangYiqun018/Avengers.git
cd Avengers

# Install dependencies
pip install -r requirements.txt
# Configure your models (copy and edit the template)
cp config/experts_template.yaml config/my_config.yaml
# Run a simple experiment
python app.py --config config/my_config.yaml --save_dir results/
Key Features:
Our method has been comprehensively evaluated across multiple categories:
| Category | Benchmarks |
|---|---|
| Mathematics | AIME, Math500, LiveMathBench, MathBench |
| Code | MBPP, HumanEval, StudentEval |
| Logic | KORBench, Knights and Knaves, BBH, Winogrande |
| Knowledge | MMLUPro, GPQA, FinQA, MedQA, ARCC, BrainTeaser |
| Affective | EmoryNLP, MELD, DailyDialog |
Note: Datasets in italics are used as out-of-distribution datasets in our paper.
Access to evaluation datasets: Avengers on HuggingFace
For researchers and developers interested in the technical implementation:
core/generate_rank_router.py - Complete pipeline for generating rank router artifactscore/ablation_experiments.py - Comprehensive framework for ablation experimentsThe core/ directory contains the complete implementation of our clustering-based routing system, including:
# Generate rank router configuration
python core/generate_rank_router.py --data_path your_data.json --n_clusters 64
# Run comprehensive ablation studies
python core/ablation_experiments.py --experiment all --data_path your_data.json
Note: All implementation preserves the core algorithmic logic described in our paper while providing production-ready code with comprehensive error handling, caching, and parallel processing support.
If you find our work useful for your research, please consider citing:
@misc{zhang2025avengerssimplerecipeuniting,
title={The Avengers: A Simple Recipe for Uniting Smaller Language Models to Challenge Proprietary Giants},
author={Yiqun Zhang and Hao Li and Chenxu Wang and Linyao Chen and Qiaosheng Zhang and Peng Ye and Shi Feng and Daling Wang and Zhen Wang and Xinrun Wang and Jia Xu and Lei Bai and Wanli Ouyang and Shuyue Hu},
year={2025},
eprint={2505.19797},
archivePrefix={arXiv},
primaryClass={cs.CL},
url={https://arxiv.org/abs/2505.19797},
}
For questions or collaborations, please contact: [email protected] or [email protected]
[AAAI 2026] The Avengers: A Simple Recipe for Uniting Smaller Language Models to Challenge Proprietary Giants
See the code
Figure 1: Comparison of proprietary models with our method (the Avengers) across six representative benchmarks. Full results on all 15 benchmarks are reported in Table 2
The Avengers is a simple recipe that effectively leverages the collective intelligence of open-source, smaller language models. Remarkably, with 10 open-source models (∼7B parameters each), the Avengers surpasses GPT-4o, 4.1, and 4.5 in average performance across 15 diverse datasets spanning mathematics, coding, logical reasoning, general knowledge, and affective tasks. As of May 2025, with 10 open-source models (~7B parameters each), the Avengers collectively outperforms GPT-4.1 (OpenAI’s flagship model released on April 14, 2025) on 9 out of 15 representative datasets.
[2025-12-10] 🎉 OpenRouterBench - We have open source all data into OpenRouterBench (huggingface, GitHub)
[2025-11-08] 🎉 AAAI 2026 (Oral) — Our paper was accepted as an Oral presentation at AAAI 2026.
Table 1: Methodological comparison between baseline methods and the Avengers
Key advantages of The Avengers: Unlike other ensemble methods, The Avengers requires no training, introduces no additional parameters, eliminates the need for designing model collaboration structures, and requires no specialized prompt engineering. This makes our approach uniquely lightweight and practical for real-world deployment.
Table 2: Main Results
Outstanding performance: Using approximately 10 models with ~7B parameters each, The Avengers achieves superior performance compared to GPT-4.1 on 10 out of 15 datasets, while also surpassing GPT-4.1 in average performance across all 15 datasets. When compared with baseline router- and mixture-based methods, The Avengers consistently delivers the best results across benchmarks.
Table 3: Out-of-distribution results
Superior generalization: Compared to routing-based methods, The Avengers demonstrates the best out-of-distribution (OOD) performance thanks to its training-free nature, which prevents overfitting to specific datasets and ensures robust generalization to unseen domains.
Table 4-6: Ablation studies.
|
Figure 2: Impact of selected models' number. |
Figure 3: Impact of cluster count K |
Robust to design choices: Ablation studies demonstrate that The Avengers is insensitive to the choice of embedding models, clustering methods (14<K<140), and model selection. With 22 models tested, our automatic model selection based on cluster ranking (scoring) achieves peak performance with ~10 models, while using only 3 models matches GPT-4.1's average performance. Among different ensemble strategies, Self-Consistency shows the best performance.
requirements.txt)# Clone the repository
git clone https://github.com/ZhangYiqun018/Avengers.git
cd Avengers
# Install dependencies
pip install -r requirements.txt
For detailed usage instructions, please refer to our comprehensive Usage Guide.
Quick Start:
# Clone the repository
git clone https://github.com/ZhangYiqun018/Avengers.git
cd Avengers

# Install dependencies
pip install -r requirements.txt

# Configure your models (copy and edit the template)
cp config/experts_template.yaml config/my_config.yaml

# Run a simple experiment
python app.py --config config/my_config.yaml --save_dir results/
Key Features:
Our method has been comprehensively evaluated across multiple categories:
| Category | Benchmarks |
|---|---|
| Mathematics | AIME, Math500, LiveMathBench, MathBench |
| Code | MBPP, HumanEval, StudentEval |
| Logic | KORBench, Knights and Knaves, BBH, Winogrande |
| Knowledge | MMLUPro, GPQA, FinQA, MedQA, ARCC, BrainTeaser |
| Affective | EmoryNLP, MELD, DailyDialog |
Note: Datasets in italics are used as out-of-distribution datasets in our paper.
Access to evaluation datasets: Avengers on HuggingFace
For researchers and developers interested in the technical implementation:
core/generate_rank_router.py - Complete pipeline for generating rank router artifactscore/ablation_experiments.py - Comprehensive framework for ablation experimentsThe core/ directory contains the complete implementation of our clustering-based routing system, including:
# Generate rank router configuration
python core/generate_rank_router.py --data_path your_data.json --n_clusters 64

# Run comprehensive ablation studies
python core/ablation_experiments.py --experiment all --data_path your_data.json
Note: All implementation preserves the core algorithmic logic described in our paper while providing production-ready code with comprehensive error handling, caching, and parallel processing support.
If you find our work useful for your research, please consider citing:
@misc{zhang2025avengerssimplerecipeuniting,
      title={The Avengers: A Simple Recipe for Uniting Smaller Language Models to Challenge Proprietary Giants},
      author={Yiqun Zhang and Hao Li and Chenxu Wang and Linyao Chen and Qiaosheng Zhang and Peng Ye and Shi Feng and Daling Wang and Zhen Wang and Xinrun Wang and Jia Xu and Lei Bai and Wanli Ouyang and Shuyue Hu},
      year={2025},
      eprint={2505.19797},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2505.19797},
}
For questions or collaborations, please contact: [email protected] or [email protected]



