
Awsome of VLM-CL. Continual Learning for VLMs: A Survey and Taxonomy Beyond Forgetting
221
93 commits
updated Sep 4, 2026
README
Awesome Continual Learning for Vision-Language Models & MLLMs


A curated list of papers, codebases, and datasets for continual learning in vision-language models (VLMs) and Multimodal Large Language Models (MLLMs), accompanying our survey paper. Last updated: 2026-08
📑 Table of Contents
- Latest News
- Citing Our Work
- Overview & Challenges
- Taxonomy
- 🏆 Mini Leaderboard (SOTA Performance)
- 📄 Papers
- 🗂️ Datasets & Benchmarks
- 🚀 Future Directions
🔥 Latest News
- [2026.08] Our survey paper, “Continual Learning for VLMs: A Survey and Taxonomy Beyond Forgetting” (v3), is now available on arXiv.
- [2026.03] We have updated the repository with a new collection of recent papers and resources to reflect the latest advances in VLM continual learning.
- [Ongoing] This repository is under active maintenance and will be continuously updated with newly released papers, code, and benchmarks from the community.
📣 Citing Our Work
If you find this repository or our survey useful for your research, please consider citing our work:
@article{liu2026continual,
  title={Continual Learning for VLMs: A Survey and Taxonomy Beyond Forgetting},
  author={Liu, Yuyang and Hong, Qiuhe and Huang, Linlan and Gomez-Villa, Alexandra and Goswami, Dipam and Liu, Xialei and van de Weijer, Joost and Tian, Yonghong},
  journal={arXiv preprint arXiv:2508.04227},
  year={2026}
}
📜 Overview
Vision-language models (VLMs) like CLIP have achieved remarkable success, but adapting them to evolving data streams without catastrophic forgetting is a critical challenge. This repository provides a systematic review of research on continual learning for VLMs (VLM-CL).
Our survey identifies three core failure modes in VLM-CL:
- 🧠 Cross-Modal Feature Drift: The degradation of alignment between visual and textual feature spaces during updates.
- ⚙️ Shared Module Interference: Destructive weight updates in shared components like cross-attention layers, which is common in fusion-based models.
- 📉 Zero-Shot Capability Erosion: The loss of generalization to unseen tasks after the model is fine-tuned on specific downstream tasks.
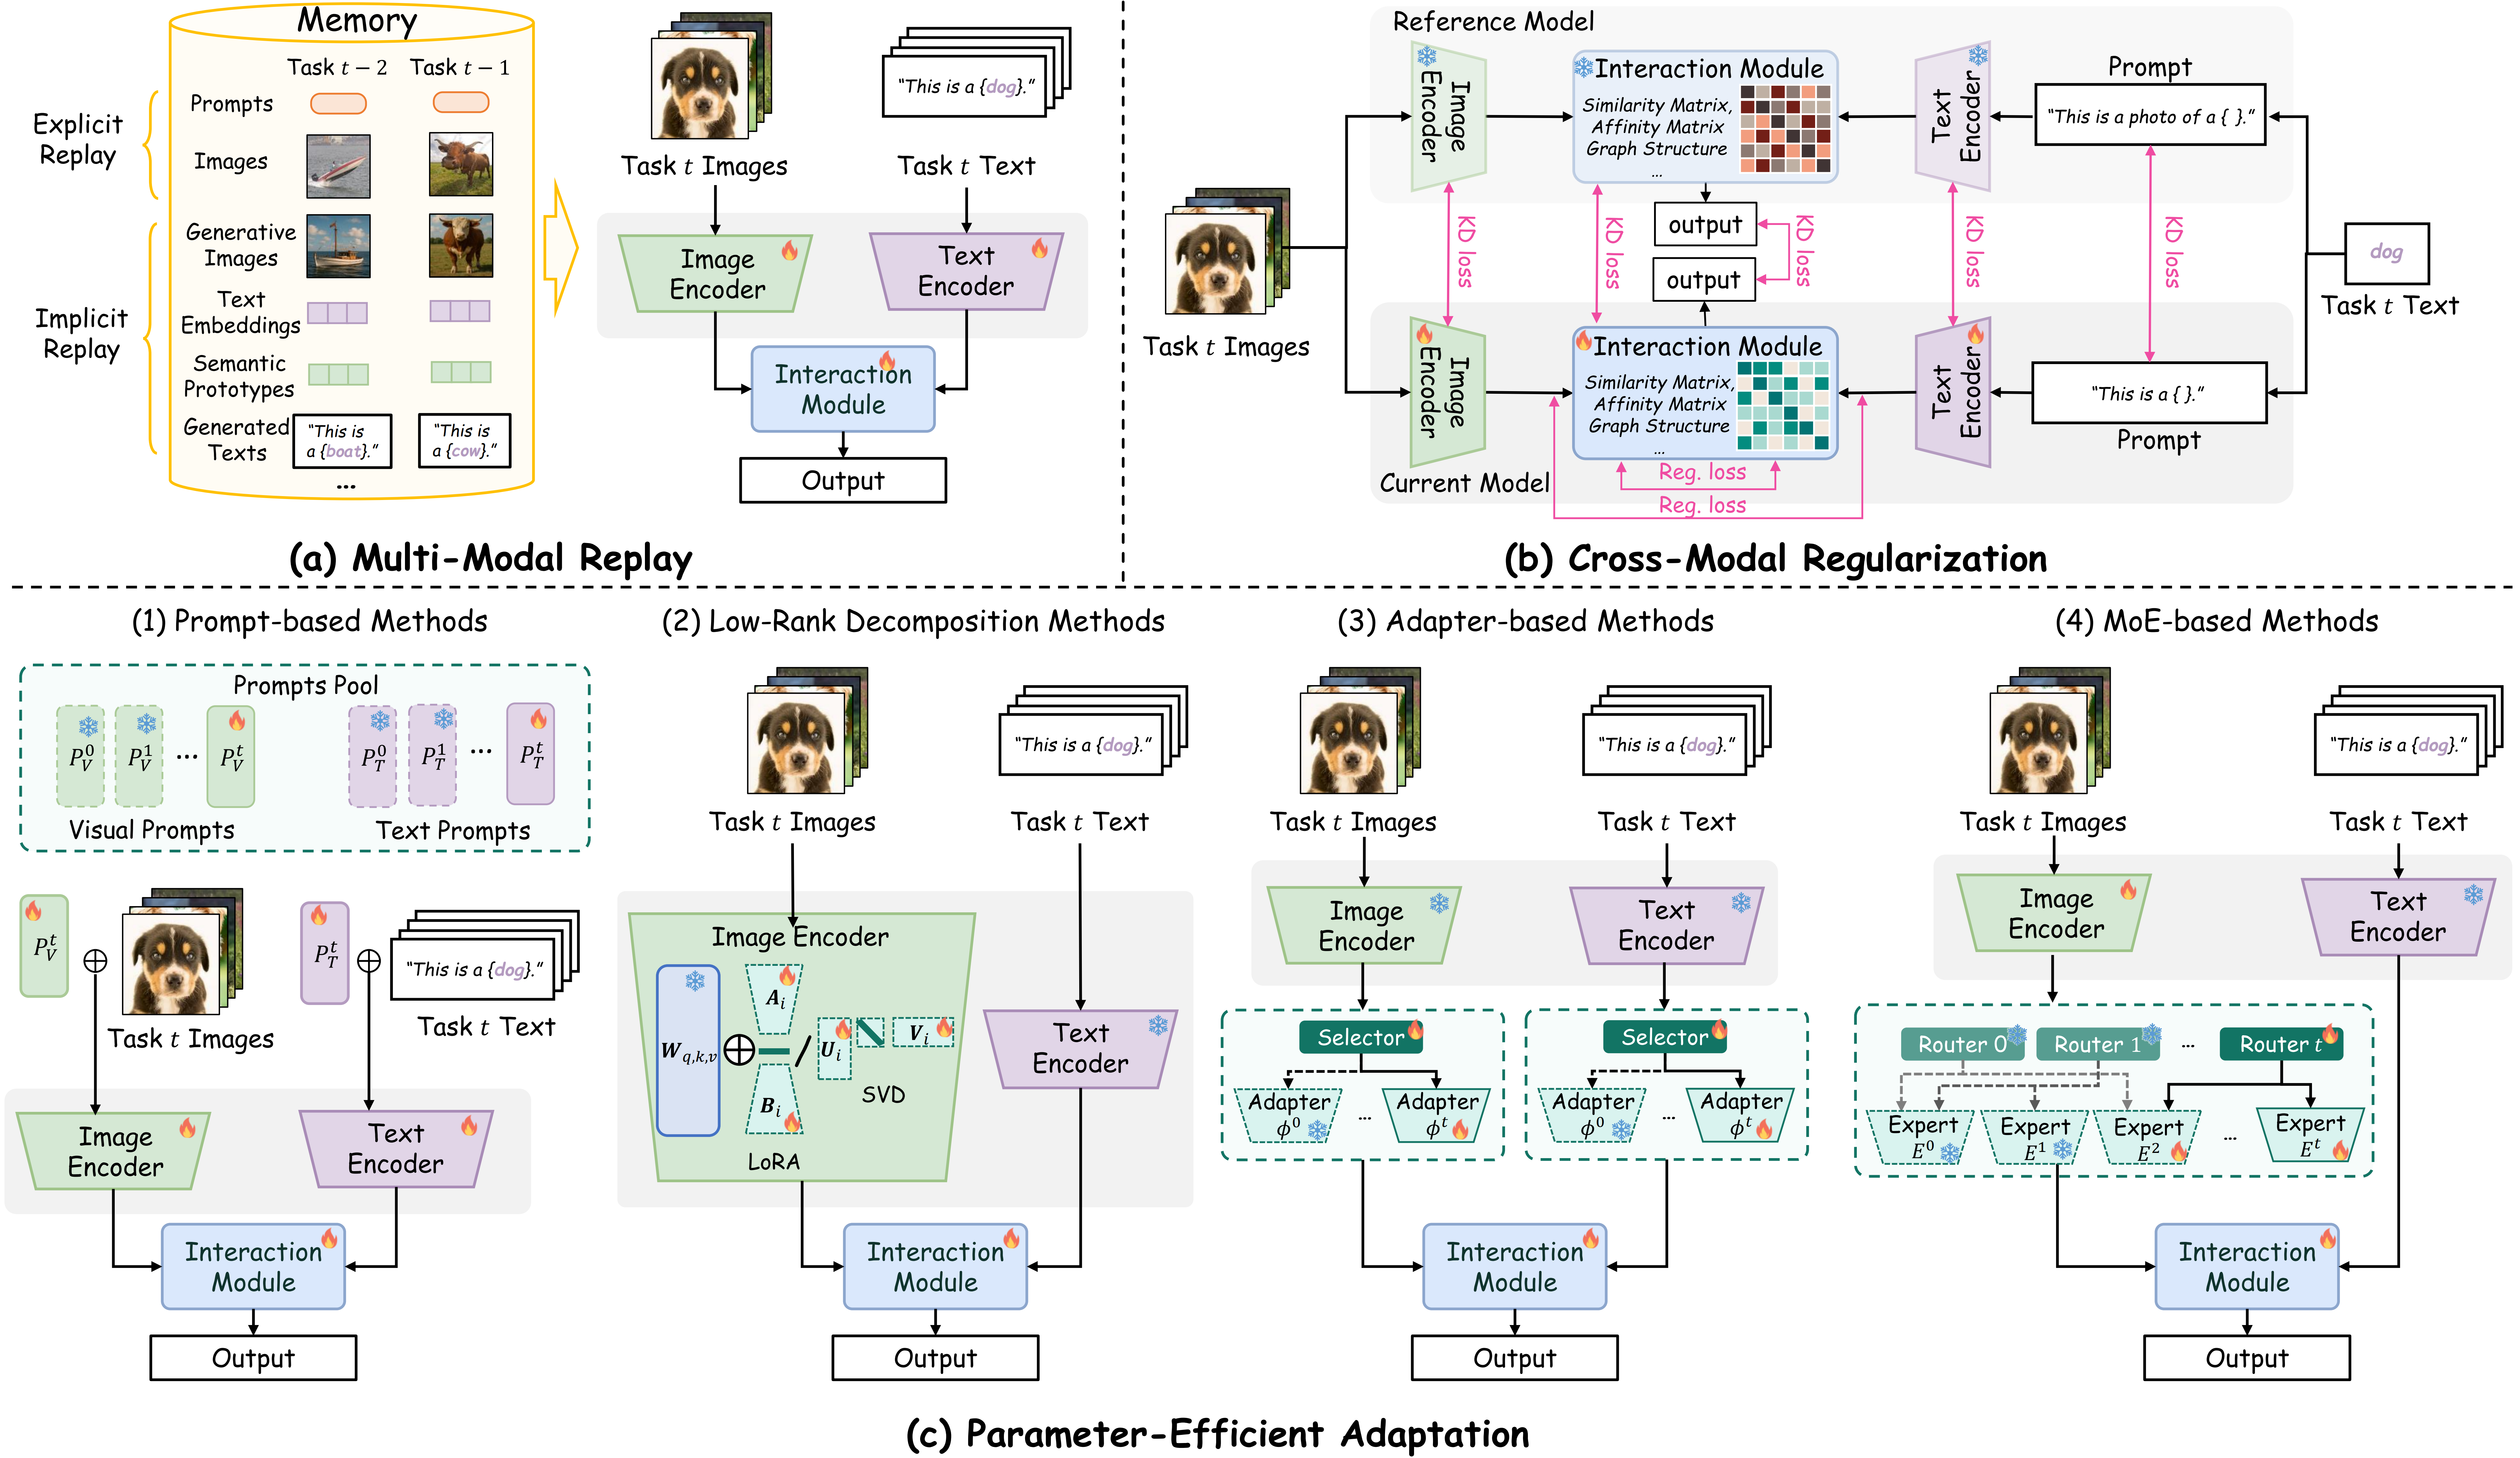
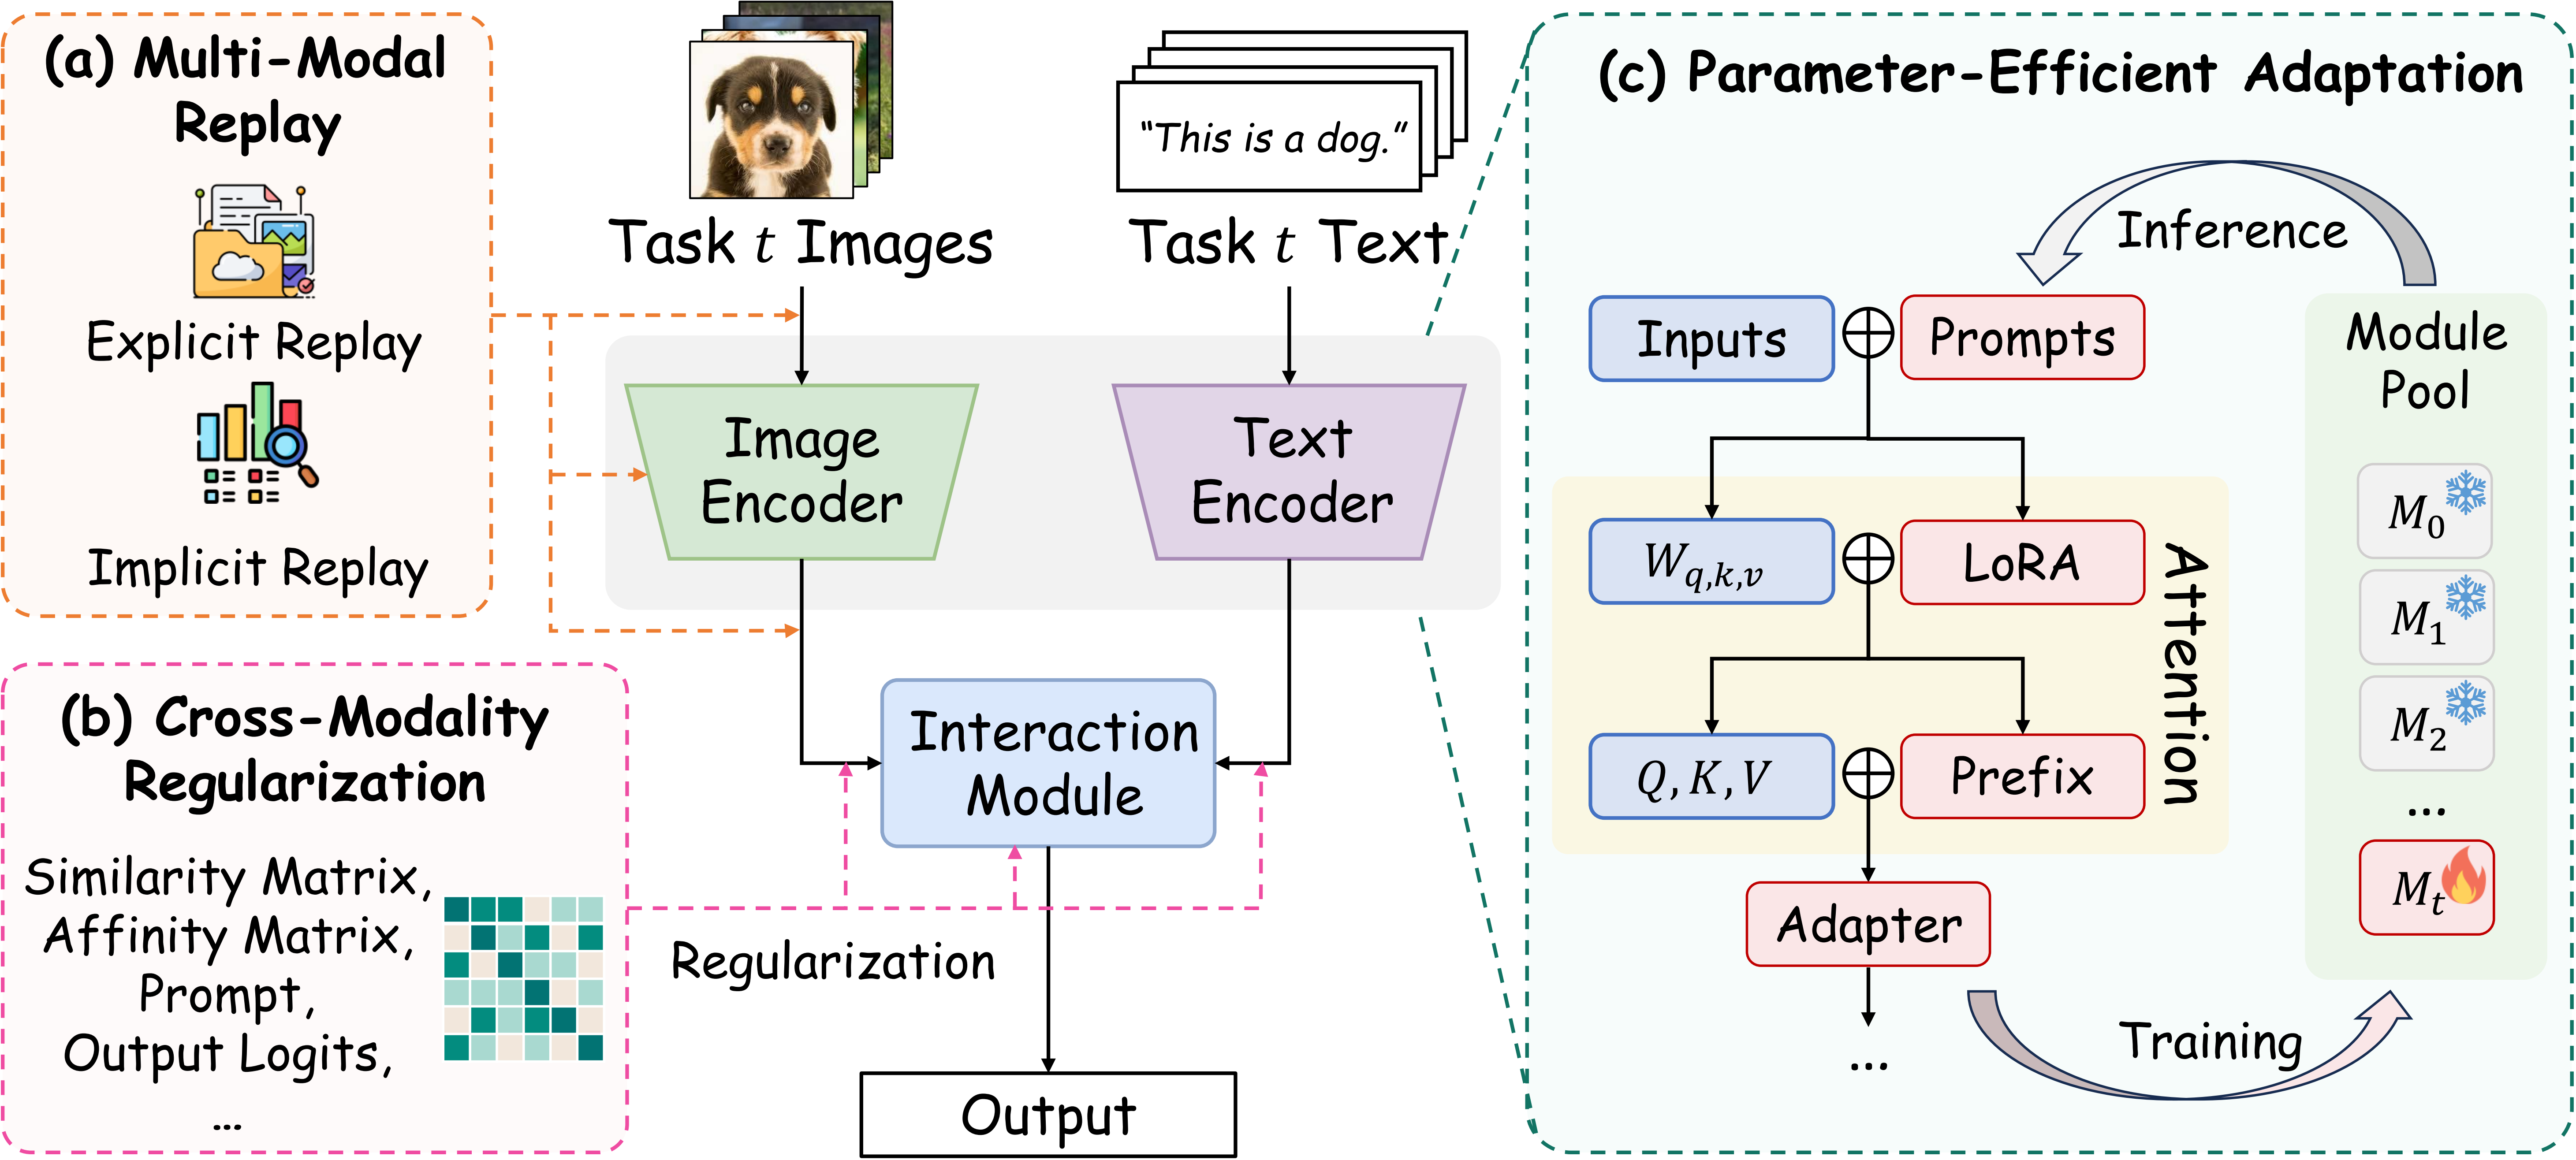
Based on these challenges, we propose a solution-driven taxonomy to categorize existing methods, which forms the structure for the paper list below. This repository serves as a community-driven hub for tracking state-of-the-art methods, datasets, and fostering collaboration.
- 🧠 Multi-Modal Replay (MMRE): Strategies that mitigate forgetting by revisiting previous knowledge, either through explicit data storage or implicit generation.
- ⚙️ Cross-Modal Regularization (CREG): Strategies that preserve alignment by imposing constraints on the model's loss function or update process, often using knowledge distillation or by directly regularizing the feature space.
- 🛠️ Parameter-Efficient Adaptation (PEA): Strategies that freeze the main pre-trained model and update only a small number of parameters using prompts, adapters, or low-rank updates to isolate task-specific knowledge.
📄 Papers
Sorted chronologically (newest first).
2026
- (ICML) Mixing Expertise with Confidence: A Mixture of Experts Framework for Robust Multi-Modal Continual Learning. [PDF]
- (AAAI) LoRA in LoRA: Towards Parameter-Efficient Architecture Expansion for Continual Visual Instruction Tuning. [PDF]
- (AAAI) Harnessing Textual Semantic Priors for Knowledge Transfer and Refinement in CLIP-Driven Continual Learning. [PDF][CODE]
- (AAAI) Decomposing and Composing: Towards Efficient Vision-Language Continual Learning via Rank-1 Expert Pool in a Single LoRA. [PDF][CODE]
- (AAAI) MacVQA: Adaptive Memory Allocation and Global Noise Filtering for Continual Visual Question Answering. [PDF][CODE]
- (AAAI) Branch, or Layer? Zeroth-Order Optimization for Continual Learning of Vision-Language Models. [PDF]
- (ICLR) Memory-Free Continual Learning with Null Space Adaptation for Zero-Shot Vision-Language Models. [PDF]
- (ICLR) Fine-tuning MLLMs Without Forgetting Is Easier Than You Think. [PDF]
- (ICLR) Adaptive Rank, Reduced Forgetting: Knowledge Retention in Continual Learning Vision-Language Models with Dynamic Rank-Selective LoRA. [PDF][CODE]
- (ICLR) PCLR: Progressively Compressed LoRA for Multimodal Continual Instruction Tuning. [PDF][CODE]
- (CVPR) Forging a Dynamic Memory: Retrieval-Guided Continual Learning for Generalist Medical Foundation Models. [PDF][CODE]
- (CVPR) ϕ-DPO: Fairness Direct Preference Optimization Approach to Continual Learning in Large Multimodal Models. [PDF][CODE]
- (CVPR) CGL: Advancing Continual GUI Learning via Reinforcement Fine-Tuning. [PDF]
- (ICML) KORE: Enhancing Knowledge Injection for Large Multimodal Models via Knowledge-Oriented Controls. [PDF]CODE]
- (arxiv) Neural Sentinel: Unified Vision Language Model (VLM) for License Plate Recognition with Human-in-the-Loop Continual Learning. [PDF]
- (arxiv) Reinforced Curriculum Pre-Alignment for Domain-Adaptive VLMs. [PDF]
- (arxiv) Continual Learning with Vision-Language Models via Semantic-Geometry Preservation. [PDF]
- (arxiv) Continual Vision-Language Learning for Remote Sensing: Benchmarking and Analysis. [PDF][CODE]
- (arxiv) Towards Robust Endogenous Reasoning: Unifying Drift Adaptation in Non-Stationary Tuning. [PDF]
- (arxiv) Hidden Forgetting in Continual Multimodal Learning: When Accuracy Survives but Grounding Fails. [PDF]
2025
- (ACL) HiDe-LLaVA: Hierarchical Decoupling for Continual Instruction Tuning of Multimodal Large Language Model. [PDF][CODE]
- (ACL) Enhancing Multimodal Continual Instruction Tuning with BranchLoRA. [PDF][CODE]
- (ICCV) External Knowledge Injection for CLIP-Based Class-Incremental Learning. [PDF][CODE]
- (ICCV) Mind the Gap: Preserving and Compensating for the Modality Gap in CLIP-Based Continual Learning. [PDF][CODE]
- (ICCV) DMNSP: Dynamic Multi-Layer Null Space Projection for Vision-Language Continual Learning. [PDF][CODE]
- (ICCV) SMoLoRA: Exploring and Defying Dual Catastrophic Forgetting in Continual Visual Instruction Tuning. [PDF][CODE]
- (ICCV) Instruction-Grounded Visual Projectors for Continual Learning of Generative Vision-Language Models. [PDF]
- (ICML) LADA: Scalable Label-Specific CLIP Adapter for Continual Learning. [PDF][CODE]
- (ICML) SEFE: Superficial and Essential Forgetting Eliminator for Multimodal Continual Instruction Tuning. [PDF][CODE]
- (ICML) Dynamic Mixture of Curriculum LoRA Experts for Continual Multimodal Instruction Tuning. [PDF][CODE]
- (ICLR) C-CLIP: Multimodal Continual Learning for Vision-Language Model. [PDF][CODE]
- (CVPR) Synthetic Data is an Elegant GIFT for Continual Vision-Language Models. [PDF][CODE]
- (CVPR) Language Guided Concept Bottleneck Models for Interpretable Continual Learning. [PDF][CODE]
- (CVPR) CL-MoE: Enhancing Multimodal Large Language Model with Dual Momentum Mixture-of-Experts for Continual Visual Question Answering. [PDF][CODE]
- (EMNLP) ModalPrompt: Towards Efficient Multimodal Continual Instruction Tuning with Dual-Modality Guided Prompt. [PDF][CODE]
- (TPAMI) Learning without Forgetting for Vision-Language Models. [PDF][CODE]
- (TMM) Visual Class Incremental Learning with Textual Priors Guidance based on an Adapted Vision-Language Model. [PDF][CODE]
- (ECML-PKDD) ChordPrompt: Orchestrating Cross-Modal Prompt Synergy for Multi-Domain Incremental Learning in CLIP. [PDF] [[CODE] (https://github.com/XiaoAI1989/ChordPrompt)]
- (TMLR) Continual Learning on CLIP via Incremental Prompt Tuning with Intrinsic Textual Anchors. [PDF][CODE]
- (TMLR) Efficient Few-Shot Continual Learning in Vision-Language Models. [PDF]
- (EMNLP Findings) Mitigating Visual Knowledge Forgetting in MLLM Instruction-tuning via Modality-decoupled Gradient Descent. [PDF]
- (ACL Findings) Progressive LoRA for Multimodal Continual Instruction Tuning. [PDF][CODE]
- (arXiv) No Images, No Problem: Retaining Knowledge in Continual VQA with Questions-Only Memory. [PDF][CODE]
- (arxiv) LVP-CLIP: Revisiting CLIP for Continual Learning with Label Vector Pool. [PDF]
- (arxiv) MLLM-CL: Continual Learning for Multimodal Large Language Models. [PDF][CODE]
- (arXiv) GNSP: Gradient Null Space Projection for Preserving Cross-Modal Alignment in VLMs Continual Learning. [PDF][CODE]
- (arxiv) Hierarchical Representation Matching for CLIP-based Class-Incremental Learning. [PDF]
- (arxiv) Hierarchical Semantic Tree Anchoring for CLIP-Based Class-Incremental Learning. [PDF]
- (arxiv) BOFA: Bridge-Layer Orthogonal Low-Rank Fusion for CLIP-Based Class-Incremental Learning. [PDF]
- (arxiv) Preserving Cross-Modal Consistency for CLIP-based Class-Incremental Learning. [PDF]
- (arxiv) Representation Calibration and Uncertainty Guidance for Class-Incremental Learning based on Vision Language Model. [PDF]
- (arxiv) Prompt-Based Continual Compositional Zero-Shot Learning. [PDF]
- (arxiv) Beyond CLIP Generalization: Against Forward&Backward Forgetting Adapter for Continual Learning of Vision-Language Models. [PDF]
- (arxiv) CalFuse: Multi-Modal Continual Learning via Feature Calibration and Parameter Fusion. [PDF]
- (arxiv) Routing-Based Continual Learning for Multimodal Large Language Models. [PDF]
2024
- (TMLR) Continual Learning in Open-vocabulary Classification with Complementary Memory Systems. [PDF]
- (ICLR) TiC-CLIP: Continual Training of CLIP Models.[PDF][CODE]
- (arxiv) A Practitioner’s Guide to Continual Multimodal Pretraining. [PDF][CODE]
- (CVPR) Generative Multi-modal Models are Good Class-Incremental Learners. [PDF][CODE]
- (CVPR) Pre-trained Vision and Language Transformers Are Few-Shot Incremental Learners. [PDF][CODE]
- (arxiv) Boosting Open-Domain Continual Learning via Leveraging Intra-domain Category-aware Prototype. [PDF]
- (AAAI) Embracing Language Inclusivity and Diversity in CLIP through Continual Language Learning.[PDF][CODE]
- (AAAI) Continual Vision-Language Retrieval via Dynamic Knowledge Rectification. [PDF]
- (AAAI) Learning Task-Aware Language-Image Representation for Class-Incremental Object Detection. [PDF]
- (AAAI) GCD: Advancing Vision-Language Models for Incremental Object Detection via Global Alignment and Correspondence Distillation [PDF]
- (ECCV) Anytime Continual Learning for Open Vocabulary Classification. [PDF] [CODE]
- (ECCV) MagMax: Leveraging Model Merging for Seamless Continual Learning. [PDF] [CODE]
- (ECCV) Mind the Interference: Retaining Pre-trained Knowledge in Parameter Efficient Continual Learning of Vision-Language Models (DIKI). [PDF] [CODE]
- (ECCV) Adapt without Forgetting: Distill Proximity from Dual Teachers in Vision-Language Models. [PDF]
- (ECCV) Select and Distill: Selective Dual-Teacher Knowledge Transfer for Continual Learning on Vision-Language Models. [PDF]
- (ECCV) Class-Incremental Learning with CLIP: Adaptive Representation Adjustment and Parameter Fusion. [PDF] [CODE]
- (NeurIPS) Advancing Cross-domain Discriminability in Continual Learning of Vision-Language Models (RAIL). [PDF][CODE]
- (NeurIPS) CLAP4CLIP: Continual Learning with Probabilistic Finetuning for Vision-Language Models. [PDF][CODE]
- (ACM MM) Low-rank Prompt Interaction for Continual Vision-language Retrieval. [PDF][CODE]
- (ACM MM) Calibrating Prompt from History for Continual Vision-Language Retrieval and Grounding. [PDF]
- (IJCAI) Continual Multimodal Knowledge Graph Construction. [PDF] [CODE]
- (TCSVT) Continual Learning of Image Classes with Language Guidance from a Vision-Language Model. [PDF][CODE]
- (arXiv) CoLeCLIP: Open-Domain Continual Learning via Joint Task Prompt and Vocabulary Learning. [PDF]
- (arXiv) LW2G: Learning Whether to Grow for Prompt-based Continual Learning. [PDF][CODE]
- (arXiv) ATLAS: Adapter-Based Multi-Modal Continual Learning with a Two-Stage Learning Strategy. [PDF][CODE]
- (arxiv) Exploiting the Semantic Knowledge of Pre-trained Text-Encoders for Continual Learning. [PDF]
- (arxiv) CLIP model is an Efficient Online Lifelong Learner. [PDF]
2023
- (AAAI) Symbolic Replay: Scene Graph as Prompt for Continual Learning on VQA Task. [PDF] [CODE]
- (CVPR) Preventing Zero-Shot Transfer Degradation in Continual Learning of Vision-Language Models (ZSCL). [PDF] [CODE]
- (CVPR) Boosting Continual Learning of Vision-Language Models via Mixture-of-Experts Adapters. [PDF] [CODE]
- (CVPR) VQACL: A Novel Visual Question Answering Continual Learning Setting. [PDF] [CODE]
- (ICCV) CTP: Towards Vision-Language Continual Pretraining via Compatible Momentum Contrast and Topology Preservation [PDF] [CODE]
- (ICCV) Decouple Before Interact: Multi-Modal Prompt Learning for Continual Visual Question Answering [PDF]
- (ICCVW) Multimodal Parameter-Efficient Few-Shot Class Incremental Learning. [PDF]
- (ICML) Continual vision-language representation learning with off-diagonal information. [PDF] [CODE]
- (ACM MM) Multi-Domain Lifelong Visual Question Answering via Self-Critical Distillation. [PDF]
- (arXiv) Class Incremental Learning with Pre-trained Vision-Language Models. [PDF]
2022
- (Neurips) S-Prompts Learning with Pre-trained Transformers: An Occam’s Razor for Domain Incremental Learning. [PDF] [CODE]
- (Neurips) Climb: A continual learning benchmark for vision-and-language tasks. [PDF] [CODE]
- (ECCV) Generative Negative Text Replay for Continual Vision-Language Pretraining. [PDF]
- (arxiv) Continual-CLIP: CLIP is an Efficient Continual Learner. [PDF] [CODE]
🗂️ Datasets & Benchmarks
Evaluating VLM-CL requires specialized benchmarks. As detailed in our survey, the landscape of benchmarks for vision-language continual learning has evolved into three tiers: Repurposed Unimodal, Adapted Multimodal, and Native VLM/MLLM-Specific benchmarks.
The tables below summarize all key datasets used in the literature according to this evolutionary taxonomy.
1. Repurposed Unimodal Benchmarks
Adapted from traditional computer vision datasets. They offer scalability for evaluating catastrophic forgetting, but provide limited insights into cross-modal misalignment.
| Dataset | Task Type | Scenario | Modality | Size | Metrics | Link/Source |
|---|---|---|---|---|---|---|
| CDDB | Classification | DIL | Image | 50K | Accuracy | [Paper] |
| CORe50 | Classification | DIL | Video | 50K | Accuracy | [Paper] |
| DomainNet | Classification | DIL | Image | 600K | Accuracy | [Link] |
| Conceptual12M | Segmentation | CIL / IIL | Image+Text | 12M | IoU, AP | [Paper] |
| ImageNet-100/1K | Classification | CIL / DIL | Image | 130K-1.3M | Accuracy | [Link] |
| TinyImageNet | Classification | CIL | Image | 100K | Accuracy | [Paper] |
| CIFAR100 | Classification | CIL | Image | 60K | Accuracy | [Link] |
| CUB200 | Classification | CIL | Image | 11.7K | Accuracy | [Link] |
| CLEAR-10/100 | Classification | CIL / DIL | Image | 4.3M-18.6M | Accuracy | [Homepage] |
| ADE20K-CL | Segmentation | CIL | Image+Annotations | 25K | IoU | [Link] |
2. Adapted Multimodal Benchmarks
Reconfigured from existing multimodal datasets. These preserve cross-modal interactions while introducing continual learning protocols.
| Dataset | Task Type | Scenario | Modality | Size | Metrics | Link/Source |
|---|---|---|---|---|---|---|
| MDL-VQA | VQA | DIL | Image+Text | 150K | Accuracy | [Paper] |
| P9D | Retrieval | DIL / TIL | Image+Text | 1M+ | AP | [Paper] |
| Flickr30K | Retrieval | CIL | Image+Annotations | 30K | Accuracy | [Link] |
| ECommerce-T2I | Retrieval | CIL | Image+Annotations | 15K | Accuracy | [Paper] |
| NExT-QA | VQA | TIL | Videos+Text | 52K | AP | [GitHub] |
3. VLM/MLLM-Specific Benchmarks
Explicitly designed to address cross-modal forgetting pathologies, zero-shot decay, compositional transfer, and instruction-tuning alignment.
| Dataset | Task Type | Scenario | Modality | Size | Metrics | Link/Source |
|---|---|---|---|---|---|---|
| CLiMB | VQA | TIL | Image+Text | 1.1M | Accuracy, F1 | [GitHub] |
| VQACL | VQA | TIL / DIL | Image+Text | 100K | Accuracy | [GitHub] |
| COCO-CL | Seg. / Ret. | CIL | Image+Annotations | 200K+ | AP, IoU, Acc. | [Paper] |
| TiC | Ret. / Class. | Time-IL | Image+Text | 127M/1B/12B | Acc., Recall | [Paper] |
| CoIN | VQA | TIL | Image+Text | 740K | Accuracy | [Paper] |
| UCIT | VQA | TIL | Image+Text | 231K | Accuracy | [Paper] |
| MLLM-CL | VQA | DIL / AIL | Image+Text | 392.7K/925K | Accuracy | [Paper] |
| MLLM-CTBench | VQA | TIL | Image+Text | 70K | Accuracy | [Paper] |
| CLeaRS | VQA | DIL / TIL | Image+Text | 207K | Accuracy | [GitHub] |
| ToS | VQA/Cap. | DIL | Image+Text | 935K | Accuracy | [Paper] |
| MTIL | Classification | TIL / CIL | Image | 438.3K | Accuracy | [Paper] |
| VTAB | Classification | CIL | Image | 10K | Accuracy | [Paper] |
| CLOVE | VQA | DIL / TIL | Image+Text | N/A | Accuracy | [Paper] |
| OMNI | Classification | CIL | Image | 1M+ | Accuracy | [Paper] |
| IMRE | RE | TIL | Image+Text | 9K | F1 | [GitHub] |
| IMNER | NER | TIL | Image+Text | 8.5K | F1 | [GitHub] |
Notes on CL Scenarios:
- CIL (Class-Incremental Learning): New classes are added in sequential tasks.
- TIL (Task-Incremental Learning): Tasks are distinct, and the task identity is known at inference time.
- DIL (Domain-Incremental Learning): The data distribution shifts across tasks (e.g., photos to sketches), but the task itself remains the same.
- IIL (Instance-Incremental Learning): New training instances of previously seen classes appear over time.
- AIL (Ability-Incremental Learning): The model sequentially acquires new capabilities or skills.
- Time-IL (Time-Incremental Learning): Data arrives chronologically, simulating real-world temporal distribution shifts.
📊 Evaluation Metrics
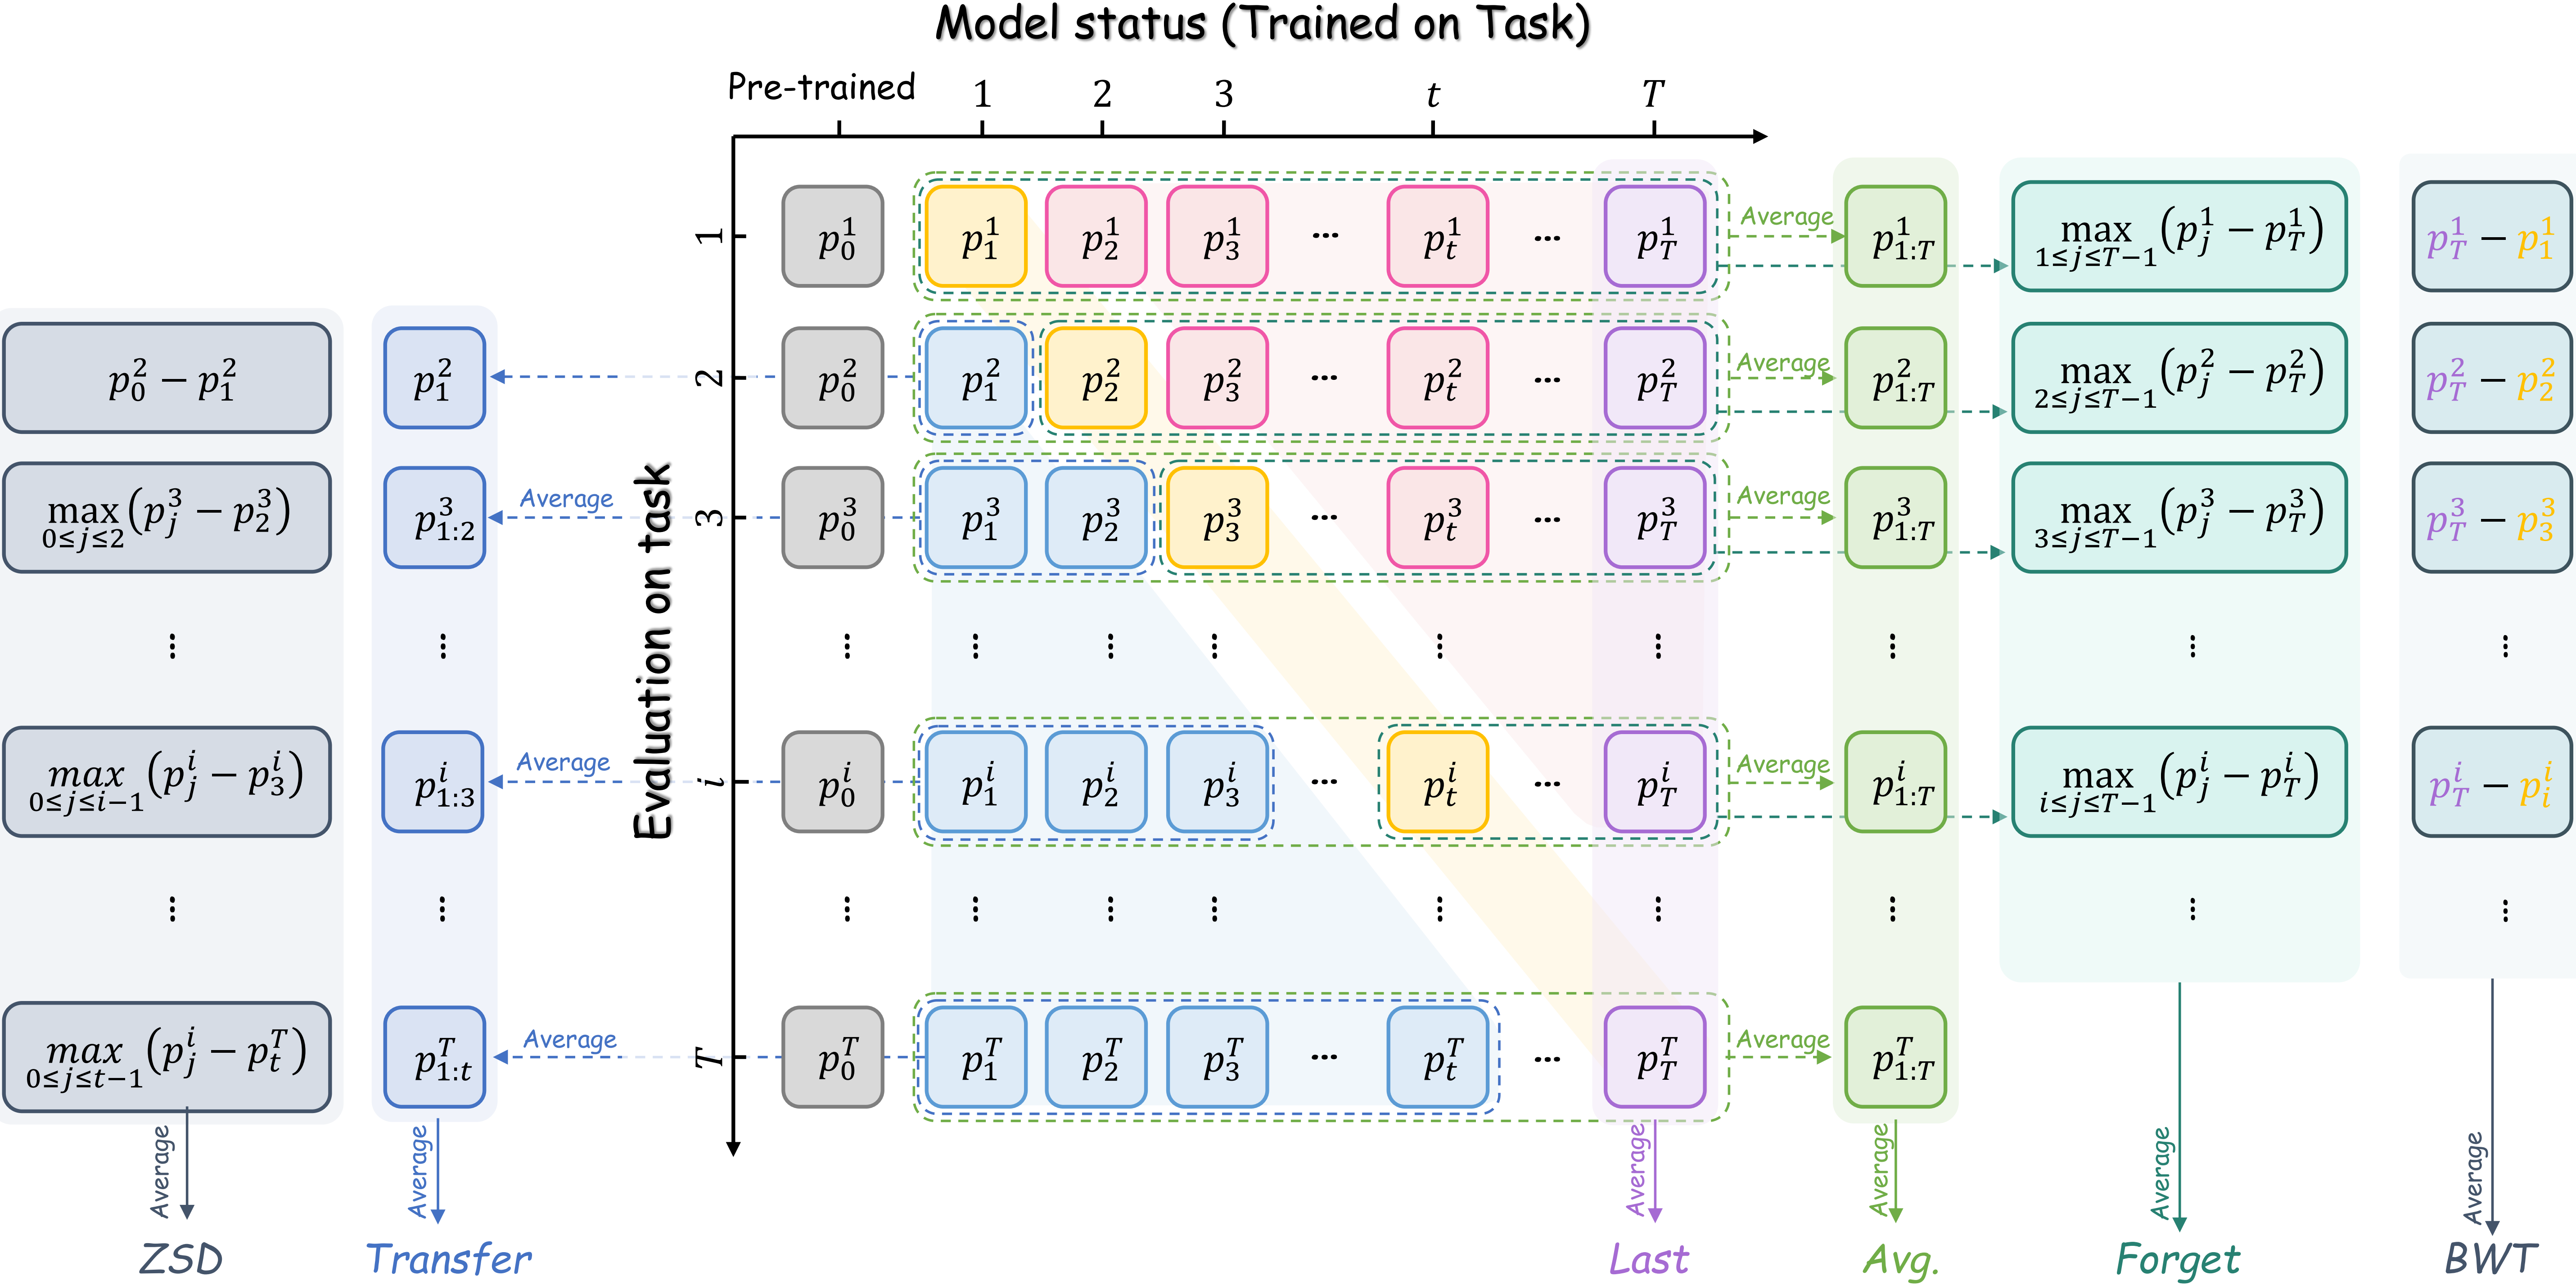
Evaluating CL in VLMs necessitates a multifaceted approach that addresses both traditional CL desiderata and VLM-specific challenges (e.g., zero-shot generalization and cross-modal alignment). Key metrics discussed in our survey include:
- Average & Last Accuracy: Measures the mean task performance over all learning stages and the retained competence after full training.
- Forgetting Ratio & Backward Transfer (BWT): Quantifies the maximum performance drop per task post-initial learning, or improvements induced by later learning.
- Zero-Shot Transfer & Zero-Shot Degradation (ZSD): Explicitly evaluates the model's generalization to unseen tasks and measures the erosion of pre-acquired open-vocabulary capabilities.
- Modality-Specific Metrics: Utilizing Recall@K, mAP, and Answer Precision (AP) for Retrieval and VQA to diagnose asymmetric modality degradation.
Regarding the detailed computation of these evaluation metrics, we provide a clear and intuitive diagram (as shown below) in the paper for comprehensive explanation.
🚀 Future Directions
Based on the gaps and trends identified in our survey, we propose several key directions for future research:
-
📊 Unified and Holistic Benchmarking: Moving beyond simple classification accuracy to incorporate compositional zero-shot evaluation and temporal, web-scale data streams.
-
💬 Continual Learning for Generative and Interactive Tasks: Enabling multimodal chatbots and agents to continually learn from human feedback and long-term memory without losing alignment.
-
🤖 Continual Learning for Vision-Language-Action (VLA) Models: Transitioning to Embodied AI where cross-modal feature drift precipitates cascading physical failures, requiring skill-compositional strategies.
-
📐 Towards a Theoretical Understanding: Developing mathematical models for cross-modal feature drift and theoretical bounds for Parameter-Efficient Adaptation.
Star History
🤝 How to Contribute
We welcome contributions! If you have a paper, dataset, or codebase that should be on this list, please open a Pull Request.
- Fork the repository.
- Add your resource to the appropriate section in
README.md. Please maintain the existing format. - Submit a pull request with a clear title and description.
🌟 Related Resources
🛠️ Maintenance
- Maintainers: Yuyang Liu, Qiuhe Hong, Linlan Huang, Alexandra Gomez-Villa, and Dipam Goswami.
- Contact: sunshineliuyuyang@gmail.com
- Star the repo to show your support! ⭐
Acknowledgments: This repository builds on the incredible efforts of the open-source research community.
Contributors


Similar repos


Awsome of VLM-CL. Continual Learning for VLMs: A Survey and Taxonomy Beyond Forgetting
221
93 commits
updated Sep 4, 2026
README
Awesome Continual Learning for Vision-Language Models & MLLMs
A curated list of papers, codebases, and datasets for continual learning in vision-language models (VLMs) and Multimodal Large Language Models (MLLMs), accompanying our survey paper. Last updated: 2026-08
📑 Table of Contents
- Latest News
- Citing Our Work
- Overview & Challenges
- Taxonomy
- 🏆 Mini Leaderboard (SOTA Performance)
- 📄 Papers
- 🗂️ Datasets & Benchmarks
- 🚀 Future Directions
🔥 Latest News
- [2026.08] Our survey paper, “Continual Learning for VLMs: A Survey and Taxonomy Beyond Forgetting” (v3), is now available on arXiv.
- [2026.03] We have updated the repository with a new collection of recent papers and resources to reflect the latest advances in VLM continual learning.
- [Ongoing] This repository is under active maintenance and will be continuously updated with newly released papers, code, and benchmarks from the community.
📣 Citing Our Work
If you find this repository or our survey useful for your research, please consider citing our work:
@article{liu2026continual,
  title={Continual Learning for VLMs: A Survey and Taxonomy Beyond Forgetting},
  author={Liu, Yuyang and Hong, Qiuhe and Huang, Linlan and Gomez-Villa, Alexandra and Goswami, Dipam and Liu, Xialei and van de Weijer, Joost and Tian, Yonghong},
  journal={arXiv preprint arXiv:2508.04227},
  year={2026}
}
📜 Overview
Vision-language models (VLMs) like CLIP have achieved remarkable success, but adapting them to evolving data streams without catastrophic forgetting is a critical challenge. This repository provides a systematic review of research on continual learning for VLMs (VLM-CL).
Our survey identifies three core failure modes in VLM-CL:
- 🧠 Cross-Modal Feature Drift: The degradation of alignment between visual and textual feature spaces during updates.
- ⚙️ Shared Module Interference: Destructive weight updates in shared components like cross-attention layers, which is common in fusion-based models.
- 📉 Zero-Shot Capability Erosion: The loss of generalization to unseen tasks after the model is fine-tuned on specific downstream tasks.
Based on these challenges, we propose a solution-driven taxonomy to categorize existing methods, which forms the structure for the paper list below. This repository serves as a community-driven hub for tracking state-of-the-art methods, datasets, and fostering collaboration.
- 🧠 Multi-Modal Replay (MMRE): Strategies that mitigate forgetting by revisiting previous knowledge, either through explicit data storage or implicit generation.
- ⚙️ Cross-Modal Regularization (CREG): Strategies that preserve alignment by imposing constraints on the model's loss function or update process, often using knowledge distillation or by directly regularizing the feature space.
- 🛠️ Parameter-Efficient Adaptation (PEA): Strategies that freeze the main pre-trained model and update only a small number of parameters using prompts, adapters, or low-rank updates to isolate task-specific knowledge.
📄 Papers
Sorted chronologically (newest first).
2026
- (ICML) Mixing Expertise with Confidence: A Mixture of Experts Framework for Robust Multi-Modal Continual Learning. [PDF]
- (AAAI) LoRA in LoRA: Towards Parameter-Efficient Architecture Expansion for Continual Visual Instruction Tuning. [PDF]
- (AAAI) Harnessing Textual Semantic Priors for Knowledge Transfer and Refinement in CLIP-Driven Continual Learning. [PDF][CODE]
- (AAAI) Decomposing and Composing: Towards Efficient Vision-Language Continual Learning via Rank-1 Expert Pool in a Single LoRA. [PDF][CODE]
- (AAAI) MacVQA: Adaptive Memory Allocation and Global Noise Filtering for Continual Visual Question Answering. [PDF][CODE]
- (AAAI) Branch, or Layer? Zeroth-Order Optimization for Continual Learning of Vision-Language Models. [PDF]
- (ICLR) Memory-Free Continual Learning with Null Space Adaptation for Zero-Shot Vision-Language Models. [PDF]
- (ICLR) Fine-tuning MLLMs Without Forgetting Is Easier Than You Think. [PDF]
- (ICLR) Adaptive Rank, Reduced Forgetting: Knowledge Retention in Continual Learning Vision-Language Models with Dynamic Rank-Selective LoRA. [PDF][CODE]
- (ICLR) PCLR: Progressively Compressed LoRA for Multimodal Continual Instruction Tuning. [PDF][CODE]
- (CVPR) Forging a Dynamic Memory: Retrieval-Guided Continual Learning for Generalist Medical Foundation Models. [PDF][CODE]
- (CVPR) ϕ-DPO: Fairness Direct Preference Optimization Approach to Continual Learning in Large Multimodal Models. [PDF][CODE]
- (CVPR) CGL: Advancing Continual GUI Learning via Reinforcement Fine-Tuning. [PDF]
- (ICML) KORE: Enhancing Knowledge Injection for Large Multimodal Models via Knowledge-Oriented Controls. [PDF]CODE]
- (arxiv) Neural Sentinel: Unified Vision Language Model (VLM) for License Plate Recognition with Human-in-the-Loop Continual Learning. [PDF]
- (arxiv) Reinforced Curriculum Pre-Alignment for Domain-Adaptive VLMs. [PDF]
- (arxiv) Continual Learning with Vision-Language Models via Semantic-Geometry Preservation. [PDF]
- (arxiv) Continual Vision-Language Learning for Remote Sensing: Benchmarking and Analysis. [PDF][CODE]
- (arxiv) Towards Robust Endogenous Reasoning: Unifying Drift Adaptation in Non-Stationary Tuning. [PDF]
- (arxiv) Hidden Forgetting in Continual Multimodal Learning: When Accuracy Survives but Grounding Fails. [PDF]
2025
- (ACL) HiDe-LLaVA: Hierarchical Decoupling for Continual Instruction Tuning of Multimodal Large Language Model. [PDF][CODE]
- (ACL) Enhancing Multimodal Continual Instruction Tuning with BranchLoRA. [PDF][CODE]
- (ICCV) External Knowledge Injection for CLIP-Based Class-Incremental Learning. [PDF][CODE]
- (ICCV) Mind the Gap: Preserving and Compensating for the Modality Gap in CLIP-Based Continual Learning. [PDF][CODE]
- (ICCV) DMNSP: Dynamic Multi-Layer Null Space Projection for Vision-Language Continual Learning. [PDF][CODE]
- (ICCV) SMoLoRA: Exploring and Defying Dual Catastrophic Forgetting in Continual Visual Instruction Tuning. [PDF][CODE]
- (ICCV) Instruction-Grounded Visual Projectors for Continual Learning of Generative Vision-Language Models. [PDF]
- (ICML) LADA: Scalable Label-Specific CLIP Adapter for Continual Learning. [PDF][CODE]
- (ICML) SEFE: Superficial and Essential Forgetting Eliminator for Multimodal Continual Instruction Tuning. [PDF][CODE]
- (ICML) Dynamic Mixture of Curriculum LoRA Experts for Continual Multimodal Instruction Tuning. [PDF][CODE]
- (ICLR) C-CLIP: Multimodal Continual Learning for Vision-Language Model. [PDF][CODE]
- (CVPR) Synthetic Data is an Elegant GIFT for Continual Vision-Language Models. [PDF][CODE]
- (CVPR) Language Guided Concept Bottleneck Models for Interpretable Continual Learning. [PDF][CODE]
- (CVPR) CL-MoE: Enhancing Multimodal Large Language Model with Dual Momentum Mixture-of-Experts for Continual Visual Question Answering. [PDF][CODE]
- (EMNLP) ModalPrompt: Towards Efficient Multimodal Continual Instruction Tuning with Dual-Modality Guided Prompt. [PDF][CODE]
- (TPAMI) Learning without Forgetting for Vision-Language Models. [PDF][CODE]
- (TMM) Visual Class Incremental Learning with Textual Priors Guidance based on an Adapted Vision-Language Model. [PDF][CODE]
- (ECML-PKDD) ChordPrompt: Orchestrating Cross-Modal Prompt Synergy for Multi-Domain Incremental Learning in CLIP. [PDF] [[CODE] (https://github.com/XiaoAI1989/ChordPrompt)]
- (TMLR) Continual Learning on CLIP via Incremental Prompt Tuning with Intrinsic Textual Anchors. [PDF][CODE]
- (TMLR) Efficient Few-Shot Continual Learning in Vision-Language Models. [PDF]
- (EMNLP Findings) Mitigating Visual Knowledge Forgetting in MLLM Instruction-tuning via Modality-decoupled Gradient Descent. [PDF]
- (ACL Findings) Progressive LoRA for Multimodal Continual Instruction Tuning. [PDF][CODE]
- (arXiv) No Images, No Problem: Retaining Knowledge in Continual VQA with Questions-Only Memory. [PDF][CODE]
- (arxiv) LVP-CLIP: Revisiting CLIP for Continual Learning with Label Vector Pool. [PDF]
- (arxiv) MLLM-CL: Continual Learning for Multimodal Large Language Models. [PDF][CODE]
- (arXiv) GNSP: Gradient Null Space Projection for Preserving Cross-Modal Alignment in VLMs Continual Learning. [PDF][CODE]
- (arxiv) Hierarchical Representation Matching for CLIP-based Class-Incremental Learning. [PDF]
- (arxiv) Hierarchical Semantic Tree Anchoring for CLIP-Based Class-Incremental Learning. [PDF]
- (arxiv) BOFA: Bridge-Layer Orthogonal Low-Rank Fusion for CLIP-Based Class-Incremental Learning. [PDF]
- (arxiv) Preserving Cross-Modal Consistency for CLIP-based Class-Incremental Learning. [PDF]
- (arxiv) Representation Calibration and Uncertainty Guidance for Class-Incremental Learning based on Vision Language Model. [PDF]
- (arxiv) Prompt-Based Continual Compositional Zero-Shot Learning. [PDF]
- (arxiv) Beyond CLIP Generalization: Against Forward&Backward Forgetting Adapter for Continual Learning of Vision-Language Models. [PDF]
- (arxiv) CalFuse: Multi-Modal Continual Learning via Feature Calibration and Parameter Fusion. [PDF]
- (arxiv) Routing-Based Continual Learning for Multimodal Large Language Models. [PDF]
2024
- (TMLR) Continual Learning in Open-vocabulary Classification with Complementary Memory Systems. [PDF]
- (ICLR) TiC-CLIP: Continual Training of CLIP Models.[PDF][CODE]
- (arxiv) A Practitioner’s Guide to Continual Multimodal Pretraining. [PDF][CODE]
- (CVPR) Generative Multi-modal Models are Good Class-Incremental Learners. [PDF][CODE]
- (CVPR) Pre-trained Vision and Language Transformers Are Few-Shot Incremental Learners. [PDF][CODE]
- (arxiv) Boosting Open-Domain Continual Learning via Leveraging Intra-domain Category-aware Prototype. [PDF]
- (AAAI) Embracing Language Inclusivity and Diversity in CLIP through Continual Language Learning.[PDF][CODE]
- (AAAI) Continual Vision-Language Retrieval via Dynamic Knowledge Rectification. [PDF]
- (AAAI) Learning Task-Aware Language-Image Representation for Class-Incremental Object Detection. [PDF]
- (AAAI) GCD: Advancing Vision-Language Models for Incremental Object Detection via Global Alignment and Correspondence Distillation [PDF]
- (ECCV) Anytime Continual Learning for Open Vocabulary Classification. [PDF] [CODE]
- (ECCV) MagMax: Leveraging Model Merging for Seamless Continual Learning. [PDF] [CODE]
- (ECCV) Mind the Interference: Retaining Pre-trained Knowledge in Parameter Efficient Continual Learning of Vision-Language Models (DIKI). [PDF] [CODE]
- (ECCV) Adapt without Forgetting: Distill Proximity from Dual Teachers in Vision-Language Models. [PDF]
- (ECCV) Select and Distill: Selective Dual-Teacher Knowledge Transfer for Continual Learning on Vision-Language Models. [PDF]
- (ECCV) Class-Incremental Learning with CLIP: Adaptive Representation Adjustment and Parameter Fusion. [PDF] [CODE]
- (NeurIPS) Advancing Cross-domain Discriminability in Continual Learning of Vision-Language Models (RAIL). [PDF][CODE]
- (NeurIPS) CLAP4CLIP: Continual Learning with Probabilistic Finetuning for Vision-Language Models. [PDF][CODE]
- (ACM MM) Low-rank Prompt Interaction for Continual Vision-language Retrieval. [PDF][CODE]
- (ACM MM) Calibrating Prompt from History for Continual Vision-Language Retrieval and Grounding. [PDF]
- (IJCAI) Continual Multimodal Knowledge Graph Construction. [PDF] [CODE]
- (TCSVT) Continual Learning of Image Classes with Language Guidance from a Vision-Language Model. [PDF][CODE]
- (arXiv) CoLeCLIP: Open-Domain Continual Learning via Joint Task Prompt and Vocabulary Learning. [PDF]
- (arXiv) LW2G: Learning Whether to Grow for Prompt-based Continual Learning. [PDF][CODE]
- (arXiv) ATLAS: Adapter-Based Multi-Modal Continual Learning with a Two-Stage Learning Strategy. [PDF][CODE]
- (arxiv) Exploiting the Semantic Knowledge of Pre-trained Text-Encoders for Continual Learning. [PDF]
- (arxiv) CLIP model is an Efficient Online Lifelong Learner. [PDF]
2023
- (AAAI) Symbolic Replay: Scene Graph as Prompt for Continual Learning on VQA Task. [PDF] [CODE]
- (CVPR) Preventing Zero-Shot Transfer Degradation in Continual Learning of Vision-Language Models (ZSCL). [PDF] [CODE]
- (CVPR) Boosting Continual Learning of Vision-Language Models via Mixture-of-Experts Adapters. [PDF] [CODE]
- (CVPR) VQACL: A Novel Visual Question Answering Continual Learning Setting. [PDF] [CODE]
- (ICCV) CTP: Towards Vision-Language Continual Pretraining via Compatible Momentum Contrast and Topology Preservation [PDF] [CODE]
- (ICCV) Decouple Before Interact: Multi-Modal Prompt Learning for Continual Visual Question Answering [PDF]
- (ICCVW) Multimodal Parameter-Efficient Few-Shot Class Incremental Learning. [PDF]
- (ICML) Continual vision-language representation learning with off-diagonal information. [PDF] [CODE]
- (ACM MM) Multi-Domain Lifelong Visual Question Answering via Self-Critical Distillation. [PDF]
- (arXiv) Class Incremental Learning with Pre-trained Vision-Language Models. [PDF]
2022
- (Neurips) S-Prompts Learning with Pre-trained Transformers: An Occam’s Razor for Domain Incremental Learning. [PDF] [CODE]
- (Neurips) Climb: A continual learning benchmark for vision-and-language tasks. [PDF] [CODE]
- (ECCV) Generative Negative Text Replay for Continual Vision-Language Pretraining. [PDF]
- (arxiv) Continual-CLIP: CLIP is an Efficient Continual Learner. [PDF] [CODE]
🗂️ Datasets & Benchmarks
Evaluating VLM-CL requires specialized benchmarks. As detailed in our survey, the landscape of benchmarks for vision-language continual learning has evolved into three tiers: Repurposed Unimodal, Adapted Multimodal, and Native VLM/MLLM-Specific benchmarks.
The tables below summarize all key datasets used in the literature according to this evolutionary taxonomy.
1. Repurposed Unimodal Benchmarks
Adapted from traditional computer vision datasets. They offer scalability for evaluating catastrophic forgetting, but provide limited insights into cross-modal misalignment.
| Dataset | Task Type | Scenario | Modality | Size | Metrics | Link/Source |
|---|---|---|---|---|---|---|
| CDDB | Classification | DIL | Image | 50K | Accuracy | [Paper] |
| CORe50 | Classification | DIL | Video | 50K | Accuracy | [Paper] |
| DomainNet | Classification | DIL | Image | 600K | Accuracy | [Link] |
| Conceptual12M | Segmentation | CIL / IIL | Image+Text | 12M | IoU, AP | [Paper] |
| ImageNet-100/1K | Classification | CIL / DIL | Image | 130K-1.3M | Accuracy | [Link] |
| TinyImageNet | Classification | CIL | Image | 100K | Accuracy | [Paper] |
| CIFAR100 | Classification | CIL | Image | 60K | Accuracy | [Link] |
| CUB200 | Classification | CIL | Image | 11.7K | Accuracy | [Link] |
| CLEAR-10/100 | Classification | CIL / DIL | Image | 4.3M-18.6M | Accuracy | [Homepage] |
| ADE20K-CL | Segmentation | CIL | Image+Annotations | 25K | IoU | [Link] |
2. Adapted Multimodal Benchmarks
Reconfigured from existing multimodal datasets. These preserve cross-modal interactions while introducing continual learning protocols.
| Dataset | Task Type | Scenario | Modality | Size | Metrics | Link/Source |
|---|---|---|---|---|---|---|
| MDL-VQA | VQA | DIL | Image+Text | 150K | Accuracy | [Paper] |
| P9D | Retrieval | DIL / TIL | Image+Text | 1M+ | AP | [Paper] |
| Flickr30K | Retrieval | CIL | Image+Annotations | 30K | Accuracy | [Link] |
| ECommerce-T2I | Retrieval | CIL | Image+Annotations | 15K | Accuracy | [Paper] |
| NExT-QA | VQA | TIL | Videos+Text | 52K | AP | [GitHub] |
3. VLM/MLLM-Specific Benchmarks
Explicitly designed to address cross-modal forgetting pathologies, zero-shot decay, compositional transfer, and instruction-tuning alignment.
| Dataset | Task Type | Scenario | Modality | Size | Metrics | Link/Source |
|---|---|---|---|---|---|---|
| CLiMB | VQA | TIL | Image+Text | 1.1M | Accuracy, F1 | [GitHub] |
| VQACL | VQA | TIL / DIL | Image+Text | 100K | Accuracy | [GitHub] |
| COCO-CL | Seg. / Ret. | CIL | Image+Annotations | 200K+ | AP, IoU, Acc. | [Paper] |
| TiC | Ret. / Class. | Time-IL | Image+Text | 127M/1B/12B | Acc., Recall | [Paper] |
| CoIN | VQA | TIL | Image+Text | 740K | Accuracy | [Paper] |
| UCIT | VQA | TIL | Image+Text | 231K | Accuracy | [Paper] |
| MLLM-CL | VQA | DIL / AIL | Image+Text | 392.7K/925K | Accuracy | [Paper] |
| MLLM-CTBench | VQA | TIL | Image+Text | 70K | Accuracy | [Paper] |
| CLeaRS | VQA | DIL / TIL | Image+Text | 207K | Accuracy | [GitHub] |
| ToS | VQA/Cap. | DIL | Image+Text | 935K | Accuracy | [Paper] |
| MTIL | Classification | TIL / CIL | Image | 438.3K | Accuracy | [Paper] |
| VTAB | Classification | CIL | Image | 10K | Accuracy | [Paper] |
| CLOVE | VQA | DIL / TIL | Image+Text | N/A | Accuracy | [Paper] |
| OMNI | Classification | CIL | Image | 1M+ | Accuracy | [Paper] |
| IMRE | RE | TIL | Image+Text | 9K | F1 | [GitHub] |
| IMNER | NER | TIL | Image+Text | 8.5K | F1 | [GitHub] |
Notes on CL Scenarios:
- CIL (Class-Incremental Learning): New classes are added in sequential tasks.
- TIL (Task-Incremental Learning): Tasks are distinct, and the task identity is known at inference time.
- DIL (Domain-Incremental Learning): The data distribution shifts across tasks (e.g., photos to sketches), but the task itself remains the same.
- IIL (Instance-Incremental Learning): New training instances of previously seen classes appear over time.
- AIL (Ability-Incremental Learning): The model sequentially acquires new capabilities or skills.
- Time-IL (Time-Incremental Learning): Data arrives chronologically, simulating real-world temporal distribution shifts.
📊 Evaluation Metrics
Evaluating CL in VLMs necessitates a multifaceted approach that addresses both traditional CL desiderata and VLM-specific challenges (e.g., zero-shot generalization and cross-modal alignment). Key metrics discussed in our survey include:
- Average & Last Accuracy: Measures the mean task performance over all learning stages and the retained competence after full training.
- Forgetting Ratio & Backward Transfer (BWT): Quantifies the maximum performance drop per task post-initial learning, or improvements induced by later learning.
- Zero-Shot Transfer & Zero-Shot Degradation (ZSD): Explicitly evaluates the model's generalization to unseen tasks and measures the erosion of pre-acquired open-vocabulary capabilities.
- Modality-Specific Metrics: Utilizing Recall@K, mAP, and Answer Precision (AP) for Retrieval and VQA to diagnose asymmetric modality degradation.
Regarding the detailed computation of these evaluation metrics, we provide a clear and intuitive diagram (as shown below) in the paper for comprehensive explanation.
🚀 Future Directions
Based on the gaps and trends identified in our survey, we propose several key directions for future research:
-
📊 Unified and Holistic Benchmarking: Moving beyond simple classification accuracy to incorporate compositional zero-shot evaluation and temporal, web-scale data streams.
-
💬 Continual Learning for Generative and Interactive Tasks: Enabling multimodal chatbots and agents to continually learn from human feedback and long-term memory without losing alignment.
-
🤖 Continual Learning for Vision-Language-Action (VLA) Models: Transitioning to Embodied AI where cross-modal feature drift precipitates cascading physical failures, requiring skill-compositional strategies.
-
📐 Towards a Theoretical Understanding: Developing mathematical models for cross-modal feature drift and theoretical bounds for Parameter-Efficient Adaptation.
Star History
🤝 How to Contribute
We welcome contributions! If you have a paper, dataset, or codebase that should be on this list, please open a Pull Request.
- Fork the repository.
- Add your resource to the appropriate section in
README.md. Please maintain the existing format. - Submit a pull request with a clear title and description.
🌟 Related Resources
🛠️ Maintenance
- Maintainers: Yuyang Liu, Qiuhe Hong, Linlan Huang, Alexandra Gomez-Villa, and Dipam Goswami.
- Contact: sunshineliuyuyang@gmail.com
- Star the repo to show your support! ⭐
Acknowledgments: This repository builds on the incredible efforts of the open-source research community.