
[ICML 2025] Flow of Reasoning: Training LLMs for Divergent Reasoning with Minimal Examples
PDDL
129
163 commits
updated Jan 31, 2026
README
Flow of Reasoning: Training LLMs for Divergent Reasoning with Minimal Examples
Official code for "Flow of Reasoning:Training LLMs for Divergent Reasoning with Minimal Examples" Also check our [Project Page]
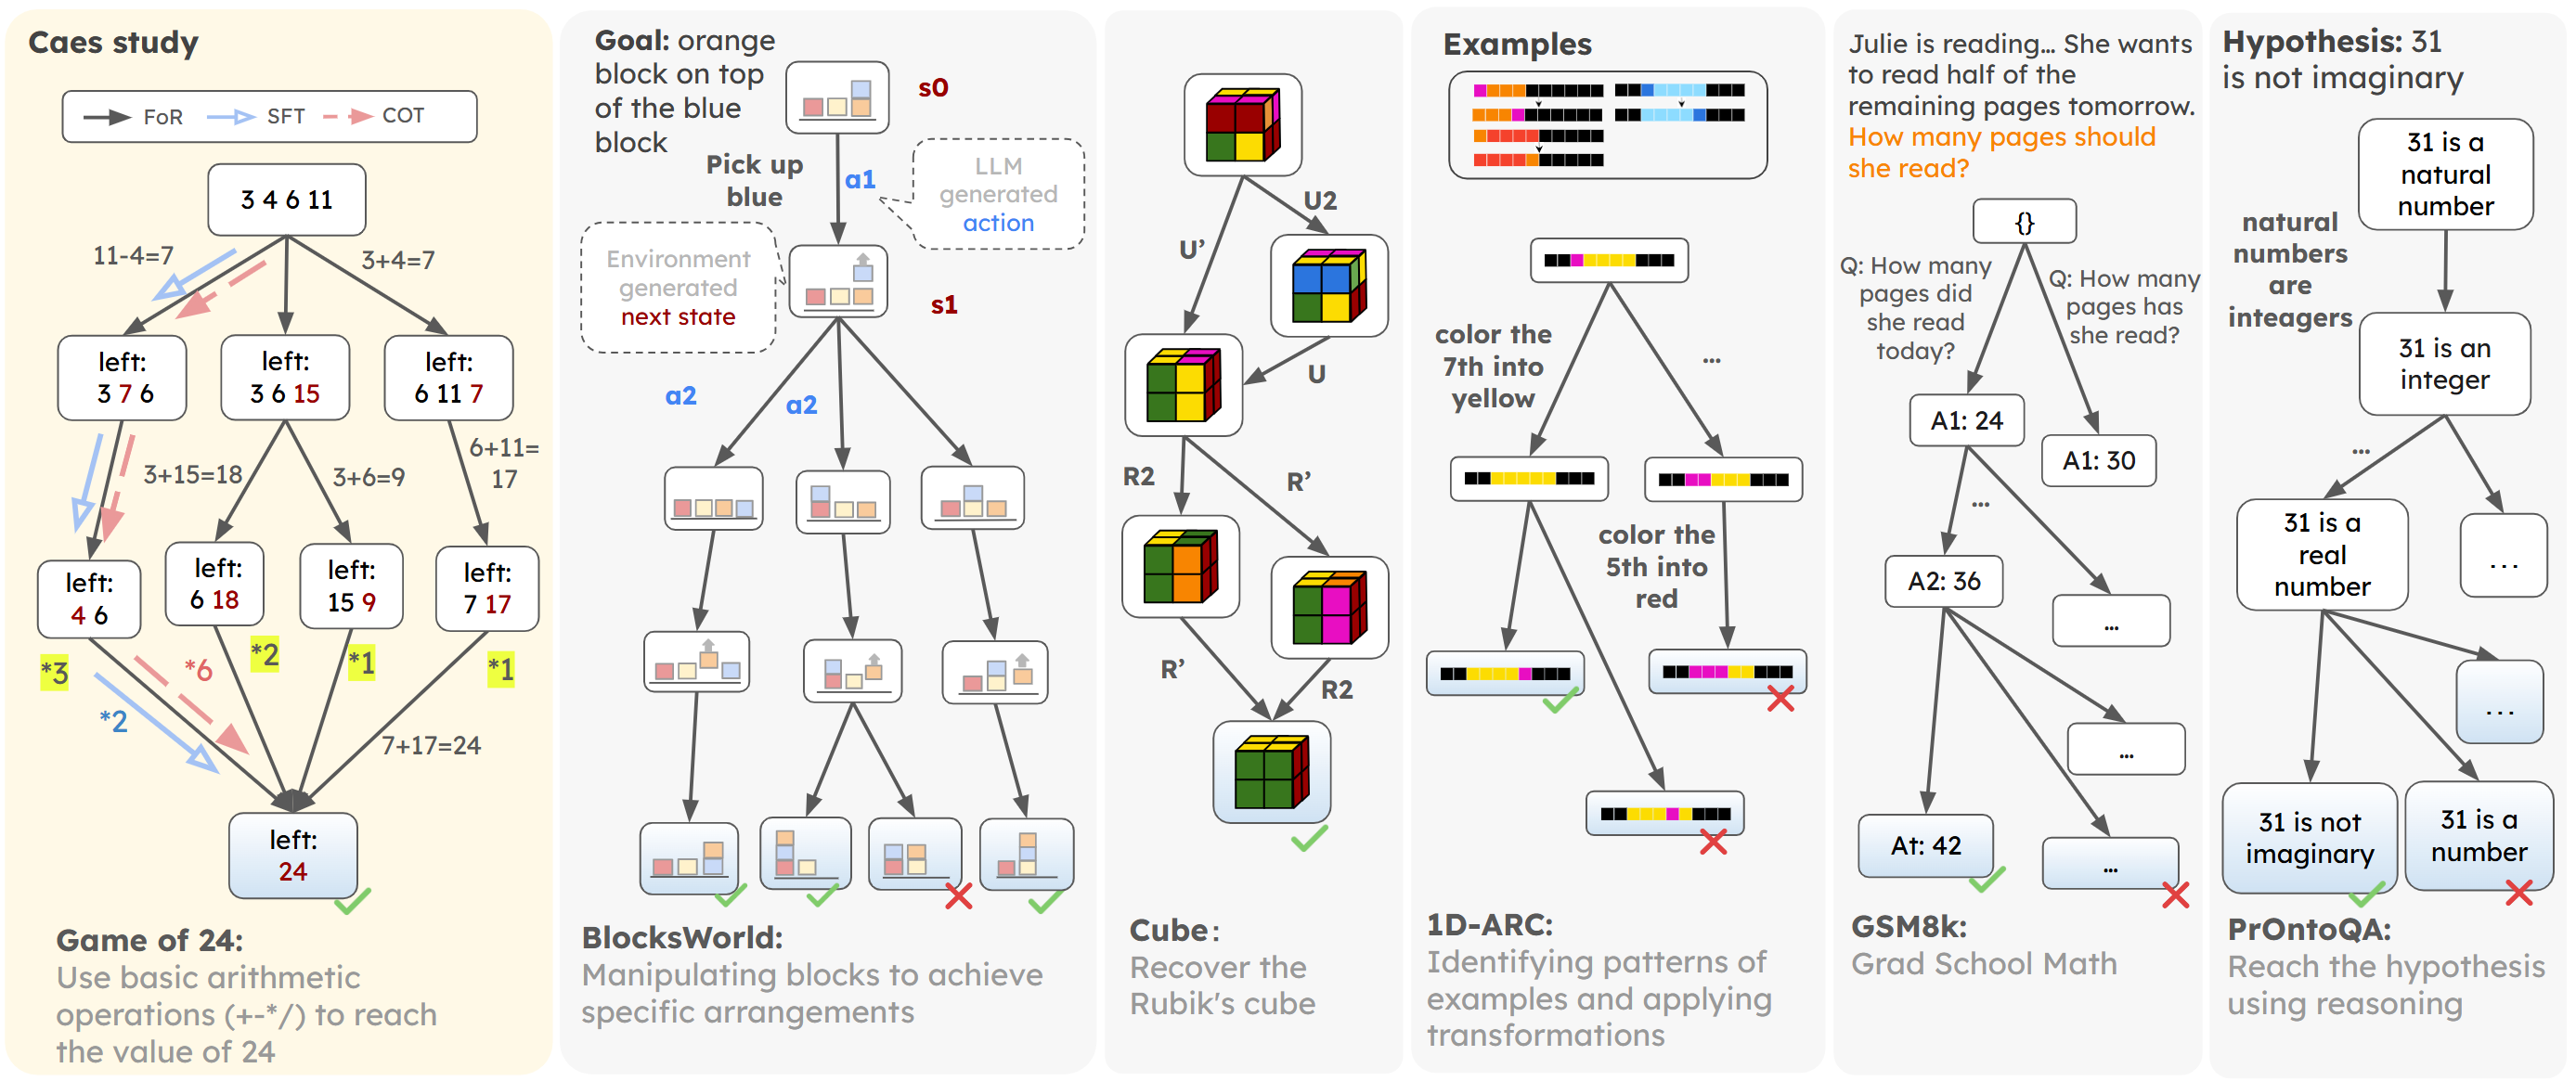
Training & Inference
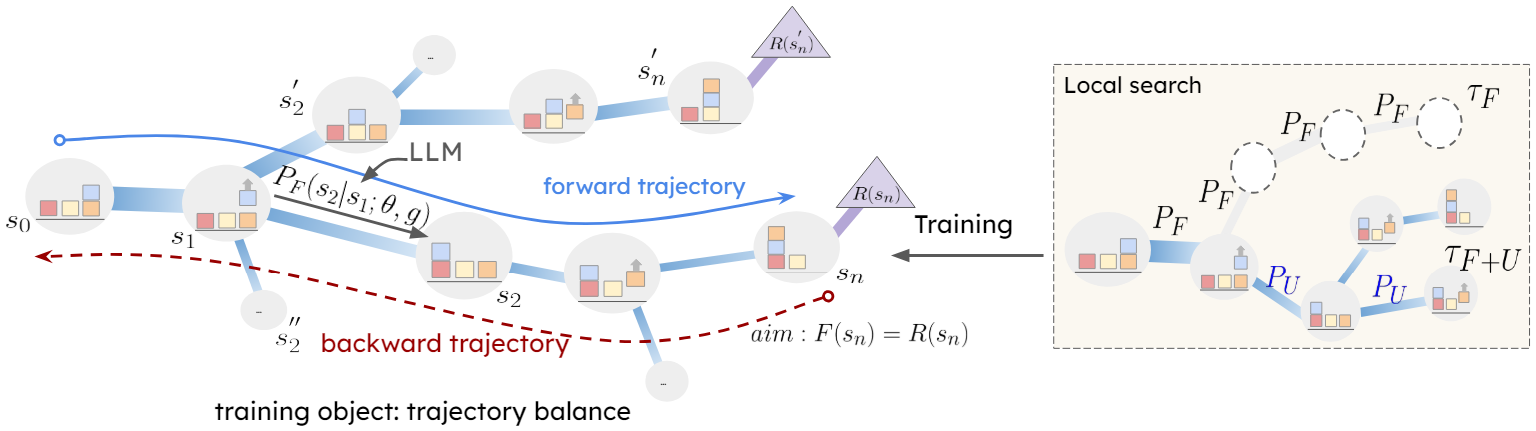
Our FoR formulates multi-step reasoning tasks as a flow:
- Design reward $R(s_n)$ of terminal states for different tasks.
- Collect trajectories with the local search technique.
- Training LLM policy $P_{F}$ with trajectory balance loss.
Code
1) Download this GitHub
git clone https://github.com/Yu-Fangxu/FoR.git
2) Prepare the environment
We recommend conda for setting up a reproducible experiment environment. We include environment.yaml for creating a working environment:
bash install.sh
3) Choose 1 of 6 tasks to run
cd BlocksWorld|Game24|prontoqa|1D-ARC|Rubik's_Cube|GSM8K
Check more detailed instructions in each branch.
Citation
@inproceedings{yuflow,
  title={Flow of Reasoning: Training LLMs for Divergent Reasoning with Minimal Examples},
  author={Yu, Fangxu and Jiang, Lai and Kang, Haoqiang and Hao, Shibo and Qin, Lianhui},
  booktitle={Forty-second International Conference on Machine Learning}
}
Contributors


Similar repos


Languages
PDDL
68.9%
C++
16.9%
Python
11.6%
[ICML 2025] Flow of Reasoning: Training LLMs for Divergent Reasoning with Minimal Examples
PDDL
129
163 commits
updated Jan 31, 2026
README
Flow of Reasoning: Training LLMs for Divergent Reasoning with Minimal Examples
Official code for "Flow of Reasoning:Training LLMs for Divergent Reasoning with Minimal Examples" Also check our [Project Page]
Training & Inference
Our FoR formulates multi-step reasoning tasks as a flow:
- Design reward $R(s_n)$ of terminal states for different tasks.
- Collect trajectories with the local search technique.
- Training LLM policy $P_{F}$ with trajectory balance loss.
Code
1) Download this GitHub
git clone https://github.com/Yu-Fangxu/FoR.git
2) Prepare the environment
We recommend conda for setting up a reproducible experiment environment. We include environment.yaml for creating a working environment:
bash install.sh
3) Choose 1 of 6 tasks to run
cd BlocksWorld|Game24|prontoqa|1D-ARC|Rubik's_Cube|GSM8K
Check more detailed instructions in each branch.
Citation
@inproceedings{yuflow,
  title={Flow of Reasoning: Training LLMs for Divergent Reasoning with Minimal Examples},
  author={Yu, Fangxu and Jiang, Lai and Kang, Haoqiang and Hao, Shibo and Qin, Lianhui},
  booktitle={Forty-second International Conference on Machine Learning}
}
Similar repos
Contributors
Languages
PDDL
68.9%
C++
16.9%
Python
11.6%