
[NeurIPS 2025 Spotlight] LLM post-training suite — featuring ReasonFlux, ReasonFlux-PRM, and ReasonFlux-Coder.
See the codeREADME
🧠 ReasonFlux Series
Advanced Open-Source LLM Post-Training Suite
Princeton University & PKU & UIUC & University of Chicago & ByteDance Seed
🎯 Mission: Building next-generation reasoning capabilities through innovative LLM post-training algorithms focusing on data selection, reinforcement learning, and inference scaling.
Contents of Repository
🚀 What Makes ReasonFlux Series Special?
1. Trajectory-Aware Process Reward Models for Long-CoT Reasoning (ReasonFlux-PRM, NeurIPS 2025)
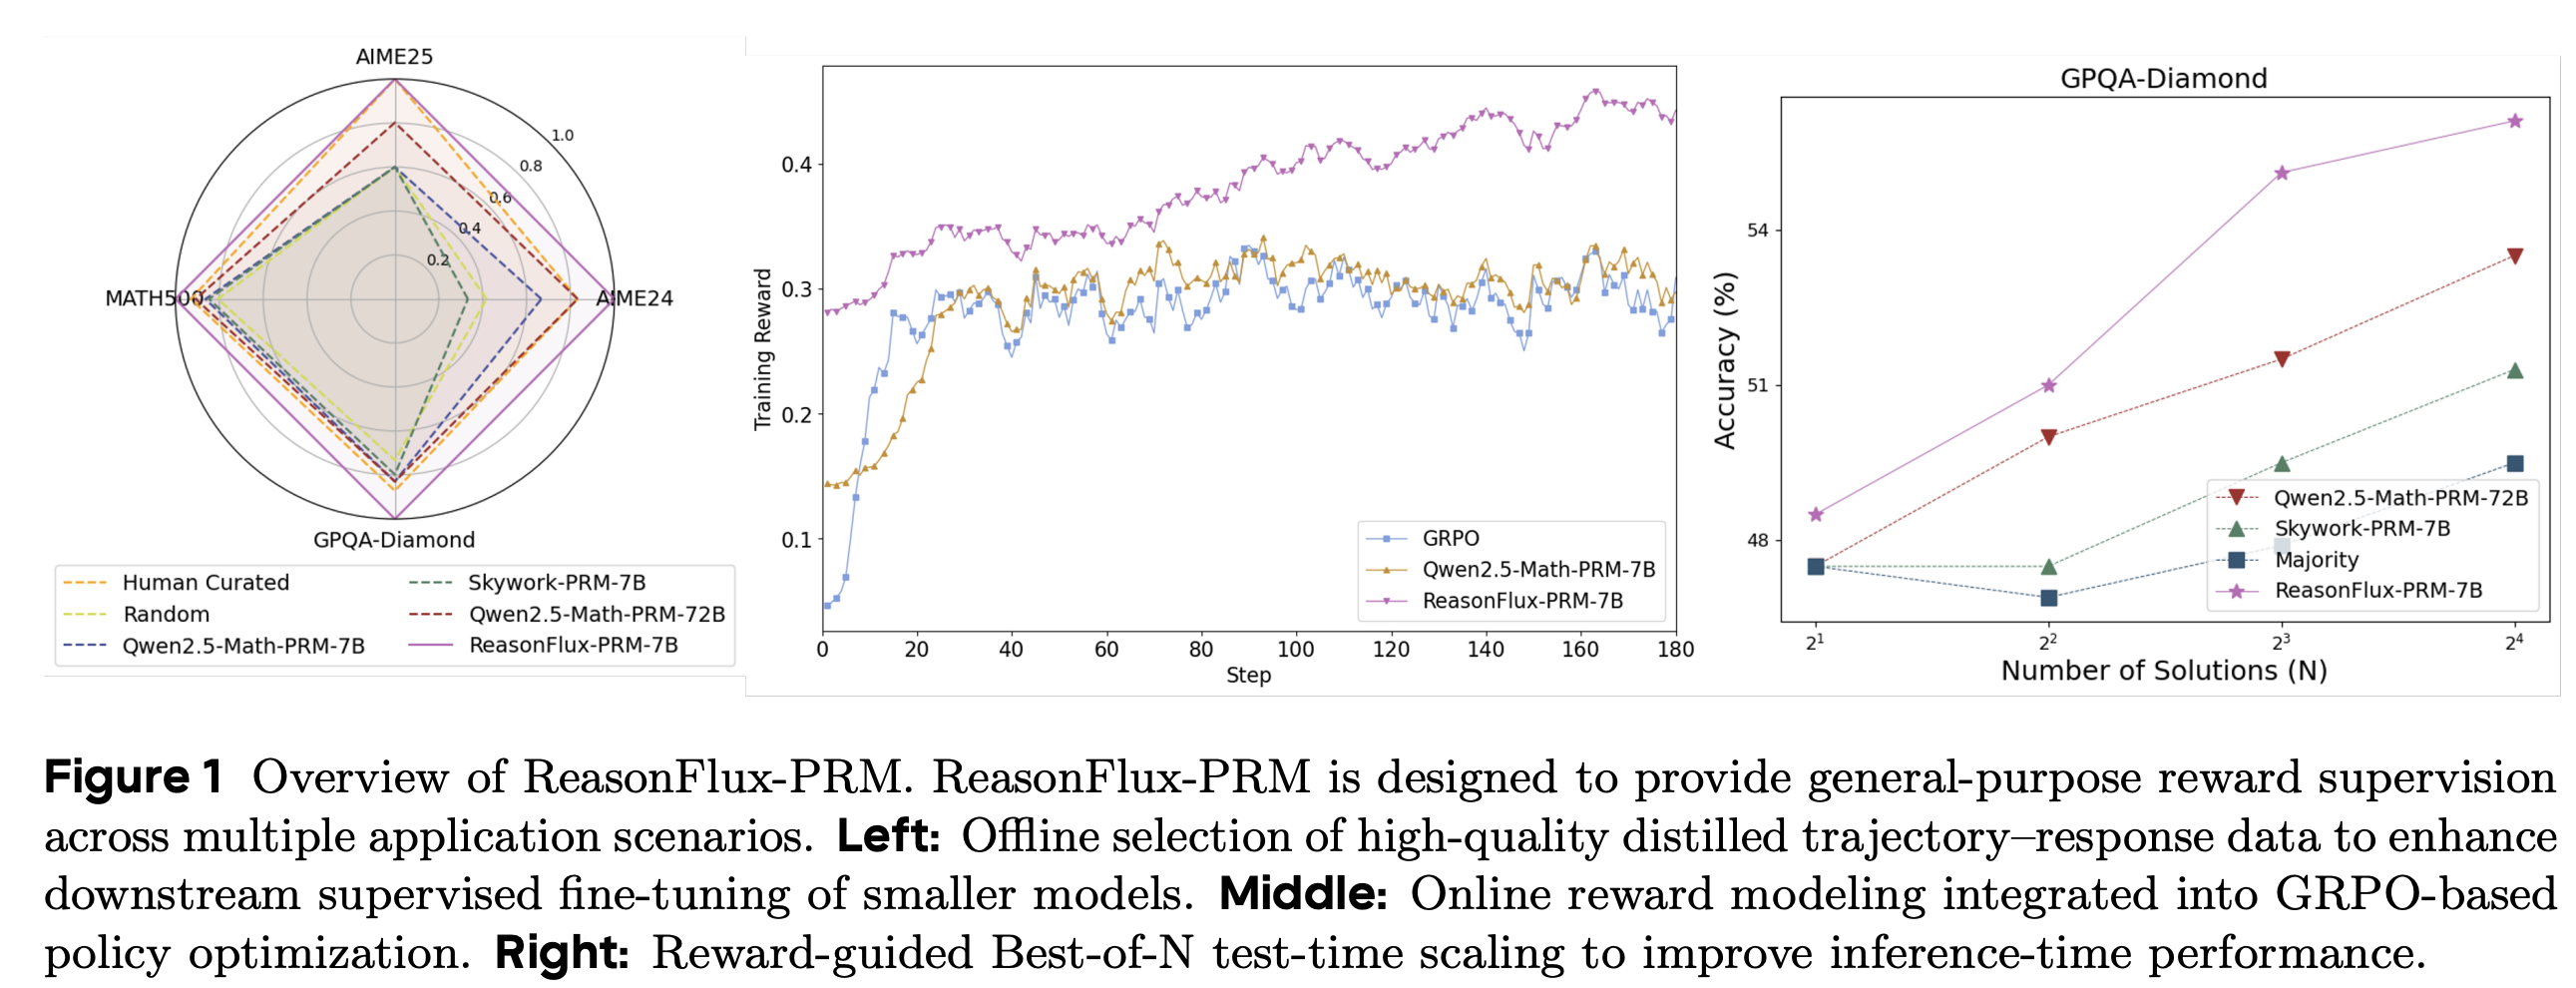
Trajectory-aware reward models that provide dense supervision for both offline data selection and online policy optimization in long-CoT reasoning.
2. Co-Evolved RL for LLM Coder and Unit Tester (ReasonFlux-Coder, NeurIPS 2025 Spotlight)
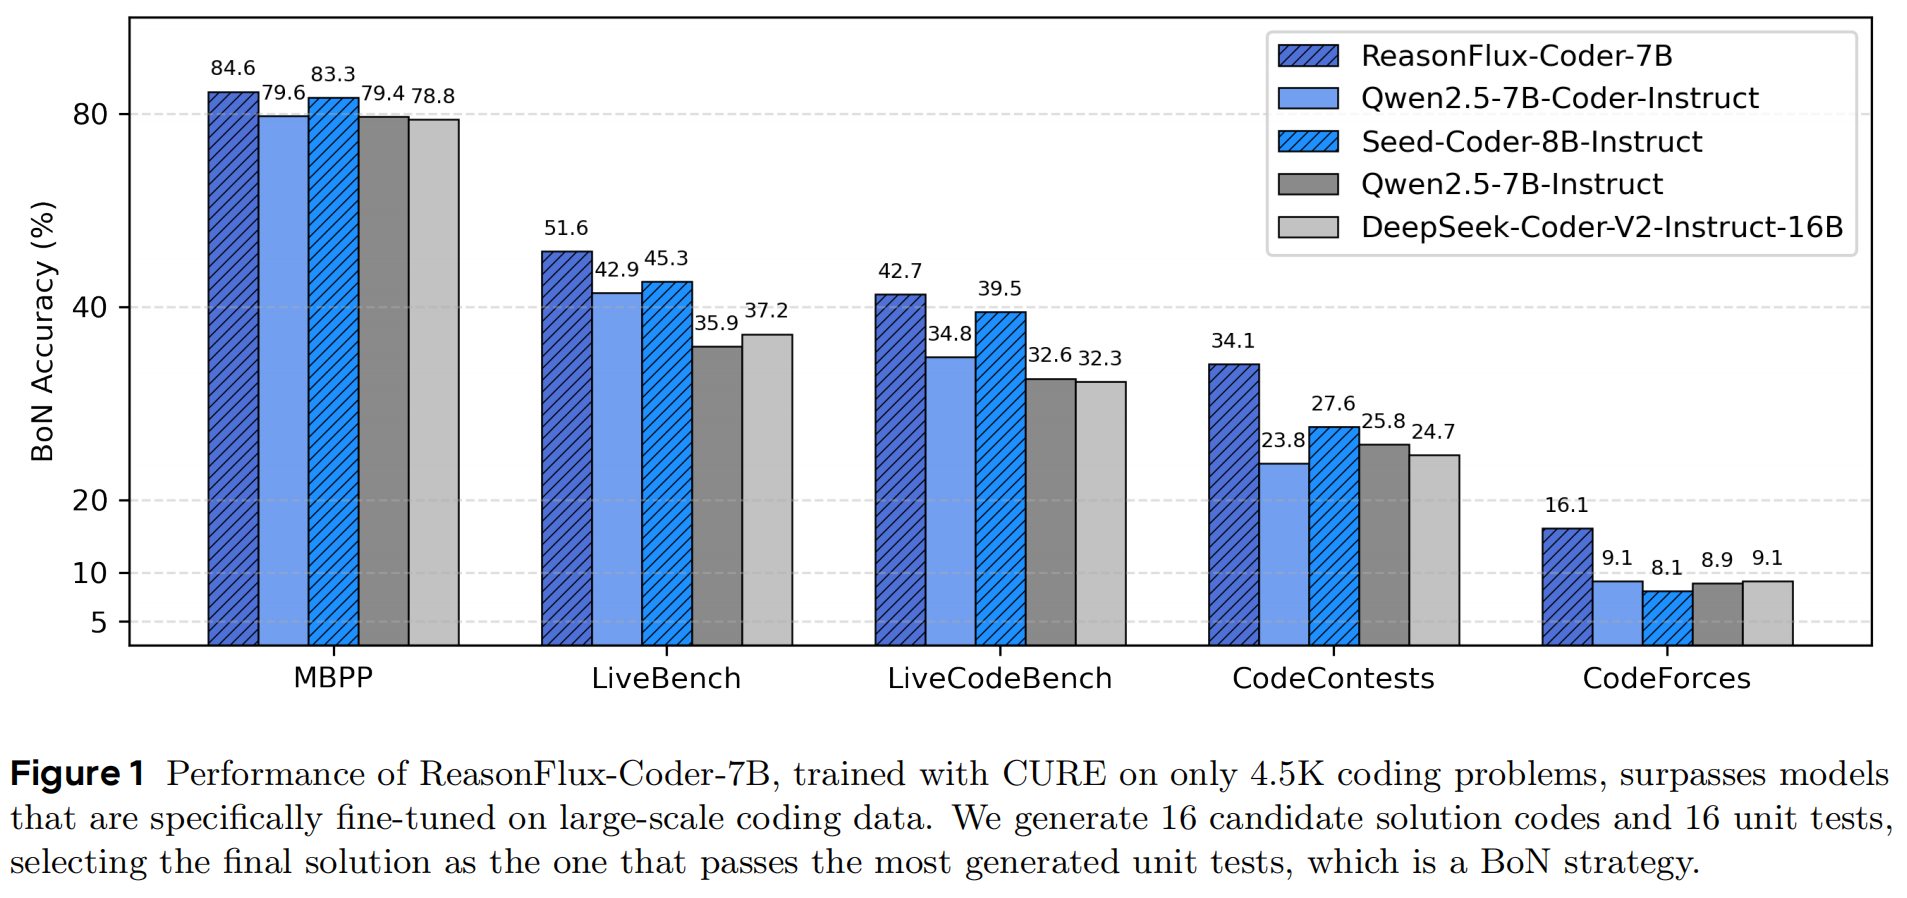
Innovative approach where coders and unit testers evolve together through reinforcement learning, creating more robust coding capabilities.
3. Long-CoT Reasoning with Thought Templates (ReasonFlux-Zero/F1)
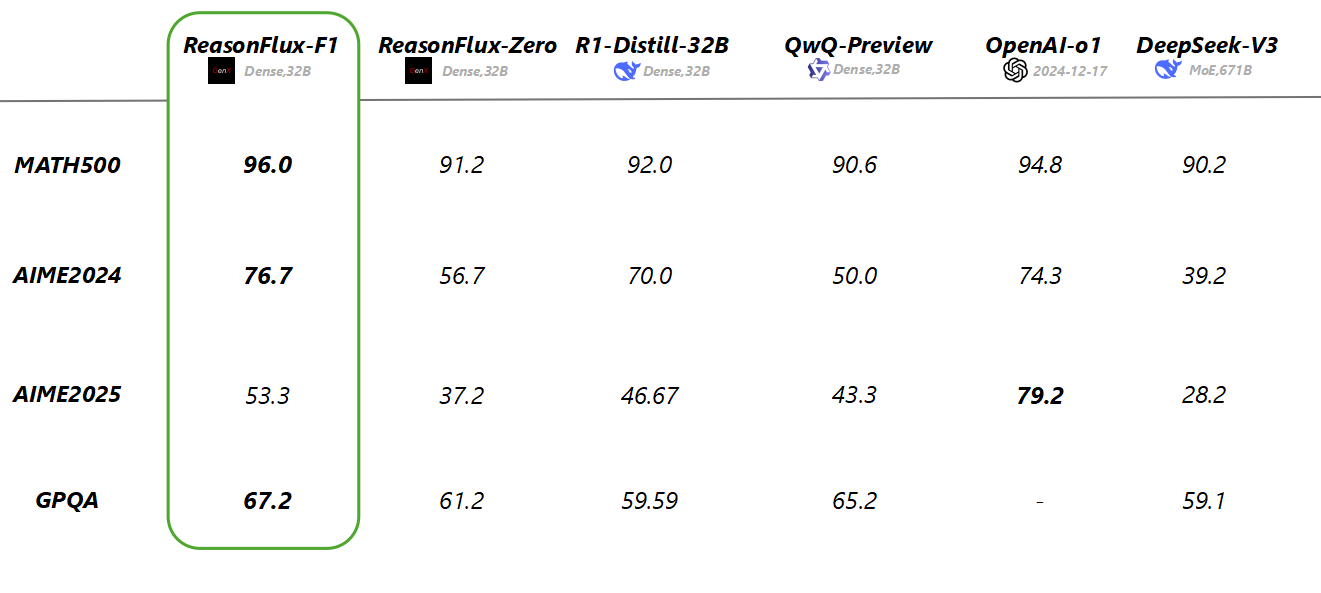
Revolutionary hierarchical reasoning framework that uses thought templates to guide complex problem-solving, achieving SOTA performance with higher efficiency.
Preliminary Work on Thought Template
Our ReasonFlux-Zero/F1 models are built upon insights from our preliminary work on thought templates—specifically, Buffer of Thoughts (NeurIPS 2024 Spotlight) and SuperCorrect (ICLR 2025). These works introduce high-level, efficient intermediate reasoning patterns that guide and structure the thinking process of large language models.
Updates
- [2025/6/23] 🎉 We introduce ReasonFlux-PRM, a family of trajectory-aware process reward models (PRMs) for long CoT reasoning in LLMs. ReasonFlux-PRM is able to support both offline and online reward supervision, by selecting high-quality training data for model distillation, providing dense process-level rewards for policy optimization during reinforcement learning, and enabling reward-guided test-time scaling. Our trained PRMs including ReasonFlux-PRM-7B and ReasonFlux-PRM-1.5B are now available on HuggingFace-GenX. We also release a 7B advanced thinking and reasoning model ReasonFlux-PRM-Qwen-2.5-7B supervised via our PRM.
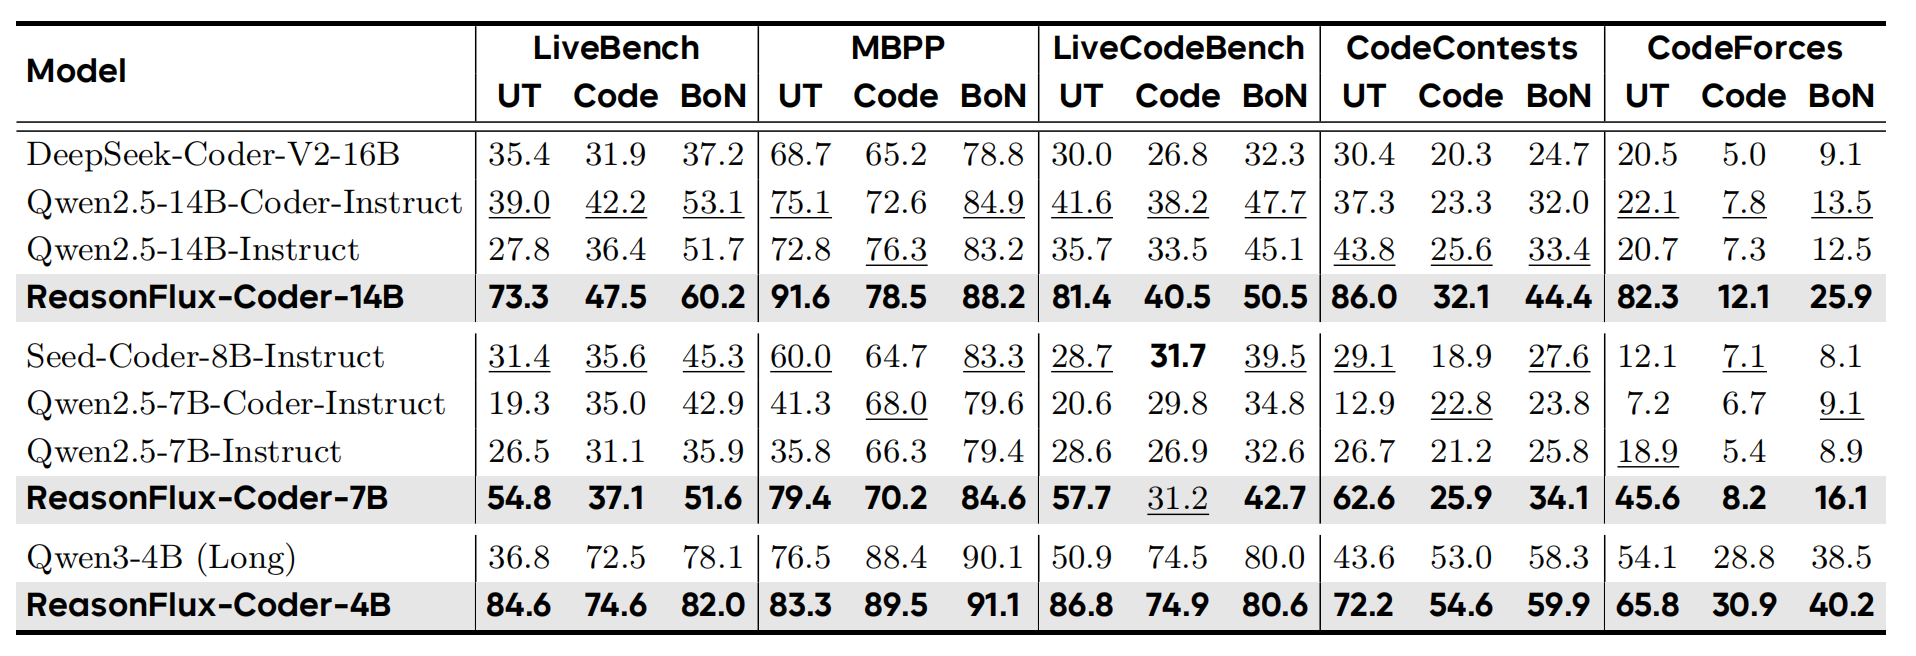
- [2025/6/04] 🎉 We release our Co-Evolving RL optimized coding LLMs, ReasonFlux-Coder-7B and ReasonFlux-Coder-14B, which outperform similarly sized Qwen Coders and DeepSeek Coders, and naturally fit into common test-time scaling and agentic coding pipelines. We also release our Long-CoT model ReasonFlux-Coder-4B, outperforming Qwen3-4B while achieving 64.8% efficiency in unit test generation.
- [2025/3/24] 🎉We release ReasonFlux-F1-32B, ReasonFlux-F1-14B, ReasonFlux-F1-7B, a series of SOTA-level reasoning LLMs by leveraging the template-augmented reasoning trajectories collected from our ReasonFlux-Zero. For the training and evaluation scripts, please refer to reasonflux-f1/README.md for detail.
- [2025/2/11]🎉We propose ReasonFlux-Zero, a hierarchical LLM reasoning framework that significantly enhances complex reasoning capabilities, outperforming SOTA models like o1-preview and DeepSeek-V3 on challenging MATH and AIME benchmarks.
Model Family Guide
🎯 Process Reward Models
| Model | Size | Capabilities | Use Cases | Download |
|---|---|---|---|---|
| ReasonFlux-PRM | 7B | • Trajectory-aware scoring • Online/Offline supervision • Dense process rewards | PRM: Data selection, RL training, Test-time scaling | 🤗 7B |
| ReasonFlux-PRM | 1.5B | • Lightweight scoring • Efficient inference • Edge deployment | PRM: Resource-constrained applications | 🤗 1.5B |
| ReasonFlux-PRM-Qwen-2.5 | 7B | • Long CoT reasoning • Solving complex tasks and problems | Tuned Reasoning Model: Math and Science Reasoning | 🤗 7B |
💻 Coding Models
| Model | Size | Specialization | Performance | Download |
|---|---|---|---|---|
| ReasonFlux-Coder | 14B | • Co-evolutionary RL • Advanced coding • Unit test generation | Outperforms Qwen & DeepSeek Coders | 🤗 14B |
| ReasonFlux-Coder | 7B | • Balanced performance • Efficient inference • Production ready | Excellent coding capabilities | 🤗 7B |
| ReasonFlux-Coder | 4B | • Long-CoT reasoning • Compact size • Unit test focused | 64.8% efficiency in unit test generation | 🤗 4B |
🧠 Reasoning Models
| Model | Size | Key Features | Best For | Download |
|---|---|---|---|---|
| ReasonFlux-F1 | 7B/14B/32B | • Template-augmented trajectories • Efficient training • Multiple sizes | General reasoning tasks | 🤗 Models |
| ReasonFlux-Zero | 32B | • Hierarchical reasoning • Template library • Foundation model | Research & development | 🤗 Model |
Performance Highlights
1. Complex Reasoning
| Model | AIME2024@pass1 | AIME2025@pass1 | MATH500@pass1 | GPQA@pass1 |
|---|---|---|---|---|
| QwQ-32B-Preview | 46.7 | 37.2 | 90.6 | 65.2 |
| LIMO-32B | 56.3 | 44.5 | 94.8 | 58.1 |
| s1-32B | 56.7 | 49.3 | 93.0 | 59.6 |
| OpenThinker-32B | 66.0 | 53.3 | 94.8 | 60.1 |
| R1-Distill-32B | 70.0 | 46.7 | 92.0 | 59.6 |
| ReasonFlux-Zero-32B | 56.7 | 37.2 | 91.2 | 61.2 |
| ReasonFlux-F1-32B | 76.7 | 53.3 | 96.0 | 67.2 |
2. Code Generation and Reasoning
3. PRMs for Long-CoT Reasoning
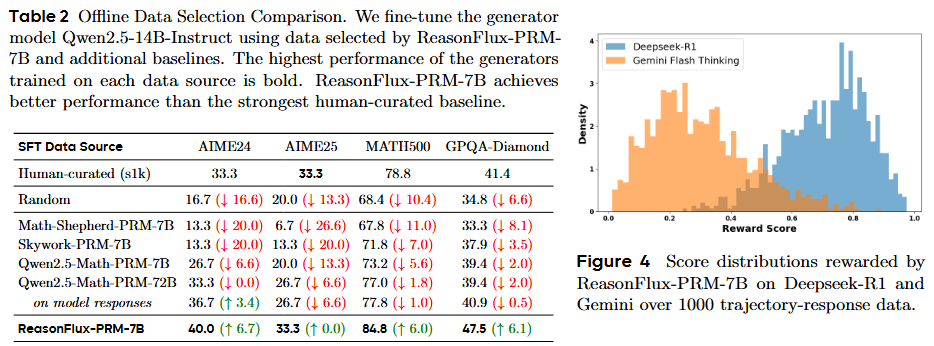
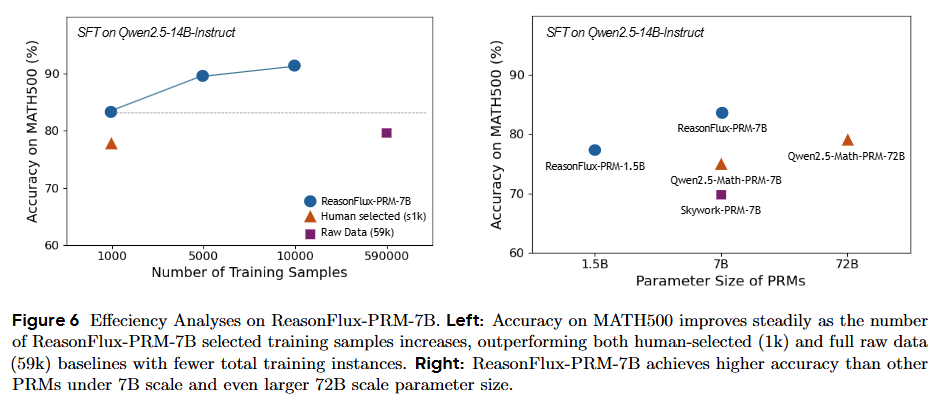
We observe that in the downstream offline data selection + SFT setting, ReasonFlux-PRM-7B surpasses the performance of the high-quality, human-curated s1k dataset. We further visualize the score distributions over 1,000 trajectory-response pairs generated by Deepseek-R1 and Gemini. The clearly separated distributions indicate that ReasonFlux-PRM-7B effectively differentiates the quality of responses from different models, offering a robust and reliable reward signal for high-quality data selection.
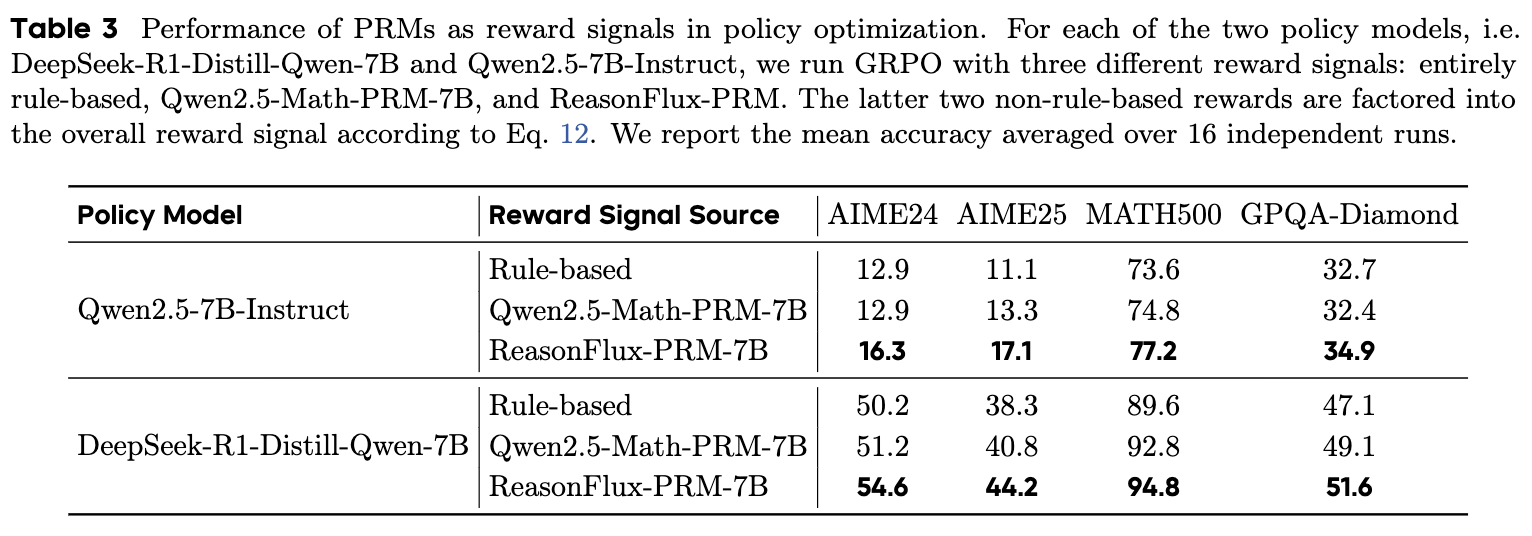
Under the online settings, ReasonFlux-PRM-7B also surpasses other PRM and rule-based baselines during the GRPO policy optimization.
Citation
@article{yang2025reasonflux,
  title={ReasonFlux: Hierarchical LLM Reasoning via Scaling Thought Templates},
  author={Yang, Ling and Yu, Zhaochen and Cui, Bin and Wang, Mengdi},
  journal={arXiv preprint arXiv:2502.06772},
  year={2025}
}

@article{wang2025reasonfluxcoder,
  title={Co-Evolving LLM Coder and Unit Tester via Reinforcement Learning},
  author={Wang, Yinjie and Yang, Ling and Tian, Ye and Shen, Ke and Wang, Mengdi},
  journal={arXiv preprint arXiv:2506.03136},
  year={2025}
}

@article{zou2025reasonfluxprm,
  title={ReasonFlux-PRM: Trajectory-Aware PRMs for Long Chain-of-Thought Reasoning in LLMs},
  author={Zou, Jiaru and Yang, Ling and Gu, Jingwen and Qiu, Jiahao and Shen, Ke and He, Jingrui and Wang, Mengdi},
  journal={arXiv preprint arXiv:2506.18896},
  year={2025}
}
Contributors


Similar repos


Languages
Python
97.6%
Jupyter Notebook
1.7%
[NeurIPS 2025 Spotlight] LLM post-training suite — featuring ReasonFlux, ReasonFlux-PRM, and ReasonFlux-Coder.
See the codeREADME
🧠 ReasonFlux Series
Advanced Open-Source LLM Post-Training Suite
Princeton University & PKU & UIUC & University of Chicago & ByteDance Seed
🎯 Mission: Building next-generation reasoning capabilities through innovative LLM post-training algorithms focusing on data selection, reinforcement learning, and inference scaling.
Contents of Repository
🚀 What Makes ReasonFlux Series Special?
1. Trajectory-Aware Process Reward Models for Long-CoT Reasoning (ReasonFlux-PRM, NeurIPS 2025)
Trajectory-aware reward models that provide dense supervision for both offline data selection and online policy optimization in long-CoT reasoning.
2. Co-Evolved RL for LLM Coder and Unit Tester (ReasonFlux-Coder, NeurIPS 2025 Spotlight)
Innovative approach where coders and unit testers evolve together through reinforcement learning, creating more robust coding capabilities.
3. Long-CoT Reasoning with Thought Templates (ReasonFlux-Zero/F1)
Revolutionary hierarchical reasoning framework that uses thought templates to guide complex problem-solving, achieving SOTA performance with higher efficiency.
Preliminary Work on Thought Template
Our ReasonFlux-Zero/F1 models are built upon insights from our preliminary work on thought templates—specifically, Buffer of Thoughts (NeurIPS 2024 Spotlight) and SuperCorrect (ICLR 2025). These works introduce high-level, efficient intermediate reasoning patterns that guide and structure the thinking process of large language models.
Updates
- [2025/6/23] 🎉 We introduce ReasonFlux-PRM, a family of trajectory-aware process reward models (PRMs) for long CoT reasoning in LLMs. ReasonFlux-PRM is able to support both offline and online reward supervision, by selecting high-quality training data for model distillation, providing dense process-level rewards for policy optimization during reinforcement learning, and enabling reward-guided test-time scaling. Our trained PRMs including ReasonFlux-PRM-7B and ReasonFlux-PRM-1.5B are now available on HuggingFace-GenX. We also release a 7B advanced thinking and reasoning model ReasonFlux-PRM-Qwen-2.5-7B supervised via our PRM.
- [2025/6/04] 🎉 We release our Co-Evolving RL optimized coding LLMs, ReasonFlux-Coder-7B and ReasonFlux-Coder-14B, which outperform similarly sized Qwen Coders and DeepSeek Coders, and naturally fit into common test-time scaling and agentic coding pipelines. We also release our Long-CoT model ReasonFlux-Coder-4B, outperforming Qwen3-4B while achieving 64.8% efficiency in unit test generation.
- [2025/3/24] 🎉We release ReasonFlux-F1-32B, ReasonFlux-F1-14B, ReasonFlux-F1-7B, a series of SOTA-level reasoning LLMs by leveraging the template-augmented reasoning trajectories collected from our ReasonFlux-Zero. For the training and evaluation scripts, please refer to reasonflux-f1/README.md for detail.
- [2025/2/11]🎉We propose ReasonFlux-Zero, a hierarchical LLM reasoning framework that significantly enhances complex reasoning capabilities, outperforming SOTA models like o1-preview and DeepSeek-V3 on challenging MATH and AIME benchmarks.
Model Family Guide
🎯 Process Reward Models
| Model | Size | Capabilities | Use Cases | Download |
|---|---|---|---|---|
| ReasonFlux-PRM | 7B | • Trajectory-aware scoring • Online/Offline supervision • Dense process rewards | PRM: Data selection, RL training, Test-time scaling | 🤗 7B |
| ReasonFlux-PRM | 1.5B | • Lightweight scoring • Efficient inference • Edge deployment | PRM: Resource-constrained applications | 🤗 1.5B |
| ReasonFlux-PRM-Qwen-2.5 | 7B | • Long CoT reasoning • Solving complex tasks and problems | Tuned Reasoning Model: Math and Science Reasoning | 🤗 7B |
💻 Coding Models
| Model | Size | Specialization | Performance | Download |
|---|---|---|---|---|
| ReasonFlux-Coder | 14B | • Co-evolutionary RL • Advanced coding • Unit test generation | Outperforms Qwen & DeepSeek Coders | 🤗 14B |
| ReasonFlux-Coder | 7B | • Balanced performance • Efficient inference • Production ready | Excellent coding capabilities | 🤗 7B |
| ReasonFlux-Coder | 4B | • Long-CoT reasoning • Compact size • Unit test focused | 64.8% efficiency in unit test generation | 🤗 4B |
🧠 Reasoning Models
| Model | Size | Key Features | Best For | Download |
|---|---|---|---|---|
| ReasonFlux-F1 | 7B/14B/32B | • Template-augmented trajectories • Efficient training • Multiple sizes | General reasoning tasks | 🤗 Models |
| ReasonFlux-Zero | 32B | • Hierarchical reasoning • Template library • Foundation model | Research & development | 🤗 Model |
Performance Highlights
1. Complex Reasoning
| Model | AIME2024@pass1 | AIME2025@pass1 | MATH500@pass1 | GPQA@pass1 |
|---|---|---|---|---|
| QwQ-32B-Preview | 46.7 | 37.2 | 90.6 | 65.2 |
| LIMO-32B | 56.3 | 44.5 | 94.8 | 58.1 |
| s1-32B | 56.7 | 49.3 | 93.0 | 59.6 |
| OpenThinker-32B | 66.0 | 53.3 | 94.8 | 60.1 |
| R1-Distill-32B | 70.0 | 46.7 | 92.0 | 59.6 |
| ReasonFlux-Zero-32B | 56.7 | 37.2 | 91.2 | 61.2 |
| ReasonFlux-F1-32B | 76.7 | 53.3 | 96.0 | 67.2 |
2. Code Generation and Reasoning
3. PRMs for Long-CoT Reasoning
We observe that in the downstream offline data selection + SFT setting, ReasonFlux-PRM-7B surpasses the performance of the high-quality, human-curated s1k dataset. We further visualize the score distributions over 1,000 trajectory-response pairs generated by Deepseek-R1 and Gemini. The clearly separated distributions indicate that ReasonFlux-PRM-7B effectively differentiates the quality of responses from different models, offering a robust and reliable reward signal for high-quality data selection.
Under the online settings, ReasonFlux-PRM-7B also surpasses other PRM and rule-based baselines during the GRPO policy optimization.
Citation
@article{yang2025reasonflux,
  title={ReasonFlux: Hierarchical LLM Reasoning via Scaling Thought Templates},
  author={Yang, Ling and Yu, Zhaochen and Cui, Bin and Wang, Mengdi},
  journal={arXiv preprint arXiv:2502.06772},
  year={2025}
}

@article{wang2025reasonfluxcoder,
  title={Co-Evolving LLM Coder and Unit Tester via Reinforcement Learning},
  author={Wang, Yinjie and Yang, Ling and Tian, Ye and Shen, Ke and Wang, Mengdi},
  journal={arXiv preprint arXiv:2506.03136},
  year={2025}
}

@article{zou2025reasonfluxprm,
  title={ReasonFlux-PRM: Trajectory-Aware PRMs for Long Chain-of-Thought Reasoning in LLMs},
  author={Zou, Jiaru and Yang, Ling and Gu, Jingwen and Qiu, Jiahao and Shen, Ke and He, Jingrui and Wang, Mengdi},
  journal={arXiv preprint arXiv:2506.18896},
  year={2025}
}
Similar repos
Contributors
Languages
Python
97.6%
Jupyter Notebook
1.7%