
Python
59
14 commits
updated Sep 19, 2026
README
Awesome Agentic Visual Generation



Agentic Visual Generation: From Generative Models to Agentic Control
Yinming Huang1,2,*, Shuyuan Tu1,*, Xi Yan1,*, Jiahao Zhan4, Zihan Yang1, Zhen Xing3, Hui Zhang1, Tiehua Zhang5, Yu-Gang Jiang1, Zuxuan Wu1,2,†
[1Fudan University; 2Shanghai Innovative Institute; 3Wan Team, Alibaba Tongyi Lab; 4CUHK, MMLab; 5School of Computer Science and Technology, Tongji University]
[*Equal contribution; †Corresponding author]
❤️ If you find our work useful, please consider giving a star ⭐ to this GitHub repository ❤️.
News
[2026-09-09]: 🔥 The paper is now available on arXiv.
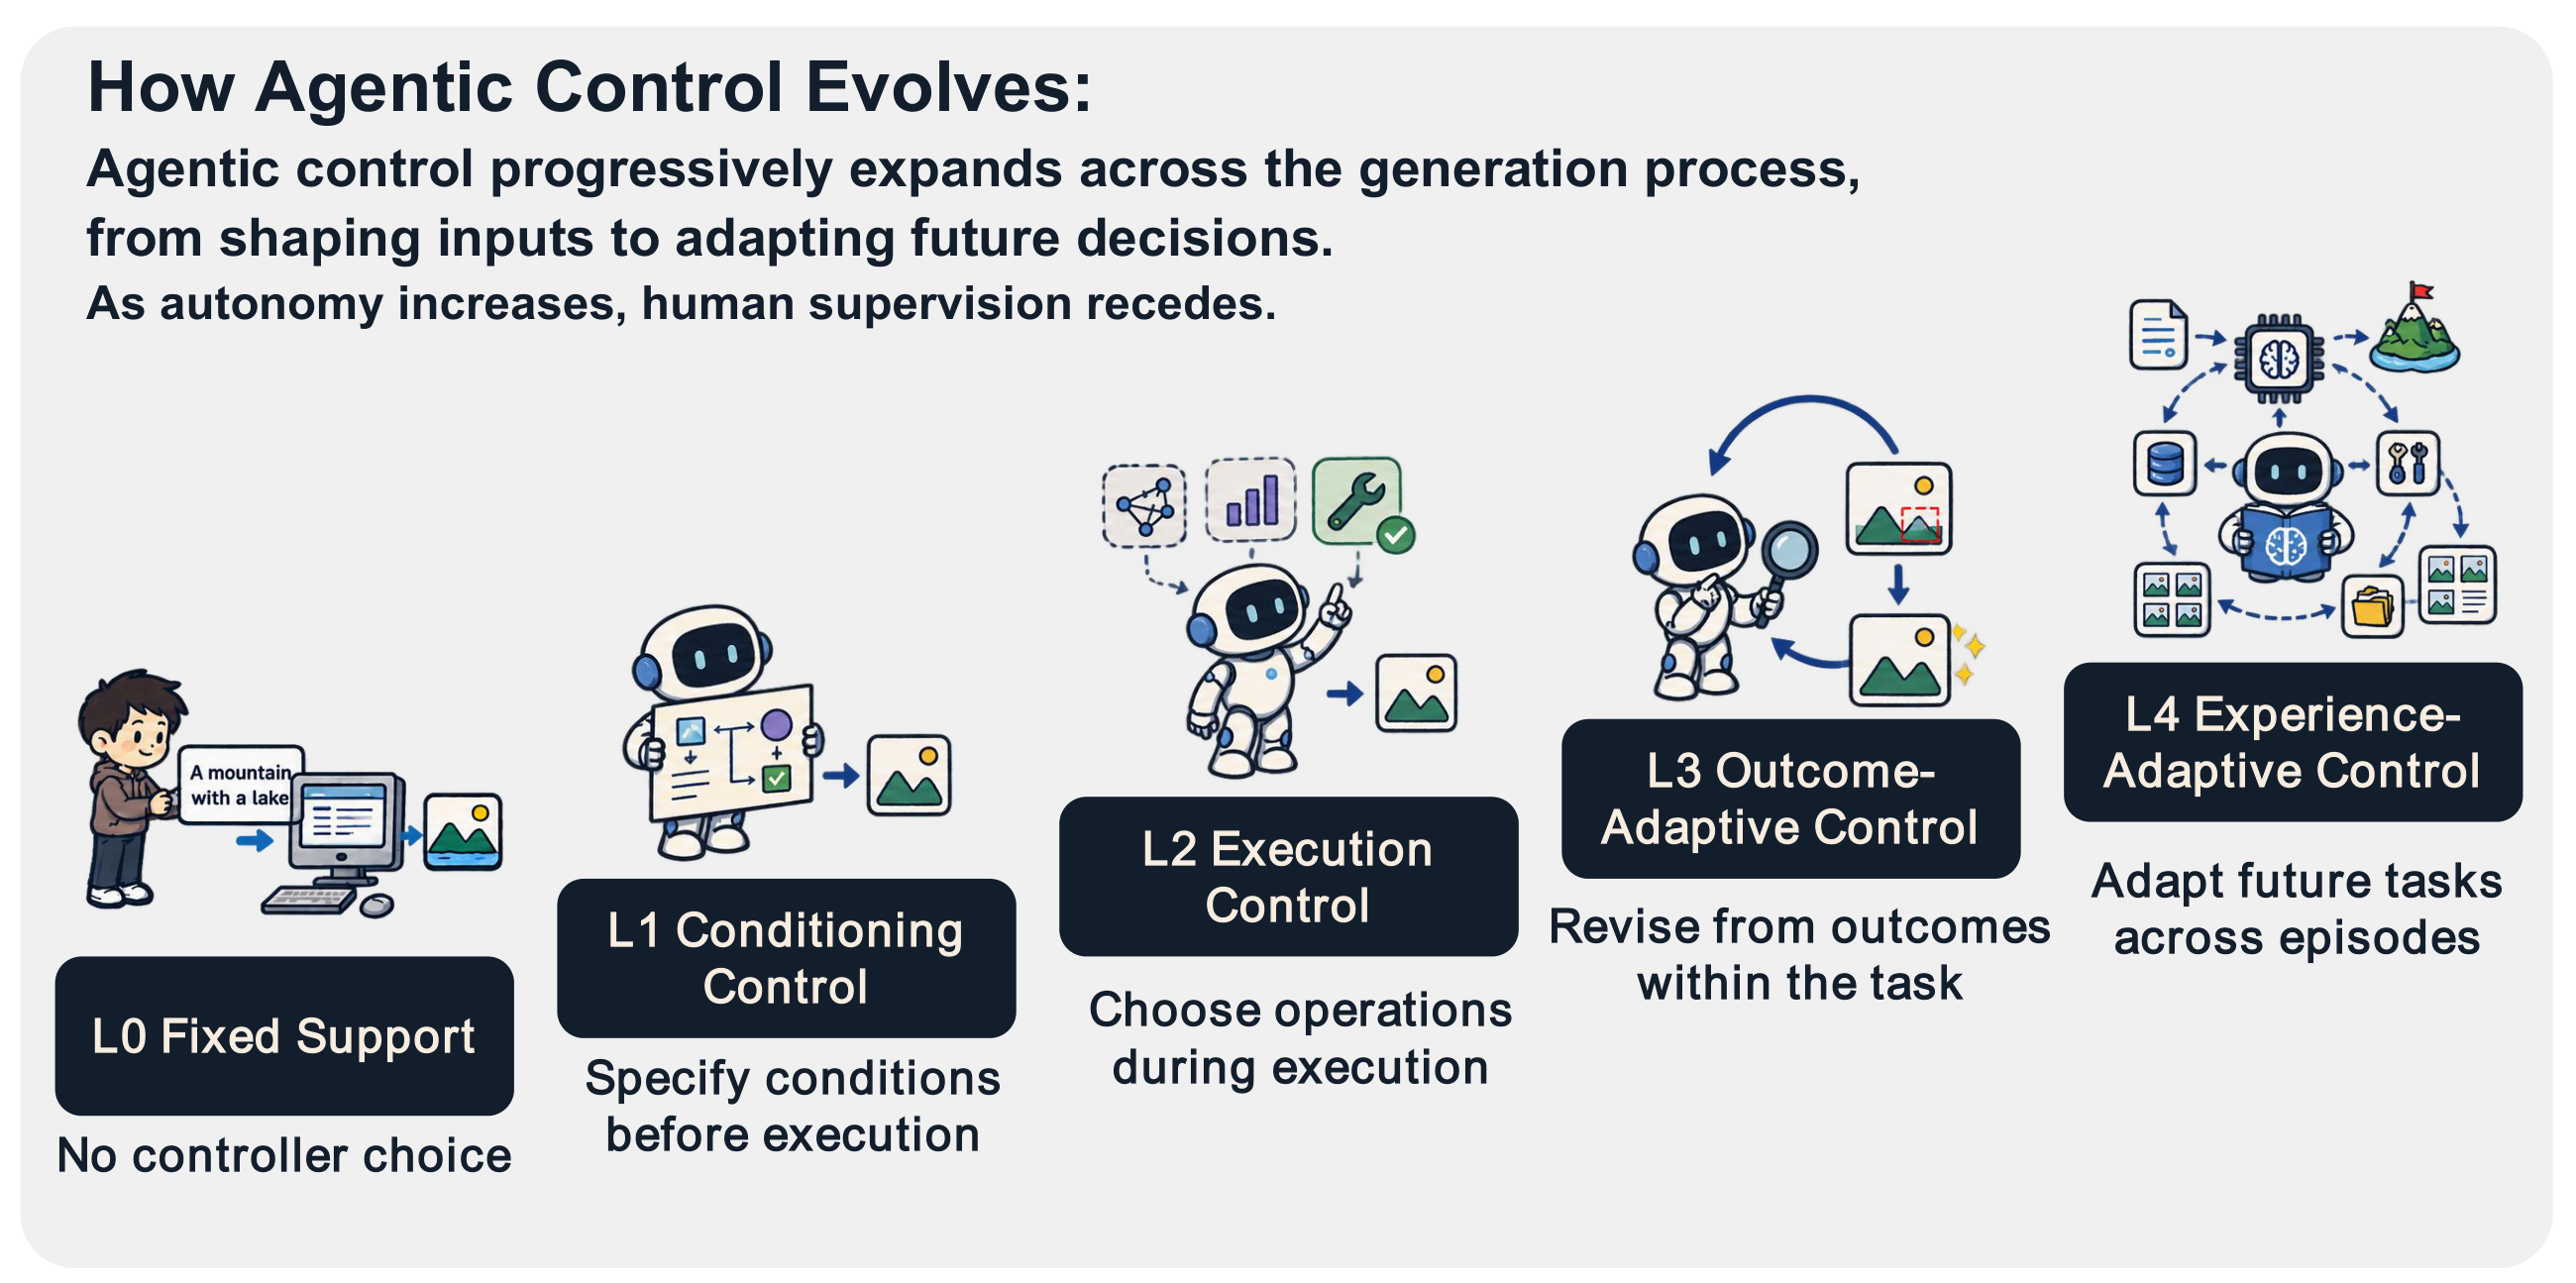
Figure 1. Visual overview of controller decision-making scope.
Vector PDF ·
arXiv paper
Pull requests are very welcome! Please help us add new papers, official resources, or corrections.
A curated and taxonomy-driven collection of 313 reviewed records spanning the L0 boundary and four controller-capability levels. The repository covers image generation and editing, video generation and editing, slide and user-interface generation, 3D scene construction, and world models.
The primary organization follows one rule: agenticity is determined by the deepest point in a generation trajectory at which the controller can causally change a future generation decision. Modality and mechanism are orthogonal tags. This prevents tool use, multi-agent design, memory, or reinforcement learning from being treated as agenticity levels by themselves.
Contents
- Paper on arXiv
- Scope and inclusion rule
- Controller-capability taxonomy
- Full classification standard
- Structured corpus
- L0: Fixed Support
- L1: Conditioning Control
- L2: Execution Control
- L3: Outcome-Adaptive Control
- L4: Experience-Adaptive Control
- Evaluation, Benchmarks, and Reward Models
- Contact
- Community
Scope and inclusion rule
An agentic visual generation system contains a visual generator or editor and a controller that makes generation-level decisions. In most current systems, an LLM, VLM, or MLLM is the controller and the visual generator is one of its tools. The controller may also be hybrid or internalized in a unified model, but generation capability alone does not establish agenticity.
We classify a system by the highest controller capability demonstrated by the complete method:
- The action type does not determine the level. A prompt rewrite before generation is L1, while a prompt rewrite caused by inspection of a generated image is L3.
- Tool use describes the action space. Multi-agent design describes the topology. Reinforcement learning describes a training method. None of them alone determines the level.
- A paper appears once in L0-L4 according to its maximum demonstrated level. The
Pathcolumn records the lower-level capabilities that it also contains. - L0 records may use agentic machinery during data construction or optimization, but the deployed visual system still follows a fixed rule. Stand-alone evaluators, reward models, benchmarks, and additional foundational components are listed separately.
Controller-capability taxonomy
| Level | Controller capability | Main question | Typical controlled variables |
|---|---|---|---|
| L0 | Fixed support | Is the inference path predetermined? | Fixed generator, retriever, evaluator, benchmark |
| L1 | Conditioning control | What declarative specification should be provided to a predetermined visual executor? | Prompt, layout, reference, knowledge, storyboard, motion plan |
| L2 | Execution control | Which visual operation should be invoked, how, and when? | Generator/editor identity, generation mode, artifact-mutating tool calls, invocation order |
| L3 | Outcome-adaptive control | What should happen after observing the result? | Revision, editing, rerouting, regeneration, stopping |
| L4 | Experience-adaptive control | How should completed trajectories change future decisions? | Long-term memory, skill, capability profile, policy |
The controller-capability levels form a progression above the L0 boundary:
conditions  ->  execution  ->  current trajectory  ->  future trajectories
    L1              L2                 L3                      L4
Modality tags used below are Image, Editing, Video, Slide, UI, 3D, and World.
The decisive boundary is decision-making scope, not architectural complexity. Multi-agent role decomposition and internal search can remain L1 when they only construct a specification. L2 requires the controller to invoke actual visual generation, editing, rendering, or artifact-mutating operations. L3 additionally requires a causal outcome-to-action link in the current trajectory, and L4 requires a persistent update across independent tasks. See TAXONOMY.md for the decision procedure, counterexamples, and evidence policy.
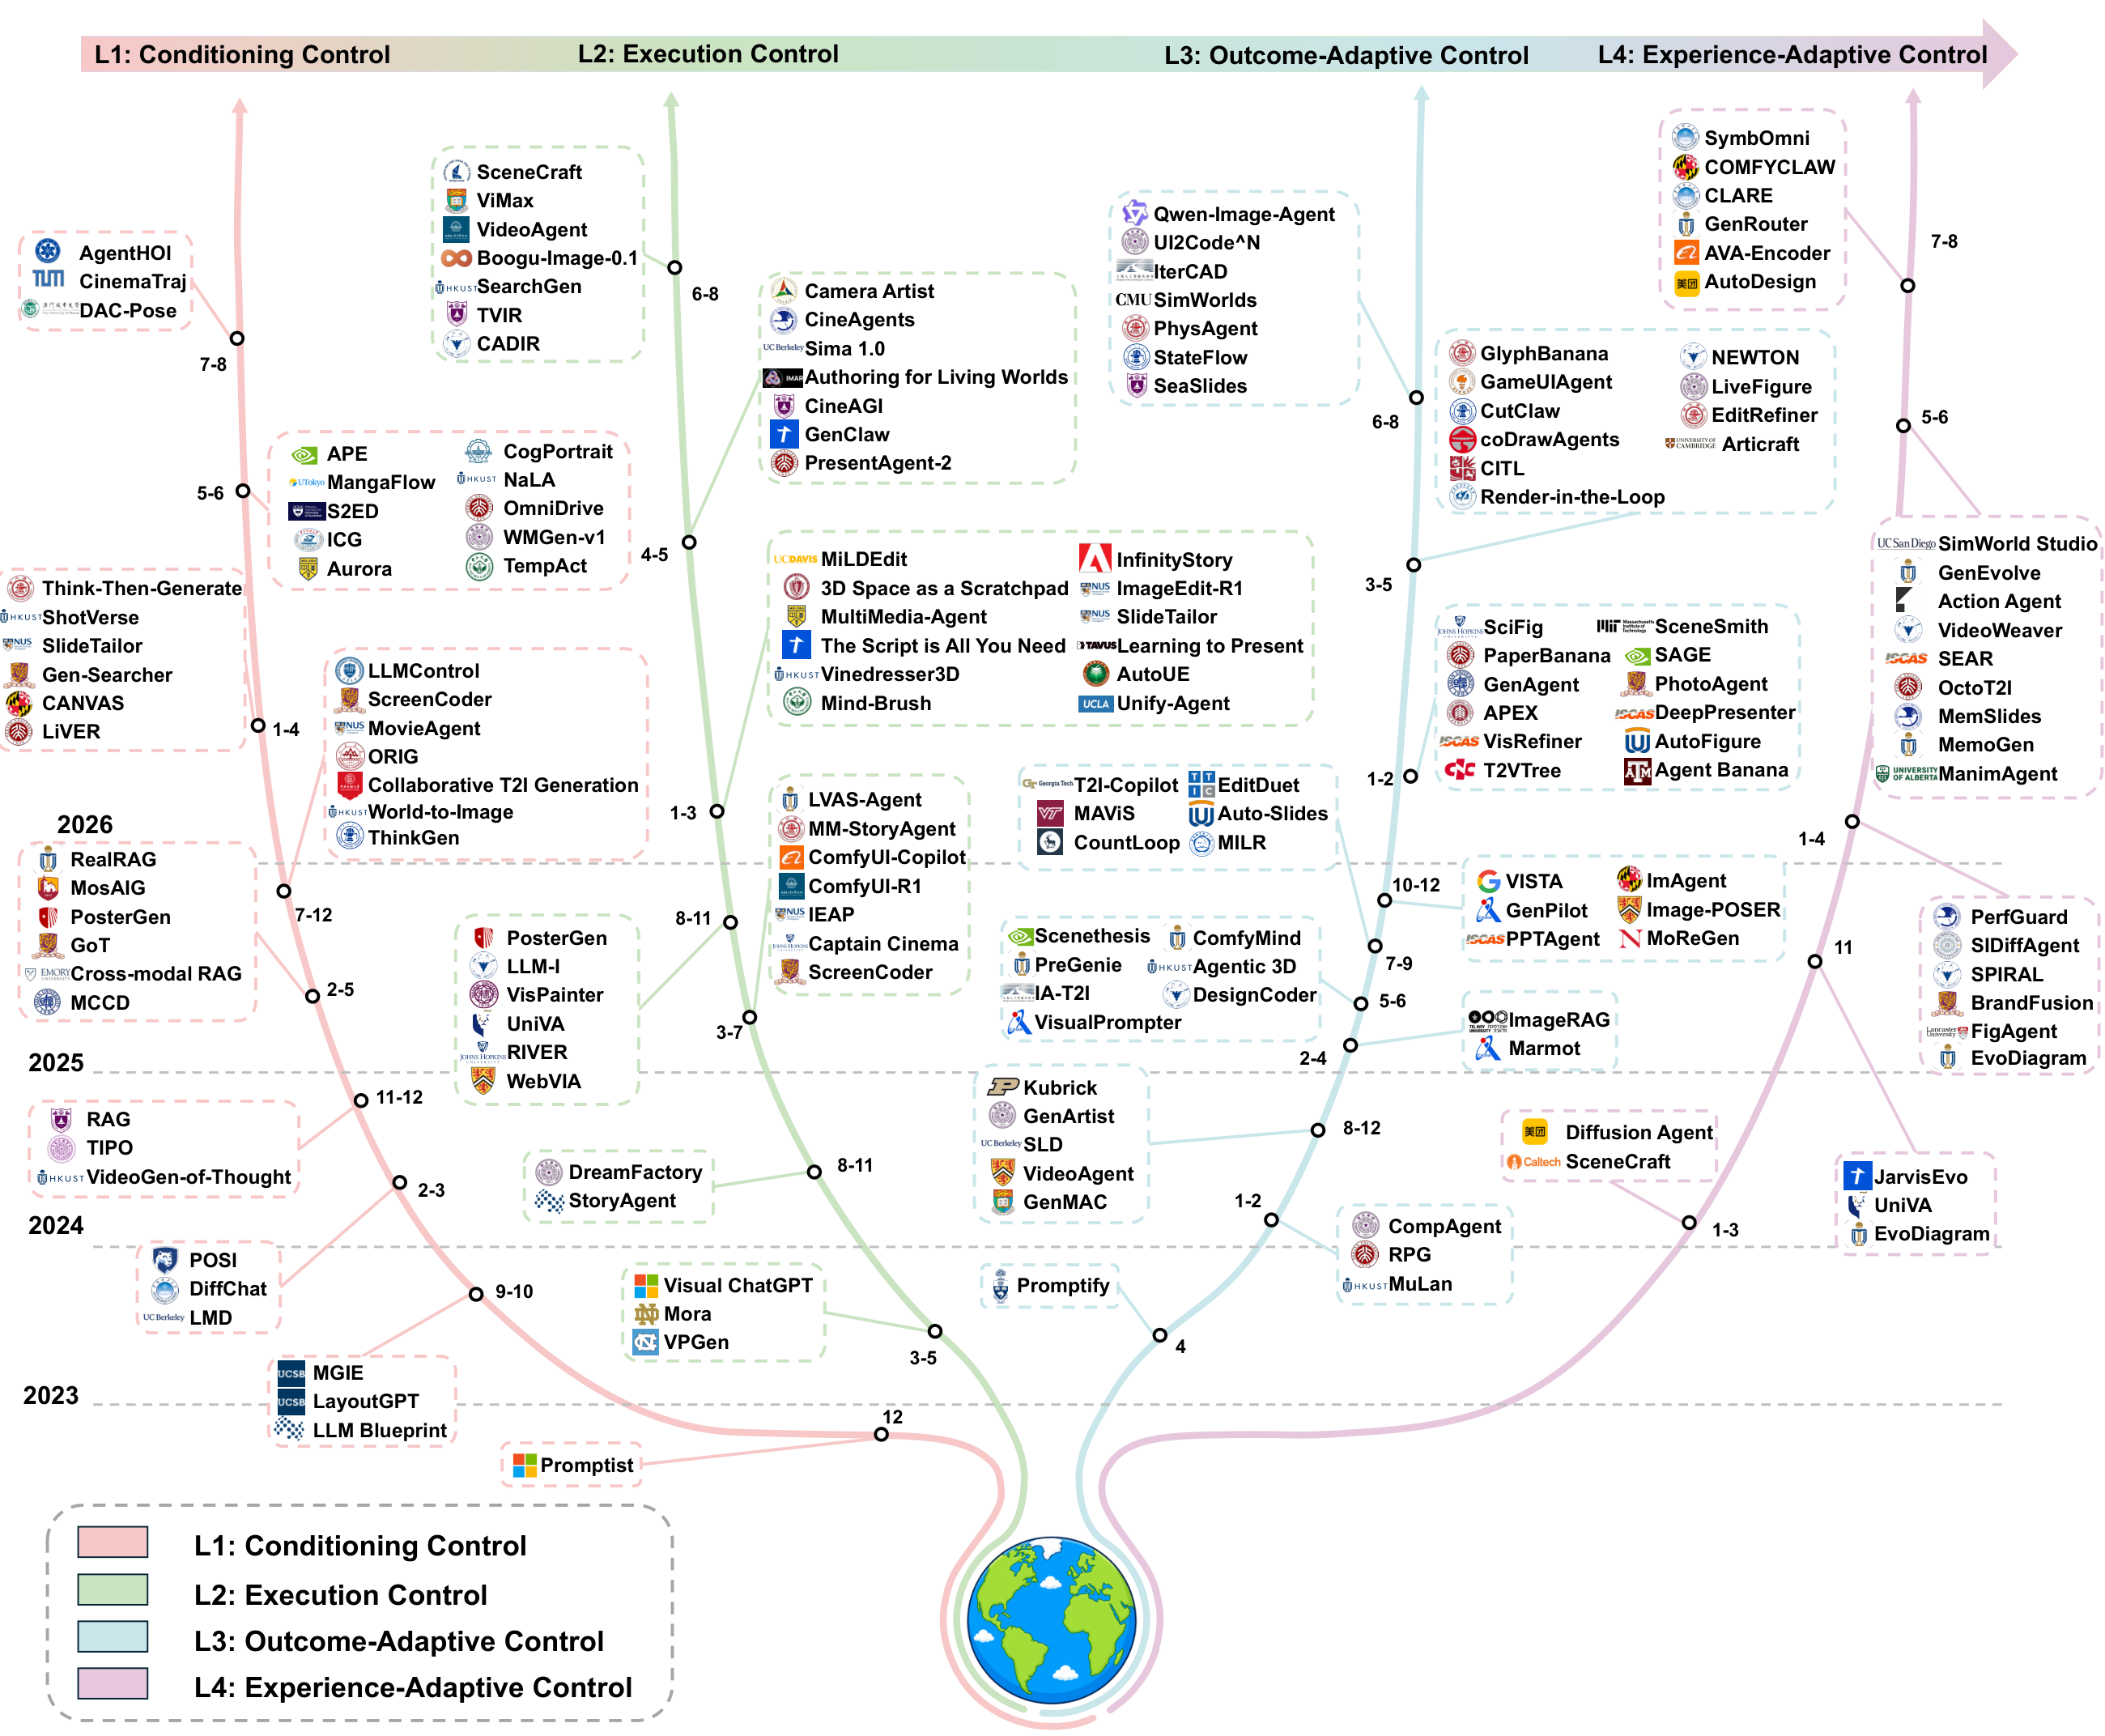
Figure 2. Representative-paper roadmap across the L1-L4 controller levels.
Vector PDF
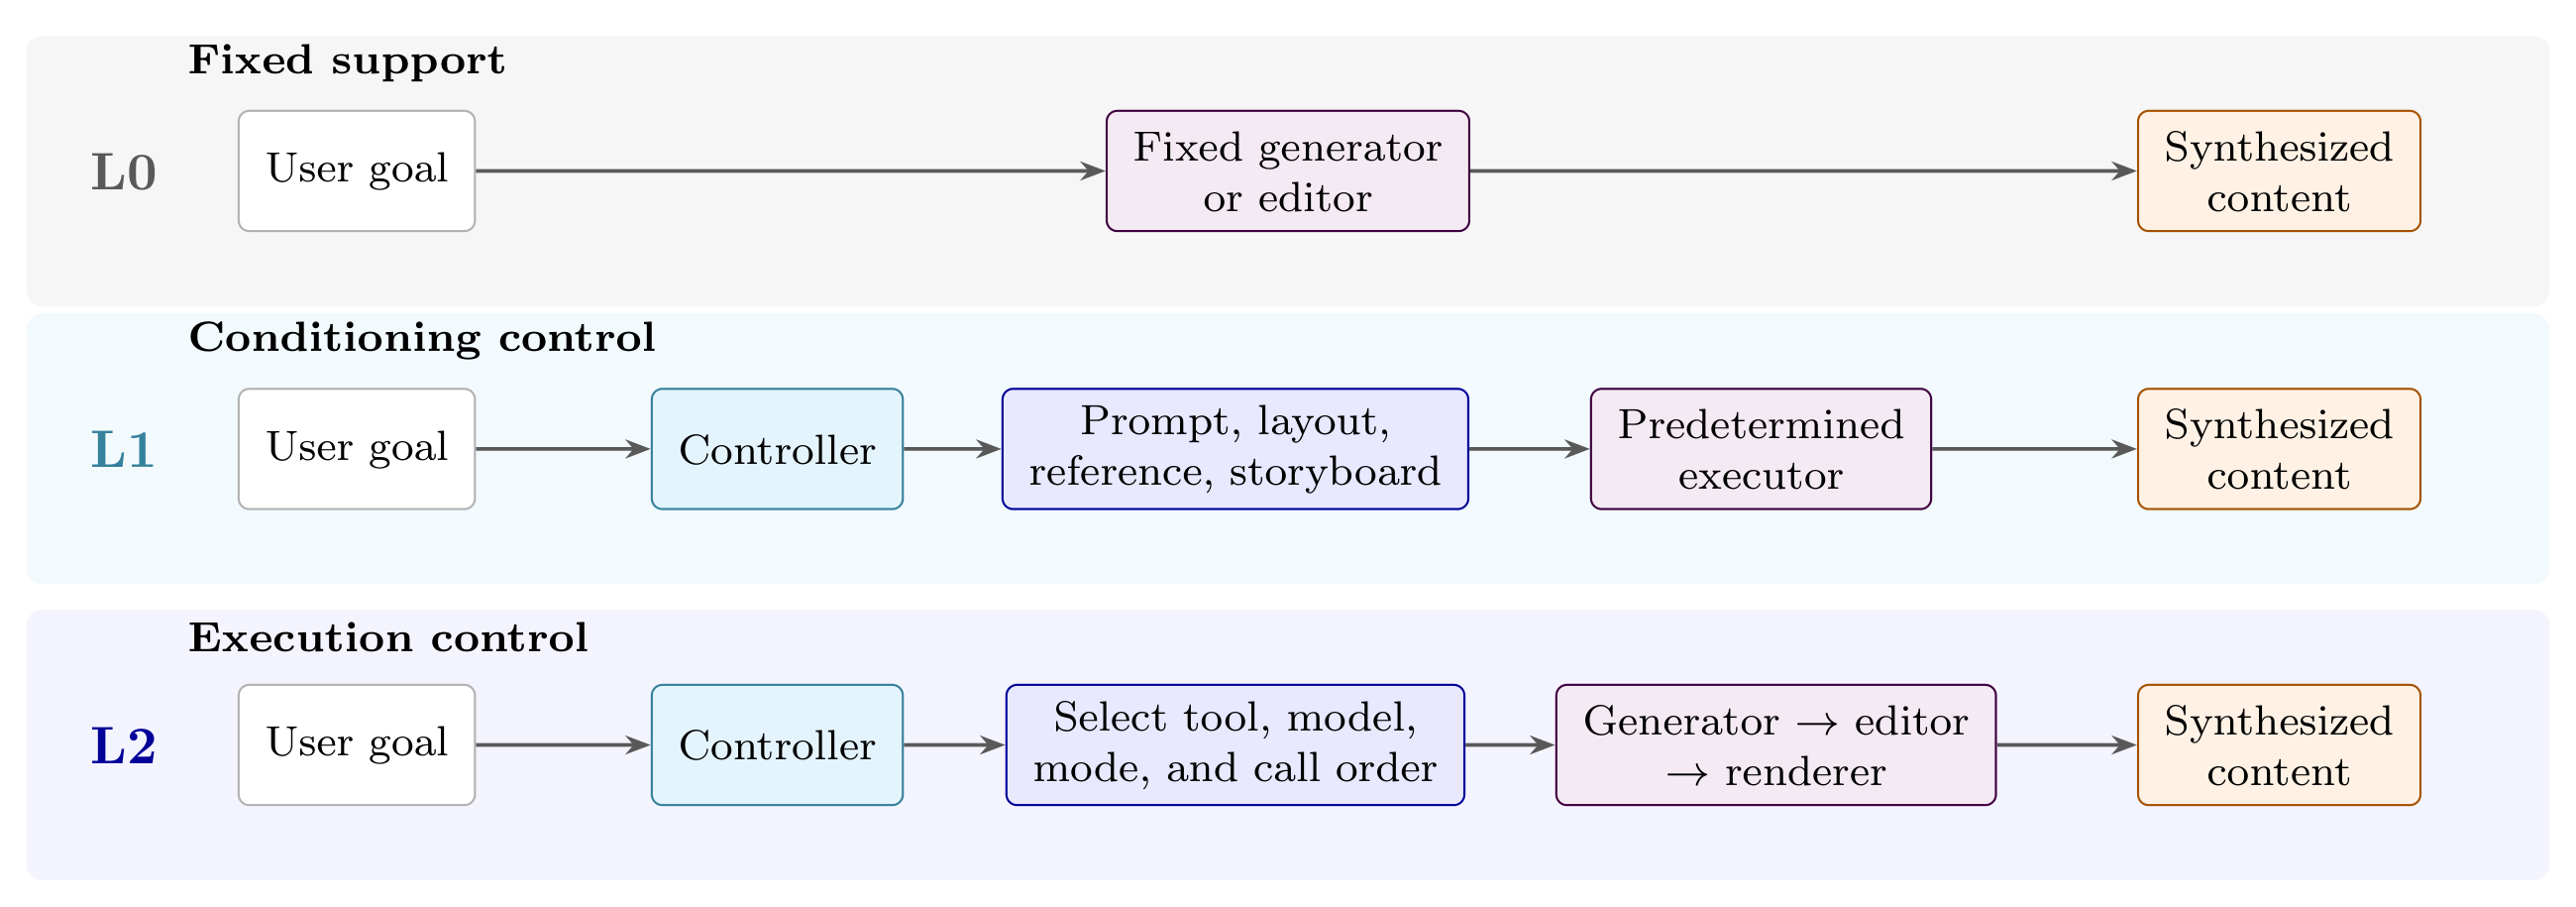
Figure 7. From L0 Fixed Support to L2 Execution Control.
Vector PDF
L0: Fixed Support
L0 Fixed Support marks the inclusion boundary rather than a peer agent level. The organizing axis is support function: generation or retrieval, data or training, evaluation, and the boundary test for fixed pipelines.
Generation and Retrieval Components
Foundational generators, editors, and fixed retrievers are cataloged under Supporting Components: the L0 Boundary.
Data Construction and Training Infrastructure
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| AgentComp | - | - | L0 | Image | Agentic preference-data construction for a fixed generator | 2025-12 |
| Gen-n-Val: Agentic Image Data Generation and Validation | GitHub  | - | L0 | Image | Synthetic-data generation and validation pipeline | 2025-06 |
Evaluators and Benchmarks
Standalone evaluators, reward models, and benchmarks are cataloged under Evaluation, Benchmarks, and Reward Models.
Boundary Test for L0 Fixed Support
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| Presentation Slide Translation and Layout Error Correction by LLMs | - | - | L0 | Slide, Editing | Fixed candidate generation and selection | 2026-07 |
| ShareVerse | - | - | L0 | Video, World | Shared generator state without controller action selection | 2026-03 |
L1: Conditioning Control
L1 controllers construct the generator-facing specification before execution. The categories follow the primary controlled specification: textual prompts, spatial and geometric structure, retrieved evidence, temporal and camera controls, or structured content.
Textual Prompt Specifications
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| APE: Agentic Prompt Enhancer for Image Generation and Editing | - | Website | L1 | Image, Editing | Prompt enhancement | 2026-06 |
| ICG: Improving Cover Image Generation via MLLM-based Prompting and Personalized Preference Alignment | - | - | L1 | Image | Prompting and preference alignment | 2026-05 |
| ThinkGen | GitHub  | - | L1 | Image | MLLM instruction construction for a fixed diffusion transformer | 2025-12 |
| TIPO: Text to Image with Text Presampling for Prompt Optimization | GitHub  | - | L1 | Image | Prompt expansion | 2024-11 |
| DiffChat: Learning to Chat with Text-to-Image Synthesis Models | GitHub  | - | L1 | Image | Instruction-conditioned prompt modification | 2024-03 |
| POSI: Universal Prompt Optimizer for Safe Text-to-Image Generation | - | - | L1 | Image | Safety-aware prompt optimization | 2024-02 |
| MGIE: Guiding Instruction-based Image Editing via Multimodal LLMs | GitHub  | Website | L1 | Editing | Expressive edit instruction | 2023-09 |
| Promptist: Optimizing Prompts for Text-to-Image Generation | GitHub  | Website | L1 | Image | Learned prompt policy | 2022-12 |
Spatial and Geometric Specifications
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| DAC-Pose: Dual-Agent Collaborative Framework for Pose-Guided Human Generation | - | - | L1 | Image | Condition construction and planning | 2026-08 |
| NaLA: A 3D Native LLM Layout Agent for High-quality 3D Scene Generation | GitHub  | Website | L1 | 3D | Condition construction and planning | 2026-06 |
| LLMControl | - | - | L1 | Image | Grounded controls | 2025-07 |
| GoT: Reasoning for Visual Generation and Editing | GitHub  | - | L1 | Image, Editing | Generation-oriented reasoning | 2025-03 |
| Region-Aware Text-to-Image Generation via Hard Binding and Soft Refinement | GitHub  | - | L1 | Image | Region binding | 2024-11 |
| LLM Blueprint | GitHub  | - | L1 | Image | Structured scene description | 2023-10 |
| LayoutGPT | GitHub  | Website | L1 | Image, 3D | Layout planning | 2023-05 |
| LLM-grounded Diffusion | GitHub  | Website | L1 | Image | Bounding-box planning | 2023-05 |
Retrieved Evidence Specifications
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| One Image is All You Need: Agentic One-Shot Image Generation via Text-Based World Models for Long-Tail Spatial Perception | - | - | L1 | Image, World | Condition construction and planning | 2026-06 |
| Gen-Searcher | GitHub  | Website | L1 | Image, World | Learned search for generation context | 2026-03 |
| Open Multimodal Retrieval-Augmented Factual Image Generation | GitHub  | Website | L1 | Image | Condition construction and planning | 2025-10 |
| World-to-Image | GitHub  | - | L1 | Image, World | Agent-driven knowledge grounding | 2025-10 |
| Cross-modal RAG | GitHub  | - | L1 | Image | Sub-dimensional retrieval | 2025-05 |
| RealRAG | GitHub  | - | L1 | Image | Self-reflective retrieval training | 2025-02 |
| When Cultures Meet: Multicultural Text-to-Image Generation | GitHub  | - | L1 | Image | Condition construction and planning | 2025-02 |
Temporal and Camera Specifications


Structured Content Specifications


L2: Execution Control
L2 controllers select and invoke actual visual operations before observing their outcomes. The categories follow the primary executable object: model and tool operations, image and structured-graphic operations, video and audiovisual operations, document and interface operations, or 3D, CAD, and world operations.
Model and Tool Operations
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| Search Beyond What Can Be Taught: Evolving the Knowledge Boundary in Agentic Visual Generation (SearchGen) | GitHub  | Website | L1+L2 | Image, World | Selective image/web search, evidence filtering, and prompt integration | 2026-07 |
| Boogu-Image-0.1: Boosting Open Agentic Multimodal Generation via Understanding under a Minimal Budget | GitHub  | Website | L1+L2 | Image | Tool and workflow orchestration | 2026-07 |
| GenClaw: Code-Driven Agentic Image Generation | GitHub  | - | L1+L2 | Image | Code-driven canvas operations | 2026-05 |
| Mind-Brush | GitHub  | - | L1+L2 | Image, Editing, World | Search/reasoning routing and generation/editing mode selection | 2026-02 |
| LLM-I: LLMs are Naturally Interleaved Multimodal Creators | GitHub  | - | L1+L2 | Image | Search, generation, code, and editing tools | 2025-09 |
| ComfyUI-Copilot: An Intelligent Assistant for Automated Workflow Development | GitHub  | - | L1+L2 | Image | Tool and workflow orchestration | 2025-06 |
| ComfyUI-R1: Exploring Reasoning Models for Workflow Generation | GitHub | - | L1+L2 | Image | Tool and workflow orchestration | 2025-06 |
| Policy Optimized Text-to-Image Pipeline Design | - | - | L1+L2 | Image | Generator and processing-block selection | 2025-05 |
| Visual ChatGPT | GitHub  | - | L1+L2 | Image, Editing | Visual foundation model orchestration | 2023-03 |
Image and Structured-Graphic Operations
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| SceneCraft: Interactive System for Image Editing via Scene Graph | - | - | L1+L2 | Image, Editing | User-directed graph editing and model dispatch | 2026-06 |
| ImageEdit-R1: Boosting Multi-Agent Image Editing via Reinforcement Learning | GitHub  | - | L1+L2 | Image, Editing | Learned decomposition, sequencing, and open-loop edit execution | 2026-03 |
| MiLDEdit: Reasoning-Based Multi-Layer Design Document Editing | - | - | L1+L2 | Image, Editing | Tool and workflow orchestration | 2026-01 |
| From Pixels to Paths: A Multi-Agent Framework for Editable Scientific Illustration | GitHub  | - | L1+L2 | Image, Editing | Tool and workflow orchestration | 2025-10 |
| Image Editing as Programs with Diffusion Models | GitHub  | Website | L1+L2 | Editing | Atomic editing-program execution | 2025-06 |
| Visual Programming for Text-to-Image Generation and Evaluation | GitHub  | Website | L1+L2 | Image | Executable visual program | 2023-05 |
Video and Audiovisual Operations
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| VideoCoCo: Code-as-CoT for Physically-Consistent Video Generation via an Agentic Dual-Engine System | GitHub  | - | L1+L2 | Video, 3D | Executable Blender simulation and draft-conditioned video editing | 2026-07 |
| VideoAgent: All-in-One Framework for Video Understanding and Editing | GitHub  | - | L1+L2 | Video, Editing | Tool and workflow orchestration | 2026-06 |
| ViMax | GitHub  | - | L1+L2 | Video | Multi-role video workflow with best-of-k quality selection | 2026-06 |
| CineAgents | - | - | L1+L2 | Video, Editing | Narrative-memory-grounded blueprint and one-pass tool assembly | 2026-04 |
| A Versatile Multimodal Agent for Multimedia Content Generation | - | - | L1+L2 | Image, Video | Tool and workflow orchestration | 2026-01 |
| The Script is All You Need: An Agentic Framework for Long-Horizon Dialogue-to-Cinematic Video Generation | GitHub  | Website | L1+L2 | Video | Tool and workflow orchestration | 2026-01 |
| Text-Driven Reasoning Video Editing via Reinforcement Learning | - | - | L1+L2 | Video, Editing | Reason-then-edit execution | 2025-11 |
| Long-Video Audio Synthesis with Multi-Agent Collaboration | GitHub  | Website | L1+L2 | Video | Audio workflow orchestration | 2025-03 |
| VisAgent | - | - | L1+L2 | Image | Narrative visualization workflow | 2025-03 |
| StoryAgent | - | - | L1+L2 | Image, Video | Storyboard and character workflow | 2024-11 |
| DreamFactory | - | - | L1+L2 | Video | Multi-scene workflow | 2024-08 |
| Mora | GitHub  | - | L1+L2 | Video | Multi-agent video modules | 2024-03 |
Document and Interface Operations
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| TVIR: Building Deep Research Agents Towards Text-Visual Interleaved Report Generation | GitHub  | Website | L1+L2 | Image | Tool and workflow orchestration | 2026-06 |
| PresentAgent-2: Towards Generalist Multimodal Presentation Agents | GitHub  | Website | L1+L2 | Slide | Tool and workflow orchestration | 2026-05 |
3D, CAD, and World Operations
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| CADIR: A Cross-Backend Editable Intermediate Representation for Agentic CAD Generation | - | - | L1+L2 | 3D, Editing | Tool and workflow orchestration | 2026-08 |
| Unify-Agent | GitHub  | - | L1+L2 | Image, World | Search-grounded generation orchestration | 2026-03 |
| AutoUE: Automated Generation of 3D Games in Unreal Engine via Multi-Agent Systems | GitHub  | - | L1+L2 | 3D | Tool and workflow orchestration | 2026-03 |
| Vinedresser3D: Agentic Text-guided 3D Editing | - | - | L1+L2 | 3D, Editing | View selection and 3D editing orchestration | 2026-02 |
| 3D Space as a Scratchpad for Editable Text-to-Image Generation | - | Website | L1+L2 | 3D, Editing | 3D scratchpad tool orchestration | 2026-01 |
L3: Outcome-Adaptive Control
L3 controllers use an observed result to change a later generation action within the current task. The categories follow the decisive feedback source: perceptual outcomes, structured and execution state, physical constraints, or explicit human review.
Perceptual Outcome Feedback
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| Beyond Starry Night: Shortcut-Aware Control-State Planning for Artist-Grounded Text to Image Generation | - | - | L1+L3 | Image | Execute-evaluate-reflect prompt correction | 2026-08 |
| VisPuzzle: Task-Aware Composite Visualization Construction | GitHub  | Dataset | L1+L2+L3 | Image | Outcome-aware verification and revision | 2026-08 |
| ParticleGen: A Multi-Agent System for Particle Effects Generation | - | - | L1+L2+L3 | Video, 3D | Rendered particle-effect feedback | 2026-08 |
| ToolArtist: Tool-Using Unified Multimodal Models for Agentic Image Generation | GitHub  | Dataset | L1+L2+L3 | Image, World | Unified search, native drawing, inspection, and revision | 2026-08 |
| Domain-Grounded Candidate Selection for Agentic Image Editing: A Shadow Removal Case | - | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-08 |
| DrawAI: Agentic Benchmark and Workflow for Making Raster Images Editable | GitHub  | Website | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-08 |
| What to Edit Next: Visually Aligned Image-Editing Follow-Up Suggestions in Conversational Systems | - | - | L1+L3 | Image, Editing | Current-image-conditioned follow-up edit policy | 2026-08 |
| Beyond Trial-and-Error: Agentic Optimization for Image-to-Video Adherence | - | - | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-08 |
| WorldClaw: Agentic 3D Open-World Generation at Scale | - | Website | L1+L2+L3 | 3D | Render-based 3D world refinement | 2026-08 |
| PosterMELD: Multi-Agent Paper-to-Poster Generation for Controllable Design Diversity with Editable Print-Ready Outputs | GitHub  | Website | L1+L2+L3 | Image, Editing | VLM-routed poster repair | 2026-08 |
| PRISM: Prompt Refinement via Image-grounded Self-rewarding Mechanism for Text-to-Image Generation | - | Code | L1+L2+L3 | Image | Outcome-aware verification and revision | 2026-07 |
| JarvisHub: An Open Harness for Canvas-Native Multimodal Creative Agents | GitHub  | Website | L1+L2+L3 | Image | Canvas-state inspection, feedback-guided revision, and recovery | 2026-07 |
| Knowledge-Centric Agents for Workflow Generation in ComfyUI | - | - | L1+L2+L3 | Image | Workflow self-refinement | 2026-07 |
| PairCoder++: Pair Programming as a Universal Paradigm for Verified Code-Driven Multimodal and Structured-Artifact Generation | GitHub  | Website | L1+L2+L3 | Image | Outcome-aware verification and revision | 2026-07 |
| CanvasAgent: Enabling Complex Image Creation and Editing via Visual Tool Orchestration | - | Dataset | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-07 |
| Cognitive-structured Multimodal Agent for Multimodal Understanding, Generation, and Editing | GitHub  | Website | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-07 |
| GMO-E$^2$DIT: Grounded Multi-Operation Editing for E-Commerce Images | - | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-07 |
| SAGE: Structured Agentic Graph Editing for Software Diagrams | GitHub  | - | L1+L2+L3 | Image, Editing | Structured diagram validation and repair | 2026-07 |
| What Can I Edit? Open-Ended Strategy Discovery and the Emotion Editability Landscape | - | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-07 |
| FilmWorld: Agentic Novel-to-Film Generation through Dynamic Cinematic World Modeling | GitHub  | Website | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-07 |
| PhysAgent: Reflective Agentic Physics Control for Physically Plausible Video Generation | GitHub  | Website | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-07 |
| Exploring Agentic Workflows for Generating High Quality Math Visual Aids | - | - | L1+L2+L3 | Image | VLM-reviewed visual-aid refinement | 2026-07 |
| RS-Gen: A Multi-Stage Agentic Framework for Reasoning and Search-Augmented Image Generation | - | - | L1+L2+L3 | Image | Adaptive routing and generate-verify-correct loop | 2026-06 |
| MetaPoint | - | - | L1+L3 | Image | Generate-reflect-execute spatial correction | 2026-06 |
| Qwen-Image-Agent | - | - | L1+L2+L3 | Image, World | Search, memory, editing, and feedback | 2026-06 |
| InterleaveThinker: Reinforcing Agentic Interleaved Generation | GitHub  | Website | L1+L2+L3 | Image | Outcome-aware verification and revision | 2026-06 |
| IEA: Amateur-Friendly Conversational Image Editing Agent via Three Stages of Multitask Alignment | GitHub  | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-06 |
| Taming I2V models for Image HOI Editing: A Cognitive Benchmark and Agentic Self-Correcting Framework | GitHub  | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-06 |
| Bridging Creative Intent and Visual Quality: Creator-Driven Recurrent Video Generation with Agentic Feedback Loops | - | - | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-06 |
| Closed-Loop Triplet Synergistic Generation for Long-Form Video | - | - | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-06 |
| IterCAD: An Iterative Multimodal Agent for Visually-Grounded CAD Generation and Editing | - | - | L1+L2+L3 | 3D, Editing | Outcome-aware verification and revision | 2026-06 |
| SceneConductor: 3D Scene Generation from a Single Image with Multi-Agent Orchestration | GitHub  | Website | L1+L2+L3 | 3D | Planner-directed 3D scene correction | 2026-06 |
| Temporal Backtracking Search for Test-time Generative Video Reasoning | - | Website | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-06 |
| Code2UML: Agentic LLMs with context engineering for scalable software visualization | - | - | L1+L2+L3 | Image | Corrector-guided UML repair | 2026-05 |
| Generation Navigator | - | - | L1+L2+L3 | Image | State-aware action choice | 2026-05 |
| SCOPE | GitHub  | Website | L1+L2+L3 | Image | Specification-guided skill orchestration, verification, and repair | 2026-05 |
| AlphaGRPO | GitHub  | Website | L1+L3 | Image | Self-reflective verifiable rewards | 2026-05 |
| Large Language Models are Universal Reasoners for Visual Generation | - | - | L1+L3 | Image | Draft and grounded self-critique | 2026-05 |
| Latent Action Control | - | - | L1+L3 | Image | Latent diagnosis and halting | 2026-05 |
| Self-Adaptive Interleaved Visual Reasoner | GitHub  | - | L1+L3 | Image | Adaptive reflection and planning | 2026-05 |
| Crafter: A Multi-Agent Harness for Editable Scientific Figure Generation from Diverse Inputs | GitHub  | - | L1+L2+L3 | Image, Editing | Critic-refiner-convergence loop | 2026-05 |
| EditRefiner | GitHub  | - | L1+L3 | Editing | Human-aligned iterative refinement | 2026-05 |
| From Plans to Pixels: Learning to Plan and Orchestrate for Open-Ended Image Editing | - | Website | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-05 |
| LiveFigure: Generating Editable Scientific Illustration with VLM Agents | GitHub  | - | L1+L2+L3 | Image, Editing | Visual-diagnostic figure correction | 2026-05 |
| Genflow Ad Studio: A Compound AI Architecture for Brand-Aligned, Self-Correcting Video Generation | - | - | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-05 |
| One Sentence, One Drama: Personalized Short-Form Drama Generation via Multi-Agent Systems | - | - | L1+L2+L3 | Video | Multi-stage reviewer loops | 2026-05 |
| Soap2Soap: Long Cinematic Video Remaking via Multi-Agent Collaboration | GitHub  | - | L1+L2+L3 | Video | Verification-triggered video regeneration | 2026-05 |
| Self-Reasoning Agentic Framework for Narrative Product Grid-Collage Generation | - | - | L1+L3 | Image | Generation-critique loop for product collage | 2026-04 |
| Render-in-the-Loop: Vector Graphics Generation via Visual Self-Feedback | - | - | L1+L2+L3 | Image | Outcome-aware verification and revision | 2026-04 |
| FiRe | - | - | L1+L3 | Image | Fine-grained multimodal reflection | 2026-04 |
| Think in Strokes, Not Pixels | - | - | L1+L3 | Image | Interleaved draft and reflection | 2026-04 |
| CAMEO: A Conditional and Quality-Aware Multi-Agent Image Editing Orchestrator | - | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-04 |
| Making Image Editing Easier via Adaptive Task Reformulation with Agentic Executions | GitHub  | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-04 |
| Refinement via Regeneration | GitHub  | - | L1+L3 | Image, Editing | Adaptive modification space | 2026-04 |
| BOOKAGENT | GitHub  | - | L1+L2+L3 | Image, Video | Verify-then-rectify storybook generation | 2026-04 |
| Co-Director | GitHub  | Website | L1+L2+L3 | Video | MLLM feedback-driven video refinement | 2026-04 |
| SCMAPR: Self-Correcting Multi-Agent Prompt Refinement for Complex-Scenario Text-to-Video Generation | GitHub  | - | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-04 |
| Vision-Guided Iterative Refinement for Frontend Code Generation | - | - | L1+L2+L3 | UI | VLM critic, rendered feedback, and iterative code revision | 2026-04 |
| Agentic Flow Steering and Parallel Rollout Search for Spatially Grounded Text-to-Image Generation | - | - | L1+L2+L3 | Image | Outcome-aware verification and revision | 2026-03 |
| coDrawAgents | GitHub  | - | L1+L2+L3 | Image | Multi-round scene construction | 2026-03 |
| GlyphBanana | GitHub  | - | L1+L2+L3 | Image | Generated-glyph inspection and iterative refinement | 2026-03 |
| VisionCreator: A Native Visual-Generation Agentic Model with Understanding, Thinking, Planning and Creation | - | - | L1+L2+L3 | Image | Tool-feedback-grounded goal verification and revision | 2026-03 |
| Feynman: Knowledge-Infused Diagramming Agent for Scalable Visual Designs | - | - | L1+L2+L3 | Image | Rendered diagram feedback | 2026-03 |
| StruVis: Enhancing Reasoning-based Text-to-Image Generation via Thinking with Structured Vision | - | - | L1+L3 | Image | Intermediate-image inspection and refinement | 2026-03 |
| GEMS | GitHub  | Website | L1+L2+L3 | Image, Editing | Current-trajectory working and experience memory | 2026-03 |
| RAISE: Requirement-Adaptive Evolutionary Refinement for Training-Free Text-to-Image Alignment | GitHub  | - | L1+L2+L3 | Image | Outcome-aware verification and revision | 2026-03 |
| IMAGAgent: Orchestrating Multi-Turn Image Editing via Constraint-Aware Planning and Reflection | GitHub  | - | L1+L2+L3 | Image, Editing | Within-request edit, critique, retry, and rollback state | 2026-03 |
| MSRAMIE: Multimodal Structured Reasoning Agent for Multi-instruction Image Editing | - | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-03 |
| Towards Context-Aware Image Anonymization with Multi-Agent Reasoning | - | - | L1+L2+L3 | Image, Editing | PDCA anonymization refinement | 2026-03 |
| SceneAssistant: A Visual Feedback Agent for Open-Vocabulary 3D Scene Generation | GitHub  | - | L1+L2+L3 | 3D | Outcome-aware verification and revision | 2026-03 |
| VQQA: An Agentic Approach for Video Evaluation and Quality Improvement | - | Website | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-03 |
| WorldAgents: Can Foundation Image Models be Agents for 3D World Models? | - | Website | L1+L2+L3 | 3D | Outcome-aware verification and revision | 2026-03 |
| GameUIAgent: An LLM-Powered Framework for Automated Game UI Design with Structured Intermediate Representation | - | - | L1+L2+L3 | UI | Non-regressive VLM reflection | 2026-03 |
| M3 | GitHub  | - | L1+L2+L3 | Image | Multi-agent visual diagnosis | 2026-02 |
| AutoFigure: Generating and Refining Publication-Ready Scientific Illustrations | GitHub  | Dataset | L1+L2+L3 | Image | Outcome-aware verification and revision | 2026-02 |
| UniReason 1.0 | GitHub  | - | L1+L3 | Image, Editing, World | Knowledge reasoning and correction | 2026-02 |
| UniT | - | Website | L1+L3 | Image | Sequential generation and refinement | 2026-02 |
| Agent Banana | GitHub  | Website | L1+L2+L3 | Editing | Multi-step reasoning and tools | 2026-02 |
| PhotoAgent | - | Website | L1+L2+L3 | Editing | Long-horizon aesthetic planning | 2026-02 |
| RetouchIQ: MLLM Agents for Instruction-Based Image Retouching with Generalist Reward | - | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-02 |
| AnimeAgent: Is the Multi-Agent via Image-to-Video models a Good Disney Storytelling Artist? | - | - | L1+L2+L3 | Video | Reviewer-guided dope-sheet refinement from generated trajectories | 2026-02 |
| PaperX: A Unified Framework for Multimodal Academic Presentation Generation with Scholar DAG | GitHub  | - | L1+L2+L3 | Slide | Rendered-slide VLM feedback and content-layout revision | 2026-02 |
| DeepPresenter: Environment-Grounded Reflection for Agentic Presentation Generation | GitHub  | Dataset | L1+L2+L3 | Slide | Outcome-aware verification and revision | 2026-02 |
| VisRefiner: Learning from Visual Differences for Screenshot-to-Code Generation | - | - | L1+L3 | UI | Difference-aligned training and render-conditioned self-refinement | 2026-02 |
| ComfySearch: Autonomous Exploration and Reasoning for ComfyUI Workflows | GitHub  | - | L1+L2+L3 | Image | Validation-guided graph repair | 2026-01 |
| GenAgent | - | - | L1+L2+L3 | Image | Trained tool use and reflection | 2026-01 |
| Vision-as-Inverse-Graphics Agent via Interleaved Multimodal Reasoning | GitHub  | Website | L1+L2+L3 | Image, 3D, World | Code-render-inspect repair loop | 2026-01 |
| APEX: Academic Poster Editing Agentic Expert | GitHub  | - | L1+L2+L3 | Image, Editing | Render-review-adjust poster editing | 2026-01 |
| Agentic Retoucher | GitHub  | - | L1+L2+L3 | Image, Editing | Defect localization and retouching | 2026-01 |
| SciFig: Towards Automating Editable Figure Generation for Scientific Papers | - | Website | L1+L2+L3 | Image, Editing | VLM-guided editable-figure refinement | 2026-01 |
| PaperBanana: Automating Academic Illustration for AI Scientists | GitHub  | Website | L1+L2+L3 | 3D | Outcome-aware verification and revision | 2026-01 |
| DraCo: Draft as CoT for Text-to-Image Preview and Rare Concept Generation | GitHub  | - | L1+L3 | Image | Draft verification and selective correction | 2025-12 |
| CoAgent | - | - | L1+L2+L3 | Video | Cross-segment consistency agent | 2025-12 |
| FronTalk: Benchmarking Front-End Development as Conversational Code Generation with Multi-Modal Feedback (AceCoder) | GitHub  | Website | L1+L2+L3 | UI | Web-agent critique and regression-aware regeneration | 2025-12 |
| Image-POSER | - | - | L1+L2+L3 | Image, Editing | Reflective expert routing | 2025-11 |
| ImAgent | - | - | L1+L2+L3 | Image | Policy-controlled test-time actions | 2025-11 |
| MIRA: Multimodal Iterative Reasoning Agent for Image Editing | - | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2025-11 |
| UI2Code^N: UI-to-Code Generation as Interactive Visual Optimization | GitHub  | Website | L1+L3 | UI | Unified render-inspect-refine model with test-time scaling | 2025-11 |
| GenPilot | GitHub  | - | L1+L2+L3 | Image | Error analysis and prompt refinement | 2025-10 |
| Hollywood Town | - | Website | L1+L2+L3 | Video | Adaptive cross-modal workflow | 2025-10 |
| VISTA: A Test-Time Self-Improving Video Generation Agent | - | Website | L1+L3 | Video | Test-time video prompt refinement | 2025-10 |
| PromptSculptor | - | - | L1+L2+L3 | Image | Multi-agent self-evaluation | 2025-09 |
| Maestro | - | - | L1+L2+L3 | Image | Critic-guided orchestration | 2025-09 |
| Interleaving Reasoning for Better Text-to-Image Generation | GitHub  | - | L1+L3 | Image | Image-conditioned textual reflection | 2025-09 |
| MILR | GitHub  | Website | L1+L3 | Image | Test-time latent search | 2025-09 |
| CountLoop | - | Website | L1+L3 | Image | Counting feedback loop | 2025-08 |
| Uni-CoT | GitHub  | Website | L1+L3 | Image | Closed-loop micro-level visual reevaluation | 2025-08 |
| A Unified Multi-Agent Framework for Universal Multimodal Understanding and Generation | - | - | L1+L2+L3 | Image | Growth-aware multimodal search | 2025-08 |
| An LLM-LVLM Driven Agent for Iterative and Fine-Grained Image Editing | - | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2025-08 |
| Talk2Image: A Multi-Agent System for Multi-Turn Image Generation and Editing | GitHub  | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2025-08 |
| AniME | - | - | L1+L2+L3 | Video | Adaptive animation planning | 2025-08 |
| MAViS | - | - | L1+L2+L3 | Video | Explore-examine-enhance stage loops | 2025-08 |
| Test-time Prompt Refinement | - | - | L1+L3 | Image | Iterative visual diagnosis | 2025-07 |
| T2I-Copilot | GitHub  | - | L1+L2+L3 | Image | Evaluator-controlled regeneration | 2025-07 |
| Beyond Simple Edits: X-Planner for Complex Instruction-Based Image Editing | - | Website | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2025-07 |
| PointT2I | - | - | L1+L3 | Image | Semantic feedback on generated pose images | 2025-06 |
| RATTPO | GitHub  | - | L1+L3 | Image | Reward-history prompt search | 2025-06 |
| VisualPrompter | GitHub  | - | L1+L3 | Image | Image-grounded prompt repair | 2025-06 |
| AniMaker: Multi-Agent Animated Storytelling with MCTS-Driven Clip Generation | GitHub  | Website | L1+L2+L3 | Video | MCTS candidate generation and review | 2025-06 |
| DesignCoder: Hierarchy-Aware and Self-Correcting UI Code Generation with Large Language Models | - | - | L1+L2+L3 | UI | Hierarchy-aware generation and vision-guided self-correction | 2025-06 |
| IA-T2I: Internet-Augmented Text-to-Image Generation | - | - | L1+L3 | Image | Generated-image self-reflection and multi-round regeneration | 2025-05 |
| ComfyMind: Toward General-Purpose Generation via Tree-Based Planning and Reactive Feedback | GitHub  | Website | L1+L2+L3 | Image | Outcome-aware verification and revision | 2025-05 |
| UniGen | - | - | L1+L3 | Image | Candidate verification and selection | 2025-05 |
| Scenethesis | - | Website | L1+L2+L3 | 3D | Render-guided scene construction | 2025-05 |
| Marmot: Object-Level Self-Correction via Multi-Agent Reasoning | - | - | L1+L2+L3 | Image | Outcome-aware verification and revision | 2025-04 |
| Twin Co-Adaptive Dialogue | - | - | L1+L3 | Image | Progressive dialogue and image updates | 2025-04 |
| CREA: A Collaborative Multi-Agent Framework for Creative Image Editing and Generation | GitHub  | Website | L1+L2+L3 | Image, Editing | Critic-guided creative image refinement | 2025-04 |
| ComfyGPT: A Self-Optimizing Multi-Agent System for Comprehensive ComfyUI Workflow Generation | GitHub  | Website | L1+L2+L3 | Image | Execute-and-refine workflow control | 2025-03 |
| FoX | - | - | L1+L3 | Image | Planning, acting, reflection, correction | 2025-03 |
| ImageRAG | GitHub  | Website | L1+L2+L3 | Image | Generation-gap-triggered retrieval | 2025-02 |
| MotionAgent | GitHub  | - | L1+L3 | Video | Optional rendered-video rethinking and motion-control regeneration | 2025-02 |
| Image CoT | GitHub  | - | L1+L3 | Image | Stepwise generation and verification | 2025-01 |
| PPTAgent: Generating and Evaluating Presentations Beyond Text-to-Slides | GitHub | - | L1+L2+L3 | Slide | Execution-feedback slide correction | 2025-01 |
| PASTA: Preference Adaptive and Sequential Text-to-Image Generation | - | Dataset | L1+L3 | Image | Sequential preference feedback | 2024-12 |
| GenMAC | GitHub  | Website | L1+L2+L3 | Video | Verification and correction | 2024-12 |
| Anim-Director | GitHub | - | L1+L2+L3 | Video | Self-reflective animation candidate selection | 2024-08 |
| Kubrick | - | Website | L1+L2+L3 | Video, 3D | Screenshot-guided Blender repair | 2024-08 |
| GenArtist | - | Website | L1+L2+L3 | Image, Editing | Tool tree, verification, and repair | 2024-07 |
| OPT2I: Improving Text-to-Image Consistency via Automatic Prompt Optimization | - | - | L1+L3 | Image | Rendered-score prompt search | 2024-03 |
| MuLan | GitHub  | - | L1+L3 | Image | Progressive construction | 2024-02 |
| RPG: Recaptioning, Planning, and Generating with Multimodal LLMs | GitHub  | - | L1+L3 | Image | Optional rendered-image self-refinement | 2024-01 |
| CompAgent | - | - | L1+L3 | Image | Visual-feedback correction | 2024-01 |
| Self-correcting LLM-controlled Diffusion Models | GitHub  | Website | L1+L3 | Image | Requirement inspection and repair | 2023-11 |
Structured and Execution Feedback


Physical and Constraint Feedback


Human Review Feedback
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| CoGen3D: An Agentic Human-AI Co-Design Pipeline for 3D Asset Generation for Virtual Reality | - | - | L1+L2+L3 | 3D | Human-confirmed concept refinement before 3D generation | 2026-07 |
| OrchestrXR: A Multi-Agent System for Idea-to-Prototype XR Study Authoring | - | - | L1+L2+L3 | World | User-reviewed patch-and-revise XR authoring | 2026-07 |
| From Idea to Co-Creation: A Planner-Actor-Critic Framework for Agent Augmented 3D Modeling | - | - | L1+L2+L3 | 3D | Outcome-aware verification and revision | 2026-01 |
| Promptify: Interactive Prompt Exploration with Large Language Models | GitHub  | - | L1+L3 | Image | Candidate-driven user feedback | 2023-04 |
L4: Experience-Adaptive Control
L4 controllers retain completed-task experience that changes decisions on later independent tasks. The categories follow the persistent carrier: capability and tool profiles, episodic and user memory, reusable procedures and skills, executable workflows and harnesses, or policy and model updates.
Capability and Tool Profiles
| Paper | GitHub | Website | Path | Modality | Persistent adaptation | Date |
|---|---|---|---|---|---|---|
| GenRouter: Unified Workflow Routing for Agentic Image Generation | GitHub  | - | L1+L2+L3+L4 | Image | Cross-task memory or skill evolution | 2026-08 |
| OctoT2I | GitHub  | - | L1+L2+L3+L4 | Image | Evolving generator capability profiles | 2026-06 |
| PerfGuard: A Performance-Aware Agent for Visual Content Generation | GitHub  | - | L1+L2+L3+L4 | Image | Execution-ranked tool preference updates | 2026-01 |
| DiffusionAgent | GitHub  | Website | L1+L2+L3+L4 | Image | Human-feedback-updated expert advantage database | 2024-01 |
Episodic and User Memory
| Paper | GitHub | Website | Path | Modality | Persistent adaptation | Date |
|---|---|---|---|---|---|---|
| MemoGen | GitHub  | - | L1+L3+L4 | Image | Cross-task episodic experience | 2026-06 |
| MemSlides: A Hierarchical Memory Driven Agent Framework for Personalized Slide Generation with Multi-turn Local Revision | GitHub  | Website | L1+L2+L3+L4 | Slide | Cross-task memory or skill evolution | 2026-06 |
| Action Agent: Agentic Video Generation Meets Flow-Constrained Diffusion | - | - | L1+L2+L3+L4 | Video | Cross-task navigation-generation memory | 2026-05 |
| BrandFusion | - | Website | L1+L2+L4 | Video | User-feedback experience pool for later brand-integration strategies | 2026-03 |
| UniVA | GitHub  | Website | L1+L2+L3+L4 | Video | Persistent trajectory and user-preference memory for later workflows | 2025-11 |
Reusable Procedures and Skills
| Paper | GitHub | Website | Path | Modality | Persistent adaptation | Date |
|---|---|---|---|---|---|---|
| ManimAgent: Self-Evolving Multimodal Agents for Visual Education | - | - | L1+L2+L3+L4 | Image | Cross-task memory or skill evolution | 2026-06 |
| Self-Evolving Agentic Image Restoration via Deliberate Planning and Intuitive Execution | - | - | L1+L2+L3+L4 | Image, Editing | Cross-task memory or skill evolution | 2026-06 |
| GenEvolve | GitHub  | Website | L1+L2+L3+L4 | Image, Editing | Visual experience distillation into skills | 2026-05 |
| SimWorld Studio: Automatic Environment Generation with Evolving Coding Agent for Embodied Agent Learning | - | - | L1+L2+L3+L4 | World | Cross-task memory or skill evolution | 2026-05 |
| EvoDiagram: Agentic Editable Diagram Creation via Design Expertise Evolution | - | - | L1+L2+L3+L4 | Image, Editing | Cross-task memory or skill evolution | 2026-04 |
| SceneCraft | - | - | L1+L2+L3+L4 | 3D | Cross-query spatial skill library | 2024-03 |
Executable Workflows and Harnesses
| Paper | GitHub | Website | Path | Modality | Persistent adaptation | Date |
|---|---|---|---|---|---|---|
| AutoDesign: Meta-Harness Optimization for Long-Horizon Agentic Design | GitHub  | Website | L1+L2+L3+L4 | Image | Cross-task memory or skill evolution | 2026-08 |
| AVA-Encoder: Towards Agent-Native Video Representation Learning | GitHub  | Website | L1+L2+L3+L4 | Video | Self-evolving film-representation program | 2026-08 |
| COMFYCLAW: Self-Evolving Skill Harnesses for Image Generation Workflows | GitHub  | - | L1+L2+L3+L4 | Image | Cross-task memory or skill evolution | 2026-07 |
| VideoWeaver | GitHub  | - | L1+L2+L3+L4 | Video | Evaluation and evolution of workflow skills | 2026-06 |
| Automatic Method Illustration Generation for AI Scientific Papers via Drawing Middleware Creation, Evolution, and Orchestration | - | - | L1+L2+L3+L4 | Image | Reusable drawing-middleware evolution | 2026-03 |
Policy and Model Updates
| Paper | GitHub | Website | Path | Modality | Persistent adaptation | Date |
|---|---|---|---|---|---|---|
| Clarify Before Executing: A Self-Evolving Agent for Resolving Intent Asymmetry in 3D Tool Orchestration | GitHub  | Dataset | L1+L2+L3+L4 | 3D | Clarification-policy evolution from completed interactions | 2026-07 |
| SymbOmni: Evolving Agentic Omni Models via Symbolic Concept Learning | GitHub  | Website | L1+L2+L3+L4 | Image | Cross-task memory or skill evolution | 2026-07 |
| SPIRAL | - | Website | L1+L2+L3+L4 | Video, World | Critic-trajectory post-training | 2026-03 |
| SIDiffAgent | - | - | L1+L3+L4 | Image | Self-improving generation behavior | 2026-02 |
| JarvisEvo: Towards a Self-Evolving Photo Editing Agent with Synergistic Editor-Evaluator Optimization | - | Website | L1+L2+L3+L4 | Image, Editing | Synergistic editor-evaluator evolution | 2025-11 |
Evaluation, Benchmarks, and Reward Models
These resources evaluate outputs, trajectories, controllers, or supporting signals. A stand-alone evaluator is not assigned an agenticity level. When an agent uses its feedback to choose a new generation action, the complete system may qualify as L3 or L4.
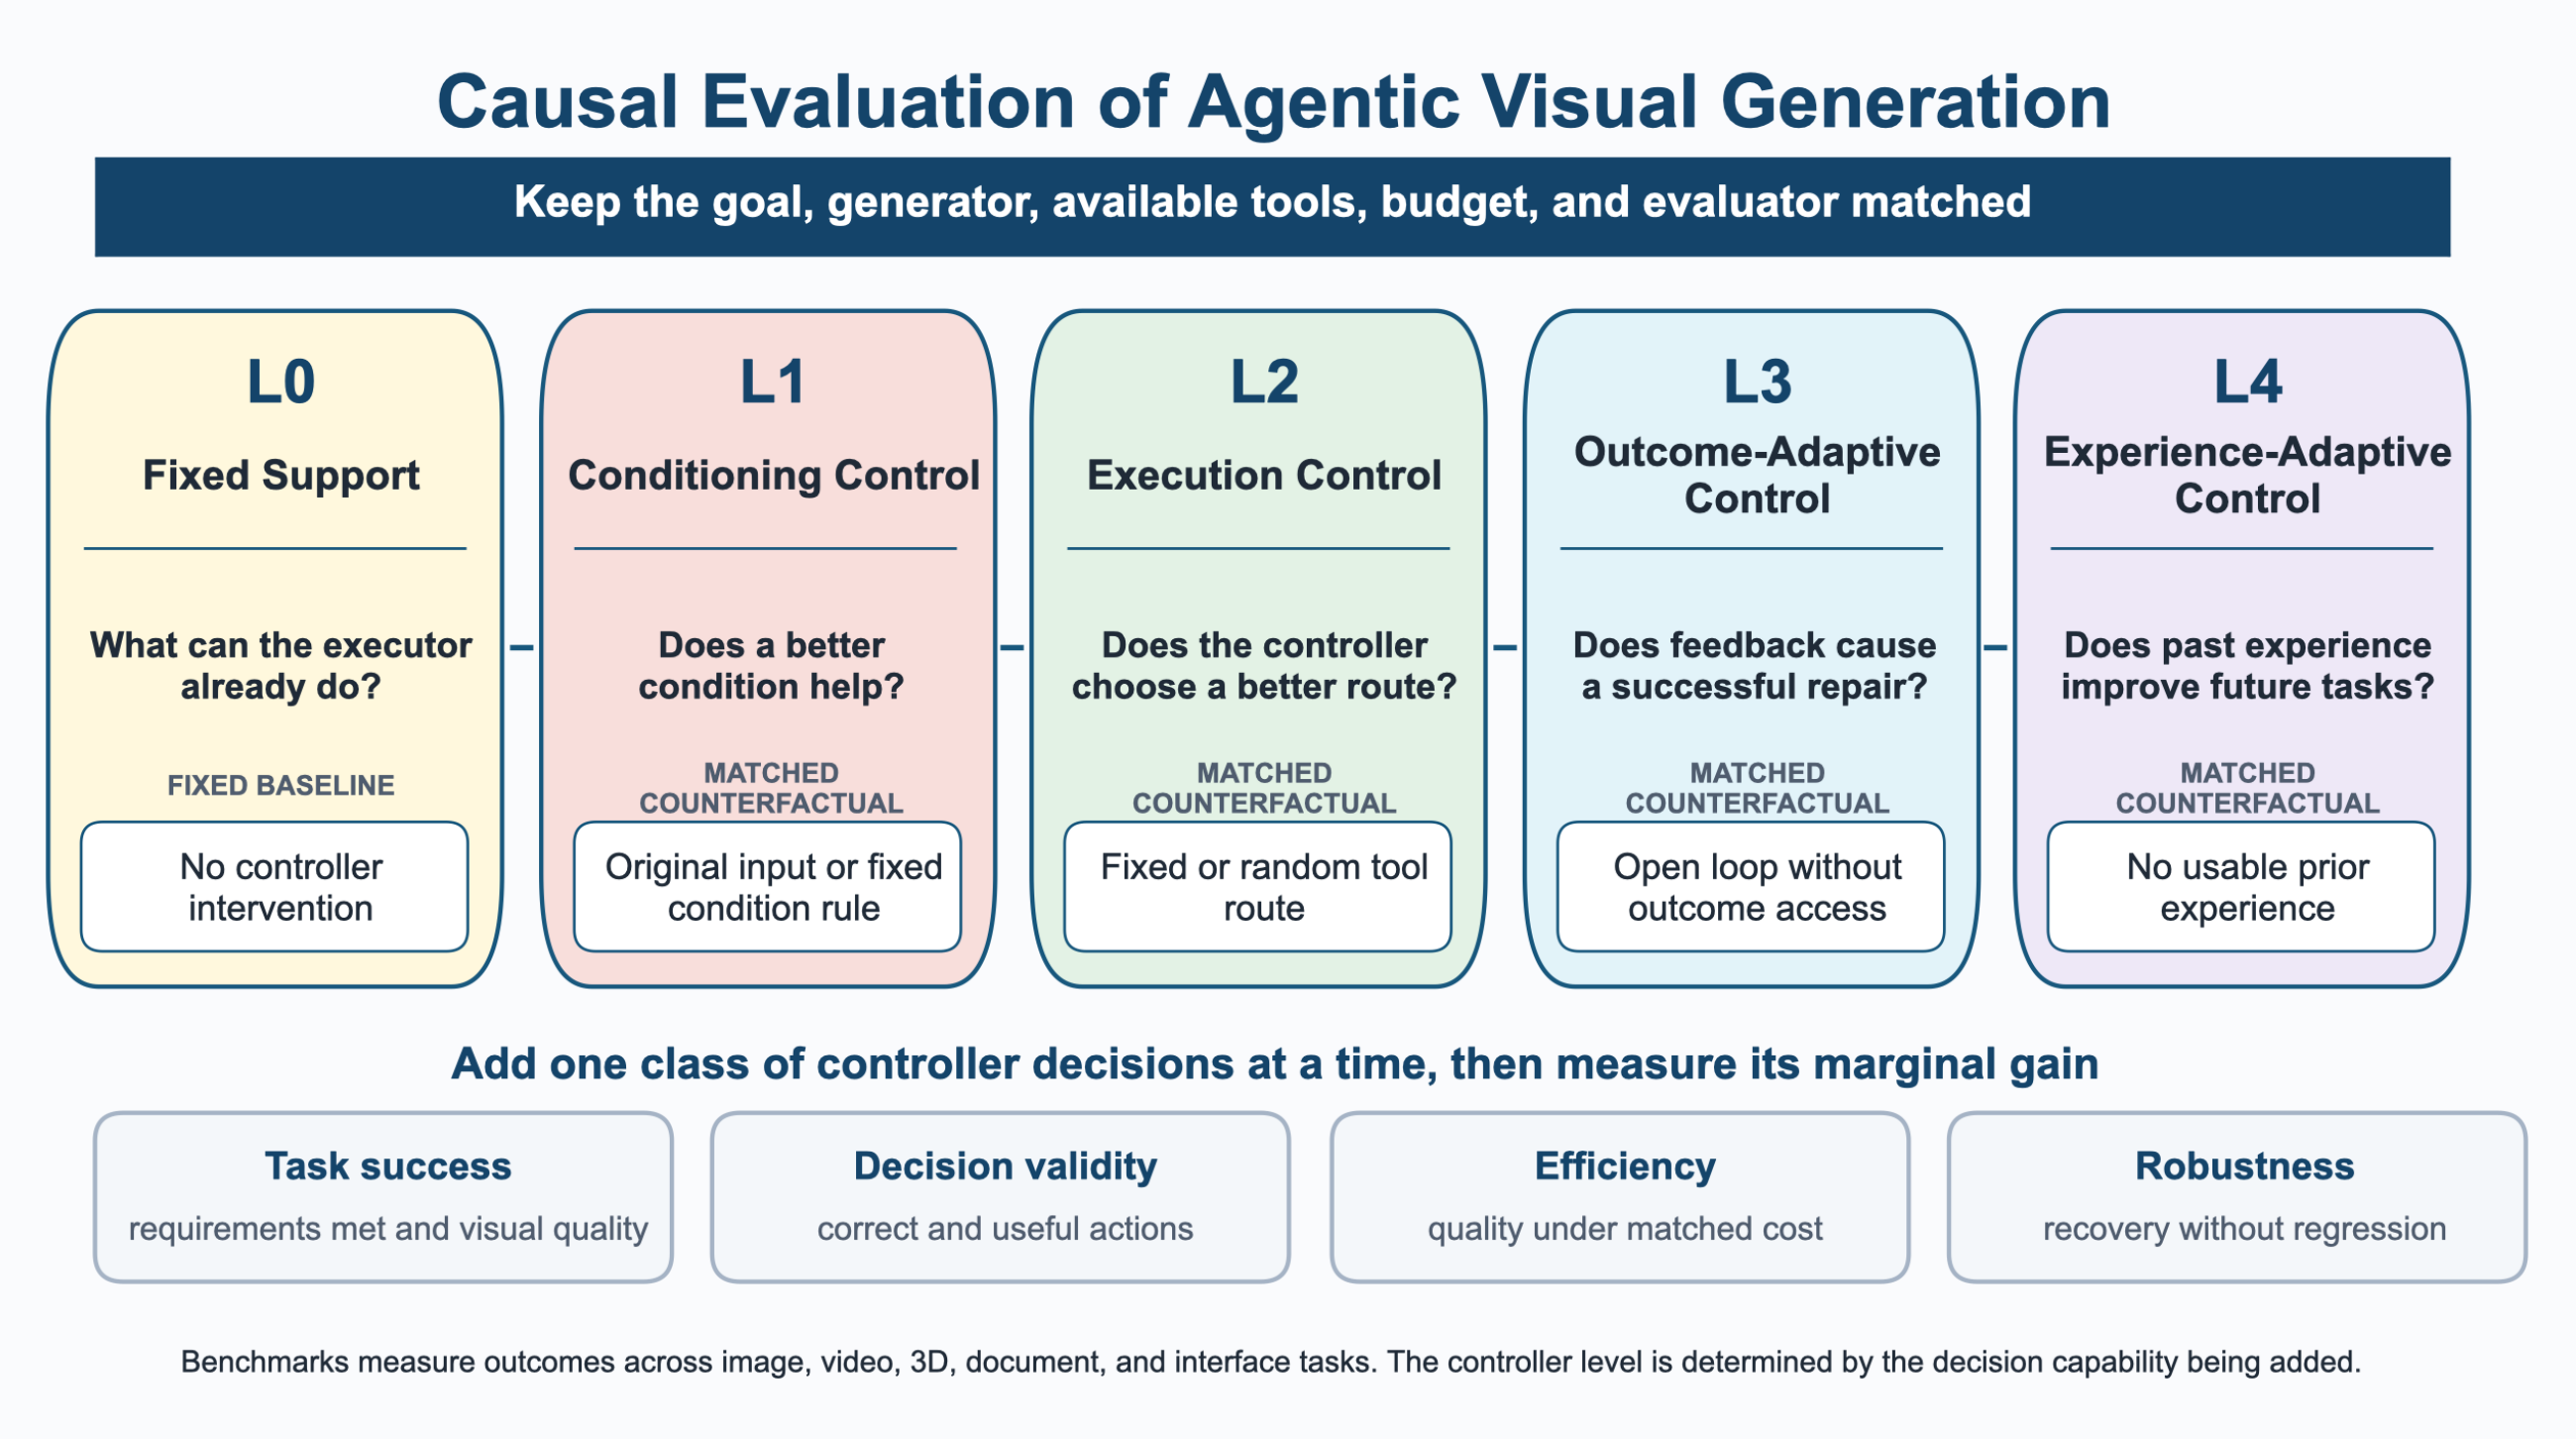
Figure 9. Causal evaluation of agentic visual generation.
Vector PDF
Agent and trajectory evaluation
| Resource | GitHub | Website | Scope | Type | Date |
|---|---|---|---|---|---|
| 3DCodeBench: Benchmarking Agentic Procedural 3D Modeling Via Code | GitHub  | Website | Procedural 3D modeling via code | Agent benchmark | 2026-06 |
| A Unified Agentic Framework for Evaluating Conditional Image Generation | GitHub  | - | Image generation | Evaluator orchestration | 2025-04 |
| ActVideoGen-Bench | - | Website | Long-horizon action-conditioned video | Agent benchmark | 2026-03 |
| AgentGen-Bench (SearchGen) | GitHub | Website | Search-intensive and no-search image prompts | Knowledge-grounded generation benchmark | 2026-07 |
| AgenticVBench: Can AI Agents Complete Real-World Post-Production Tasks? | GitHub  | Website | Real-world video post-production | Agent benchmark | 2026-05 |
| AtelierEval | - | - | Human and LLM prompters | Prompter evaluation | 2026-05 |
| CineBench | - | - | Cinematic compilation | Agent benchmark | 2026-04 |
| DirectorBench: Diagnosing Long-Form Video Generation with Personalized Multi-Agent Evaluation | GitHub  | Dataset | Long-form video generation | Multi-agent evaluator | 2026-05 |
| Draw ALL Your Imagine | GitHub  | - | Complex image instructions | Benchmark and iterative agent framework | 2025-05 |
| IA-Bench | - | - | Planning, reasoning, search, and memory in image generation | Agent benchmark | 2026-06 |
| MSVE-Bench and NB-Q | GitHub (announced) | Website | 3–5 minute multi-shot video extrapolation | Benchmark and source-grounded protocol | 2026-05 |
| SynthSeg-Agents | - | - | Synthetic data for segmentation | Downstream task evaluation | 2025-12 |
| UniVA-Bench | GitHub | Website | Multi-step video workflows | Agent benchmark | 2025-11 |
Output benchmarks and evaluators
| Resource | GitHub | Website | Modality | Focus | Date |
|---|---|---|---|---|---|
| AIGVE-MACS | - | Website | Video | Multi-aspect comments and scores | 2025-07 |
| EvalCrafter | GitHub  | Website | Video | Human-aligned video evaluation | 2023-10 |
| GenEval | GitHub  | - | Image | Object, count, color, and position | 2023-10 |
| MME-Unify | GitHub  | Website | Image | Unified understanding and generation | 2025-04 |
| Multi-Modal Language Models as Text-to-Image Model Evaluators | - | - | Image | MLLM-based evaluation | 2025-05 |
| T2I-CompBench | - | Website | Image | Compositional text-image alignment | 2023-07 |
| VBench | GitHub  | Website | Video | Appearance and temporal quality | 2023-11 |
| VideoArgus: Agentic Rubric-Grounded Unified Evaluation for Video Generation and Editing | GitHub  | Website | Video generation and editing | Rubric-grounded evaluator | 2026-08 |
| VisEditBench: Can Vision-Language Models Edit Visualization Code from Multimodal Feedback? | GitHub  | - | Visualization-code editing from multimodal feedback | Editing benchmark | 2026-08 |
Slide and user-interface benchmarks


Reward models, verifiers, and preference data
| Resource | GitHub | Website | Scope | Role | Date |
|---|---|---|---|---|---|
| Customized Reward Models for Text-to-Image Generation | GitHub  | - | Text-to-image | Request-specific reward | 2025-07 |
| Generative Universal Verifier | GitHub  | Website | Multimodal generation | Generative verification | 2025-10 |
| ImageReward | GitHub  | - | Text-to-image | General preference reward | 2023-04 |
| Personalized Reward Modeling for Text-to-Image Generation | - | - | Text-to-image | User-conditioned reward | 2025-11 |
| Pick-a-Pic | GitHub  | - | Text-to-image | Pairwise preference dataset | 2023-05 |
| Unified Multimodal Chain-of-Thought Reward Model | - | Website | Multimodal generation | Reasoning-based reward | 2025-05 |
Supporting Components: the L0 Boundary
L0 is an inclusion boundary, not an agent category. The following systems are important generators, editors, retrieval modules, or optimization methods, but their fixed execution rules do not give a controller any generation-level decisions by themselves.
| Supporting component | GitHub | Website | Modality | Why it is outside L1-L4 | Date |
|---|---|---|---|---|---|
| AeSlides: Incentivizing Aesthetic Layout in LLM-Based Slide Generation via Verifiable Rewards | GitHub  | Website | Slide | Trains a slide generator with layout rewards but no inference-time control trajectory | 2026-04 |
| Ask, Solve, Generate: Self-Evolving Unified Multimodal Understanding and Generation via Self-Consistency Rewards | GitHub  | Website | Image | Fixed training, data, benchmark, or evaluation procedure without inference-time generation control | 2026-06 |
| Audio-Visual Flamingo: Open Audio-Visual Intelligence for Long and Complex Videos | GitHub  | Website | Video | Audio-visual understanding and reasoning model; does not generate or edit visual artifacts | 2026-07 |
| AVI-Edit | - | Website | Editing | Fixed editing pipeline | 2025-12 |
| DALL-E 2 | - | - | Image | Fixed conditional generator | 2022-04 |
| DALL-E 3 | - | - | Image | Fixed conditional generator | 2023-09 |
| DataEvolver: Self-Evolving Multi-Agent Data Construction for Text-Rich Image Generation | GitHub  | - | Image | Fixed training, data, benchmark, or evaluation procedure without inference-time generation control | 2026-06 |
| DPOK | GitHub  | - | Image | Optimizes a generator rather than a generation-level controller | 2023-05 |
| DreamFusion | - | Website | 3D | Fixed optimization pipeline | 2022-09 |
| DreamGaussian | GitHub  | Website | 3D | Fixed optimization pipeline | 2023-09 |
| FrontCoder: Scaling Visual Fidelity in Front-End Code Generation | GitHub  | - | UI | Trains a one-shot frontend code generator without inference-time control | 2026-07 |
| GLIDE | GitHub  | - | Image | Fixed conditional generator | 2021-12 |
| Imagen | - | Website | Image | Fixed conditional generator | 2022-05 |
| Imagen Video | - | Website | Video | Fixed conditional generator | 2022-10 |
| InstructPix2Pix | GitHub  | Website | Editing | Fixed single-pass editor | 2022-11 |
| JAVEDIT: Joint Audio-Visual Instruction-Guided Video Editing with Agentic Data Curation | - | Dataset | Video, Editing | Fixed training, data, benchmark, or evaluation procedure without inference-time generation control | 2026-06 |
| Latent Diffusion | GitHub  | - | Image | Fixed conditional generator | 2021-12 |
| Lumiere | - | Website | Video | Fixed conditional generator | 2024-01 |
| Magic3D | - | Website | 3D | Fixed optimization pipeline | 2022-11 |
| Make-A-Video | - | - | Video | Fixed conditional generator | 2022-09 |
| ModelScopeT2V | - | Website | Video | Fixed conditional generator | 2023-08 |
| OSPO: Object-Centric Self-Improving Preference Optimization for Text-to-Image Generation | GitHub  | - | Image | Fixed training, data, benchmark, or evaluation procedure without inference-time generation control | 2025-06 |
| Parti | - | Website | Image | Fixed conditional generator | 2022-06 |
| Re-Imagen | - | - | Image | Fixed retrieval and generation pipeline | 2022-09 |
| ReasonGen-R1: CoT for Autoregressive Image generation models through SFT and RL | GitHub  | Website | Image | Fixed training, data, benchmark, or evaluation procedure without inference-time generation control | 2025-05 |
| Reward-Instruct | GitHub  | - | Image | Optimizes a generator rather than a generation-level controller | 2025-03 |
| ScaleEdit-12M: Scaling Open-Source Image Editing Data Generation via Multi-Agent Framework | GitHub  | Dataset | Image, Editing | Fixed training, data, benchmark, or evaluation procedure without inference-time generation control | 2026-03 |
| SDXL | GitHub  | - | Image | Fixed conditional generator | 2023-07 |
| Show-1 | GitHub  | Website | Video | Fixed conditional generator | 2023-09 |
| SmartEdit | - | Website | Editing | Single-pass editor | 2023-12 |
| T2I-R1: Reinforcing Image Generation with Collaborative Semantic-level and Token-level CoT | GitHub  | - | Image | Fixed training, data, benchmark, or evaluation procedure without inference-time generation control | 2025-05 |
| TokenFlow | GitHub  | Website | Editing | Fixed editing pipeline | 2023-07 |
| Tune-A-Video | GitHub  | Website | Editing | Fixed editing pipeline | 2022-12 |
| Video Diffusion Models | - | Website | Video | Fixed conditional generator | 2022-04 |
| Video LDM | - | Website | Video | Fixed conditional generator | 2023-04 |
| Video-P2P | - | Website | Editing | Fixed editing pipeline | 2023-03 |
| WorldCycle: Self-Verifiable Reinforcement Learning for Long-Horizon Video World Models | - | Website | Video | Fixed training, data, benchmark, or evaluation procedure without inference-time generation control | 2026-08 |
Community
Welcome to join our community to discuss agentic visual generation:
- WeChat community — open the QR code and scan it with WeChat.
- Discord community — join the discussion on Discord.
Contact
If you have any suggestions or find this repo helpful, feel free to contact us.
Email: yinminghuang1828@gmail.com, francisshuyuan@gmail.com.
If you find our work useful, please consider giving a star ⭐ to this github repository and citing it ❤️:
@article{huang2026agenticvisualgeneration,
  title={Agentic Visual Generation: From Generative Models to Agentic Control},
  author={Huang, Yinming and Tu, Shuyuan and Yan, Xi and Zhan, Jiahao and Yang, Zihan and Xing, Zhen and Zhang, Hui and Zhang, Tiehua and Jiang, Yu-Gang and Wu, Zuxuan},
  journal={arXiv preprint arXiv:2609.06758},
  year={2026}
}
Contributors


Similar repos


Languages
Python
100.0%
Python
59
14 commits
updated Sep 19, 2026
README
Awesome Agentic Visual Generation
Agentic Visual Generation: From Generative Models to Agentic Control
Yinming Huang1,2,*, Shuyuan Tu1,*, Xi Yan1,*, Jiahao Zhan4, Zihan Yang1, Zhen Xing3, Hui Zhang1, Tiehua Zhang5, Yu-Gang Jiang1, Zuxuan Wu1,2,†
[1Fudan University; 2Shanghai Innovative Institute; 3Wan Team, Alibaba Tongyi Lab; 4CUHK, MMLab; 5School of Computer Science and Technology, Tongji University]
[*Equal contribution; †Corresponding author]
❤️ If you find our work useful, please consider giving a star ⭐ to this GitHub repository ❤️.
News
[2026-09-09]: 🔥 The paper is now available on arXiv.
Figure 1. Visual overview of controller decision-making scope.
Vector PDF ·
arXiv paper
Pull requests are very welcome! Please help us add new papers, official resources, or corrections.
A curated and taxonomy-driven collection of 313 reviewed records spanning the L0 boundary and four controller-capability levels. The repository covers image generation and editing, video generation and editing, slide and user-interface generation, 3D scene construction, and world models.
The primary organization follows one rule: agenticity is determined by the deepest point in a generation trajectory at which the controller can causally change a future generation decision. Modality and mechanism are orthogonal tags. This prevents tool use, multi-agent design, memory, or reinforcement learning from being treated as agenticity levels by themselves.
Contents
- Paper on arXiv
- Scope and inclusion rule
- Controller-capability taxonomy
- Full classification standard
- Structured corpus
- L0: Fixed Support
- L1: Conditioning Control
- L2: Execution Control
- L3: Outcome-Adaptive Control
- L4: Experience-Adaptive Control
- Evaluation, Benchmarks, and Reward Models
- Contact
- Community
Scope and inclusion rule
An agentic visual generation system contains a visual generator or editor and a controller that makes generation-level decisions. In most current systems, an LLM, VLM, or MLLM is the controller and the visual generator is one of its tools. The controller may also be hybrid or internalized in a unified model, but generation capability alone does not establish agenticity.
We classify a system by the highest controller capability demonstrated by the complete method:
- The action type does not determine the level. A prompt rewrite before generation is L1, while a prompt rewrite caused by inspection of a generated image is L3.
- Tool use describes the action space. Multi-agent design describes the topology. Reinforcement learning describes a training method. None of them alone determines the level.
- A paper appears once in L0-L4 according to its maximum demonstrated level. The
Pathcolumn records the lower-level capabilities that it also contains. - L0 records may use agentic machinery during data construction or optimization, but the deployed visual system still follows a fixed rule. Stand-alone evaluators, reward models, benchmarks, and additional foundational components are listed separately.
Controller-capability taxonomy
| Level | Controller capability | Main question | Typical controlled variables |
|---|---|---|---|
| L0 | Fixed support | Is the inference path predetermined? | Fixed generator, retriever, evaluator, benchmark |
| L1 | Conditioning control | What declarative specification should be provided to a predetermined visual executor? | Prompt, layout, reference, knowledge, storyboard, motion plan |
| L2 | Execution control | Which visual operation should be invoked, how, and when? | Generator/editor identity, generation mode, artifact-mutating tool calls, invocation order |
| L3 | Outcome-adaptive control | What should happen after observing the result? | Revision, editing, rerouting, regeneration, stopping |
| L4 | Experience-adaptive control | How should completed trajectories change future decisions? | Long-term memory, skill, capability profile, policy |
The controller-capability levels form a progression above the L0 boundary:
conditions  ->  execution  ->  current trajectory  ->  future trajectories
    L1              L2                 L3                      L4
Modality tags used below are Image, Editing, Video, Slide, UI, 3D, and World.
The decisive boundary is decision-making scope, not architectural complexity. Multi-agent role decomposition and internal search can remain L1 when they only construct a specification. L2 requires the controller to invoke actual visual generation, editing, rendering, or artifact-mutating operations. L3 additionally requires a causal outcome-to-action link in the current trajectory, and L4 requires a persistent update across independent tasks. See TAXONOMY.md for the decision procedure, counterexamples, and evidence policy.
Figure 2. Representative-paper roadmap across the L1-L4 controller levels.
Vector PDF
Figure 7. From L0 Fixed Support to L2 Execution Control.
Vector PDF
L0: Fixed Support
L0 Fixed Support marks the inclusion boundary rather than a peer agent level. The organizing axis is support function: generation or retrieval, data or training, evaluation, and the boundary test for fixed pipelines.
Generation and Retrieval Components
Foundational generators, editors, and fixed retrievers are cataloged under Supporting Components: the L0 Boundary.
Data Construction and Training Infrastructure
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| AgentComp | - | - | L0 | Image | Agentic preference-data construction for a fixed generator | 2025-12 |
| Gen-n-Val: Agentic Image Data Generation and Validation | GitHub | - | L0 | Image | Synthetic-data generation and validation pipeline | 2025-06 |
Evaluators and Benchmarks
Standalone evaluators, reward models, and benchmarks are cataloged under Evaluation, Benchmarks, and Reward Models.
Boundary Test for L0 Fixed Support
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| Presentation Slide Translation and Layout Error Correction by LLMs | - | - | L0 | Slide, Editing | Fixed candidate generation and selection | 2026-07 |
| ShareVerse | - | - | L0 | Video, World | Shared generator state without controller action selection | 2026-03 |
L1: Conditioning Control
L1 controllers construct the generator-facing specification before execution. The categories follow the primary controlled specification: textual prompts, spatial and geometric structure, retrieved evidence, temporal and camera controls, or structured content.
Textual Prompt Specifications
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| APE: Agentic Prompt Enhancer for Image Generation and Editing | - | Website | L1 | Image, Editing | Prompt enhancement | 2026-06 |
| ICG: Improving Cover Image Generation via MLLM-based Prompting and Personalized Preference Alignment | - | - | L1 | Image | Prompting and preference alignment | 2026-05 |
| ThinkGen | GitHub | - | L1 | Image | MLLM instruction construction for a fixed diffusion transformer | 2025-12 |
| TIPO: Text to Image with Text Presampling for Prompt Optimization | GitHub | - | L1 | Image | Prompt expansion | 2024-11 |
| DiffChat: Learning to Chat with Text-to-Image Synthesis Models | GitHub | - | L1 | Image | Instruction-conditioned prompt modification | 2024-03 |
| POSI: Universal Prompt Optimizer for Safe Text-to-Image Generation | - | - | L1 | Image | Safety-aware prompt optimization | 2024-02 |
| MGIE: Guiding Instruction-based Image Editing via Multimodal LLMs | GitHub | Website | L1 | Editing | Expressive edit instruction | 2023-09 |
| Promptist: Optimizing Prompts for Text-to-Image Generation | GitHub | Website | L1 | Image | Learned prompt policy | 2022-12 |
Spatial and Geometric Specifications
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| DAC-Pose: Dual-Agent Collaborative Framework for Pose-Guided Human Generation | - | - | L1 | Image | Condition construction and planning | 2026-08 |
| NaLA: A 3D Native LLM Layout Agent for High-quality 3D Scene Generation | GitHub | Website | L1 | 3D | Condition construction and planning | 2026-06 |
| LLMControl | - | - | L1 | Image | Grounded controls | 2025-07 |
| GoT: Reasoning for Visual Generation and Editing | GitHub | - | L1 | Image, Editing | Generation-oriented reasoning | 2025-03 |
| Region-Aware Text-to-Image Generation via Hard Binding and Soft Refinement | GitHub | - | L1 | Image | Region binding | 2024-11 |
| LLM Blueprint | GitHub | - | L1 | Image | Structured scene description | 2023-10 |
| LayoutGPT | GitHub | Website | L1 | Image, 3D | Layout planning | 2023-05 |
| LLM-grounded Diffusion | GitHub | Website | L1 | Image | Bounding-box planning | 2023-05 |
Retrieved Evidence Specifications
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| One Image is All You Need: Agentic One-Shot Image Generation via Text-Based World Models for Long-Tail Spatial Perception | - | - | L1 | Image, World | Condition construction and planning | 2026-06 |
| Gen-Searcher | GitHub | Website | L1 | Image, World | Learned search for generation context | 2026-03 |
| Open Multimodal Retrieval-Augmented Factual Image Generation | GitHub | Website | L1 | Image | Condition construction and planning | 2025-10 |
| World-to-Image | GitHub | - | L1 | Image, World | Agent-driven knowledge grounding | 2025-10 |
| Cross-modal RAG | GitHub | - | L1 | Image | Sub-dimensional retrieval | 2025-05 |
| RealRAG | GitHub | - | L1 | Image | Self-reflective retrieval training | 2025-02 |
| When Cultures Meet: Multicultural Text-to-Image Generation | GitHub | - | L1 | Image | Condition construction and planning | 2025-02 |
Temporal and Camera Specifications
Structured Content Specifications
L2: Execution Control
L2 controllers select and invoke actual visual operations before observing their outcomes. The categories follow the primary executable object: model and tool operations, image and structured-graphic operations, video and audiovisual operations, document and interface operations, or 3D, CAD, and world operations.
Model and Tool Operations
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| Search Beyond What Can Be Taught: Evolving the Knowledge Boundary in Agentic Visual Generation (SearchGen) | GitHub | Website | L1+L2 | Image, World | Selective image/web search, evidence filtering, and prompt integration | 2026-07 |
| Boogu-Image-0.1: Boosting Open Agentic Multimodal Generation via Understanding under a Minimal Budget | GitHub | Website | L1+L2 | Image | Tool and workflow orchestration | 2026-07 |
| GenClaw: Code-Driven Agentic Image Generation | GitHub | - | L1+L2 | Image | Code-driven canvas operations | 2026-05 |
| Mind-Brush | GitHub | - | L1+L2 | Image, Editing, World | Search/reasoning routing and generation/editing mode selection | 2026-02 |
| LLM-I: LLMs are Naturally Interleaved Multimodal Creators | GitHub | - | L1+L2 | Image | Search, generation, code, and editing tools | 2025-09 |
| ComfyUI-Copilot: An Intelligent Assistant for Automated Workflow Development | GitHub | - | L1+L2 | Image | Tool and workflow orchestration | 2025-06 |
| ComfyUI-R1: Exploring Reasoning Models for Workflow Generation | GitHub | - | L1+L2 | Image | Tool and workflow orchestration | 2025-06 |
| Policy Optimized Text-to-Image Pipeline Design | - | - | L1+L2 | Image | Generator and processing-block selection | 2025-05 |
| Visual ChatGPT | GitHub | - | L1+L2 | Image, Editing | Visual foundation model orchestration | 2023-03 |
Image and Structured-Graphic Operations
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| SceneCraft: Interactive System for Image Editing via Scene Graph | - | - | L1+L2 | Image, Editing | User-directed graph editing and model dispatch | 2026-06 |
| ImageEdit-R1: Boosting Multi-Agent Image Editing via Reinforcement Learning | GitHub | - | L1+L2 | Image, Editing | Learned decomposition, sequencing, and open-loop edit execution | 2026-03 |
| MiLDEdit: Reasoning-Based Multi-Layer Design Document Editing | - | - | L1+L2 | Image, Editing | Tool and workflow orchestration | 2026-01 |
| From Pixels to Paths: A Multi-Agent Framework for Editable Scientific Illustration | GitHub | - | L1+L2 | Image, Editing | Tool and workflow orchestration | 2025-10 |
| Image Editing as Programs with Diffusion Models | GitHub | Website | L1+L2 | Editing | Atomic editing-program execution | 2025-06 |
| Visual Programming for Text-to-Image Generation and Evaluation | GitHub | Website | L1+L2 | Image | Executable visual program | 2023-05 |
Video and Audiovisual Operations
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| VideoCoCo: Code-as-CoT for Physically-Consistent Video Generation via an Agentic Dual-Engine System | GitHub | - | L1+L2 | Video, 3D | Executable Blender simulation and draft-conditioned video editing | 2026-07 |
| VideoAgent: All-in-One Framework for Video Understanding and Editing | GitHub | - | L1+L2 | Video, Editing | Tool and workflow orchestration | 2026-06 |
| ViMax | GitHub | - | L1+L2 | Video | Multi-role video workflow with best-of-k quality selection | 2026-06 |
| CineAgents | - | - | L1+L2 | Video, Editing | Narrative-memory-grounded blueprint and one-pass tool assembly | 2026-04 |
| A Versatile Multimodal Agent for Multimedia Content Generation | - | - | L1+L2 | Image, Video | Tool and workflow orchestration | 2026-01 |
| The Script is All You Need: An Agentic Framework for Long-Horizon Dialogue-to-Cinematic Video Generation | GitHub | Website | L1+L2 | Video | Tool and workflow orchestration | 2026-01 |
| Text-Driven Reasoning Video Editing via Reinforcement Learning | - | - | L1+L2 | Video, Editing | Reason-then-edit execution | 2025-11 |
| Long-Video Audio Synthesis with Multi-Agent Collaboration | GitHub | Website | L1+L2 | Video | Audio workflow orchestration | 2025-03 |
| VisAgent | - | - | L1+L2 | Image | Narrative visualization workflow | 2025-03 |
| StoryAgent | - | - | L1+L2 | Image, Video | Storyboard and character workflow | 2024-11 |
| DreamFactory | - | - | L1+L2 | Video | Multi-scene workflow | 2024-08 |
| Mora | GitHub | - | L1+L2 | Video | Multi-agent video modules | 2024-03 |
Document and Interface Operations
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| TVIR: Building Deep Research Agents Towards Text-Visual Interleaved Report Generation | GitHub | Website | L1+L2 | Image | Tool and workflow orchestration | 2026-06 |
| PresentAgent-2: Towards Generalist Multimodal Presentation Agents | GitHub | Website | L1+L2 | Slide | Tool and workflow orchestration | 2026-05 |
3D, CAD, and World Operations
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| CADIR: A Cross-Backend Editable Intermediate Representation for Agentic CAD Generation | - | - | L1+L2 | 3D, Editing | Tool and workflow orchestration | 2026-08 |
| Unify-Agent | GitHub | - | L1+L2 | Image, World | Search-grounded generation orchestration | 2026-03 |
| AutoUE: Automated Generation of 3D Games in Unreal Engine via Multi-Agent Systems | GitHub | - | L1+L2 | 3D | Tool and workflow orchestration | 2026-03 |
| Vinedresser3D: Agentic Text-guided 3D Editing | - | - | L1+L2 | 3D, Editing | View selection and 3D editing orchestration | 2026-02 |
| 3D Space as a Scratchpad for Editable Text-to-Image Generation | - | Website | L1+L2 | 3D, Editing | 3D scratchpad tool orchestration | 2026-01 |
L3: Outcome-Adaptive Control
L3 controllers use an observed result to change a later generation action within the current task. The categories follow the decisive feedback source: perceptual outcomes, structured and execution state, physical constraints, or explicit human review.
Perceptual Outcome Feedback
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| Beyond Starry Night: Shortcut-Aware Control-State Planning for Artist-Grounded Text to Image Generation | - | - | L1+L3 | Image | Execute-evaluate-reflect prompt correction | 2026-08 |
| VisPuzzle: Task-Aware Composite Visualization Construction | GitHub | Dataset | L1+L2+L3 | Image | Outcome-aware verification and revision | 2026-08 |
| ParticleGen: A Multi-Agent System for Particle Effects Generation | - | - | L1+L2+L3 | Video, 3D | Rendered particle-effect feedback | 2026-08 |
| ToolArtist: Tool-Using Unified Multimodal Models for Agentic Image Generation | GitHub | Dataset | L1+L2+L3 | Image, World | Unified search, native drawing, inspection, and revision | 2026-08 |
| Domain-Grounded Candidate Selection for Agentic Image Editing: A Shadow Removal Case | - | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-08 |
| DrawAI: Agentic Benchmark and Workflow for Making Raster Images Editable | GitHub | Website | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-08 |
| What to Edit Next: Visually Aligned Image-Editing Follow-Up Suggestions in Conversational Systems | - | - | L1+L3 | Image, Editing | Current-image-conditioned follow-up edit policy | 2026-08 |
| Beyond Trial-and-Error: Agentic Optimization for Image-to-Video Adherence | - | - | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-08 |
| WorldClaw: Agentic 3D Open-World Generation at Scale | - | Website | L1+L2+L3 | 3D | Render-based 3D world refinement | 2026-08 |
| PosterMELD: Multi-Agent Paper-to-Poster Generation for Controllable Design Diversity with Editable Print-Ready Outputs | GitHub | Website | L1+L2+L3 | Image, Editing | VLM-routed poster repair | 2026-08 |
| PRISM: Prompt Refinement via Image-grounded Self-rewarding Mechanism for Text-to-Image Generation | - | Code | L1+L2+L3 | Image | Outcome-aware verification and revision | 2026-07 |
| JarvisHub: An Open Harness for Canvas-Native Multimodal Creative Agents | GitHub | Website | L1+L2+L3 | Image | Canvas-state inspection, feedback-guided revision, and recovery | 2026-07 |
| Knowledge-Centric Agents for Workflow Generation in ComfyUI | - | - | L1+L2+L3 | Image | Workflow self-refinement | 2026-07 |
| PairCoder++: Pair Programming as a Universal Paradigm for Verified Code-Driven Multimodal and Structured-Artifact Generation | GitHub | Website | L1+L2+L3 | Image | Outcome-aware verification and revision | 2026-07 |
| CanvasAgent: Enabling Complex Image Creation and Editing via Visual Tool Orchestration | - | Dataset | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-07 |
| Cognitive-structured Multimodal Agent for Multimodal Understanding, Generation, and Editing | GitHub | Website | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-07 |
| GMO-E$^2$DIT: Grounded Multi-Operation Editing for E-Commerce Images | - | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-07 |
| SAGE: Structured Agentic Graph Editing for Software Diagrams | GitHub | - | L1+L2+L3 | Image, Editing | Structured diagram validation and repair | 2026-07 |
| What Can I Edit? Open-Ended Strategy Discovery and the Emotion Editability Landscape | - | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-07 |
| FilmWorld: Agentic Novel-to-Film Generation through Dynamic Cinematic World Modeling | GitHub | Website | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-07 |
| PhysAgent: Reflective Agentic Physics Control for Physically Plausible Video Generation | GitHub | Website | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-07 |
| Exploring Agentic Workflows for Generating High Quality Math Visual Aids | - | - | L1+L2+L3 | Image | VLM-reviewed visual-aid refinement | 2026-07 |
| RS-Gen: A Multi-Stage Agentic Framework for Reasoning and Search-Augmented Image Generation | - | - | L1+L2+L3 | Image | Adaptive routing and generate-verify-correct loop | 2026-06 |
| MetaPoint | - | - | L1+L3 | Image | Generate-reflect-execute spatial correction | 2026-06 |
| Qwen-Image-Agent | - | - | L1+L2+L3 | Image, World | Search, memory, editing, and feedback | 2026-06 |
| InterleaveThinker: Reinforcing Agentic Interleaved Generation | GitHub | Website | L1+L2+L3 | Image | Outcome-aware verification and revision | 2026-06 |
| IEA: Amateur-Friendly Conversational Image Editing Agent via Three Stages of Multitask Alignment | GitHub | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-06 |
| Taming I2V models for Image HOI Editing: A Cognitive Benchmark and Agentic Self-Correcting Framework | GitHub | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-06 |
| Bridging Creative Intent and Visual Quality: Creator-Driven Recurrent Video Generation with Agentic Feedback Loops | - | - | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-06 |
| Closed-Loop Triplet Synergistic Generation for Long-Form Video | - | - | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-06 |
| IterCAD: An Iterative Multimodal Agent for Visually-Grounded CAD Generation and Editing | - | - | L1+L2+L3 | 3D, Editing | Outcome-aware verification and revision | 2026-06 |
| SceneConductor: 3D Scene Generation from a Single Image with Multi-Agent Orchestration | GitHub | Website | L1+L2+L3 | 3D | Planner-directed 3D scene correction | 2026-06 |
| Temporal Backtracking Search for Test-time Generative Video Reasoning | - | Website | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-06 |
| Code2UML: Agentic LLMs with context engineering for scalable software visualization | - | - | L1+L2+L3 | Image | Corrector-guided UML repair | 2026-05 |
| Generation Navigator | - | - | L1+L2+L3 | Image | State-aware action choice | 2026-05 |
| SCOPE | GitHub | Website | L1+L2+L3 | Image | Specification-guided skill orchestration, verification, and repair | 2026-05 |
| AlphaGRPO | GitHub | Website | L1+L3 | Image | Self-reflective verifiable rewards | 2026-05 |
| Large Language Models are Universal Reasoners for Visual Generation | - | - | L1+L3 | Image | Draft and grounded self-critique | 2026-05 |
| Latent Action Control | - | - | L1+L3 | Image | Latent diagnosis and halting | 2026-05 |
| Self-Adaptive Interleaved Visual Reasoner | GitHub | - | L1+L3 | Image | Adaptive reflection and planning | 2026-05 |
| Crafter: A Multi-Agent Harness for Editable Scientific Figure Generation from Diverse Inputs | GitHub | - | L1+L2+L3 | Image, Editing | Critic-refiner-convergence loop | 2026-05 |
| EditRefiner | GitHub | - | L1+L3 | Editing | Human-aligned iterative refinement | 2026-05 |
| From Plans to Pixels: Learning to Plan and Orchestrate for Open-Ended Image Editing | - | Website | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-05 |
| LiveFigure: Generating Editable Scientific Illustration with VLM Agents | GitHub | - | L1+L2+L3 | Image, Editing | Visual-diagnostic figure correction | 2026-05 |
| Genflow Ad Studio: A Compound AI Architecture for Brand-Aligned, Self-Correcting Video Generation | - | - | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-05 |
| One Sentence, One Drama: Personalized Short-Form Drama Generation via Multi-Agent Systems | - | - | L1+L2+L3 | Video | Multi-stage reviewer loops | 2026-05 |
| Soap2Soap: Long Cinematic Video Remaking via Multi-Agent Collaboration | GitHub | - | L1+L2+L3 | Video | Verification-triggered video regeneration | 2026-05 |
| Self-Reasoning Agentic Framework for Narrative Product Grid-Collage Generation | - | - | L1+L3 | Image | Generation-critique loop for product collage | 2026-04 |
| Render-in-the-Loop: Vector Graphics Generation via Visual Self-Feedback | - | - | L1+L2+L3 | Image | Outcome-aware verification and revision | 2026-04 |
| FiRe | - | - | L1+L3 | Image | Fine-grained multimodal reflection | 2026-04 |
| Think in Strokes, Not Pixels | - | - | L1+L3 | Image | Interleaved draft and reflection | 2026-04 |
| CAMEO: A Conditional and Quality-Aware Multi-Agent Image Editing Orchestrator | - | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-04 |
| Making Image Editing Easier via Adaptive Task Reformulation with Agentic Executions | GitHub | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-04 |
| Refinement via Regeneration | GitHub | - | L1+L3 | Image, Editing | Adaptive modification space | 2026-04 |
| BOOKAGENT | GitHub | - | L1+L2+L3 | Image, Video | Verify-then-rectify storybook generation | 2026-04 |
| Co-Director | GitHub | Website | L1+L2+L3 | Video | MLLM feedback-driven video refinement | 2026-04 |
| SCMAPR: Self-Correcting Multi-Agent Prompt Refinement for Complex-Scenario Text-to-Video Generation | GitHub | - | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-04 |
| Vision-Guided Iterative Refinement for Frontend Code Generation | - | - | L1+L2+L3 | UI | VLM critic, rendered feedback, and iterative code revision | 2026-04 |
| Agentic Flow Steering and Parallel Rollout Search for Spatially Grounded Text-to-Image Generation | - | - | L1+L2+L3 | Image | Outcome-aware verification and revision | 2026-03 |
| coDrawAgents | GitHub | - | L1+L2+L3 | Image | Multi-round scene construction | 2026-03 |
| GlyphBanana | GitHub | - | L1+L2+L3 | Image | Generated-glyph inspection and iterative refinement | 2026-03 |
| VisionCreator: A Native Visual-Generation Agentic Model with Understanding, Thinking, Planning and Creation | - | - | L1+L2+L3 | Image | Tool-feedback-grounded goal verification and revision | 2026-03 |
| Feynman: Knowledge-Infused Diagramming Agent for Scalable Visual Designs | - | - | L1+L2+L3 | Image | Rendered diagram feedback | 2026-03 |
| StruVis: Enhancing Reasoning-based Text-to-Image Generation via Thinking with Structured Vision | - | - | L1+L3 | Image | Intermediate-image inspection and refinement | 2026-03 |
| GEMS | GitHub | Website | L1+L2+L3 | Image, Editing | Current-trajectory working and experience memory | 2026-03 |
| RAISE: Requirement-Adaptive Evolutionary Refinement for Training-Free Text-to-Image Alignment | GitHub | - | L1+L2+L3 | Image | Outcome-aware verification and revision | 2026-03 |
| IMAGAgent: Orchestrating Multi-Turn Image Editing via Constraint-Aware Planning and Reflection | GitHub | - | L1+L2+L3 | Image, Editing | Within-request edit, critique, retry, and rollback state | 2026-03 |
| MSRAMIE: Multimodal Structured Reasoning Agent for Multi-instruction Image Editing | - | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-03 |
| Towards Context-Aware Image Anonymization with Multi-Agent Reasoning | - | - | L1+L2+L3 | Image, Editing | PDCA anonymization refinement | 2026-03 |
| SceneAssistant: A Visual Feedback Agent for Open-Vocabulary 3D Scene Generation | GitHub | - | L1+L2+L3 | 3D | Outcome-aware verification and revision | 2026-03 |
| VQQA: An Agentic Approach for Video Evaluation and Quality Improvement | - | Website | L1+L2+L3 | Video | Outcome-aware verification and revision | 2026-03 |
| WorldAgents: Can Foundation Image Models be Agents for 3D World Models? | - | Website | L1+L2+L3 | 3D | Outcome-aware verification and revision | 2026-03 |
| GameUIAgent: An LLM-Powered Framework for Automated Game UI Design with Structured Intermediate Representation | - | - | L1+L2+L3 | UI | Non-regressive VLM reflection | 2026-03 |
| M3 | GitHub | - | L1+L2+L3 | Image | Multi-agent visual diagnosis | 2026-02 |
| AutoFigure: Generating and Refining Publication-Ready Scientific Illustrations | GitHub | Dataset | L1+L2+L3 | Image | Outcome-aware verification and revision | 2026-02 |
| UniReason 1.0 | GitHub | - | L1+L3 | Image, Editing, World | Knowledge reasoning and correction | 2026-02 |
| UniT | - | Website | L1+L3 | Image | Sequential generation and refinement | 2026-02 |
| Agent Banana | GitHub | Website | L1+L2+L3 | Editing | Multi-step reasoning and tools | 2026-02 |
| PhotoAgent | - | Website | L1+L2+L3 | Editing | Long-horizon aesthetic planning | 2026-02 |
| RetouchIQ: MLLM Agents for Instruction-Based Image Retouching with Generalist Reward | - | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2026-02 |
| AnimeAgent: Is the Multi-Agent via Image-to-Video models a Good Disney Storytelling Artist? | - | - | L1+L2+L3 | Video | Reviewer-guided dope-sheet refinement from generated trajectories | 2026-02 |
| PaperX: A Unified Framework for Multimodal Academic Presentation Generation with Scholar DAG | GitHub | - | L1+L2+L3 | Slide | Rendered-slide VLM feedback and content-layout revision | 2026-02 |
| DeepPresenter: Environment-Grounded Reflection for Agentic Presentation Generation | GitHub | Dataset | L1+L2+L3 | Slide | Outcome-aware verification and revision | 2026-02 |
| VisRefiner: Learning from Visual Differences for Screenshot-to-Code Generation | - | - | L1+L3 | UI | Difference-aligned training and render-conditioned self-refinement | 2026-02 |
| ComfySearch: Autonomous Exploration and Reasoning for ComfyUI Workflows | GitHub | - | L1+L2+L3 | Image | Validation-guided graph repair | 2026-01 |
| GenAgent | - | - | L1+L2+L3 | Image | Trained tool use and reflection | 2026-01 |
| Vision-as-Inverse-Graphics Agent via Interleaved Multimodal Reasoning | GitHub | Website | L1+L2+L3 | Image, 3D, World | Code-render-inspect repair loop | 2026-01 |
| APEX: Academic Poster Editing Agentic Expert | GitHub | - | L1+L2+L3 | Image, Editing | Render-review-adjust poster editing | 2026-01 |
| Agentic Retoucher | GitHub | - | L1+L2+L3 | Image, Editing | Defect localization and retouching | 2026-01 |
| SciFig: Towards Automating Editable Figure Generation for Scientific Papers | - | Website | L1+L2+L3 | Image, Editing | VLM-guided editable-figure refinement | 2026-01 |
| PaperBanana: Automating Academic Illustration for AI Scientists | GitHub | Website | L1+L2+L3 | 3D | Outcome-aware verification and revision | 2026-01 |
| DraCo: Draft as CoT for Text-to-Image Preview and Rare Concept Generation | GitHub | - | L1+L3 | Image | Draft verification and selective correction | 2025-12 |
| CoAgent | - | - | L1+L2+L3 | Video | Cross-segment consistency agent | 2025-12 |
| FronTalk: Benchmarking Front-End Development as Conversational Code Generation with Multi-Modal Feedback (AceCoder) | GitHub | Website | L1+L2+L3 | UI | Web-agent critique and regression-aware regeneration | 2025-12 |
| Image-POSER | - | - | L1+L2+L3 | Image, Editing | Reflective expert routing | 2025-11 |
| ImAgent | - | - | L1+L2+L3 | Image | Policy-controlled test-time actions | 2025-11 |
| MIRA: Multimodal Iterative Reasoning Agent for Image Editing | - | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2025-11 |
| UI2Code^N: UI-to-Code Generation as Interactive Visual Optimization | GitHub | Website | L1+L3 | UI | Unified render-inspect-refine model with test-time scaling | 2025-11 |
| GenPilot | GitHub | - | L1+L2+L3 | Image | Error analysis and prompt refinement | 2025-10 |
| Hollywood Town | - | Website | L1+L2+L3 | Video | Adaptive cross-modal workflow | 2025-10 |
| VISTA: A Test-Time Self-Improving Video Generation Agent | - | Website | L1+L3 | Video | Test-time video prompt refinement | 2025-10 |
| PromptSculptor | - | - | L1+L2+L3 | Image | Multi-agent self-evaluation | 2025-09 |
| Maestro | - | - | L1+L2+L3 | Image | Critic-guided orchestration | 2025-09 |
| Interleaving Reasoning for Better Text-to-Image Generation | GitHub | - | L1+L3 | Image | Image-conditioned textual reflection | 2025-09 |
| MILR | GitHub | Website | L1+L3 | Image | Test-time latent search | 2025-09 |
| CountLoop | - | Website | L1+L3 | Image | Counting feedback loop | 2025-08 |
| Uni-CoT | GitHub | Website | L1+L3 | Image | Closed-loop micro-level visual reevaluation | 2025-08 |
| A Unified Multi-Agent Framework for Universal Multimodal Understanding and Generation | - | - | L1+L2+L3 | Image | Growth-aware multimodal search | 2025-08 |
| An LLM-LVLM Driven Agent for Iterative and Fine-Grained Image Editing | - | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2025-08 |
| Talk2Image: A Multi-Agent System for Multi-Turn Image Generation and Editing | GitHub | - | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2025-08 |
| AniME | - | - | L1+L2+L3 | Video | Adaptive animation planning | 2025-08 |
| MAViS | - | - | L1+L2+L3 | Video | Explore-examine-enhance stage loops | 2025-08 |
| Test-time Prompt Refinement | - | - | L1+L3 | Image | Iterative visual diagnosis | 2025-07 |
| T2I-Copilot | GitHub | - | L1+L2+L3 | Image | Evaluator-controlled regeneration | 2025-07 |
| Beyond Simple Edits: X-Planner for Complex Instruction-Based Image Editing | - | Website | L1+L2+L3 | Image, Editing | Outcome-aware verification and revision | 2025-07 |
| PointT2I | - | - | L1+L3 | Image | Semantic feedback on generated pose images | 2025-06 |
| RATTPO | GitHub | - | L1+L3 | Image | Reward-history prompt search | 2025-06 |
| VisualPrompter | GitHub | - | L1+L3 | Image | Image-grounded prompt repair | 2025-06 |
| AniMaker: Multi-Agent Animated Storytelling with MCTS-Driven Clip Generation | GitHub | Website | L1+L2+L3 | Video | MCTS candidate generation and review | 2025-06 |
| DesignCoder: Hierarchy-Aware and Self-Correcting UI Code Generation with Large Language Models | - | - | L1+L2+L3 | UI | Hierarchy-aware generation and vision-guided self-correction | 2025-06 |
| IA-T2I: Internet-Augmented Text-to-Image Generation | - | - | L1+L3 | Image | Generated-image self-reflection and multi-round regeneration | 2025-05 |
| ComfyMind: Toward General-Purpose Generation via Tree-Based Planning and Reactive Feedback | GitHub | Website | L1+L2+L3 | Image | Outcome-aware verification and revision | 2025-05 |
| UniGen | - | - | L1+L3 | Image | Candidate verification and selection | 2025-05 |
| Scenethesis | - | Website | L1+L2+L3 | 3D | Render-guided scene construction | 2025-05 |
| Marmot: Object-Level Self-Correction via Multi-Agent Reasoning | - | - | L1+L2+L3 | Image | Outcome-aware verification and revision | 2025-04 |
| Twin Co-Adaptive Dialogue | - | - | L1+L3 | Image | Progressive dialogue and image updates | 2025-04 |
| CREA: A Collaborative Multi-Agent Framework for Creative Image Editing and Generation | GitHub | Website | L1+L2+L3 | Image, Editing | Critic-guided creative image refinement | 2025-04 |
| ComfyGPT: A Self-Optimizing Multi-Agent System for Comprehensive ComfyUI Workflow Generation | GitHub | Website | L1+L2+L3 | Image | Execute-and-refine workflow control | 2025-03 |
| FoX | - | - | L1+L3 | Image | Planning, acting, reflection, correction | 2025-03 |
| ImageRAG | GitHub | Website | L1+L2+L3 | Image | Generation-gap-triggered retrieval | 2025-02 |
| MotionAgent | GitHub | - | L1+L3 | Video | Optional rendered-video rethinking and motion-control regeneration | 2025-02 |
| Image CoT | GitHub | - | L1+L3 | Image | Stepwise generation and verification | 2025-01 |
| PPTAgent: Generating and Evaluating Presentations Beyond Text-to-Slides | GitHub | - | L1+L2+L3 | Slide | Execution-feedback slide correction | 2025-01 |
| PASTA: Preference Adaptive and Sequential Text-to-Image Generation | - | Dataset | L1+L3 | Image | Sequential preference feedback | 2024-12 |
| GenMAC | GitHub | Website | L1+L2+L3 | Video | Verification and correction | 2024-12 |
| Anim-Director | GitHub | - | L1+L2+L3 | Video | Self-reflective animation candidate selection | 2024-08 |
| Kubrick | - | Website | L1+L2+L3 | Video, 3D | Screenshot-guided Blender repair | 2024-08 |
| GenArtist | - | Website | L1+L2+L3 | Image, Editing | Tool tree, verification, and repair | 2024-07 |
| OPT2I: Improving Text-to-Image Consistency via Automatic Prompt Optimization | - | - | L1+L3 | Image | Rendered-score prompt search | 2024-03 |
| MuLan | GitHub | - | L1+L3 | Image | Progressive construction | 2024-02 |
| RPG: Recaptioning, Planning, and Generating with Multimodal LLMs | GitHub | - | L1+L3 | Image | Optional rendered-image self-refinement | 2024-01 |
| CompAgent | - | - | L1+L3 | Image | Visual-feedback correction | 2024-01 |
| Self-correcting LLM-controlled Diffusion Models | GitHub | Website | L1+L3 | Image | Requirement inspection and repair | 2023-11 |
Structured and Execution Feedback
Physical and Constraint Feedback
Human Review Feedback
| Paper | GitHub | Website | Path | Modality | Primary mechanism | Date |
|---|---|---|---|---|---|---|
| CoGen3D: An Agentic Human-AI Co-Design Pipeline for 3D Asset Generation for Virtual Reality | - | - | L1+L2+L3 | 3D | Human-confirmed concept refinement before 3D generation | 2026-07 |
| OrchestrXR: A Multi-Agent System for Idea-to-Prototype XR Study Authoring | - | - | L1+L2+L3 | World | User-reviewed patch-and-revise XR authoring | 2026-07 |
| From Idea to Co-Creation: A Planner-Actor-Critic Framework for Agent Augmented 3D Modeling | - | - | L1+L2+L3 | 3D | Outcome-aware verification and revision | 2026-01 |
| Promptify: Interactive Prompt Exploration with Large Language Models | GitHub | - | L1+L3 | Image | Candidate-driven user feedback | 2023-04 |
L4: Experience-Adaptive Control
L4 controllers retain completed-task experience that changes decisions on later independent tasks. The categories follow the persistent carrier: capability and tool profiles, episodic and user memory, reusable procedures and skills, executable workflows and harnesses, or policy and model updates.
Capability and Tool Profiles
| Paper | GitHub | Website | Path | Modality | Persistent adaptation | Date |
|---|---|---|---|---|---|---|
| GenRouter: Unified Workflow Routing for Agentic Image Generation | GitHub | - | L1+L2+L3+L4 | Image | Cross-task memory or skill evolution | 2026-08 |
| OctoT2I | GitHub | - | L1+L2+L3+L4 | Image | Evolving generator capability profiles | 2026-06 |
| PerfGuard: A Performance-Aware Agent for Visual Content Generation | GitHub | - | L1+L2+L3+L4 | Image | Execution-ranked tool preference updates | 2026-01 |
| DiffusionAgent | GitHub | Website | L1+L2+L3+L4 | Image | Human-feedback-updated expert advantage database | 2024-01 |
Episodic and User Memory
| Paper | GitHub | Website | Path | Modality | Persistent adaptation | Date |
|---|---|---|---|---|---|---|
| MemoGen | GitHub | - | L1+L3+L4 | Image | Cross-task episodic experience | 2026-06 |
| MemSlides: A Hierarchical Memory Driven Agent Framework for Personalized Slide Generation with Multi-turn Local Revision | GitHub | Website | L1+L2+L3+L4 | Slide | Cross-task memory or skill evolution | 2026-06 |
| Action Agent: Agentic Video Generation Meets Flow-Constrained Diffusion | - | - | L1+L2+L3+L4 | Video | Cross-task navigation-generation memory | 2026-05 |
| BrandFusion | - | Website | L1+L2+L4 | Video | User-feedback experience pool for later brand-integration strategies | 2026-03 |
| UniVA | GitHub | Website | L1+L2+L3+L4 | Video | Persistent trajectory and user-preference memory for later workflows | 2025-11 |
Reusable Procedures and Skills
| Paper | GitHub | Website | Path | Modality | Persistent adaptation | Date |
|---|---|---|---|---|---|---|
| ManimAgent: Self-Evolving Multimodal Agents for Visual Education | - | - | L1+L2+L3+L4 | Image | Cross-task memory or skill evolution | 2026-06 |
| Self-Evolving Agentic Image Restoration via Deliberate Planning and Intuitive Execution | - | - | L1+L2+L3+L4 | Image, Editing | Cross-task memory or skill evolution | 2026-06 |
| GenEvolve | GitHub | Website | L1+L2+L3+L4 | Image, Editing | Visual experience distillation into skills | 2026-05 |
| SimWorld Studio: Automatic Environment Generation with Evolving Coding Agent for Embodied Agent Learning | - | - | L1+L2+L3+L4 | World | Cross-task memory or skill evolution | 2026-05 |
| EvoDiagram: Agentic Editable Diagram Creation via Design Expertise Evolution | - | - | L1+L2+L3+L4 | Image, Editing | Cross-task memory or skill evolution | 2026-04 |
| SceneCraft | - | - | L1+L2+L3+L4 | 3D | Cross-query spatial skill library | 2024-03 |
Executable Workflows and Harnesses
| Paper | GitHub | Website | Path | Modality | Persistent adaptation | Date |
|---|---|---|---|---|---|---|
| AutoDesign: Meta-Harness Optimization for Long-Horizon Agentic Design | GitHub | Website | L1+L2+L3+L4 | Image | Cross-task memory or skill evolution | 2026-08 |
| AVA-Encoder: Towards Agent-Native Video Representation Learning | GitHub | Website | L1+L2+L3+L4 | Video | Self-evolving film-representation program | 2026-08 |
| COMFYCLAW: Self-Evolving Skill Harnesses for Image Generation Workflows | GitHub | - | L1+L2+L3+L4 | Image | Cross-task memory or skill evolution | 2026-07 |
| VideoWeaver | GitHub | - | L1+L2+L3+L4 | Video | Evaluation and evolution of workflow skills | 2026-06 |
| Automatic Method Illustration Generation for AI Scientific Papers via Drawing Middleware Creation, Evolution, and Orchestration | - | - | L1+L2+L3+L4 | Image | Reusable drawing-middleware evolution | 2026-03 |
Policy and Model Updates
| Paper | GitHub | Website | Path | Modality | Persistent adaptation | Date |
|---|---|---|---|---|---|---|
| Clarify Before Executing: A Self-Evolving Agent for Resolving Intent Asymmetry in 3D Tool Orchestration | GitHub | Dataset | L1+L2+L3+L4 | 3D | Clarification-policy evolution from completed interactions | 2026-07 |
| SymbOmni: Evolving Agentic Omni Models via Symbolic Concept Learning | GitHub | Website | L1+L2+L3+L4 | Image | Cross-task memory or skill evolution | 2026-07 |
| SPIRAL | - | Website | L1+L2+L3+L4 | Video, World | Critic-trajectory post-training | 2026-03 |
| SIDiffAgent | - | - | L1+L3+L4 | Image | Self-improving generation behavior | 2026-02 |
| JarvisEvo: Towards a Self-Evolving Photo Editing Agent with Synergistic Editor-Evaluator Optimization | - | Website | L1+L2+L3+L4 | Image, Editing | Synergistic editor-evaluator evolution | 2025-11 |
Evaluation, Benchmarks, and Reward Models
These resources evaluate outputs, trajectories, controllers, or supporting signals. A stand-alone evaluator is not assigned an agenticity level. When an agent uses its feedback to choose a new generation action, the complete system may qualify as L3 or L4.
Figure 9. Causal evaluation of agentic visual generation.
Vector PDF
Agent and trajectory evaluation
| Resource | GitHub | Website | Scope | Type | Date |
|---|---|---|---|---|---|
| 3DCodeBench: Benchmarking Agentic Procedural 3D Modeling Via Code | GitHub | Website | Procedural 3D modeling via code | Agent benchmark | 2026-06 |
| A Unified Agentic Framework for Evaluating Conditional Image Generation | GitHub | - | Image generation | Evaluator orchestration | 2025-04 |
| ActVideoGen-Bench | - | Website | Long-horizon action-conditioned video | Agent benchmark | 2026-03 |
| AgentGen-Bench (SearchGen) | GitHub | Website | Search-intensive and no-search image prompts | Knowledge-grounded generation benchmark | 2026-07 |
| AgenticVBench: Can AI Agents Complete Real-World Post-Production Tasks? | GitHub | Website | Real-world video post-production | Agent benchmark | 2026-05 |
| AtelierEval | - | - | Human and LLM prompters | Prompter evaluation | 2026-05 |
| CineBench | - | - | Cinematic compilation | Agent benchmark | 2026-04 |
| DirectorBench: Diagnosing Long-Form Video Generation with Personalized Multi-Agent Evaluation | GitHub | Dataset | Long-form video generation | Multi-agent evaluator | 2026-05 |
| Draw ALL Your Imagine | GitHub | - | Complex image instructions | Benchmark and iterative agent framework | 2025-05 |
| IA-Bench | - | - | Planning, reasoning, search, and memory in image generation | Agent benchmark | 2026-06 |
| MSVE-Bench and NB-Q | GitHub (announced) | Website | 3–5 minute multi-shot video extrapolation | Benchmark and source-grounded protocol | 2026-05 |
| SynthSeg-Agents | - | - | Synthetic data for segmentation | Downstream task evaluation | 2025-12 |
| UniVA-Bench | GitHub | Website | Multi-step video workflows | Agent benchmark | 2025-11 |
Output benchmarks and evaluators
| Resource | GitHub | Website | Modality | Focus | Date |
|---|---|---|---|---|---|
| AIGVE-MACS | - | Website | Video | Multi-aspect comments and scores | 2025-07 |
| EvalCrafter | GitHub | Website | Video | Human-aligned video evaluation | 2023-10 |
| GenEval | GitHub | - | Image | Object, count, color, and position | 2023-10 |
| MME-Unify | GitHub | Website | Image | Unified understanding and generation | 2025-04 |
| Multi-Modal Language Models as Text-to-Image Model Evaluators | - | - | Image | MLLM-based evaluation | 2025-05 |
| T2I-CompBench | - | Website | Image | Compositional text-image alignment | 2023-07 |
| VBench | GitHub | Website | Video | Appearance and temporal quality | 2023-11 |
| VideoArgus: Agentic Rubric-Grounded Unified Evaluation for Video Generation and Editing | GitHub | Website | Video generation and editing | Rubric-grounded evaluator | 2026-08 |
| VisEditBench: Can Vision-Language Models Edit Visualization Code from Multimodal Feedback? | GitHub | - | Visualization-code editing from multimodal feedback | Editing benchmark | 2026-08 |
Slide and user-interface benchmarks
Reward models, verifiers, and preference data
| Resource | GitHub | Website | Scope | Role | Date |
|---|---|---|---|---|---|
| Customized Reward Models for Text-to-Image Generation | GitHub | - | Text-to-image | Request-specific reward | 2025-07 |
| Generative Universal Verifier | GitHub | Website | Multimodal generation | Generative verification | 2025-10 |
| ImageReward | GitHub | - | Text-to-image | General preference reward | 2023-04 |
| Personalized Reward Modeling for Text-to-Image Generation | - | - | Text-to-image | User-conditioned reward | 2025-11 |
| Pick-a-Pic | GitHub | - | Text-to-image | Pairwise preference dataset | 2023-05 |
| Unified Multimodal Chain-of-Thought Reward Model | - | Website | Multimodal generation | Reasoning-based reward | 2025-05 |
Supporting Components: the L0 Boundary
L0 is an inclusion boundary, not an agent category. The following systems are important generators, editors, retrieval modules, or optimization methods, but their fixed execution rules do not give a controller any generation-level decisions by themselves.
| Supporting component | GitHub | Website | Modality | Why it is outside L1-L4 | Date |
|---|---|---|---|---|---|
| AeSlides: Incentivizing Aesthetic Layout in LLM-Based Slide Generation via Verifiable Rewards | GitHub | Website | Slide | Trains a slide generator with layout rewards but no inference-time control trajectory | 2026-04 |
| Ask, Solve, Generate: Self-Evolving Unified Multimodal Understanding and Generation via Self-Consistency Rewards | GitHub | Website | Image | Fixed training, data, benchmark, or evaluation procedure without inference-time generation control | 2026-06 |
| Audio-Visual Flamingo: Open Audio-Visual Intelligence for Long and Complex Videos | GitHub | Website | Video | Audio-visual understanding and reasoning model; does not generate or edit visual artifacts | 2026-07 |
| AVI-Edit | - | Website | Editing | Fixed editing pipeline | 2025-12 |
| DALL-E 2 | - | - | Image | Fixed conditional generator | 2022-04 |
| DALL-E 3 | - | - | Image | Fixed conditional generator | 2023-09 |
| DataEvolver: Self-Evolving Multi-Agent Data Construction for Text-Rich Image Generation | GitHub | - | Image | Fixed training, data, benchmark, or evaluation procedure without inference-time generation control | 2026-06 |
| DPOK | GitHub | - | Image | Optimizes a generator rather than a generation-level controller | 2023-05 |
| DreamFusion | - | Website | 3D | Fixed optimization pipeline | 2022-09 |
| DreamGaussian | GitHub | Website | 3D | Fixed optimization pipeline | 2023-09 |
| FrontCoder: Scaling Visual Fidelity in Front-End Code Generation | GitHub | - | UI | Trains a one-shot frontend code generator without inference-time control | 2026-07 |
| GLIDE | GitHub | - | Image | Fixed conditional generator | 2021-12 |
| Imagen | - | Website | Image | Fixed conditional generator | 2022-05 |
| Imagen Video | - | Website | Video | Fixed conditional generator | 2022-10 |
| InstructPix2Pix | GitHub | Website | Editing | Fixed single-pass editor | 2022-11 |
| JAVEDIT: Joint Audio-Visual Instruction-Guided Video Editing with Agentic Data Curation | - | Dataset | Video, Editing | Fixed training, data, benchmark, or evaluation procedure without inference-time generation control | 2026-06 |
| Latent Diffusion | GitHub | - | Image | Fixed conditional generator | 2021-12 |
| Lumiere | - | Website | Video | Fixed conditional generator | 2024-01 |
| Magic3D | - | Website | 3D | Fixed optimization pipeline | 2022-11 |
| Make-A-Video | - | - | Video | Fixed conditional generator | 2022-09 |
| ModelScopeT2V | - | Website | Video | Fixed conditional generator | 2023-08 |
| OSPO: Object-Centric Self-Improving Preference Optimization for Text-to-Image Generation | GitHub | - | Image | Fixed training, data, benchmark, or evaluation procedure without inference-time generation control | 2025-06 |
| Parti | - | Website | Image | Fixed conditional generator | 2022-06 |
| Re-Imagen | - | - | Image | Fixed retrieval and generation pipeline | 2022-09 |
| ReasonGen-R1: CoT for Autoregressive Image generation models through SFT and RL | GitHub | Website | Image | Fixed training, data, benchmark, or evaluation procedure without inference-time generation control | 2025-05 |
| Reward-Instruct | GitHub | - | Image | Optimizes a generator rather than a generation-level controller | 2025-03 |
| ScaleEdit-12M: Scaling Open-Source Image Editing Data Generation via Multi-Agent Framework | GitHub | Dataset | Image, Editing | Fixed training, data, benchmark, or evaluation procedure without inference-time generation control | 2026-03 |
| SDXL | GitHub | - | Image | Fixed conditional generator | 2023-07 |
| Show-1 | GitHub | Website | Video | Fixed conditional generator | 2023-09 |
| SmartEdit | - | Website | Editing | Single-pass editor | 2023-12 |
| T2I-R1: Reinforcing Image Generation with Collaborative Semantic-level and Token-level CoT | GitHub | - | Image | Fixed training, data, benchmark, or evaluation procedure without inference-time generation control | 2025-05 |
| TokenFlow | GitHub | Website | Editing | Fixed editing pipeline | 2023-07 |
| Tune-A-Video | GitHub | Website | Editing | Fixed editing pipeline | 2022-12 |
| Video Diffusion Models | - | Website | Video | Fixed conditional generator | 2022-04 |
| Video LDM | - | Website | Video | Fixed conditional generator | 2023-04 |
| Video-P2P | - | Website | Editing | Fixed editing pipeline | 2023-03 |
| WorldCycle: Self-Verifiable Reinforcement Learning for Long-Horizon Video World Models | - | Website | Video | Fixed training, data, benchmark, or evaluation procedure without inference-time generation control | 2026-08 |
Community
Welcome to join our community to discuss agentic visual generation:
- WeChat community — open the QR code and scan it with WeChat.
- Discord community — join the discussion on Discord.
Contact
If you have any suggestions or find this repo helpful, feel free to contact us.
Email: yinminghuang1828@gmail.com, francisshuyuan@gmail.com.
If you find our work useful, please consider giving a star ⭐ to this github repository and citing it ❤️:
@article{huang2026agenticvisualgeneration,
  title={Agentic Visual Generation: From Generative Models to Agentic Control},
  author={Huang, Yinming and Tu, Shuyuan and Yan, Xi and Zhan, Jiahao and Yang, Zihan and Xing, Zhen and Zhang, Hui and Zhang, Tiehua and Jiang, Yu-Gang and Wu, Zuxuan},
  journal={arXiv preprint arXiv:2609.06758},
  year={2026}
}
Similar repos
Contributors
Languages
Python
100.0%