Official codes of VEnhancer: Generative Space-Time Enhancement for Video Generation
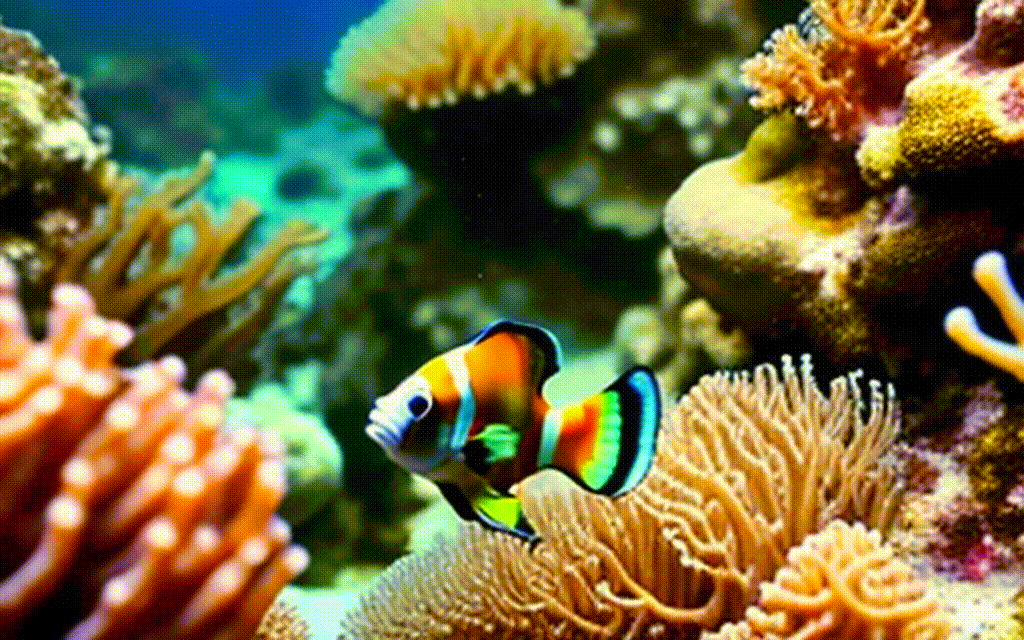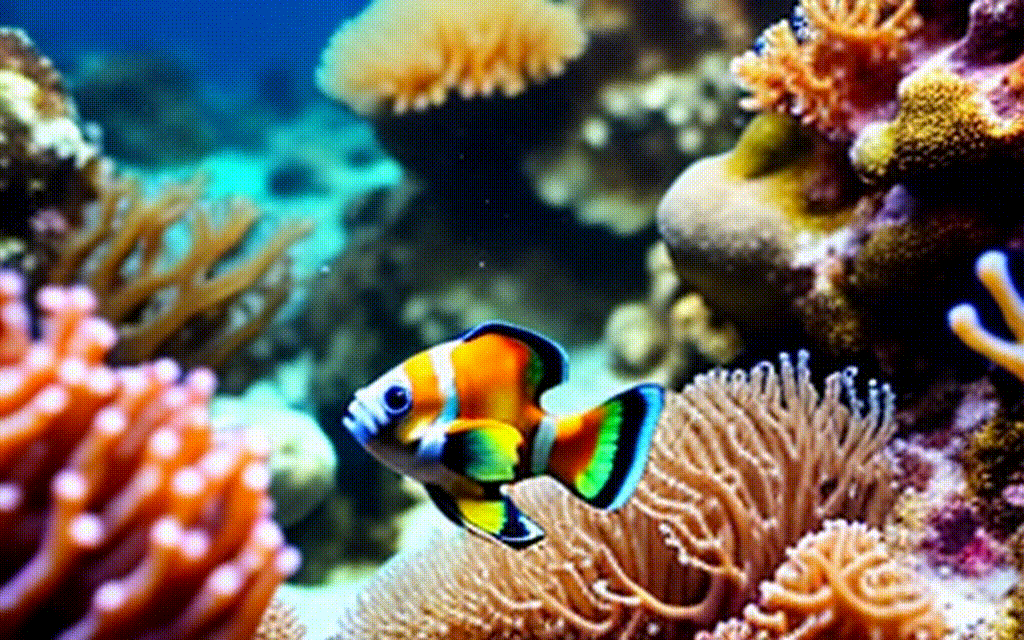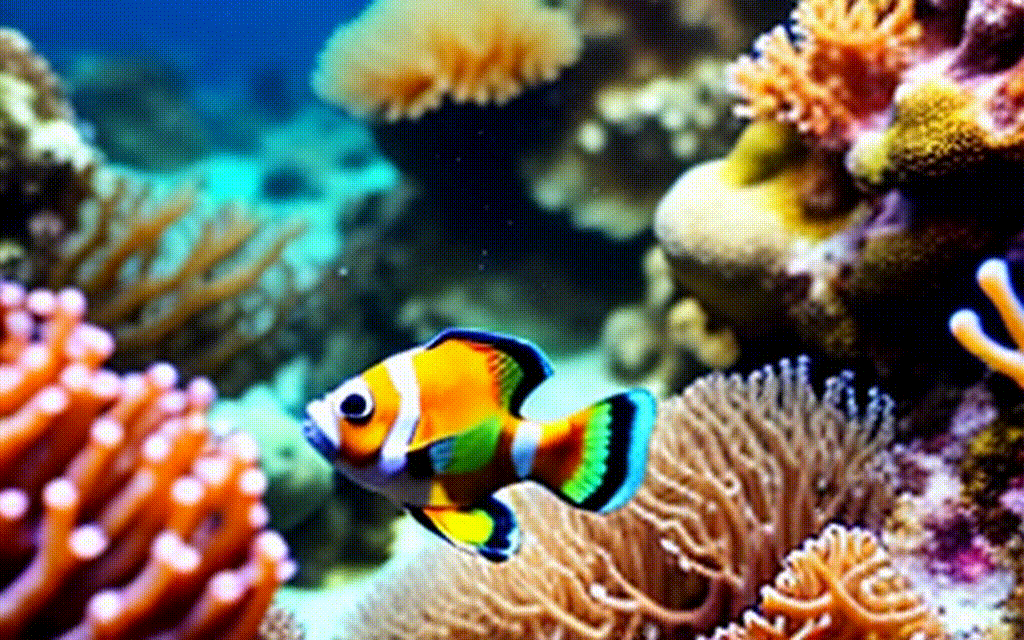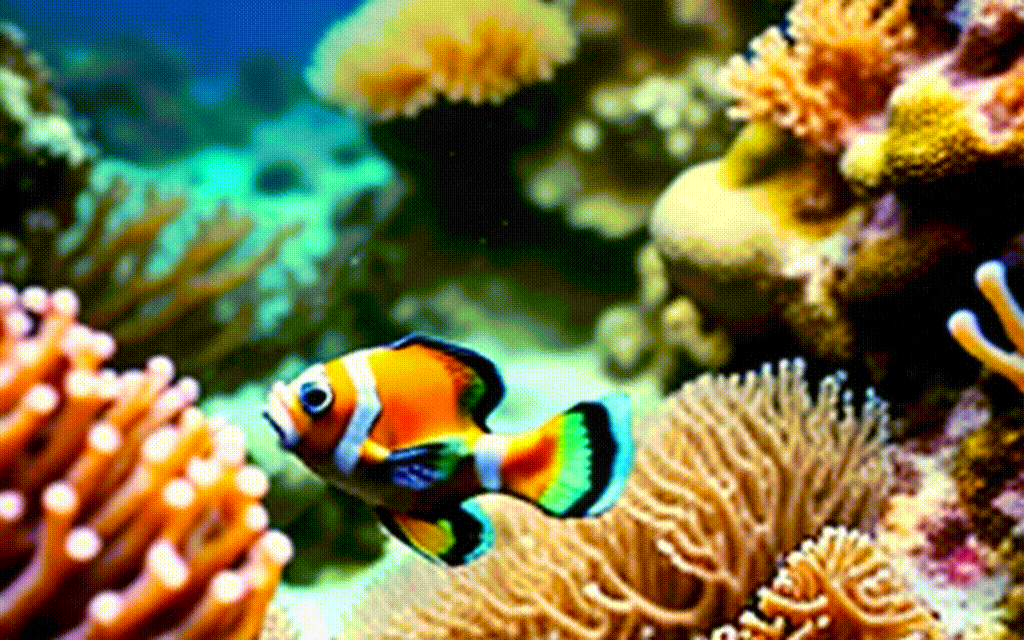
See the codeVEnhancer, an All-in-One generative video enhancement model that can achieve spatial super-resolution, temporal super-resolution, and video refinement for AI-generated videos.
| AIGC video | +VEnhancer |
|
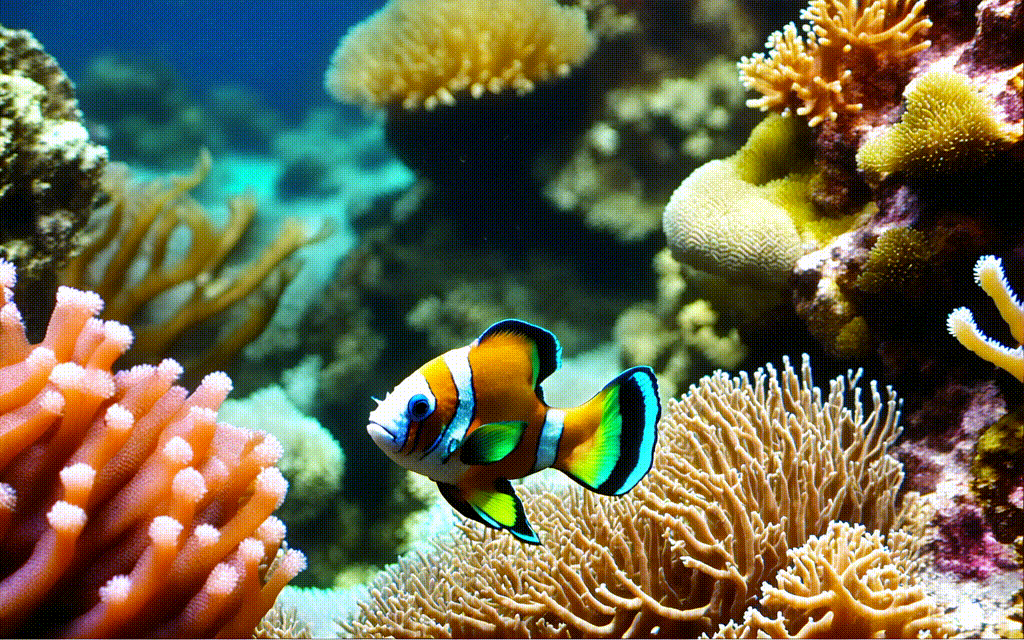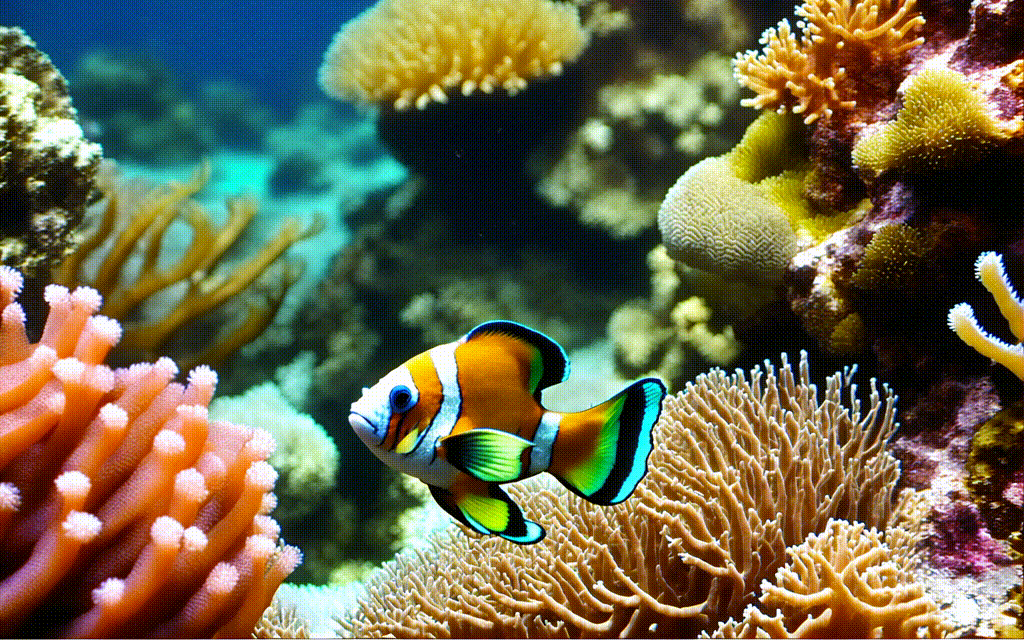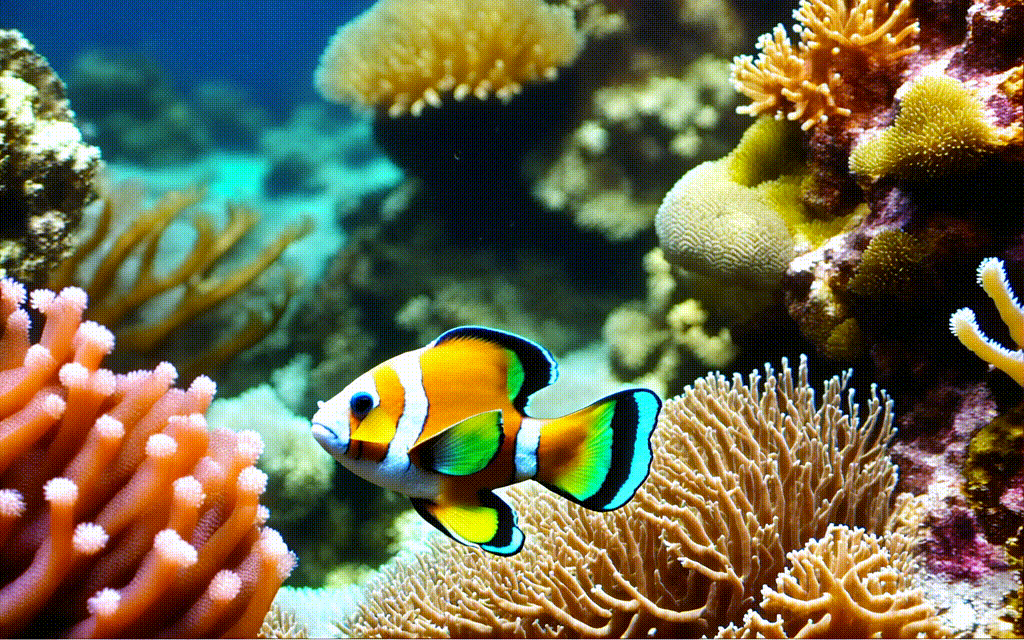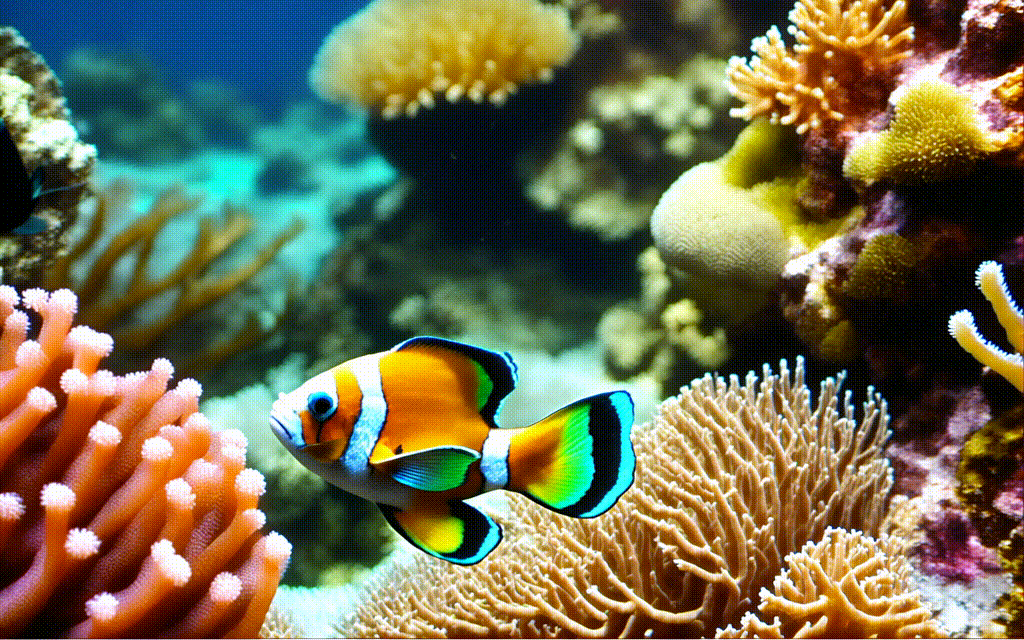
|
📖 For more visual results, go checkout our project page
--solver_mode 'fast' in the script command); Use temporal VAE to reduce video flickering.| Inputs & Results | Model Version | ||
|---|---|---|---|
| Prompt: A close-up shot of a woman standing in a dimly lit room. she is wearing a traditional chinese outfit, which includes a red and gold dress with intricate designs and a matching headpiece. from Open-Sora | v2 | ||
| Prompt: Einstein plays guitar. | v2 | ||
| Prompt: A girl eating noodles. | v2 | ||
| Prompt: A little brick man visiting an art gallery. from Kling | v1 |
VEnhancer achieves spatial super-resolution, temporal super-resolution (i.e, frame interpolation), and video refinement in one model. It is flexible to adapt to different upsampling factors (e.g., 1x~8x) for either spatial or temporal super-resolution. Besides, it provides flexible control to modify the refinement strength for handling diversified video artifacts.
It follows ControlNet and copies the architecures and weights of multi-frame encoder and middle block of a pretrained video diffusion model to build a trainable condition network. This video ControlNet accepts both low-resolution key frames and full frames of noisy latents as inputs. Also, the noise level $\sigma$ regarding noise augmentation and downscaling factor $s$ serve as additional network conditioning through our proposed video-aware conditioning apart from timestep $t$ and prompt $c_{text}$.
# clone this repo
git clone https://github.com/Vchitect/VEnhancer.git
cd VEnhancer

# create environment
conda create -n venhancer python=3.10
conda activate venhancer
pip install torch==2.0.1 torchvision==0.15.2 torchaudio==2.0.2
pip install -r requirements.txt
Note that ffmpeg command should be enabled. If you have sudo access, then you can install it using the following command:
sudo apt-get update && apt-get install ffmpeg libsm6 libxext6 -y
| Model Name | Description | HuggingFace | BaiduNetdisk |
|---|---|---|---|
| venhancer_paper.pth | very creative, strong refinement, but sometimes over-smooths edges and texture details. | download | download |
| venhancer_v2.pth | less creative, but can generate better texture details, and has better identity preservation. | download | download |
VEnhancer/ckpts directory. (optional as it can be done automatically) bash run_VEnhancer.sh
for single GPU inference (at least A100 80G is required), or
bash run_VEnhancer_MultiGPU.sh
for multiple GPU inference.
In run_VEnhancer.sh or run_VEnhancer_MultiGPU.sh,
version. We now provide two choices: v1 and v2 (venhancer_paper.pth and venhancer_v2.pth, respectively).up_scale is the upsampling factor ($1\sim8$) for spatial super-resolution. $\times3,4$ are recommended. Note that the target resolution will be adjusted no higher than 2k resolution.target_fps is your expected target fps, and the default is 24.noise_aug is the noise level ($0\sim300$) regarding noise augmentation. Higher noise corresponds to stronger refinement. $200\sim300$ are recommended.--filename_as_prompt to automatically use filename as prompt; or you can write the prompt to a txt file, and specify the prompt_path by setting --prompt_path [your_prompt_path]; or directly provide the prompt by specifying --prompt [your_prompt].--solver_mode fast has fixed 15 sampling steps. For --solver_mode normal, you can modify steps to trade off efficiency over video quality.The same functionality is also available as a gradio demo. Please follow the previous guidelines, and specify the model version (v1 or v2).
python gradio_app.py --version v1
If you use our work in your research, please cite our publication:
@article{he2024venhancer,
  title={VEnhancer: Generative Space-Time Enhancement for Video Generation},
  author={He, Jingwen and Xue, Tianfan and Liu, Dongyang and Lin, Xinqi and Gao, Peng and Lin, Dahua and Qiao, Yu and Ouyang, Wanli and Liu, Ziwei},
  journal={arXiv preprint arXiv:2407.07667},
  year={2024}
}
Our codebase builds on modelscope. Thanks the authors for sharing their awesome codebases!
If you have any questions, please feel free to reach us at [email protected].
1,722 followers · starred Aug 2024
128 followers · starred Sep 2024
259 followers · starred Apr 2025
388 followers · starred Sep 2024
Official codes of VEnhancer: Generative Space-Time Enhancement for Video Generation
See the codeVEnhancer, an All-in-One generative video enhancement model that can achieve spatial super-resolution, temporal super-resolution, and video refinement for AI-generated videos.
| AIGC video | +VEnhancer |
|
|
|
📖 For more visual results, go checkout our project page
--solver_mode 'fast' in the script command); Use temporal VAE to reduce video flickering.| Inputs & Results | Model Version | ||
|---|---|---|---|
| Prompt: A close-up shot of a woman standing in a dimly lit room. she is wearing a traditional chinese outfit, which includes a red and gold dress with intricate designs and a matching headpiece. from Open-Sora | v2 | ||
| Prompt: Einstein plays guitar. | v2 | ||
| Prompt: A girl eating noodles. | v2 | ||
| Prompt: A little brick man visiting an art gallery. from Kling | v1 |
VEnhancer achieves spatial super-resolution, temporal super-resolution (i.e, frame interpolation), and video refinement in one model. It is flexible to adapt to different upsampling factors (e.g., 1x~8x) for either spatial or temporal super-resolution. Besides, it provides flexible control to modify the refinement strength for handling diversified video artifacts.
It follows ControlNet and copies the architecures and weights of multi-frame encoder and middle block of a pretrained video diffusion model to build a trainable condition network. This video ControlNet accepts both low-resolution key frames and full frames of noisy latents as inputs. Also, the noise level $\sigma$ regarding noise augmentation and downscaling factor $s$ serve as additional network conditioning through our proposed video-aware conditioning apart from timestep $t$ and prompt $c_{text}$.
# clone this repo
git clone https://github.com/Vchitect/VEnhancer.git
cd VEnhancer

# create environment
conda create -n venhancer python=3.10
conda activate venhancer
pip install torch==2.0.1 torchvision==0.15.2 torchaudio==2.0.2
pip install -r requirements.txt
Note that ffmpeg command should be enabled. If you have sudo access, then you can install it using the following command:
sudo apt-get update && apt-get install ffmpeg libsm6 libxext6 -y
| Model Name | Description | HuggingFace | BaiduNetdisk |
|---|---|---|---|
| venhancer_paper.pth | very creative, strong refinement, but sometimes over-smooths edges and texture details. | download | download |
| venhancer_v2.pth | less creative, but can generate better texture details, and has better identity preservation. | download | download |
VEnhancer/ckpts directory. (optional as it can be done automatically) bash run_VEnhancer.sh
for single GPU inference (at least A100 80G is required), or
bash run_VEnhancer_MultiGPU.sh
for multiple GPU inference.
In run_VEnhancer.sh or run_VEnhancer_MultiGPU.sh,
version. We now provide two choices: v1 and v2 (venhancer_paper.pth and venhancer_v2.pth, respectively).up_scale is the upsampling factor ($1\sim8$) for spatial super-resolution. $\times3,4$ are recommended. Note that the target resolution will be adjusted no higher than 2k resolution.target_fps is your expected target fps, and the default is 24.noise_aug is the noise level ($0\sim300$) regarding noise augmentation. Higher noise corresponds to stronger refinement. $200\sim300$ are recommended.--filename_as_prompt to automatically use filename as prompt; or you can write the prompt to a txt file, and specify the prompt_path by setting --prompt_path [your_prompt_path]; or directly provide the prompt by specifying --prompt [your_prompt].--solver_mode fast has fixed 15 sampling steps. For --solver_mode normal, you can modify steps to trade off efficiency over video quality.The same functionality is also available as a gradio demo. Please follow the previous guidelines, and specify the model version (v1 or v2).
python gradio_app.py --version v1
If you use our work in your research, please cite our publication:
@article{he2024venhancer,
  title={VEnhancer: Generative Space-Time Enhancement for Video Generation},
  author={He, Jingwen and Xue, Tianfan and Liu, Dongyang and Lin, Xinqi and Gao, Peng and Lin, Dahua and Qiao, Yu and Ouyang, Wanli and Liu, Ziwei},
  journal={arXiv preprint arXiv:2407.07667},
  year={2024}
}
Our codebase builds on modelscope. Thanks the authors for sharing their awesome codebases!
If you have any questions, please feel free to reach us at [email protected].
1,722 followers · starred Aug 2024
128 followers · starred Sep 2024
259 followers · starred Apr 2025
388 followers · starred Sep 2024