[AAAI-2026]FlashVideo: Flowing Fidelity to Detail for Efficient High-Resolution Video Generation
See the code
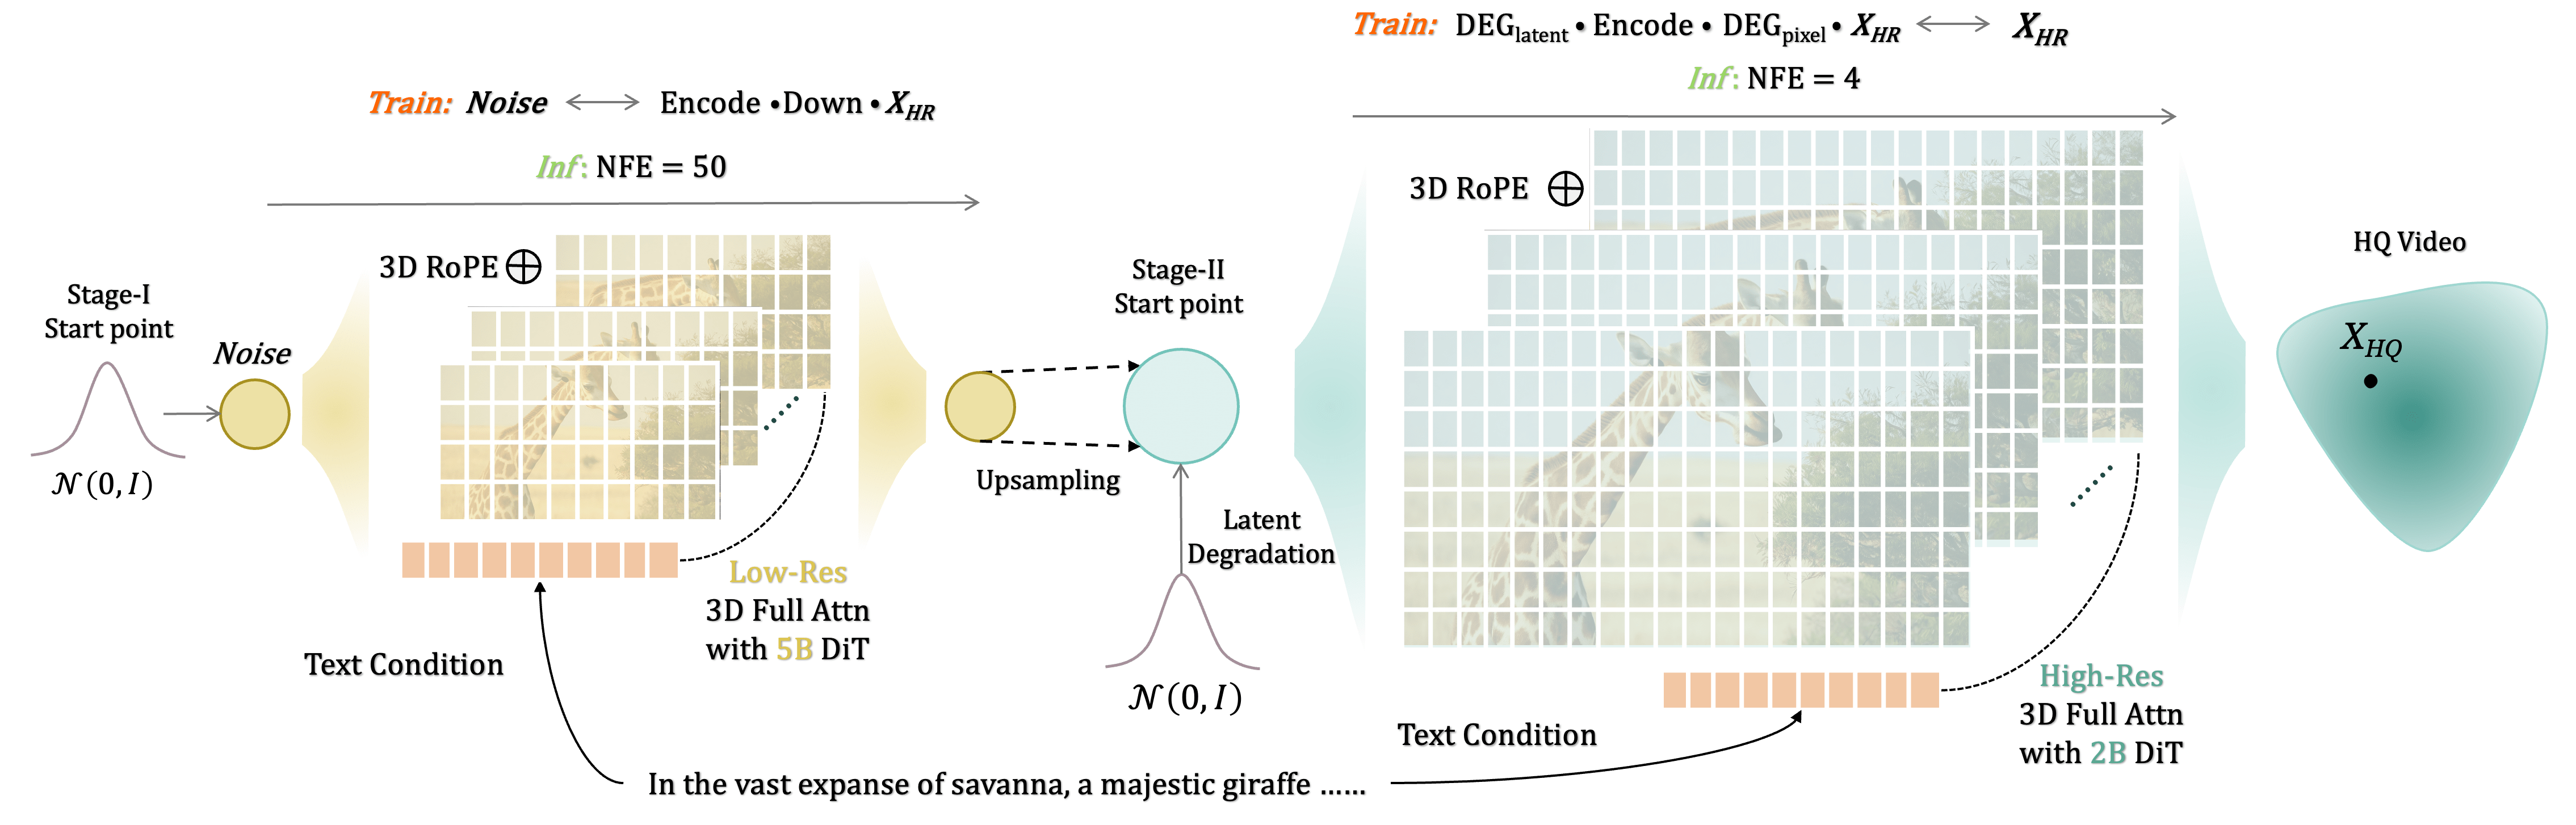
FlashVideo: Flowing Fidelity to Detail for Efficient High-Resolution Video Generation
Shilong Zhang, Wenbo Li, Shoufa Chen, Chongjian Ge, Peize Sun,
Yida Zhang, Yi Jiang, Zehuan Yuan, Bingyue Peng, Ping Luo,
HKU, CUHK, ByteDance

In this repository, we provide:
This repository is tested with PyTorch 2.4.0+cu121 and Python 3.11.11. You can install the necessary dependencies using the following command:
pip install -r requirements.txt
To get the 3D VAE (identical to CogVideoX), along with Stage-I and Stage-II weights, set them up as follows:
cd FlashVideo
mkdir -p ./checkpoints
huggingface-cli download --local-dir ./checkpoints  FoundationVision/FlashVideo
The checkpoints should be organized as shown below:
├── 3d-vae.pt
├── stage1.pt
└── stage2.pt
You can conveniently provide user prompts in our Jupyter notebook. The default configuration for spatial and temporal slices in the VAE Decoder is tailored for an 80G GPU. For GPUs with less memory, one might consider increasing the spatial and temporal slice.
flashvideo/demo.ipynb
You can conveniently provide the user prompt in a text file and generate videos with multiple gpus.
bash inf_270_1080p.sh
This project is developed based on CogVideoX. Please refer to their original license for usage details.
@article{zhang2025flashvideo,
  title={FlashVideo: Flowing Fidelity to Detail for Efficient High-Resolution Video Generation},
  author={Zhang, Shilong and Li, Wenbo and Chen, Shoufa and Ge, Chongjian and Sun, Peize and Zhang, Yida and Jiang, Yi and Yuan, Zehuan and Peng, Binyue and Luo, Ping},
  journal={arXiv preprint arXiv:2502.05179},
  year={2025}
}
135 followers · starred Feb 2025
415 followers · starred Feb 2025
499 followers · starred Feb 2025
86 followers · starred Feb 2025
[AAAI-2026]FlashVideo: Flowing Fidelity to Detail for Efficient High-Resolution Video Generation
See the code
FlashVideo: Flowing Fidelity to Detail for Efficient High-Resolution Video Generation
Shilong Zhang, Wenbo Li, Shoufa Chen, Chongjian Ge, Peize Sun,
Yida Zhang, Yi Jiang, Zehuan Yuan, Bingyue Peng, Ping Luo,
HKU, CUHK, ByteDance
In this repository, we provide:
This repository is tested with PyTorch 2.4.0+cu121 and Python 3.11.11. You can install the necessary dependencies using the following command:
pip install -r requirements.txt
To get the 3D VAE (identical to CogVideoX), along with Stage-I and Stage-II weights, set them up as follows:
cd FlashVideo
mkdir -p ./checkpoints
huggingface-cli download --local-dir ./checkpoints  FoundationVision/FlashVideo
The checkpoints should be organized as shown below:
├── 3d-vae.pt
├── stage1.pt
└── stage2.pt
You can conveniently provide user prompts in our Jupyter notebook. The default configuration for spatial and temporal slices in the VAE Decoder is tailored for an 80G GPU. For GPUs with less memory, one might consider increasing the spatial and temporal slice.
flashvideo/demo.ipynb
You can conveniently provide the user prompt in a text file and generate videos with multiple gpus.
bash inf_270_1080p.sh
This project is developed based on CogVideoX. Please refer to their original license for usage details.
@article{zhang2025flashvideo,
  title={FlashVideo: Flowing Fidelity to Detail for Efficient High-Resolution Video Generation},
  author={Zhang, Shilong and Li, Wenbo and Chen, Shoufa and Ge, Chongjian and Sun, Peize and Zhang, Yida and Jiang, Yi and Yuan, Zehuan and Peng, Binyue and Luo, Ping},
  journal={arXiv preprint arXiv:2502.05179},
  year={2025}
}
135 followers · starred Feb 2025
415 followers · starred Feb 2025
499 followers · starred Feb 2025
86 followers · starred Feb 2025