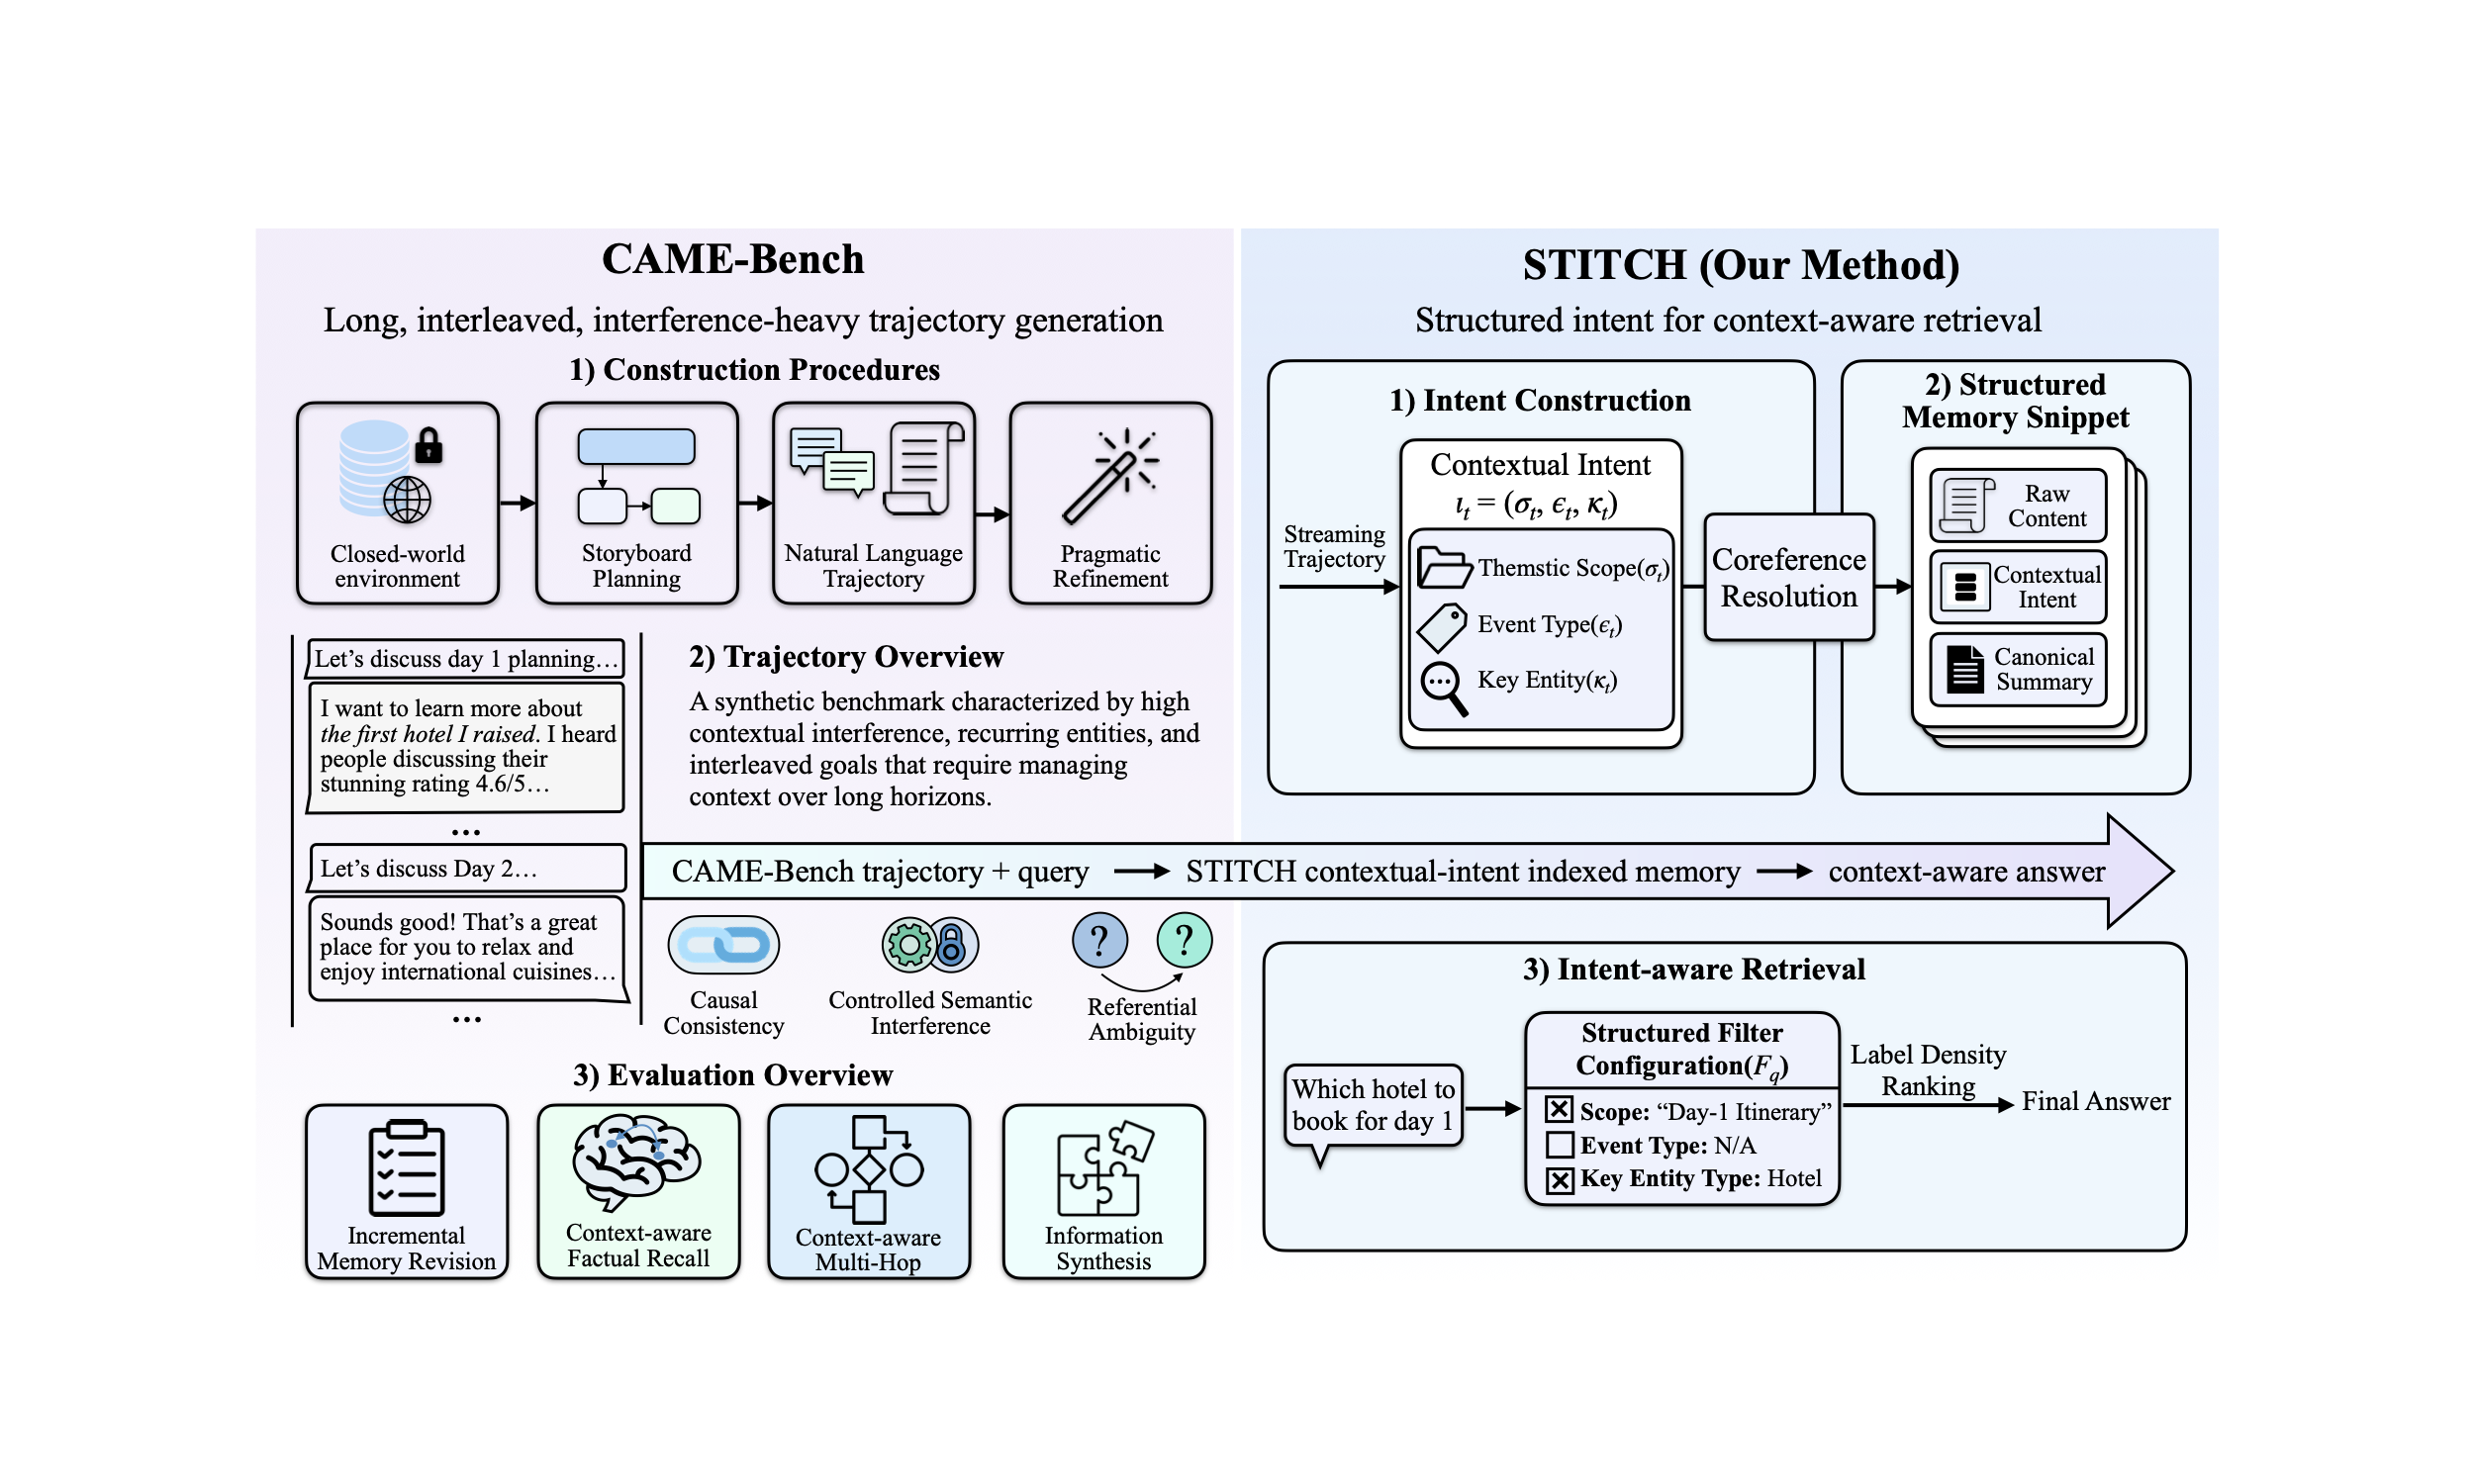
This repository contains STITCH (Structured Intent Tracking in Contextual History), a novel memory system for agents, and CAME-Bench, a comprehensive benchmark for evaluating agent memory consolidation.
🌐 Visit our project website for interactive demos, detailed methodology, and the benchmark explorer. Read the full paper here. Dataset is available on Hugging Face.
Start by setting up the environment. We recommend using a virtual environment:
# 1. Create and activate environment
python3 -m venv .venv
source .venv/bin/activate

# 2. Install dependencies
pip install -r requirements.txt
Select the relevant guide below based on your objective:
To evaluate a new retrieval or memory method using our dataset and metrics, check out the example script:
# Configure your API key first (e.g. OpenAI)
export OPENAI_API_KEY="sk-..."

# Run the example benchmark script
python example_run_benchmark.py
For detailed documentation: 👉 Read the Benchmark Usage Guide
To apply the STITCH memory system to external logs or other benchmarks: 👉 Read the STITCH Usage Guide
To reproduce the experimental results for STITCH on CAME-Bench and LongMemEval as reported in the paper:
👉 Switch to the paper-exp branch
git checkout paper-exp
To generate the CAME-Bench dataset from scratch (including debate trajectories and travel plans):
👉 Switch to the CAME-Bench_construction branch
git checkout CAME-Bench_construction
| Path | Description |
|---|---|
came_bench/ | The core benchmark library, including data loading, pipeline, and evaluation logic. |
method_stitch/ | Core implementation of the STITCH memory system. |
proto/ | Protocol Buffer definitions for data structures and configurations. |
scripts/ | Utility scripts. |
doc/ | Documentation and usage guides. |
@misc{yang2026groundingagentmemorycontextual,
      title={Grounding Agent Memory in Contextual Intent},
      author={Ruozhen Yang and Yucheng Jiang and Yueqi Jiang and Priyanka Kargupta and Yunyi Zhang and Jiawei Han},
      year={2026},
      eprint={2601.10702},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2601.10702},
}