
Volumetric Radiology AI in the Era of Multimodal Large Language Models
23
39 commits
updated Aug 24, 2026
README
Volumetric Radiology AI in the Era of Multimodal Large Language Models

The official resource repository for our review of volumetric radiology foundation models, multimodal large language models, agentic systems, and evaluation benchmarks.
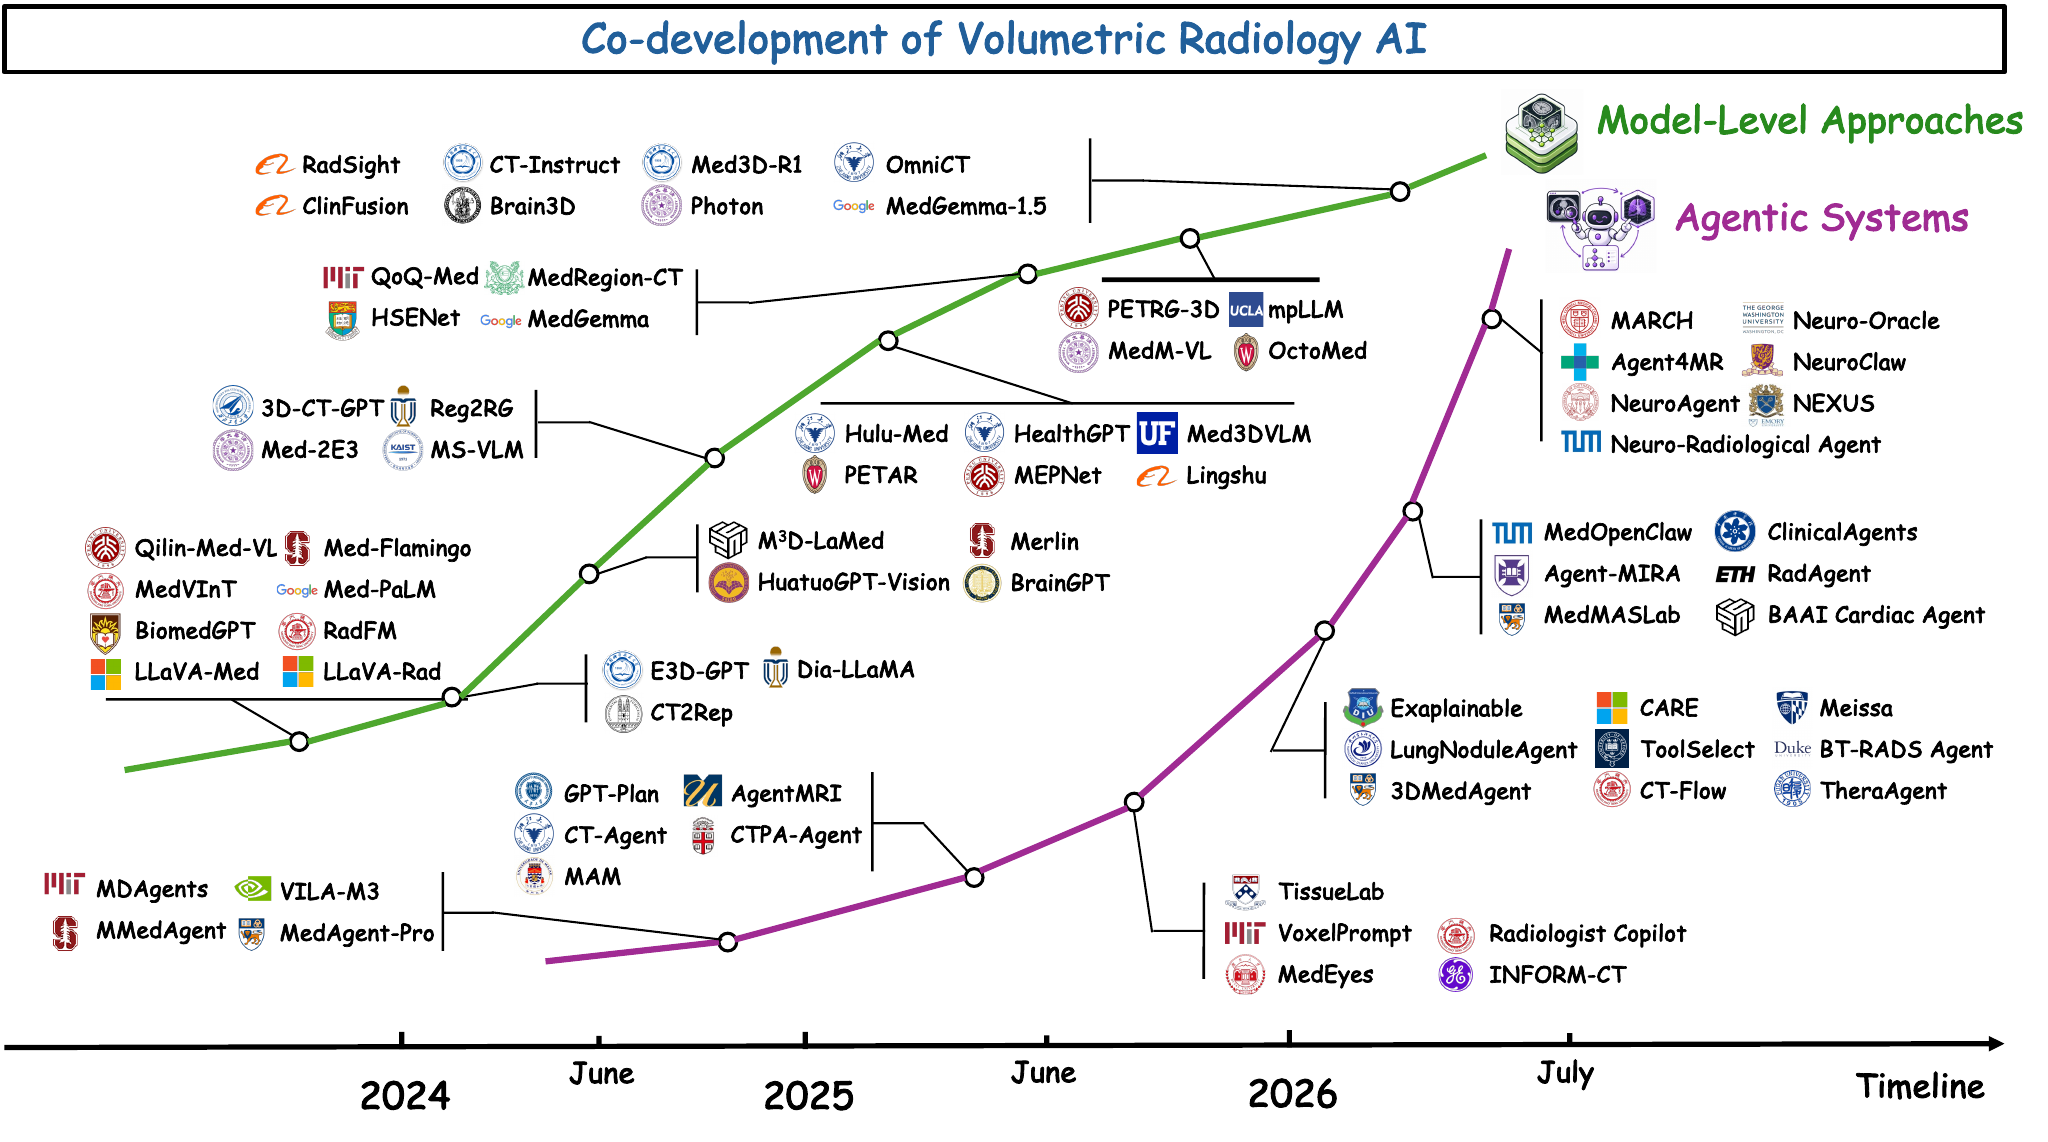
Co-development of volumetric radiology foundation models and agentic systems.
Contents
Foundation Models
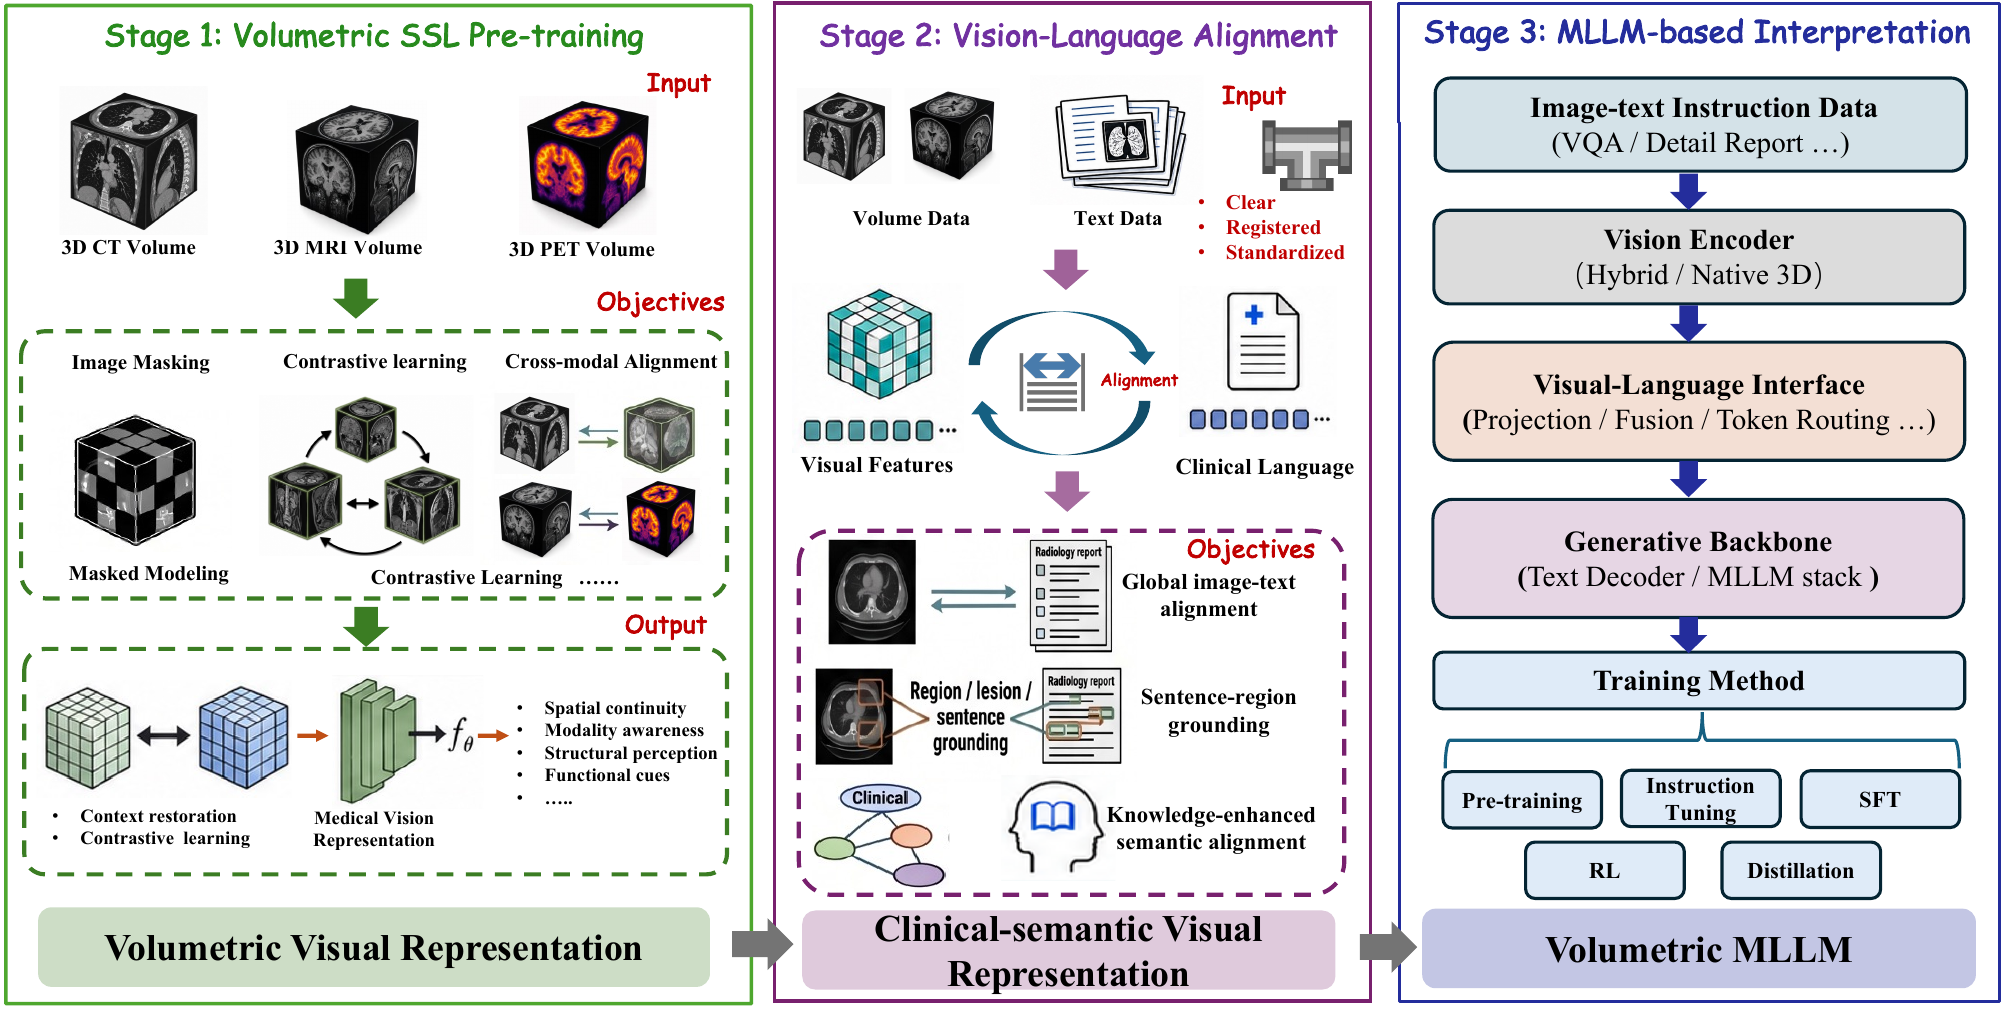
Foundation-model landscape: volumetric self-supervised pre-training, vision-language alignment, and MLLM-based interpretation.
Self-Supervised Pre-training
| Method | Title | Venue | Date | Paper | Project |
|---|---|---|---|---|---|
| Models Genesis | Medical Image Analysis | 21.02 | Paper | Project | |
| UniMiSS | UniMiSS: Universal Medical Self-Supervised Learning via Breaking Dimensionality Barrier | ECCV2022&TPAMI | 21.12 | Paper | Project |
| Swin-UNETR | Self-Supervised Pre-Training of Swin Transformers for 3D Medical Image Analysis | CVPR 2022 | CVPR 2022 | Paper | Project |
| PCRLv2 | A Unified Visual Information Preservation Framework for Self-supervised Pre-training in Medical Image Analysis | IEEE TPAMI | 2023.01 | Paper | Project |
| MIM-Med3D | Masked Image Modeling Advances 3D Medical Image Analysis | WACV 2023 | 2023.01 | Paper | Project |
| GVSL | Geometric Visual Similarity Learning in 3D Medical Image Self-supervised Pre-training | CVPR 2023 | 2023.03 | Paper | Project |
| M3AE | M3AE: Multimodal Representation Learning for Brain Tumor Segmentation with Missing Modalities | AAAI 2023 | 2023.03 | Paper | Project |
| HybridMIM | HybridMIM: A Hybrid Masked Image Modeling Framework for 3D Medical Image Segmentation | IEEE JBHI | 2024.04 | Paper | Project |
| VoCo | Large-Scale 3D Medical Image Pre-Training With Geometric Context Priors | CVPR 2024 / IEEE TPAMI | 2024.06 | Paper | Project |
| CDSSL-P3D | Cross-Dimensional Medical Self-Supervised Representation Learning Based on a Pseudo-3D Transformation | MICCAI 24 | 2024.10 | Paper | - |
| MDM | Masked Deformation Modeling for Volumetric Brain MRI Self-Supervised Pre-Training | IEEE TMI | 2024.12 | Paper | Project |
| DAE | Disruptive Autoencoders: Leveraging Low-level features for 3D Medical Image Pre-training | MIDL 2024 | 2024.06 | Paper | Project |
| Unified 3D MRI Representations via Sequence-Invariant Contrastive Learning | arXiv | 2025.01 | Paper | Project | |
| GzPT | Improving Self-Supervised Medical Image Pre-Training by Early Alignment With Human Eye Gaze Information | AAAI24/IEEE TMI | 2025.01 | Paper | Project |
| FM-HCT | 3D Foundation AI Model for Generalizable Disease Detection in Head Computed Tomography | arXiv | 2025.02 | Paper | Project |
| MedVAE: Efficient Automated Interpretation of Medical Images with Large-Scale Generalizable Autoencoders | MIDL 2025 | 2025.02 | Paper | Project | |
| MiM | MiM: Mask in Mask Self-Supervised Pre-Training for 3D Medical Image Analysis | IEEE TMI | 2025.04 | Paper | - |
| BrainMVP | BrainMVP: Multi-modal Vision Pre-training for Brain MRI Analysis | CVPR 2025 (Highlight) | 2025.06 | Paper | Project |
| SPECTRE | Scaling Self-Supervised and Cross-Modal Pretraining for Volumetric CT Transformers | CVPR 2026 | 2025.11 | Paper | Project |
| SubFore | HU-based Foreground Masking for 3D Medical Masked Image Modeling | MICCAI25 | 2025.10 | Paper | Project |
| 3DINO | A generalizable 3D framework and model for self-supervised learning in medical imaging | npj Digital Medicine | 2025.11 | Paper | Project |
| TotalFM | TotalFM: An Organ-Separated Framework for 3D-CT Vision Foundation Models | arxiv | 2026.01 | Paper | - |
| Curia-2 | Curia-2: Scaling Self-Supervised Learning for Radiology Foundation Models | arxiv | 2026.02 | Paper | - |
| OCTCube-M | A 3D multimodal optical coherence tomography foundation model for retinal and systemic diseases with cross-cohort and cross-device validation | Nature Biomedical Engineering | 2026.04 | Paper | Project |
| NeuroSTORM | Towards a general-purpose foundation model for fMRI analysis | NBME | 2026.03 | Paper | Project |
| Triad | Vision foundation model for 3D magnetic resonance imaging segmentation, classification, and registration | MedIA | 2026.05 | Paper | - |
| Foundation-VAE | Foundation VAEs for 3D CT Reconstruction, Augmentation, and Generation | ICML 2026 | 2026.05 | Paper | Project |
| CoralBay | CoralBay: A Self-Supervised CT Foundation Model | arXiv | 2026.06 | Paper | - |
| How Much MRI Preprocessing Is Enough? A Cost-Utility Study for Brain MRI Foundation Models | arXiv | 2026.06 | Paper | - | |
| NeuroVFM | Health system learning enables generalist neuroimaging models | Nature Medicine | 2026.07 | Paper | Project |
| BrainFIBRE | BrainFIBRE: A Foundation Model via Information Decomposition for Brain Microstructure | ECCV 2026 / arXiv | 2026.07 | Paper | - |
| BoneCoT / BoneFM | BoneCoT: multicentre validation of a whole-body skeleton foundation model for bone metastases guided by clinician-derived chain of thought | Nature Biomedical Engineering | 2026.07 | Paper | Project |
| Cardiac CT FM | A Unified Framework for Comprehensive Cardiac CT Segmentation and Phenotyping: Human-in-the-Loop Data Annotation, Vision Foundation Model Development, Multicenter Evaluation and Clinical Validation | arXiv | 2026.07 | Paper | - |
| COJEPA | Contrastive Joint-Embedding Prediction for Representation Learning in Structural MRI | arXiv | 2026.07 | Paper | - |
| BrainNext | BrainNext: A General-Purpose Self-Supervised Foundation Model for Brain MRI Analysis | arXiv | 2026.07 | Paper | - |
| OrganLens | OrganLens: Organ-Specific Representation Learning for CT Foundation Models | arXiv | 2026.07 | Paper | - |
| Rad-JEPA 3D | Rad-JEPA 3D: Radiology Joint-Embedding Predictive Model for 3D Computed Tomography | arXiv | 2026.07 | Paper | - |
Contrastive Learning (CLIP-based Methods)
| Method | Dimension | Title | Venue | Date | Paper | Project |
|---|---|---|---|---|---|---|
| MedCLIP | 2D | MedCLIP: Contrastive Learning from Unpaired Medical Images and Text | EMNLP 2022 | 2022.12 | Paper | Project |
| PubMedCLIP | 2D | PubMedCLIP: How Much Does CLIP Benefit Visual Question Answering in the Medical Domain? | EACL 2023 (Findings) | 2023.05 | Paper | Project |
| MedBLIP | 2D | MedBLIP: Bootstrapping Language-Image Pre-training from 3D Medical Images and Texts | arxiv | 2023.05 | Paper | - |
| CLIP-Lung | 2D | CLIP-Lung: Textual Knowledge-Guided Lung Nodule Malignancy Prediction | MICCAI 2023 | 2023.10 | Paper | Project |
| BioMedCLIP | 2D | BiomedCLIP: A Multimodal Biomedical Foundation Model Pretrained from Fifteen Million Scientific Image-Text Pairs | NEJM AI 2024 | 2024.01 | Paper | Project |
| PMC-CLIP | 2D | PMC-CLIP: Contrastive Language-Image Pre-training using Biomedical Documents | MICCAI 2023 | 2023.10 | Paper | Project |
| UniMedCLIP | 2D | UniMed-CLIP: Towards a Unified Image-Text Pretraining Paradigm for Diverse Medical Imaging Modalities | Arxiv | 2024.12 | Paper | Project |
| ConceptCLIP | 2D | ConceptCLIP: Towards Trustworthy Medical AI via Concept-Enhanced Contrastive Language-Image Pre-training | arXiv | 2025.01 | Paper | Project |
| MMKD-CLIP | 2D | Unifying Biomedical Vision-Language Expertise: Towards a Generalist Foundation Model via Multi-CLIP Knowledge Distillation | Arxiv | 2025.06 | Paper | - |
| RadiSimCLIP | 2D | RadiSimCLIP: A Radiology Vision-Language Model Pretrained on Simulated Radiologist Learning Dataset for Zero-Shot Medical Image Understanding | MICCAI 2025 Workshop | 2025.10 | Paper | Project |
| UniBrain | 3D | UniBrain: Universal Brain MRI Diagnosis with Hierarchical Knowledge-enhanced Pre-training | Computerized Medical Imaging and Graphics | 2023.09 | Paper | Project |
| CT2Rep | 3D | CT2Rep: Automated Radiology Report Generation for 3D Medical Imaging | MICCAI 2024 | 2024.03 | Paper | Project |
| CT-CLIP | 3D | Generalist Foundation Models from a Multimodal Dataset for 3D Computed Tomography | Nat Biomed Eng | 2024.03 | Paper | Project |
| CT-GLIP | 3D | CT-GLIP: 3D Grounded Language-Image Pretraining with CT Scans and Radiology Reports for Full-Body Scenarios | arXiv | 2024.04 | Paper | - |
| RadCLIP | 3D | RadCLIP: Enhancing Radiologic Image Analysis Through Contrastive Language–Image Pretraining | TNNLS | 2024.03 | Paper | - |
| Percival | 3D | A Pan-Organ Vision-Language Model for Generalizable 3D CT Representations | medRxiv | 2025.07 | Paper | - |
| OpenVocabCT | 3D | Towards Universal Text-driven CT Image Segmentation | arXiv | 2025.03 | Paper | - |
| fVLM | 3D | Large-scale and Fine-grained Vision-language Pre-training for Enhanced CT Image Understanding | ICLR 2025 | 2025.03 | Paper | Project |
| HLIP | 3D | Towards Scalable Language-Image Pre-training for 3D Medical Imaging | arxiv | 2025.05 | Paper | Project |
| RadZero3D | 3D | RadZero3D: Bridging Self-Supervised Video Models and Medical Vision-Language Alignment for Zero-Shot Chest CT Interpretation | ICCV 2025 Workshop | 2025.10 | Paper | - |
| T3D | 3D | T3D: Advancing 3D Medical Vision-Language Pre-training by Learning Multi-View Visual Consistency | ICCV 2025 Workshop | 2025.10 | Paper | - |
| ViSD-Boost | 3D | Boosting Vision Semantic Density with Anatomy Normality Modeling for Medical Vision-language Pre-training | ICCV 2025 | 2025.08 | Paper | Project |
| VELVET-Med | 3D | VELVET-Med: Vision and Efficient Language Pre-training for Volumetric Imaging Tasks in Medicine | arXiv | 2025.08 | Paper | - |
| MedVista3D | 3D | MedVista3D: Vision-Language Modeling for Reducing Diagnostic Errors in 3D CT Disease Detection, Understanding and Reporting | arXiv | 2025.09 | Paper | - |
| COLIPRI | 3D | Comprehensive Language-Image Pre-training for 3D Medical Image Understanding | arXiv | 2025.10 | Paper | Project |
| MPS-CT | 3D | More performant and scalable: Rethinking contrastive vision-language pre-training of radiology in the LLM era | MICCAI 2025 | 2025.10 | Paper | Project |
| PET-CLIP Captioner | 3D | Location-Guided Automated Lesion Captioning in Whole-body PET/CT Images | MICCAI 2025 | 2025.10 | Paper | - |
| MR-CLIP | 3D | Metadata-Aligned 3D MRI Representations for Contrast Understanding and Quality Control | arXiv | 2025.11 | Paper | - |
| BrgSA | 3D | Bridged Semantic Alignment for Zero-shot 3D Medical Image Diagnosis | arXiv | 2025.11 | Paper | Project |
| SCALE-VLP | 3D | SCALE-VLP: Soft-Weighted Contrastive Volumetric Vision-Language Pre-training with Spatial-Knowledge Semantics | arXiv | 2025.11 | Paper | - |
| SPECTRE | 3D | Scaling Self-Supervised and Cross-Modal Pretraining for Volumetric CT Transformers | CVPR 2026 | 2025.11 | Paper | Project |
| Pillar-0 | 3D | Pillar-0: A New Frontier for Radiology Foundation Models | arxiv | 2025.11 | Paper | Project |
| BTB3D | 3D | Better Tokens for Better 3D: Advancing Vision-Language Modeling in 3D Medical Imaging | NeurIPS 2025 | 2025.12 | Paper | Project |
| NeuroVFM | 3D | NeuroVFM: A Contrastive Vision-Language Model for Medical Reasoning in Alzheimer's Disease Diagnosis | WACV 2026 Workshops | 2026.01 | Paper | - |
| TotalFM | 3D | TotalFM: An Organ-Separated Framework for 3D-CT Vision Foundation Models | arxiv | 2026.01 | Paper | - |
| MG-3D | 3D | MG-3D: Multi-Grained Knowledge-Enhanced 3D Medical Vision-Language Pre-training | Medical Image Analysis (MedIA) | 2026.01 | Paper | Project |
| MedMAP | 3D | 3D Modality-Aware Pre-training for Vision-Language Model in MRI Multi-organ Abnormality Detection | arxiv | 2026.02 | Paper | Project |
| Prima | 3D | Learning neuroimaging models from health system-scale data | Nature Biomedical Engineering | 2026.02 | Paper | Project |
| SigVLP | 3D | SigVLP: Sigmoid Volume-Language Pre-Training for Self-Supervised CT-Volume Adaptive Representation Learning | arXiv | 2026.02 | Paper | - |
| RadFinder | 3D | Learning to Read Where to Look: Disease-Aware Vision–Language Pretraining for 3D CT | arXiv | 2026.03 | Paper | Project |
| Decipher-MR | 3D | Decipher-MR: A Vision-Language Foundation Model for 3D MRI Representations | npj Digital Medicine | 2026.04 | Paper | - |
| 3D | CLIP Architecture for Abdominal CT Image–Text Alignment and Zero-Shot Learning: Investigating Batch Composition and Data Scaling | arxiv | 2026.04 | Paper | - | |
| ASAP | 3D | ASAP: Advancing Medical Volumetric Representation Learning with Anatomy-aware Semantically-adaptive Pre-training | arXiv | 2026.05 | Paper | - |
| GLeVE | 3D | GLeVE: Graph-Guided Lesion Grounding with Proposal Verification in 3D CT | arXiv | 2026.05 | Paper | - |
| CA-GCL | 3D | CA-GCL: Cross-Anatomy Global-Local Contrastive Learning for Robust 3D Medical Image Understanding | arXiv | 2026.05 | Paper | - |
| SegReg-Rep | 3D | SegReg-Rep: Region-Aware Vision-Language Alignment for Fine-Grained Radiology Report Generation from 3D Medical Images | IEEE TPRMS | 2026.05 | Paper | Project |
| GLINT | 3D | GLINT: Sparsely Gated Vision-Language Alignment for Fine-Grained Radiology Representations | arXiv | 2026.06 | Paper | - |
| RadGrounder | 2D | Scalable Training of Spatially Grounded 2D Vision-Language Models for Radiology | arXiv | 2026.06 | Paper | - |
| RenalCLIP | 3D | A Disease-Centric Vision-Language Foundation Model for Precision Oncology in Kidney Cancer | Nature Communications | 2026.06 | Paper | - |
| Jolia / ConQuer | 3D | Jolia: Concept-Level Vision-Language Alignment for 3D CT Contrastive Learning | arXiv | 2026.06 | Paper | - |
| 3D | Disease-Centric Vision-Language Pretraining with Hybrid Visual Encoding for 3D Computed Tomography | arXiv | 2026.06 | Paper | - | |
| MedReCo | 3D | A Vision-language Framework for Comparative Reasoning in Radiology | arXiv | 2026.06 | Paper | - |
| SuG | 3D | Super-Generalist: Towards Comprehensive and Accurate Medical Image Understanding via Generalist-Specialist Synergy | arXiv | 2026.07 | Paper | - |
| OKA-CT | 3D | Learning Anatomy-Grounded CT Vision-Language Representations with Organ-Hierarchical Report Knowledge | arXiv | 2026.07 | Paper | - |
| OCP-CT | 3D | Fine-Grained Vision-Language Pretraining with Organ-Conditioned Pattern Tokens for CT Understanding | arXiv | 2026.07 | Paper | - |
| MseaCL | 3D | Multimodal Semantic-Aware Contrastive Learning For False Negative Mitigation in 3D Medical Imaging | arXiv | 2026.07 | Paper | - |
| CARVE | 3D | When Can Test-Time Adaptation Help Zero-Shot CT Vision-Language Models? | arXiv | 2026.07 | Paper | - |
| ACA | 3D | Anatomy Contextualized Adaption of CT Foundation Models | arXiv | 2026.07 | Paper | - |
| Spectrum | 3D | Learning How Much, Not Just What: Cross-Patient Burden Order for CT Vision-Language Pretraining | arXiv | 2026.07 | Paper | - |
| SCOPE | 3D | Semantically Calibrated Evidence Composition for CT Vision-Language Learning | arXiv | 2026.07 | Paper | - |
MLLM-based Methods
2D-only
| Method | Title | Venue | Date | Paper | Project |
|---|---|---|---|---|---|
| BiomedGPT | BiomedGPT: A Generalist Vision-Language Foundation Model for Diverse Biomedical Tasks | Nat Med 2024 | 2023.05 | Paper | Project |
| MedVInT | PMC-VQA: Visual Instruction Tuning for Medical Visual Question Answering | Arxiv/ Communications Medicine | 2023.05/2024.12 | Paper | - |
| LLaVA-Med | LLaVA-Med: Training a Large Language-and-Vision Assistant for Biomedicine in One Day | NeurIPS 2023 | 2023.06 | Paper | Project |
| Med-Flamingo | Med-Flamingo: a Multimodal Medical Few-shot Learner | ML4H 2023 | 2023.07 | Paper | Project |
| Med-PaLM M | Towards Generalist Biomedical AI | NEJM AI 2024 / arXiv | 2023.07 | Paper | Project |
| Qilin-Med-VL | Qilin-Med-VL: Towards Chinese Large Vision-Language Model for General Healthcare | arXiv | 2023.10 | Paper | - |
| R2GenGPT | R2GenGPT: Radiology Report Generation with Frozen LLMs | Meta-Radiology | 2023.11 | Paper | - |
| BiRD | A Refer-and-Ground Multimodal Large Language Model for Biomedicine | MICCAI 2024 | 2024.06 | Paper | - |
| HuatuoGPT-Vision | Towards Injecting Medical Visual Knowledge into Multimodal LLMs at Scale | EMNLP24 | 2024.06 | Paper | Project |
| Llama3-Med | Advancing High Resolution Vision-Language Models in Biomedicine | arXiv | 2024.06 | Paper | Project |
| MiniGPT-Med | MiniGPT-Med: Large Language Model as a General Interface for Radiology Diagnosis | arXiv | 2024.07 | Paper | Project |
| TinyLLaVA-Med | Democratizing MLLMs in Healthcare: TinyLLaVA-Med for Efficient Healthcare Diagnostics in Resource-Constrained Settings | MICCAI24 | 2024.09 | Paper | - |
| Med-MoE | Med-MoE: Mixture of Domain-Specific Experts for Lightweight Medical Vision-Language Models | EMNLP24 | 2024.09 | Paper | Project |
| GMAI-VL | GMAI-VL & GMAI-VL-5.5M: A Large Vision-Language Model and A Comprehensive Multimodal Dataset Towards General Medical AI | arXiv/AAAI26 | 2024.11 | Paper | Project |
| BiMediX2 | BiMediX2: Bio-Medical EXpert LMM for Diverse Medical Modalities | Findings of EMNLP 2025 | 2025.01 | Paper | Project |
| HealthGPT | HealthGPT: A Medical Large Vision-Language Model for Unifying Comprehension and Generation via Heterogeneous Knowledge Adaptation | ICML 2025 | 2025.02 | Paper | Project |
| MedVLM-R1 | MedVLM-R1: Incentivizing Medical Reasoning Capability of Vision-Language Models (VLMs) via Reinforcement Learning | MICCAI25 | 2025.02 | Paper | Project |
| Med-R1 | Med-R1: Reinforcement Learning for Generalizable Medical Reasoning in Vision-Language Models | TMI | 2025.03 | Paper | Project |
| OmniV-Med | OmniV-Med: Scaling Medical Vision-Language Model for Universal Visual Understanding | arXiv | 2025.04 | Paper | - |
| UniBioMed | UniBiomed: A Universal Foundation Model for Grounded Biomedical Image Interpretation | arXiv | 2025.04 | Paper | Project |
| MedRegA | MedRegA: Interpretable Bilingual Multimodal Large Language Model for Diverse Biomedical Tasks | ICLR25 | 2025.04 | Paper | Project |
| UMed-LVLM | Improving Medical Large Vision-Language Models with Abnormal-Aware Feedback | ACL 2025 | 2025.05 | Paper | - |
| QoQ-Med | QoQ-Med: Building Multimodal Clinical Foundation Models with Domain-Aware GRPO Training | arXiv | 2025.06 | Paper | Project |
| Lingshu | Lingshu: A Generalist Foundation Model for Unified Multimodal Medical Understanding and Reasoning | arXiv | 2025.06 | Paper | Project |
| MedGemma | MedGemma Technical Report | arXiv | 2025.07 | Paper | Project |
| Critus-V | Citrus-V: Advancing Medical Foundation Models with Unified Medical Image Grounding for Clinical Reasoning | arXiv | 2025.09 | Paper | Project |
| MedPLIB | Towards a Multimodal Large Language Model with Pixel-Level Insight for Biomedicine | AAAI25 | 2025.10 | Paper | Project |
| OctoMed | OctoMed: Data Recipes for State-of-the-Art Multimodal Medical Reasoning | arXiv | 2025.11 | Paper | Project |
| MedMO | MedMO: Grounding and Understanding Multimodal Large Language Model for Medical Images | arXiv | 2026.02 | Paper | Project |
| MediX-R1 | MediX-R1: Open Ended Medical Reinforcement Learning | arXiv | 2026.02 | Paper | Project |
| MEDIC-AD | MEDIC-AD: Towards Medical Vision-Language Model’s Clinical Intelligence | CVPR26 Oral | 2026.03 | Paper | Project |
| MedVR | MedVR: Annotation-Free Medical Visual Reasoning via Agentic Reinforcement Learning | ICLR 26 | 2026.04 | Paper | Project |
Unified 2D + Serialized-3D
| Method | Title | Venue | Date | Paper | Project |
|---|---|---|---|---|---|
| RadFM | Towards Generalist Foundation Model for Radiology by Leveraging Web-scale 2D&3D Medical Data | Nat Commun 2025 / arXiv | 2023.08 | Paper | Project |
| Med-Gemini | Advancing Multimodal Medical Capabilities of Gemini | Nat Med 2025 / arXiv | 2024.05 | Paper | Project |
| Med-2E3 | Med-2E3: A 2D-Enhanced 3D Medical Multimodal Large Language Model | BIBM25 | 2024.11 | Paper | - |
| Hulu-Med | Hulu-Med: A Transparent Generalist Model towards Holistic Medical Vision-Language Understanding | arXiv | 2025.10 | Paper | Project |
| Fleming-VL | Fleming-VL: Towards Universal Medical Visual Reasoning with Multimodal LLMs | arXiv | 2025.11 | Paper | Project |
| MedM-VL | MedM-VL: What Makes a Good Medical LVLM? | International Workshop on Agentic AI for Medicine 2025 | 2025.09 | Paper | Project |
| CTInstruct | CTInstruct: Towards Unified 3D CT Understanding via Instruction Tuning | AAAI 26 | 2026.01 | Paper | Project |
| A data-efficient 3D medical vision-language model using only a 2D encoder | Scientific report | 2026.02 | Paper | - | |
| MedPruner | MedPruner: Training-Free Hierarchical Token Pruning for Efficient 3D Medical Image Understanding in Vision-Language Models | MICCAI2026 | 2026.03 | Paper | - |
| Photon | Photon: Speedup Volume Understanding with Efficient Multimodal Large Language Models | ICLR 26 | 2026.03 | Paper | Project |
| OmniCT | OmniCT: Towards a Unified Slice-Volume LVLM for Comprehensive CT Analysis | ICLR 26 | 2026.03 | Paper | Project |
| MedGemma1.5 | MedGemma 1.5 Technical Report | arXiv | 2026.04 | Paper | Project |
| TGH-MoE | Adapting 2D Multi-Modal Large Language Model for 3D CT Image Analysis | arXiv | 2026.04 | Paper | - |
| Brain-Adapter | Brain-Adapter: A Dual-Stream Vision-Language MIL Framework for Comprehensive 3D CT Diagnosis of Acute Intracranial Pathologies | arXiv | 2026.06 | Paper | - |
| UniReason-Med | UniReason-Med: A Shared Grounded Reasoning Interface for 2D-to-3D Transfer in Medical VQA | arXiv | 2026.06 | Paper | Project |
| MedReCo-VLM | A Vision-language Framework for Comparative Reasoning in Radiology | arXiv | 2026.06 | Paper | - |
| RadSight | RadSight: Towards Perceptually Reliable Multimodal Radiology Image Understanding | arXiv | 2026.07 | Paper | Project |
| ClinFusion | ClinFusion: A Vision-Centric Multimodal LLM System for Holistic Medical Understanding | arXiv | 2026.07 | Paper | Project |
| Hounsfield | Towards Enhancing 3D Spatial Reasoning in Medical Multimodal Large Language Models | arXiv | 2026.07 | Paper | Project |
| MedARC | MedARC: Training-Free Adaptive Redundancy Compression of Visual Tokens for 3D Medical Vision-Language Models | arXiv | 2026.07 | Paper | - |
| ORCA | ORCA: ORgan-Centroid Aggregation for Training-Free 3D CT Visual Token Compression | arXiv | 2026.07 | Paper | Project |
Native 3D-Volume
| Method | Title | Venue | Date | Paper | Project |
|---|---|---|---|---|---|
| CT2Rep | CT2Rep: Automated Radiology Report Generation for 3D Medical Imaging | MICCAI 2024 / arXiv | 2024.03 | Paper | Project |
| Dia-LLaMA | Dia-LLaMA: Towards Large Language Model-driven CT Report Generation | MICCAI | 2024.03 | Paper | - |
| M3D-LaMed | M3D: Advancing 3D Medical Image Analysis with Multi-Modal Large Language Models | ICLR 2025 / arXiv | 2024.04 | Paper | Project |
| Merlin | Merlin: A Computed Tomography Vision-Language Foundation Model and Dataset | Nature 2026 / arXiv | 2024.06 | Paper | Project |
| BrainGPT | Towards a Holistic Framework for Multimodal Large Language Models in Three-dimensional Brain CT Report Generation | Nat Commun 2025 / arXiv | 2024.07 | Paper | Project |
| 3D-CT-GPT | 3D-CT-GPT: Generating 3D Radiology Reports through Integration of Large Vision-Language Models | arXiv | 2024.09 | Paper | - |
| E3D-GPT | E3D-GPT: Enhanced 3D Visual Foundation for Medical Vision-Language Model | arXiv | 2024.10 | Paper | - |
| Reg2RG | Large Language Model with Region-guided Referring and Grounding for CT Report Generation | arXiv | 2024.11 | Paper | - |
| MS-VLM | Read Like a Radiologist: Efficient Vision-Language Model for 3D Medical Imaging Interpretation | arXiv | 2024.12 | Paper | - |
| MEPNet | MEPNet: Medical Entity-balanced Prompting Network for Brain CT Report Generation | arXiv | 2025.03 | Paper | - |
| Med3DVLM | Med3DVLM: An Efficient Vision-Language Model for 3D Medical Image Analysis | IEEE JBHI 2025 / arXiv | 2025.03 | Paper | Project |
| HSENet | HSENet: Hybrid Spatial Encoding Network for 3D Medical Vision-Language Understanding | arXiv | 2025.06 | Paper | - |
| MedRegion-CT | MedRegion-CT: Region-Focused Multimodal LLM for Comprehensive 3D CT Report Generation | arXiv | 2025.06 | Paper | - |
| mpLLM | Multimodal LLM With Hierarchical Mixture-of-Experts for VQA on 3D Brain MRI | arXiv | 2025.09 | Paper | - |
| 3DReasonKnee | 3DReasonKnee: Advancing Grounded Reasoning in Medical Vision Language Models | arXiv | 2025.10 | Paper | - |
| PETAR | PETAR: Localized Findings Generation with Mask-Aware Vision-Language Modeling for PET Automated Reporting | arXiv | 2025.10 | Paper | - |
| BTB3D | Better Tokens for Better 3D: Advancing Vision-Language Modeling in 3D Medical Imaging | NeurlPS 2025 | 2025.10 | Paper | Project |
| PETRG-3D | Vision-Language Models for Automated 3D PET/CT Report Generation | arXiv | 2025.11 | Paper | - |
| CTest-Metric | CTest-Metric: A Unified Framework to Assess Clinical Validity of Metrics for CT Report Generation | ISBI2026 | 2026.01 | Paper | - |
| Brain3D | Brain3D: Brain Report Automation via Inflated Vision Transformers in 3D | arXiv | 2026.02 | Paper | Project |
| Med3D-R1 | Med3D-R1: Incentivizing Clinical Reasoning in 3D Medical Vision-Language Models for Abnormality Diagnosis | arXiv | 2026.02 | Paper | - |
| LoV3D | LoV3D: Grounding Cognitive Prognosis Reasoning in Longitudinal 3D Brain MRI via Regional Volume Assessments | arXiv | 2026.03 | Paper | - |
| Ker-VLJEPA-3B | Curriculum-Driven 3D CT Report Generation via Language-Free Visual Grafting and Zone-Constrained Compression | arXiv | 2026.03 | Paper | Project |
| U-VLM | U-VLM: Hierarchical Vision Language Modeling for Report Generation | arXiv | 2026.02 | Paper | Project |
| CT-CHAT | Generalist foundation models from a multimodal dataset for 3D computed tomography | Nature Biomedical Engineering | 2026.02 | Paper | Project |
| MedVL-SAM2 | MedVL-SAM2: A unified 3D medical vision–language model for multimodal reasoning and prompt-driven segmentation | arXiv | 2026.01 | Paper | - |
| BoiD | Enhancing 3D medical multi-modal large language models with integrated human body priors for computed tomography | Pattern Recognition | 2026.04 | Paper | - |
| DCP-PD | Enhancing Fine-Grained Spatial Grounding in 3D CT Report Generation via Discriminative Guidance | arxiv | 2026.04 | Paper | - |
| SegReg-Rep | SegReg-Rep: Region-Aware Vision-Language Alignment for Fine-Grained Radiology Report Generation from 3D Medical Images | IEEE TPRMS | 2026.05 | Paper | Project |
| CLarGen | Generating Reports or Repeating Templates? Measuring and Mitigating Template Collapse in 3D CT Report Generation | arXiv | 2026.05 | Paper | - |
| TIF-GRPO | Regulating Anatomy-Aware Rewards via Trajectory-Integral Feedback for Volumetric Computed Tomography Analysis | arXiv | 2026.05 | Paper | - |
| RAD3D-Prefix | Revisiting LLM Adaptation for 3D CT Report Generation: A Study of Scaling and Diagnostic Priors | arXiv | 2026.06 | Paper | - |
| E-MRL | E-MRL: Cross-view Aligned Evidence-driven Multimodal Reinforcement Learning for Reliable 3D Tumor Analysis | arXiv | 2026.06 | Paper | - |
| MRI2Rep | MRI2Rep: Autoregressive Structured Report Generation for 3D Liver MRI | arXiv | 2026.06 | Paper | - |
| NeuroVFM | Health system learning enables generalist neuroimaging models | Nature Medicine | 2026.07 | Paper | Project |
| PIPA | PIPA: Prior-Driven Prompting with Diagnosis-Oriented Retrieval-Augmentation for 3D Radiology Report Generation | IEEE TMI | 2026.07 | Paper | Project |
| MonteRET | MonteRET: AI Agent Enhancing Multimodal LLMs with Multi-granularity Knowledge Retrieval for Chest CT Report Generation | arXiv | 2026.07 | Paper | - |
| Multi-LLM MRI | Multi-LLM Collaborative MRI Report Generation for Visual Instruction Tuning in Brain Oncology | arXiv | 2026.07 | Paper | - |
Agentic Systems
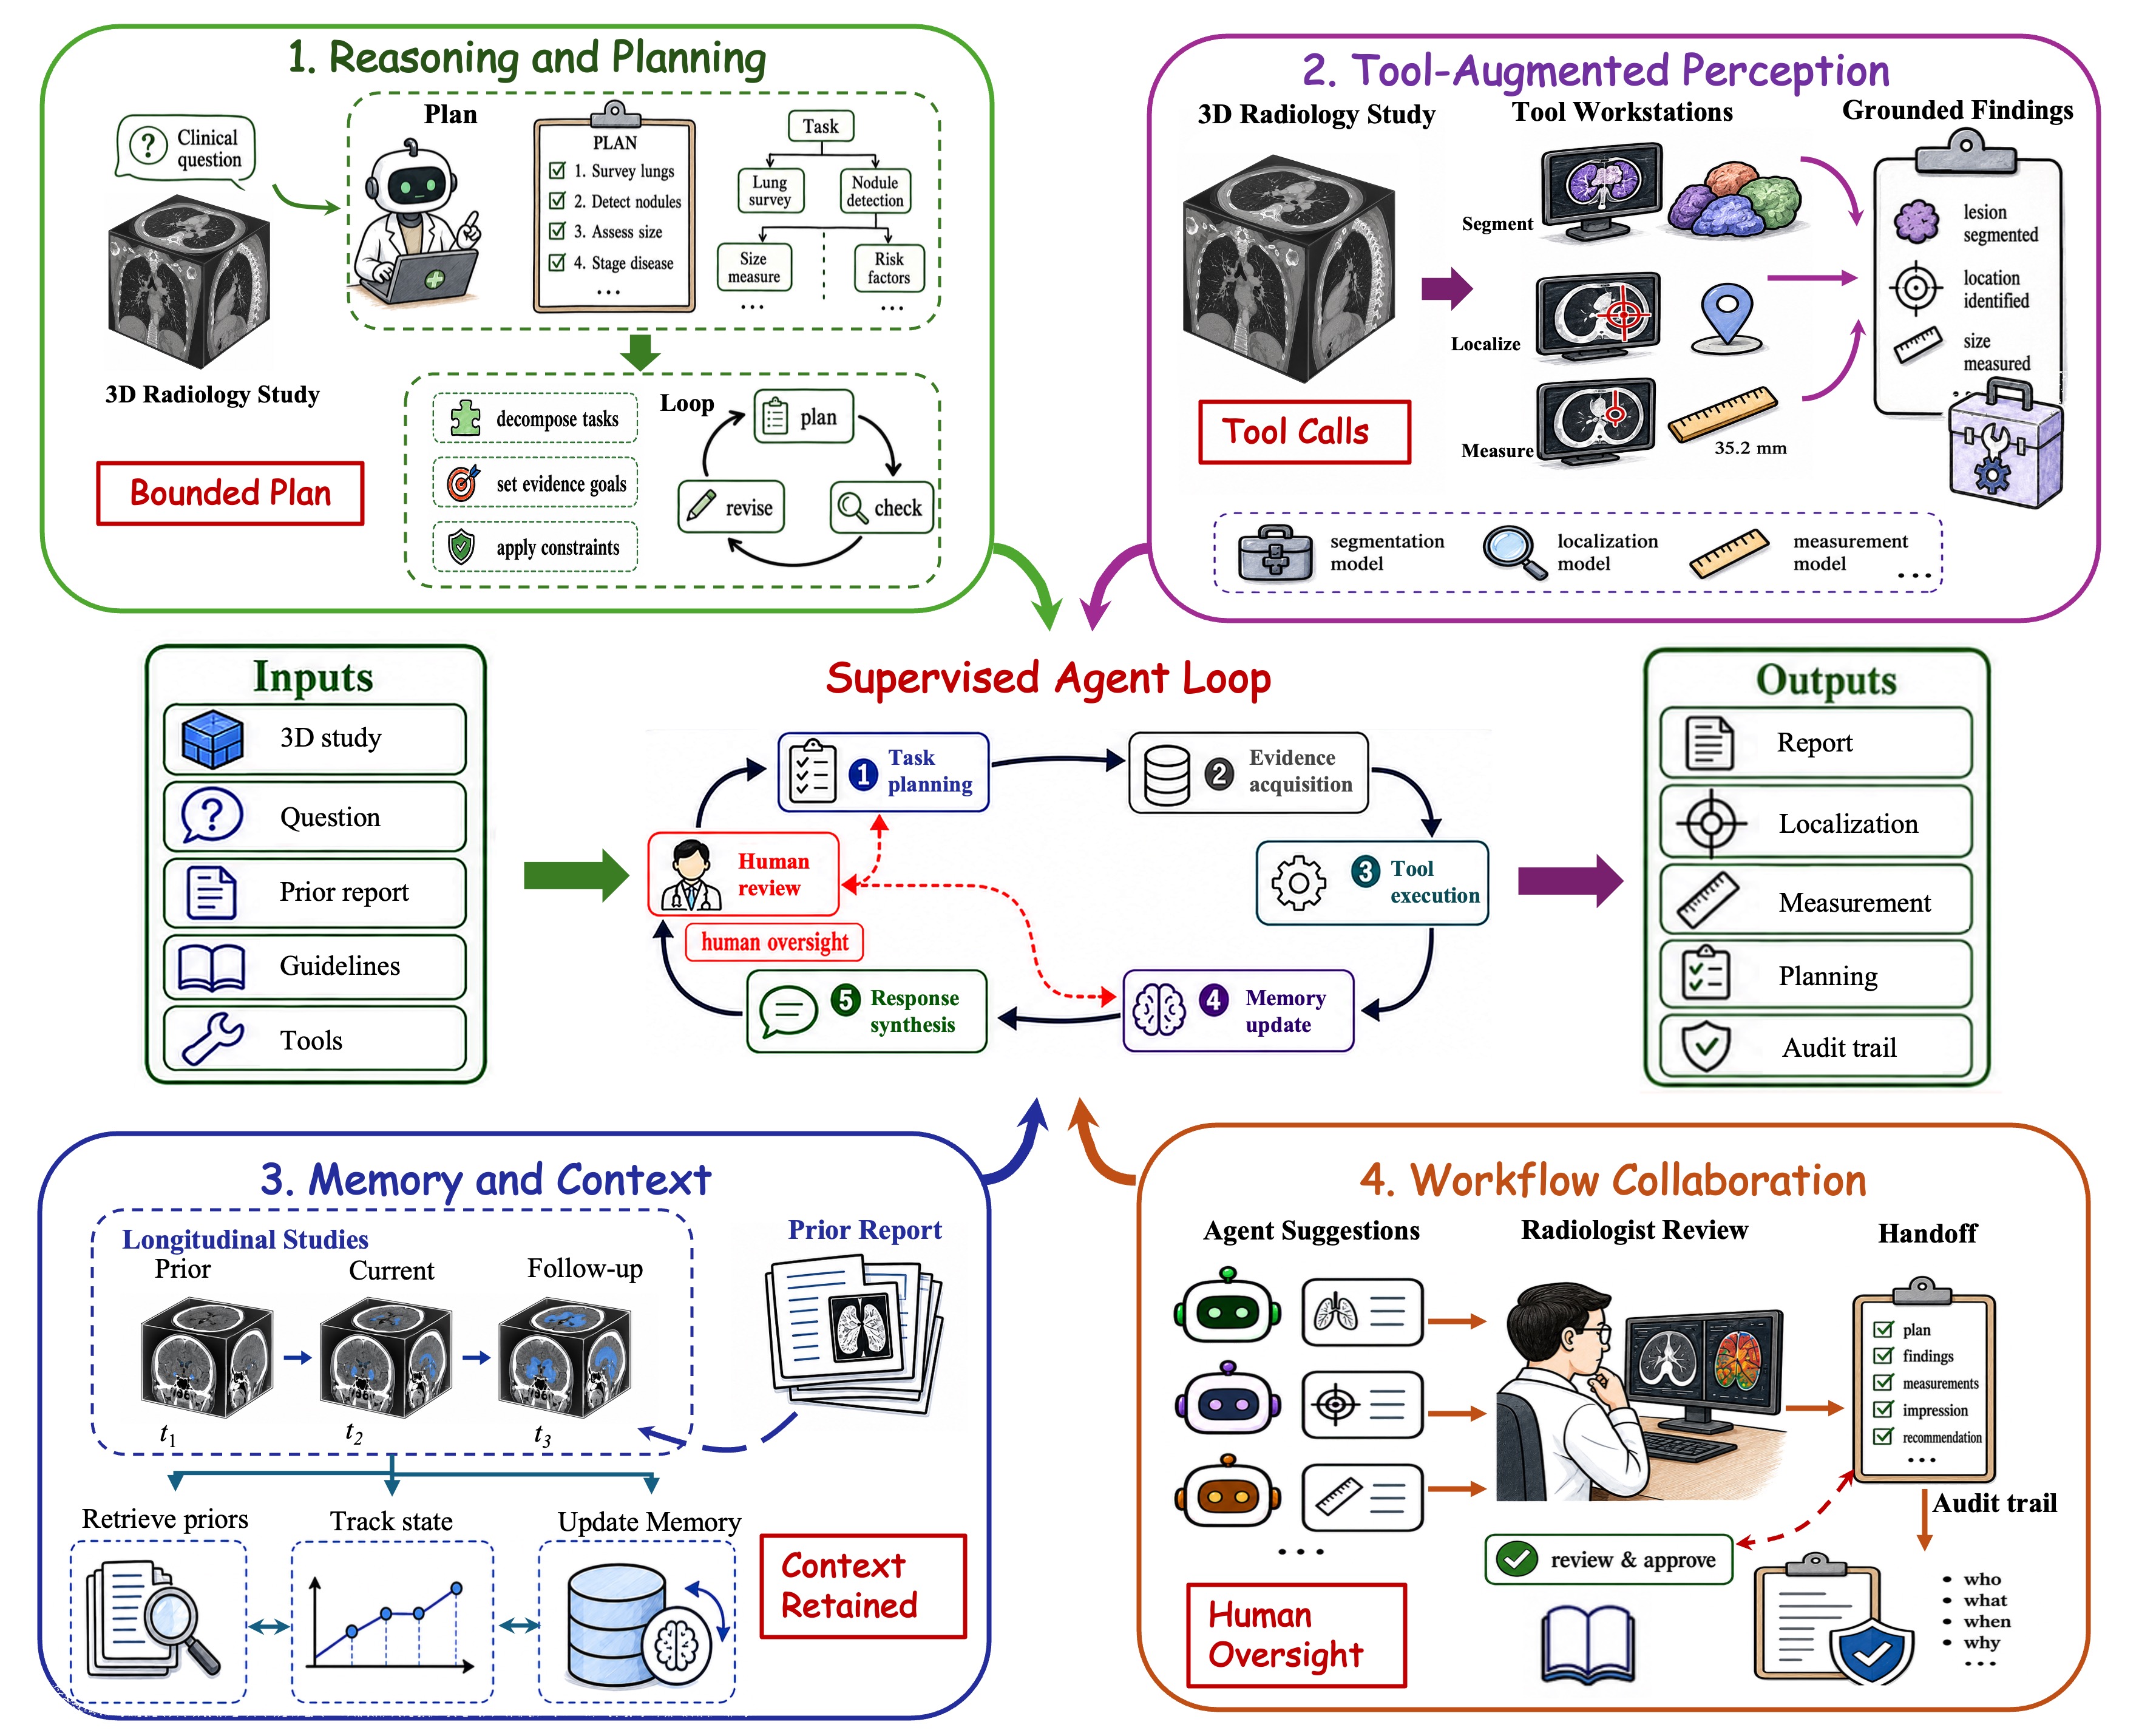
Core modules of agentic 3D radiology workflows: reasoning and planning, tool-augmented perception, memory and context, and workflow collaboration.
| Method | Title | Venue | Date | Paper | Project |
|---|---|---|---|---|---|
| MDAgents | MDAgents: An Adaptive Collaboration of LLMs for Medical Decision-Making | NeurIPS 2024 | 2024.12 (arXiv: 2024.04) | Paper | Project |
| MMedAgent | MMedAgent: Learning to Use Medical Tools with Multi-modal Agent | Findings of EMNLP 2024 | 2024.11 (arXiv: 2024.07) | Paper | Project |
| MedAgent-Pro | MedAgent-Pro: Towards Evidence-based Multi-modal Medical Diagnosis via Reasoning Agentic Workflow | ICLR 2026 | 2025.03 | Paper | Project |
| DOLA | Autonomous Radiotherapy Treatment Planning Using DOLA: A Privacy-Preserving, LLM-Based Optimization Agent | arXiv | 2025.03 | Paper | - |
| GPT-Plan | A Feasibility Study of Automating Radiotherapy Planning with Large Language Model Agents | Physics in Medicine and Biology | 2025.03 | Paper | - |
| VILA-M3 | VILA-M3: Enhancing Vision-Language Models with Medical Expert Knowledge | CVPR25 | 2024.11 | Paper | Project |
| CT-Agent | CT-Agent: A Multimodal-LLM Agent for 3D CT Radiology Question Answering | arXiv | 2025.05 | Paper | - |
| M^3Builder | M^3Builder: A Multi-Agent System for Automated Machine Learning in Medical Imaging | AI for Clinical Applications 2025 | 2025.05 | Paper | - |
| SAMIRA | Towards user-centered interactive medical image segmentation in VR with an assistive AI agent | arXiv | 2025.05 | Paper | - |
| MAM | MAM: Modular Multi-Agent Framework for Multi-Modal Medical Diagnosis via Role-Specialized Collaboration | Findings of ACL 2025 | 2025.07 (arXiv: 2025.06) | Paper | Project |
| AgentMRI | AgentMRI: A Vision Language Model-Powered AI System for Self-regulating MRI Reconstruction with Multiple Degradations | Journal of Imaging Informatics in Medicine | 2025.07 | Paper | - |
| CTPA-Agent | Vision-language model for report generation and outcome prediction in CT pulmonary angiogram | npj Digital Medicine | 2025.07 | Paper | Project |
| TissueLab | A co-evolving agentic AI system for medical imaging analysis | arXiv | 2025.09 | Paper | Project |
| Scan-do Attitude | Scan-do Attitude: Towards Autonomous CT Protocol Management Using a Large Language Model Agent | Agentic AI for Medicine / Springer | 2025.09 | Paper | - |
| VoxelPrompt | VoxelPrompt: A Vision Agent for End-to-End Medical Image Analysis | arXiv | 2025.10 | Paper | - |
| MedAgentSim | MedAgentSim: Self-Evolving Multi-Agent Simulations for Realistic Clinical Interactions | MICCAI 2025 | 2025.10 (arXiv: 2025.03) | Paper | Project |
| AURA | AURA: A Multi-Modal Medical Agent for Understanding, Reasoning & Annotation | MICCAI Workshop 2025 | 2025.10 (arXiv: 2025.07) | Paper | Project |
| MedEyes | MedEyes: Learning Dynamic Visual Focus for Medical Progressive Diagnosis | arXiv | 2025.11 | Paper | Project |
| MedSAM3 | MedSAM3: Delving into Segment Anything with Medical Concepts | arXiv | 2025.11 | Paper | Project |
| Radiologist Copilot | Radiologist Copilot: An Agentic Framework Orchestrating Specialized Tools for Reliable Radiology Reporting | arXiv | 2025.12 | Paper | - |
| INFORM-CT | INFORM-CT: INtegrating LLMs and VLMs FOR Incidental Findings Management in Abdominal CT | MIDL 2026 | 2025.12 | Paper | Project |
| IBISAgent | IBISAgent: Reinforcing Pixel-Level Visual Reasoning in MLLMs for Universal Biomedical Object Referring and Segmentation | arXiv | 2026.01 | Paper | - |
| MedVistaGym | MEDVISTAGYM: A Scalable Training Environment for Thinking with Medical Images via Tool-Integrated Reinforcement Learning | arXiv | 2026.01 | Paper | - |
| An Explainable Agentic AI Framework for Uncertainty-Aware and Abstention-Enabled Acute Ischemic Stroke Imaging Decisions | arXiv | 2026.01 | Paper | - | |
| LungNoduleAgent | LungNoduleAgent: A Collaborative Multi-Agent System for Precision Diagnosis of Lung Nodules | AAAI 2026 | 2026.02 (arXiv: 2025.11) | Paper | Project |
| 3DMedAgent | 3DMedAgent: Unified Perception-to-Understanding for 3D Medical Analysis | arXiv | 2026.02 | Paper | Project |
| MedSAM-Agent | MedSAM-Agent: Empowering Interactive Medical Image Segmentation with Multi-turn Agentic Reinforcement Learning | arXiv | 2026.02 | Paper | Project |
| CARE | CARE: Towards Clinical Accountability in Multi-Modal Medical Reasoning with an Evidence-Grounded Agentic Framework | ICLR 2026 | 2026.05 (arXiv: 2026.03) | Paper | Project |
| ToolSelect | Picking the Right Specialist: Attentive Neural Process-based Selection of Task-Specialized Models as Tools for Agentic Healthcare Systems | arXiv | 2026.02 | Paper | - |
| CoMMa | CoMMa: Contribution-Aware Medical Multi-Agents From A Game-Theoretic Perspective | arXiv | 2026.02 | Paper | - |
| MedSegAgent | MedSegAgent: A Universal and Scalable Multi-Agent System for Instructive Medical Image Segmentation | IEEE JBHI | 2026.03 | Paper | Project |
| CT-Flow | CT-Flow: Orchestrating CT Interpretation Workflow with Model Context Protocol Servers | arXiv | 2026.03 | Paper | - |
| Agent-MIRA | Agent-MIRA: AI-orchestrated Medical Imaging Agent for PET Image Retrieval and Assistance | Computerized Medical Imaging and Graphics | 2026.03 | Paper | - |
| Meissa | Meissa: Multi-modal Medical Agentic Intelligence | arXiv | 2026.03 | Paper | Project |
| BT-RADS Agent | Agentic Automation of BT-RADS Scoring: End-to-End Multi-Agent System for Standardized Brain Tumor Follow-up Assessment | arXiv | 2026.03 | Paper | - |
| TheraAgent | TheraAgent: Multi-Agent Framework with Self-Evolving Memory and Evidence-Calibrated Reasoning for PET Theranostics | arXiv | 2026.03 | Paper | - |
| MedOpenClaw | MEDOPENCLAW: Auditable Medical Imaging Agents Reasoning over Uncurated Full Studies | arXiv | 2026.03 | Paper | - |
| MedMASLab | MedMASLab: A Unified Orchestration Framework for Benchmarking Multimodal Medical Multi-Agent Systems | arXiv | 2026.03 | Paper | Project |
| ClinicalAgents | ClinicalAgents: Multi-Agent Orchestration for Clinical Decision Making with Dual-Memory | arXiv | 2026.03 | Paper | - |
| Doctorina MedBench | Doctorina MedBench: End-to-End Evaluation of Agent-Based Medical AI | arXiv | 2026.03 | Paper | - |
| SEER | Skill-Evolving Grounded Reasoning for Free-Text Promptable 3D Medical Image Segmentation | arXiv | 2026.03 | Paper | |
| RadAgent | RadAgent: A Tool-Using AI Agent for Stepwise Interpretation of Chest Computed Tomography | arXiv | 2026.04 | Paper | Project |
| BAAI Cardiac Agent | BAAI Cardiac Agent: An intelligent multimodal agent for automated reasoning and diagnosis of cardiovascular diseases from cardiac magnetic resonance imaging | arXiv | 2026.04 | Paper | Project |
| DosimeTron | DosimeTron: Automating Personalized Monte Carlo Radiation Dosimetry in PET/CT with Agentic AI | arXiv | 2026.04 | Paper | - |
| MARCH | MARCH: Multi-Agent Radiology Clinical Hierarchy for CT Report Generation | ACL 2026 | 2026.04 | Paper | - |
| Neuro-Radiological Agent | Agentic Large Language Models for Training-Free Neuro-Radiological Image Analysis | arXiv | 2026.04 | Paper | - |
| Agent4MR | Agentic MR sequence development: leveraging LLMs with MR skills for automatic physics-informed sequence development | arXiv | 2026.04 | Paper | - |
| Artifact-based Agent Framework | An Artifact-based Agent Framework for Adaptive and Reproducible Medical Image Processing | arXiv | 2026.04 | Paper | - |
| NeuroClaw | NeuroClaw: Closed-Loop Agentic AI for Executable and Reproducible Neuroimaging Research | arXiv | 2026.04 | Paper | - |
| Neuro-Oracle | Neuro-Oracle: A Trajectory-Aware Agentic RAG Framework for Interpretable Epilepsy Surgical Prognosis | arXiv | 2026.04 | Paper | - |
| MedScribe | MedScribe: Clinically Grounded CT Reporting through Agentic Workflows | arXiv | 2026.05 | Paper | - |
| GAZE | GAZE: Grounded Agentic Zero-shot Evaluation with Viewer-Level Tools and Literature Retrieval on Rare Brain MRI | arXiv | 2026.05 | Paper | - |
| NeuroAgent | NeuroAgent: LLM Agents for Multimodal Neuroimaging Analysis and Research | arXiv | 2026.05 | Paper | - |
| NEXUS | Towards a Virtual Neuroscientist: Autonomous Neuroimaging Analysis via Multi-Agent Collaboration | arXiv | 2026.05 | Paper | Project |
| M2M-LLM-RT | A Machine-to-Machine Knowledge-Guided LLM Agent for Generalizable Radiotherapy Treatment Planning | arXiv | 2026.05 | Paper | - |
| SpineAgent | A Multi-Agent System for Spine MRI Report Generation from Multi-Sequence Imaging | arXiv | 2026.06 | Paper | - |
| MedToolica | MedToolica: Finetuning-Free Agentic Compositional Tool Learning for 3D CT Reasoning | Machine Learning and Knowledge Extraction | 2026.06 | Paper | Project |
| MARTP | MARTP: A Multi-Agent Simulation Framework for Automated Radiation Therapy Planning Based on LLMs | Physics in Medicine and Biology | 2026.06 | Paper | - |
| SAGE | Automated Stereotactic Radiosurgery Planning Using a Human-in-the-Loop Reasoning Large Language Model Agent | Research Square | 2026.06 | Paper | - |
| PET/CT Agent | End-to-End PET/CT Interpretation and Quantification with an LLM-Orchestrated AI Agent: A Real-World Pilot Study | Journal of Nuclear Medicine | 2026.06 | Paper | - |
| PD-CTAgent | Policy-Driven CT-Agent: Modeling Phase-Aware Diagnostic Control for Clinically Consistent CT Reasoning | arXiv | 2026.07 | Paper | - |
| MonteRET | MonteRET: AI Agent Enhancing Multimodal LLMs with Multi-granularity Knowledge Retrieval for Chest CT Report Generation | arXiv | 2026.07 | Paper | - |
| One-for-All | One-for-All Adaptive Radiotherapy Planning Agent: A Foundation Framework for Daily CBCT-guided Radiotherapy | arXiv | 2026.07 | Paper | - |
Datasets & Benchmarks
| Dataset | Title | Date | Venue | Paper Link | Project |
|---|---|---|---|---|---|
| SLIVER07 | Segmentation in the liver 2007 (SLIVER07) challenge | 2007.09 | MICCAI Workshop | Paper | Project |
| SKI10 | Segmentation of Knee Images 2010 (SKI10) | 2010.09 | MICCAI Challenge | Paper | Project |
| LIDC-IDRI | Data From LIDC-IDRI: The Lung Image Database Consortium and Image Database Resource Initiative | 2011.06 | Med Phys | Paper | Project |
| LOLA11 | LOLA11: LObe and Lung Analysis 2011 Challenge | 2011.09 | MICCAI Workshop | Project | |
| STACOM 2011 Motion Tracking | STACOM 2011: Cardiac Motion Tracking Challenge | 2011.09 | MICCAI Workshop | Paper | Project |
| Mindboggle-101 | Mindboggle-101: Evaluating Brain Image Labeling Methods | 2012.09 | NeuroImage | Paper | Project |
| PROMISE12 | PROMISE12: Prostate MR Image Segmentation 2012 Challenge | 2012.10 | MICCAI Challenge | Paper | Project |
| NLST | The National Lung Screening Trial: overview and study design | 2013.01 | Radiology | Project | |
| Farsiu Ophthalmology 2013 | Quantitative Classification of Eyes with and without Intermediate Age-related Macular Degeneration Using Optical Coherence Tomography | 2013.03 | Ophthalmology | Paper | Project |
| Prostate-3T | Data From Prostate-3T | 2013.06 | TCIA Collection | Project | |
| MRBrainS13 | MRBrainS13: Grand Challenge on MR Brain Image Segmentation | 2013.09 | MICCAI Challenge | Project | |
| Chiu BOE 2014 | Kernel regression based segmentation of optical coherence tomography images with diabetic macular edema | 2014.01 | Biomed Opt Express | Paper | Project |
| Srinivasan BOE 2014 | Fully automated detection of diabetic macular edema and dry age-related macular degeneration from optical coherence tomography images | 2014.03 | Biomed Opt Express | Paper | Project |
| orCaScore | An evaluation of automatic coronary artery calcium scoring methods with cardiac CT using the orCaScore framework | 2014.09 | MICCAI Challenge | Paper | Project |
| CETUS2014 | CETUS: Cardiac Echocardiography Tracking and Segmentation Challenge | 2014.09 | MICCAI Challenge | Project | |
| Prostate-Diagnosis | PROSTATE-DIAGNOSIS: Multiparametric MRI for Prostate Cancer | 2015.03 | TCIA Collection | Project | |
| BTCV | MICCAI multi-atlas labeling beyond the cranial vault-workshop and challenge | 2015.04 | MICCAI Workshop | Project | |
| ISMRM2015 HARDI | ISMRM 2015 Tractography Challenge | 2015.06 | ISMRM Challenge | Project | |
| NEATBrainS15 | NEATBrainS15: Neonatal Brain Structure Segmentation | 2015.09 | MICCAI Challenge | Project | |
| PDDCA | Public Domain Database for Computational Anatomy: Head and Neck | 2015.09 | MICCAI Challenge | Project | |
| HVSMR 2016 | HVSMR 2016: Whole Heart and Great Vessel Segmentation Challenge | 2016.07 | MICCAI Challenge | Paper | Project |
| MSSEG 2016 | Objective Evaluation of Multiple Sclerosis Lesion Segmentation using a Data Management and Processing Infrastructure | 2016.10 | MICCAI Challenge/Nature | Paper | Project |
| PROSTATEx | PROSTATEx: PROSTATE MR Image Dataset With Prostate Cancer Annotations | 2016.10 | SPIE-AAPM-NCI PROSTATEx Challenge | Project | |
| WMH | WMH Segmentation Challenge: White Matter Hyperintensity Segmentation in Brain MR | 2017.03 | MICCAI Challenge | Paper | Project |
| LGG-1p19qDeletion | LGG-1p19qDeletion: Low-Grade Glioma MRI with Genomic Annotations | 2017.03 | TCIA Collection | Project | |
| PROSTATEx-2 | PROSTATEx-2: Lesion Classification Challenge | 2017.06 | AAPM Grand Challenge | Project | |
| ACDC | Automatic Cardiac Diagnosis Challenge | 2017.09 | STACOM / MICCAI | Paper | Project |
| RETOUCH | RETOUCH: Retinal OCT Fluid Segmentation Challenge | 2017.09 | MICCAI Challenge | Paper | Project |
| ROCC | ROCC: Retinal OCT Classification Challenge | 2017.09 | MICCAI Challenge | Project | |
| iSeg2017 | iSeg-2017: Infant Brain MRI Segmentation Challenge | 2017.09 | MICCAI Challenge | Paper | Project |
| DeepLesion | DeepLesion: automated mining of large-scale lesion annotations and universal lesion detection in CT | 2017.10 | JMI / arXiv | Paper | Project |
| LUNA 16 | Validation, comparison, and combination of algorithms for automatic detection of pulmonary nodules in computed tomography images: the LUNA 16 challenge | 2017.12 | Medical Image Analysis | Paper | Project |
| Mandibular-CT-Dataset | Mandibular CT Dataset Collection for 3D Reconstruction and Segmentation | 2018.03 | figshare | Paper | Project |
| FUMPE | Computer-aided detection of pulmonary embolism in CT | 2018.03 | arXiv / Kaggle | Project | |
| ISLES 2018 | ISLES 2018 – Ischemic Stroke Lesion Segmentation | 2018.09 | MICCAI Challenge | Paper | Project |
| MRBrainS18 | MRBrainS18: MR Brain Segmentation Challenge 2018 | 2018.09 | MICCAI Challenge | Project | |
| Atrial Segmentation Challenge | 2018 Atrial Segmentation Challenge | 2018.09 | MICCAI Challenge | Project | |
| IVDM3Seg | IVDM3Seg: Intervertebral Disc and Vertebrae Segmentation Challenge | 2018.09 | MICCAI Challenge | Project | |
| MRNet | MRNet: Knee MRI Dataset for Abnormality Detection | 2018.09 | NIPS Workshop | Project | |
| OCT Glaucoma Detection | Glaucoma Detection in 3D Spectral-Domain OCT | 2018.10 | Sci Rep | Project | |
| BraTS | Brain Tumor Segmentation (BraTS) Challenge | 2018.11 | MICCAI Challenge (series) | Paper | Project |
| fastMRI | fastMRI: A Publicly Available Raw k-Space and DICOM Dataset of Knee and Brain MR Images | 2018.11 | MRM | Paper | Project |
| LiTS | Liver Tumor Segmentation (LiTS) Challenge | 2019.01 | MICCAI Challenge | Paper | Project |
| OASIS-3 | OASIS-3: Longitudinal Neuroimaging, Clinical, and Cognitive Dataset for Normal Aging and Alzheimer Disease | 2019.01 | Sci Data | Paper | Project |
| MM-WHS | MM-WHS: Multi-Modality Whole Heart Segmentation | 2019.02 | MICCAI Challenge | Paper | Project |
| CHAOS CT-MRI | CHAOS - Combined (CT-MR) Healthy Abdominal Organ Segmentation | 2019.02 | ISBI Challenge | Paper | Project |
| KiTS19 | KiTS19: Kidney Tumor Segmentation Challenge | 2019.04 | MICCAI Challenge | Paper | Project |
| AAPM-RT-MAC | AAPM RT-MAC: MR-only based Radiotherapy in Head and Neck | 2019.07 | AAPM Challenge | Paper | Project |
| iSeg-2019 | iSeg-2019: Infant Brain MRI Segmentation Challenge | 2019.09 | MICCAI Challenge | Paper | Project |
| SegTHOR | SegTHOR: Segmentation of thoracic organs at risk in CT images | 2019.09 | Physica Medica | Paper | Project |
| VerSe20 | VerSe 2020: Vertebral Segmentation Challenge at MICCAI | 2020.01 | MICCAI Challenge | Project | |
| VerSe19 | VerSe 2019: Vertebral Segmentation Challenge at MICCAI | 2020.01 | MICCAI Challenge | Paper | Project |
| COVID-19-CT-Seg | COVID-19 CT lung and infection segmentation dataset | 2020.04 | zenodo | Project | |
| M&Ms | M&Ms: Multi-Centre, Multi-Vendor & Multi-Disease Cardiac MR Segmentation Challenge | 2020.05 | MICCAI Challenge | Project | |
| CTPelvic1K | CTPelvic1K: A Large-Scale Pelvic CT Dataset for Multi-Task Parsing | 2020.06 | arXiv | Paper | Project |
| Prostate MR Segmentation Dataset (SAML) | Federated Domain Generalization on Medical Image Segmentation via Episodic Learning in Continuous Frequency Space | 2020.09 | MICCAI | Project | |
| EMIDEC | EMIDEC 2020: Myocardial Infarction Detection, Segmentation and Classification | 2020.09 | MICCAI Challenge | Paper | Project |
| KNOAP2020 | KNOAP2020: Knee Osteoarthritis Progression Prediction Challenge | 2020.09 | MICCAI Challenge | Project | |
| Learn2Reg Lung CT | Learn2Reg 2020: Lung CT Registration | 2020.09 | MICCAI Challenge | Project | |
| Learn2Reg Abdomen CT-CT | Learn2Reg 2020: Abdominal CT-CT Registration | 2020.09 | MICCAI Challenge | Project | |
| RibFrac2020 | RibFrac: Rib Fracture Detection and Classification Challenge | 2020.10 | MICCAI Challenge | Project | |
| HECKTOR 2020 | HECKTOR 2020: Segmentation of Head and Neck Tumor in PET/CT | 2020.11 | MICCAI Challenge | Project | |
| CT-ORG | CT-ORG, a new dataset for multiple organ segmentation in computed tomography | 2020.11 | Nature | Paper | Project |
| RAD-ChestCT | Machine-Learning-Based Multiple Abnormality Prediction with Large-Scale Chest Computed Tomography Volumes | 2021.01 | Medical Image Analysis | Paper | Project |
| Eye OCT Datasets (3D) | 3D Retinal OCT Classification and Segmentation Dataset | 2021.01 | Tianchi | Project | |
| HECKTOR 2021 | HECKTOR 2021: Head and Neck Tumor Segmentation and Outcome Prediction | 2021.05 | MICCAI Challenge | Project | |
| CTSpine1K | CTSpine1K: A Large-Scale Dataset for Spine Parsing in CT | 2021.07 | arXiv | Project | |
| MSSEG-2 | MSSEG-2 challenge: Multiple Sclerosis Lesion Segmentation at 7T and 3T MRI | 2021.07 | NeuroImage Clin | Project | |
| FLARE21 | FLARE 2021: A Challenge on Abdominal Multi-organ Segmentation | 2021.09 | MICCAI Challenge | Project | |
| QUBIQ2021 3D CT | QUBIQ 2021: Quantification of Uncertainty in Biomedical Image Quantification | 2021.09 | MICCAI Challenge | Project | |
| M&Ms-2 | M&Ms-2: Multi-Domain Cardiac MR Segmentation | 2021.09 | MICCAI Challenge | Project | |
| Learn2Reg Abdomen MR-CT | Learn2Reg 2021: Abdominal MR-CT Multi-Modal Registration | 2021.09 | MICCAI Challenge | Project | |
| CrossMoDA2021 | CrossMoDA 2021: Unsupervised Domain Adaptation for Cross-Modality Vestibular Schwannoma Segmentation | 2021.09 | MICCAI Challenge | Project | |
| WORD | WORD: A Whole-Organ CT Dataset for Robust Multi-Organ Segmentation | 2021.10 | arXiv | Paper | Project |
| MedMNIST v2 | MedMNIST v2 -- A large-scale lightweight benchmark for 2D and 3D biomedical image classification | 2021.10 | Nature | Paper | Project |
| CADA | CADA: Cerebral Aneurysm Detection and Analysis Challenge | 2022.04 | MICCAI Challenge | Project | |
| CADA-AS | CADA-AS: Aneurysm Segmentation Challenge | 2022.04 | MICCAI Challenge | Project | |
| CADA-RRE | CADA-RRE: Rupture Risk Estimation for Cerebral Aneurysms | 2022.04 | MICCAI Challenge | Project | |
| TotalSegmentator | TotalSegmentator: robust segmentation of 104 anatomic structures in CT images | 2022.06 | arXiv | Paper | Project |
| AMOS | AMOS: A Large-Scale Abdominal Multi-Organ Benchmark for Versatile Medical Image Segmentation | 2022.06 | NeurIPS 2022 | Paper | Project |
| MSD | The medical segmentation decathlon | 2022.07 | Nature Communications | Paper | Project |
| AutoPET | The AutoPET Challenge: Automated Lesion Segmentation in Whole-Body FDG-PET/CT | 2022.07 | MICCAI Challenge (autoPET2022) | Project | |
| UPENN-GBM | UPENN-GBM: Multi-modal MRI Dataset for Glioblastoma Segmentation | 2022.07 | TCIA Collection | Project | |
| KiPA22 | KiPA22: Kidney PArametric segmentation in contrast-enhanced CT | 2022.08 | MICCAI Challenge | Project | |
| OLIVES | OLIVES: A 3D OCT Dataset for Longitudinal Retinal Imaging | 2022.09 | arXiv | Project | |
| PI-CAI | PI-CAI: Prostate Imaging–Cancer AI Challenge | 2022.09 | MICCAI Challenge | Project | |
| LAScarQS 2022 | LAScarQS 2022: Left Atrial Scar Quantification and Segmentation Challenge | 2022.09 | MICCAI Challenge | Project | |
| CrossMoDA2022 | CrossMoDA 2022: Domain Adaptation for Vestibular Schwannoma Segmentation and Koos Grading | 2022.09 | MICCAI Challenge | Project | |
| FeTA 2022 | FeTA 2022: Fetal Brain Tissue Segmentation at MICCAI | 2022.09 | MICCAI Challenge | Project | |
| COSMOS 2022 | COSMOS 2022: Carotid Artery Vessel Wall Segmentation | 2022.09 | MICCAI Challenge | Project | |
| cSeg-2022 | cSeg 2022: Cerebellum Segmentation Challenge | 2022.09 | MICCAI Challenge | Project | |
| ISLES 2022 | ISLES 2022 – Acute and Subacute Ischemic Stroke Lesion Segmentation | 2022.09 | MICCAI Challenge | Project | |
| InSTANCE2022 | InSTANCE 2022: Intracranial Hemorrhage Segmentation Challenge | 2022.09 | MICCAI Challenge | Paper | Project |
| Learn2Reg NLST | Learn2Reg 2022: Thoracic CT Registration with NLST | 2022.09 | MICCAI Challenge | Project | |
| Shifts Challenge 2022 | Shifts 2022: Distribution Shifts in Multiple Sclerosis Lesion Segmentation | 2022.09 | MICCAI Challenge | Paper | Project |
| HECKTOR 22 | Overview of the HECKTOR challenge at MICCAI 2022: automatic head and neck tumor segmentation and outcome prediction in PET/CT | 2023 | MICCAI 2022 | Paper | Project |
| LNDb | LNDb challenge on automatic lung cancer patient management | 2023.03 | Medical Image Analysis | Paper | Project |
| Semi-TeethSeg | Semi-TeethSeg: Semi-Supervised 3D Tooth Segmentation in CBCT/CT | 2023.04 | arXiv | Project | |
| PARSE22 | Efficient automatic segmentation for multi-level pulmonary arteries: The parse challenge | 2023.04 | arXiv | Paper | Project |
| STAGE | STAGE: Longitudinal OCT Dataset for Glaucoma Progression | 2023.04 | Dataset | Project | |
| KiTS21 | The kits21 challenge: Automatic segmentation of kidneys, renal tumors, and renal cysts in corticomedullary-phase ct | 2023.07 | arXiv | Paper | Project |
| AutoPET II | AutoPET-II: Ensemble-based Uncertainty-Aware Lesion Segmentation in Multi-Center FDG-PET/CT | 2023.07 | MICCAI Challenge (AutoPET-II) | Project | |
| MedMD | Towards Generalist Foundation Model for Radiology by Leveraging Web-scale 2D&3D Medical Data | 2023.08 | arXiv | Paper | Project |
| ULS23 | ULS23 Challenge: Universal Lesion Segmentation in CT for Oncological Imaging | 2023.08 | MICCAI Challenge | Project | |
| SegRap2023 | SegRap 2023: Nasopharyngeal Carcinoma Radiotherapy Segmentation Challenge | 2023.08 | MICCAI Challenge | Project | |
| LNQ2023 | LNQ2023: Lymph Node Quantification in Chest CT | 2023.08 | MICCAI Challenge | Project | |
| FLARE23 | FLARE 2023: A Federated Learning Challenge for Abdominal Multi-Organ Segmentation | 2023.09 | MICCAI Challenge | Project | |
| CrossMoDA2023 | CrossMoDA 2023: Multi-Center Domain Adaptation for VS Segmentation | 2023.09 | MICCAI Challenge | Project | |
| ATLAS2023 | ATLAS 2023: Liver Tumor Segmentation Challenge | 2023.09 | MICCAI Challenge | Paper | Project |
| SMILE-UHURA2023 | SMILE-UHURA 2023: Small Vessel Disease Lesion Segmentation | 2023.09 | MICCAI Challenge | Paper | Project |
| CAS2023 | CAS 2023: Brain Structure Segmentation Benchmark | 2023.09 | MICCAI Challenge | Project | |
| CROWN2023 | CROWN 2023: White Matter Hyperintensity and Other Pathology Classification | 2023.09 | MICCAI Challenge | Project | |
| SLCN | SLCN: Structural Lesion and Connectivity in Neurodevelopmental Disorders | 2023.09 | MICCAI Challenge | Project | |
| ToothFairy2023 | ToothFairy: 3D CBCT Dataset for Inferior Alveolar Nerve Segmentation | 2023.09 | MICCAI Challenge | Project | |
| XPRESS2023 | XPRESS 2023: X-ray Phase-Contrast CT Neuroanatomy Segmentation | 2023.09 | MICCAI Challenge | Paper | Project |
| Learn2Reg ThoraxCBCT | Learn2Reg 2023: Thorax CBCT/FBCT Deformable Registration | 2023.09 | MICCAI Challenge | Project | |
| TDSC-ABUS2023 | TDSC-ABUS2023: Automated Breast Ultrasound Segmentation Challenge | 2023.09 | MICCAI Challenge | Paper | Project |
| MVSeg-3DTEE2023 | MVSeg-3DTEE2023: Mitral Valve Segmentation from 3D TEE | 2023.09 | MICCAI Challenge | Project | |
| RegPro2023 | RegPro 2023: Prostate MR-US Registration Challenge | 2023.09 | MICCAI Challenge | Project | |
| KiTS23 | KiTS23: Kidney and Kidney Tumor Segmentation with Comprehensive Clinical Annotations | 2023.10 | arXiv | Project | |
| WBMR-NF | WBMR-NF: Whole-Body MRI for Neurofibromatosis | 2023.11 | Dataset | Project | |
| GAMMA | GAMMA Challenge: Glaucoma Assessment with Multi-Modality Data | 2023.12 | MICCAI Challenge | Paper | Project |
| ATM'22 | ATM'22: Airway Tree Modeling in Thoracic CT | 2023.12 | MICCAI Challenge | Paper | Project |
| INSPECT | INSPECT: A Multimodal Dataset for Pulmonary Embolism Diagnosis and Prognosis | 2023.12 | NeurIPS 2023 | Paper | Project |
| HaN-Seg | HaN-Seg 2023: Head and Neck Organ at Risk Segmentation Challenge | 2024 | MICCAI Challenge | Paper | Project |
| VALDO | Where is VALDO? Vascular Lesions Detection and Segmentation Challenge | 2024.01 | MICCAI Challenge | Paper | Project |
| BIMCV-R | BIMCV-R: Large-Scale Thoracic CT Reconstruction Benchmark | 2024.01 | MICCAI24 | Paper | Project |
| IXI | Information eXtraction from Images (IXI) Dataset | 2024.01 | Dataset | Project | |
| RAOS | RAOS: A Large-Scale Radiotherapy Abdominal Organ Segmentation Dataset | 2024.01 | MICCAI24 | Paper | Project |
| ISLES 2024 | Ischemic Stroke Lesion Segmentation Challenge 2024 (ISLES 2024) | 2024.02 | MICCAI Challenge | Project | |
| AbdomenAtlas | AbdomenAtlas-20K: A Large-Scale Benchmark for Abdominal Multi-Organ Segmentation in CT | 2024.02 | arXiv | Paper | Project |
| OpenMind | OpenMind: Large-Scale Head-and-Neck MR Dataset for Foundation Models | 2024.02 | arXiv | Project | |
| TriALS2024 | TriALS 2024: Liver Tumor Segmentation and Outcome Prediction – Task 1 | 2024.03 | MICCAI24 | Project | |
| LAScarQS++ 2024 | LAScarQS++ 2024: Multi-Center Atrial Scar Segmentation | 2024.03 | CARE Workshop (MICCAI) | Project | |
| MyoPS | MyoPS: A Benchmark of Myocardial Pathology Segmentation Combining Three-Sequence Cardiac Magnetic Resonance Images# MyoPS: A Benchmark of Myocardial Pathology Segmentation Combining Three-Sequence Cardiac Magnetic Resonance Images | 2024.03 | CARE Workshop | Paper | Project |
| WHS++ 2024 | WHS++ 2024: Multi-Center Whole Heart Segmentation | 2024.03 | CARE Workshop | Project | |
| AMOS-MM | AMOS-MM: Multi-Phase Abdominal CT Benchmark for Translation and Synthesis | 2024.03 | arXiv | Paper | Project |
| CT2Rep | CT2Rep: Automated Radiology Report Generation for 3D Medical Imaging | 2024.03 | MICCAI 2024 | Paper | Project |
| TotalSegmentator MRI | TotalSegmentator MRI: Whole-body MRI Segmentation of 150 Structures | 2024.04 | arXiv | Paper | Project |
| RadGenome-ChestCT | RadGenome-Chest CT: a grounded vision-language dataset for chest CT analysis | 2024.04 | arXiv | Paper | Project |
| M3D | M3D: Advancing 3D Medical Image Analysis with Multi-Modal Large Language Models | 2024.04 | ICLR 2025 | Paper | Project |
| AIIB23 | AIIB23: Airway Inflammation Imaging Biomarkers Challenge | 2024.06 | MICCAI Challenge | Paper | Project |
| CT-3DRRG | Argus: Benchmarking and Enhancing Vision-Language Models for 3D Radiology Report Generation | 2024.06 | arXiv | Paper | — |
| RadGenome-Brain MRI | AutoRG-Brain: Grounded Report Generation for Brain MRI | 2024.10 | MICCAI 2024 | Paper | Project |
| MedShapeNet | MedShapeNet -- A Large-Scale Dataset of 3D Medical Shapes for Computer Vision | 2024.12 | Biomedizinische Technik | Paper | Project |
| RadA-BenchPlat | How well can modern LLMs act as agent cores in radiology environments? | 2024.12 | arXiv | Paper | |
| MedVL-CT69K | Large-scale and Fine-grained Vision-language Pre-training for Enhanced CT Image Understanding | 2025.01 | ICLR 2025 | Paper | Project |
| Triad | Triad: Vision Foundation Model for 3D Magnetic Resonance Imaging | 2025.02 | arXiv | Paper | |
| 3D-BrainCT | Towards a holistic framework for multimodal LLM in 3D brain CT radiology report generation | 2025.03 | Nat. Commun. | Paper | — |
| PENGWIN2024-Task1 | PENGWIN 2024: Pelvic Fracture Segmentation in Trauma CT | 2025.04 | MICCAI Challenge | Paper | Project |
| RibFrac | Deep rib fracture instance segmentation and classification from ct on the ribfrac challenge | 2025.04 | IEEE | Paper | Project |
| DeepTumorVQA | Are Vision Language Models Ready for Clinical Diagnosis? A 3D Medical Benchmark for Tumor-centric Visual Question Answering | 2025.05 | NeurIPS 2025 | Paper | Project |
| NOVA | NOVA: A Benchmark for Anomaly Localization and Clinical Reasoning in Brain MRI | 2025.05 | NeurIPS 2025 | Paper | |
| Lingshu | Lingshu: A Generalist Foundation Model for Unified Multimodal Medical Understanding and Reasoning | 2025.06 | arXiv | Paper | Project |
| ReXGroundingCT | ReXGroundingCT: A 3D Chest CT Dataset for Segmentation of Findings from Free-Text Reports | 2025.07 | arXiv | Paper | Project |
| ViPET-ReportGen | Toward a Vision-Language Foundation Model for Medical Data: Multimodal Dataset and Benchmarks for Vietnamese PET/CT Report Generation | 2025.12 | NeurIPS 2025 | Paper | Project |
| 3D-RAD | 3D-RAD: A Comprehensive 3D Radiology Med-VQA Dataset with Multi-Temporal Analysis and Diverse Diagnostic Tasks | 2025.12 | NeurIPS 2025 | Paper | Project |
| MR-RATE | MR-RATE: A Vision-Language Foundation Model and Dataset for Magnetic Resonance Imaging | 2026 | — | — | Project |
| CT-RATE | Generalist Foundation Models from a Multimodal Dataset for 3D Computed Tomography | 2026.02 | Nature | Paper | Project |
| CT-FlowBench | CT-FlowBench: Benchmark for CT interpretation workflow and tool-use | 2026.03 | arXiv | Paper | |
| Merlin | Merlin: A Vision Language Foundation Model for 3D Computed Tomography | 2026.03 | Nature | Paper | Project |
| Gastric-X | Gastric-X: A Multimodal Multi-Phase Benchmark Dataset for Advancing Vision-Language Models in Gastric Cancer Analysis | 2026.03 | CVIPPR 2026 | Paper | — |
| SpatialMed | Beyond Medical Diagnostics: How Medical Multimodal Large Language Models Think in Space | 2026.03 | arXiv | Paper | |
| BONBID-HIE2023 | BONBID-HIE 2023: Neonatal Hypoxic-Ischemic Encephalopathy Lesion Segmentation | 2026.04 | MICCAI Challenge | Paper | Project |
| SGMRI-VQA | Beyond a Single Frame: Multi-Frame Spatially Grounded Reasoning Across Volumetric MRI | 2026.04 | arXiv | Paper | |
| Curia-2 | Curia-2: Scaling Self-Supervised Learning for Radiology Foundation Models | 2026.04 | arXiv | Paper | |
| CT-SpatialVQA | Lost in Volume: The CT-SpatialVQA Benchmark for Evaluating Semantic-Spatial Understanding of 3D Medical Vision-Language Models | 2026.05 | arXiv | Paper | |
| Med-StepBench | Med-StepBench: A Hierarchical Reasoning Framework for Evaluating Hallucinations in Medical Vision-Language Models | 2026.05 | arXiv | Paper | |
| DeepTumorVQA-H | DeepTumorVQA: A Hierarchical 3D CT Benchmark for Stage-Wise Evaluation of Medical VLMs and Tool-Augmented Agents | 2026.05 | arXiv | Paper | |
| ABRA | ABRA: Agent Benchmark for Radiology Applications | 2026.05 | arXiv | Paper | |
| RadSaFE-200 | Safety and Accuracy Follow Different Scaling Laws in Clinical Large Language Models | 2026.05 | arXiv | Paper | |
| Oncology VQA Benchmark | Automated Report-Derived Oncology VQA Benchmark for Evaluating Vision-Language Models on 3D Medical Imaging | 2026.06 | arXiv | Paper | |
| Abdomen-NCCT Benchmark | A Multi-Center Benchmark for Abdominal Disease Diagnosis and Report Generation from Non-Contrast CT | 2026.06 | arXiv | Paper | |
| RadOT-Eval | RadOT-Eval: Auditable Structured-Evidence Transport for Radiology Report Evaluation | 2026.06 | arXiv | Paper | |
| ReportQA | ReportQA: QA-Based Radiology Report Evaluation | 2026.06 | arXiv | Paper | |
| CORTEX | CORTEX: A Structured Reasoning Benchmark for Trustworthy 3D Chest CT MLLMs | 2026.06 | arXiv | Paper | |
| MedCTA | MedCTA: A Benchmark for Clinical Tool Agents | 2026.06 | arXiv | Paper | |
| Lung CT FM Benchmark | Foundation Models vs. Radiomics for Lung Computed Tomography: A Benchmark of Feature Extractors, Classification Heads, and Segmentation Choices | 2026.07 | arXiv | Paper | Project |
| Brain Oncology 3D MRI-Text | Multi-LLM Collaborative MRI Report Generation for Visual Instruction Tuning in Brain Oncology | 2026.07 | arXiv | Paper | - |
| COBRA2026 | COBRA2026: a large-scale multicenter pelvic cone-beam computed tomography projection dataset | 2026.07 | arXiv | Paper | Project |
| GLI-AL | GLI-AL: A Multi-Modal Glioma MRI Label Resource with Unified Anatomy-Lesion Labels | 2026.07 | arXiv | Paper | Project |


Similar repos


Volumetric Radiology AI in the Era of Multimodal Large Language Models
23
39 commits
updated Aug 24, 2026
README
Volumetric Radiology AI in the Era of Multimodal Large Language Models
The official resource repository for our review of volumetric radiology foundation models, multimodal large language models, agentic systems, and evaluation benchmarks.
Co-development of volumetric radiology foundation models and agentic systems.
Contents
Foundation Models
Foundation-model landscape: volumetric self-supervised pre-training, vision-language alignment, and MLLM-based interpretation.
Self-Supervised Pre-training
| Method | Title | Venue | Date | Paper | Project |
|---|---|---|---|---|---|
| Models Genesis | Medical Image Analysis | 21.02 | Paper | Project | |
| UniMiSS | UniMiSS: Universal Medical Self-Supervised Learning via Breaking Dimensionality Barrier | ECCV2022&TPAMI | 21.12 | Paper | Project |
| Swin-UNETR | Self-Supervised Pre-Training of Swin Transformers for 3D Medical Image Analysis | CVPR 2022 | CVPR 2022 | Paper | Project |
| PCRLv2 | A Unified Visual Information Preservation Framework for Self-supervised Pre-training in Medical Image Analysis | IEEE TPAMI | 2023.01 | Paper | Project |
| MIM-Med3D | Masked Image Modeling Advances 3D Medical Image Analysis | WACV 2023 | 2023.01 | Paper | Project |
| GVSL | Geometric Visual Similarity Learning in 3D Medical Image Self-supervised Pre-training | CVPR 2023 | 2023.03 | Paper | Project |
| M3AE | M3AE: Multimodal Representation Learning for Brain Tumor Segmentation with Missing Modalities | AAAI 2023 | 2023.03 | Paper | Project |
| HybridMIM | HybridMIM: A Hybrid Masked Image Modeling Framework for 3D Medical Image Segmentation | IEEE JBHI | 2024.04 | Paper | Project |
| VoCo | Large-Scale 3D Medical Image Pre-Training With Geometric Context Priors | CVPR 2024 / IEEE TPAMI | 2024.06 | Paper | Project |
| CDSSL-P3D | Cross-Dimensional Medical Self-Supervised Representation Learning Based on a Pseudo-3D Transformation | MICCAI 24 | 2024.10 | Paper | - |
| MDM | Masked Deformation Modeling for Volumetric Brain MRI Self-Supervised Pre-Training | IEEE TMI | 2024.12 | Paper | Project |
| DAE | Disruptive Autoencoders: Leveraging Low-level features for 3D Medical Image Pre-training | MIDL 2024 | 2024.06 | Paper | Project |
| Unified 3D MRI Representations via Sequence-Invariant Contrastive Learning | arXiv | 2025.01 | Paper | Project | |
| GzPT | Improving Self-Supervised Medical Image Pre-Training by Early Alignment With Human Eye Gaze Information | AAAI24/IEEE TMI | 2025.01 | Paper | Project |
| FM-HCT | 3D Foundation AI Model for Generalizable Disease Detection in Head Computed Tomography | arXiv | 2025.02 | Paper | Project |
| MedVAE: Efficient Automated Interpretation of Medical Images with Large-Scale Generalizable Autoencoders | MIDL 2025 | 2025.02 | Paper | Project | |
| MiM | MiM: Mask in Mask Self-Supervised Pre-Training for 3D Medical Image Analysis | IEEE TMI | 2025.04 | Paper | - |
| BrainMVP | BrainMVP: Multi-modal Vision Pre-training for Brain MRI Analysis | CVPR 2025 (Highlight) | 2025.06 | Paper | Project |
| SPECTRE | Scaling Self-Supervised and Cross-Modal Pretraining for Volumetric CT Transformers | CVPR 2026 | 2025.11 | Paper | Project |
| SubFore | HU-based Foreground Masking for 3D Medical Masked Image Modeling | MICCAI25 | 2025.10 | Paper | Project |
| 3DINO | A generalizable 3D framework and model for self-supervised learning in medical imaging | npj Digital Medicine | 2025.11 | Paper | Project |
| TotalFM | TotalFM: An Organ-Separated Framework for 3D-CT Vision Foundation Models | arxiv | 2026.01 | Paper | - |
| Curia-2 | Curia-2: Scaling Self-Supervised Learning for Radiology Foundation Models | arxiv | 2026.02 | Paper | - |
| OCTCube-M | A 3D multimodal optical coherence tomography foundation model for retinal and systemic diseases with cross-cohort and cross-device validation | Nature Biomedical Engineering | 2026.04 | Paper | Project |
| NeuroSTORM | Towards a general-purpose foundation model for fMRI analysis | NBME | 2026.03 | Paper | Project |
| Triad | Vision foundation model for 3D magnetic resonance imaging segmentation, classification, and registration | MedIA | 2026.05 | Paper | - |
| Foundation-VAE | Foundation VAEs for 3D CT Reconstruction, Augmentation, and Generation | ICML 2026 | 2026.05 | Paper | Project |
| CoralBay | CoralBay: A Self-Supervised CT Foundation Model | arXiv | 2026.06 | Paper | - |
| How Much MRI Preprocessing Is Enough? A Cost-Utility Study for Brain MRI Foundation Models | arXiv | 2026.06 | Paper | - | |
| NeuroVFM | Health system learning enables generalist neuroimaging models | Nature Medicine | 2026.07 | Paper | Project |
| BrainFIBRE | BrainFIBRE: A Foundation Model via Information Decomposition for Brain Microstructure | ECCV 2026 / arXiv | 2026.07 | Paper | - |
| BoneCoT / BoneFM | BoneCoT: multicentre validation of a whole-body skeleton foundation model for bone metastases guided by clinician-derived chain of thought | Nature Biomedical Engineering | 2026.07 | Paper | Project |
| Cardiac CT FM | A Unified Framework for Comprehensive Cardiac CT Segmentation and Phenotyping: Human-in-the-Loop Data Annotation, Vision Foundation Model Development, Multicenter Evaluation and Clinical Validation | arXiv | 2026.07 | Paper | - |
| COJEPA | Contrastive Joint-Embedding Prediction for Representation Learning in Structural MRI | arXiv | 2026.07 | Paper | - |
| BrainNext | BrainNext: A General-Purpose Self-Supervised Foundation Model for Brain MRI Analysis | arXiv | 2026.07 | Paper | - |
| OrganLens | OrganLens: Organ-Specific Representation Learning for CT Foundation Models | arXiv | 2026.07 | Paper | - |
| Rad-JEPA 3D | Rad-JEPA 3D: Radiology Joint-Embedding Predictive Model for 3D Computed Tomography | arXiv | 2026.07 | Paper | - |
Contrastive Learning (CLIP-based Methods)
| Method | Dimension | Title | Venue | Date | Paper | Project |
|---|---|---|---|---|---|---|
| MedCLIP | 2D | MedCLIP: Contrastive Learning from Unpaired Medical Images and Text | EMNLP 2022 | 2022.12 | Paper | Project |
| PubMedCLIP | 2D | PubMedCLIP: How Much Does CLIP Benefit Visual Question Answering in the Medical Domain? | EACL 2023 (Findings) | 2023.05 | Paper | Project |
| MedBLIP | 2D | MedBLIP: Bootstrapping Language-Image Pre-training from 3D Medical Images and Texts | arxiv | 2023.05 | Paper | - |
| CLIP-Lung | 2D | CLIP-Lung: Textual Knowledge-Guided Lung Nodule Malignancy Prediction | MICCAI 2023 | 2023.10 | Paper | Project |
| BioMedCLIP | 2D | BiomedCLIP: A Multimodal Biomedical Foundation Model Pretrained from Fifteen Million Scientific Image-Text Pairs | NEJM AI 2024 | 2024.01 | Paper | Project |
| PMC-CLIP | 2D | PMC-CLIP: Contrastive Language-Image Pre-training using Biomedical Documents | MICCAI 2023 | 2023.10 | Paper | Project |
| UniMedCLIP | 2D | UniMed-CLIP: Towards a Unified Image-Text Pretraining Paradigm for Diverse Medical Imaging Modalities | Arxiv | 2024.12 | Paper | Project |
| ConceptCLIP | 2D | ConceptCLIP: Towards Trustworthy Medical AI via Concept-Enhanced Contrastive Language-Image Pre-training | arXiv | 2025.01 | Paper | Project |
| MMKD-CLIP | 2D | Unifying Biomedical Vision-Language Expertise: Towards a Generalist Foundation Model via Multi-CLIP Knowledge Distillation | Arxiv | 2025.06 | Paper | - |
| RadiSimCLIP | 2D | RadiSimCLIP: A Radiology Vision-Language Model Pretrained on Simulated Radiologist Learning Dataset for Zero-Shot Medical Image Understanding | MICCAI 2025 Workshop | 2025.10 | Paper | Project |
| UniBrain | 3D | UniBrain: Universal Brain MRI Diagnosis with Hierarchical Knowledge-enhanced Pre-training | Computerized Medical Imaging and Graphics | 2023.09 | Paper | Project |
| CT2Rep | 3D | CT2Rep: Automated Radiology Report Generation for 3D Medical Imaging | MICCAI 2024 | 2024.03 | Paper | Project |
| CT-CLIP | 3D | Generalist Foundation Models from a Multimodal Dataset for 3D Computed Tomography | Nat Biomed Eng | 2024.03 | Paper | Project |
| CT-GLIP | 3D | CT-GLIP: 3D Grounded Language-Image Pretraining with CT Scans and Radiology Reports for Full-Body Scenarios | arXiv | 2024.04 | Paper | - |
| RadCLIP | 3D | RadCLIP: Enhancing Radiologic Image Analysis Through Contrastive Language–Image Pretraining | TNNLS | 2024.03 | Paper | - |
| Percival | 3D | A Pan-Organ Vision-Language Model for Generalizable 3D CT Representations | medRxiv | 2025.07 | Paper | - |
| OpenVocabCT | 3D | Towards Universal Text-driven CT Image Segmentation | arXiv | 2025.03 | Paper | - |
| fVLM | 3D | Large-scale and Fine-grained Vision-language Pre-training for Enhanced CT Image Understanding | ICLR 2025 | 2025.03 | Paper | Project |
| HLIP | 3D | Towards Scalable Language-Image Pre-training for 3D Medical Imaging | arxiv | 2025.05 | Paper | Project |
| RadZero3D | 3D | RadZero3D: Bridging Self-Supervised Video Models and Medical Vision-Language Alignment for Zero-Shot Chest CT Interpretation | ICCV 2025 Workshop | 2025.10 | Paper | - |
| T3D | 3D | T3D: Advancing 3D Medical Vision-Language Pre-training by Learning Multi-View Visual Consistency | ICCV 2025 Workshop | 2025.10 | Paper | - |
| ViSD-Boost | 3D | Boosting Vision Semantic Density with Anatomy Normality Modeling for Medical Vision-language Pre-training | ICCV 2025 | 2025.08 | Paper | Project |
| VELVET-Med | 3D | VELVET-Med: Vision and Efficient Language Pre-training for Volumetric Imaging Tasks in Medicine | arXiv | 2025.08 | Paper | - |
| MedVista3D | 3D | MedVista3D: Vision-Language Modeling for Reducing Diagnostic Errors in 3D CT Disease Detection, Understanding and Reporting | arXiv | 2025.09 | Paper | - |
| COLIPRI | 3D | Comprehensive Language-Image Pre-training for 3D Medical Image Understanding | arXiv | 2025.10 | Paper | Project |
| MPS-CT | 3D | More performant and scalable: Rethinking contrastive vision-language pre-training of radiology in the LLM era | MICCAI 2025 | 2025.10 | Paper | Project |
| PET-CLIP Captioner | 3D | Location-Guided Automated Lesion Captioning in Whole-body PET/CT Images | MICCAI 2025 | 2025.10 | Paper | - |
| MR-CLIP | 3D | Metadata-Aligned 3D MRI Representations for Contrast Understanding and Quality Control | arXiv | 2025.11 | Paper | - |
| BrgSA | 3D | Bridged Semantic Alignment for Zero-shot 3D Medical Image Diagnosis | arXiv | 2025.11 | Paper | Project |
| SCALE-VLP | 3D | SCALE-VLP: Soft-Weighted Contrastive Volumetric Vision-Language Pre-training with Spatial-Knowledge Semantics | arXiv | 2025.11 | Paper | - |
| SPECTRE | 3D | Scaling Self-Supervised and Cross-Modal Pretraining for Volumetric CT Transformers | CVPR 2026 | 2025.11 | Paper | Project |
| Pillar-0 | 3D | Pillar-0: A New Frontier for Radiology Foundation Models | arxiv | 2025.11 | Paper | Project |
| BTB3D | 3D | Better Tokens for Better 3D: Advancing Vision-Language Modeling in 3D Medical Imaging | NeurIPS 2025 | 2025.12 | Paper | Project |
| NeuroVFM | 3D | NeuroVFM: A Contrastive Vision-Language Model for Medical Reasoning in Alzheimer's Disease Diagnosis | WACV 2026 Workshops | 2026.01 | Paper | - |
| TotalFM | 3D | TotalFM: An Organ-Separated Framework for 3D-CT Vision Foundation Models | arxiv | 2026.01 | Paper | - |
| MG-3D | 3D | MG-3D: Multi-Grained Knowledge-Enhanced 3D Medical Vision-Language Pre-training | Medical Image Analysis (MedIA) | 2026.01 | Paper | Project |
| MedMAP | 3D | 3D Modality-Aware Pre-training for Vision-Language Model in MRI Multi-organ Abnormality Detection | arxiv | 2026.02 | Paper | Project |
| Prima | 3D | Learning neuroimaging models from health system-scale data | Nature Biomedical Engineering | 2026.02 | Paper | Project |
| SigVLP | 3D | SigVLP: Sigmoid Volume-Language Pre-Training for Self-Supervised CT-Volume Adaptive Representation Learning | arXiv | 2026.02 | Paper | - |
| RadFinder | 3D | Learning to Read Where to Look: Disease-Aware Vision–Language Pretraining for 3D CT | arXiv | 2026.03 | Paper | Project |
| Decipher-MR | 3D | Decipher-MR: A Vision-Language Foundation Model for 3D MRI Representations | npj Digital Medicine | 2026.04 | Paper | - |
| 3D | CLIP Architecture for Abdominal CT Image–Text Alignment and Zero-Shot Learning: Investigating Batch Composition and Data Scaling | arxiv | 2026.04 | Paper | - | |
| ASAP | 3D | ASAP: Advancing Medical Volumetric Representation Learning with Anatomy-aware Semantically-adaptive Pre-training | arXiv | 2026.05 | Paper | - |
| GLeVE | 3D | GLeVE: Graph-Guided Lesion Grounding with Proposal Verification in 3D CT | arXiv | 2026.05 | Paper | - |
| CA-GCL | 3D | CA-GCL: Cross-Anatomy Global-Local Contrastive Learning for Robust 3D Medical Image Understanding | arXiv | 2026.05 | Paper | - |
| SegReg-Rep | 3D | SegReg-Rep: Region-Aware Vision-Language Alignment for Fine-Grained Radiology Report Generation from 3D Medical Images | IEEE TPRMS | 2026.05 | Paper | Project |
| GLINT | 3D | GLINT: Sparsely Gated Vision-Language Alignment for Fine-Grained Radiology Representations | arXiv | 2026.06 | Paper | - |
| RadGrounder | 2D | Scalable Training of Spatially Grounded 2D Vision-Language Models for Radiology | arXiv | 2026.06 | Paper | - |
| RenalCLIP | 3D | A Disease-Centric Vision-Language Foundation Model for Precision Oncology in Kidney Cancer | Nature Communications | 2026.06 | Paper | - |
| Jolia / ConQuer | 3D | Jolia: Concept-Level Vision-Language Alignment for 3D CT Contrastive Learning | arXiv | 2026.06 | Paper | - |
| 3D | Disease-Centric Vision-Language Pretraining with Hybrid Visual Encoding for 3D Computed Tomography | arXiv | 2026.06 | Paper | - | |
| MedReCo | 3D | A Vision-language Framework for Comparative Reasoning in Radiology | arXiv | 2026.06 | Paper | - |
| SuG | 3D | Super-Generalist: Towards Comprehensive and Accurate Medical Image Understanding via Generalist-Specialist Synergy | arXiv | 2026.07 | Paper | - |
| OKA-CT | 3D | Learning Anatomy-Grounded CT Vision-Language Representations with Organ-Hierarchical Report Knowledge | arXiv | 2026.07 | Paper | - |
| OCP-CT | 3D | Fine-Grained Vision-Language Pretraining with Organ-Conditioned Pattern Tokens for CT Understanding | arXiv | 2026.07 | Paper | - |
| MseaCL | 3D | Multimodal Semantic-Aware Contrastive Learning For False Negative Mitigation in 3D Medical Imaging | arXiv | 2026.07 | Paper | - |
| CARVE | 3D | When Can Test-Time Adaptation Help Zero-Shot CT Vision-Language Models? | arXiv | 2026.07 | Paper | - |
| ACA | 3D | Anatomy Contextualized Adaption of CT Foundation Models | arXiv | 2026.07 | Paper | - |
| Spectrum | 3D | Learning How Much, Not Just What: Cross-Patient Burden Order for CT Vision-Language Pretraining | arXiv | 2026.07 | Paper | - |
| SCOPE | 3D | Semantically Calibrated Evidence Composition for CT Vision-Language Learning | arXiv | 2026.07 | Paper | - |
MLLM-based Methods
2D-only
| Method | Title | Venue | Date | Paper | Project |
|---|---|---|---|---|---|
| BiomedGPT | BiomedGPT: A Generalist Vision-Language Foundation Model for Diverse Biomedical Tasks | Nat Med 2024 | 2023.05 | Paper | Project |
| MedVInT | PMC-VQA: Visual Instruction Tuning for Medical Visual Question Answering | Arxiv/ Communications Medicine | 2023.05/2024.12 | Paper | - |
| LLaVA-Med | LLaVA-Med: Training a Large Language-and-Vision Assistant for Biomedicine in One Day | NeurIPS 2023 | 2023.06 | Paper | Project |
| Med-Flamingo | Med-Flamingo: a Multimodal Medical Few-shot Learner | ML4H 2023 | 2023.07 | Paper | Project |
| Med-PaLM M | Towards Generalist Biomedical AI | NEJM AI 2024 / arXiv | 2023.07 | Paper | Project |
| Qilin-Med-VL | Qilin-Med-VL: Towards Chinese Large Vision-Language Model for General Healthcare | arXiv | 2023.10 | Paper | - |
| R2GenGPT | R2GenGPT: Radiology Report Generation with Frozen LLMs | Meta-Radiology | 2023.11 | Paper | - |
| BiRD | A Refer-and-Ground Multimodal Large Language Model for Biomedicine | MICCAI 2024 | 2024.06 | Paper | - |
| HuatuoGPT-Vision | Towards Injecting Medical Visual Knowledge into Multimodal LLMs at Scale | EMNLP24 | 2024.06 | Paper | Project |
| Llama3-Med | Advancing High Resolution Vision-Language Models in Biomedicine | arXiv | 2024.06 | Paper | Project |
| MiniGPT-Med | MiniGPT-Med: Large Language Model as a General Interface for Radiology Diagnosis | arXiv | 2024.07 | Paper | Project |
| TinyLLaVA-Med | Democratizing MLLMs in Healthcare: TinyLLaVA-Med for Efficient Healthcare Diagnostics in Resource-Constrained Settings | MICCAI24 | 2024.09 | Paper | - |
| Med-MoE | Med-MoE: Mixture of Domain-Specific Experts for Lightweight Medical Vision-Language Models | EMNLP24 | 2024.09 | Paper | Project |
| GMAI-VL | GMAI-VL & GMAI-VL-5.5M: A Large Vision-Language Model and A Comprehensive Multimodal Dataset Towards General Medical AI | arXiv/AAAI26 | 2024.11 | Paper | Project |
| BiMediX2 | BiMediX2: Bio-Medical EXpert LMM for Diverse Medical Modalities | Findings of EMNLP 2025 | 2025.01 | Paper | Project |
| HealthGPT | HealthGPT: A Medical Large Vision-Language Model for Unifying Comprehension and Generation via Heterogeneous Knowledge Adaptation | ICML 2025 | 2025.02 | Paper | Project |
| MedVLM-R1 | MedVLM-R1: Incentivizing Medical Reasoning Capability of Vision-Language Models (VLMs) via Reinforcement Learning | MICCAI25 | 2025.02 | Paper | Project |
| Med-R1 | Med-R1: Reinforcement Learning for Generalizable Medical Reasoning in Vision-Language Models | TMI | 2025.03 | Paper | Project |
| OmniV-Med | OmniV-Med: Scaling Medical Vision-Language Model for Universal Visual Understanding | arXiv | 2025.04 | Paper | - |
| UniBioMed | UniBiomed: A Universal Foundation Model for Grounded Biomedical Image Interpretation | arXiv | 2025.04 | Paper | Project |
| MedRegA | MedRegA: Interpretable Bilingual Multimodal Large Language Model for Diverse Biomedical Tasks | ICLR25 | 2025.04 | Paper | Project |
| UMed-LVLM | Improving Medical Large Vision-Language Models with Abnormal-Aware Feedback | ACL 2025 | 2025.05 | Paper | - |
| QoQ-Med | QoQ-Med: Building Multimodal Clinical Foundation Models with Domain-Aware GRPO Training | arXiv | 2025.06 | Paper | Project |
| Lingshu | Lingshu: A Generalist Foundation Model for Unified Multimodal Medical Understanding and Reasoning | arXiv | 2025.06 | Paper | Project |
| MedGemma | MedGemma Technical Report | arXiv | 2025.07 | Paper | Project |
| Critus-V | Citrus-V: Advancing Medical Foundation Models with Unified Medical Image Grounding for Clinical Reasoning | arXiv | 2025.09 | Paper | Project |
| MedPLIB | Towards a Multimodal Large Language Model with Pixel-Level Insight for Biomedicine | AAAI25 | 2025.10 | Paper | Project |
| OctoMed | OctoMed: Data Recipes for State-of-the-Art Multimodal Medical Reasoning | arXiv | 2025.11 | Paper | Project |
| MedMO | MedMO: Grounding and Understanding Multimodal Large Language Model for Medical Images | arXiv | 2026.02 | Paper | Project |
| MediX-R1 | MediX-R1: Open Ended Medical Reinforcement Learning | arXiv | 2026.02 | Paper | Project |
| MEDIC-AD | MEDIC-AD: Towards Medical Vision-Language Model’s Clinical Intelligence | CVPR26 Oral | 2026.03 | Paper | Project |
| MedVR | MedVR: Annotation-Free Medical Visual Reasoning via Agentic Reinforcement Learning | ICLR 26 | 2026.04 | Paper | Project |
Unified 2D + Serialized-3D
| Method | Title | Venue | Date | Paper | Project |
|---|---|---|---|---|---|
| RadFM | Towards Generalist Foundation Model for Radiology by Leveraging Web-scale 2D&3D Medical Data | Nat Commun 2025 / arXiv | 2023.08 | Paper | Project |
| Med-Gemini | Advancing Multimodal Medical Capabilities of Gemini | Nat Med 2025 / arXiv | 2024.05 | Paper | Project |
| Med-2E3 | Med-2E3: A 2D-Enhanced 3D Medical Multimodal Large Language Model | BIBM25 | 2024.11 | Paper | - |
| Hulu-Med | Hulu-Med: A Transparent Generalist Model towards Holistic Medical Vision-Language Understanding | arXiv | 2025.10 | Paper | Project |
| Fleming-VL | Fleming-VL: Towards Universal Medical Visual Reasoning with Multimodal LLMs | arXiv | 2025.11 | Paper | Project |
| MedM-VL | MedM-VL: What Makes a Good Medical LVLM? | International Workshop on Agentic AI for Medicine 2025 | 2025.09 | Paper | Project |
| CTInstruct | CTInstruct: Towards Unified 3D CT Understanding via Instruction Tuning | AAAI 26 | 2026.01 | Paper | Project |
| A data-efficient 3D medical vision-language model using only a 2D encoder | Scientific report | 2026.02 | Paper | - | |
| MedPruner | MedPruner: Training-Free Hierarchical Token Pruning for Efficient 3D Medical Image Understanding in Vision-Language Models | MICCAI2026 | 2026.03 | Paper | - |
| Photon | Photon: Speedup Volume Understanding with Efficient Multimodal Large Language Models | ICLR 26 | 2026.03 | Paper | Project |
| OmniCT | OmniCT: Towards a Unified Slice-Volume LVLM for Comprehensive CT Analysis | ICLR 26 | 2026.03 | Paper | Project |
| MedGemma1.5 | MedGemma 1.5 Technical Report | arXiv | 2026.04 | Paper | Project |
| TGH-MoE | Adapting 2D Multi-Modal Large Language Model for 3D CT Image Analysis | arXiv | 2026.04 | Paper | - |
| Brain-Adapter | Brain-Adapter: A Dual-Stream Vision-Language MIL Framework for Comprehensive 3D CT Diagnosis of Acute Intracranial Pathologies | arXiv | 2026.06 | Paper | - |
| UniReason-Med | UniReason-Med: A Shared Grounded Reasoning Interface for 2D-to-3D Transfer in Medical VQA | arXiv | 2026.06 | Paper | Project |
| MedReCo-VLM | A Vision-language Framework for Comparative Reasoning in Radiology | arXiv | 2026.06 | Paper | - |
| RadSight | RadSight: Towards Perceptually Reliable Multimodal Radiology Image Understanding | arXiv | 2026.07 | Paper | Project |
| ClinFusion | ClinFusion: A Vision-Centric Multimodal LLM System for Holistic Medical Understanding | arXiv | 2026.07 | Paper | Project |
| Hounsfield | Towards Enhancing 3D Spatial Reasoning in Medical Multimodal Large Language Models | arXiv | 2026.07 | Paper | Project |
| MedARC | MedARC: Training-Free Adaptive Redundancy Compression of Visual Tokens for 3D Medical Vision-Language Models | arXiv | 2026.07 | Paper | - |
| ORCA | ORCA: ORgan-Centroid Aggregation for Training-Free 3D CT Visual Token Compression | arXiv | 2026.07 | Paper | Project |
Native 3D-Volume
| Method | Title | Venue | Date | Paper | Project |
|---|---|---|---|---|---|
| CT2Rep | CT2Rep: Automated Radiology Report Generation for 3D Medical Imaging | MICCAI 2024 / arXiv | 2024.03 | Paper | Project |
| Dia-LLaMA | Dia-LLaMA: Towards Large Language Model-driven CT Report Generation | MICCAI | 2024.03 | Paper | - |
| M3D-LaMed | M3D: Advancing 3D Medical Image Analysis with Multi-Modal Large Language Models | ICLR 2025 / arXiv | 2024.04 | Paper | Project |
| Merlin | Merlin: A Computed Tomography Vision-Language Foundation Model and Dataset | Nature 2026 / arXiv | 2024.06 | Paper | Project |
| BrainGPT | Towards a Holistic Framework for Multimodal Large Language Models in Three-dimensional Brain CT Report Generation | Nat Commun 2025 / arXiv | 2024.07 | Paper | Project |
| 3D-CT-GPT | 3D-CT-GPT: Generating 3D Radiology Reports through Integration of Large Vision-Language Models | arXiv | 2024.09 | Paper | - |
| E3D-GPT | E3D-GPT: Enhanced 3D Visual Foundation for Medical Vision-Language Model | arXiv | 2024.10 | Paper | - |
| Reg2RG | Large Language Model with Region-guided Referring and Grounding for CT Report Generation | arXiv | 2024.11 | Paper | - |
| MS-VLM | Read Like a Radiologist: Efficient Vision-Language Model for 3D Medical Imaging Interpretation | arXiv | 2024.12 | Paper | - |
| MEPNet | MEPNet: Medical Entity-balanced Prompting Network for Brain CT Report Generation | arXiv | 2025.03 | Paper | - |
| Med3DVLM | Med3DVLM: An Efficient Vision-Language Model for 3D Medical Image Analysis | IEEE JBHI 2025 / arXiv | 2025.03 | Paper | Project |
| HSENet | HSENet: Hybrid Spatial Encoding Network for 3D Medical Vision-Language Understanding | arXiv | 2025.06 | Paper | - |
| MedRegion-CT | MedRegion-CT: Region-Focused Multimodal LLM for Comprehensive 3D CT Report Generation | arXiv | 2025.06 | Paper | - |
| mpLLM | Multimodal LLM With Hierarchical Mixture-of-Experts for VQA on 3D Brain MRI | arXiv | 2025.09 | Paper | - |
| 3DReasonKnee | 3DReasonKnee: Advancing Grounded Reasoning in Medical Vision Language Models | arXiv | 2025.10 | Paper | - |
| PETAR | PETAR: Localized Findings Generation with Mask-Aware Vision-Language Modeling for PET Automated Reporting | arXiv | 2025.10 | Paper | - |
| BTB3D | Better Tokens for Better 3D: Advancing Vision-Language Modeling in 3D Medical Imaging | NeurlPS 2025 | 2025.10 | Paper | Project |
| PETRG-3D | Vision-Language Models for Automated 3D PET/CT Report Generation | arXiv | 2025.11 | Paper | - |
| CTest-Metric | CTest-Metric: A Unified Framework to Assess Clinical Validity of Metrics for CT Report Generation | ISBI2026 | 2026.01 | Paper | - |
| Brain3D | Brain3D: Brain Report Automation via Inflated Vision Transformers in 3D | arXiv | 2026.02 | Paper | Project |
| Med3D-R1 | Med3D-R1: Incentivizing Clinical Reasoning in 3D Medical Vision-Language Models for Abnormality Diagnosis | arXiv | 2026.02 | Paper | - |
| LoV3D | LoV3D: Grounding Cognitive Prognosis Reasoning in Longitudinal 3D Brain MRI via Regional Volume Assessments | arXiv | 2026.03 | Paper | - |
| Ker-VLJEPA-3B | Curriculum-Driven 3D CT Report Generation via Language-Free Visual Grafting and Zone-Constrained Compression | arXiv | 2026.03 | Paper | Project |
| U-VLM | U-VLM: Hierarchical Vision Language Modeling for Report Generation | arXiv | 2026.02 | Paper | Project |
| CT-CHAT | Generalist foundation models from a multimodal dataset for 3D computed tomography | Nature Biomedical Engineering | 2026.02 | Paper | Project |
| MedVL-SAM2 | MedVL-SAM2: A unified 3D medical vision–language model for multimodal reasoning and prompt-driven segmentation | arXiv | 2026.01 | Paper | - |
| BoiD | Enhancing 3D medical multi-modal large language models with integrated human body priors for computed tomography | Pattern Recognition | 2026.04 | Paper | - |
| DCP-PD | Enhancing Fine-Grained Spatial Grounding in 3D CT Report Generation via Discriminative Guidance | arxiv | 2026.04 | Paper | - |
| SegReg-Rep | SegReg-Rep: Region-Aware Vision-Language Alignment for Fine-Grained Radiology Report Generation from 3D Medical Images | IEEE TPRMS | 2026.05 | Paper | Project |
| CLarGen | Generating Reports or Repeating Templates? Measuring and Mitigating Template Collapse in 3D CT Report Generation | arXiv | 2026.05 | Paper | - |
| TIF-GRPO | Regulating Anatomy-Aware Rewards via Trajectory-Integral Feedback for Volumetric Computed Tomography Analysis | arXiv | 2026.05 | Paper | - |
| RAD3D-Prefix | Revisiting LLM Adaptation for 3D CT Report Generation: A Study of Scaling and Diagnostic Priors | arXiv | 2026.06 | Paper | - |
| E-MRL | E-MRL: Cross-view Aligned Evidence-driven Multimodal Reinforcement Learning for Reliable 3D Tumor Analysis | arXiv | 2026.06 | Paper | - |
| MRI2Rep | MRI2Rep: Autoregressive Structured Report Generation for 3D Liver MRI | arXiv | 2026.06 | Paper | - |
| NeuroVFM | Health system learning enables generalist neuroimaging models | Nature Medicine | 2026.07 | Paper | Project |
| PIPA | PIPA: Prior-Driven Prompting with Diagnosis-Oriented Retrieval-Augmentation for 3D Radiology Report Generation | IEEE TMI | 2026.07 | Paper | Project |
| MonteRET | MonteRET: AI Agent Enhancing Multimodal LLMs with Multi-granularity Knowledge Retrieval for Chest CT Report Generation | arXiv | 2026.07 | Paper | - |
| Multi-LLM MRI | Multi-LLM Collaborative MRI Report Generation for Visual Instruction Tuning in Brain Oncology | arXiv | 2026.07 | Paper | - |
Agentic Systems
Core modules of agentic 3D radiology workflows: reasoning and planning, tool-augmented perception, memory and context, and workflow collaboration.
| Method | Title | Venue | Date | Paper | Project |
|---|---|---|---|---|---|
| MDAgents | MDAgents: An Adaptive Collaboration of LLMs for Medical Decision-Making | NeurIPS 2024 | 2024.12 (arXiv: 2024.04) | Paper | Project |
| MMedAgent | MMedAgent: Learning to Use Medical Tools with Multi-modal Agent | Findings of EMNLP 2024 | 2024.11 (arXiv: 2024.07) | Paper | Project |
| MedAgent-Pro | MedAgent-Pro: Towards Evidence-based Multi-modal Medical Diagnosis via Reasoning Agentic Workflow | ICLR 2026 | 2025.03 | Paper | Project |
| DOLA | Autonomous Radiotherapy Treatment Planning Using DOLA: A Privacy-Preserving, LLM-Based Optimization Agent | arXiv | 2025.03 | Paper | - |
| GPT-Plan | A Feasibility Study of Automating Radiotherapy Planning with Large Language Model Agents | Physics in Medicine and Biology | 2025.03 | Paper | - |
| VILA-M3 | VILA-M3: Enhancing Vision-Language Models with Medical Expert Knowledge | CVPR25 | 2024.11 | Paper | Project |
| CT-Agent | CT-Agent: A Multimodal-LLM Agent for 3D CT Radiology Question Answering | arXiv | 2025.05 | Paper | - |
| M^3Builder | M^3Builder: A Multi-Agent System for Automated Machine Learning in Medical Imaging | AI for Clinical Applications 2025 | 2025.05 | Paper | - |
| SAMIRA | Towards user-centered interactive medical image segmentation in VR with an assistive AI agent | arXiv | 2025.05 | Paper | - |
| MAM | MAM: Modular Multi-Agent Framework for Multi-Modal Medical Diagnosis via Role-Specialized Collaboration | Findings of ACL 2025 | 2025.07 (arXiv: 2025.06) | Paper | Project |
| AgentMRI | AgentMRI: A Vision Language Model-Powered AI System for Self-regulating MRI Reconstruction with Multiple Degradations | Journal of Imaging Informatics in Medicine | 2025.07 | Paper | - |
| CTPA-Agent | Vision-language model for report generation and outcome prediction in CT pulmonary angiogram | npj Digital Medicine | 2025.07 | Paper | Project |
| TissueLab | A co-evolving agentic AI system for medical imaging analysis | arXiv | 2025.09 | Paper | Project |
| Scan-do Attitude | Scan-do Attitude: Towards Autonomous CT Protocol Management Using a Large Language Model Agent | Agentic AI for Medicine / Springer | 2025.09 | Paper | - |
| VoxelPrompt | VoxelPrompt: A Vision Agent for End-to-End Medical Image Analysis | arXiv | 2025.10 | Paper | - |
| MedAgentSim | MedAgentSim: Self-Evolving Multi-Agent Simulations for Realistic Clinical Interactions | MICCAI 2025 | 2025.10 (arXiv: 2025.03) | Paper | Project |
| AURA | AURA: A Multi-Modal Medical Agent for Understanding, Reasoning & Annotation | MICCAI Workshop 2025 | 2025.10 (arXiv: 2025.07) | Paper | Project |
| MedEyes | MedEyes: Learning Dynamic Visual Focus for Medical Progressive Diagnosis | arXiv | 2025.11 | Paper | Project |
| MedSAM3 | MedSAM3: Delving into Segment Anything with Medical Concepts | arXiv | 2025.11 | Paper | Project |
| Radiologist Copilot | Radiologist Copilot: An Agentic Framework Orchestrating Specialized Tools for Reliable Radiology Reporting | arXiv | 2025.12 | Paper | - |
| INFORM-CT | INFORM-CT: INtegrating LLMs and VLMs FOR Incidental Findings Management in Abdominal CT | MIDL 2026 | 2025.12 | Paper | Project |
| IBISAgent | IBISAgent: Reinforcing Pixel-Level Visual Reasoning in MLLMs for Universal Biomedical Object Referring and Segmentation | arXiv | 2026.01 | Paper | - |
| MedVistaGym | MEDVISTAGYM: A Scalable Training Environment for Thinking with Medical Images via Tool-Integrated Reinforcement Learning | arXiv | 2026.01 | Paper | - |
| An Explainable Agentic AI Framework for Uncertainty-Aware and Abstention-Enabled Acute Ischemic Stroke Imaging Decisions | arXiv | 2026.01 | Paper | - | |
| LungNoduleAgent | LungNoduleAgent: A Collaborative Multi-Agent System for Precision Diagnosis of Lung Nodules | AAAI 2026 | 2026.02 (arXiv: 2025.11) | Paper | Project |
| 3DMedAgent | 3DMedAgent: Unified Perception-to-Understanding for 3D Medical Analysis | arXiv | 2026.02 | Paper | Project |
| MedSAM-Agent | MedSAM-Agent: Empowering Interactive Medical Image Segmentation with Multi-turn Agentic Reinforcement Learning | arXiv | 2026.02 | Paper | Project |
| CARE | CARE: Towards Clinical Accountability in Multi-Modal Medical Reasoning with an Evidence-Grounded Agentic Framework | ICLR 2026 | 2026.05 (arXiv: 2026.03) | Paper | Project |
| ToolSelect | Picking the Right Specialist: Attentive Neural Process-based Selection of Task-Specialized Models as Tools for Agentic Healthcare Systems | arXiv | 2026.02 | Paper | - |
| CoMMa | CoMMa: Contribution-Aware Medical Multi-Agents From A Game-Theoretic Perspective | arXiv | 2026.02 | Paper | - |
| MedSegAgent | MedSegAgent: A Universal and Scalable Multi-Agent System for Instructive Medical Image Segmentation | IEEE JBHI | 2026.03 | Paper | Project |
| CT-Flow | CT-Flow: Orchestrating CT Interpretation Workflow with Model Context Protocol Servers | arXiv | 2026.03 | Paper | - |
| Agent-MIRA | Agent-MIRA: AI-orchestrated Medical Imaging Agent for PET Image Retrieval and Assistance | Computerized Medical Imaging and Graphics | 2026.03 | Paper | - |
| Meissa | Meissa: Multi-modal Medical Agentic Intelligence | arXiv | 2026.03 | Paper | Project |
| BT-RADS Agent | Agentic Automation of BT-RADS Scoring: End-to-End Multi-Agent System for Standardized Brain Tumor Follow-up Assessment | arXiv | 2026.03 | Paper | - |
| TheraAgent | TheraAgent: Multi-Agent Framework with Self-Evolving Memory and Evidence-Calibrated Reasoning for PET Theranostics | arXiv | 2026.03 | Paper | - |
| MedOpenClaw | MEDOPENCLAW: Auditable Medical Imaging Agents Reasoning over Uncurated Full Studies | arXiv | 2026.03 | Paper | - |
| MedMASLab | MedMASLab: A Unified Orchestration Framework for Benchmarking Multimodal Medical Multi-Agent Systems | arXiv | 2026.03 | Paper | Project |
| ClinicalAgents | ClinicalAgents: Multi-Agent Orchestration for Clinical Decision Making with Dual-Memory | arXiv | 2026.03 | Paper | - |
| Doctorina MedBench | Doctorina MedBench: End-to-End Evaluation of Agent-Based Medical AI | arXiv | 2026.03 | Paper | - |
| SEER | Skill-Evolving Grounded Reasoning for Free-Text Promptable 3D Medical Image Segmentation | arXiv | 2026.03 | Paper | |
| RadAgent | RadAgent: A Tool-Using AI Agent for Stepwise Interpretation of Chest Computed Tomography | arXiv | 2026.04 | Paper | Project |
| BAAI Cardiac Agent | BAAI Cardiac Agent: An intelligent multimodal agent for automated reasoning and diagnosis of cardiovascular diseases from cardiac magnetic resonance imaging | arXiv | 2026.04 | Paper | Project |
| DosimeTron | DosimeTron: Automating Personalized Monte Carlo Radiation Dosimetry in PET/CT with Agentic AI | arXiv | 2026.04 | Paper | - |
| MARCH | MARCH: Multi-Agent Radiology Clinical Hierarchy for CT Report Generation | ACL 2026 | 2026.04 | Paper | - |
| Neuro-Radiological Agent | Agentic Large Language Models for Training-Free Neuro-Radiological Image Analysis | arXiv | 2026.04 | Paper | - |
| Agent4MR | Agentic MR sequence development: leveraging LLMs with MR skills for automatic physics-informed sequence development | arXiv | 2026.04 | Paper | - |
| Artifact-based Agent Framework | An Artifact-based Agent Framework for Adaptive and Reproducible Medical Image Processing | arXiv | 2026.04 | Paper | - |
| NeuroClaw | NeuroClaw: Closed-Loop Agentic AI for Executable and Reproducible Neuroimaging Research | arXiv | 2026.04 | Paper | - |
| Neuro-Oracle | Neuro-Oracle: A Trajectory-Aware Agentic RAG Framework for Interpretable Epilepsy Surgical Prognosis | arXiv | 2026.04 | Paper | - |
| MedScribe | MedScribe: Clinically Grounded CT Reporting through Agentic Workflows | arXiv | 2026.05 | Paper | - |
| GAZE | GAZE: Grounded Agentic Zero-shot Evaluation with Viewer-Level Tools and Literature Retrieval on Rare Brain MRI | arXiv | 2026.05 | Paper | - |
| NeuroAgent | NeuroAgent: LLM Agents for Multimodal Neuroimaging Analysis and Research | arXiv | 2026.05 | Paper | - |
| NEXUS | Towards a Virtual Neuroscientist: Autonomous Neuroimaging Analysis via Multi-Agent Collaboration | arXiv | 2026.05 | Paper | Project |
| M2M-LLM-RT | A Machine-to-Machine Knowledge-Guided LLM Agent for Generalizable Radiotherapy Treatment Planning | arXiv | 2026.05 | Paper | - |
| SpineAgent | A Multi-Agent System for Spine MRI Report Generation from Multi-Sequence Imaging | arXiv | 2026.06 | Paper | - |
| MedToolica | MedToolica: Finetuning-Free Agentic Compositional Tool Learning for 3D CT Reasoning | Machine Learning and Knowledge Extraction | 2026.06 | Paper | Project |
| MARTP | MARTP: A Multi-Agent Simulation Framework for Automated Radiation Therapy Planning Based on LLMs | Physics in Medicine and Biology | 2026.06 | Paper | - |
| SAGE | Automated Stereotactic Radiosurgery Planning Using a Human-in-the-Loop Reasoning Large Language Model Agent | Research Square | 2026.06 | Paper | - |
| PET/CT Agent | End-to-End PET/CT Interpretation and Quantification with an LLM-Orchestrated AI Agent: A Real-World Pilot Study | Journal of Nuclear Medicine | 2026.06 | Paper | - |
| PD-CTAgent | Policy-Driven CT-Agent: Modeling Phase-Aware Diagnostic Control for Clinically Consistent CT Reasoning | arXiv | 2026.07 | Paper | - |
| MonteRET | MonteRET: AI Agent Enhancing Multimodal LLMs with Multi-granularity Knowledge Retrieval for Chest CT Report Generation | arXiv | 2026.07 | Paper | - |
| One-for-All | One-for-All Adaptive Radiotherapy Planning Agent: A Foundation Framework for Daily CBCT-guided Radiotherapy | arXiv | 2026.07 | Paper | - |
Datasets & Benchmarks
| Dataset | Title | Date | Venue | Paper Link | Project |
|---|---|---|---|---|---|
| SLIVER07 | Segmentation in the liver 2007 (SLIVER07) challenge | 2007.09 | MICCAI Workshop | Paper | Project |
| SKI10 | Segmentation of Knee Images 2010 (SKI10) | 2010.09 | MICCAI Challenge | Paper | Project |
| LIDC-IDRI | Data From LIDC-IDRI: The Lung Image Database Consortium and Image Database Resource Initiative | 2011.06 | Med Phys | Paper | Project |
| LOLA11 | LOLA11: LObe and Lung Analysis 2011 Challenge | 2011.09 | MICCAI Workshop | Project | |
| STACOM 2011 Motion Tracking | STACOM 2011: Cardiac Motion Tracking Challenge | 2011.09 | MICCAI Workshop | Paper | Project |
| Mindboggle-101 | Mindboggle-101: Evaluating Brain Image Labeling Methods | 2012.09 | NeuroImage | Paper | Project |
| PROMISE12 | PROMISE12: Prostate MR Image Segmentation 2012 Challenge | 2012.10 | MICCAI Challenge | Paper | Project |
| NLST | The National Lung Screening Trial: overview and study design | 2013.01 | Radiology | Project | |
| Farsiu Ophthalmology 2013 | Quantitative Classification of Eyes with and without Intermediate Age-related Macular Degeneration Using Optical Coherence Tomography | 2013.03 | Ophthalmology | Paper | Project |
| Prostate-3T | Data From Prostate-3T | 2013.06 | TCIA Collection | Project | |
| MRBrainS13 | MRBrainS13: Grand Challenge on MR Brain Image Segmentation | 2013.09 | MICCAI Challenge | Project | |
| Chiu BOE 2014 | Kernel regression based segmentation of optical coherence tomography images with diabetic macular edema | 2014.01 | Biomed Opt Express | Paper | Project |
| Srinivasan BOE 2014 | Fully automated detection of diabetic macular edema and dry age-related macular degeneration from optical coherence tomography images | 2014.03 | Biomed Opt Express | Paper | Project |
| orCaScore | An evaluation of automatic coronary artery calcium scoring methods with cardiac CT using the orCaScore framework | 2014.09 | MICCAI Challenge | Paper | Project |
| CETUS2014 | CETUS: Cardiac Echocardiography Tracking and Segmentation Challenge | 2014.09 | MICCAI Challenge | Project | |
| Prostate-Diagnosis | PROSTATE-DIAGNOSIS: Multiparametric MRI for Prostate Cancer | 2015.03 | TCIA Collection | Project | |
| BTCV | MICCAI multi-atlas labeling beyond the cranial vault-workshop and challenge | 2015.04 | MICCAI Workshop | Project | |
| ISMRM2015 HARDI | ISMRM 2015 Tractography Challenge | 2015.06 | ISMRM Challenge | Project | |
| NEATBrainS15 | NEATBrainS15: Neonatal Brain Structure Segmentation | 2015.09 | MICCAI Challenge | Project | |
| PDDCA | Public Domain Database for Computational Anatomy: Head and Neck | 2015.09 | MICCAI Challenge | Project | |
| HVSMR 2016 | HVSMR 2016: Whole Heart and Great Vessel Segmentation Challenge | 2016.07 | MICCAI Challenge | Paper | Project |
| MSSEG 2016 | Objective Evaluation of Multiple Sclerosis Lesion Segmentation using a Data Management and Processing Infrastructure | 2016.10 | MICCAI Challenge/Nature | Paper | Project |
| PROSTATEx | PROSTATEx: PROSTATE MR Image Dataset With Prostate Cancer Annotations | 2016.10 | SPIE-AAPM-NCI PROSTATEx Challenge | Project | |
| WMH | WMH Segmentation Challenge: White Matter Hyperintensity Segmentation in Brain MR | 2017.03 | MICCAI Challenge | Paper | Project |
| LGG-1p19qDeletion | LGG-1p19qDeletion: Low-Grade Glioma MRI with Genomic Annotations | 2017.03 | TCIA Collection | Project | |
| PROSTATEx-2 | PROSTATEx-2: Lesion Classification Challenge | 2017.06 | AAPM Grand Challenge | Project | |
| ACDC | Automatic Cardiac Diagnosis Challenge | 2017.09 | STACOM / MICCAI | Paper | Project |
| RETOUCH | RETOUCH: Retinal OCT Fluid Segmentation Challenge | 2017.09 | MICCAI Challenge | Paper | Project |
| ROCC | ROCC: Retinal OCT Classification Challenge | 2017.09 | MICCAI Challenge | Project | |
| iSeg2017 | iSeg-2017: Infant Brain MRI Segmentation Challenge | 2017.09 | MICCAI Challenge | Paper | Project |
| DeepLesion | DeepLesion: automated mining of large-scale lesion annotations and universal lesion detection in CT | 2017.10 | JMI / arXiv | Paper | Project |
| LUNA 16 | Validation, comparison, and combination of algorithms for automatic detection of pulmonary nodules in computed tomography images: the LUNA 16 challenge | 2017.12 | Medical Image Analysis | Paper | Project |
| Mandibular-CT-Dataset | Mandibular CT Dataset Collection for 3D Reconstruction and Segmentation | 2018.03 | figshare | Paper | Project |
| FUMPE | Computer-aided detection of pulmonary embolism in CT | 2018.03 | arXiv / Kaggle | Project | |
| ISLES 2018 | ISLES 2018 – Ischemic Stroke Lesion Segmentation | 2018.09 | MICCAI Challenge | Paper | Project |
| MRBrainS18 | MRBrainS18: MR Brain Segmentation Challenge 2018 | 2018.09 | MICCAI Challenge | Project | |
| Atrial Segmentation Challenge | 2018 Atrial Segmentation Challenge | 2018.09 | MICCAI Challenge | Project | |
| IVDM3Seg | IVDM3Seg: Intervertebral Disc and Vertebrae Segmentation Challenge | 2018.09 | MICCAI Challenge | Project | |
| MRNet | MRNet: Knee MRI Dataset for Abnormality Detection | 2018.09 | NIPS Workshop | Project | |
| OCT Glaucoma Detection | Glaucoma Detection in 3D Spectral-Domain OCT | 2018.10 | Sci Rep | Project | |
| BraTS | Brain Tumor Segmentation (BraTS) Challenge | 2018.11 | MICCAI Challenge (series) | Paper | Project |
| fastMRI | fastMRI: A Publicly Available Raw k-Space and DICOM Dataset of Knee and Brain MR Images | 2018.11 | MRM | Paper | Project |
| LiTS | Liver Tumor Segmentation (LiTS) Challenge | 2019.01 | MICCAI Challenge | Paper | Project |
| OASIS-3 | OASIS-3: Longitudinal Neuroimaging, Clinical, and Cognitive Dataset for Normal Aging and Alzheimer Disease | 2019.01 | Sci Data | Paper | Project |
| MM-WHS | MM-WHS: Multi-Modality Whole Heart Segmentation | 2019.02 | MICCAI Challenge | Paper | Project |
| CHAOS CT-MRI | CHAOS - Combined (CT-MR) Healthy Abdominal Organ Segmentation | 2019.02 | ISBI Challenge | Paper | Project |
| KiTS19 | KiTS19: Kidney Tumor Segmentation Challenge | 2019.04 | MICCAI Challenge | Paper | Project |
| AAPM-RT-MAC | AAPM RT-MAC: MR-only based Radiotherapy in Head and Neck | 2019.07 | AAPM Challenge | Paper | Project |
| iSeg-2019 | iSeg-2019: Infant Brain MRI Segmentation Challenge | 2019.09 | MICCAI Challenge | Paper | Project |
| SegTHOR | SegTHOR: Segmentation of thoracic organs at risk in CT images | 2019.09 | Physica Medica | Paper | Project |
| VerSe20 | VerSe 2020: Vertebral Segmentation Challenge at MICCAI | 2020.01 | MICCAI Challenge | Project | |
| VerSe19 | VerSe 2019: Vertebral Segmentation Challenge at MICCAI | 2020.01 | MICCAI Challenge | Paper | Project |
| COVID-19-CT-Seg | COVID-19 CT lung and infection segmentation dataset | 2020.04 | zenodo | Project | |
| M&Ms | M&Ms: Multi-Centre, Multi-Vendor & Multi-Disease Cardiac MR Segmentation Challenge | 2020.05 | MICCAI Challenge | Project | |
| CTPelvic1K | CTPelvic1K: A Large-Scale Pelvic CT Dataset for Multi-Task Parsing | 2020.06 | arXiv | Paper | Project |
| Prostate MR Segmentation Dataset (SAML) | Federated Domain Generalization on Medical Image Segmentation via Episodic Learning in Continuous Frequency Space | 2020.09 | MICCAI | Project | |
| EMIDEC | EMIDEC 2020: Myocardial Infarction Detection, Segmentation and Classification | 2020.09 | MICCAI Challenge | Paper | Project |
| KNOAP2020 | KNOAP2020: Knee Osteoarthritis Progression Prediction Challenge | 2020.09 | MICCAI Challenge | Project | |
| Learn2Reg Lung CT | Learn2Reg 2020: Lung CT Registration | 2020.09 | MICCAI Challenge | Project | |
| Learn2Reg Abdomen CT-CT | Learn2Reg 2020: Abdominal CT-CT Registration | 2020.09 | MICCAI Challenge | Project | |
| RibFrac2020 | RibFrac: Rib Fracture Detection and Classification Challenge | 2020.10 | MICCAI Challenge | Project | |
| HECKTOR 2020 | HECKTOR 2020: Segmentation of Head and Neck Tumor in PET/CT | 2020.11 | MICCAI Challenge | Project | |
| CT-ORG | CT-ORG, a new dataset for multiple organ segmentation in computed tomography | 2020.11 | Nature | Paper | Project |
| RAD-ChestCT | Machine-Learning-Based Multiple Abnormality Prediction with Large-Scale Chest Computed Tomography Volumes | 2021.01 | Medical Image Analysis | Paper | Project |
| Eye OCT Datasets (3D) | 3D Retinal OCT Classification and Segmentation Dataset | 2021.01 | Tianchi | Project | |
| HECKTOR 2021 | HECKTOR 2021: Head and Neck Tumor Segmentation and Outcome Prediction | 2021.05 | MICCAI Challenge | Project | |
| CTSpine1K | CTSpine1K: A Large-Scale Dataset for Spine Parsing in CT | 2021.07 | arXiv | Project | |
| MSSEG-2 | MSSEG-2 challenge: Multiple Sclerosis Lesion Segmentation at 7T and 3T MRI | 2021.07 | NeuroImage Clin | Project | |
| FLARE21 | FLARE 2021: A Challenge on Abdominal Multi-organ Segmentation | 2021.09 | MICCAI Challenge | Project | |
| QUBIQ2021 3D CT | QUBIQ 2021: Quantification of Uncertainty in Biomedical Image Quantification | 2021.09 | MICCAI Challenge | Project | |
| M&Ms-2 | M&Ms-2: Multi-Domain Cardiac MR Segmentation | 2021.09 | MICCAI Challenge | Project | |
| Learn2Reg Abdomen MR-CT | Learn2Reg 2021: Abdominal MR-CT Multi-Modal Registration | 2021.09 | MICCAI Challenge | Project | |
| CrossMoDA2021 | CrossMoDA 2021: Unsupervised Domain Adaptation for Cross-Modality Vestibular Schwannoma Segmentation | 2021.09 | MICCAI Challenge | Project | |
| WORD | WORD: A Whole-Organ CT Dataset for Robust Multi-Organ Segmentation | 2021.10 | arXiv | Paper | Project |
| MedMNIST v2 | MedMNIST v2 -- A large-scale lightweight benchmark for 2D and 3D biomedical image classification | 2021.10 | Nature | Paper | Project |
| CADA | CADA: Cerebral Aneurysm Detection and Analysis Challenge | 2022.04 | MICCAI Challenge | Project | |
| CADA-AS | CADA-AS: Aneurysm Segmentation Challenge | 2022.04 | MICCAI Challenge | Project | |
| CADA-RRE | CADA-RRE: Rupture Risk Estimation for Cerebral Aneurysms | 2022.04 | MICCAI Challenge | Project | |
| TotalSegmentator | TotalSegmentator: robust segmentation of 104 anatomic structures in CT images | 2022.06 | arXiv | Paper | Project |
| AMOS | AMOS: A Large-Scale Abdominal Multi-Organ Benchmark for Versatile Medical Image Segmentation | 2022.06 | NeurIPS 2022 | Paper | Project |
| MSD | The medical segmentation decathlon | 2022.07 | Nature Communications | Paper | Project |
| AutoPET | The AutoPET Challenge: Automated Lesion Segmentation in Whole-Body FDG-PET/CT | 2022.07 | MICCAI Challenge (autoPET2022) | Project | |
| UPENN-GBM | UPENN-GBM: Multi-modal MRI Dataset for Glioblastoma Segmentation | 2022.07 | TCIA Collection | Project | |
| KiPA22 | KiPA22: Kidney PArametric segmentation in contrast-enhanced CT | 2022.08 | MICCAI Challenge | Project | |
| OLIVES | OLIVES: A 3D OCT Dataset for Longitudinal Retinal Imaging | 2022.09 | arXiv | Project | |
| PI-CAI | PI-CAI: Prostate Imaging–Cancer AI Challenge | 2022.09 | MICCAI Challenge | Project | |
| LAScarQS 2022 | LAScarQS 2022: Left Atrial Scar Quantification and Segmentation Challenge | 2022.09 | MICCAI Challenge | Project | |
| CrossMoDA2022 | CrossMoDA 2022: Domain Adaptation for Vestibular Schwannoma Segmentation and Koos Grading | 2022.09 | MICCAI Challenge | Project | |
| FeTA 2022 | FeTA 2022: Fetal Brain Tissue Segmentation at MICCAI | 2022.09 | MICCAI Challenge | Project | |
| COSMOS 2022 | COSMOS 2022: Carotid Artery Vessel Wall Segmentation | 2022.09 | MICCAI Challenge | Project | |
| cSeg-2022 | cSeg 2022: Cerebellum Segmentation Challenge | 2022.09 | MICCAI Challenge | Project | |
| ISLES 2022 | ISLES 2022 – Acute and Subacute Ischemic Stroke Lesion Segmentation | 2022.09 | MICCAI Challenge | Project | |
| InSTANCE2022 | InSTANCE 2022: Intracranial Hemorrhage Segmentation Challenge | 2022.09 | MICCAI Challenge | Paper | Project |
| Learn2Reg NLST | Learn2Reg 2022: Thoracic CT Registration with NLST | 2022.09 | MICCAI Challenge | Project | |
| Shifts Challenge 2022 | Shifts 2022: Distribution Shifts in Multiple Sclerosis Lesion Segmentation | 2022.09 | MICCAI Challenge | Paper | Project |
| HECKTOR 22 | Overview of the HECKTOR challenge at MICCAI 2022: automatic head and neck tumor segmentation and outcome prediction in PET/CT | 2023 | MICCAI 2022 | Paper | Project |
| LNDb | LNDb challenge on automatic lung cancer patient management | 2023.03 | Medical Image Analysis | Paper | Project |
| Semi-TeethSeg | Semi-TeethSeg: Semi-Supervised 3D Tooth Segmentation in CBCT/CT | 2023.04 | arXiv | Project | |
| PARSE22 | Efficient automatic segmentation for multi-level pulmonary arteries: The parse challenge | 2023.04 | arXiv | Paper | Project |
| STAGE | STAGE: Longitudinal OCT Dataset for Glaucoma Progression | 2023.04 | Dataset | Project | |
| KiTS21 | The kits21 challenge: Automatic segmentation of kidneys, renal tumors, and renal cysts in corticomedullary-phase ct | 2023.07 | arXiv | Paper | Project |
| AutoPET II | AutoPET-II: Ensemble-based Uncertainty-Aware Lesion Segmentation in Multi-Center FDG-PET/CT | 2023.07 | MICCAI Challenge (AutoPET-II) | Project | |
| MedMD | Towards Generalist Foundation Model for Radiology by Leveraging Web-scale 2D&3D Medical Data | 2023.08 | arXiv | Paper | Project |
| ULS23 | ULS23 Challenge: Universal Lesion Segmentation in CT for Oncological Imaging | 2023.08 | MICCAI Challenge | Project | |
| SegRap2023 | SegRap 2023: Nasopharyngeal Carcinoma Radiotherapy Segmentation Challenge | 2023.08 | MICCAI Challenge | Project | |
| LNQ2023 | LNQ2023: Lymph Node Quantification in Chest CT | 2023.08 | MICCAI Challenge | Project | |
| FLARE23 | FLARE 2023: A Federated Learning Challenge for Abdominal Multi-Organ Segmentation | 2023.09 | MICCAI Challenge | Project | |
| CrossMoDA2023 | CrossMoDA 2023: Multi-Center Domain Adaptation for VS Segmentation | 2023.09 | MICCAI Challenge | Project | |
| ATLAS2023 | ATLAS 2023: Liver Tumor Segmentation Challenge | 2023.09 | MICCAI Challenge | Paper | Project |
| SMILE-UHURA2023 | SMILE-UHURA 2023: Small Vessel Disease Lesion Segmentation | 2023.09 | MICCAI Challenge | Paper | Project |
| CAS2023 | CAS 2023: Brain Structure Segmentation Benchmark | 2023.09 | MICCAI Challenge | Project | |
| CROWN2023 | CROWN 2023: White Matter Hyperintensity and Other Pathology Classification | 2023.09 | MICCAI Challenge | Project | |
| SLCN | SLCN: Structural Lesion and Connectivity in Neurodevelopmental Disorders | 2023.09 | MICCAI Challenge | Project | |
| ToothFairy2023 | ToothFairy: 3D CBCT Dataset for Inferior Alveolar Nerve Segmentation | 2023.09 | MICCAI Challenge | Project | |
| XPRESS2023 | XPRESS 2023: X-ray Phase-Contrast CT Neuroanatomy Segmentation | 2023.09 | MICCAI Challenge | Paper | Project |
| Learn2Reg ThoraxCBCT | Learn2Reg 2023: Thorax CBCT/FBCT Deformable Registration | 2023.09 | MICCAI Challenge | Project | |
| TDSC-ABUS2023 | TDSC-ABUS2023: Automated Breast Ultrasound Segmentation Challenge | 2023.09 | MICCAI Challenge | Paper | Project |
| MVSeg-3DTEE2023 | MVSeg-3DTEE2023: Mitral Valve Segmentation from 3D TEE | 2023.09 | MICCAI Challenge | Project | |
| RegPro2023 | RegPro 2023: Prostate MR-US Registration Challenge | 2023.09 | MICCAI Challenge | Project | |
| KiTS23 | KiTS23: Kidney and Kidney Tumor Segmentation with Comprehensive Clinical Annotations | 2023.10 | arXiv | Project | |
| WBMR-NF | WBMR-NF: Whole-Body MRI for Neurofibromatosis | 2023.11 | Dataset | Project | |
| GAMMA | GAMMA Challenge: Glaucoma Assessment with Multi-Modality Data | 2023.12 | MICCAI Challenge | Paper | Project |
| ATM'22 | ATM'22: Airway Tree Modeling in Thoracic CT | 2023.12 | MICCAI Challenge | Paper | Project |
| INSPECT | INSPECT: A Multimodal Dataset for Pulmonary Embolism Diagnosis and Prognosis | 2023.12 | NeurIPS 2023 | Paper | Project |
| HaN-Seg | HaN-Seg 2023: Head and Neck Organ at Risk Segmentation Challenge | 2024 | MICCAI Challenge | Paper | Project |
| VALDO | Where is VALDO? Vascular Lesions Detection and Segmentation Challenge | 2024.01 | MICCAI Challenge | Paper | Project |
| BIMCV-R | BIMCV-R: Large-Scale Thoracic CT Reconstruction Benchmark | 2024.01 | MICCAI24 | Paper | Project |
| IXI | Information eXtraction from Images (IXI) Dataset | 2024.01 | Dataset | Project | |
| RAOS | RAOS: A Large-Scale Radiotherapy Abdominal Organ Segmentation Dataset | 2024.01 | MICCAI24 | Paper | Project |
| ISLES 2024 | Ischemic Stroke Lesion Segmentation Challenge 2024 (ISLES 2024) | 2024.02 | MICCAI Challenge | Project | |
| AbdomenAtlas | AbdomenAtlas-20K: A Large-Scale Benchmark for Abdominal Multi-Organ Segmentation in CT | 2024.02 | arXiv | Paper | Project |
| OpenMind | OpenMind: Large-Scale Head-and-Neck MR Dataset for Foundation Models | 2024.02 | arXiv | Project | |
| TriALS2024 | TriALS 2024: Liver Tumor Segmentation and Outcome Prediction – Task 1 | 2024.03 | MICCAI24 | Project | |
| LAScarQS++ 2024 | LAScarQS++ 2024: Multi-Center Atrial Scar Segmentation | 2024.03 | CARE Workshop (MICCAI) | Project | |
| MyoPS | MyoPS: A Benchmark of Myocardial Pathology Segmentation Combining Three-Sequence Cardiac Magnetic Resonance Images# MyoPS: A Benchmark of Myocardial Pathology Segmentation Combining Three-Sequence Cardiac Magnetic Resonance Images | 2024.03 | CARE Workshop | Paper | Project |
| WHS++ 2024 | WHS++ 2024: Multi-Center Whole Heart Segmentation | 2024.03 | CARE Workshop | Project | |
| AMOS-MM | AMOS-MM: Multi-Phase Abdominal CT Benchmark for Translation and Synthesis | 2024.03 | arXiv | Paper | Project |
| CT2Rep | CT2Rep: Automated Radiology Report Generation for 3D Medical Imaging | 2024.03 | MICCAI 2024 | Paper | Project |
| TotalSegmentator MRI | TotalSegmentator MRI: Whole-body MRI Segmentation of 150 Structures | 2024.04 | arXiv | Paper | Project |
| RadGenome-ChestCT | RadGenome-Chest CT: a grounded vision-language dataset for chest CT analysis | 2024.04 | arXiv | Paper | Project |
| M3D | M3D: Advancing 3D Medical Image Analysis with Multi-Modal Large Language Models | 2024.04 | ICLR 2025 | Paper | Project |
| AIIB23 | AIIB23: Airway Inflammation Imaging Biomarkers Challenge | 2024.06 | MICCAI Challenge | Paper | Project |
| CT-3DRRG | Argus: Benchmarking and Enhancing Vision-Language Models for 3D Radiology Report Generation | 2024.06 | arXiv | Paper | — |
| RadGenome-Brain MRI | AutoRG-Brain: Grounded Report Generation for Brain MRI | 2024.10 | MICCAI 2024 | Paper | Project |
| MedShapeNet | MedShapeNet -- A Large-Scale Dataset of 3D Medical Shapes for Computer Vision | 2024.12 | Biomedizinische Technik | Paper | Project |
| RadA-BenchPlat | How well can modern LLMs act as agent cores in radiology environments? | 2024.12 | arXiv | Paper | |
| MedVL-CT69K | Large-scale and Fine-grained Vision-language Pre-training for Enhanced CT Image Understanding | 2025.01 | ICLR 2025 | Paper | Project |
| Triad | Triad: Vision Foundation Model for 3D Magnetic Resonance Imaging | 2025.02 | arXiv | Paper | |
| 3D-BrainCT | Towards a holistic framework for multimodal LLM in 3D brain CT radiology report generation | 2025.03 | Nat. Commun. | Paper | — |
| PENGWIN2024-Task1 | PENGWIN 2024: Pelvic Fracture Segmentation in Trauma CT | 2025.04 | MICCAI Challenge | Paper | Project |
| RibFrac | Deep rib fracture instance segmentation and classification from ct on the ribfrac challenge | 2025.04 | IEEE | Paper | Project |
| DeepTumorVQA | Are Vision Language Models Ready for Clinical Diagnosis? A 3D Medical Benchmark for Tumor-centric Visual Question Answering | 2025.05 | NeurIPS 2025 | Paper | Project |
| NOVA | NOVA: A Benchmark for Anomaly Localization and Clinical Reasoning in Brain MRI | 2025.05 | NeurIPS 2025 | Paper | |
| Lingshu | Lingshu: A Generalist Foundation Model for Unified Multimodal Medical Understanding and Reasoning | 2025.06 | arXiv | Paper | Project |
| ReXGroundingCT | ReXGroundingCT: A 3D Chest CT Dataset for Segmentation of Findings from Free-Text Reports | 2025.07 | arXiv | Paper | Project |
| ViPET-ReportGen | Toward a Vision-Language Foundation Model for Medical Data: Multimodal Dataset and Benchmarks for Vietnamese PET/CT Report Generation | 2025.12 | NeurIPS 2025 | Paper | Project |
| 3D-RAD | 3D-RAD: A Comprehensive 3D Radiology Med-VQA Dataset with Multi-Temporal Analysis and Diverse Diagnostic Tasks | 2025.12 | NeurIPS 2025 | Paper | Project |
| MR-RATE | MR-RATE: A Vision-Language Foundation Model and Dataset for Magnetic Resonance Imaging | 2026 | — | — | Project |
| CT-RATE | Generalist Foundation Models from a Multimodal Dataset for 3D Computed Tomography | 2026.02 | Nature | Paper | Project |
| CT-FlowBench | CT-FlowBench: Benchmark for CT interpretation workflow and tool-use | 2026.03 | arXiv | Paper | |
| Merlin | Merlin: A Vision Language Foundation Model for 3D Computed Tomography | 2026.03 | Nature | Paper | Project |
| Gastric-X | Gastric-X: A Multimodal Multi-Phase Benchmark Dataset for Advancing Vision-Language Models in Gastric Cancer Analysis | 2026.03 | CVIPPR 2026 | Paper | — |
| SpatialMed | Beyond Medical Diagnostics: How Medical Multimodal Large Language Models Think in Space | 2026.03 | arXiv | Paper | |
| BONBID-HIE2023 | BONBID-HIE 2023: Neonatal Hypoxic-Ischemic Encephalopathy Lesion Segmentation | 2026.04 | MICCAI Challenge | Paper | Project |
| SGMRI-VQA | Beyond a Single Frame: Multi-Frame Spatially Grounded Reasoning Across Volumetric MRI | 2026.04 | arXiv | Paper | |
| Curia-2 | Curia-2: Scaling Self-Supervised Learning for Radiology Foundation Models | 2026.04 | arXiv | Paper | |
| CT-SpatialVQA | Lost in Volume: The CT-SpatialVQA Benchmark for Evaluating Semantic-Spatial Understanding of 3D Medical Vision-Language Models | 2026.05 | arXiv | Paper | |
| Med-StepBench | Med-StepBench: A Hierarchical Reasoning Framework for Evaluating Hallucinations in Medical Vision-Language Models | 2026.05 | arXiv | Paper | |
| DeepTumorVQA-H | DeepTumorVQA: A Hierarchical 3D CT Benchmark for Stage-Wise Evaluation of Medical VLMs and Tool-Augmented Agents | 2026.05 | arXiv | Paper | |
| ABRA | ABRA: Agent Benchmark for Radiology Applications | 2026.05 | arXiv | Paper | |
| RadSaFE-200 | Safety and Accuracy Follow Different Scaling Laws in Clinical Large Language Models | 2026.05 | arXiv | Paper | |
| Oncology VQA Benchmark | Automated Report-Derived Oncology VQA Benchmark for Evaluating Vision-Language Models on 3D Medical Imaging | 2026.06 | arXiv | Paper | |
| Abdomen-NCCT Benchmark | A Multi-Center Benchmark for Abdominal Disease Diagnosis and Report Generation from Non-Contrast CT | 2026.06 | arXiv | Paper | |
| RadOT-Eval | RadOT-Eval: Auditable Structured-Evidence Transport for Radiology Report Evaluation | 2026.06 | arXiv | Paper | |
| ReportQA | ReportQA: QA-Based Radiology Report Evaluation | 2026.06 | arXiv | Paper | |
| CORTEX | CORTEX: A Structured Reasoning Benchmark for Trustworthy 3D Chest CT MLLMs | 2026.06 | arXiv | Paper | |
| MedCTA | MedCTA: A Benchmark for Clinical Tool Agents | 2026.06 | arXiv | Paper | |
| Lung CT FM Benchmark | Foundation Models vs. Radiomics for Lung Computed Tomography: A Benchmark of Feature Extractors, Classification Heads, and Segmentation Choices | 2026.07 | arXiv | Paper | Project |
| Brain Oncology 3D MRI-Text | Multi-LLM Collaborative MRI Report Generation for Visual Instruction Tuning in Brain Oncology | 2026.07 | arXiv | Paper | - |
| COBRA2026 | COBRA2026: a large-scale multicenter pelvic cone-beam computed tomography projection dataset | 2026.07 | arXiv | Paper | Project |
| GLI-AL | GLI-AL: A Multi-Modal Glioma MRI Label Resource with Unified Anatomy-Lesion Labels | 2026.07 | arXiv | Paper | Project |