SIBench/Awesome-Visual-Spatial-Reasoning

This is a project about visual spatial reasoning.

HTML

148

159 commits

updated Jul 27, 2026

See the code

README

Awesome Visual Spatial Reasoning

Songsong Yu*1,2, Yuxin Chen🌟*2, Hao Ju*3, Lianjie Jia*4, Fuxi Zhang4, Shaofei Huang3,
Yuhan Wu4, Rundi Cui4, Binghao Ran4, Zhang Zaibin4, Zhedong Zheng3, Zhipeng Zhang1,
Yifan Wang4, Lin Song2, Lijun Wang4, Yanwei Li✉️5, Ying Shan2, Huchuan Lu4,

1SJTU, 2ARC Lab, Tencent PCG, 3UM, 4DLUT, 5CUHK * Equal Contributions 🌟 Project Lead ✉️ Corresponding Author

🤗 Dataset    |   🌐 Leaderboard   |   📊 Survey    |   🎯 Code    |   📄 arXiv   |   🗺️ 📖 Interactive Survey Page (中/EN)

News and Updates

  • 🆕🔥✨26.5.6 - Added 4 new papers (2026.03~2026.04) including SpatiO, World2VLM, ReVSI, and Holi-Spatial.
  • 🆕🔥✨26.3.29 - Added 7 new papers (2026.03.22~2026.03.29) and launched 📖 Interactive Bilingual Survey Page covering 110+ papers with ZH/EN toggle, timeline, trend analysis, and benchmark summary.
  • 🆕🔥✨26.3.23 - Added 9 new papers (2025.10 ~ 2026.03) covering benchmarks, training methods, and spatial reasoning frameworks.
  • 📜📜📜25.9.23 - Preprint a survey article on visual spatial reasoning tasks.
  • 🎯🎯🎯25.9.23 - Release comprehensive evaluation results of mainstream models in visual spatial reasoning.
  • 🙌👏👐25.9.15 - Open-source evaluation data for visual spatial reasoning tasks.
  • 🤩🥳🤗25.9.15 - Open-source evaluation toolkit.
  • ✍️🦾💼25.6.28 - Collected the "Datasets" section.
  • 🏃🏃‍♀️🏃‍♂️25.6.16 - The "Awesome Visual Spatial Reasoning" project is now live!
  • 👏🕮💻25.6.12 - The project has conducted research and collected 100 relevant works.
  • 🙋‍♀️🙋‍♂️🙋25.6.10 - We launches a review project on visual spatial reasoning.

Open-source evaluation toolkit

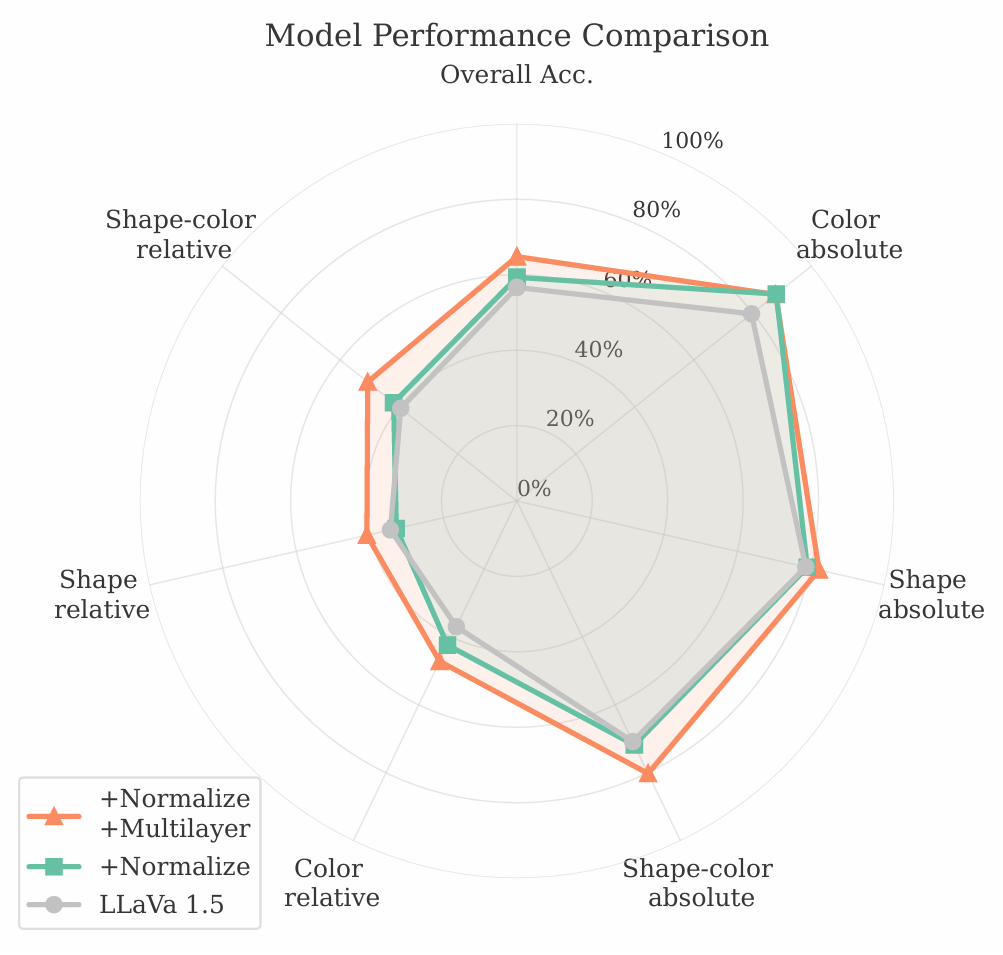
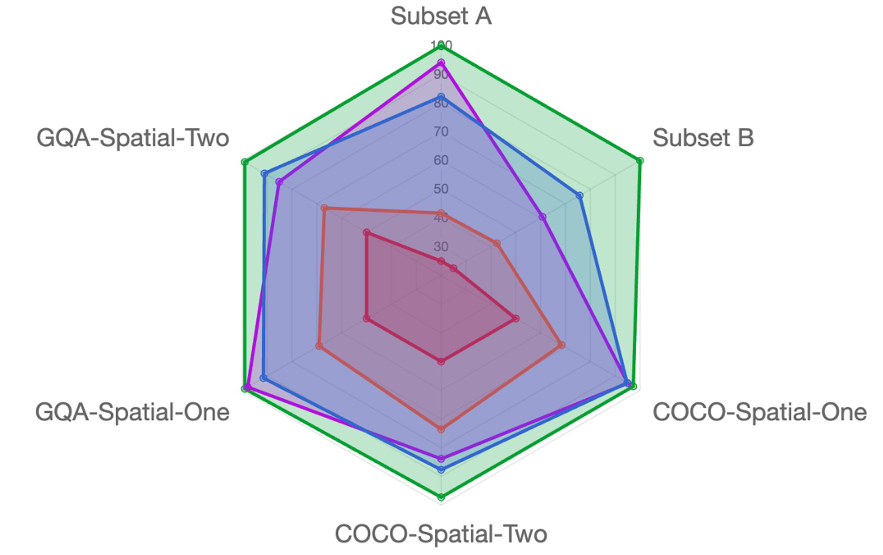
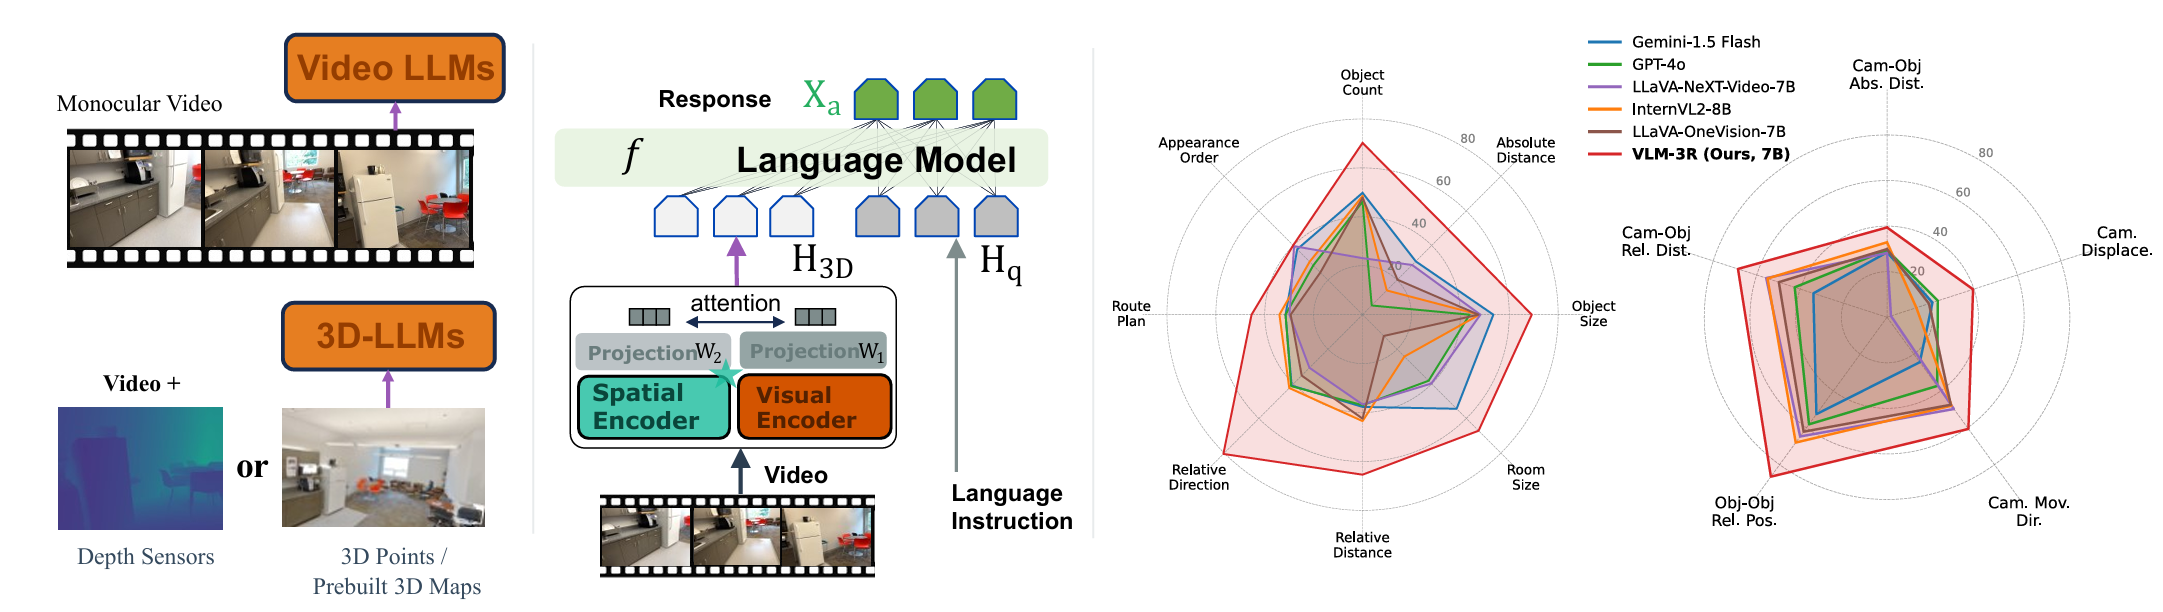
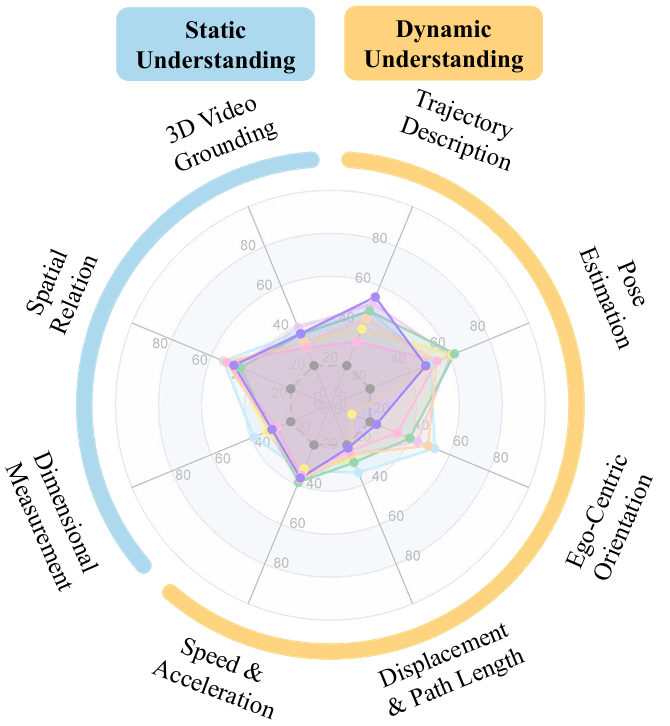
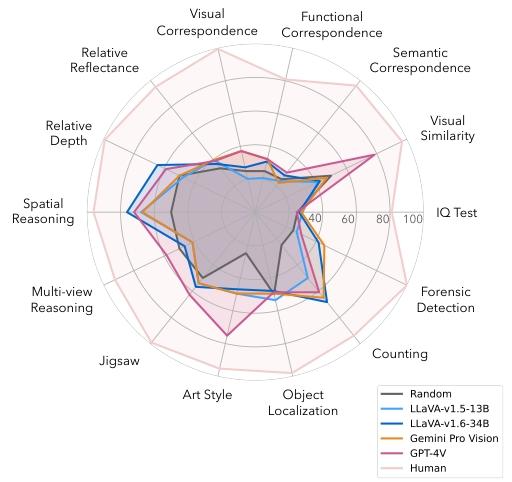
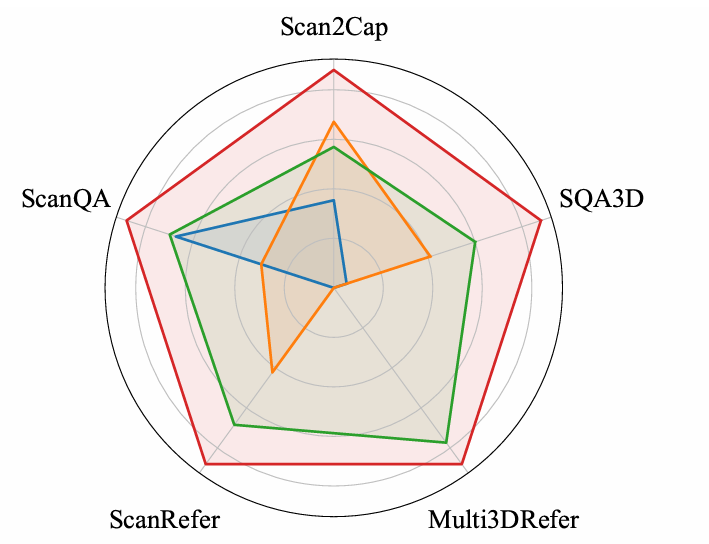
radar2.6

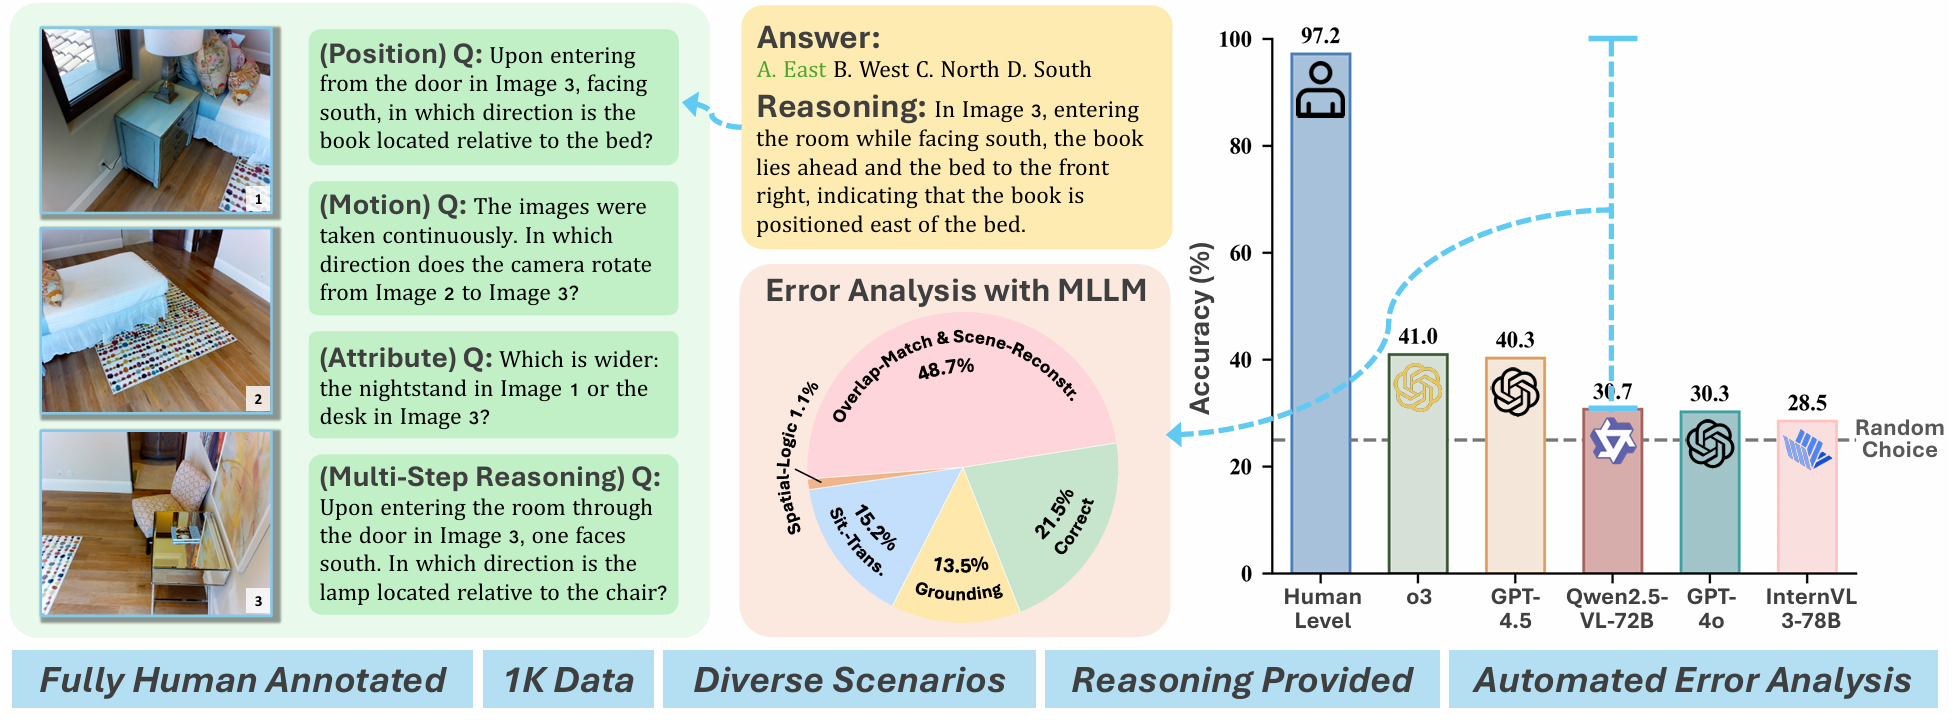
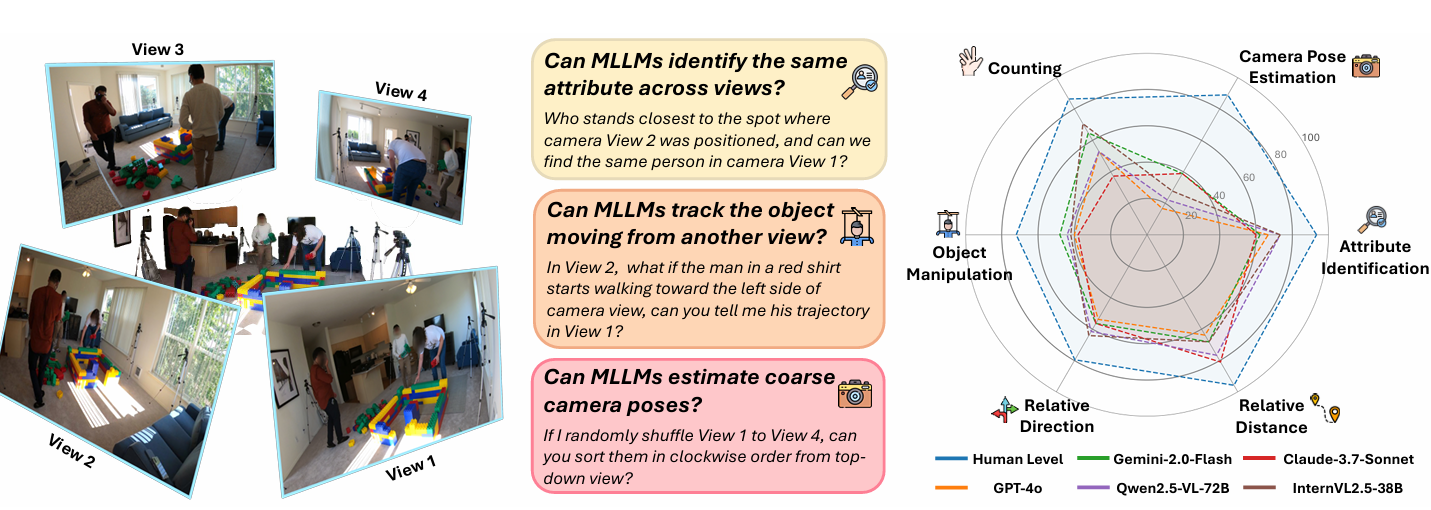
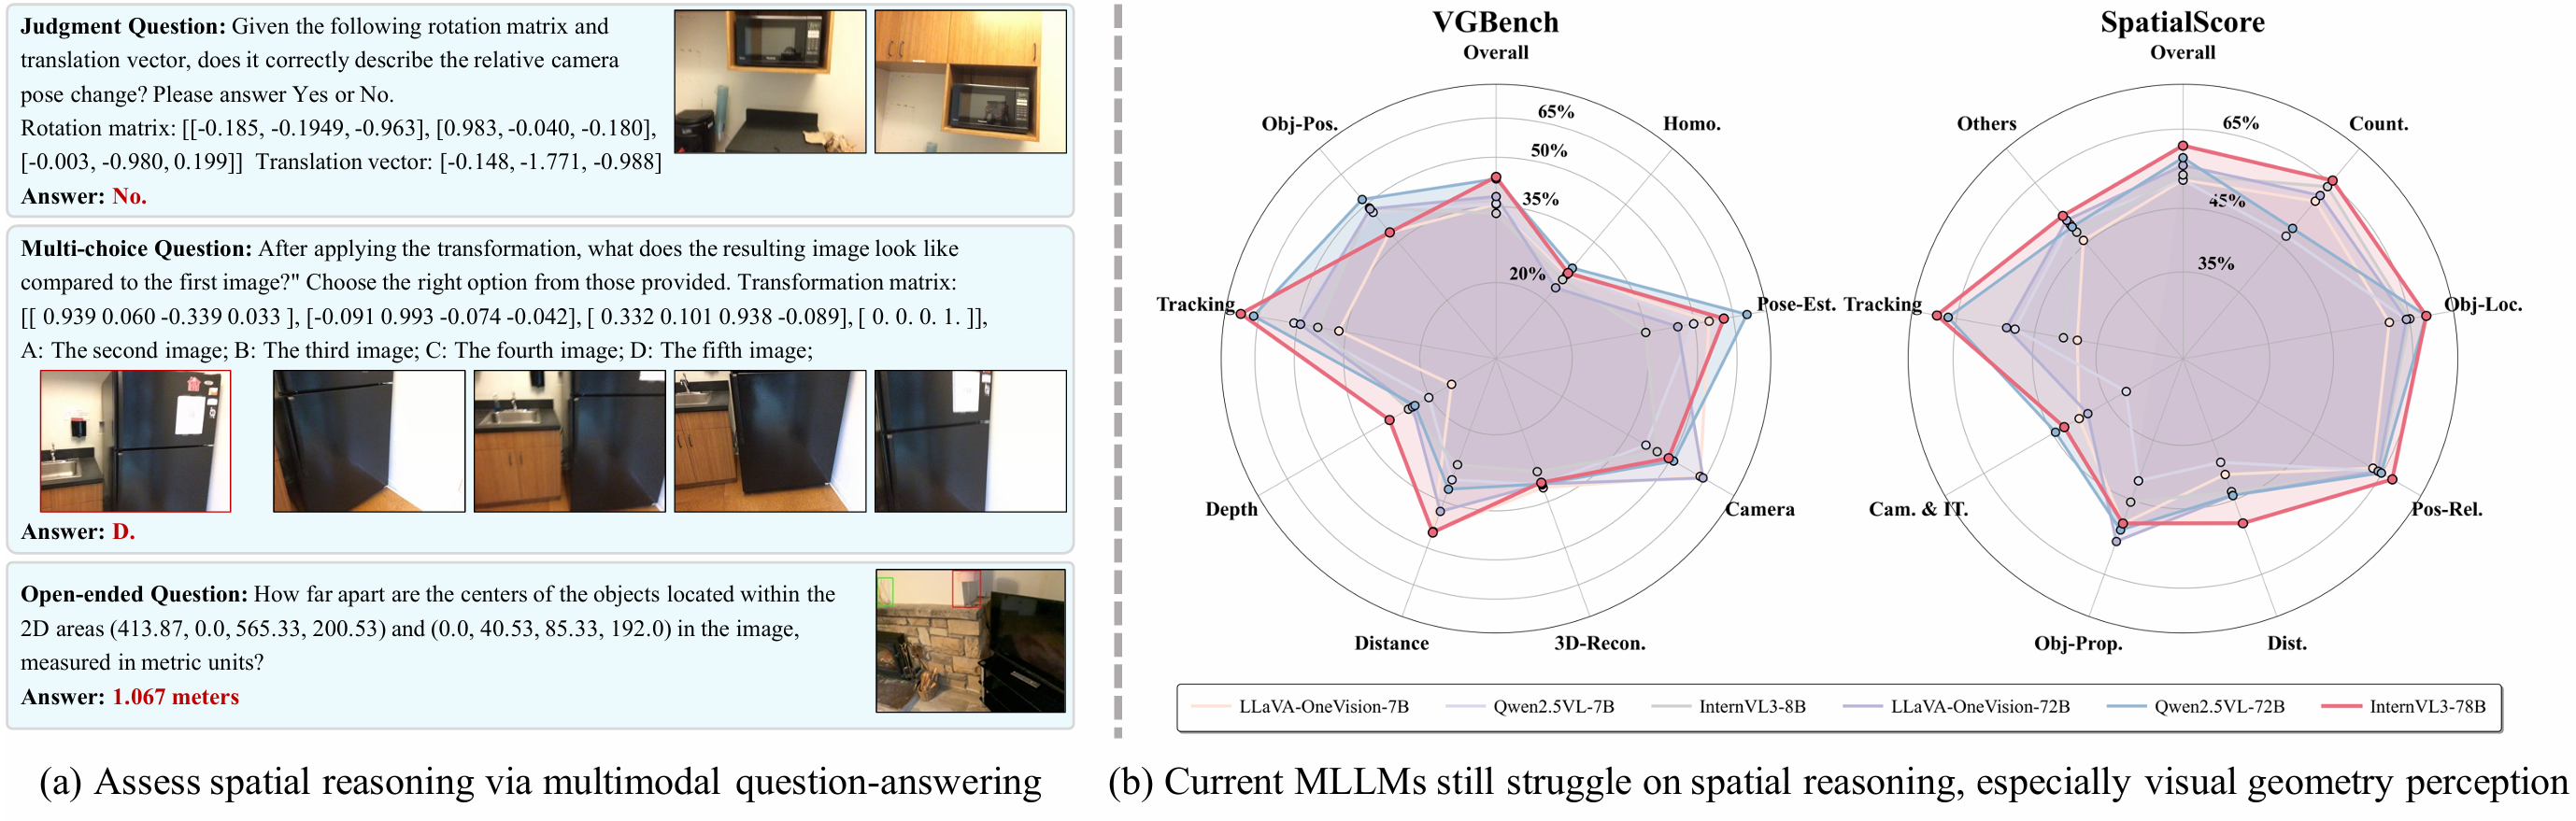
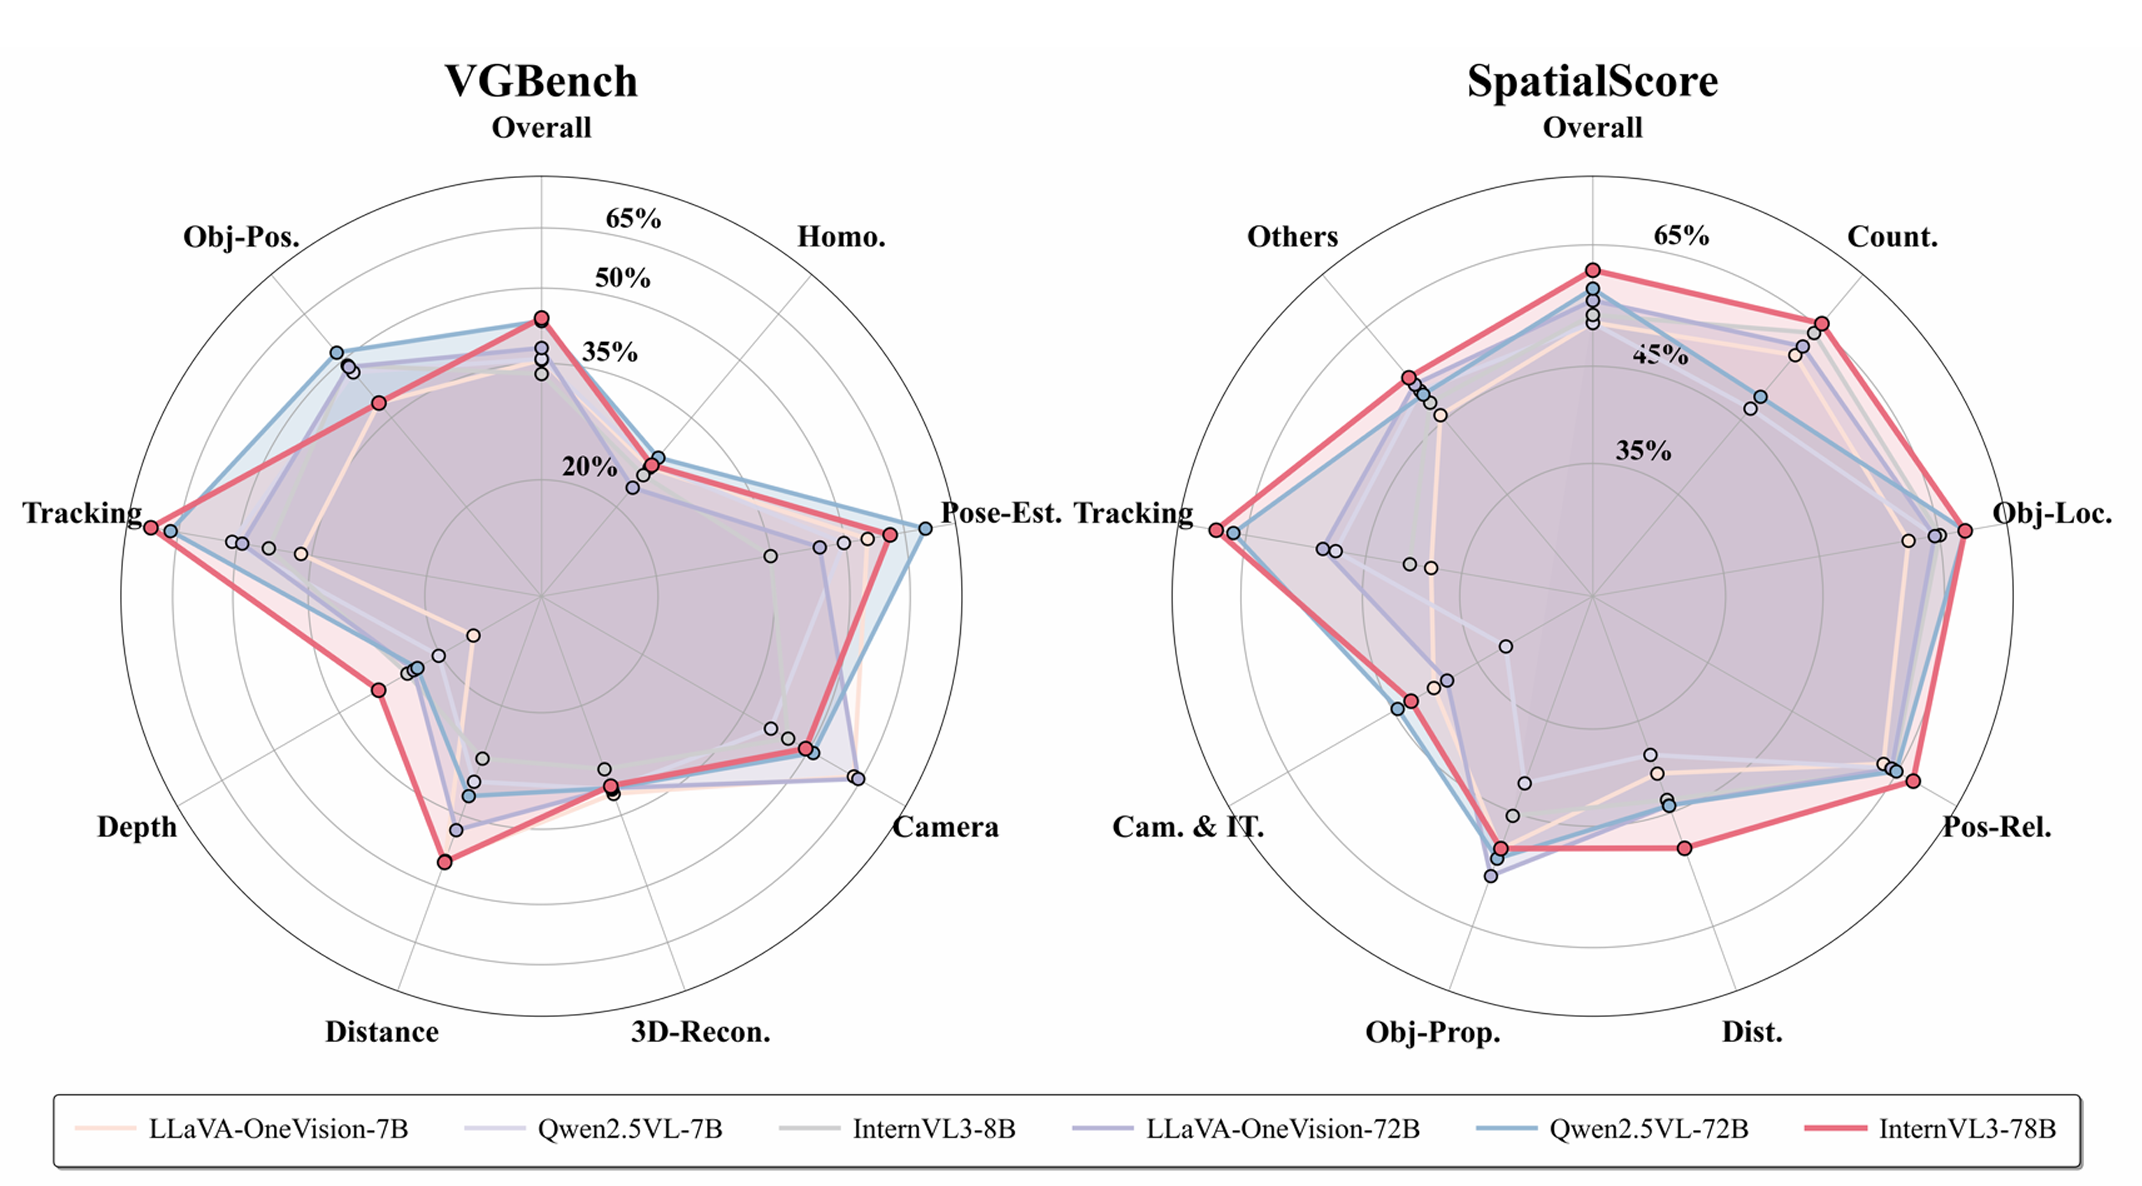
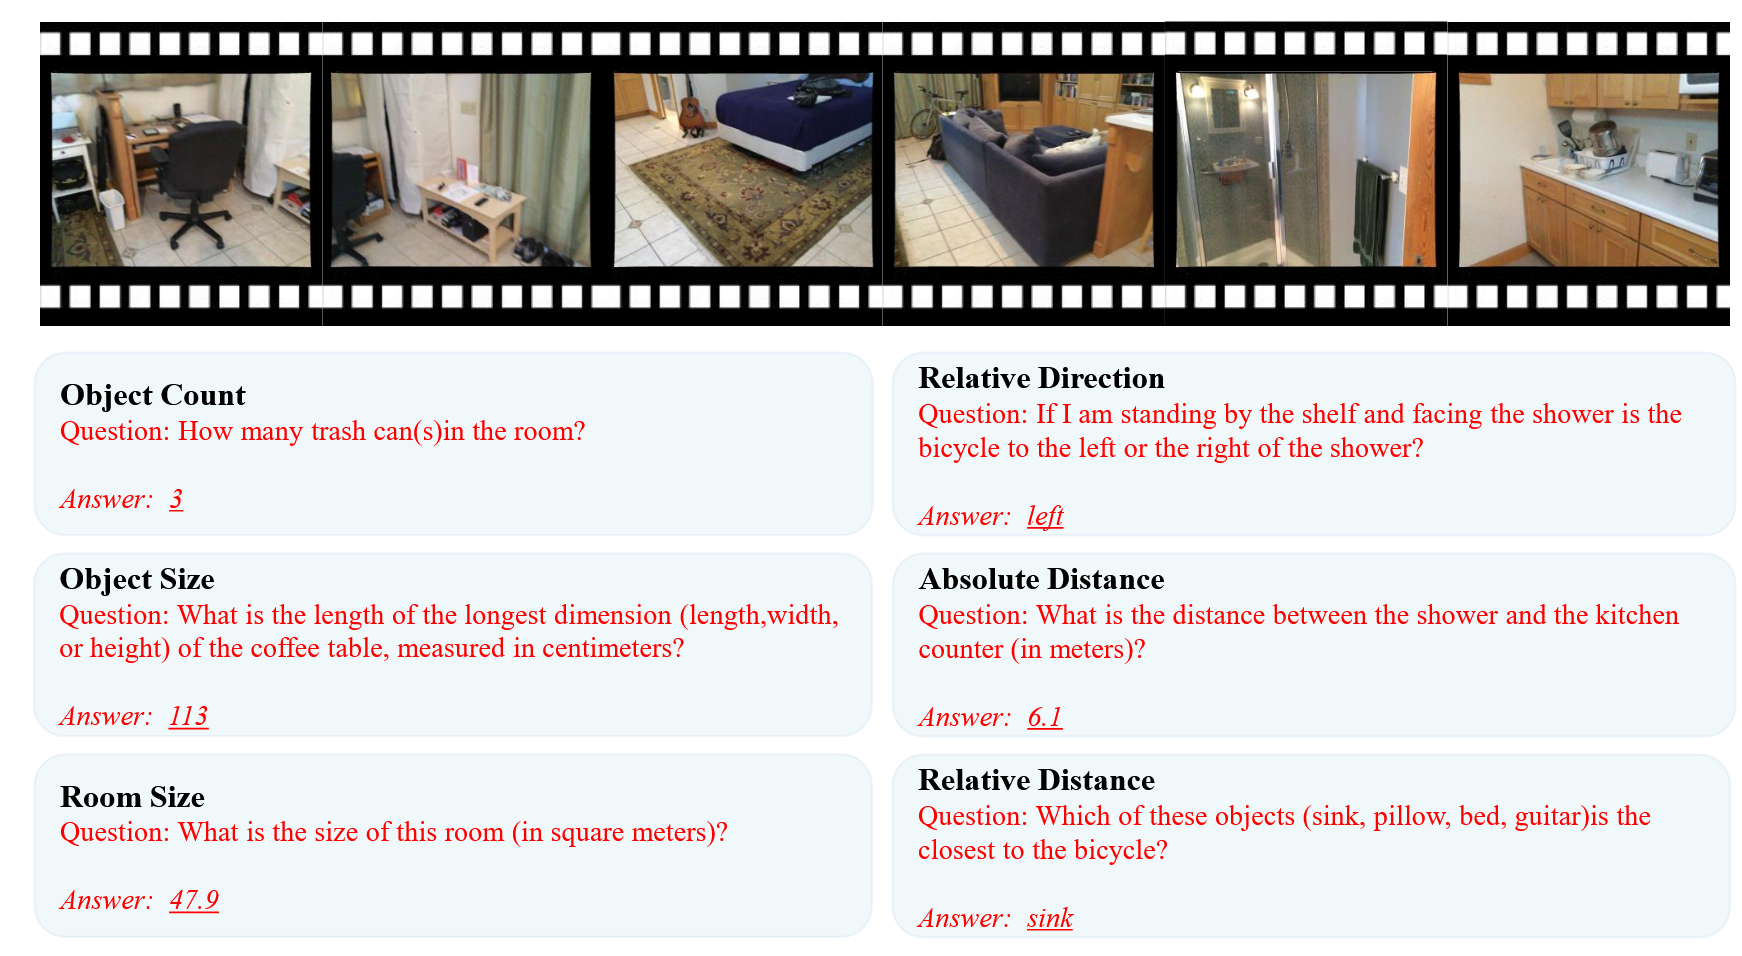
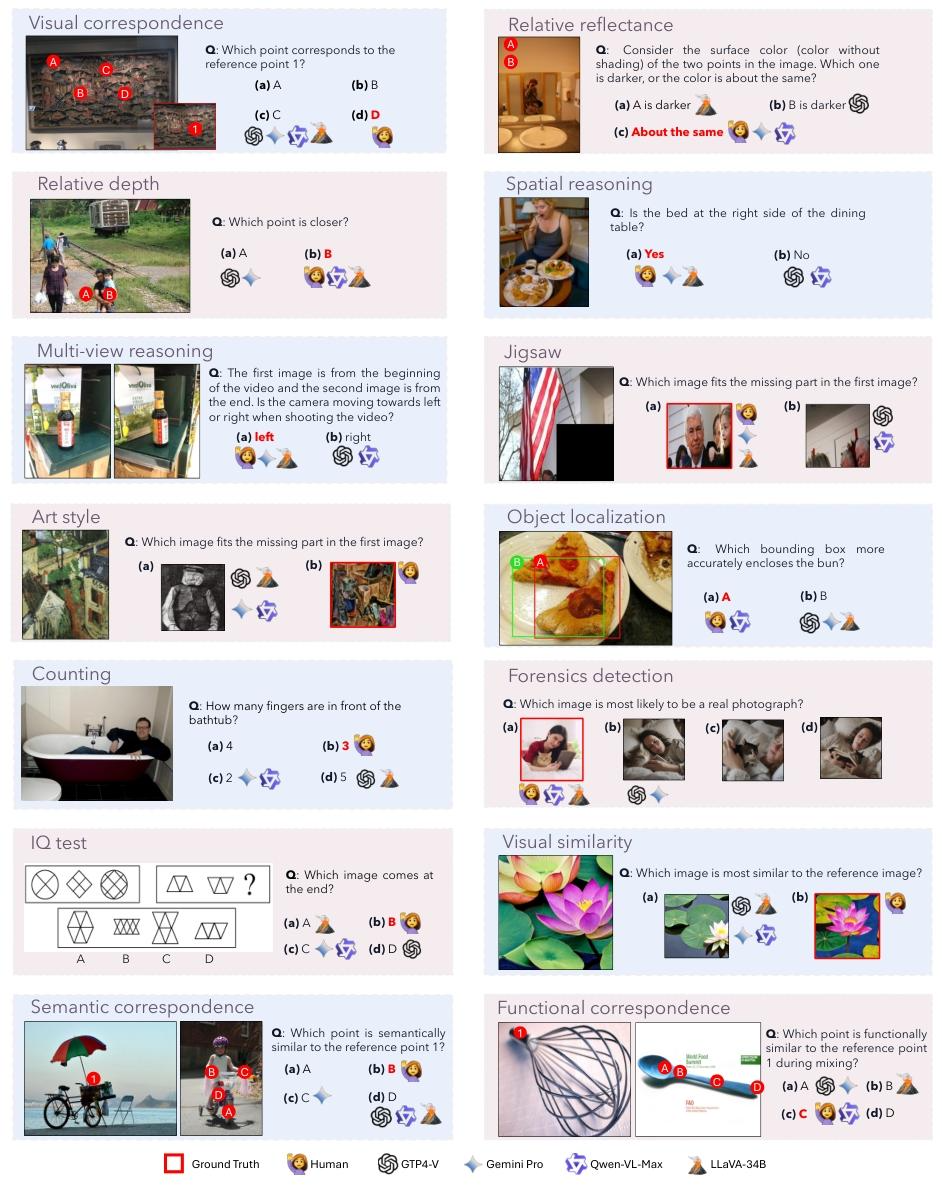
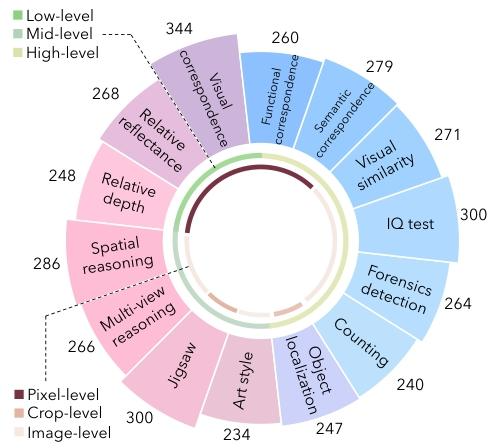
Evaluation of SOTA Models on 23 Visual Spatial Reasoning Tasks.

Code Usage:

- git clone https://github.com/song2yu/SIBench-VSR.git
- Refer to the README.md for more details

Contributing

We welcome contributions to this repository! If you would like to contribute, please follow these steps:

  • Fork the repository.
  • Create a new branch with your changes.
  • Submit a pull request with a clear description of your changes.

You can also open an issue if you have anything to add or comment.

Please feel free to contact us (SongsongYu203@163.com).

Overview

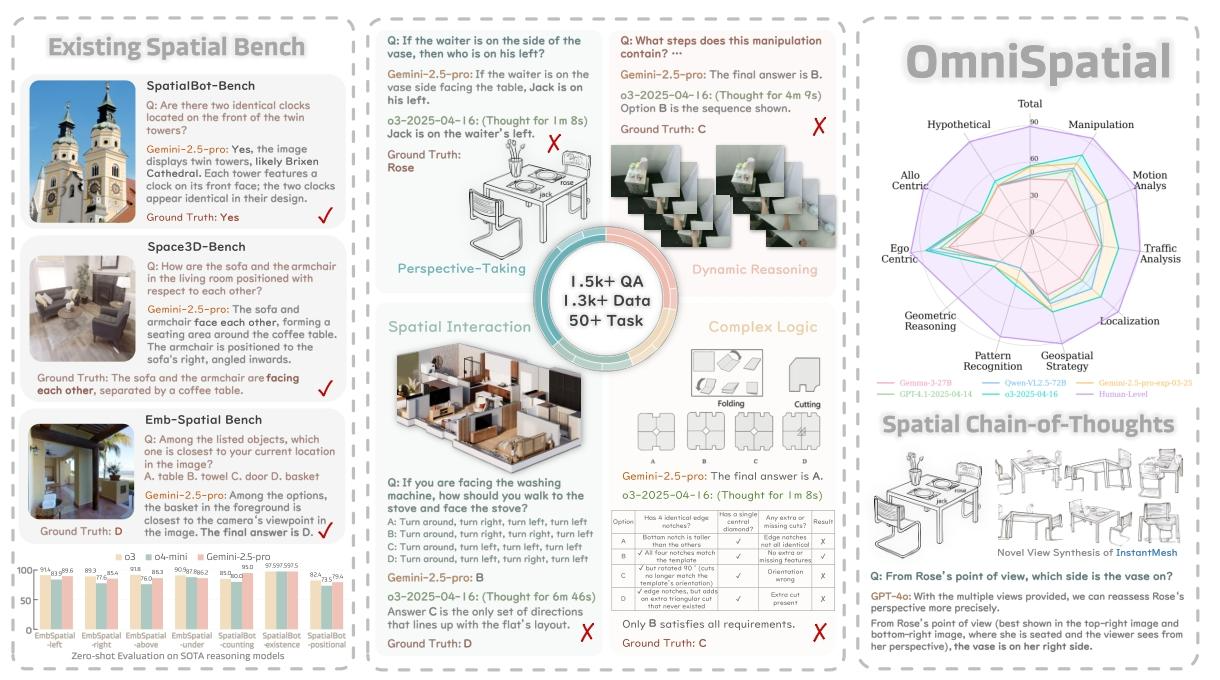
The research community is increasingly focused on the visual spatial reasoning (VSR) abilities of Vision-Language Models (VLMs). Yet, the field lacks a clear overview of its evolution and a standardized benchmark for evaluation. Current assessment methods are disparate and lack a common toolkit. This project aims to fill that void. We are developing a unified, comprehensive, and diverse evaluation toolkit, along with an accompanying survey paper. We are actively seeking collaboration and discussion with fellow experts to advance this initiative.

Task Explanation

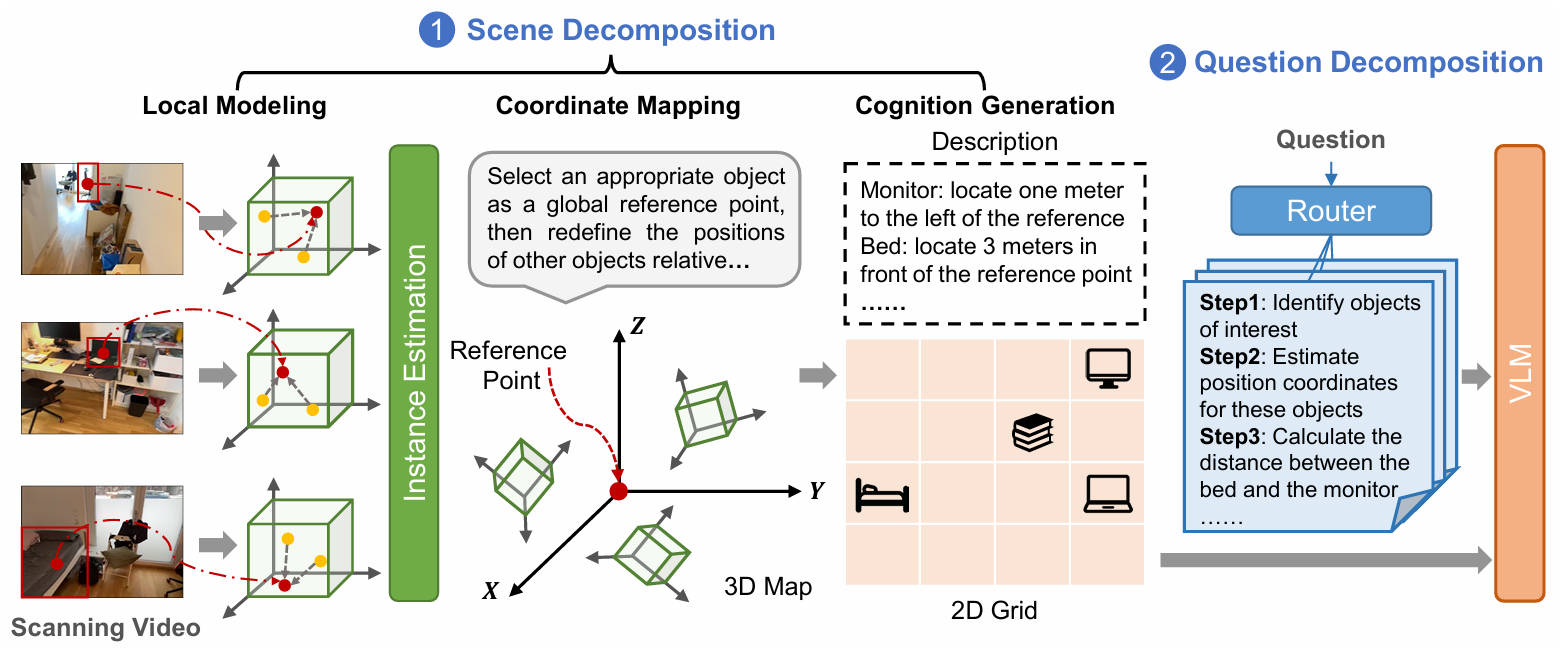
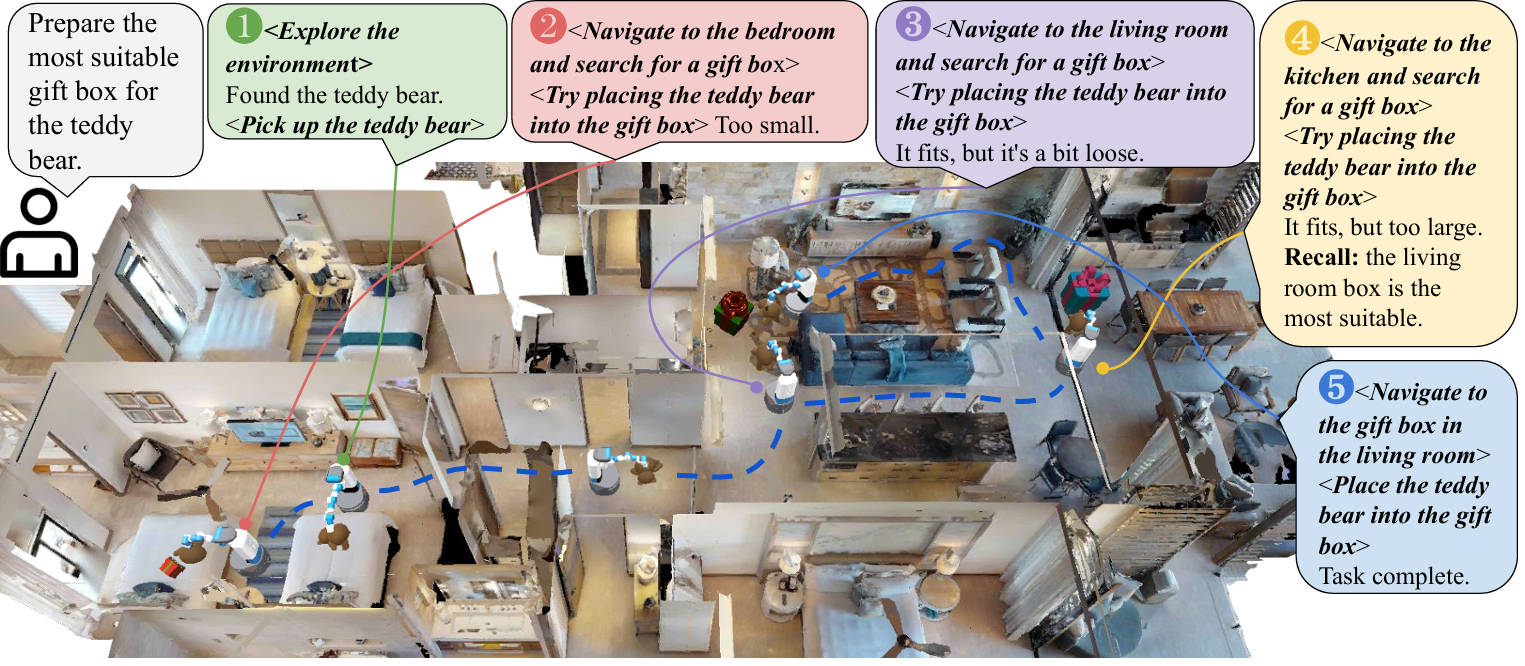
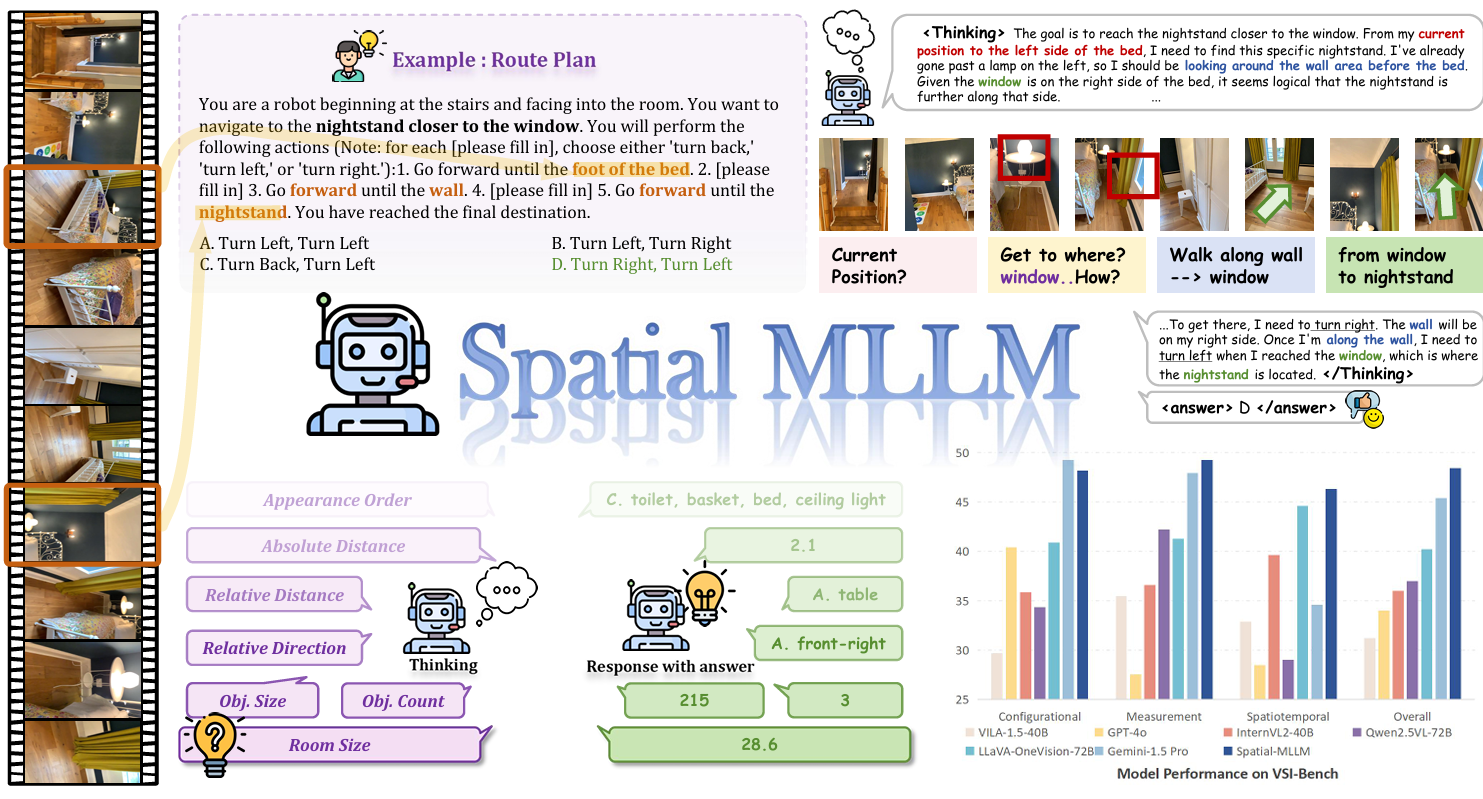
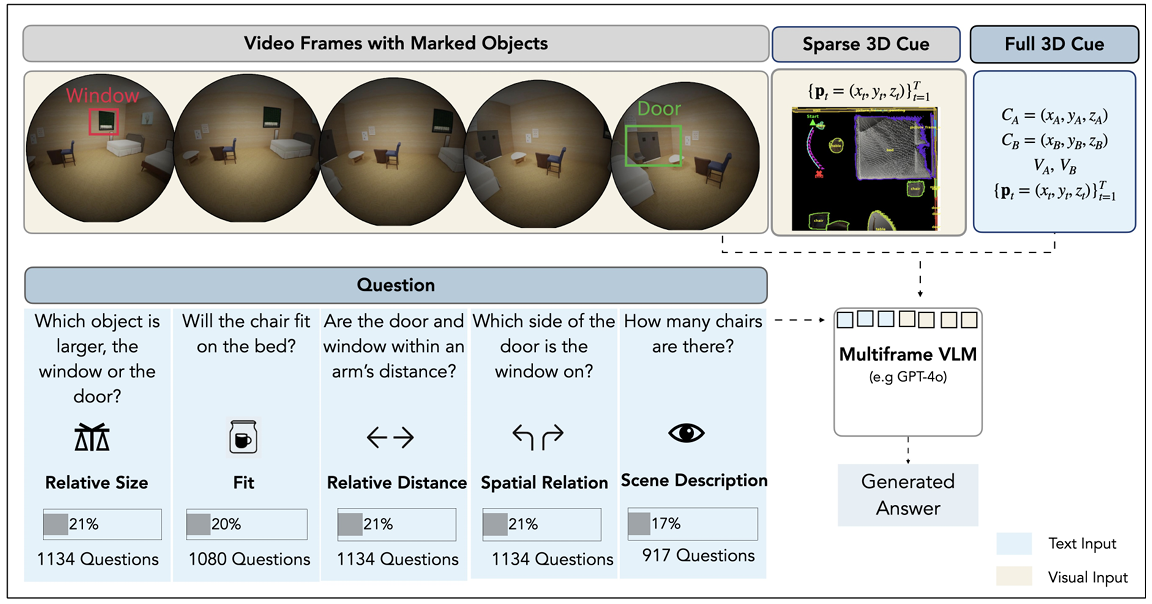
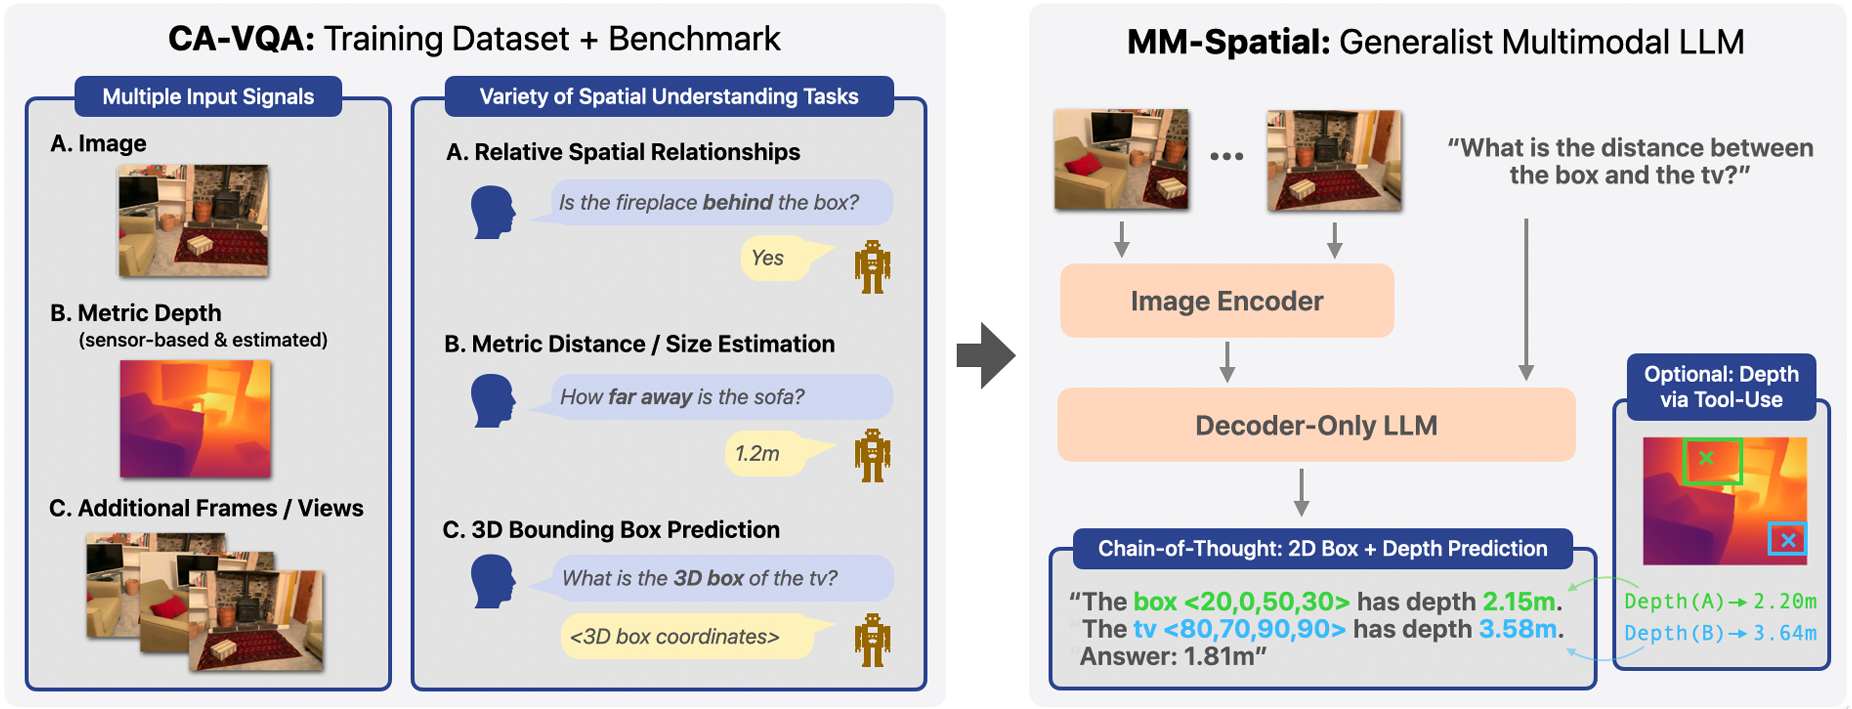
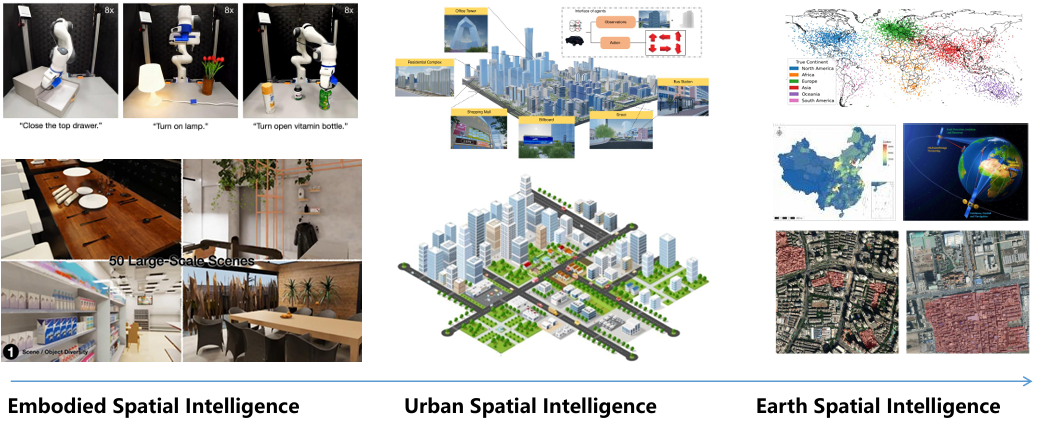
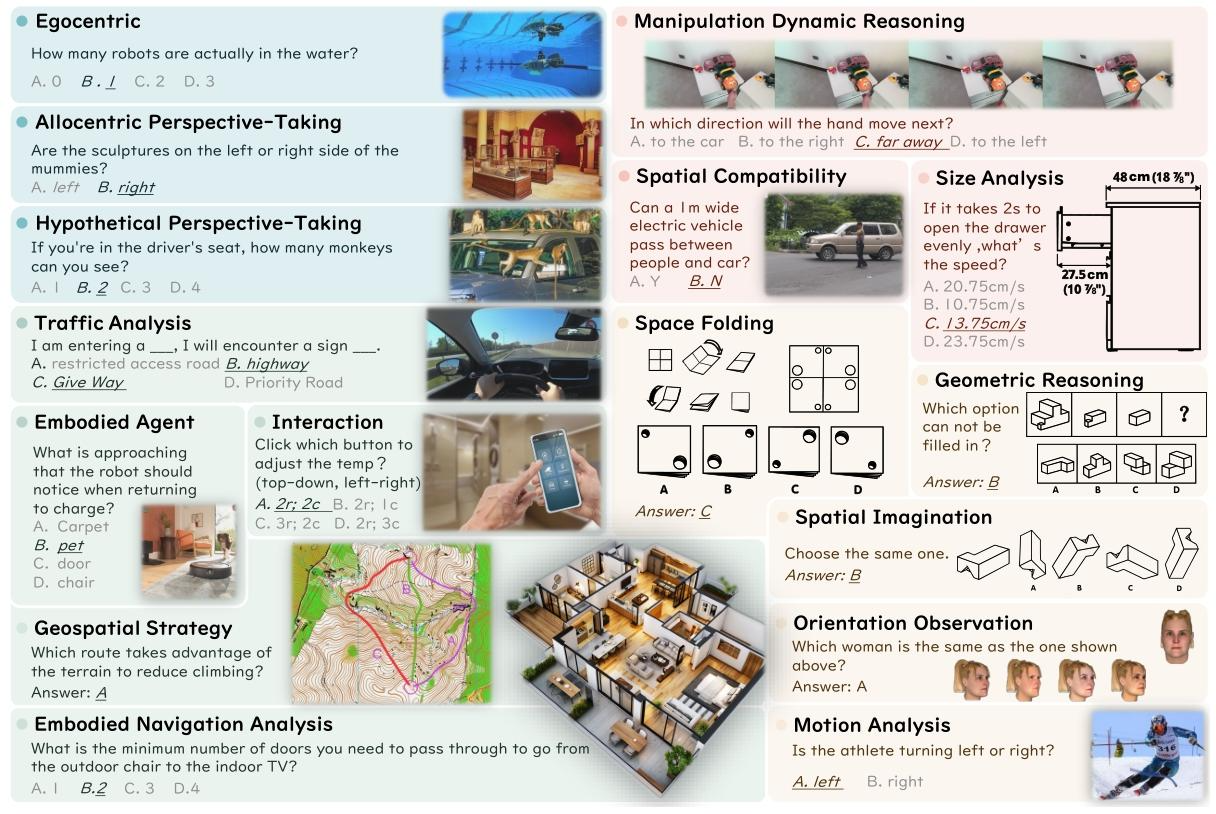
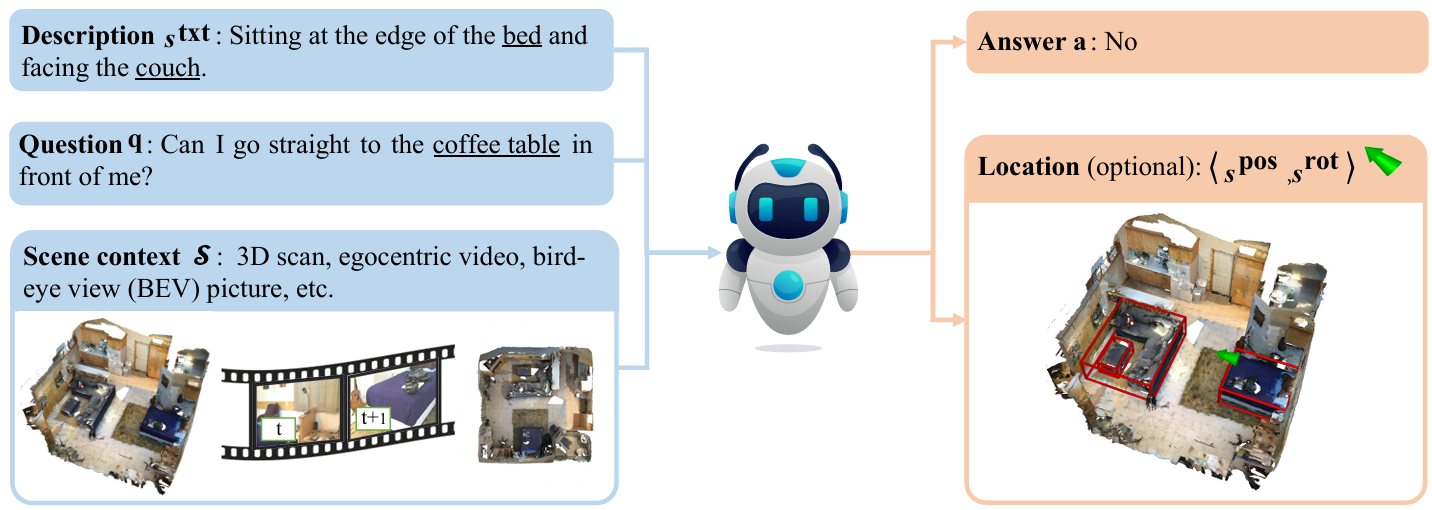
Visual spatial understanding is a key task at the intersection of computer vision and cognitive science. It aims to enable intelligent agents (such as robots and AI systems) to parse spatial relationships in the environment through visual inputs (images, videos, etc.), forming an abstract cognition of the physical world. In Embodied Intelligence, it serves as the foundation for agents to achieve the "perception-decision-action" loop—only by understanding attributes like object positions, distances, sizes, and orientations in space can intelligent agents navigate environments, manipulate objects, or interact with humans.

Timeline

Visual Spatial Intelligence-A Survey

Citation

If you find this project useful, please consider citing:

@article{sibench2025,
  title={How Far are VLMs from True Visual Spatial Intelligence? A Benchmark-Driven Perspective},
  author={Songsong Yu, Yuxin Chen, Hao Ju, Lianjie Jia, Fuxi Zhang, Shaofei Huang, Yuhan Wu, Rundi Cui, Binghao Ran, Zaibin Zhang, Zhedong Zheng, Zhipeng Zhang, Yifan Wang, Lin Song, Lijun Wang, Yanwei Li, Ying Shan, Huchuan Lu},
  journal={arXiv preprint arXiv:2509.18905},
  year={2025}
}

Table of Contents

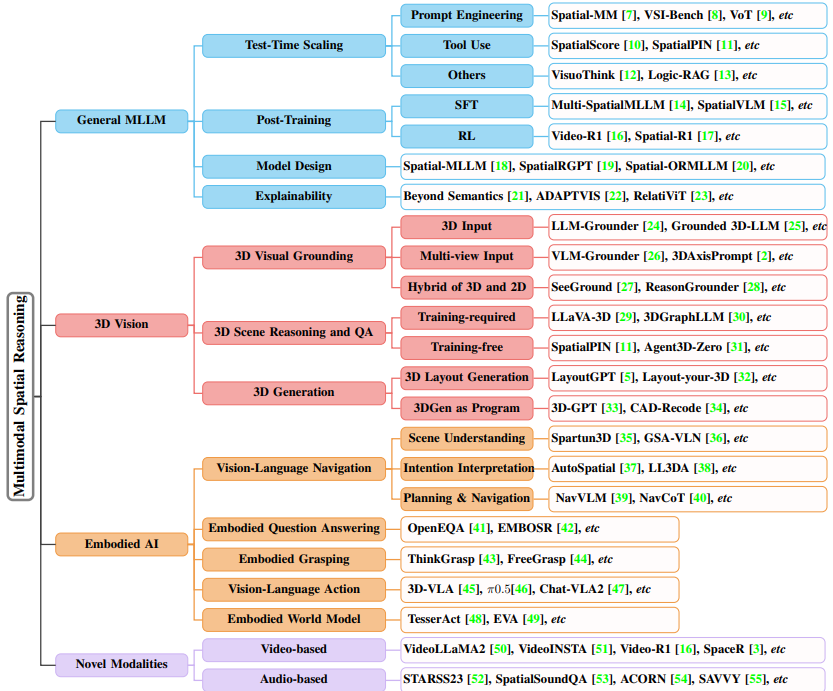
To facilitate the community's quick understanding of visual-spatial reasoning, we first categorized it by input modalities into Single image, Monocular Video, and Multi-View Images. We also surveyed other input modalities such as point clouds, as well as specific applications like embodied robotics. These are temporarily grouped under "Others," and we will conduct a more detailed sorting in the future.

Papers

Single Image

<tr>
<td><a href="https://arxiv.org/pdf/2512.07733">SpatialDreamer: Incentivizing Spatial Reasoning via Active Mental Imagery</a></td>
<td>ARXIV</td>
<td>25-12</td>
<td><a href="https://github.com/mengcaopku/SpatialDreamer">link</a></td>
<td><img src="https://img.shields.io/github/stars/mengcaopku/SpatialDreamer.svg?style=social&label=Star" alt="Star count"/></td>
<td>--</td>
<td><img src="excel_images/2026-01-09_210340_756.jpg" alt="img" /></td>
TitleVenueDateCodeStarsBenchmarkIllustration
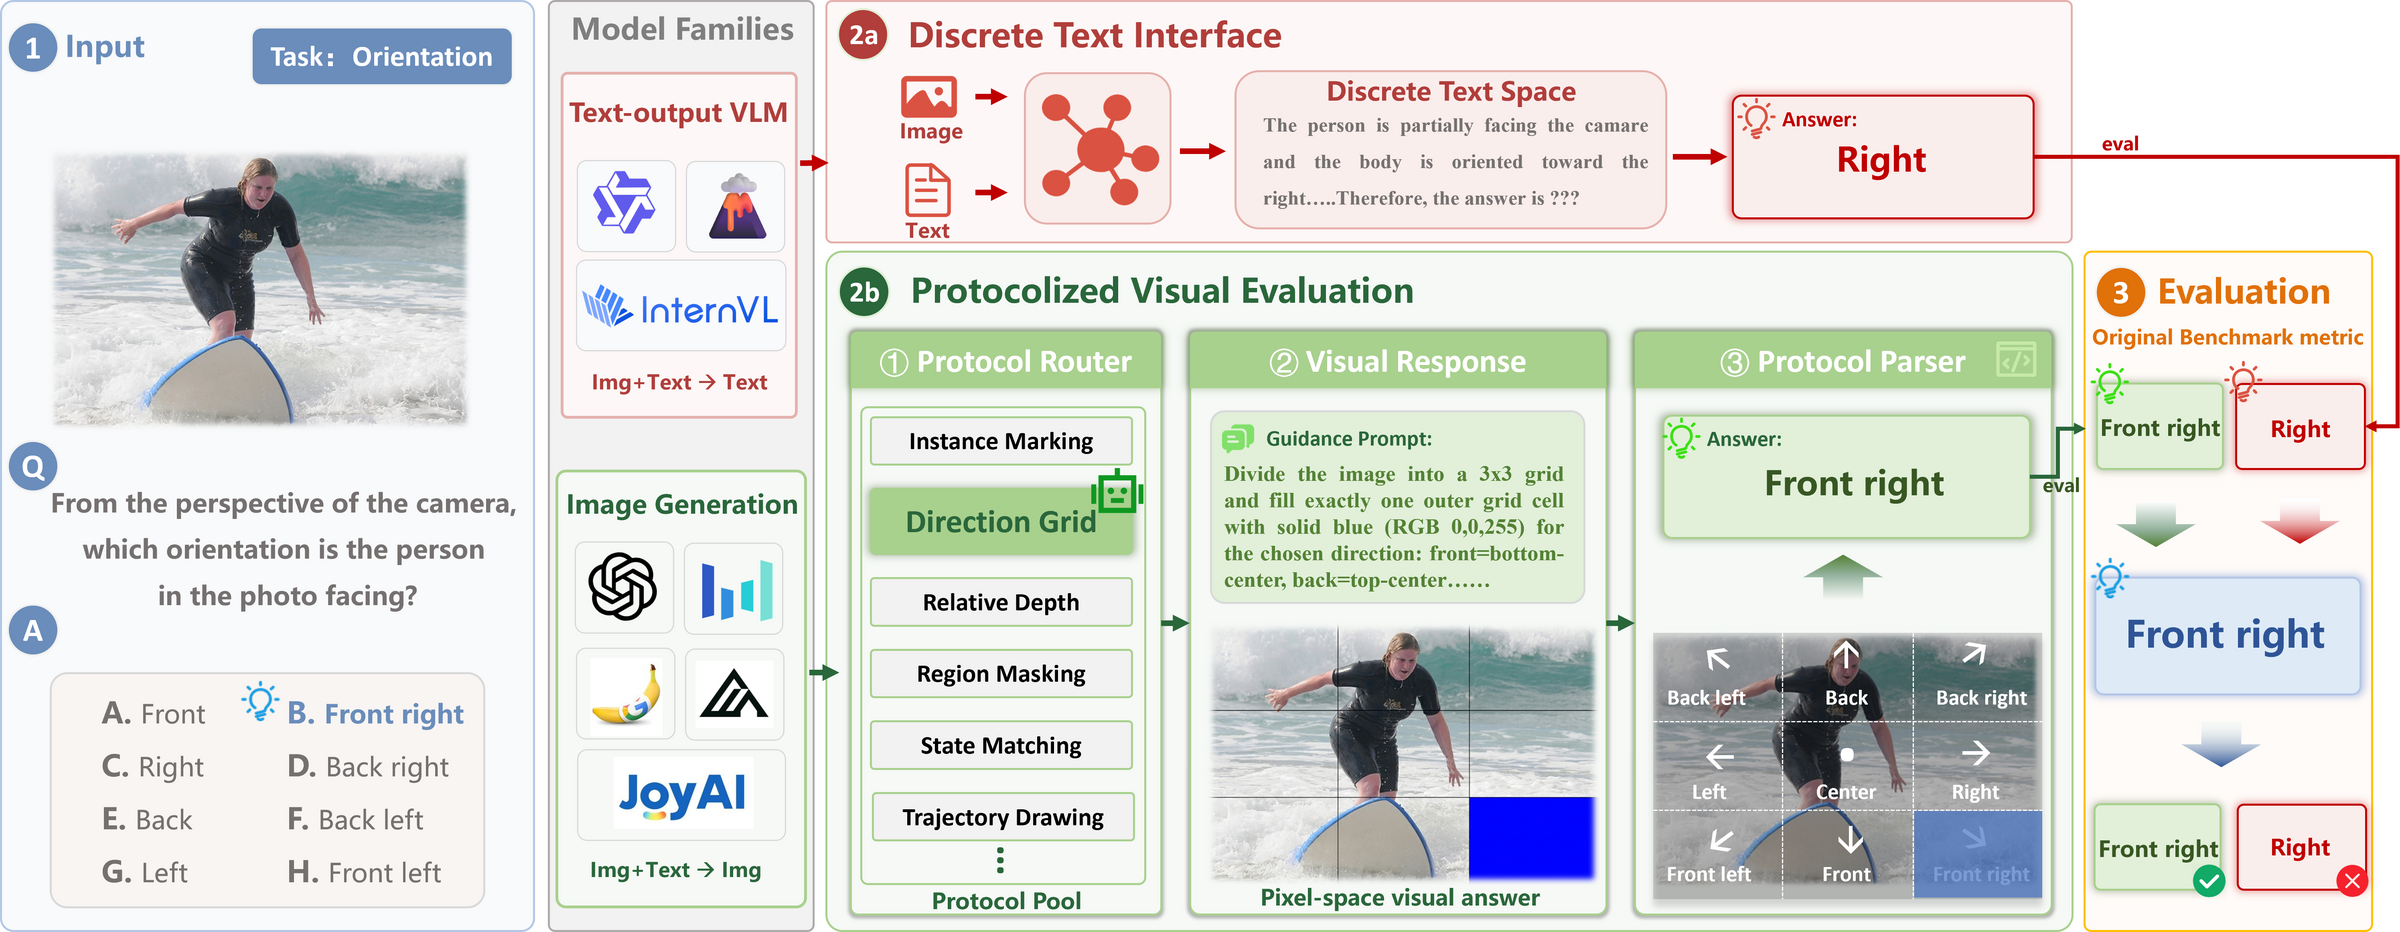
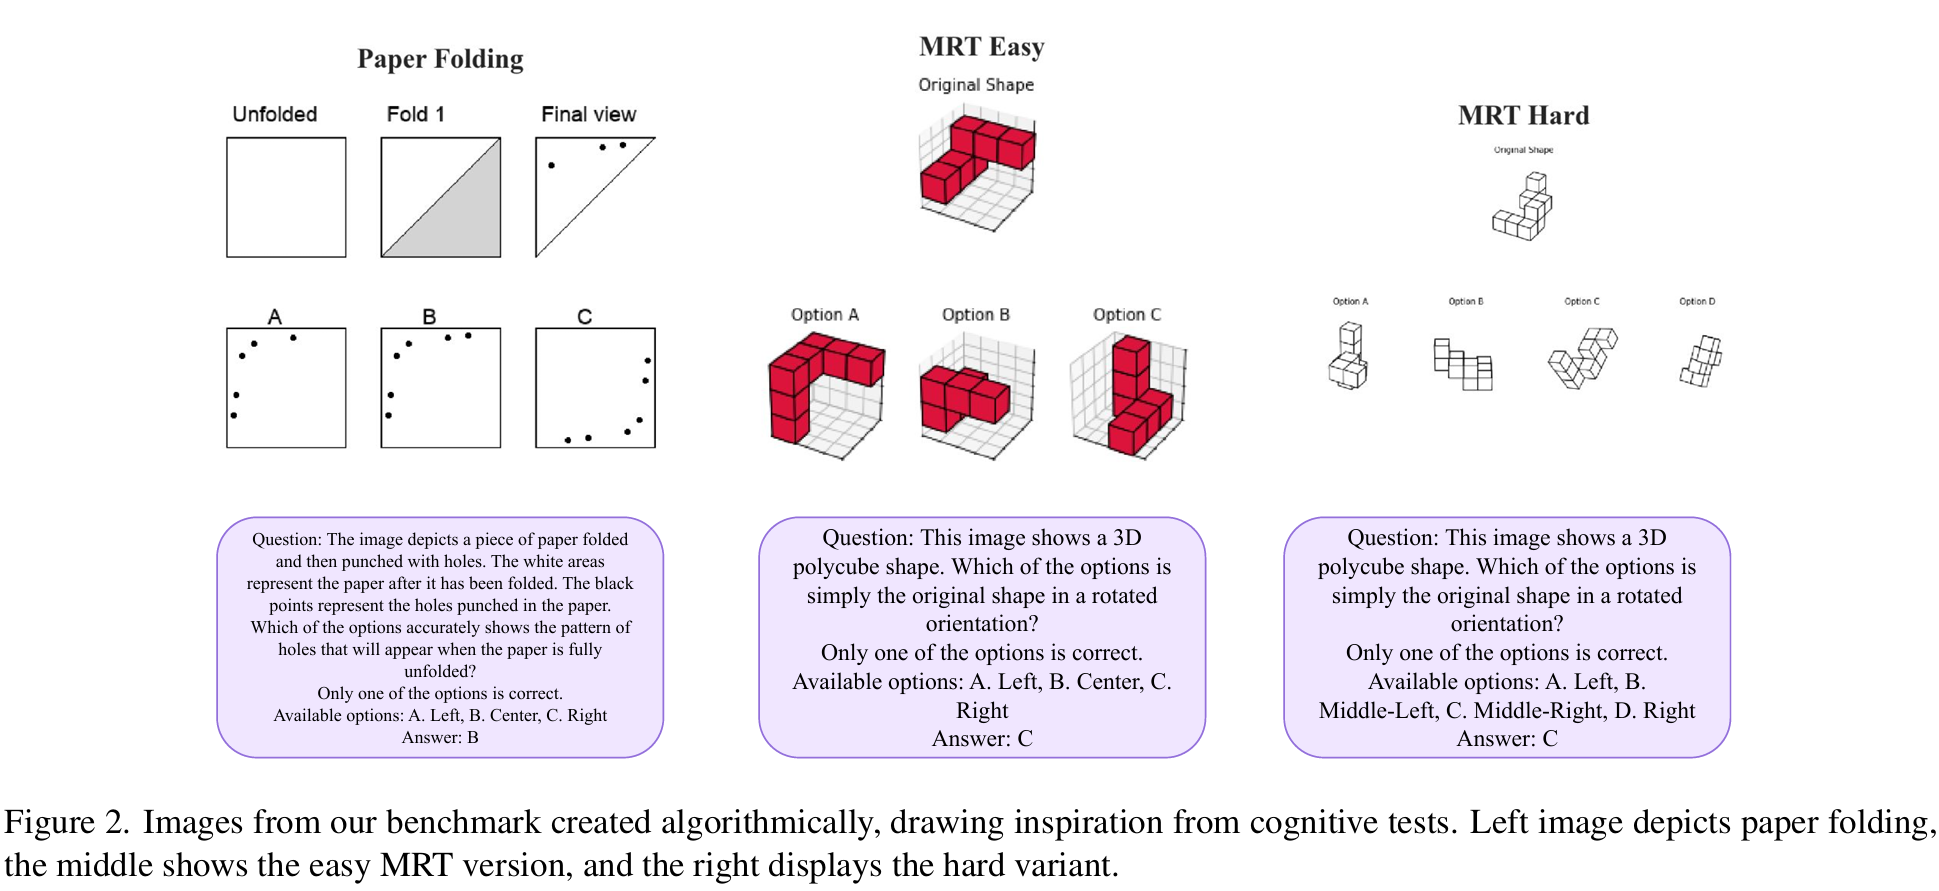
Show, Don't Tell: Evaluating Spatial Cognition in Generative Pixels Rather Than LLM TextARXIV26-07linkStar countSpatialGen-Benchimg
SpatiO: Adaptive Test-Time Orchestration of Vision-Language Agents for Spatial ReasoningARXIV26-04----3DSRBench, CV-Bench, Omni3D-Bench--
HiSpatial: Taming Hierarchical 3D Spatial Understanding in Vision-Language ModelsCVPR 202626-03----SQA3D, ScanQA--
LanteRn: Latent Visual Structured ReasoningARXIV26-03--------
Unleashing Spatial Reasoning in Multimodal Large Language Models via Textual Representation Guided ReasoningARXIV26-03----VSI-Bench, ScanQA--
3D-Layout-R1: Structured Reasoning for Language-Instructed Spatial EditingARXIV26-03--------
Attention in Space: Functional Roles of VLM Heads for Spatial ReasoningARXIV26-03----SpatialBench--
MultihopSpatial: Multi-hop Compositional Spatial Reasoning Benchmark for Vision-Language ModelECCV 202626-03linkStar countMultihopSpatialimg
Thinking with Geometry: Active Geometry Integration for Spatial ReasoningARXIV26-02----VSI-Bench, CVBench--
SpatialBoost: Enhancing Visual Representation through Language-Guided ReasoningARXIV26-03----ScanQA, CVBench--
SSR: Pushing the Limit of Spatial Intelligence with Structured Scene ReasoningARXIV26-03----VSI-Bench--
Perception-Aware Multimodal Spatial Reasoning from Monocular ImagesARXIV26-03----SURDS--
SpatiaLQA: A Benchmark for Evaluating Spatial Logical Reasoning in Vision-Language ModelsCVPR26-02linkStar countSpatiaLQA--
SpatiaLab: Can Vision-Language Models Perform Spatial Reasoning in the Wild?ICLR26-02----SpatiaLab--
CityCube: Benchmarking Cross-view Spatial Reasoning on Vision-Language Models in Urban EnvironmentsARXIV26-01----CityCube--
Thinking with Blueprints: Assisting Vision-Language Models in Spatial Reasoning via Structured Object RepresentationARXIV26-01--------
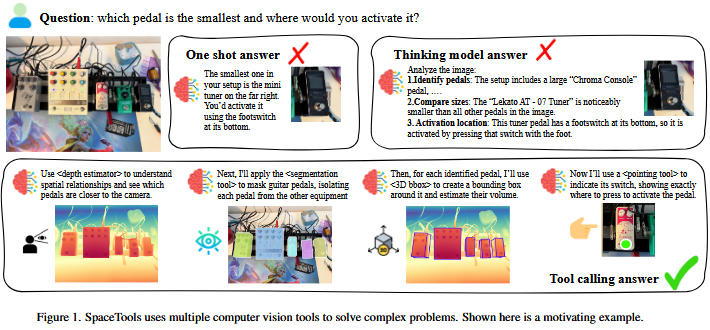
SpaceTools: Tool-Augmented Spatial Reasoning via Double Interactive RLARXIV25-12linkStar count--img
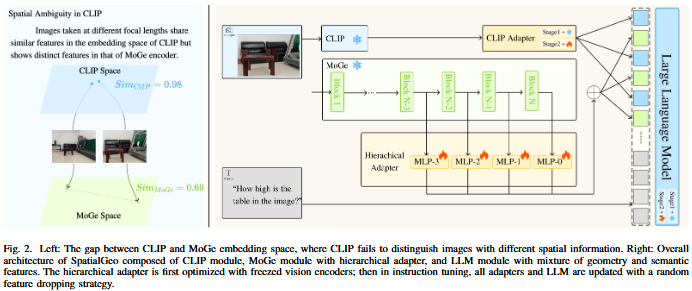
SpatialGeo: Boosting Spatial Reasoning in Multimodal LLMs via Geometry-Semantics FusionARXIV25-11linkStar count--img
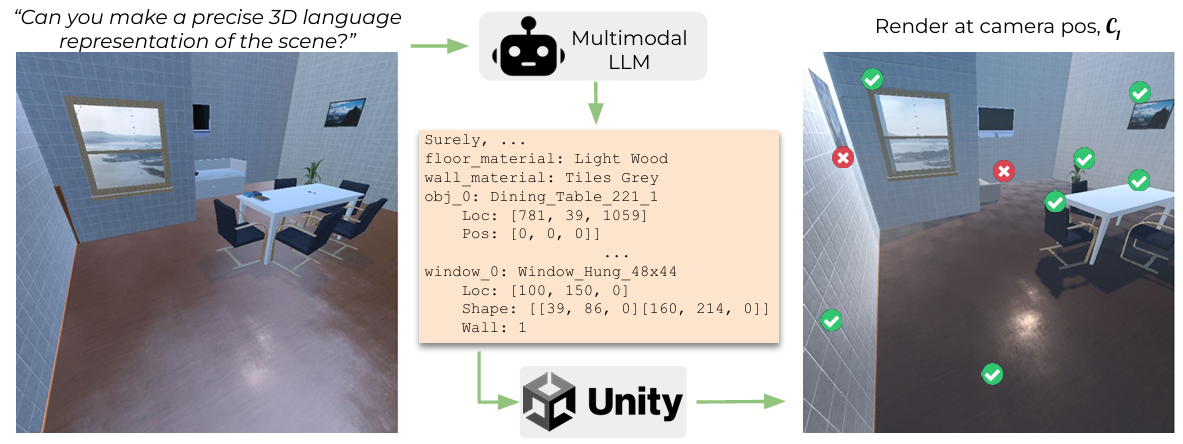
R2D3:ImpartingSpatial Reasoning by Reconstructing 3D Scenes from 2D ImagesARXIV------R2D3img
RoboRefer: Towards Spatial Referring with Reasoning in Vision-Language Models for RobticsARXIV25-06link--RefSpatial-Benchimg
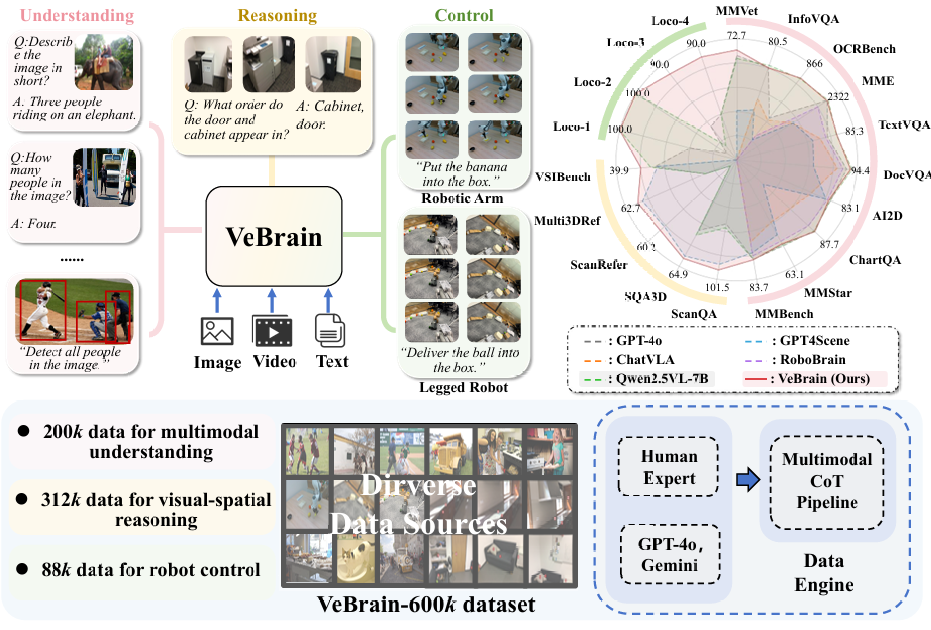
Visual Embodied Brain: Let Multimodal Large Language Models See, Think, and Control in SpacesARXIV25-06linkStar countVeBrain-600kimg
SVQA-R1: Reinforcing Spatial Reasoning in MLLMs via View-Consistent Reward OptimizationARXIV25-06----SVQA-R1img
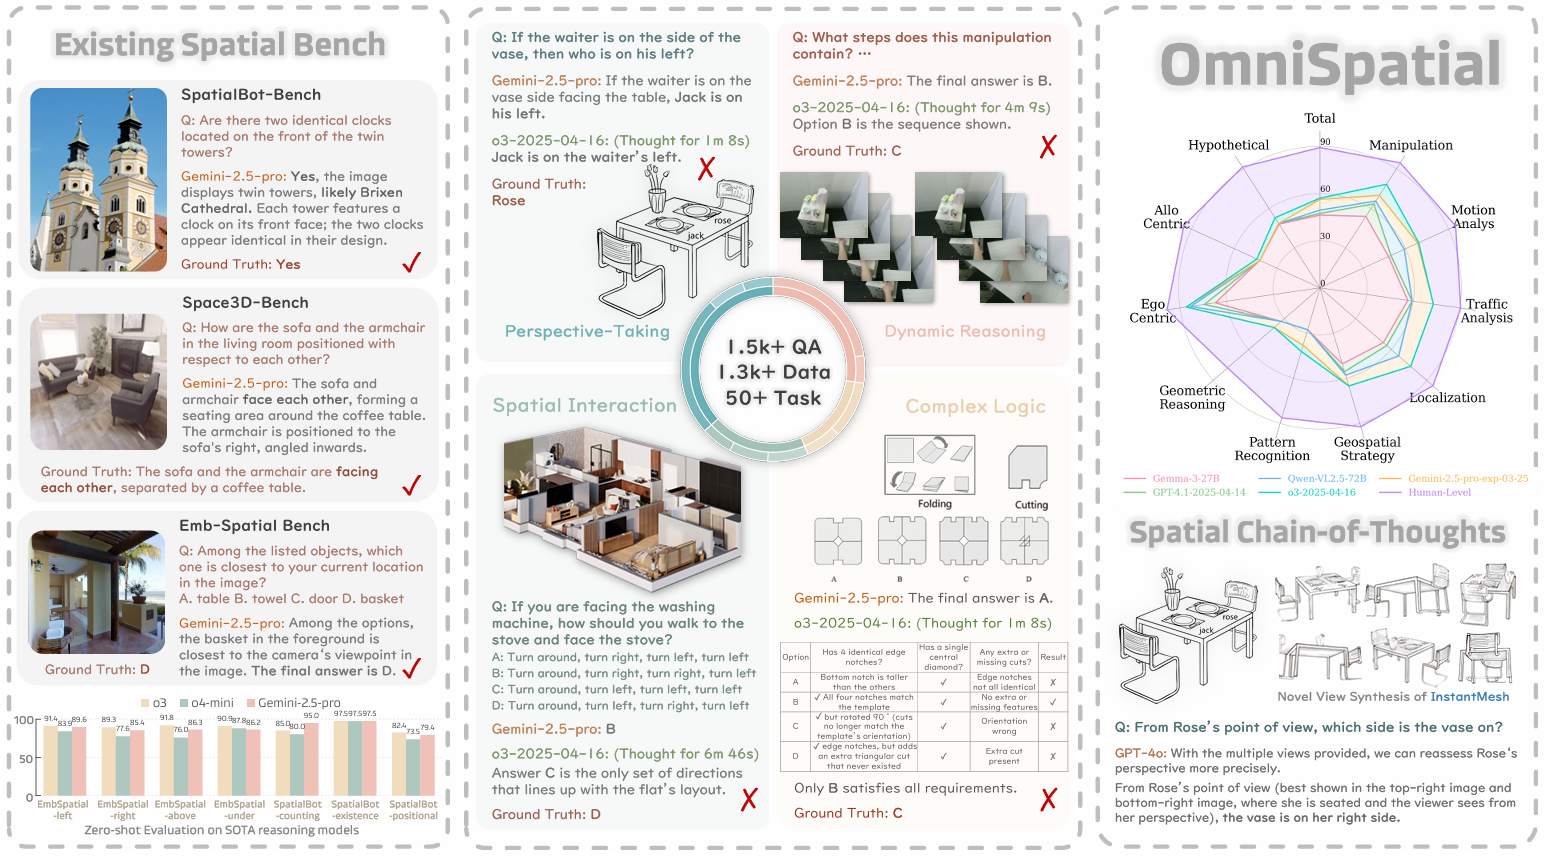
OmniSpatial: Towards Comprehensive Spatial Reasoning Benchmark for Vision Language Models--25-06linkStar countOmniSpatialimg
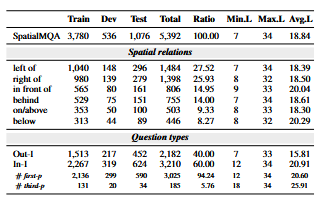
Can Multimodal Large Language Models Understand Spatial RelationsARXIV25-05linkStar countSpatialMQAimg
SSR: Enhancing Depth Perception in Vision-Language Models via Rationale-Guided Spatial Reasoning--25-05----SSR-CoTimg
Spatial-LLaVA: Enhancing Large Language Models with Spatial Referring Expressions for Visual UnderstandingARXIV25-05link--SUNSPOTimg
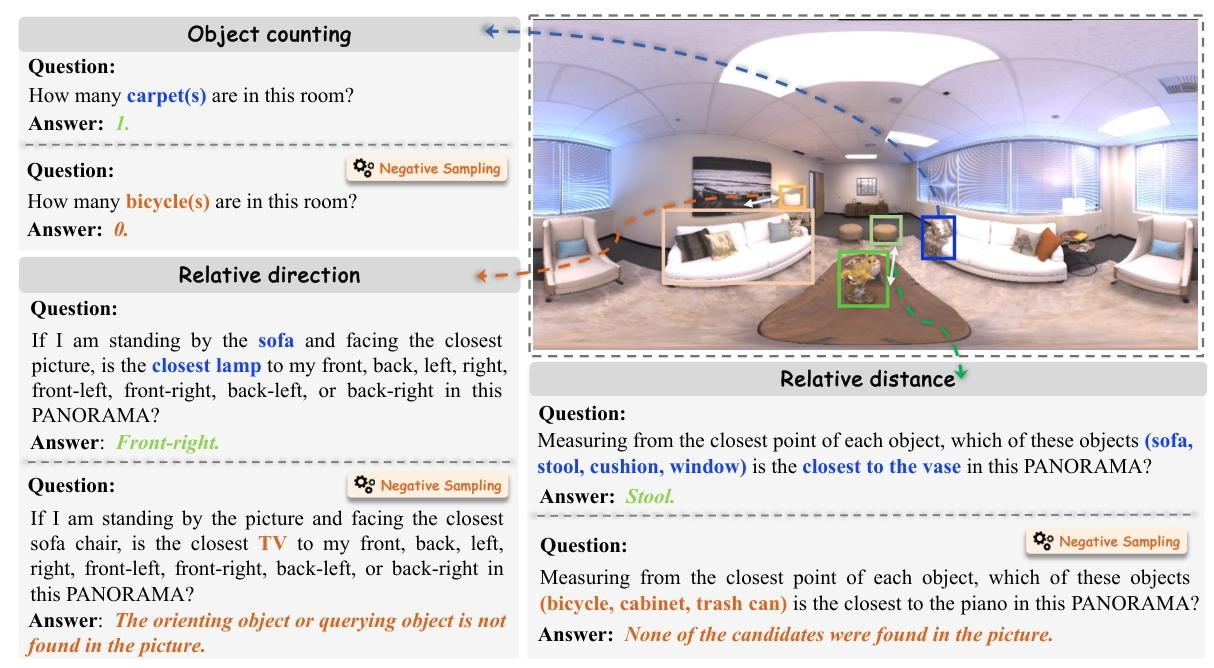
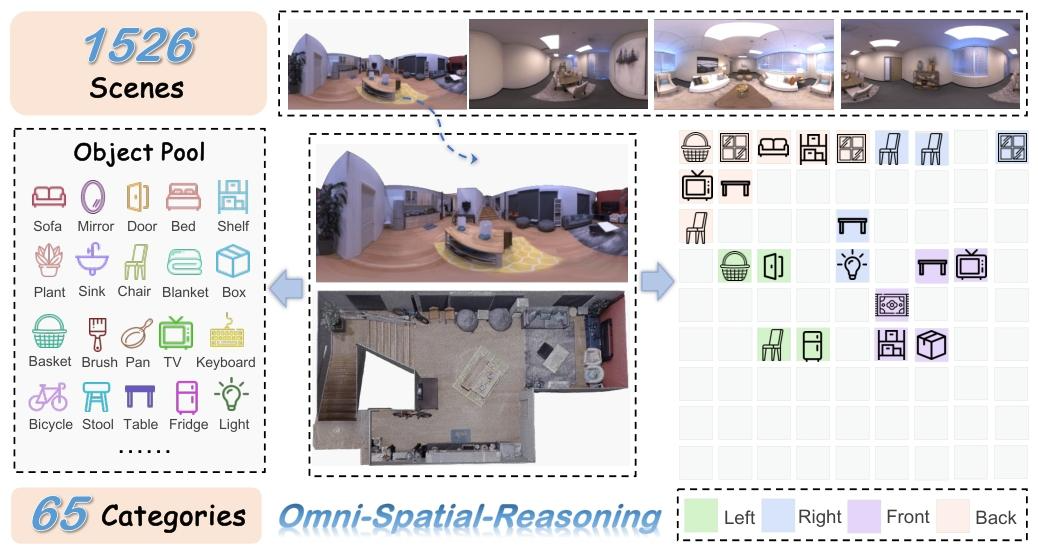
Are Multimodal Large Language Models Ready for Omnidirectional Spatial Reasoning?ARXIV25-05link--OSR-Benchimg
SITE: towards Spatial Intelligence Thorough EvaluationARXIV25-05linkStar countSITEimg
Pixel Reasoner: Incentivizing Pixel-Space Reasoning with Curiosity-Driven Reinforcement LearningARXIV25-05----TallyQA, V*
InfographicVQA, MVBench
img
Improved Visual-Spatial Reasoning via R1-Zero-Like TrainingARXIV25-04linkStar countVSI-100Kimg
Perspective-Aware Reasoning in Vision-Language Models via Mental Imagery SimulationARXIV25-04linkStar countCOMFORT++, 3DSRBenchimg
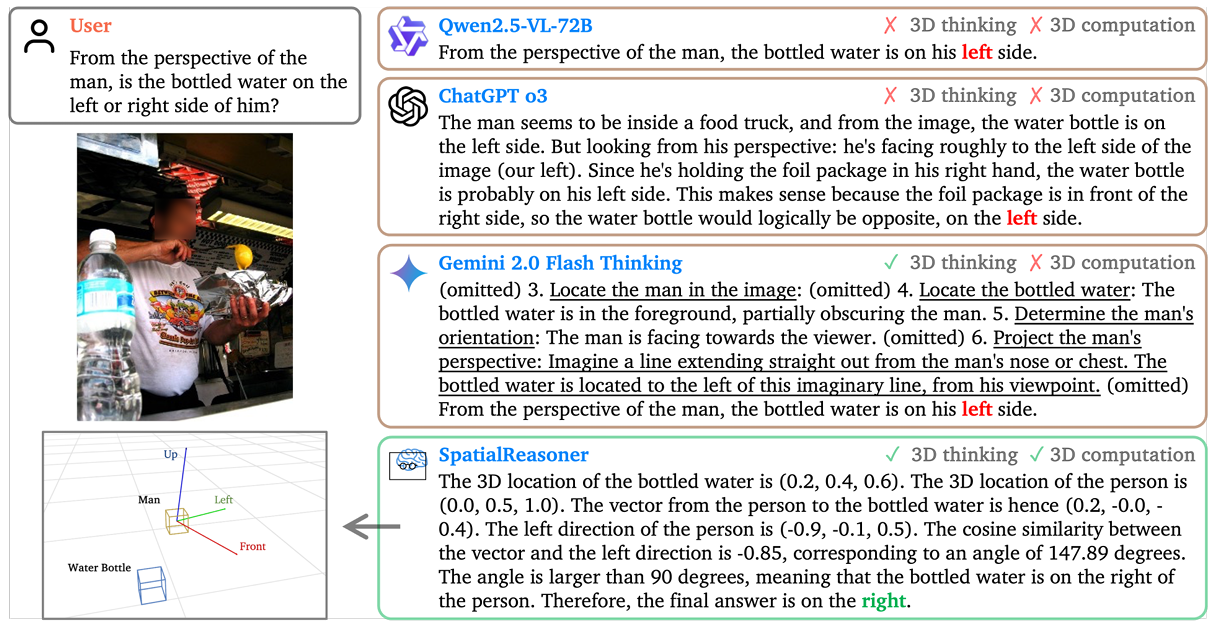
SpatialReasoner: Towards Explicit and Generalizable 3D Spatial ReasoningARXIV25-04link----img
Vision language models are unreliable at trivial spatial cognitionARXIV25-04----TableTestimg
SpaRE: Enhancing Spatial Reasoning in Vision-Language Models with Synthetic DataARXIV25-04----vsr, what's up
3DSR-Bench, RealWorldQA
img
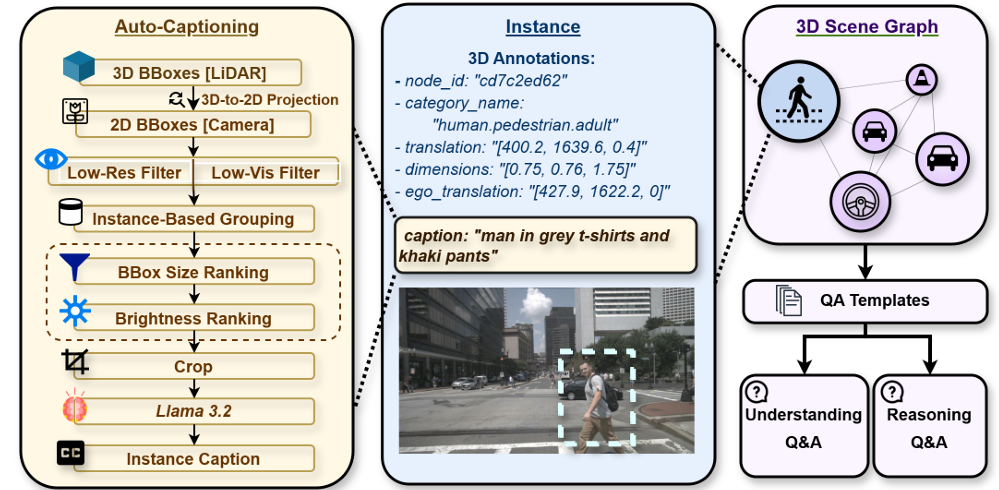
NUSCENES-SPATIALQA: A Spatial Understanding and Reasoning Benchmark for Vision-Language Models in Autonomous DrivingARXIV25-04linkStar countNuScenes-SpatialQAimg
Beyond Semantics Rediscovering Spatial Awareness in Vision-Language Models--25-03link----img
MetaSpatial: Reinforcing 3D Spatial Reasoning in VLMs for the MetaverseARXIV25-03linkStar countMetaSpatialimg
Mind the Gap: Benchmarking Spatial Reasoning in Vision-Language ModelsARXIV25-03linkStar countSRBenchimg
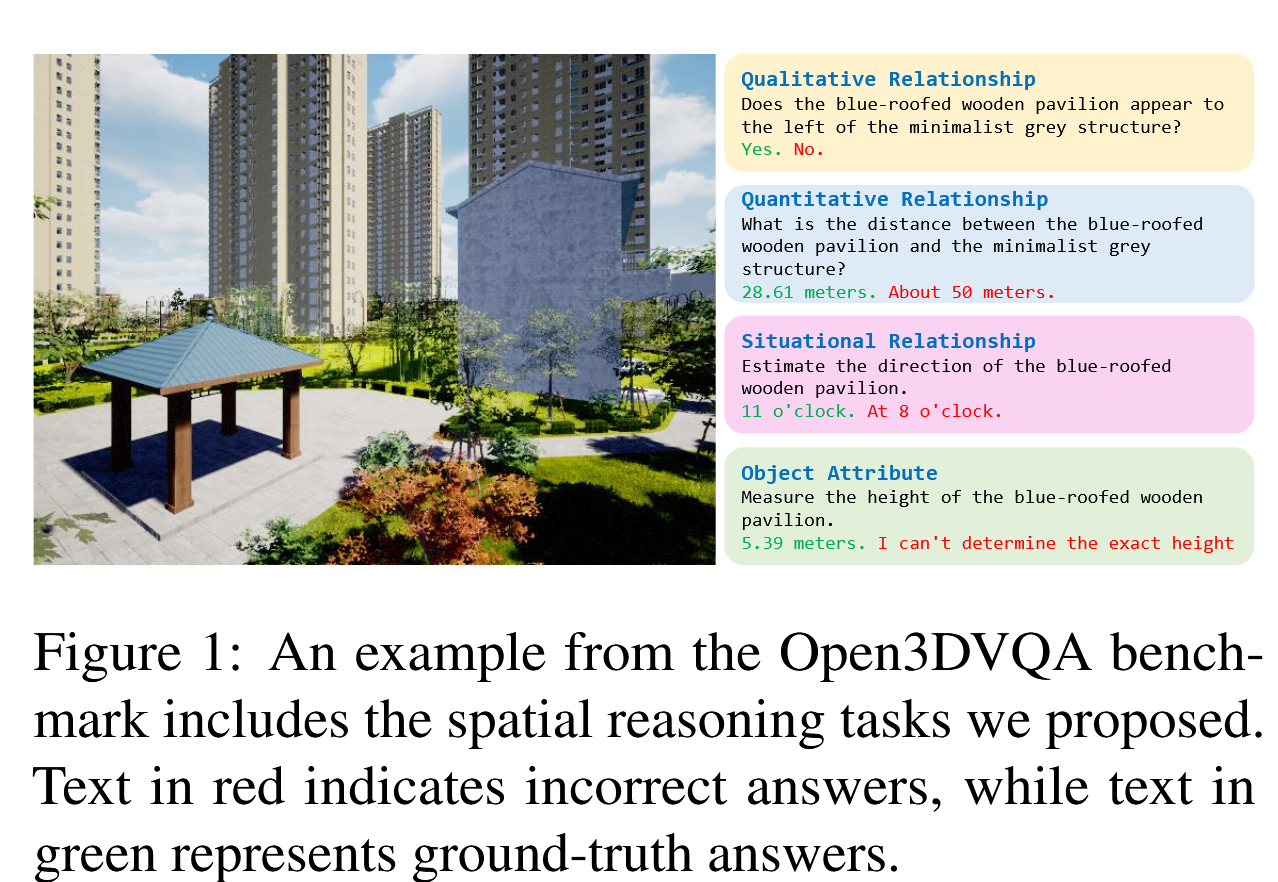
Open3DVQA: ABenchmark for Comprehensive Spatial Reasoning with Multimodal Large Language Model in Open SpaceARXIV25-03linkStar countOpen3DVQAimg
AutoSpatial: Visual-Language Reasoning for Social Robot Navigation through Efficient Spatial Reasoning LearningARXIV25-03linkStar countAutoSpatialimg
Why Is Spatial Reasoning Hard for VLMs? AnAttention Mechanism Perspective on Focus AreasARXIV25-03linkStar count--img
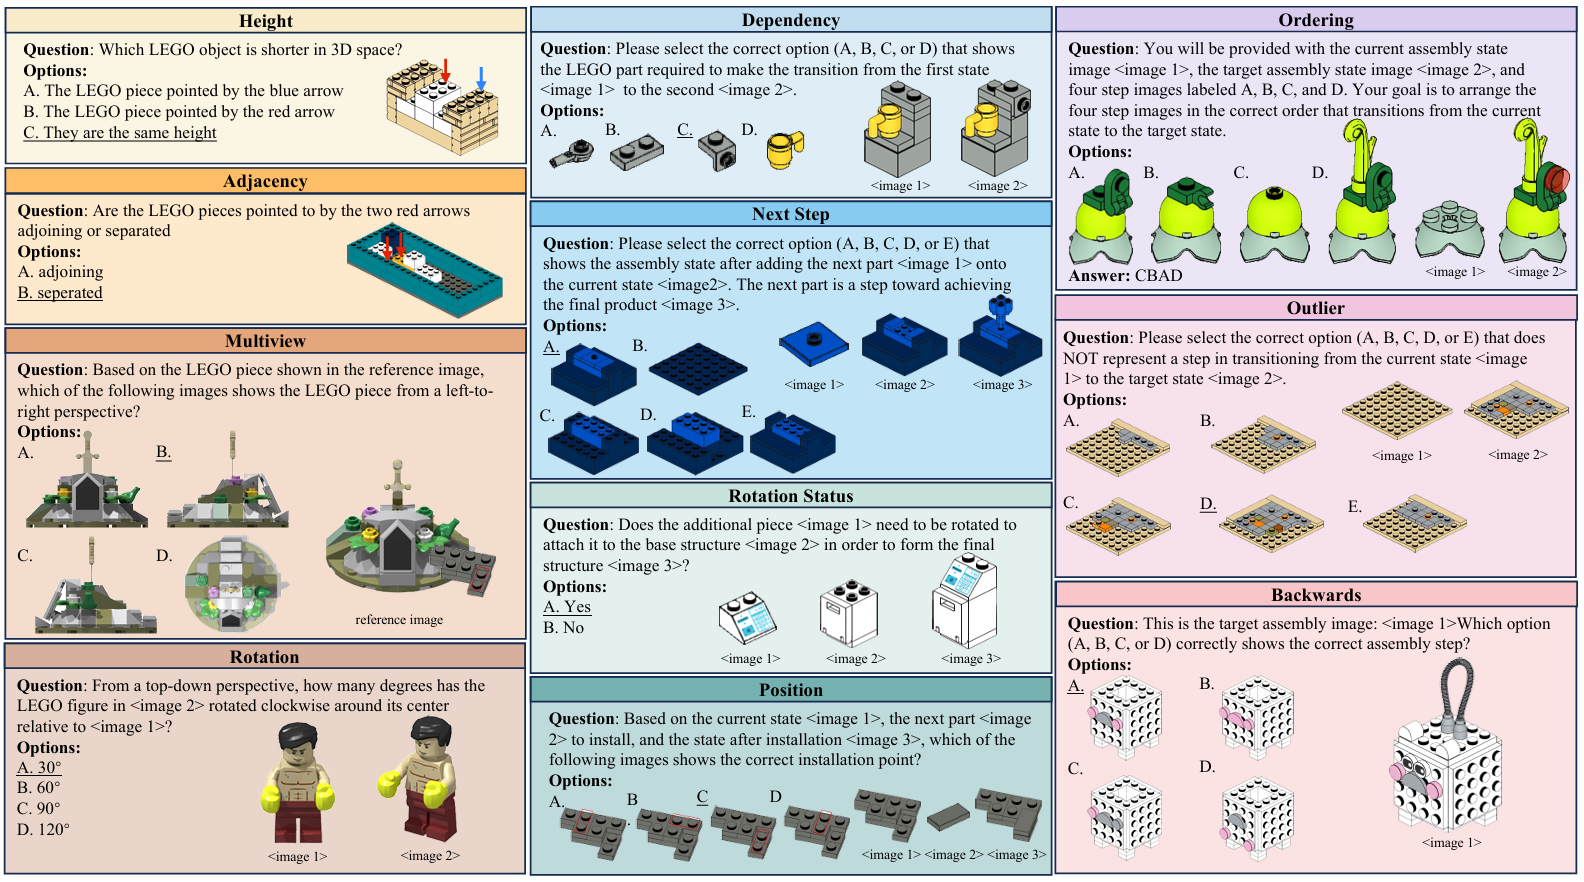
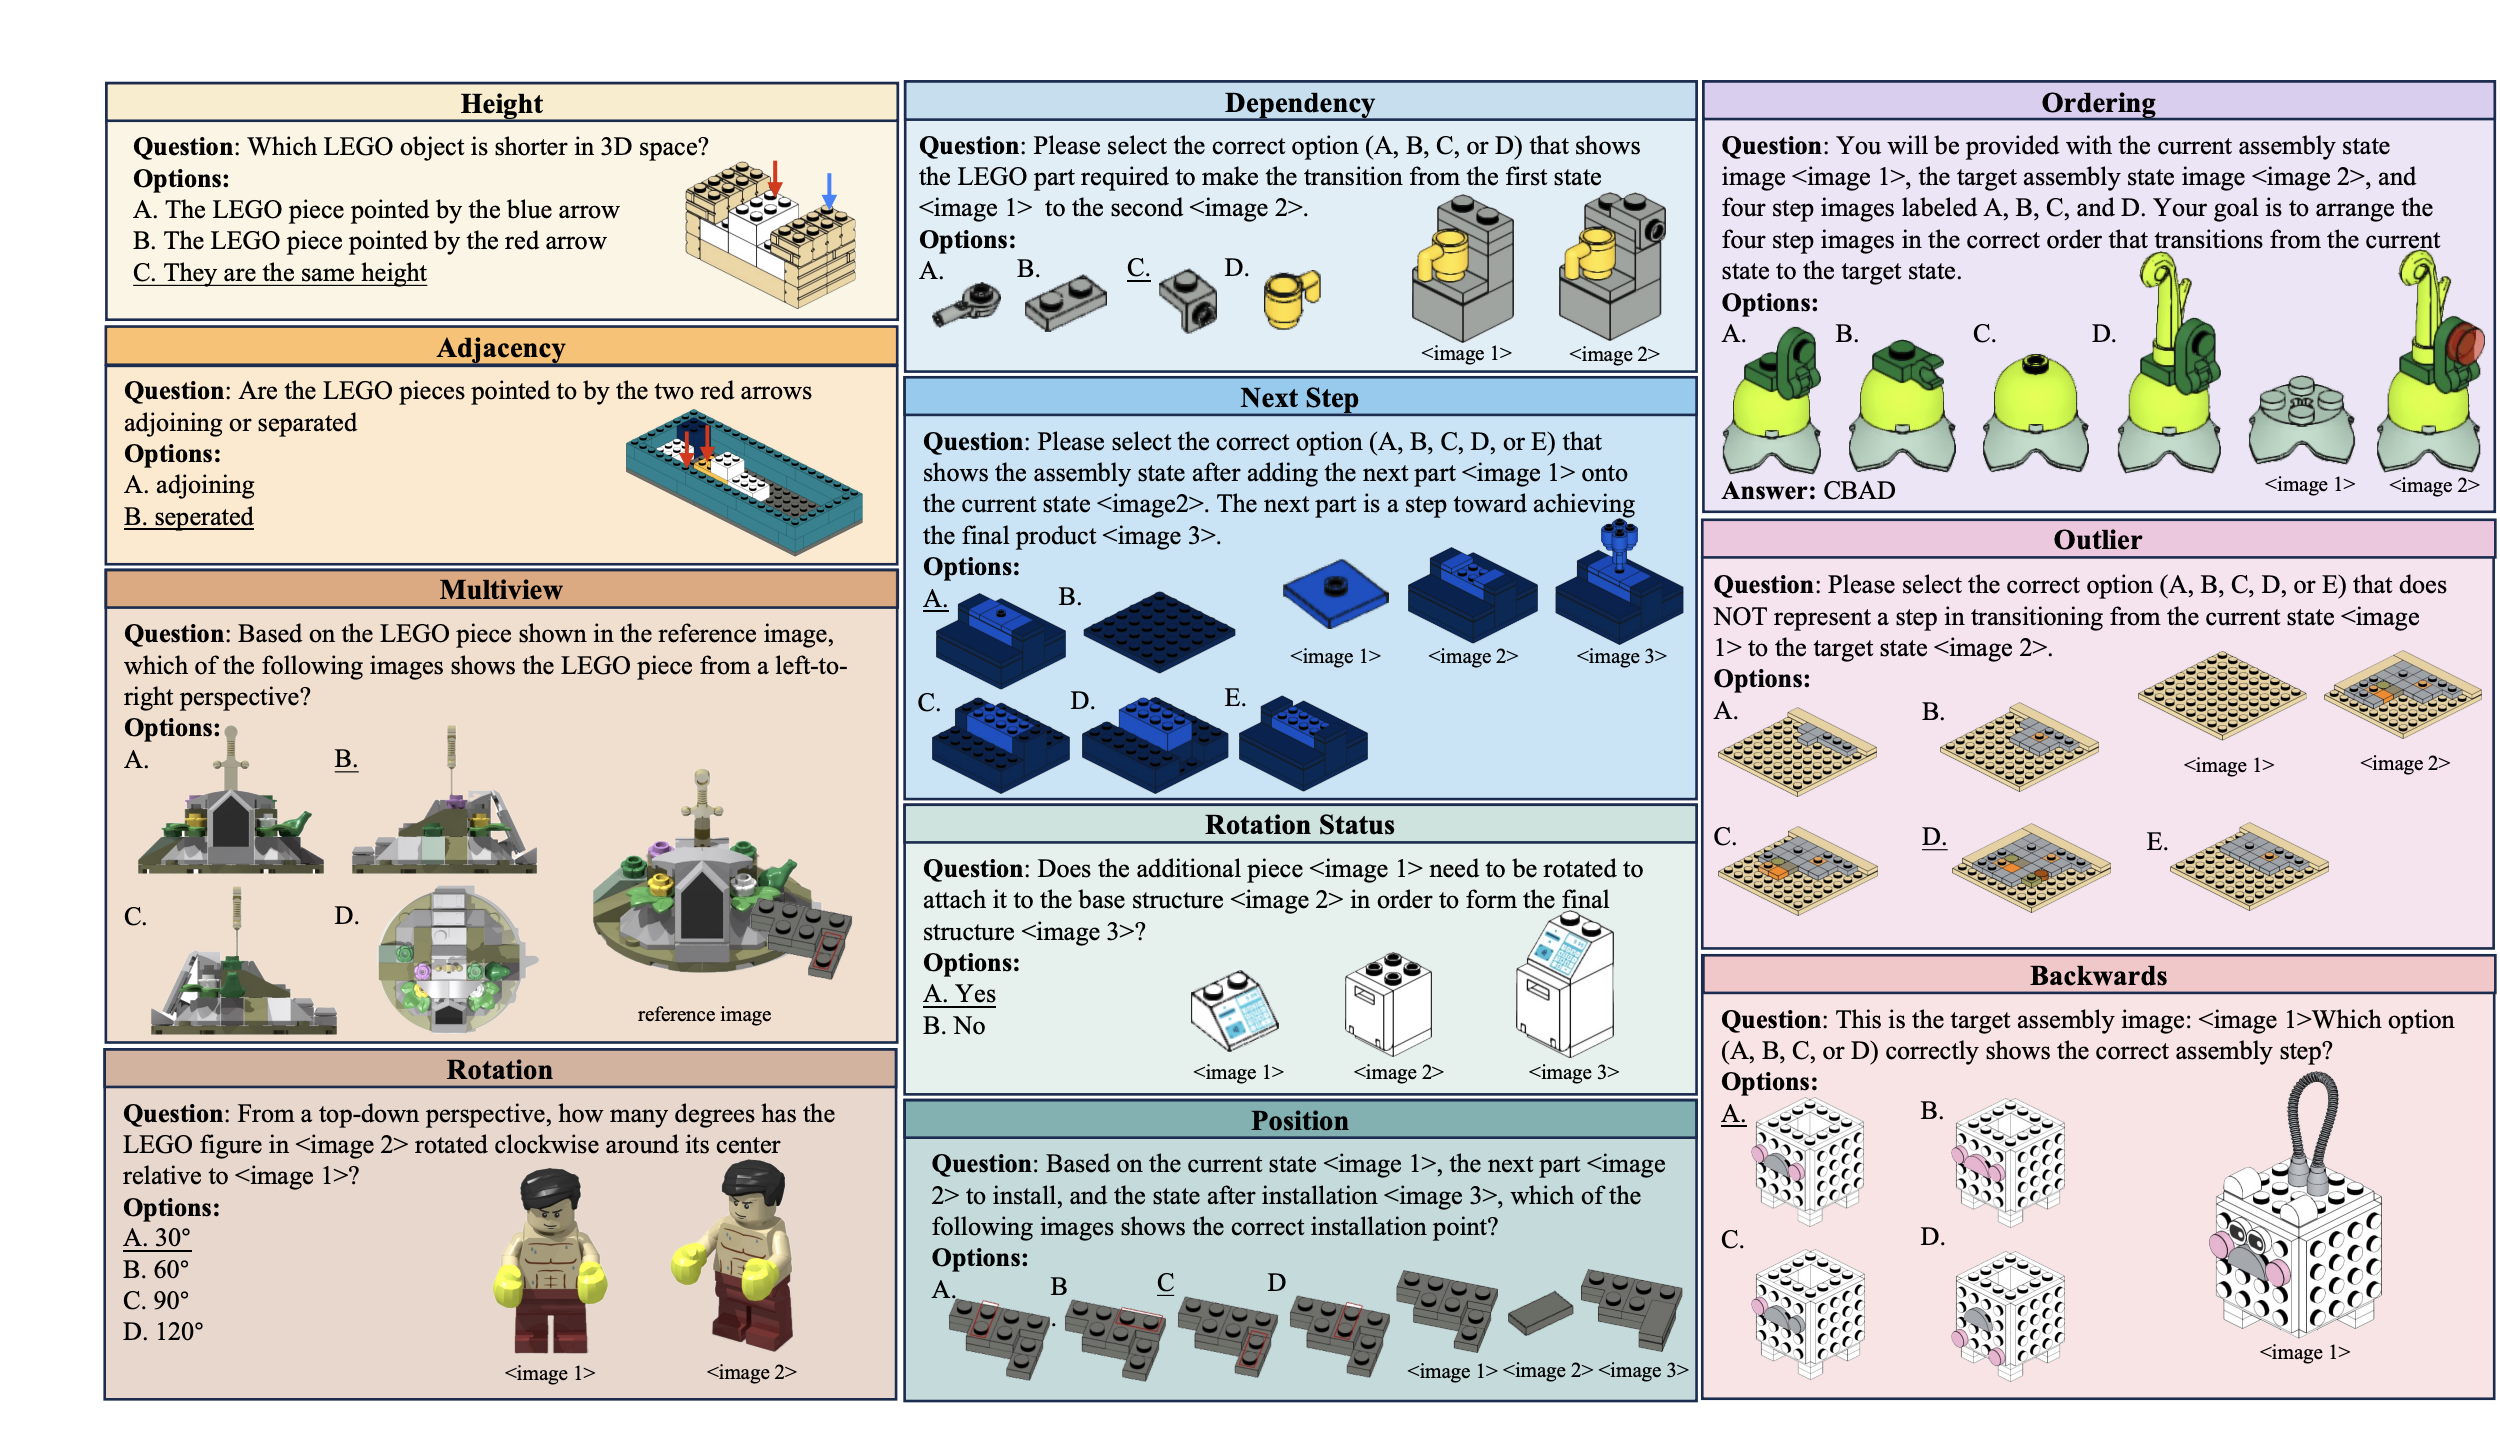
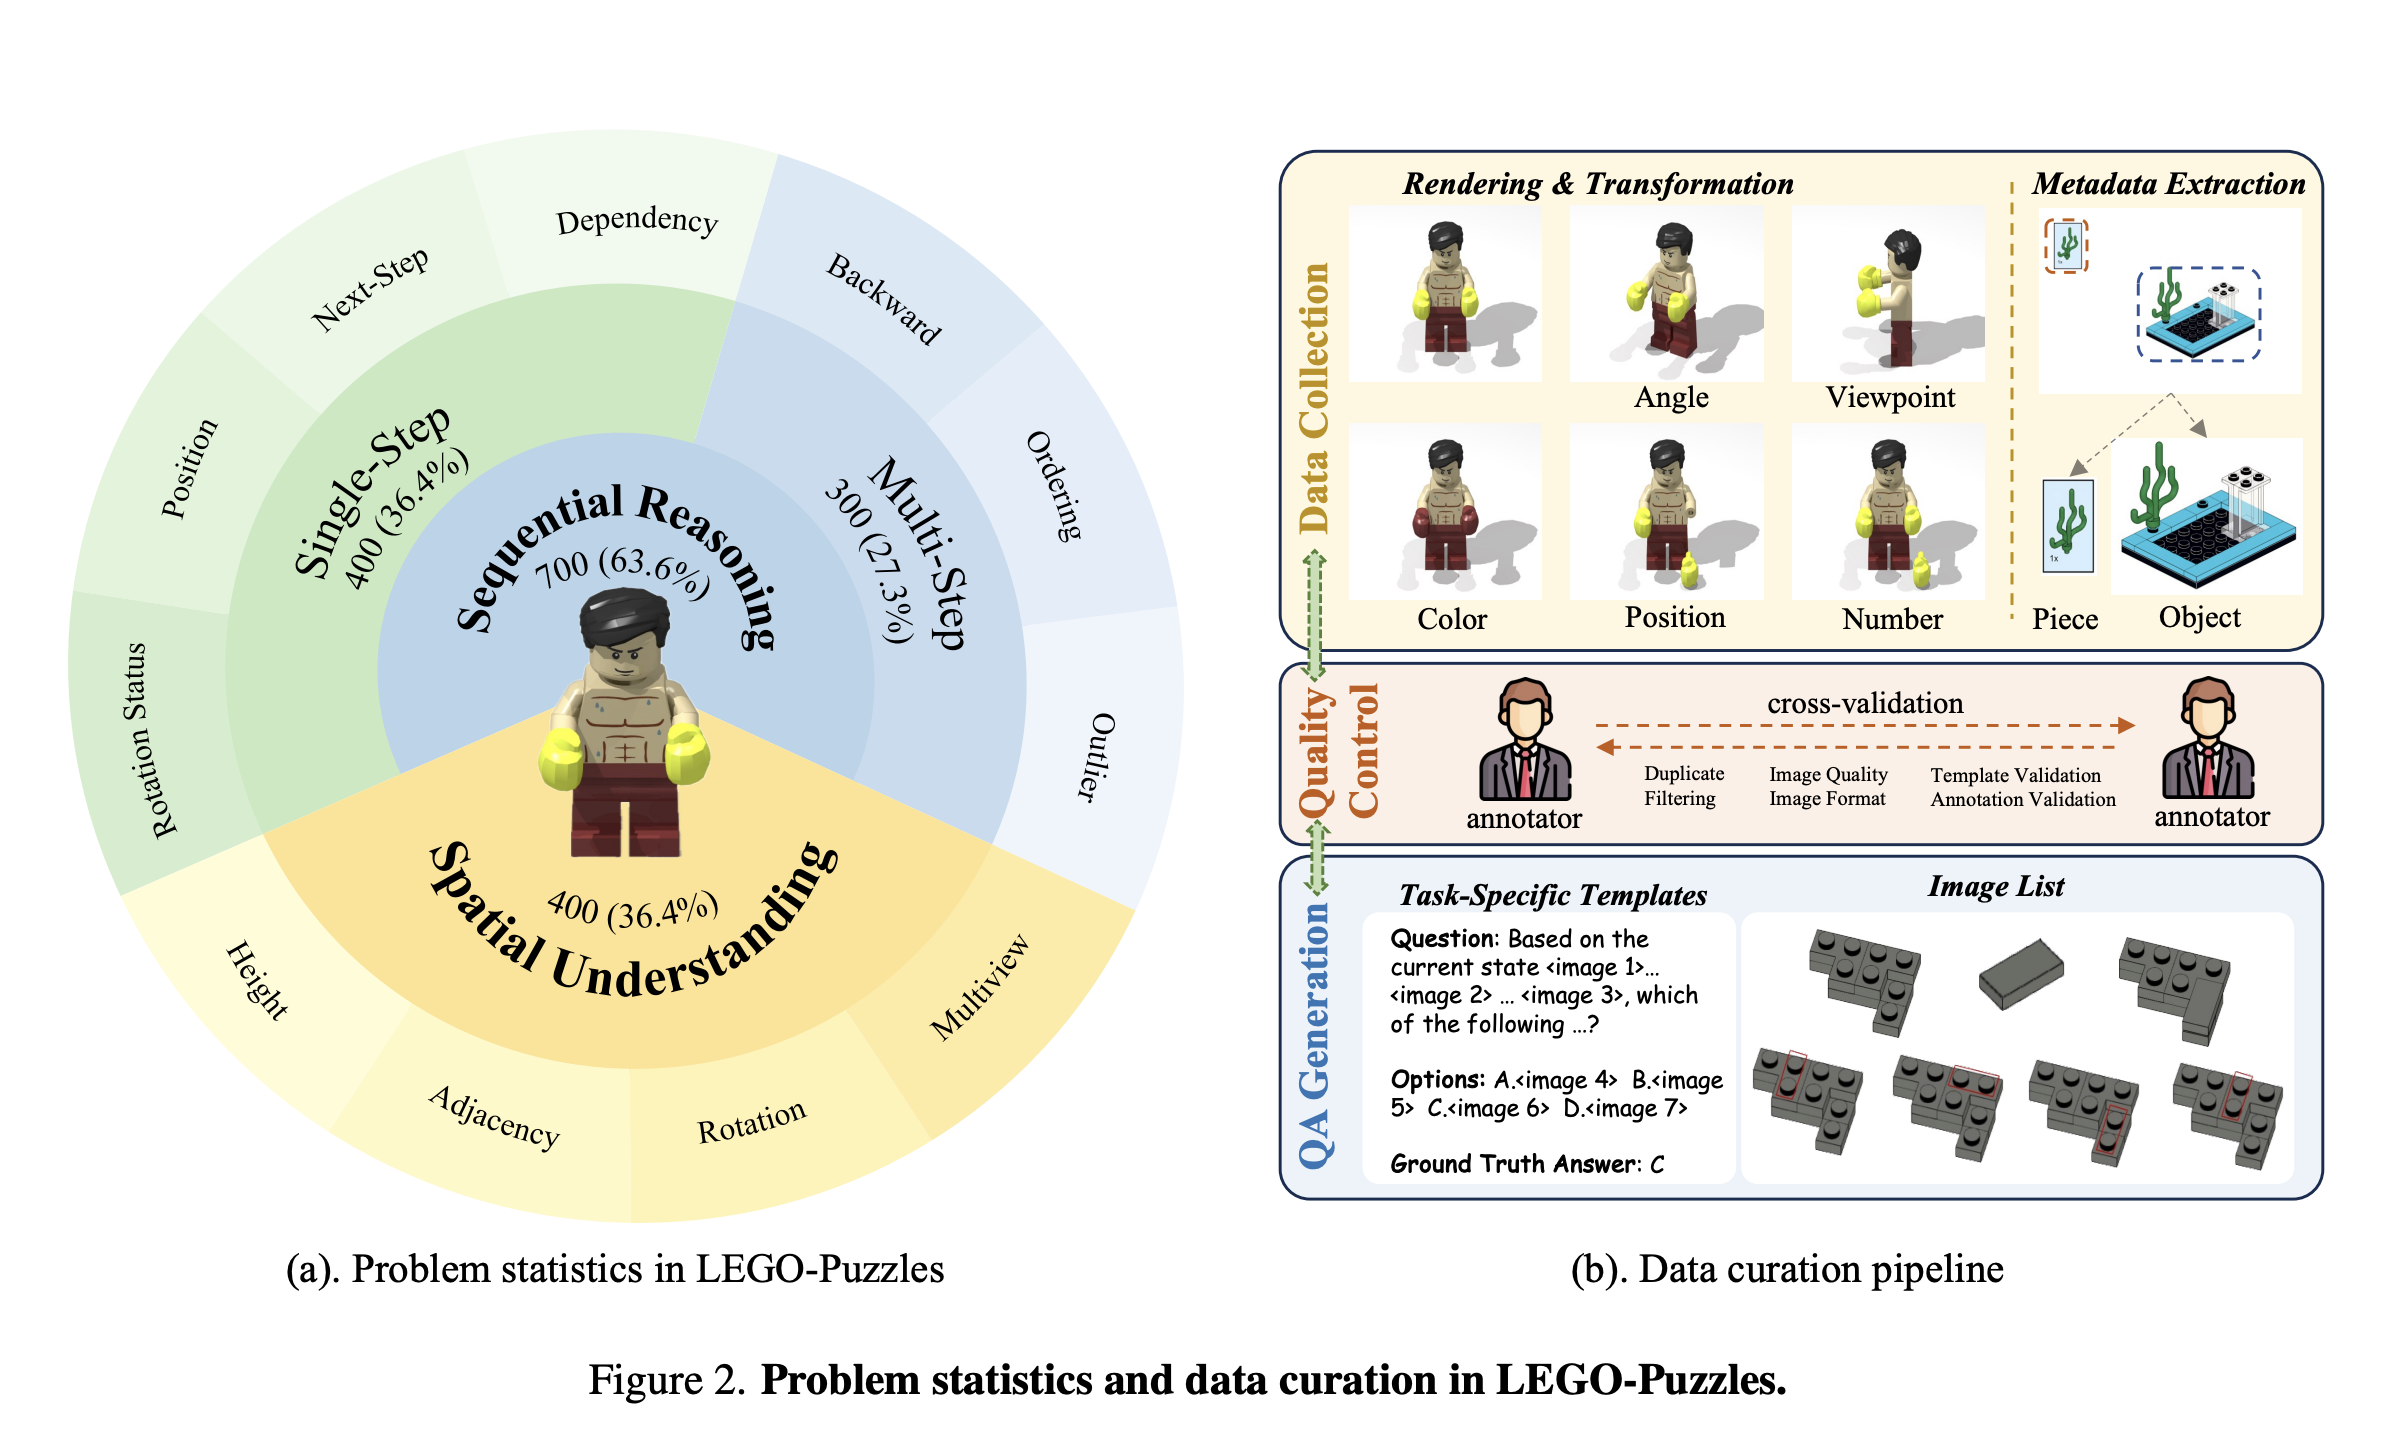
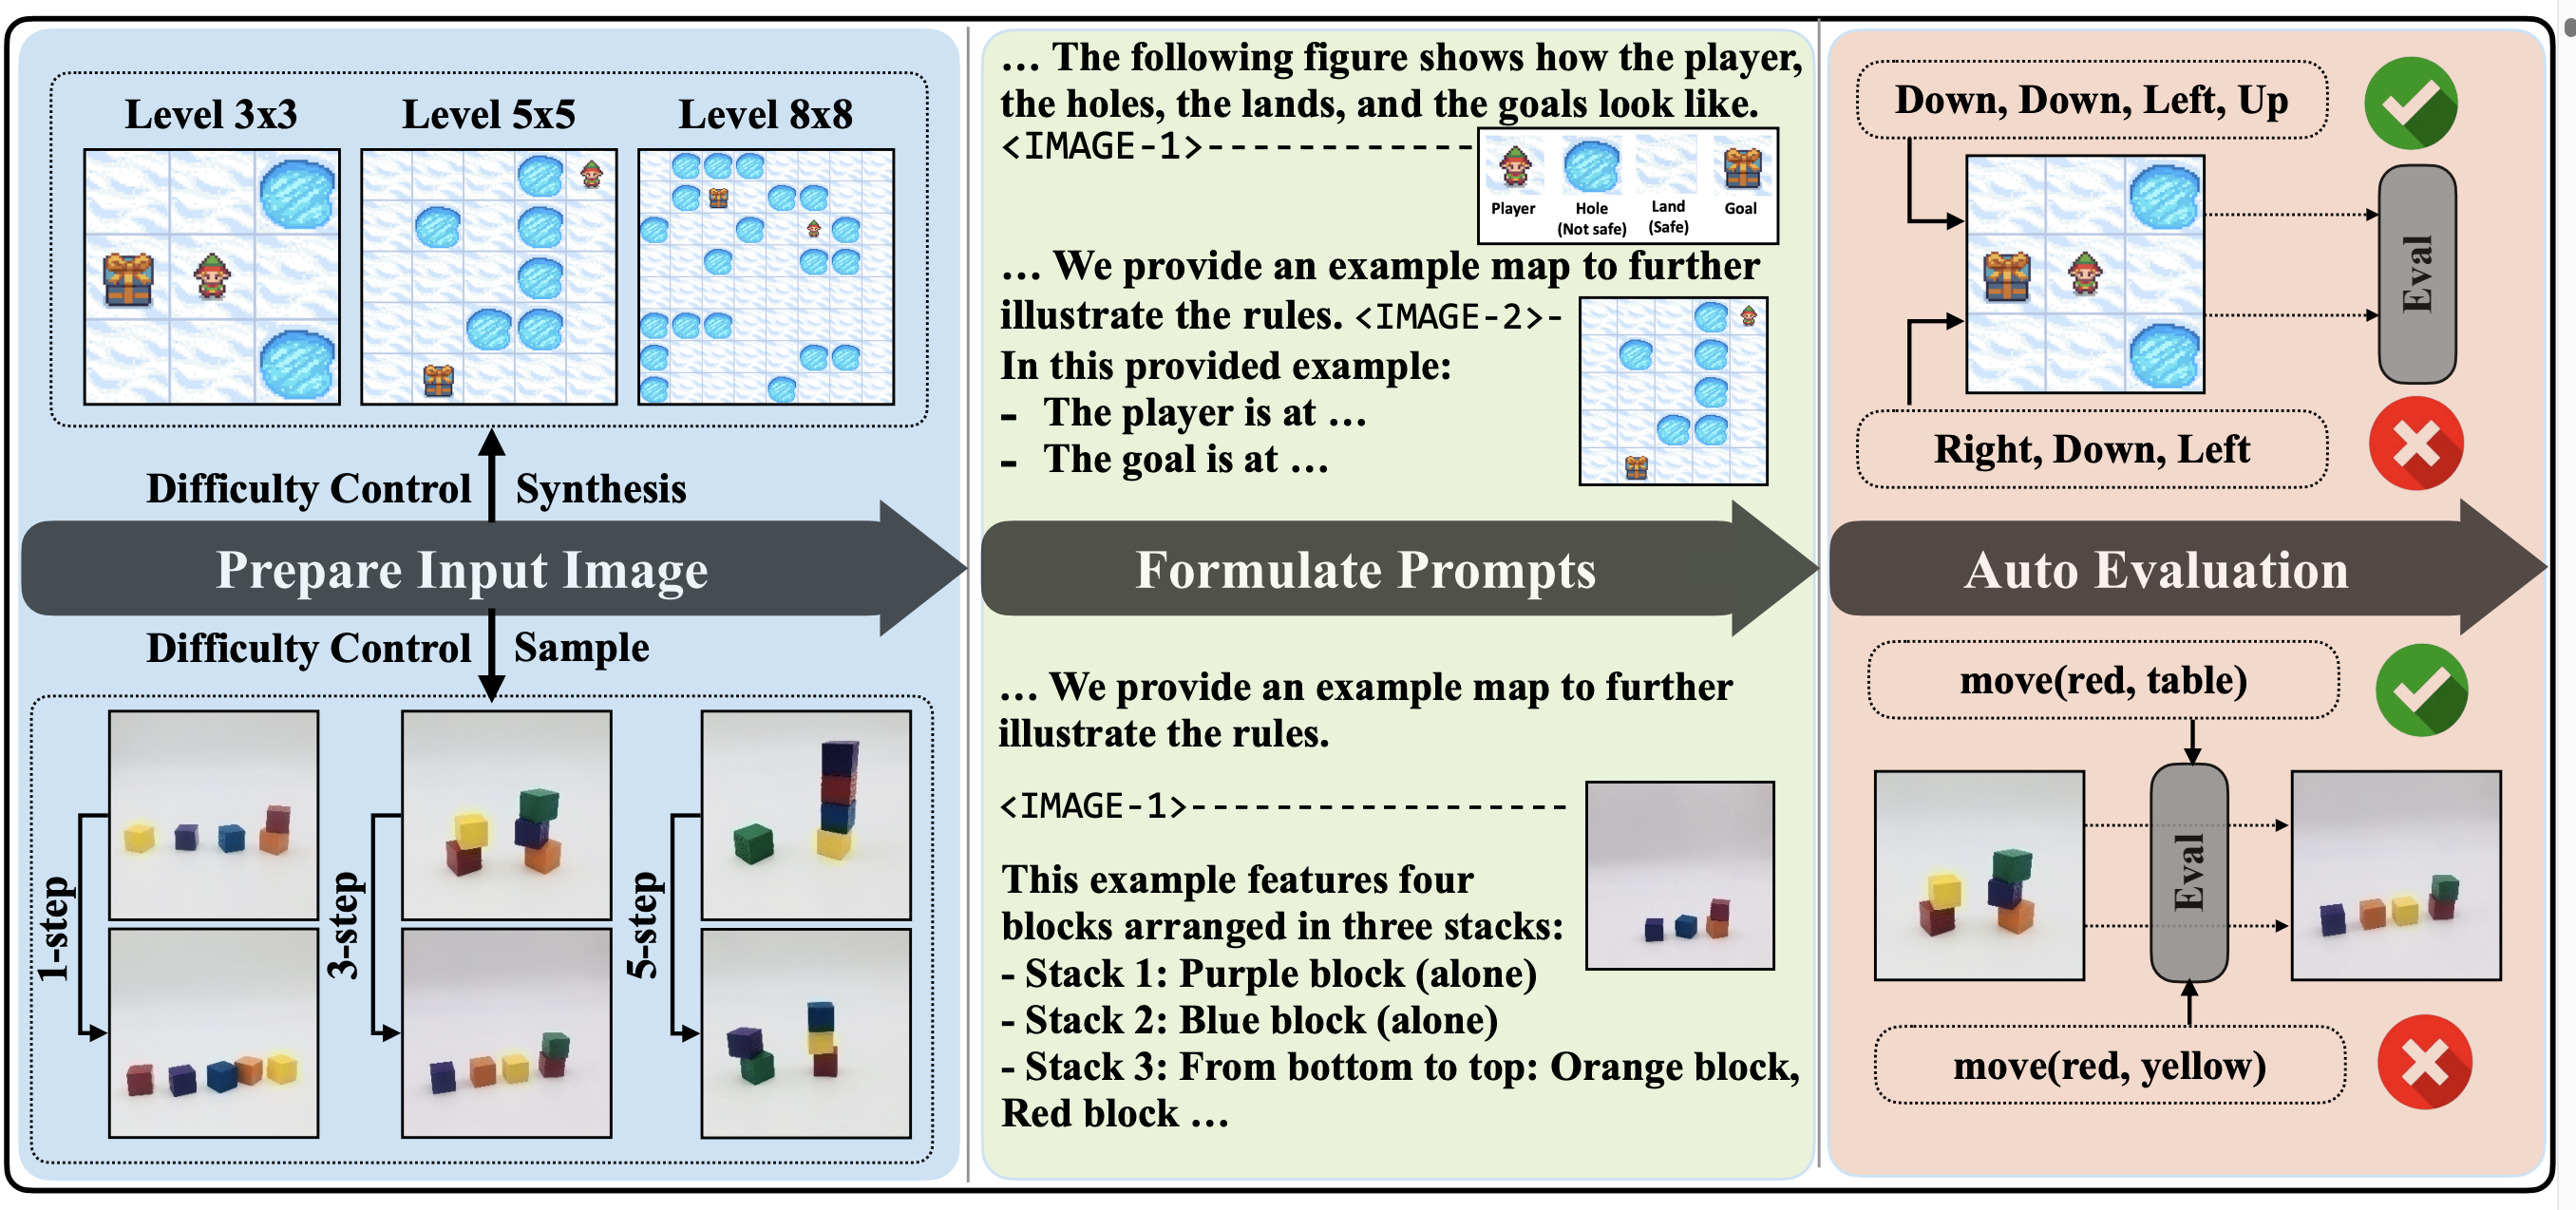
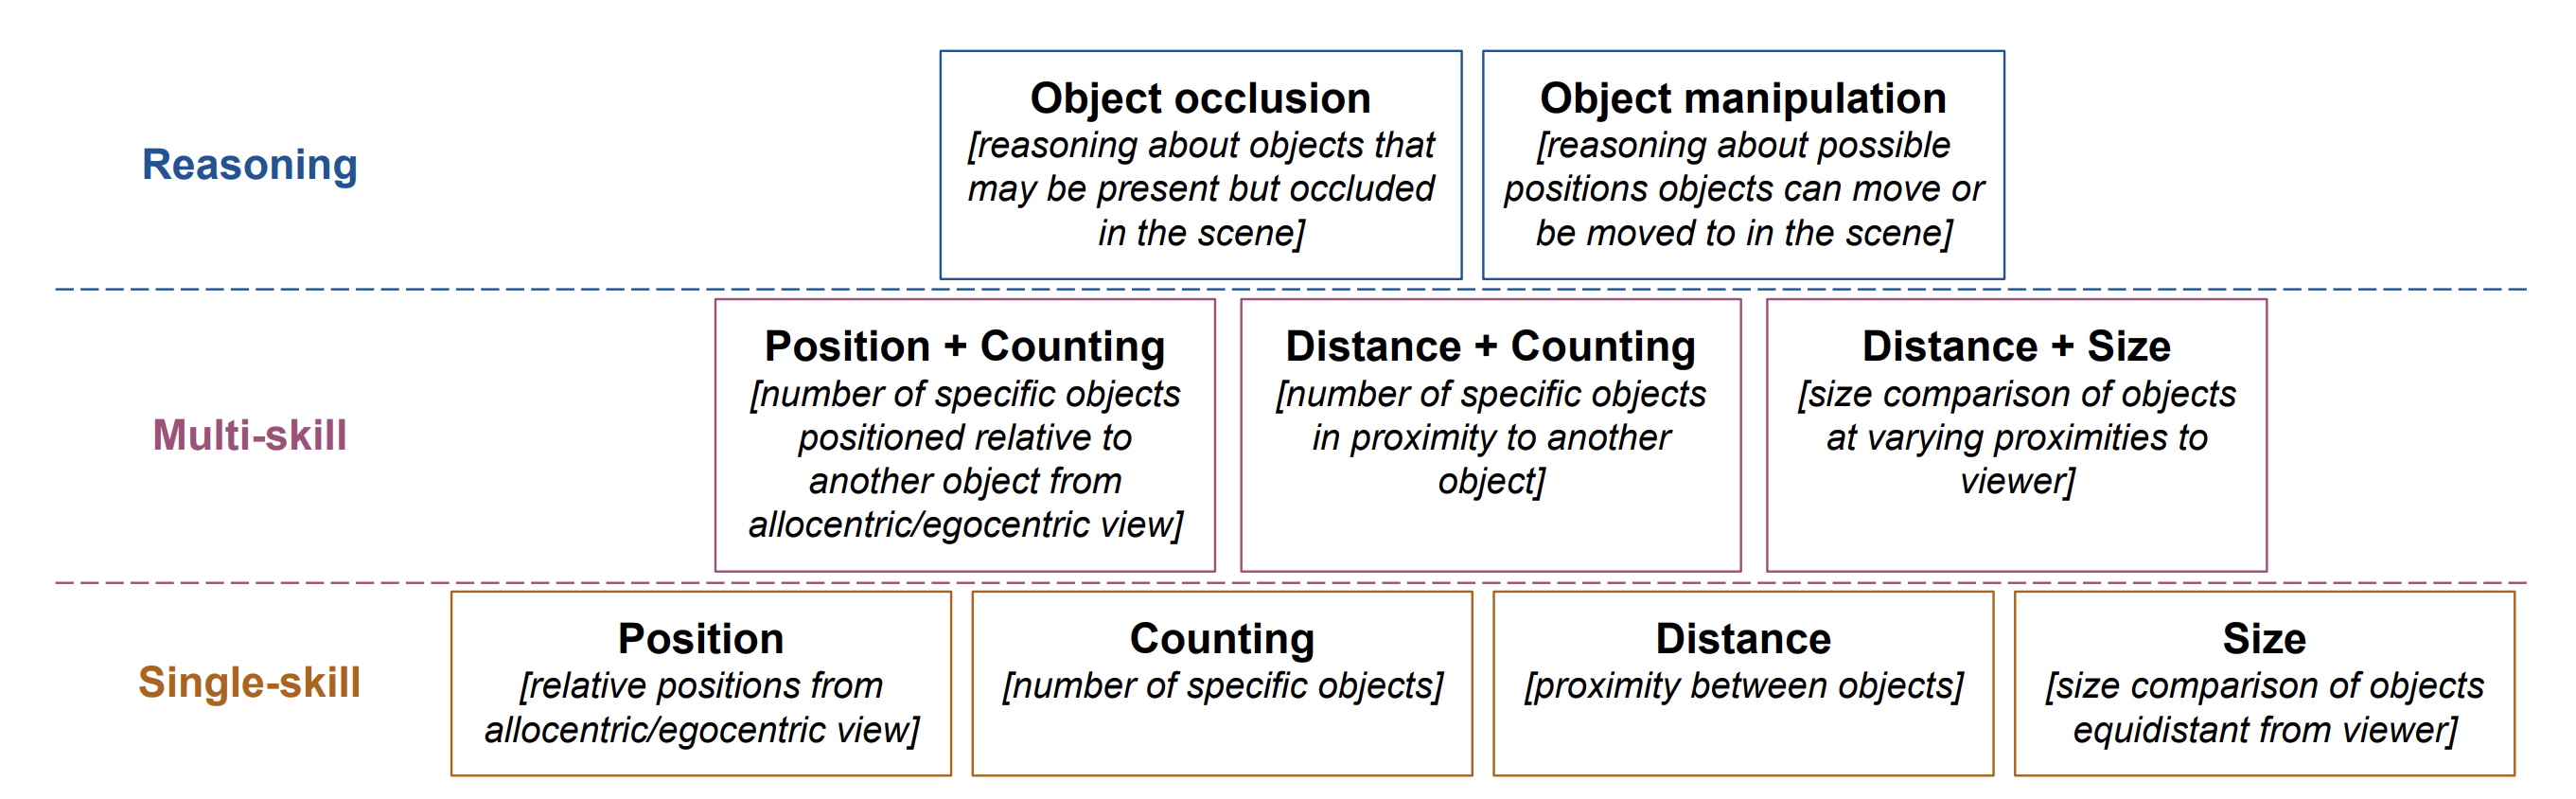
LEGO-Puzzles: How Good Are MLLMs at Multi-Step Spatial ReasoningARXIV25-03linkStar countLEGO-Puzzlesimg
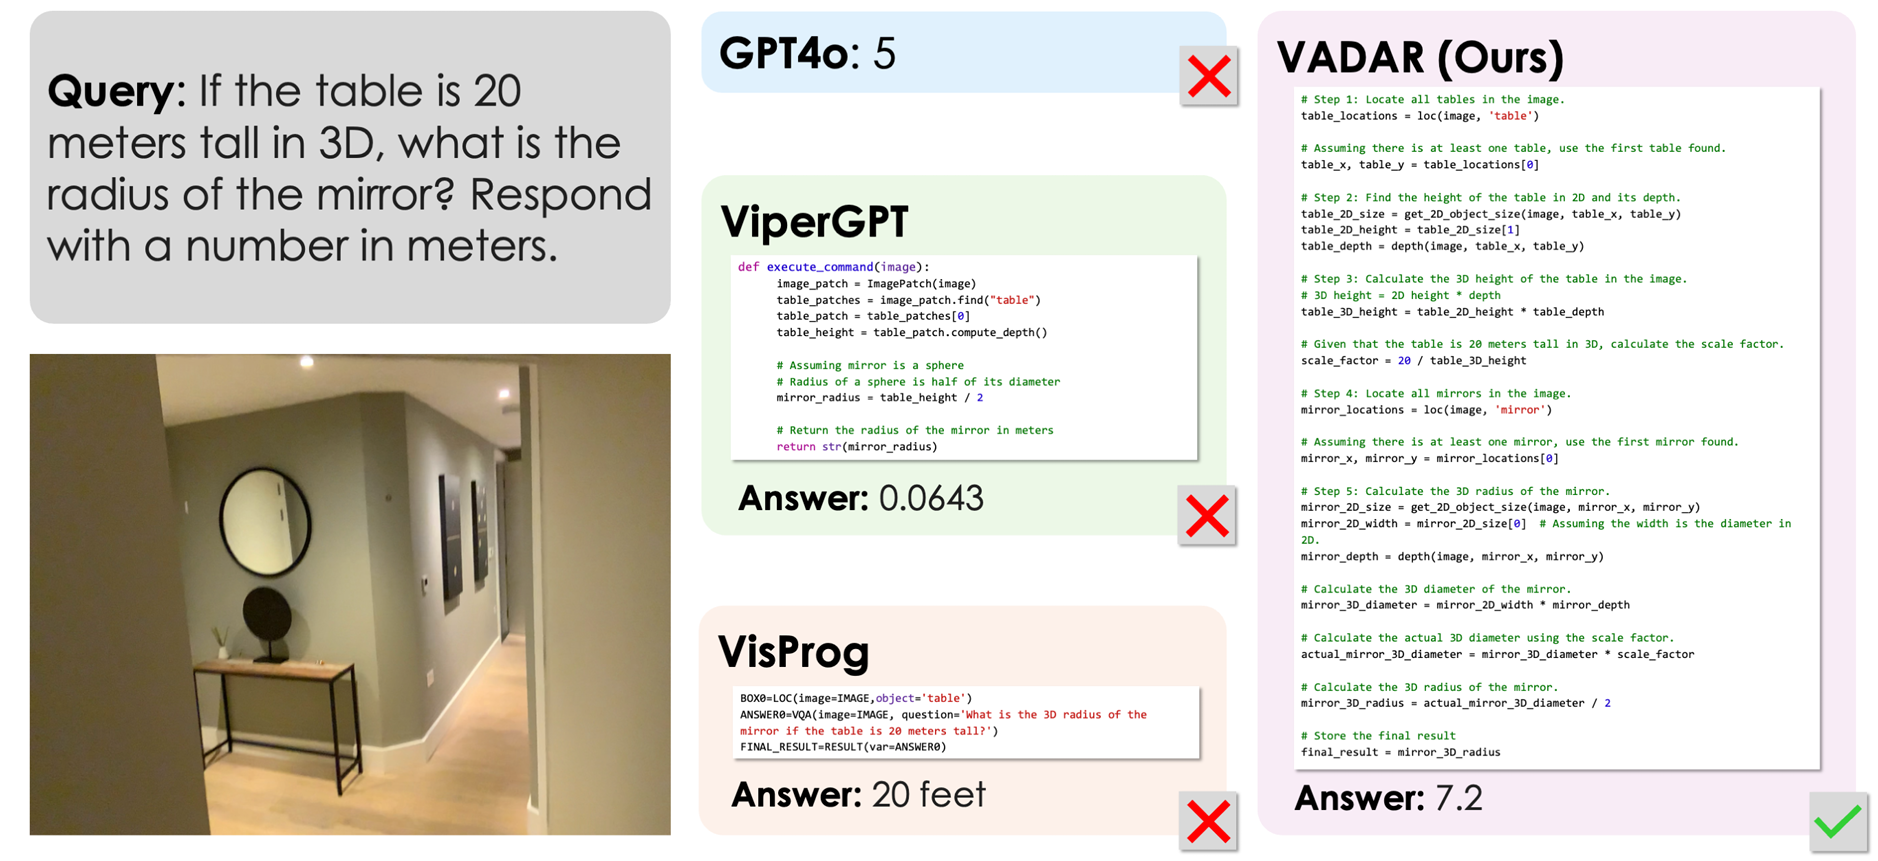
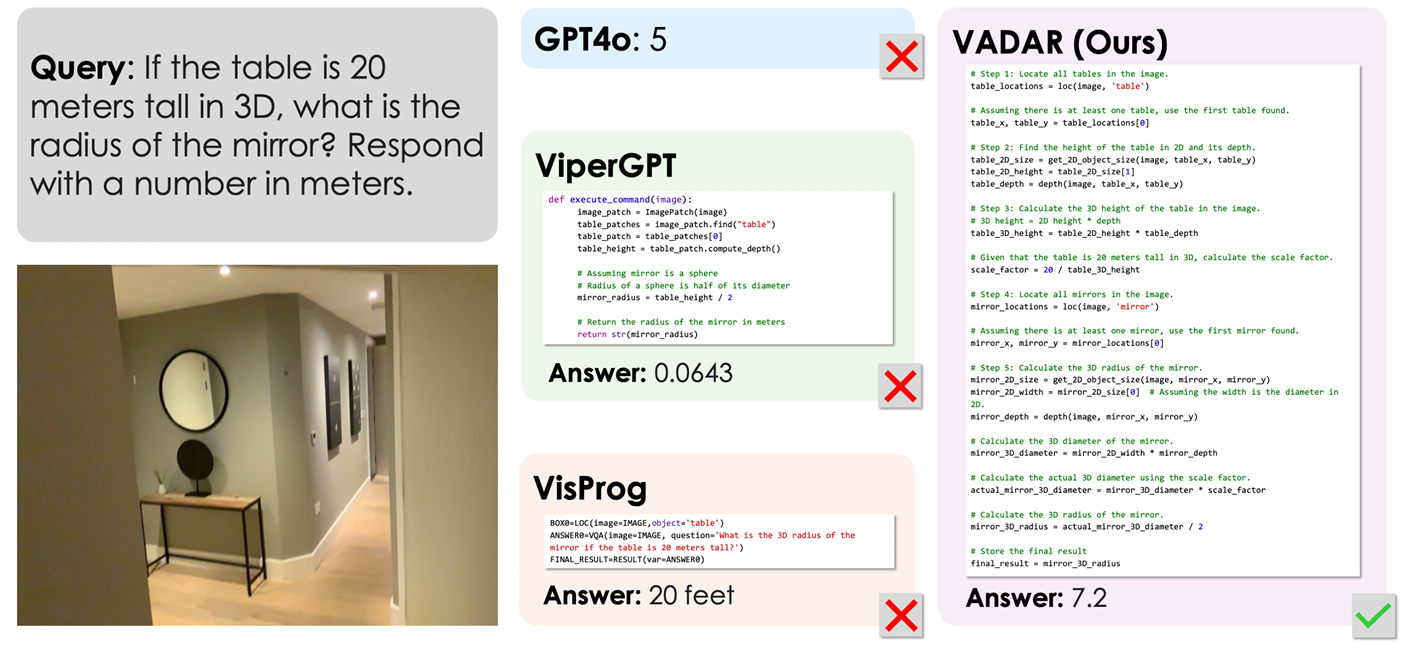
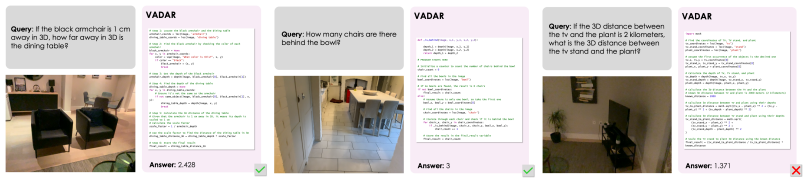
Visual Agentic AI for Spatial Reasoning with a Dynamic APIARXIV25-02linkStar count--img
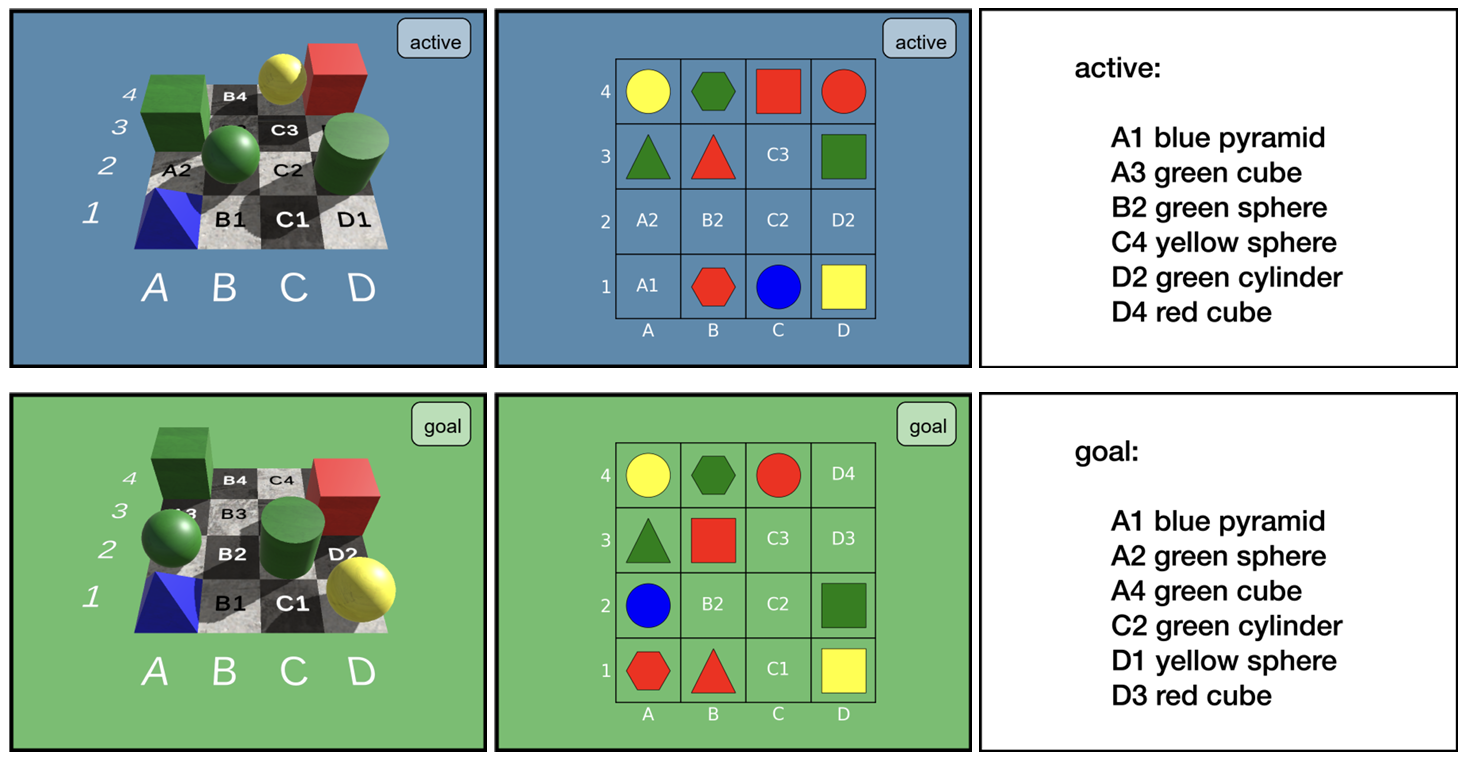
iVISPAR —AnInteractive Visual-Spatial Reasoning Benchmark for VLMsARXIV25-02linkStar countiVISPARimg
Visual Agentic AI for Spatial Reasoning with a Dynamic APIARXIV25-02linkStar countQ-Spatial Bench, VSI-Benchimg
Defining and Evaluating Visual Language Models’ Basic Spatial Abilities: A Perspective from PsychometricsARXIV25-02----BSA-Testsimg
Mitigating Hallucinations in Multimodal Spatial Relations through Constraint-Aware PromptingNAACL25-02linkStar countARO, GQA
MMRel
img
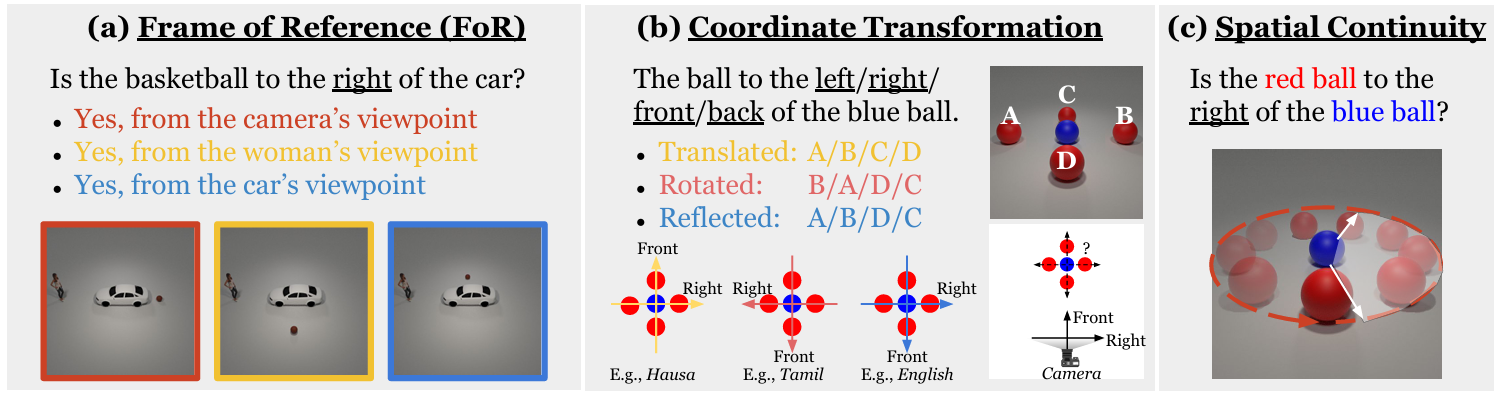
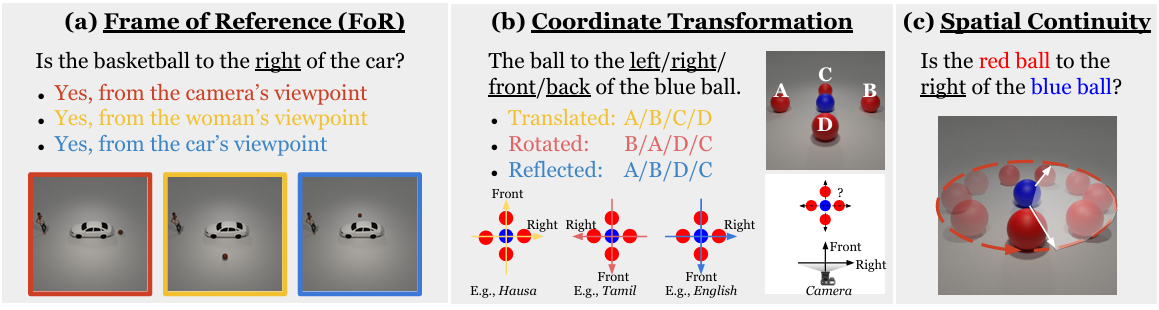
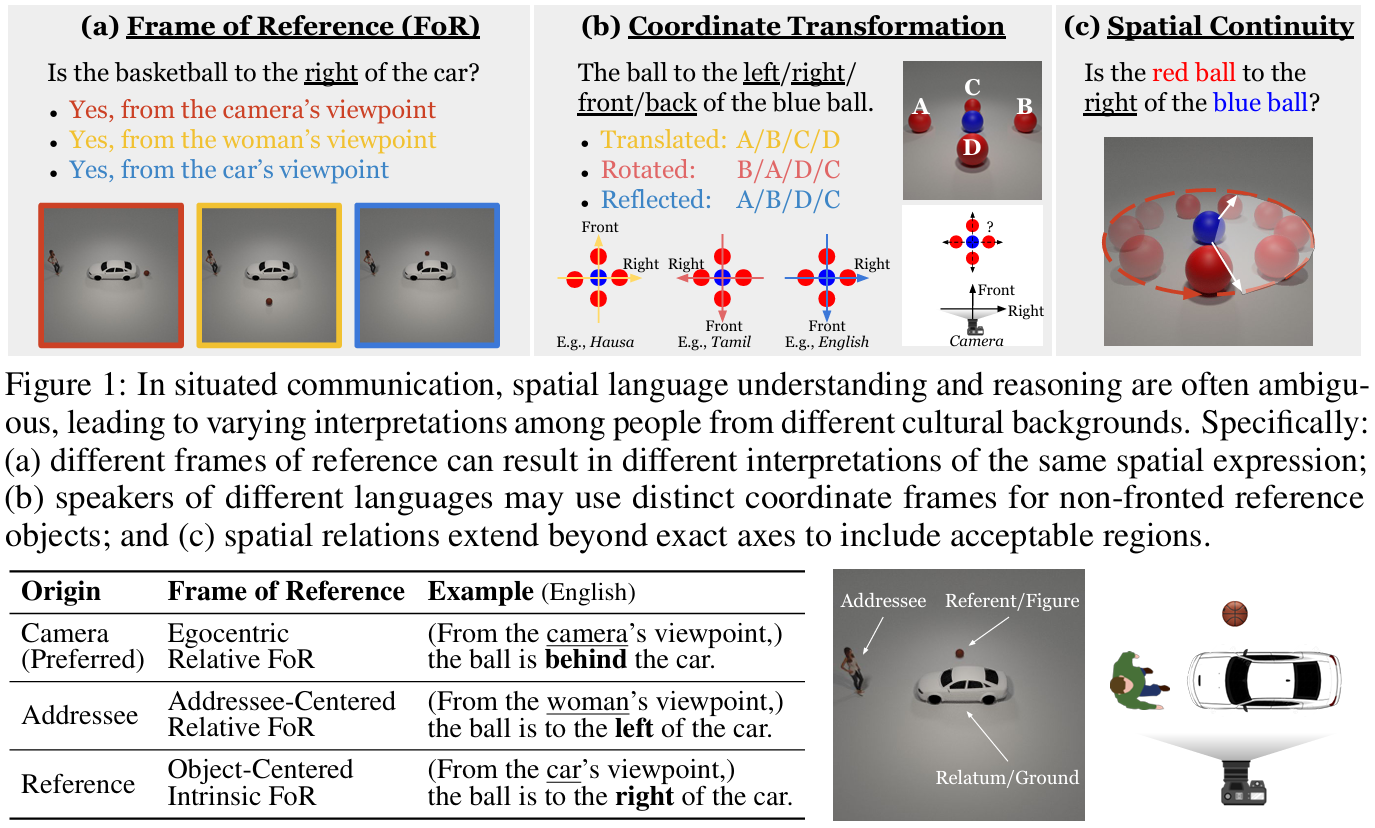
Do Vision-Language Models Represent Space and How. Evaluating Spatial Frame of Reference under AmbiguitiesICLR25-01link--COMFORTimg
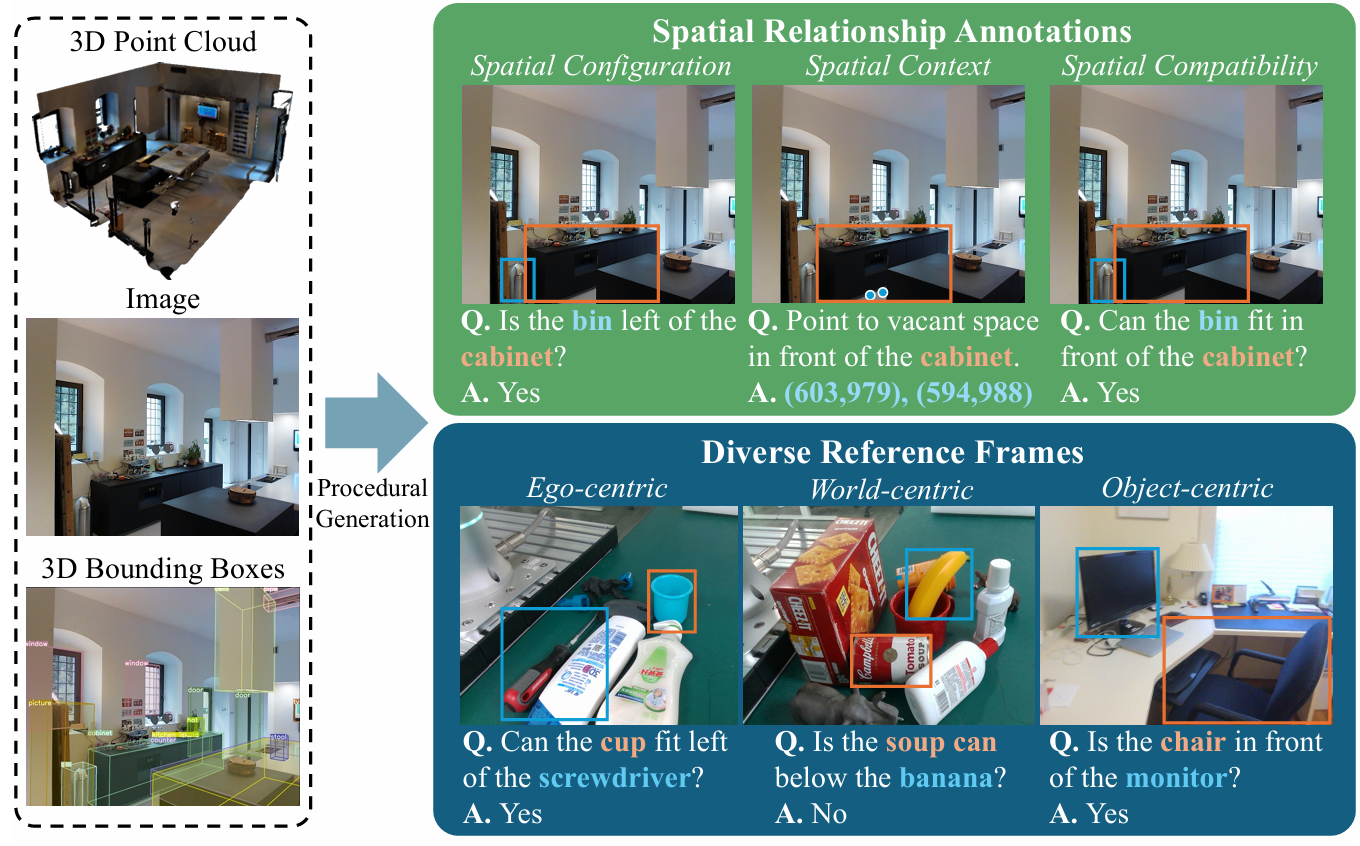
ROBOSPATIAL: Teaching Spatial Understanding to 2D and 3D Vision-Language Models for RoboticsCVPR25-01------img
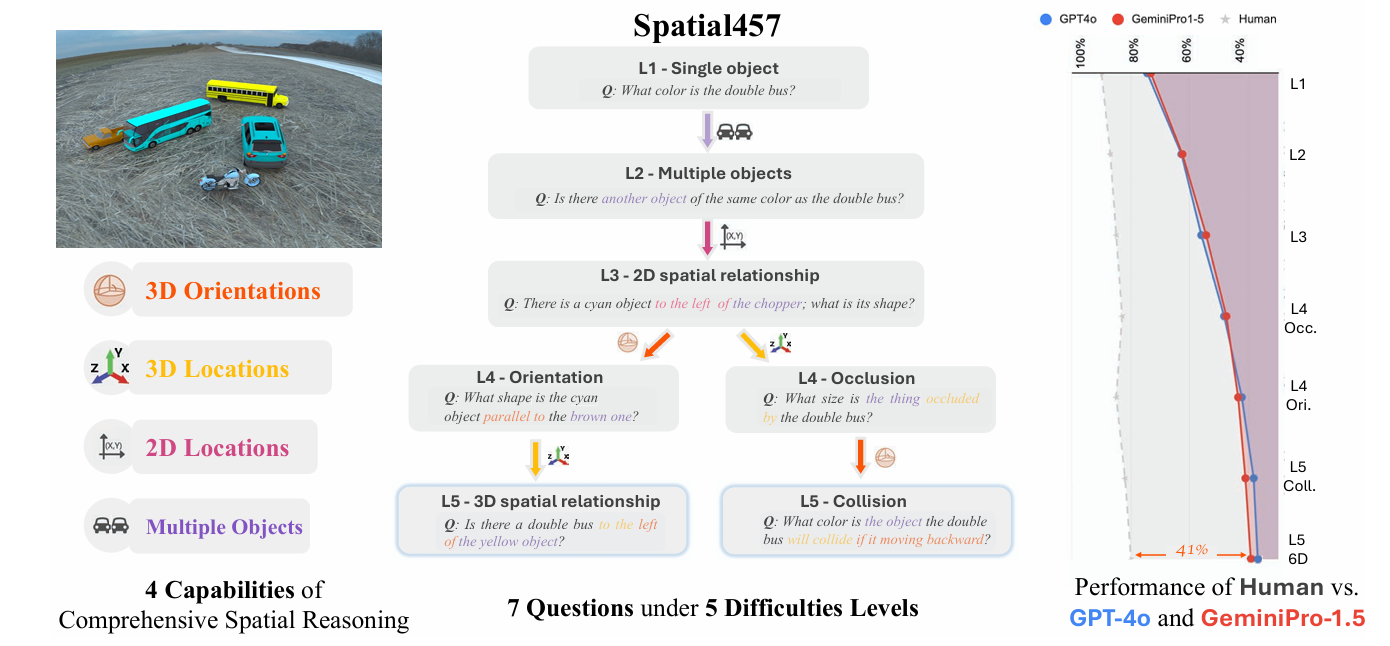
Spatial457: A Diagnostic Benchmark for 6D Spatial Reasoning of Large Multimodal ModelsCVPR25-01------img
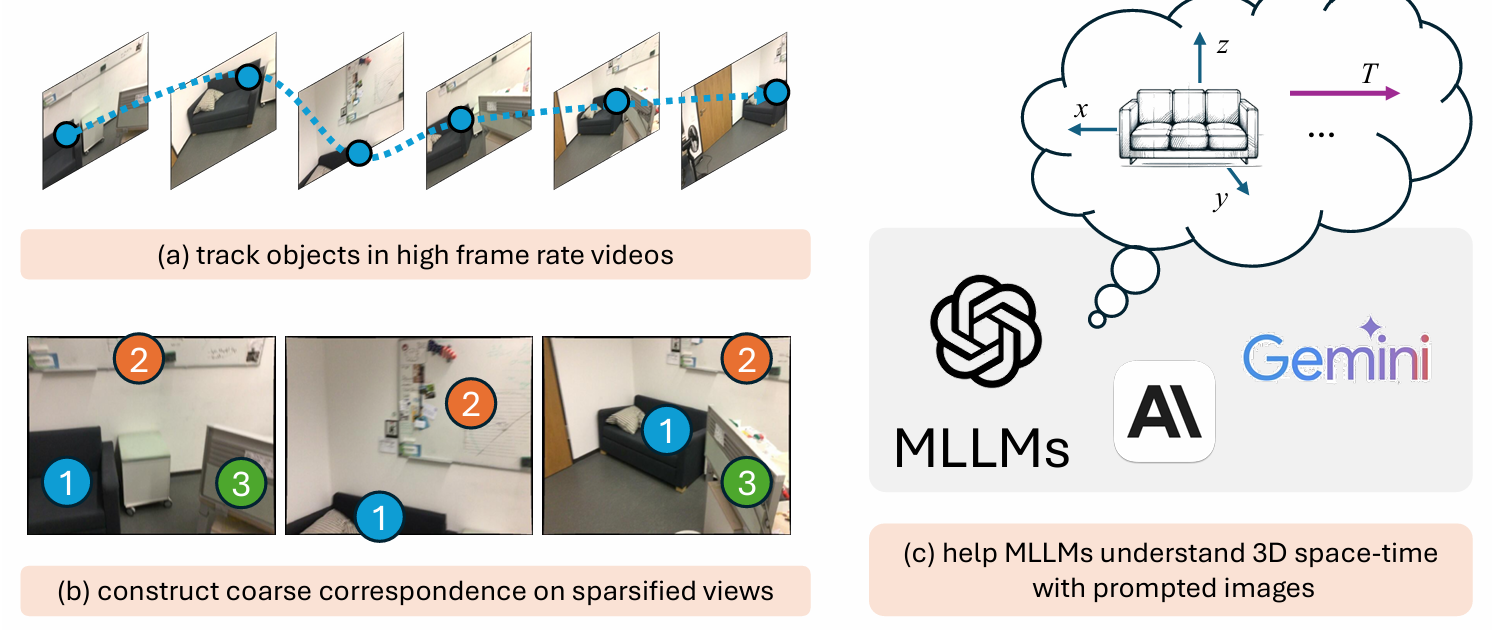
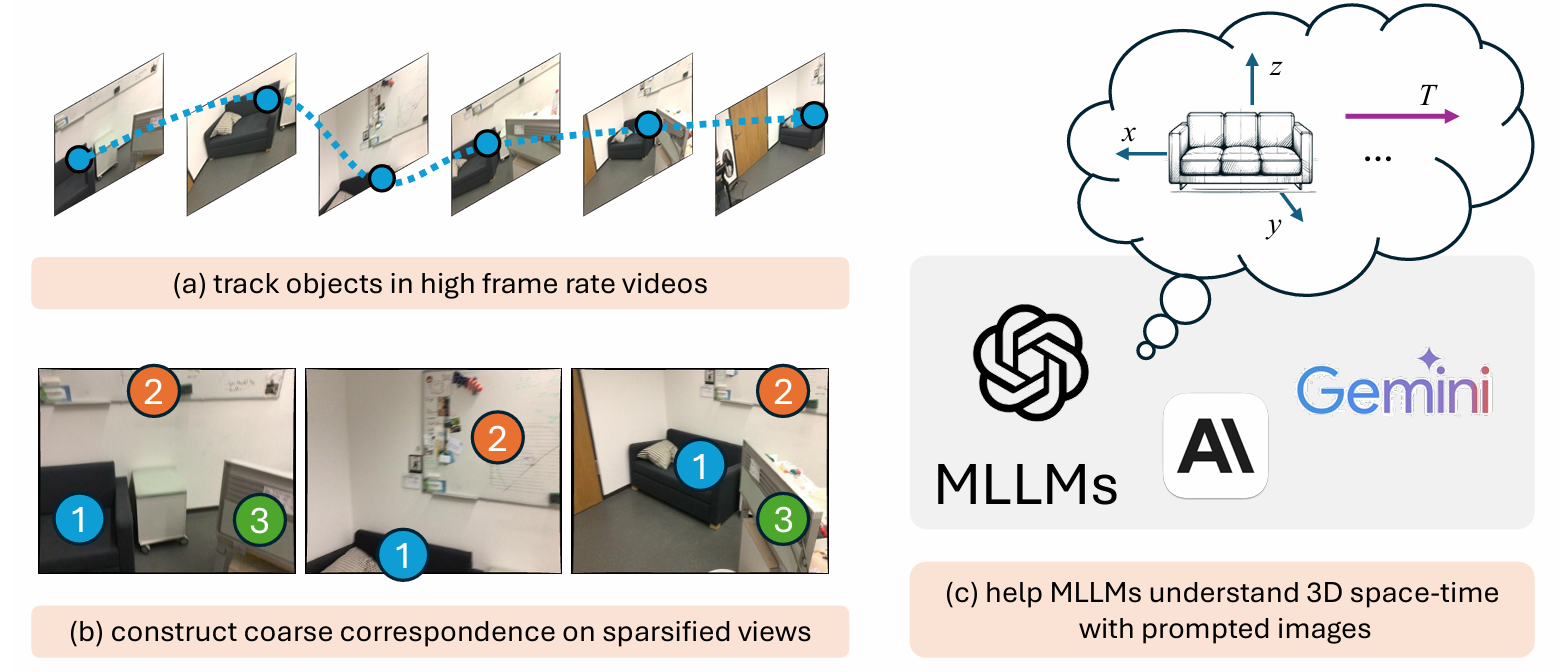
COARSE CORRESPONDENCES Boost Spatial-Temporal Reasoning in Multimodal Language ModelCVPR25-01link----img
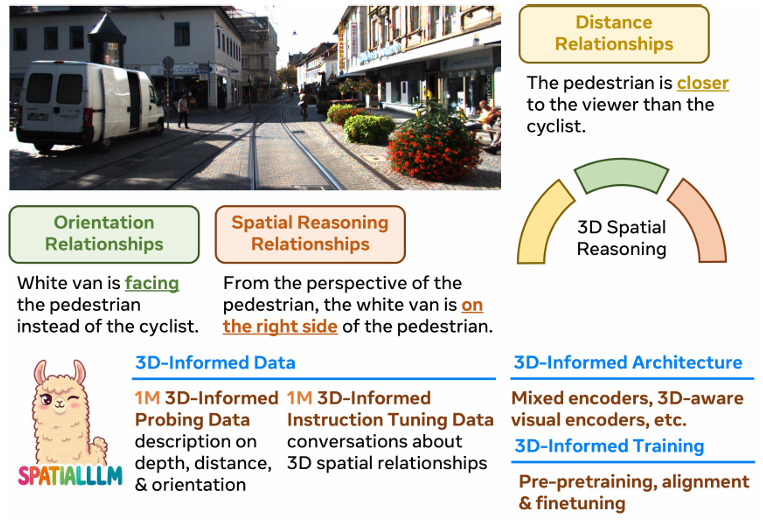
SpatialLLM: A Compound 3D-Informed Design towards Spatially-Intelligent Large Multimodal ModelsCVPR25-01link----img
SpatialCLIP: Learning 3D-aware Image Representations from Spatially Discriminative LanguageCVPR25-01linkStar countSpatialBenchimg
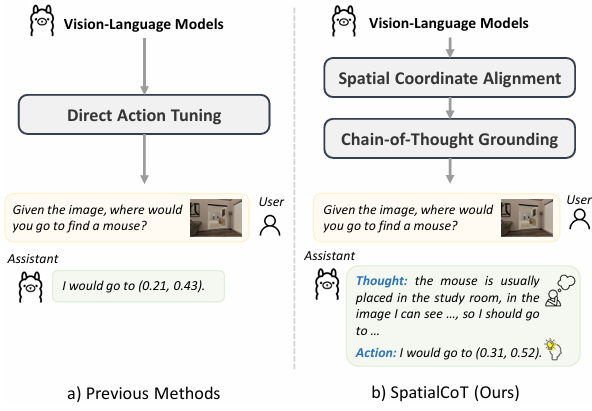
SpatialCoT: Advancing Spatial Reasoning through Coordinate Alignment and Chain-of-Thought for Embodied Task PlanningARXIV25-01------img
ReasonGrounder: LVLM-Guided Hierarchical Feature Splatting for Open-Vocabulary 3D Visual Grounding and ReasoningCVPR25-01link--ReasoningGDimg
Imagine while Reasoning in Space: Multimodal Visualization-of-ThoughtARXIV25-01----LEC23, WMS+24
LZZ+24, RDT+24
img
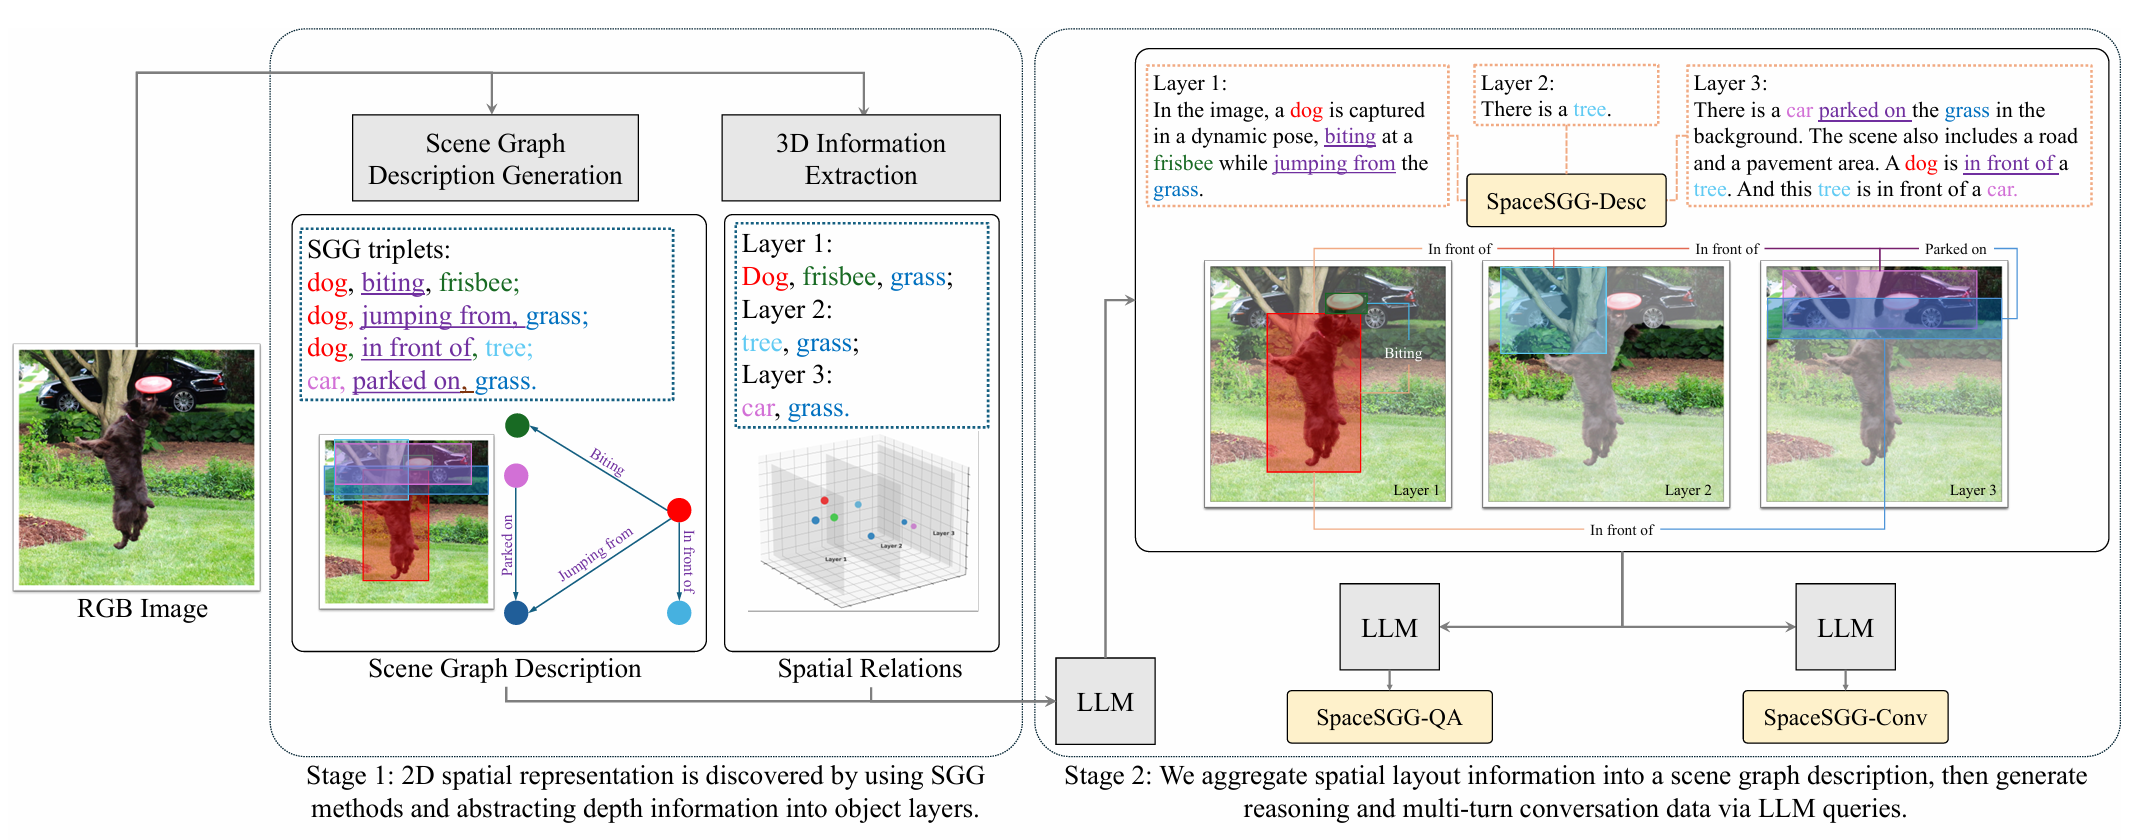
LLaVA-SpaceSGG: Visual Instruct Tuning for Open-vocabulary Scene Graph Generation with Enhanced Spatial RelationsARXIV24-12linkStar countSpaceSGGimg
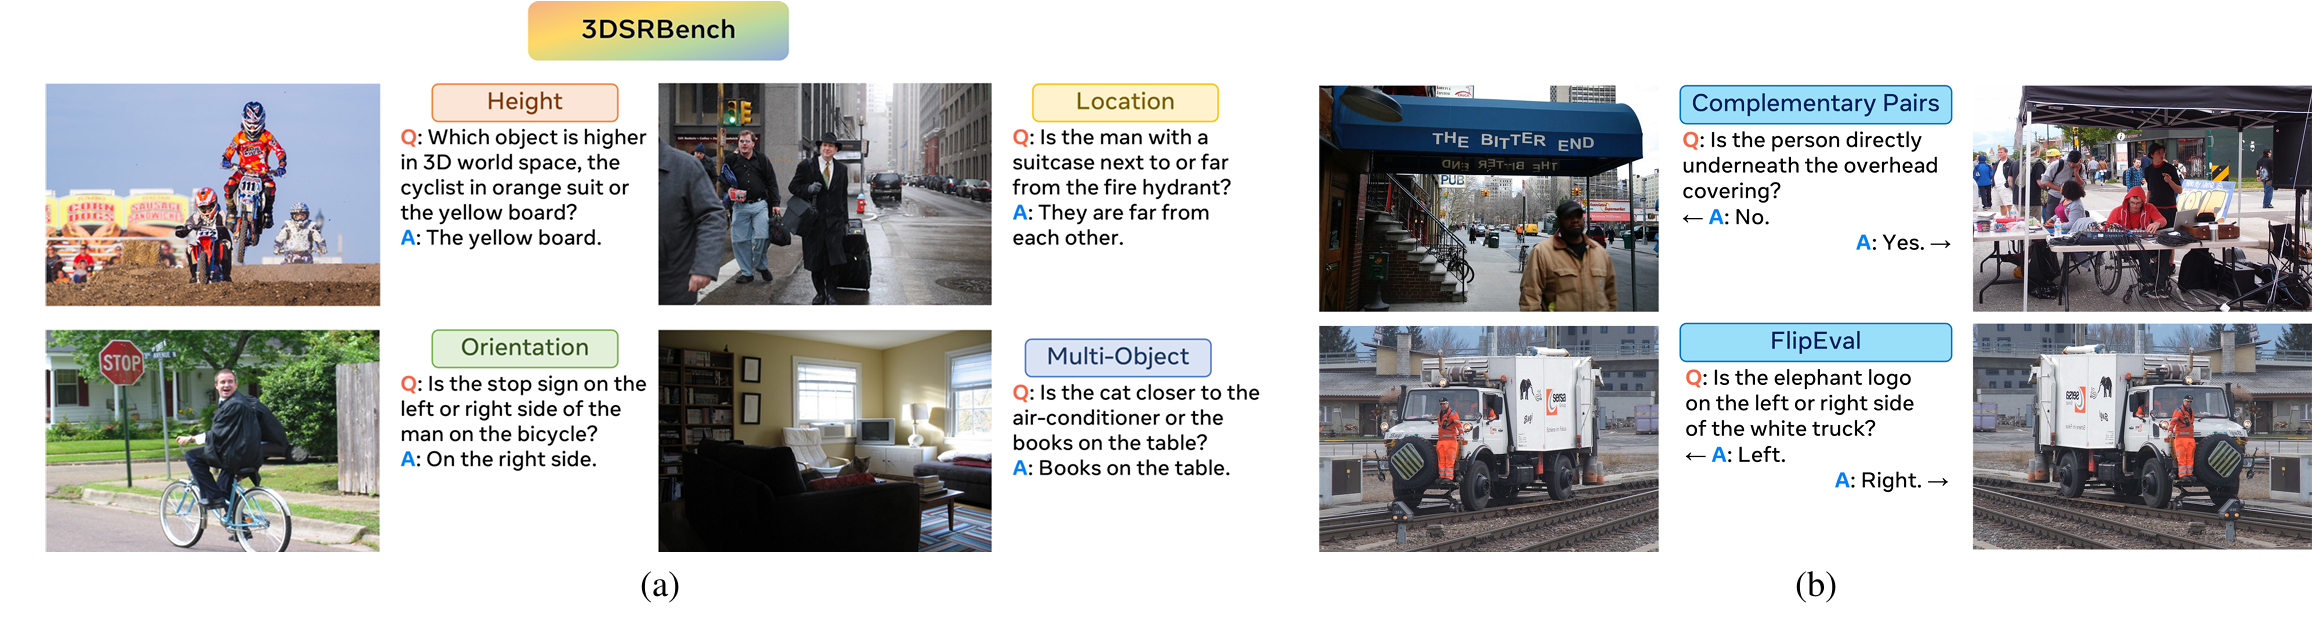
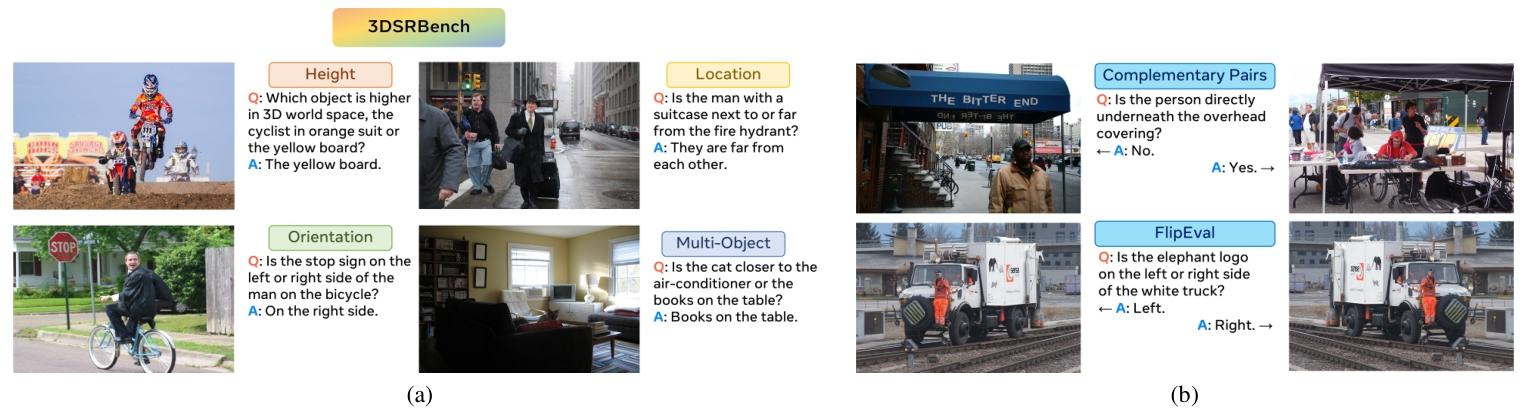
3DSRBench: A Comprehensive 3D Spatial Reasoning BenchmarkARXIV24-12link--3DSRBenchimg
SPHERE: Unveiling Spatial Blind Spots in Vision-Language Models Through Hierarchical EvaluationACL24-12linkStar countSPHEREimg
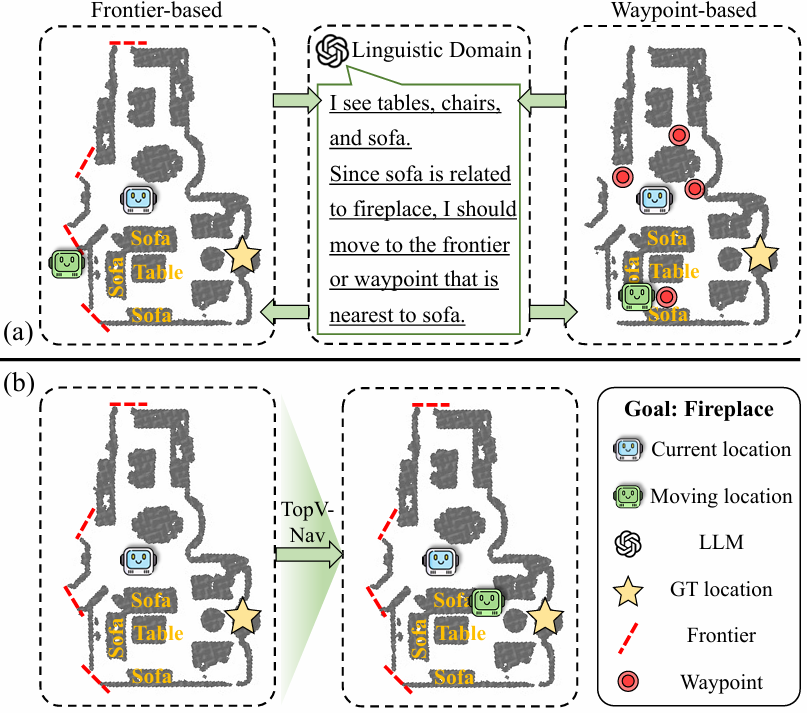
TopV-Nav: Unlocking the Top-View Spatial Reasoning Potential of MLLM for Zero-shot Object NavigationARXIV24-11------img
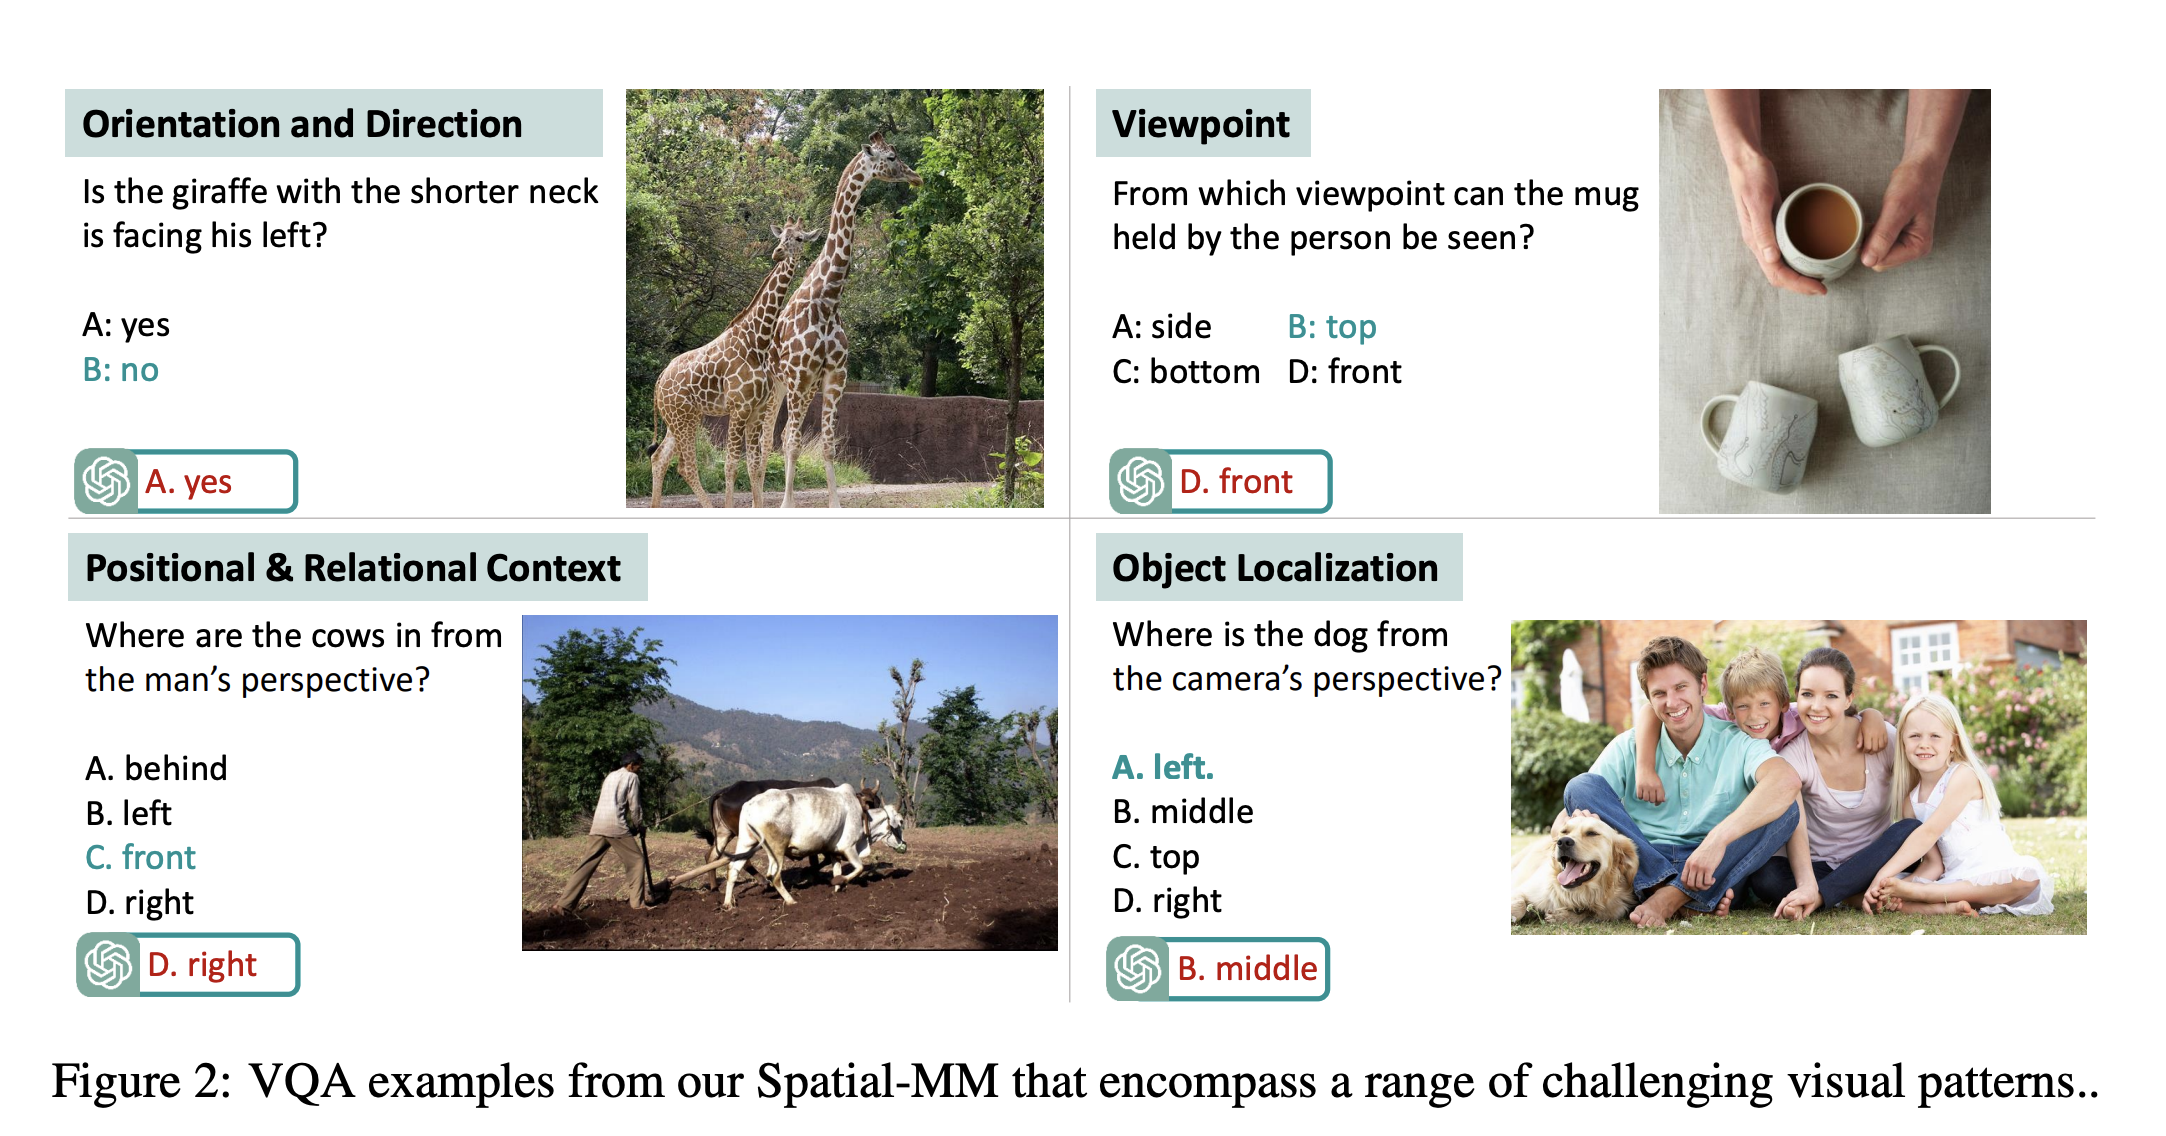
AnEmpirical Analysis on Spatial Reasoning Capabilities of Large Multimodal ModelsEMNLP24-11linkStar countSpatial-MMimg
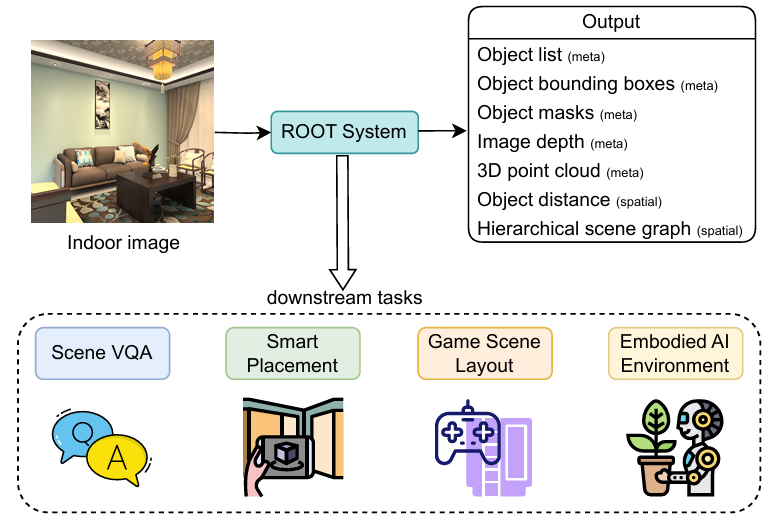
ROOT: VLM-based System for Indoor Scene Understanding and BeyondARXIV24-11linkStar countSceneVLMimg
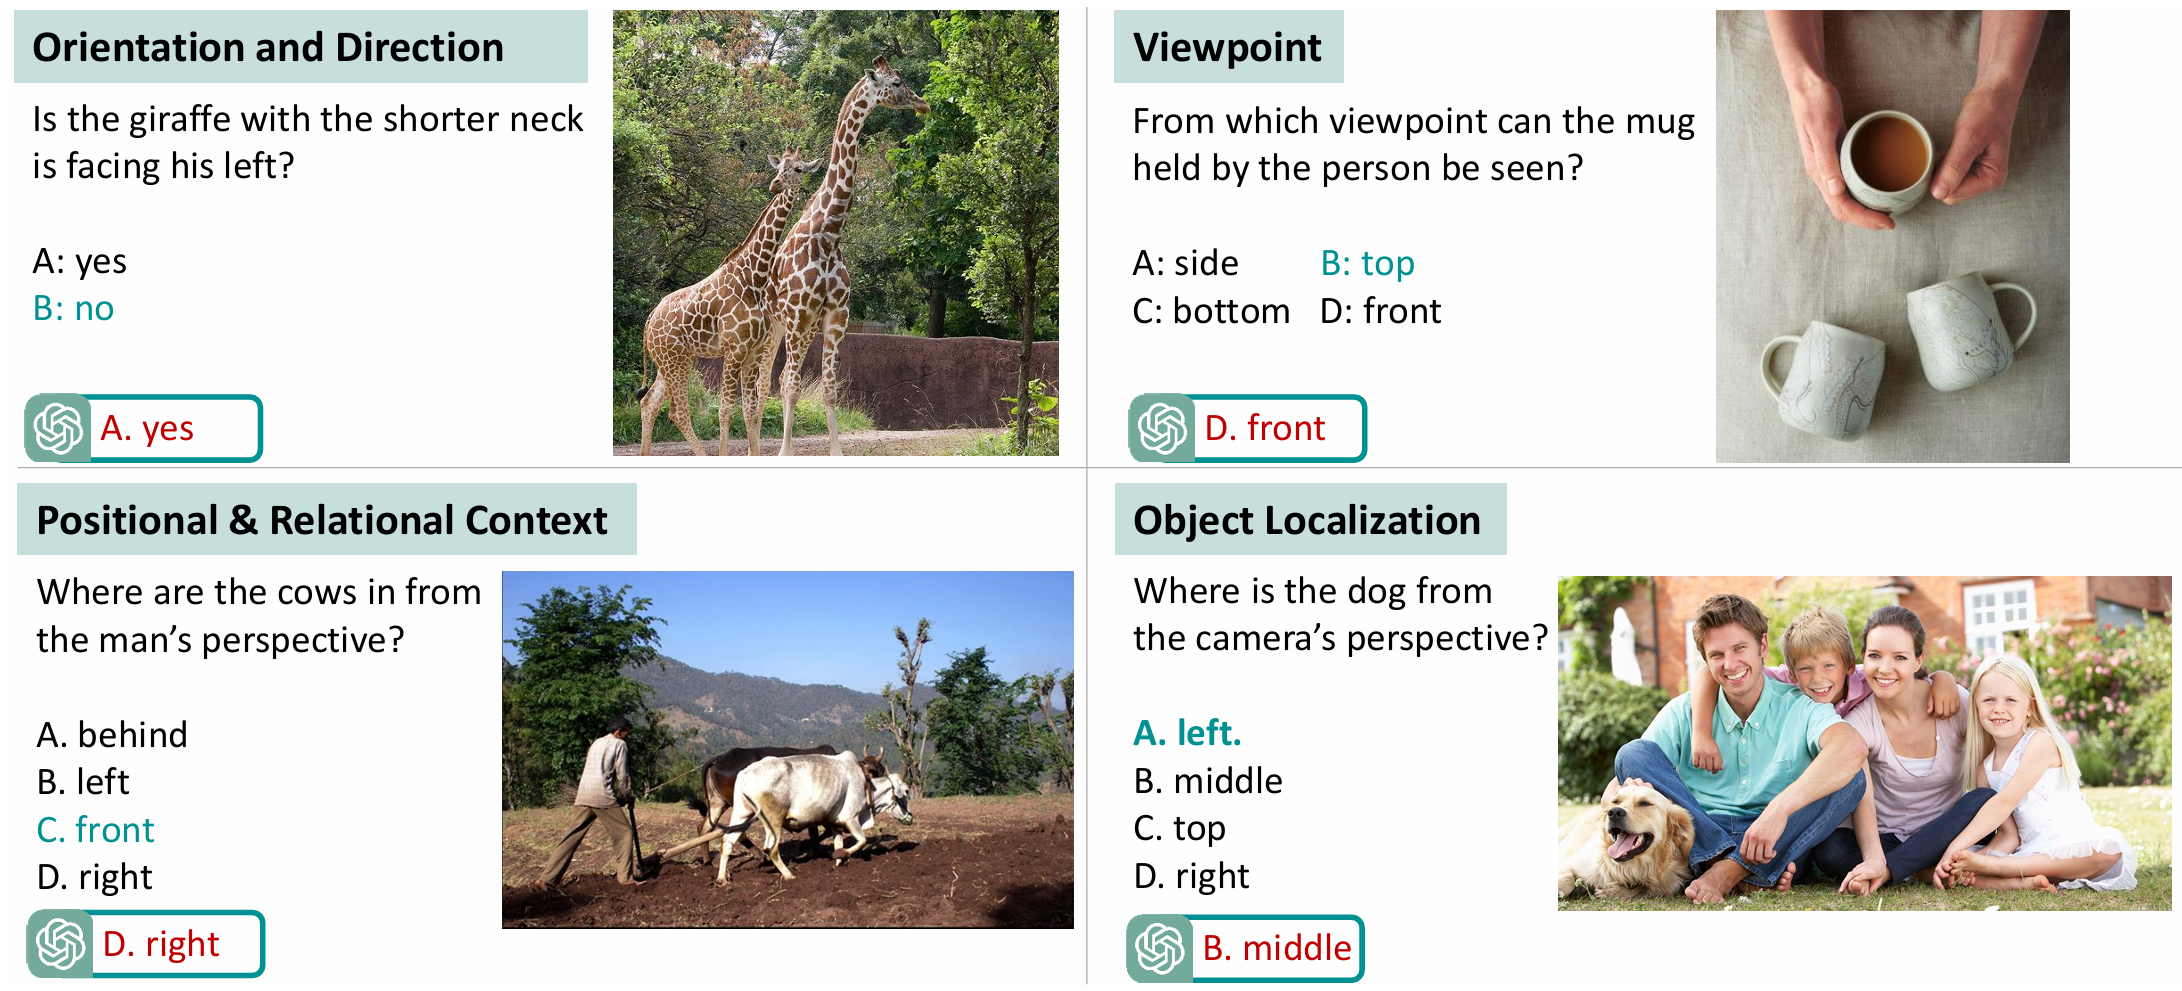
An Empirical Analysis on Spatial Reasoning Capabilities of Large Multimodal ModelsEMNLP 202424-11linkStar countSpatial-MM, GQA-spatialimg
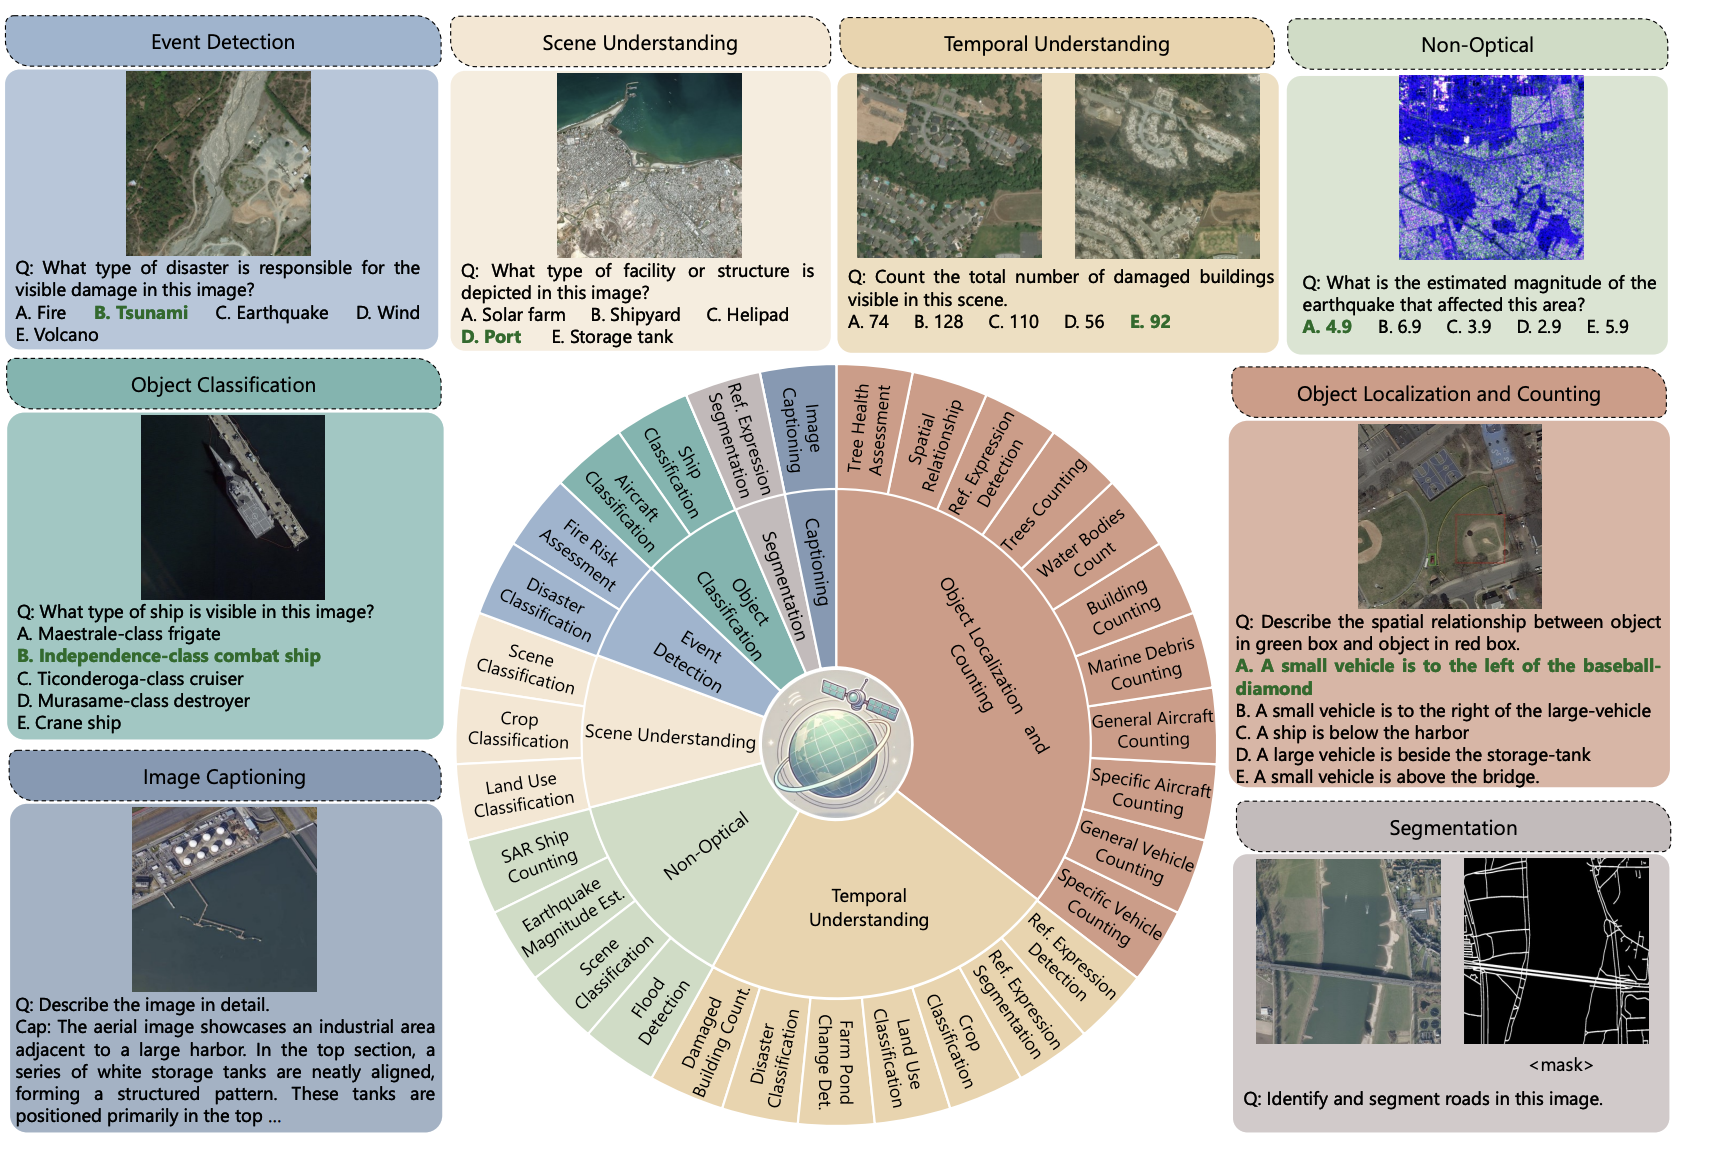
GEOBench-VLM: Benchmarking Vision-Language Models for Geospatial TasksARXIV24-11linkStar countGEOBench-VLMimg
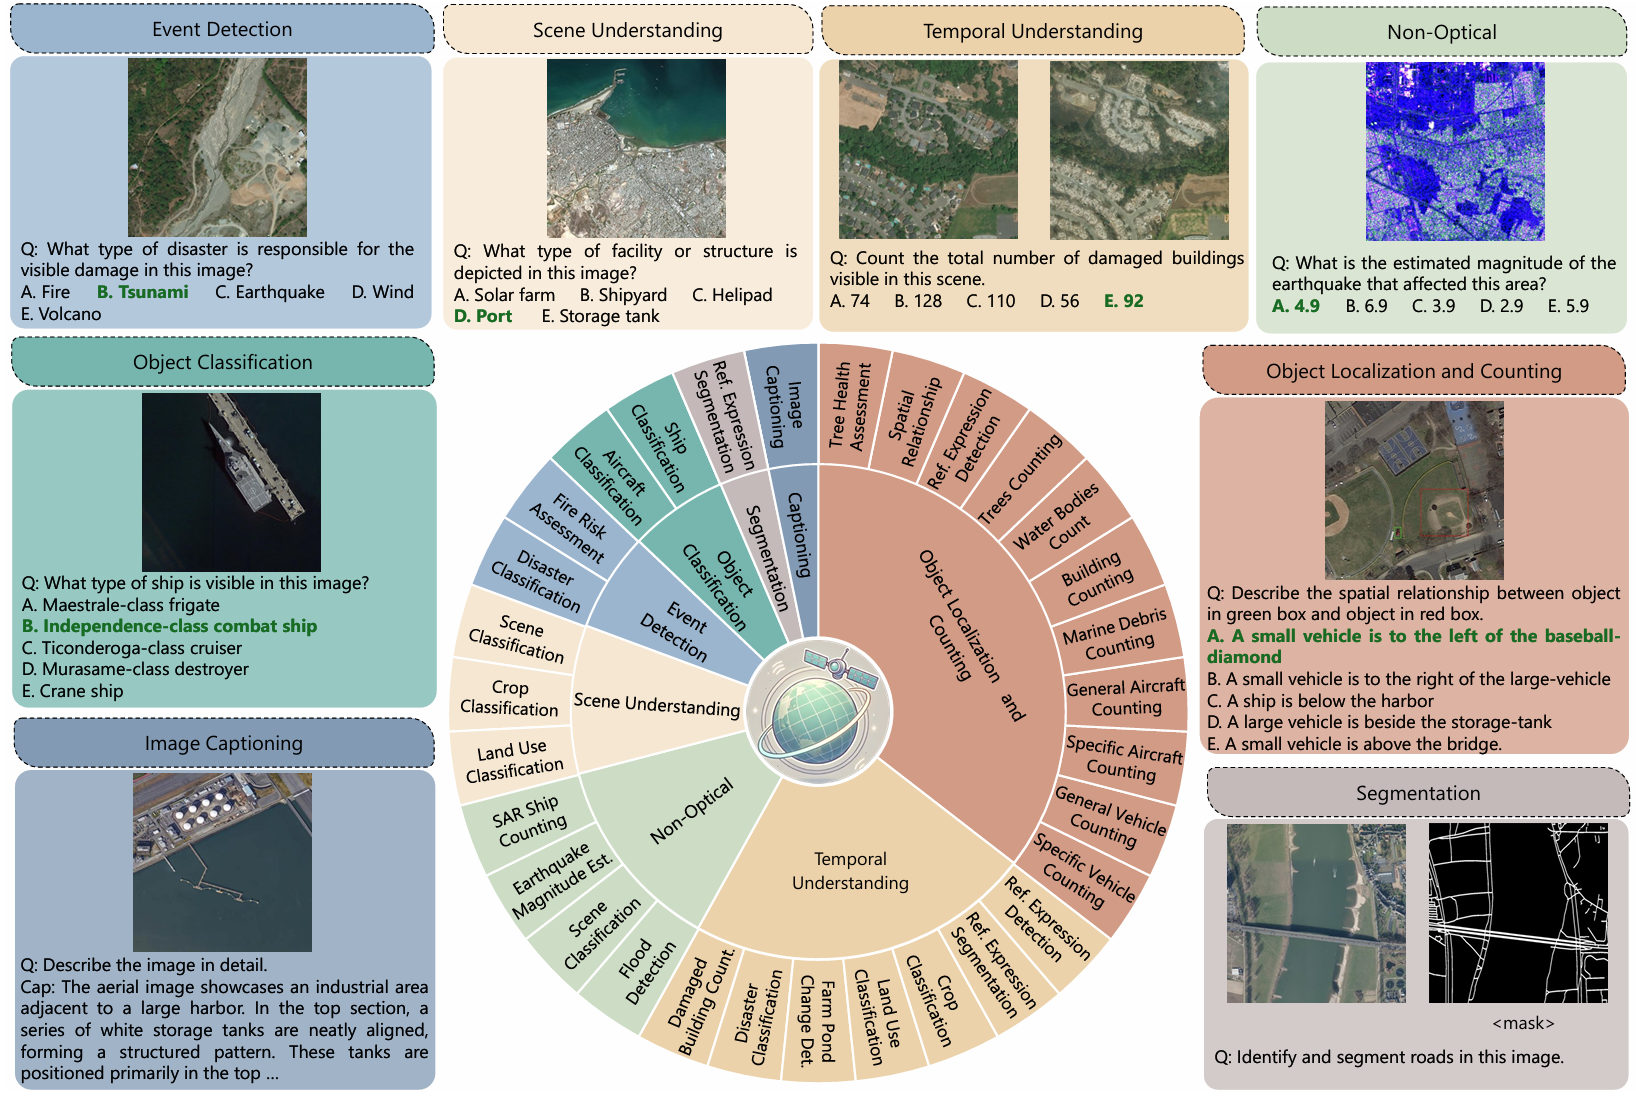
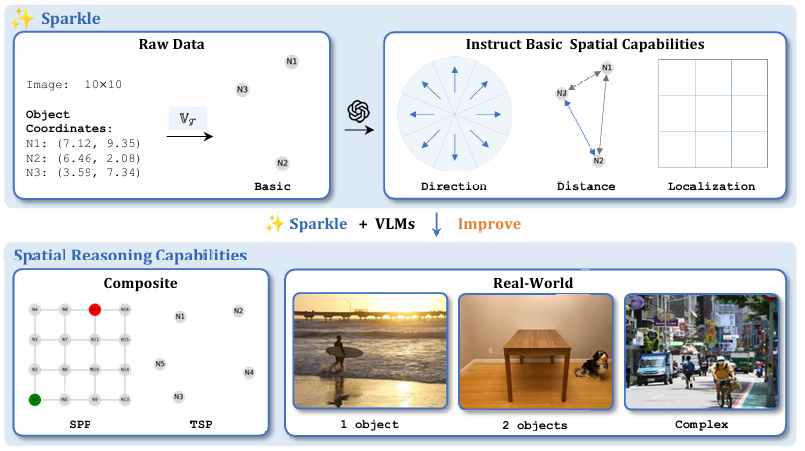
Sparkle: Mastering Basic Spatial Capabilities in Vision Language Models Elicits Generalization to Spatial ReasoningNIPS24-10----what's up, coco-spatial
GQA-spatial
img
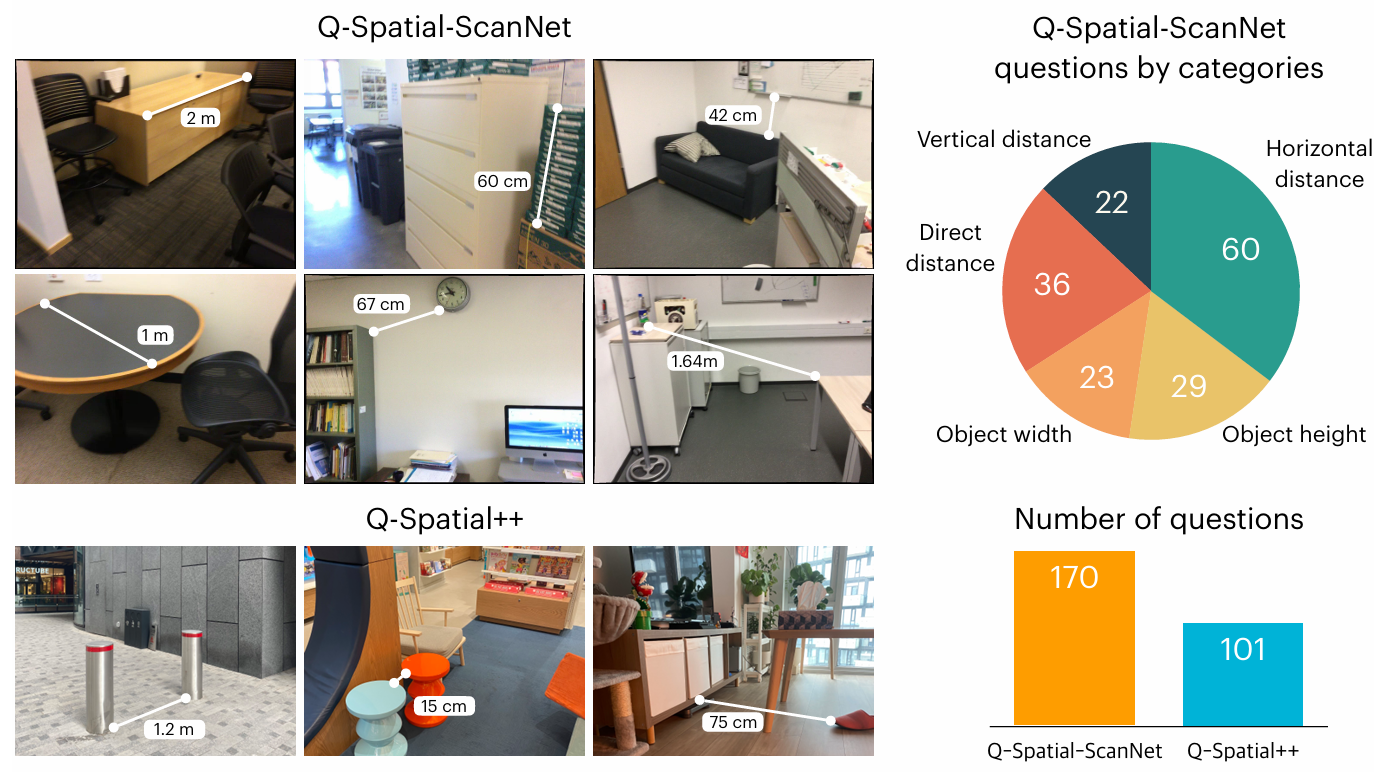
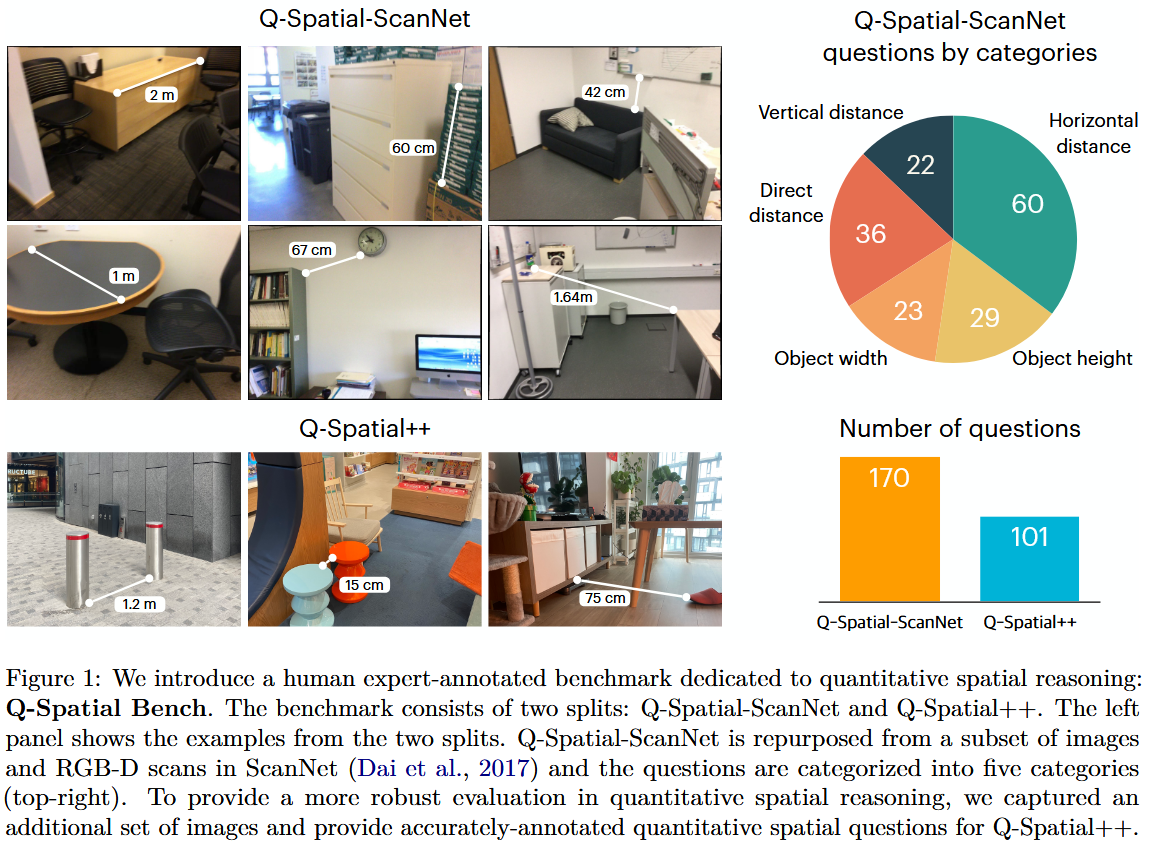
Reasoning Paths with Reference Objects Elicit Quantitative Spatial Reasoning in Large Vision-Language ModelsARXIV24-09linkStar countQ-Spatial Benchimg
Can Vision Language Models Learn from Visual Demonstrations of Ambiguous Spatial Reasoning?ARXIV24-09linkStar countSVATimg
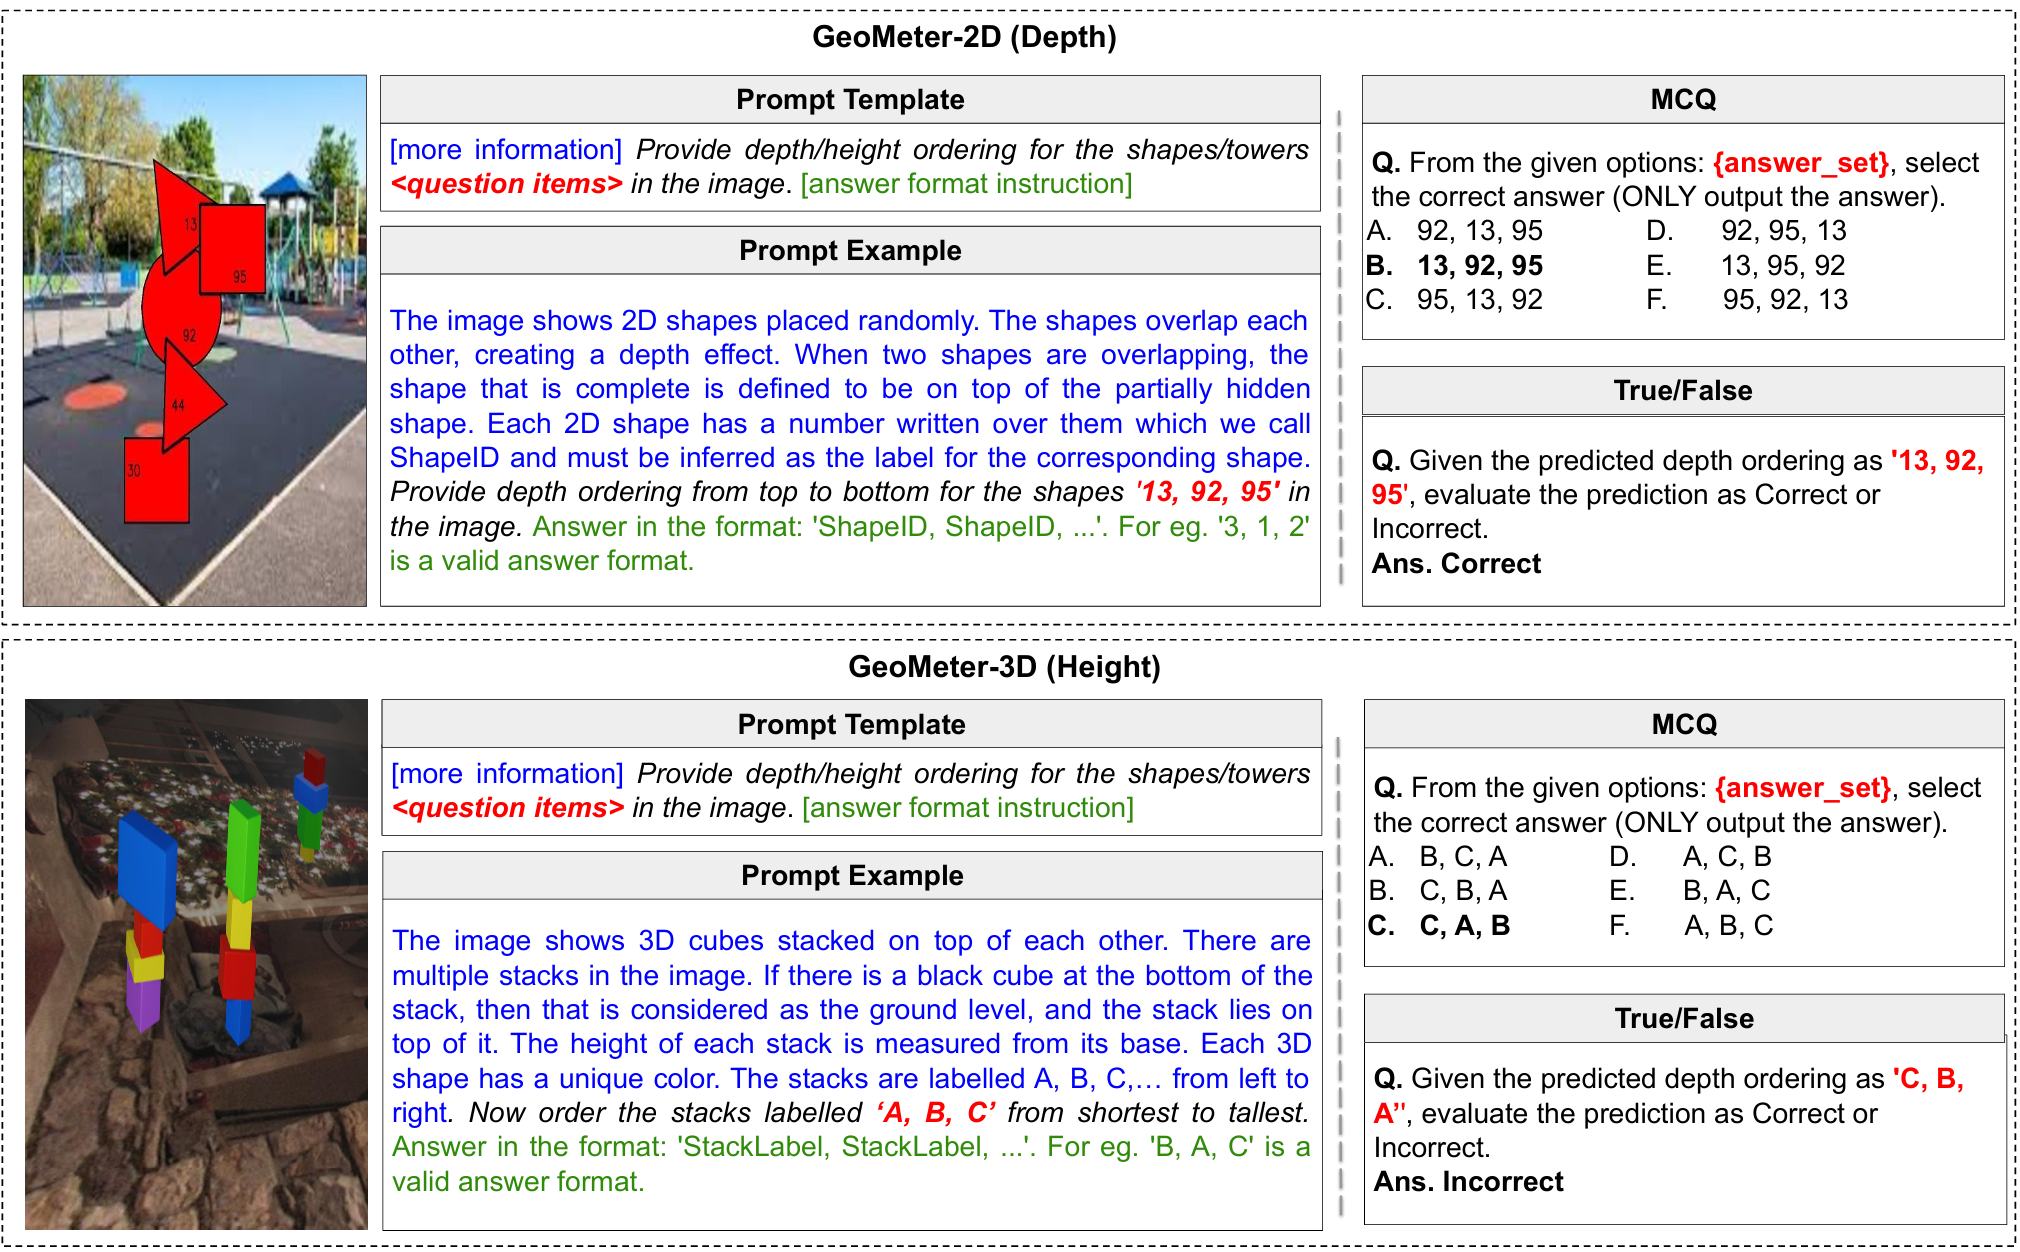
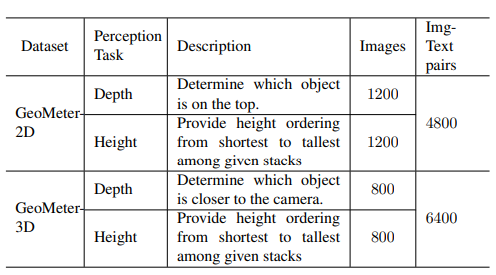
Understanding Depth and Height Perception in Large Visual-Language ModelsCVPRW24-08linkStar countGeoMeterimg
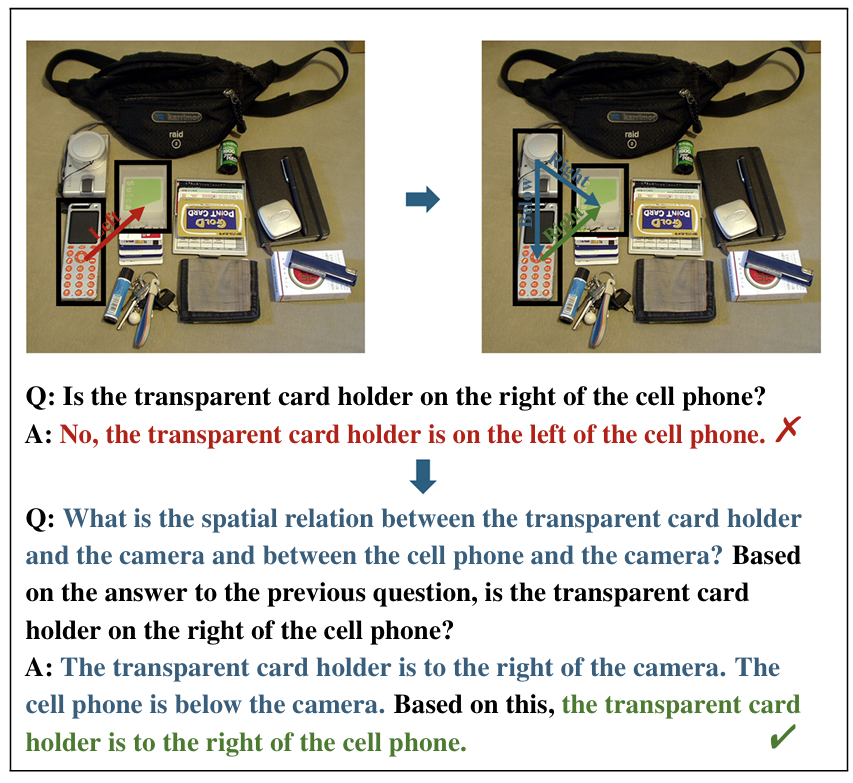
Coarse Correspondences Boost Spatial-Temporal Reasoning in Multimodal Language Model--24-08----ScanQA, OpenEQA’s episodic memory subset
EgoSchema, R2R
SQA3D
img
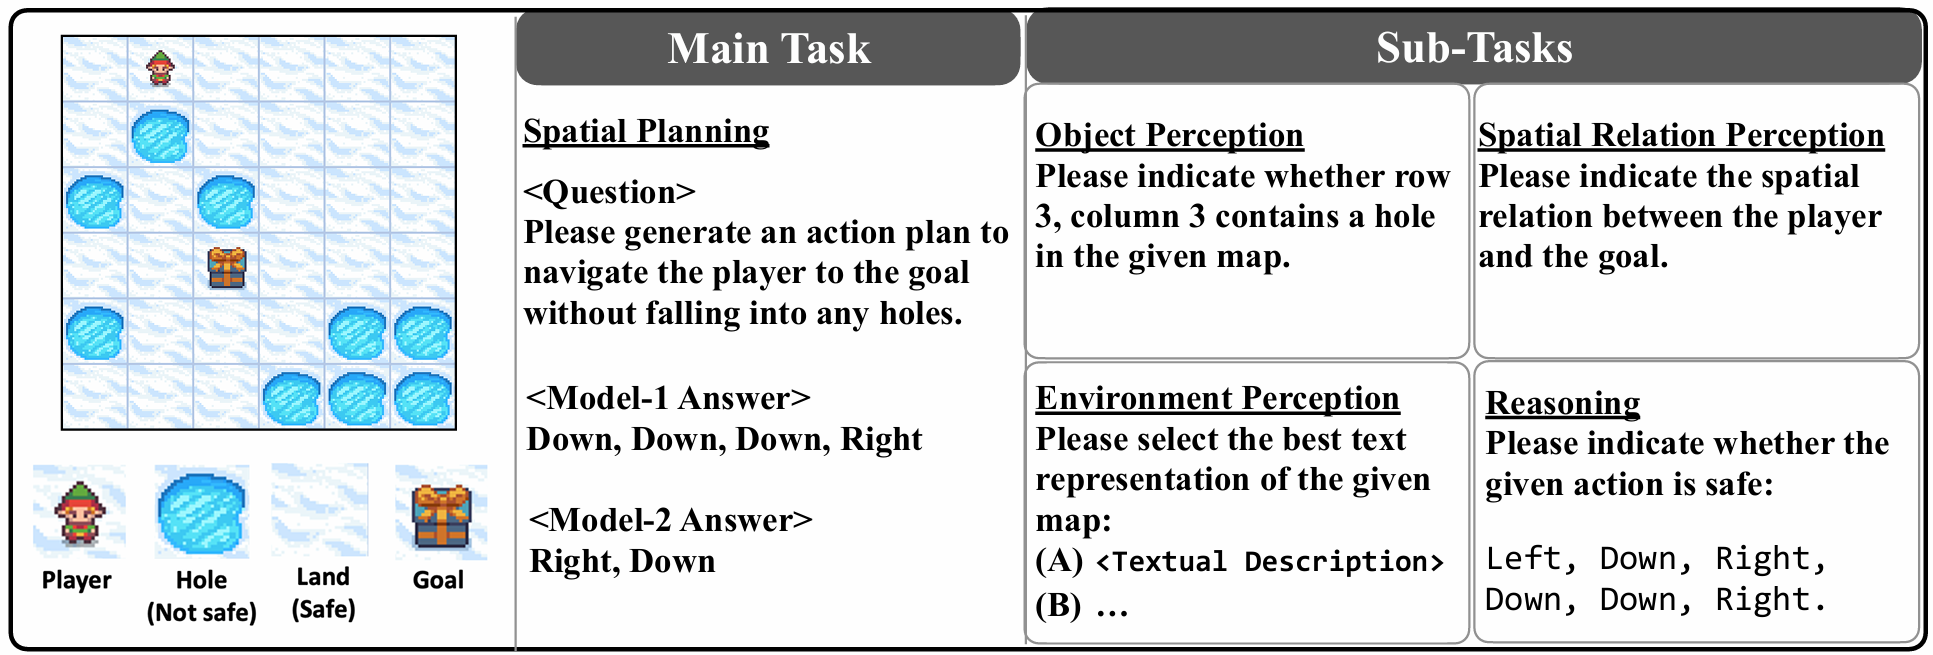
VSP: Assessing the dual challenges of perception and reasoning in spatial planning tasks for VLMsARXIV24-07linkStar countVSPimg
SpatialBot: Precise Spatial Understanding with Vision Language ModelsICRA24-06linkStar countSpatialBenchimg
SpatialRGPT: Grounded Spatial Reasoning in Vision-Language ModelsARXIV24-06linkStar countSpatialRGPT-Benchimg
TOPVIEWRS: Vision-Language Models as Top-View Spatial ReasonersARXIV24-06link----img
Is A Picture Worth A Thousand Words? Delving Into Spatial Reasoning for Vision Language ModelsNIPS24-06linkStar countSpatialEvalimg
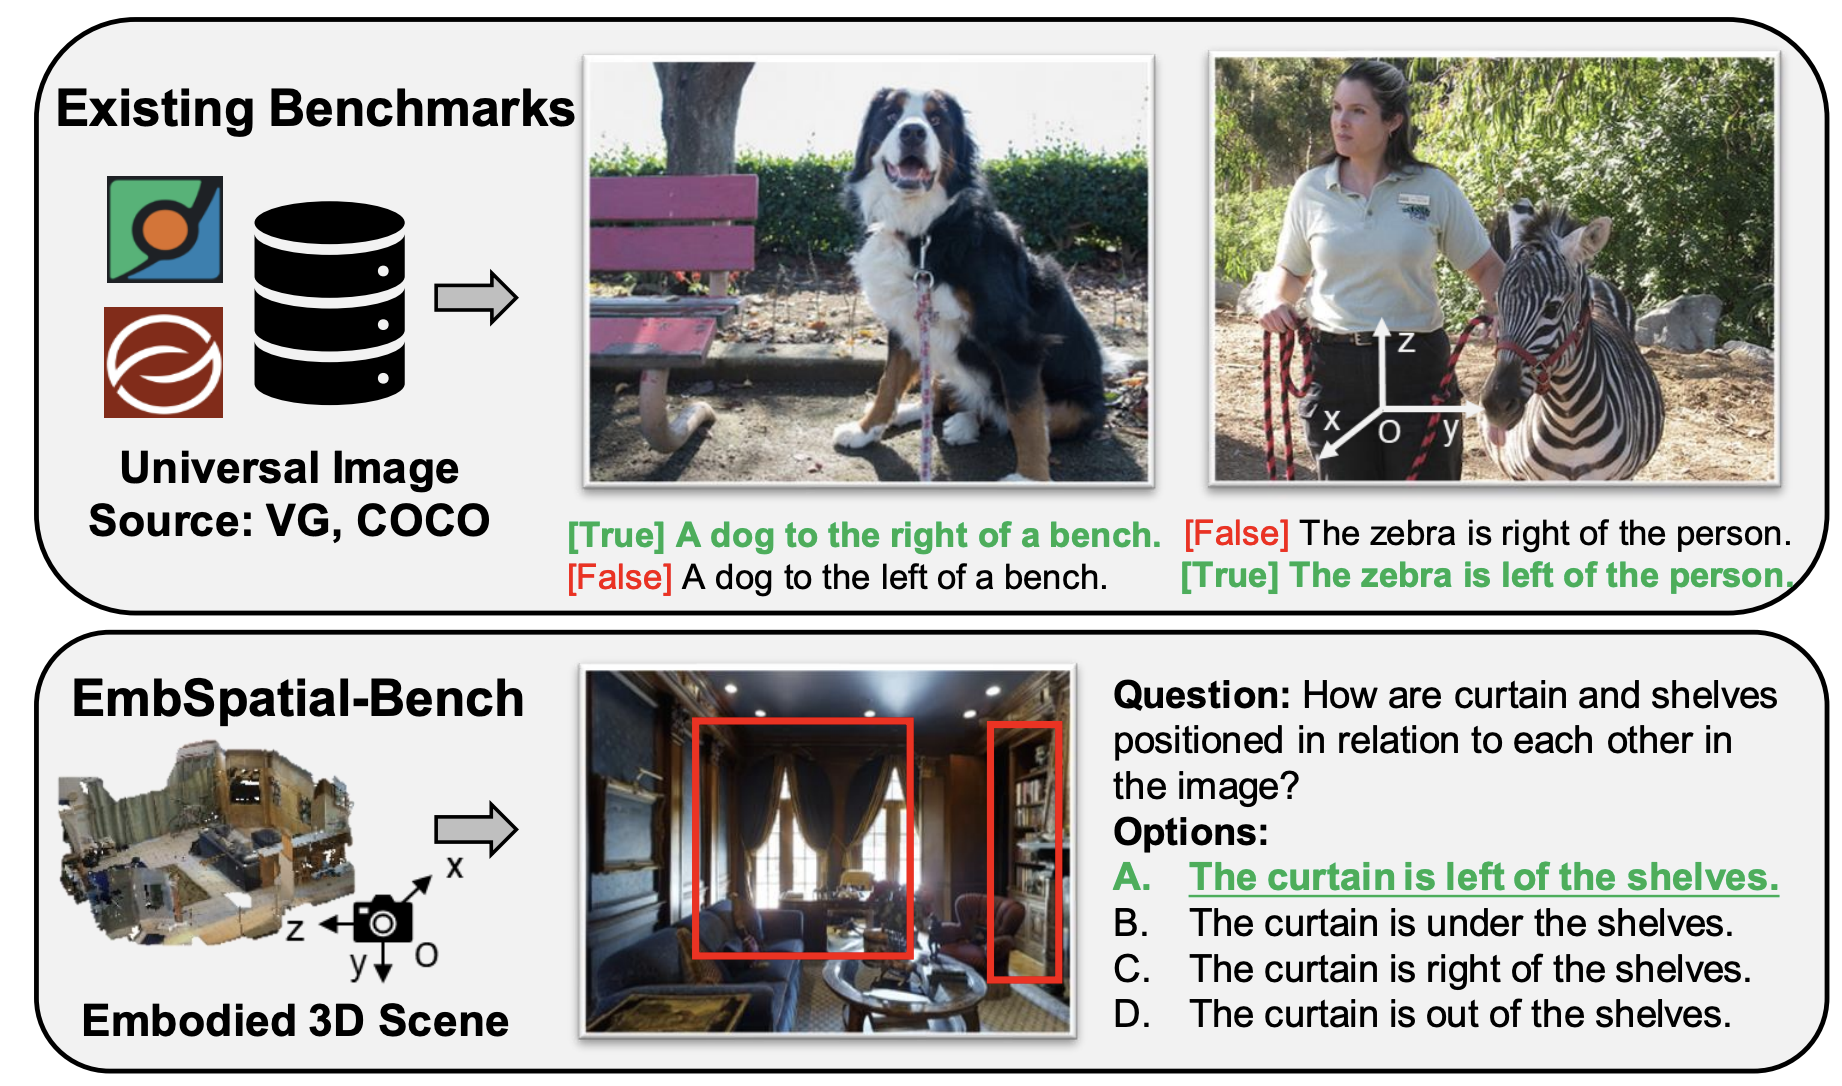
EmbSpatial-Bench: Benchmarking Spatial Understanding for Embodied Tasks with Large Vision-Language ModelsARXIV24-06linkStar countEmbSpatial-Benchimg
GSR-BENCH: A Benchmark for Grounded Spatial Reasoning Evaluation via Multimodal LLMsNEURIPS 2024 WORKSHOP24-06----GSR-BENCHimg
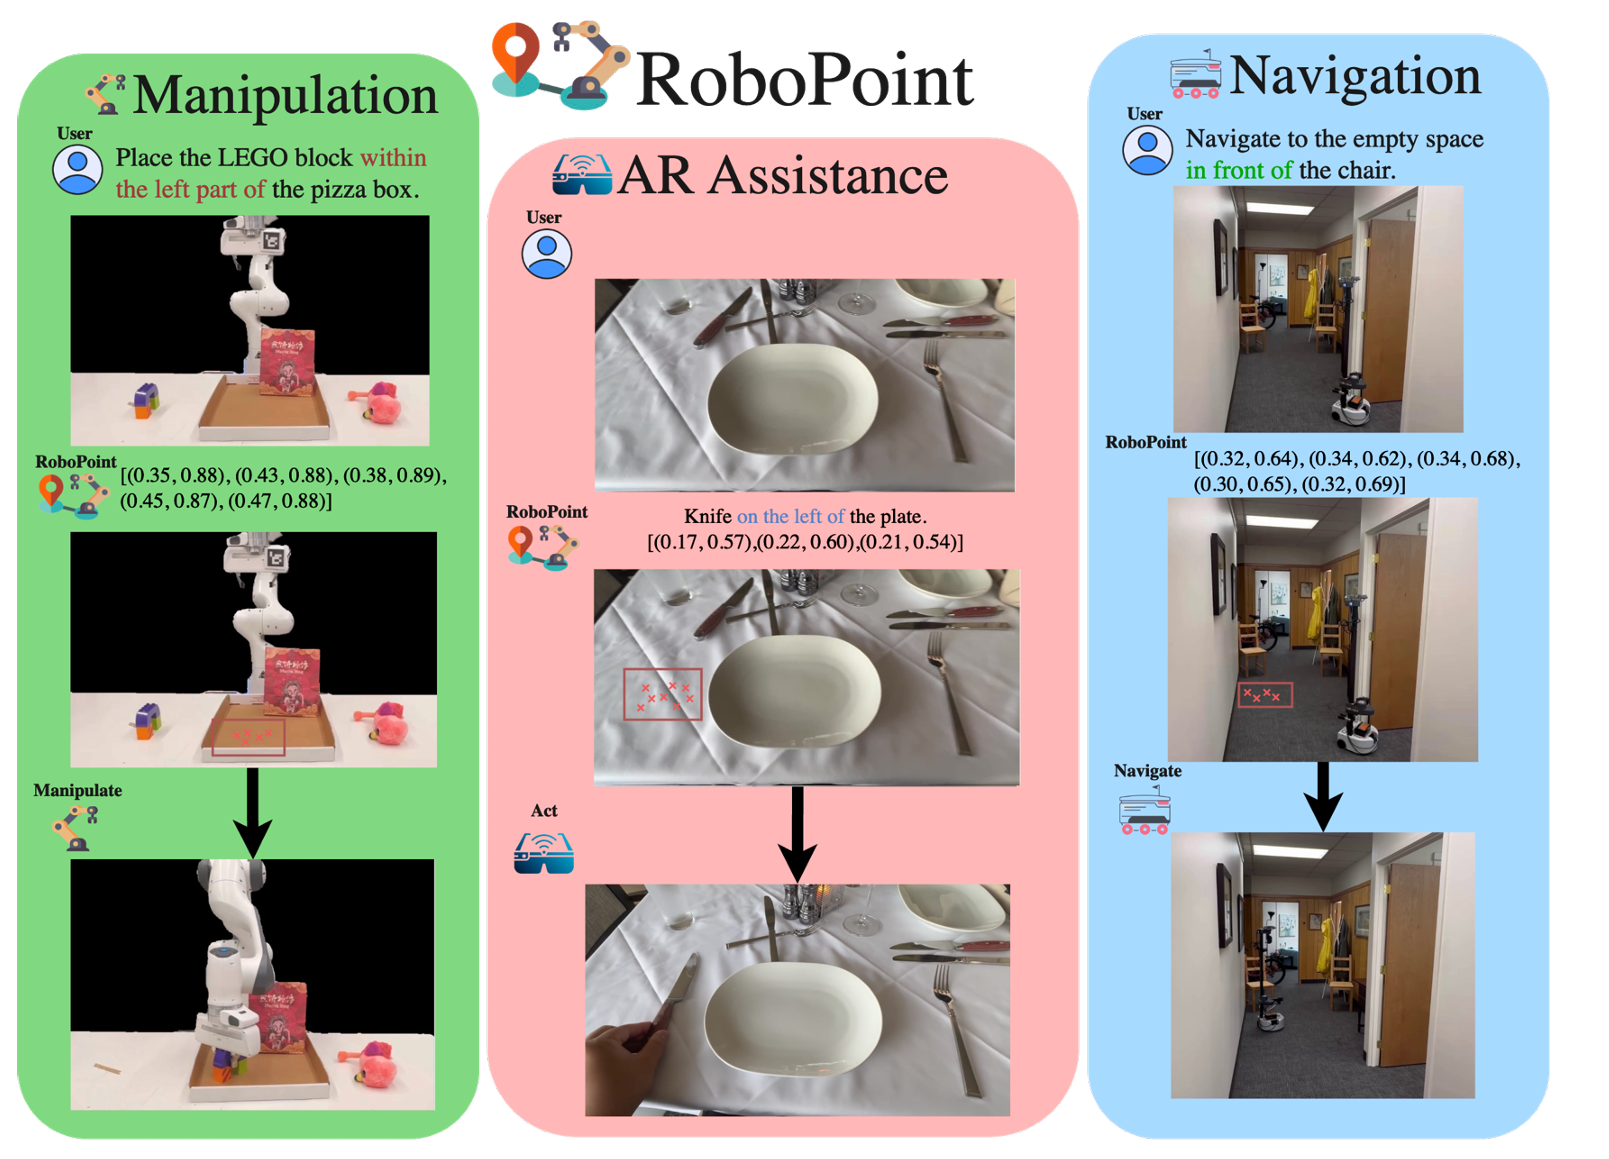
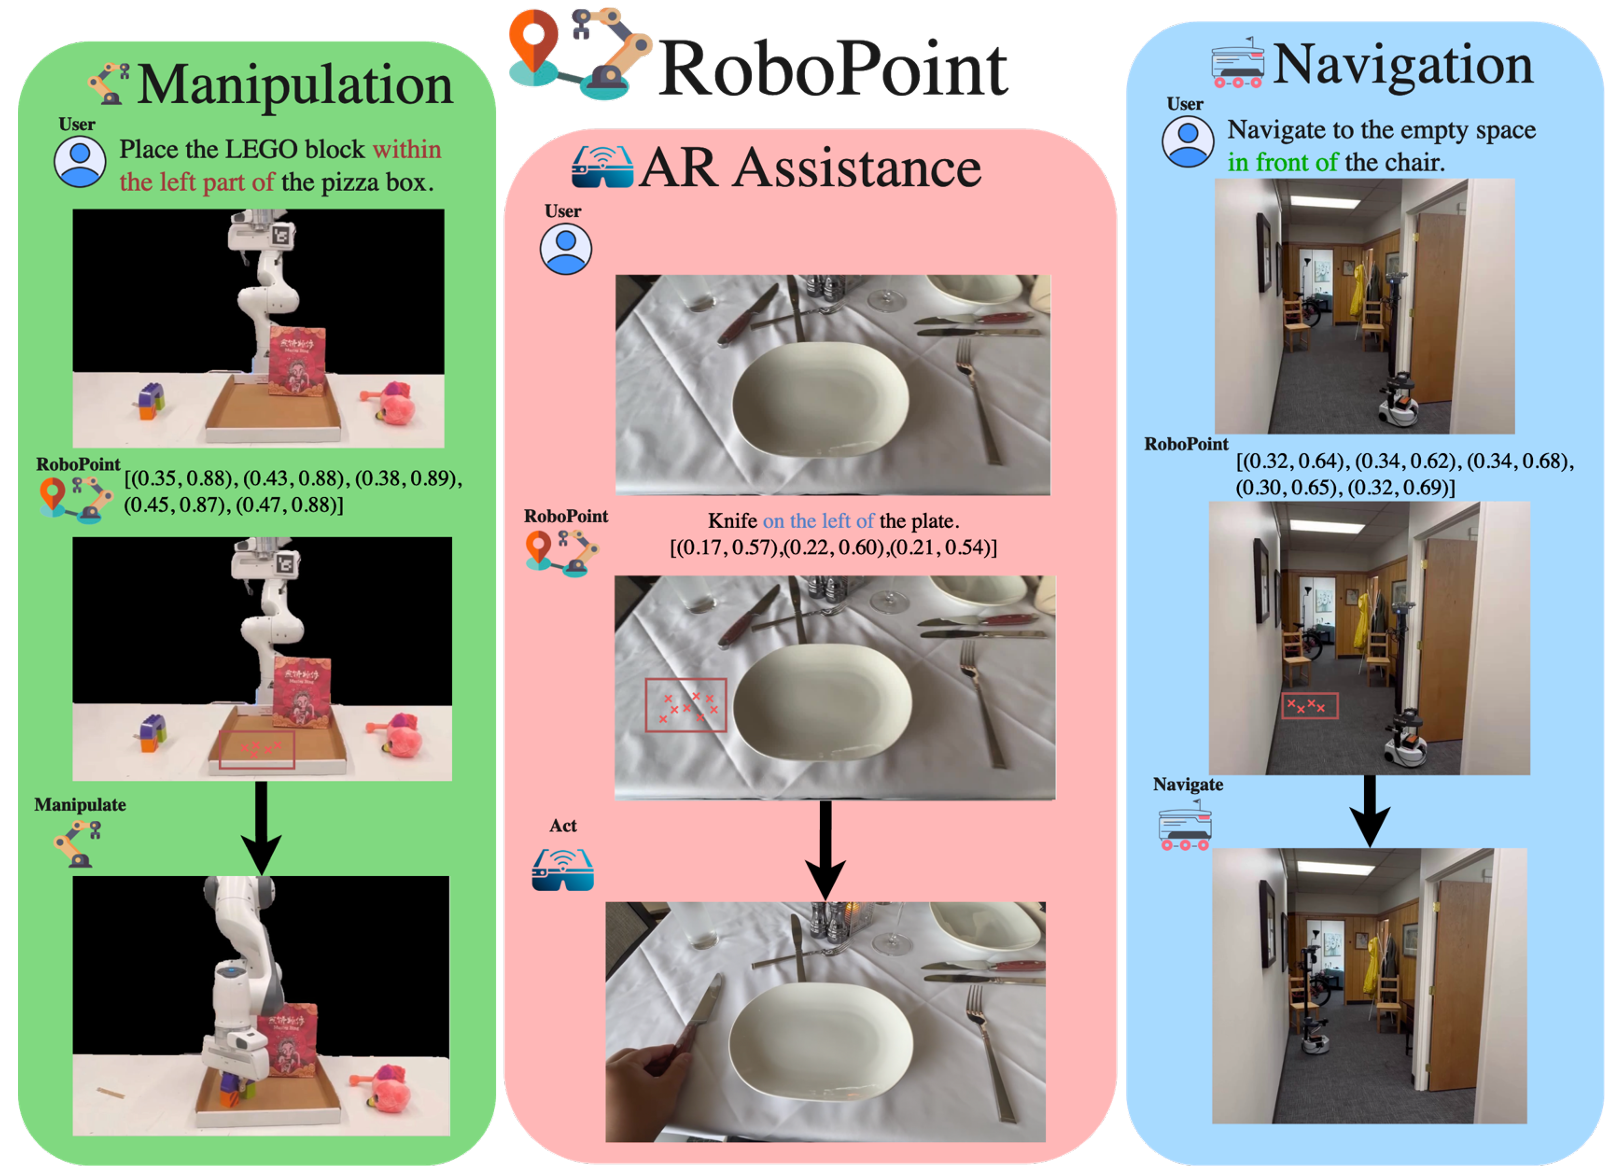
RoboPoint: A Vision-Language Model for Spatial Affordance Prediction for RoboticsCORL202424-06linkStar countRoboPointimg
Reframing Spatial Reasoning Evaluation in Language Models:A Real-World Simulation Benchmark for Qualitative ReasoningARXIV24-05----RoomSpace, bAbI
StepGame, SpartQA
SpaRTUN
img
RAG-Guided Large Language Models for Visual Spatial Description with Adaptive Hallucination CorrectorACMMM2424-05----VSDimg
Mind's Eye of LLMs: Visualization-of-Thought Elicits Spatial Reasoning in Large Language ModelsNIPS24-04linkStar countVoTimg
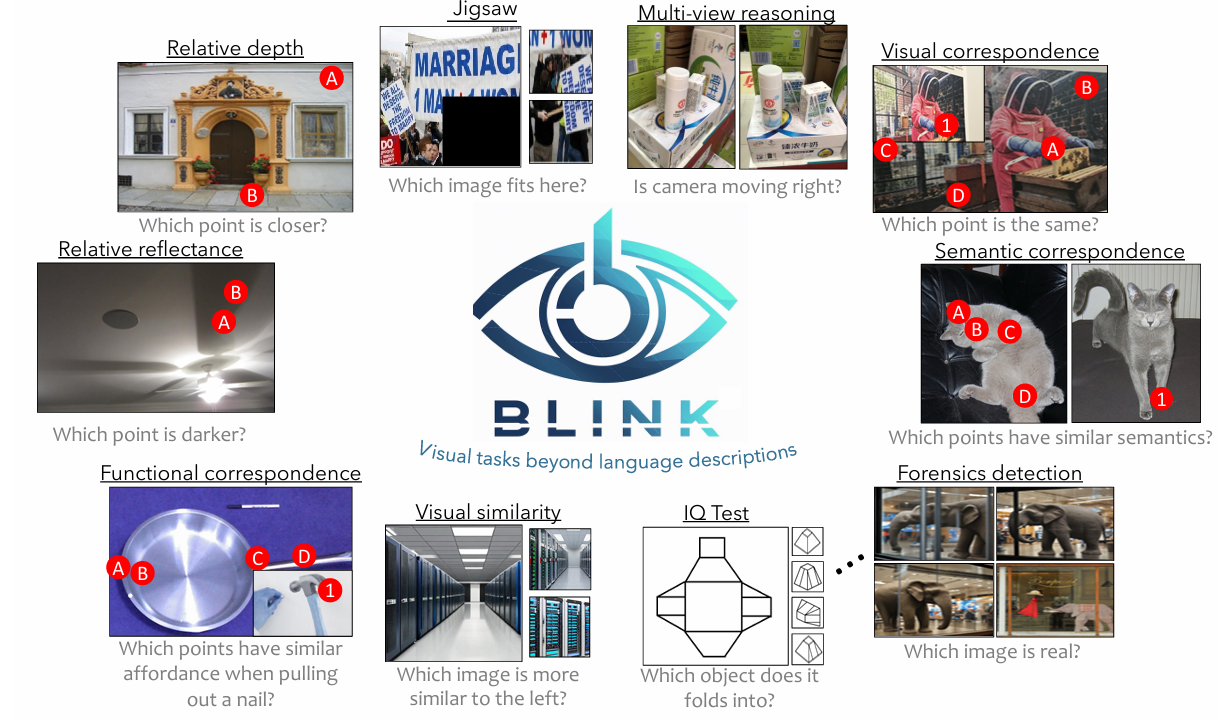
BLINK: Multimodal Large Language Models Can See but Not PerceiveECCV24-04linkStar countBLINKimg
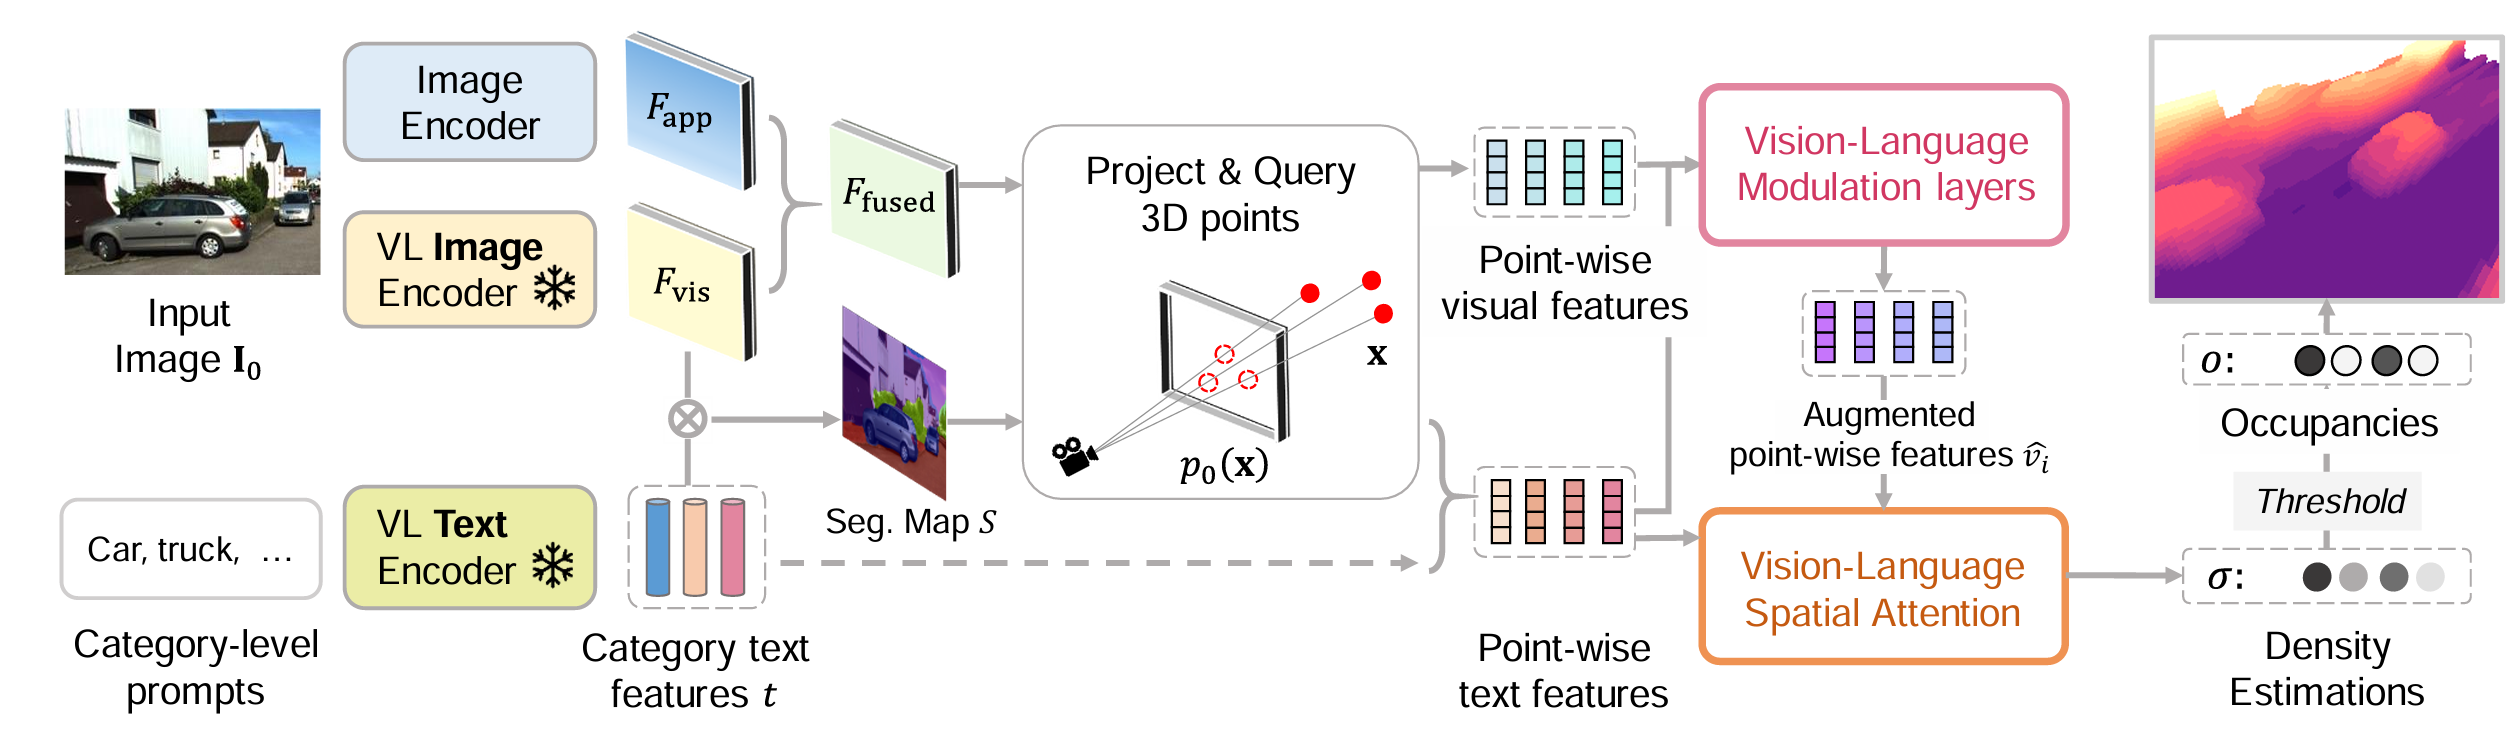
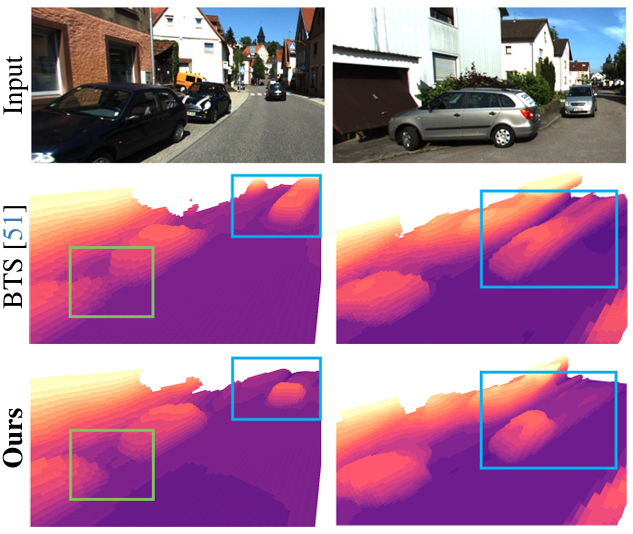
Know Your Neighbors: Improving Single-View Reconstruction via Spatial Vision-Language ReasoningCVPR202424-04linkStar countKITTI-360img
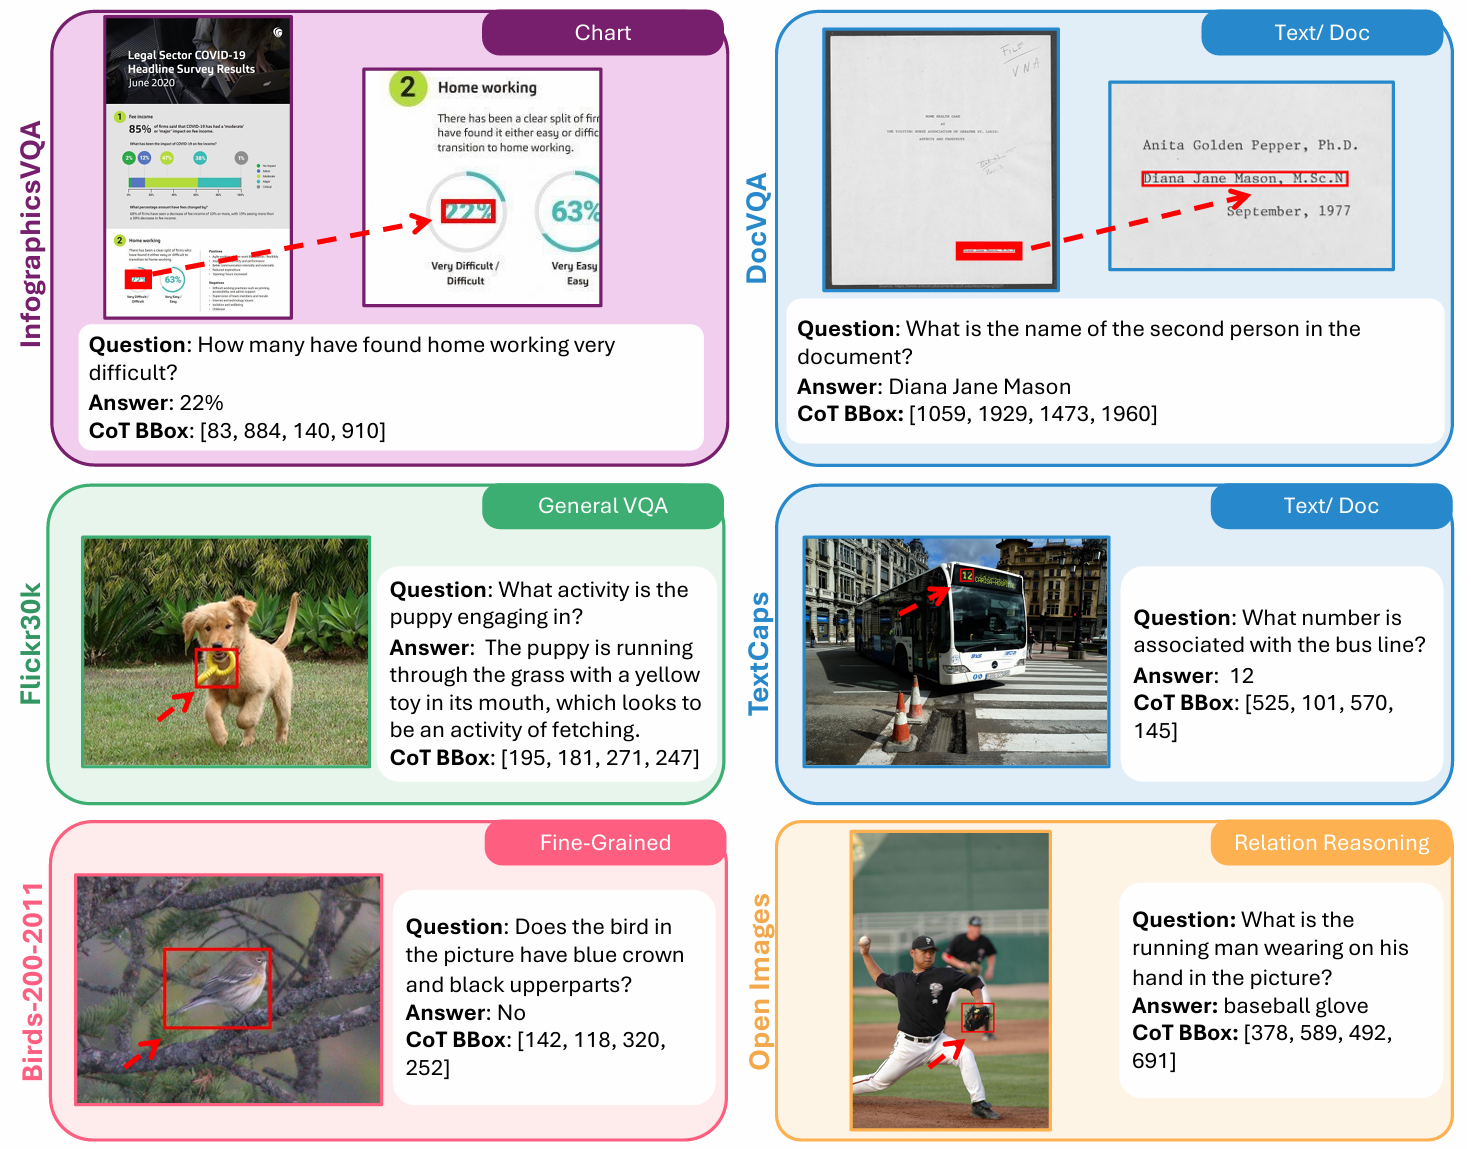
Visual CoT: Advancing Multi-Modal Language Models with a Comprehensive Dataset and Benchmark for Chain-of-Thought Reasoning--24-03linkStar countVisual-CoTimg
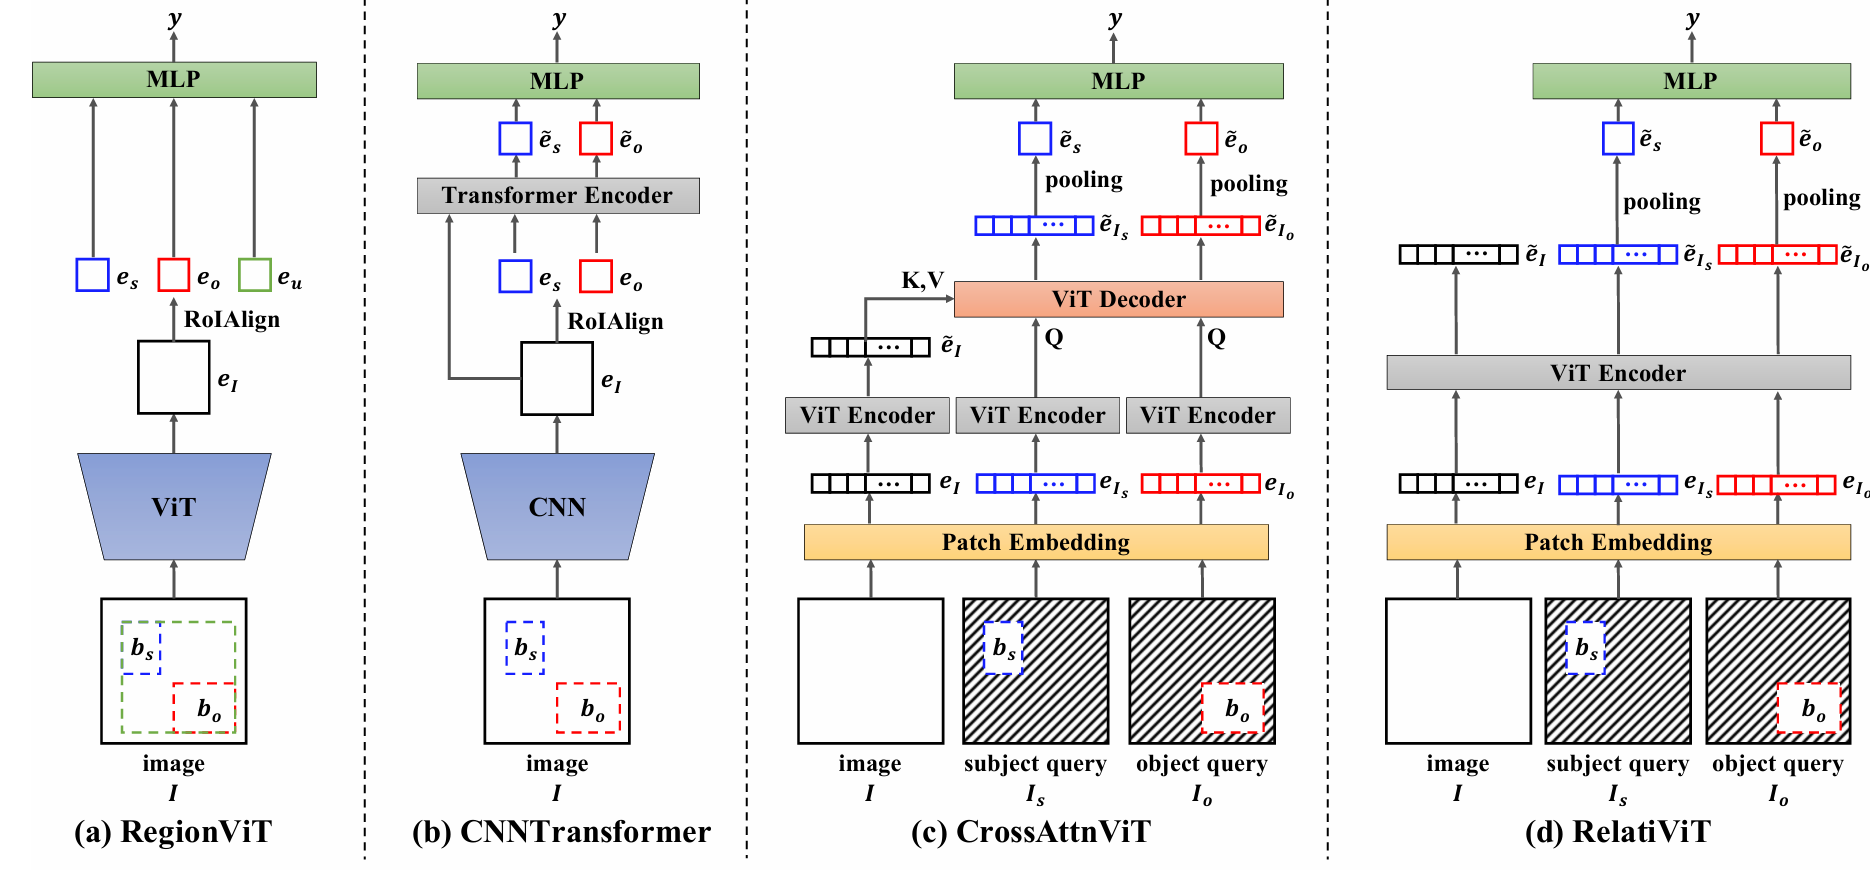
Can Transformers Capture Spatial Relations between Objects?ICLR24-03linkStar countSRPimg
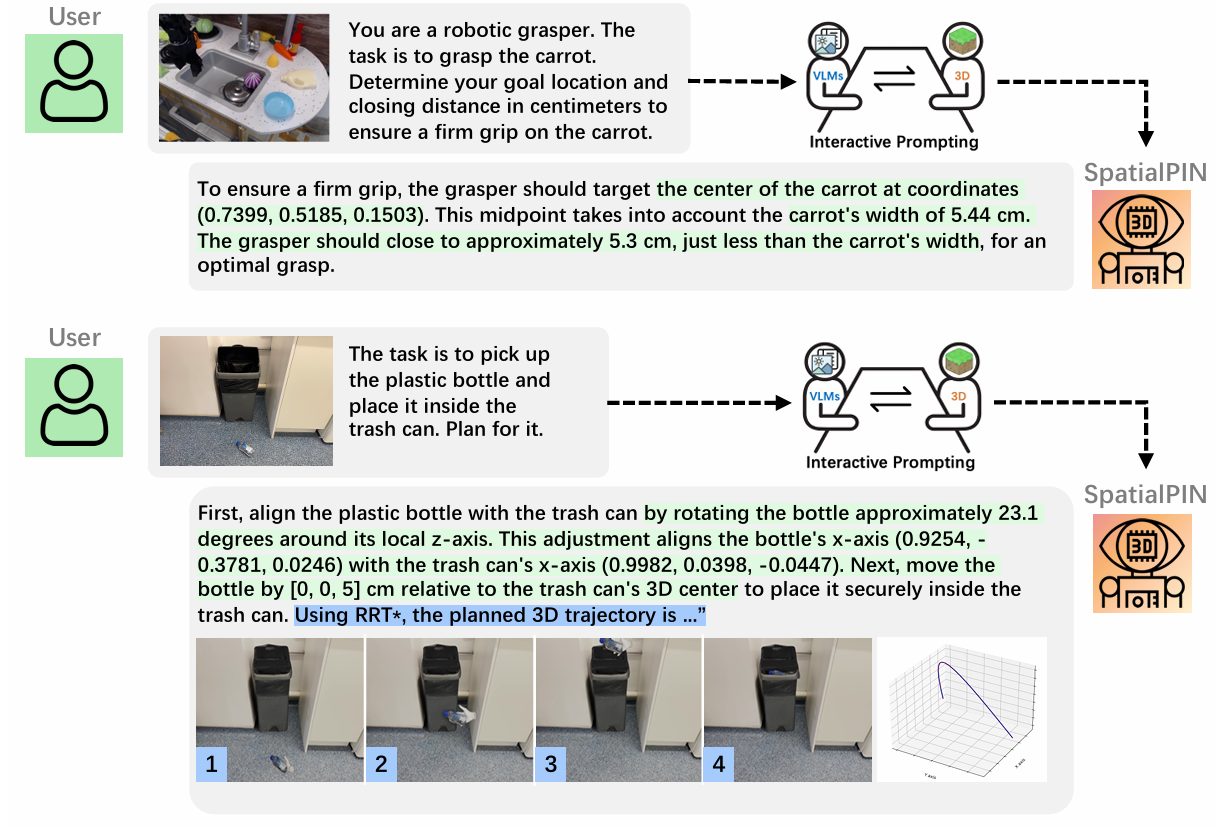
SpatialPIN: Enhancing Spatial Reasoning Capabilities of Vision-Language Models through Prompting and Interacting 3D PriorsNEURIPS202424-03linkStar countNOCS, RT-1
BridgeData V2, YCBInEOAT
img
SpatialVLM Endowing Vision-Language Models with Spatial Reasoning CapabilitiesCVPR24-01linkStar count--img
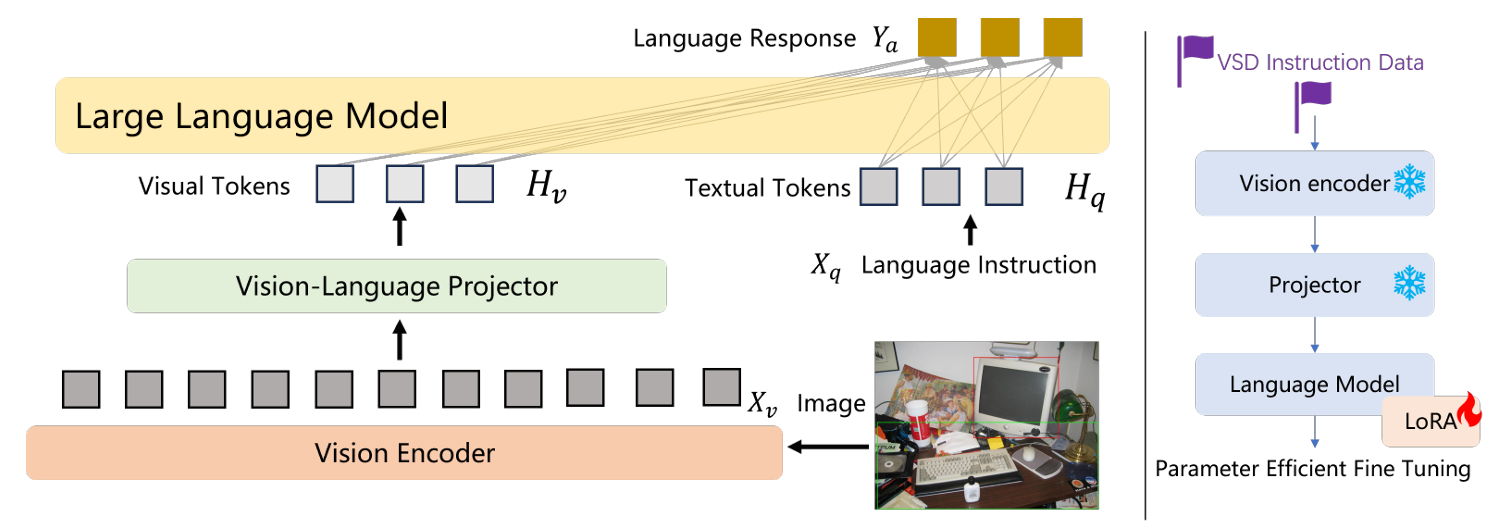
LLaVA-VSD: Large Language-and-Vision Assistant for Visual Spatial DescriptionACM MM24-01------img
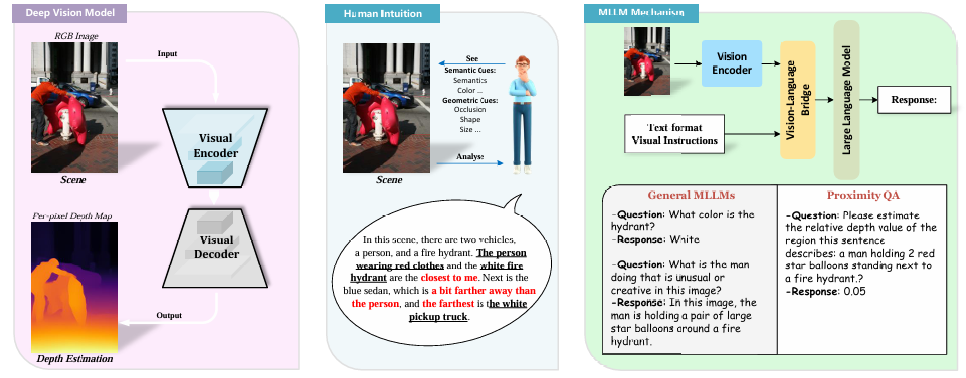
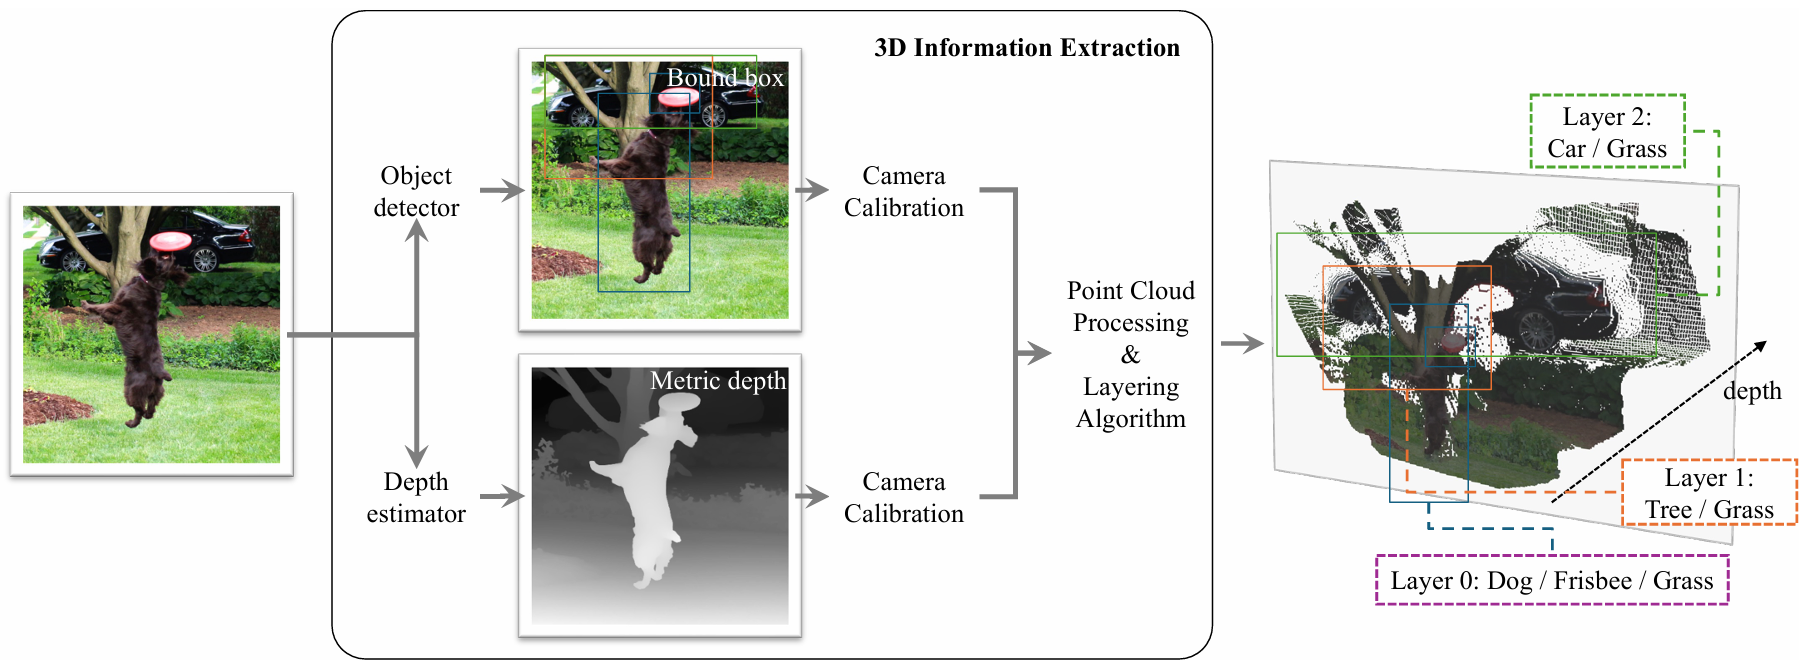
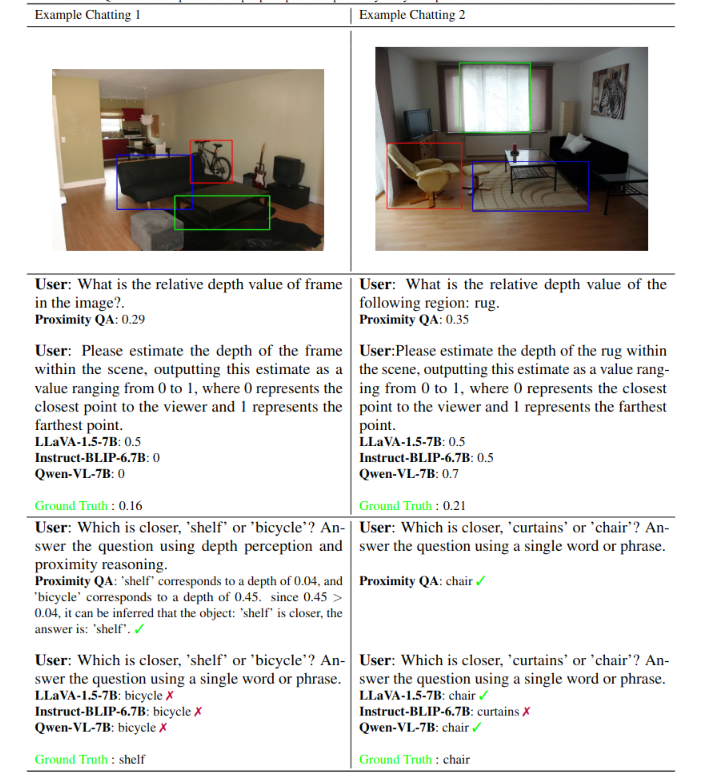
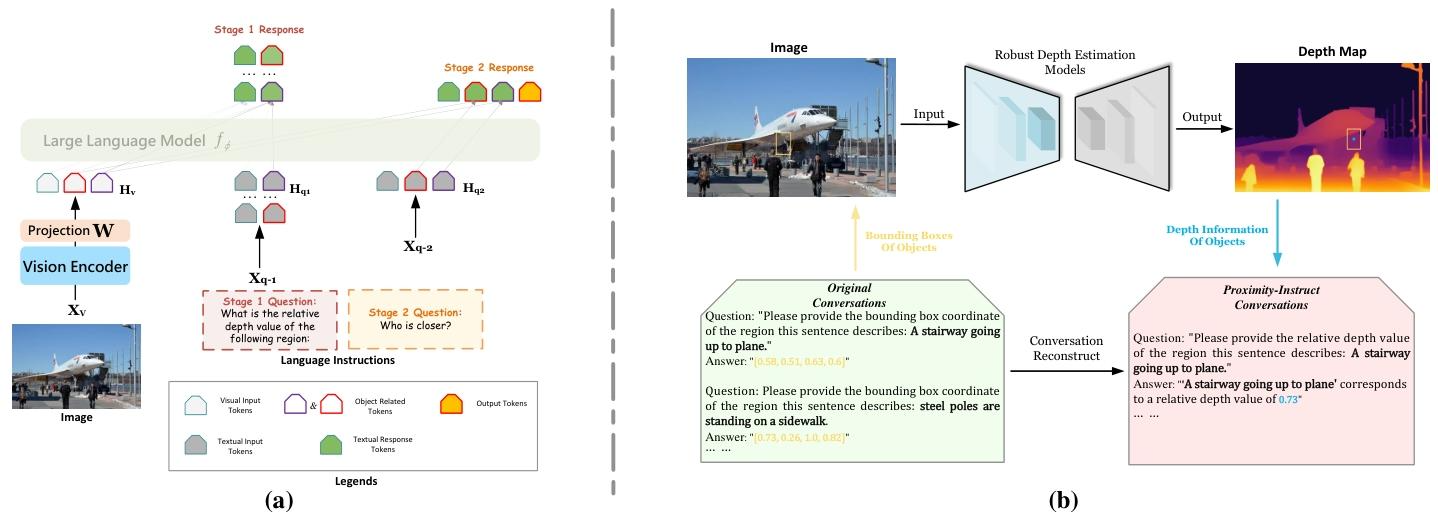
Proximity QA: Unleashing the Power of Multi-Modal Large Language Models for Spatial Proximity AnalysisARXIV24-01linkStar countProximity-110Kimg
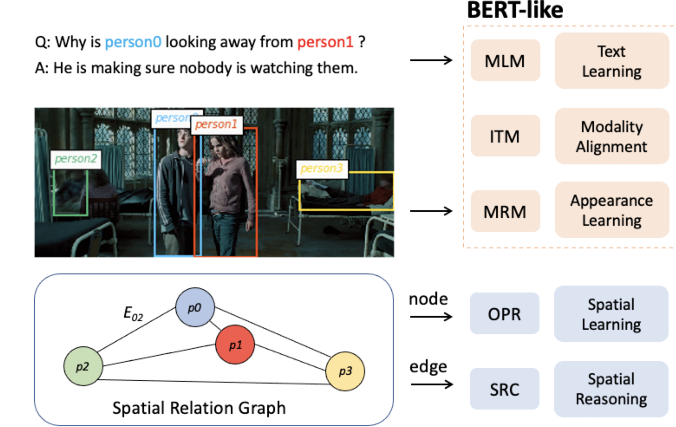
Improving Vision-and-Language Reasoning via Spatial Relations ModelingWACV23-11------img
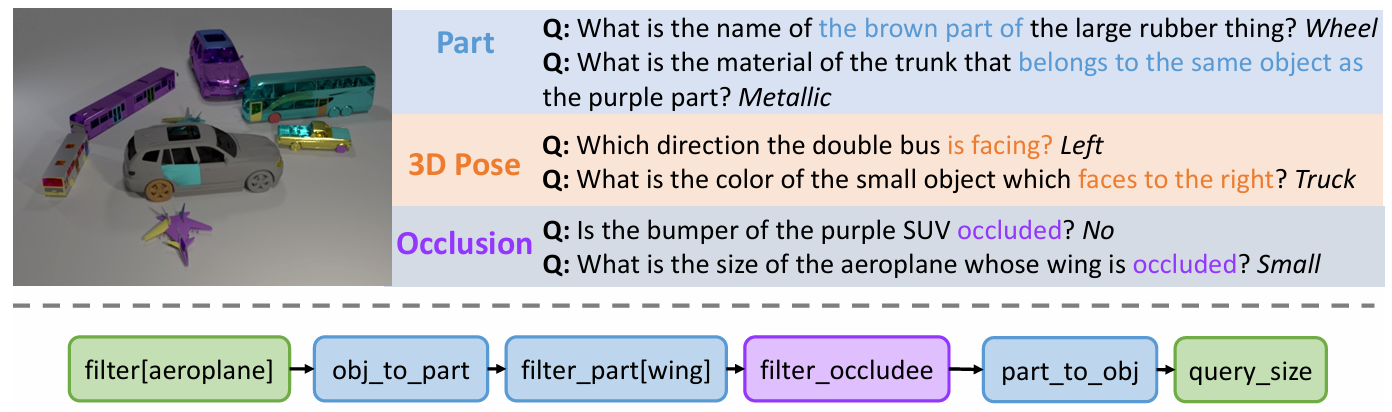
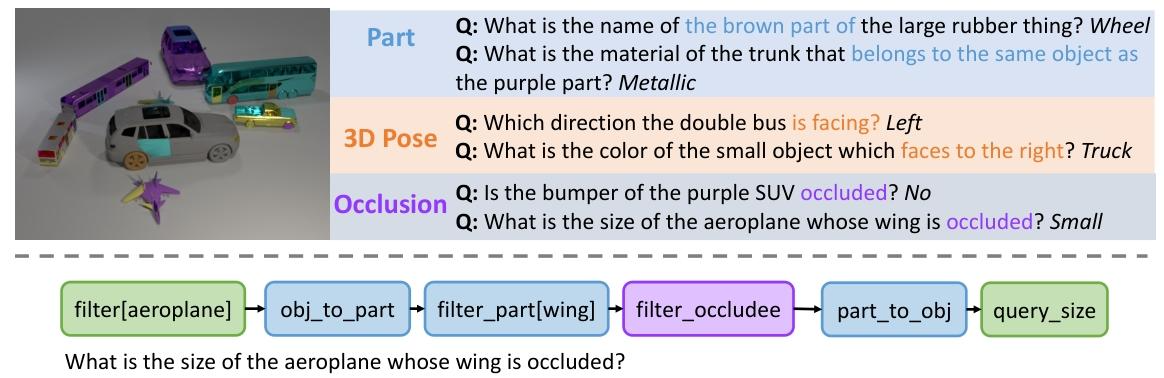
3D-Aware Visual Question Answering about Parts, Poses and OcclusionsNIPS23-10linkStar countSuper-CLEVR-3Dimg
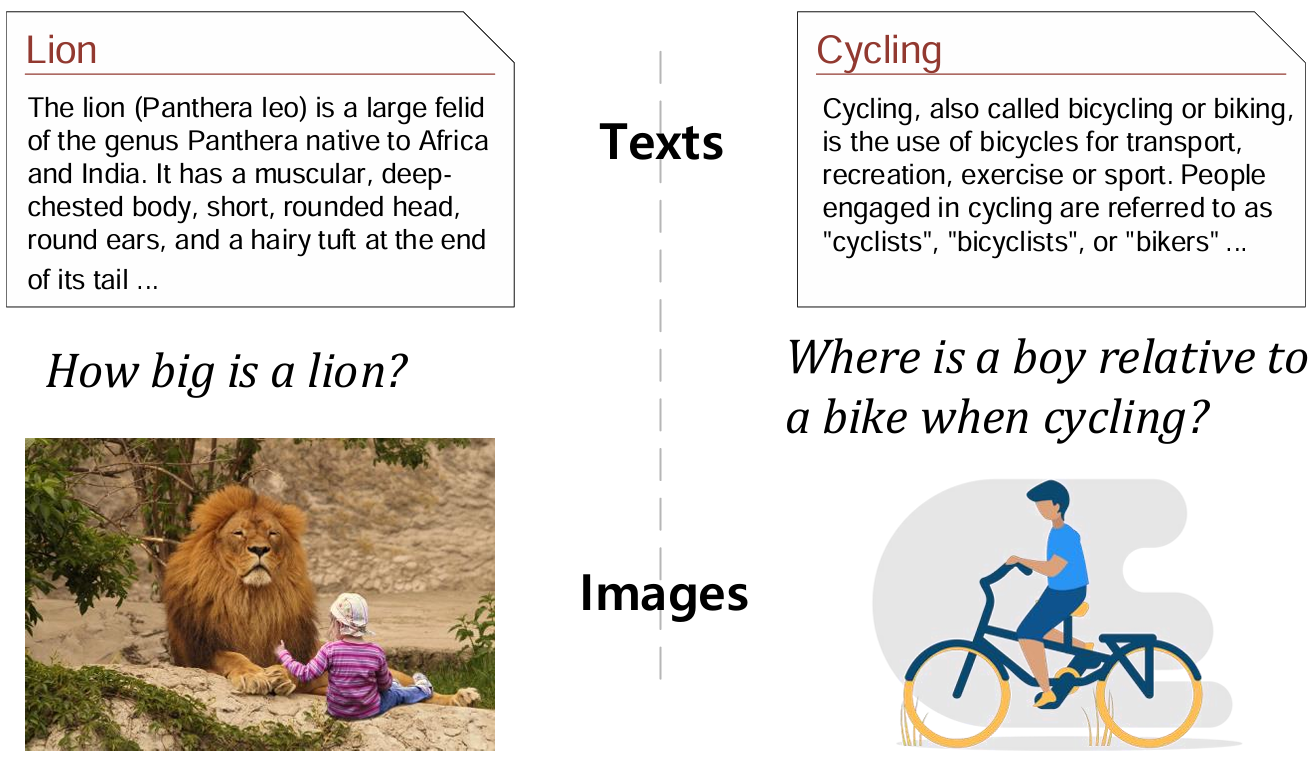
Things not Written in Text: Exploring Spatial Commonsense from Visual SignalsACL202222-03linkStar count--img

Monocular-Video

TitleVenueDateCodeStarsBenchmarkIllustration
World2VLM: Distilling World Model Imagination into VLMs for Dynamic Spatial ReasoningARXIV26-04link--SAT-Real, VSI-Bench, MindCube--
ReVSI: Rebuilding Visual Spatial Intelligence Evaluation for Accurate Assessment of VLM 3D ReasoningARXIV26-04----ReVSI--
Holi-Spatial: Evolving Video Streams into Holistic 3D Spatial IntelligenceICML 202626-03linkStar countHoli-Spatial-4M--
CoV: Chain-of-View Prompting for Spatial ReasoningARXIV26-01--------
Cambrian-S: Towards Spatial Supersensing in VideoARXIV25-11linkStar countVSI-SUPERimg
Vision-Language Memory for Spatial ReasoningARXIV25-11link----img
VisualTrans: A Benchmark for Real-World Visual Transformation ReasoningARXIV25-08link--VisualTransimg
VLM4D: Towards Spatiotemporal Awareness in Vision Language ModelsICCV25-08link--VLM4Dimg
OpenEQA: Embodied Question Answering in the Era of Foundation ModelsCVPR--linkStar countOpenEQAimg
Spatial Understanding from Videos: Structured Prompts Meet Simulation DataARXIV25-06linkStar count--img
VLM-3R: Vision-Language Models Augmented with Instruction-Aligned 3D ReconstructionARXIV25-05linkStar countVSTiBenchimg
3DLLM-Mem: Long-Term Spatial-Temporal Memory for Embodied 3D Large Language ModelARXIV25-05linkStar count3DMEM-Benchimg
Spatial-MLLM Boosting MLLM Capabilities in Visual-based Spatial IntelligenceARXIV25-05linkStar countSpatial-MLLM-120kimg
Out of Sight, Not Out of Context? Egocentric Spatial Reasoning in VLMs Across Disjoint FramesARXIV25-05----DISJOINT-3DQAimg
Learning from Videos for 3D World: Enhancing MLLMs with 3D Vision Geometry PriorsARXIV25-05linkStar countVSI-Benchimg
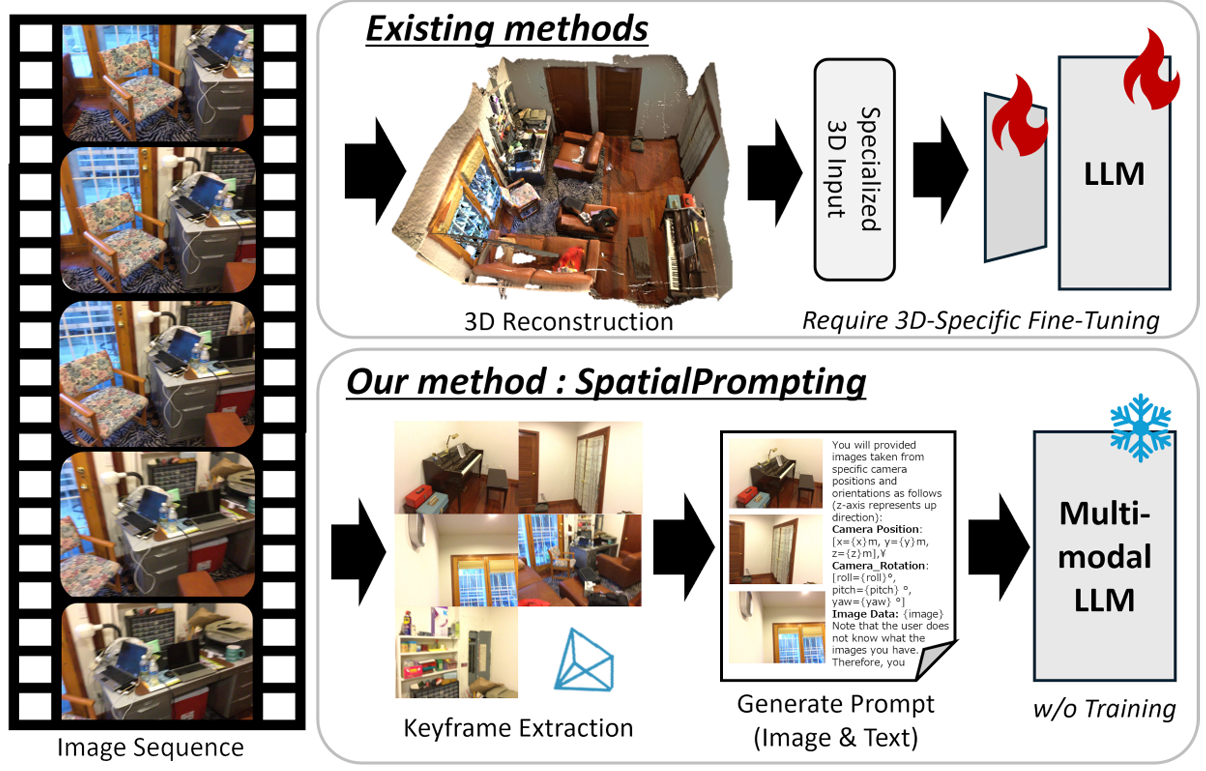
SpatialPrompting: Keyframe-driven Zero-Shot Spatial Reasoning with Off-the-Shelf Multimodal Large Language ModelsARXIV25-05------img
Towards Visuospatial Cognition via Hierarchical Fusion of Visual ExpertsARXIV25-05linkStar count--img
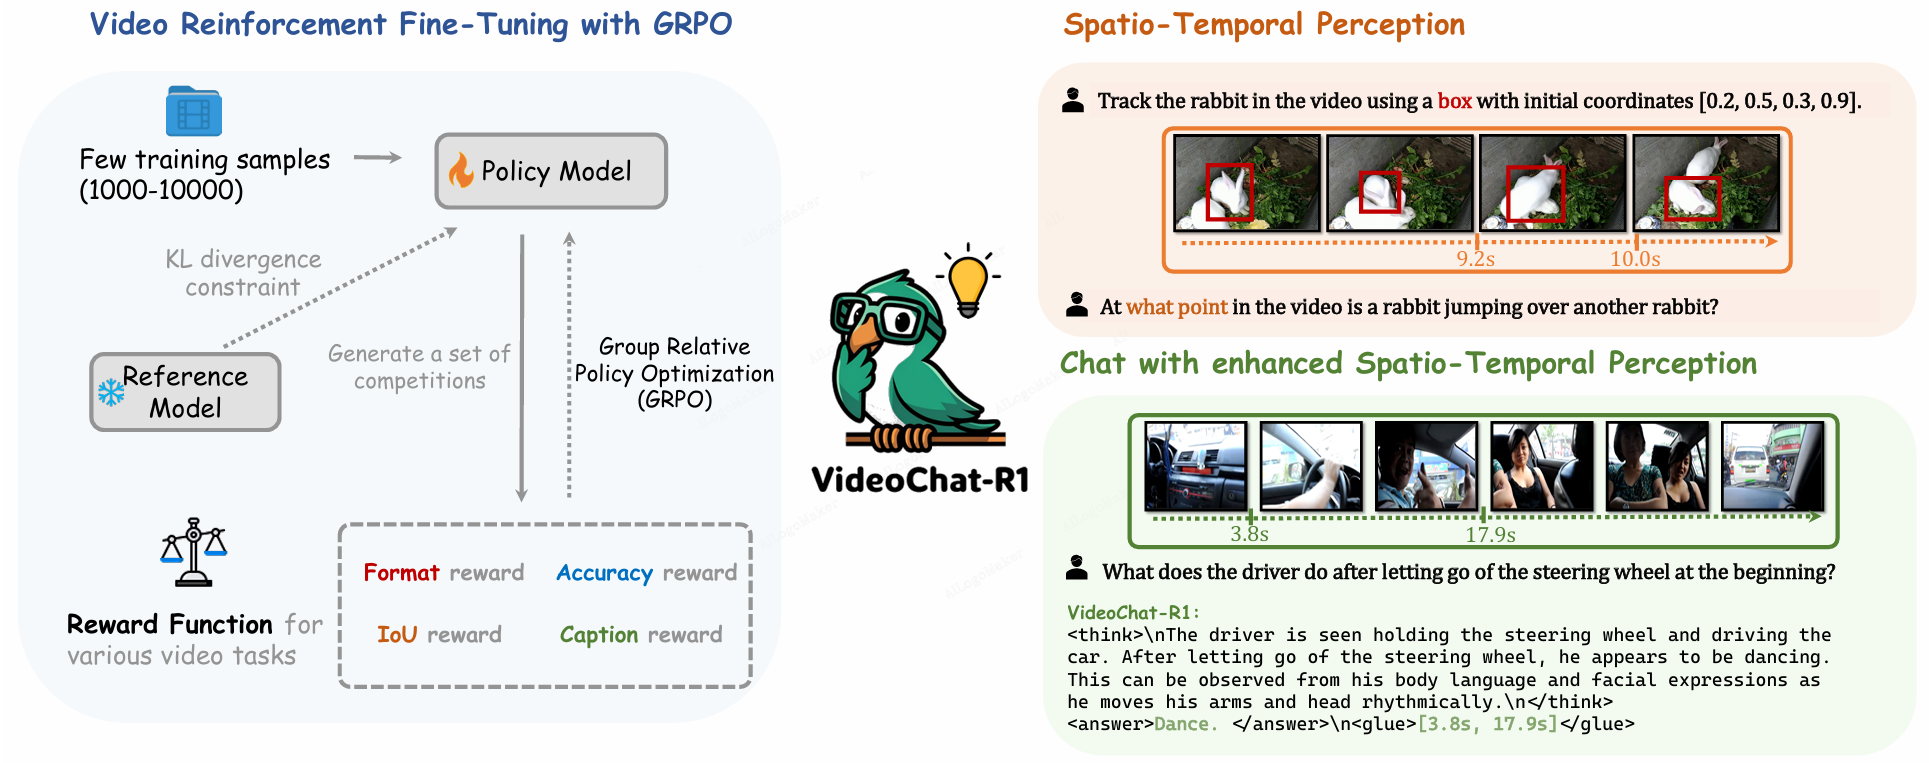
VideoChat-R1: Enhancing Spatio-Temporal Perception via Reinforcement Fine-TuningARXIV25-04linkStar count--img
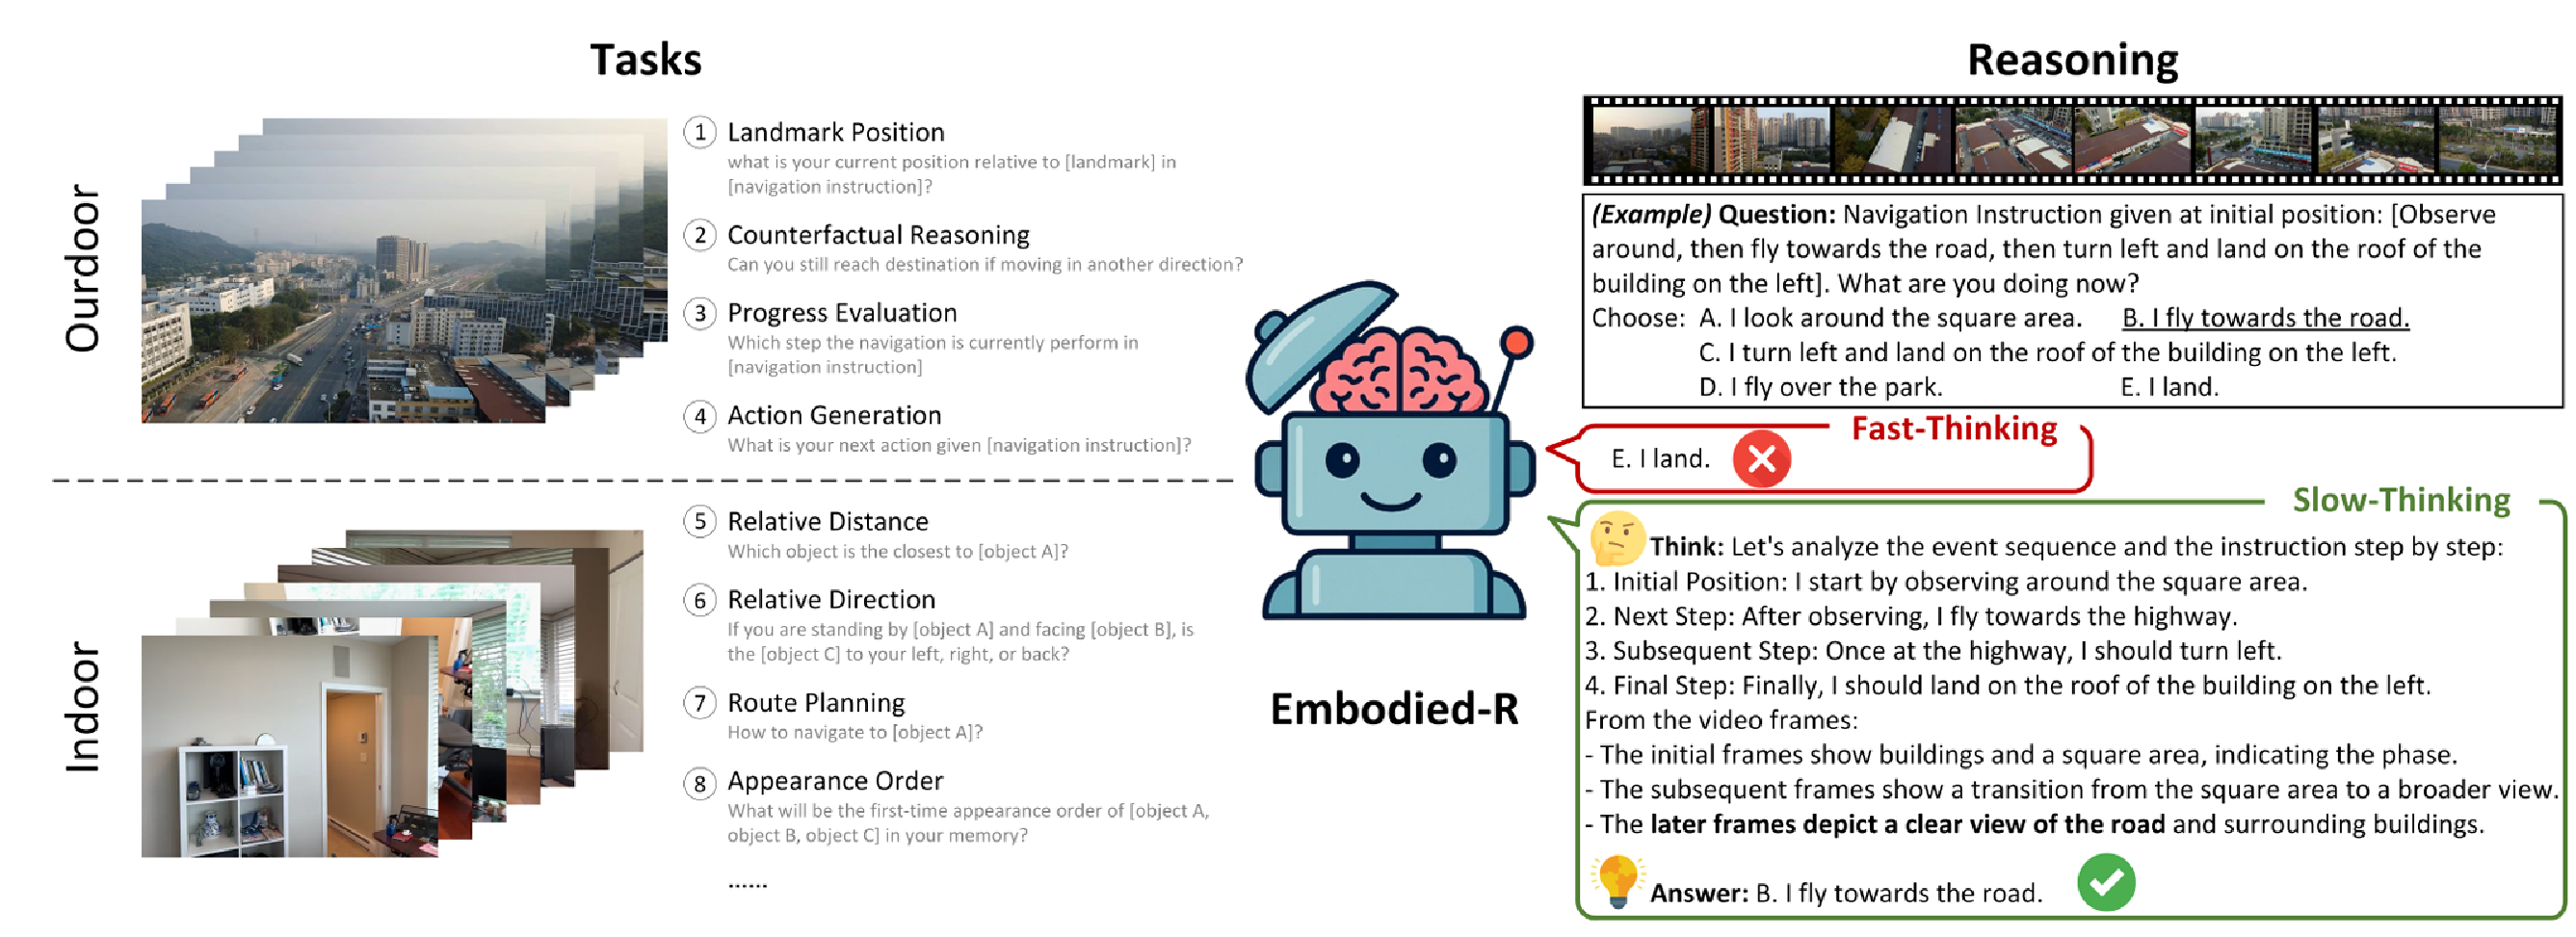
Embodied-R: Collaborative Framework for Activating Embodied Spatial Reasoning in Foundation Models via Reinforcement LearningARXIV25-04linkStar countEmbodied-Rimg
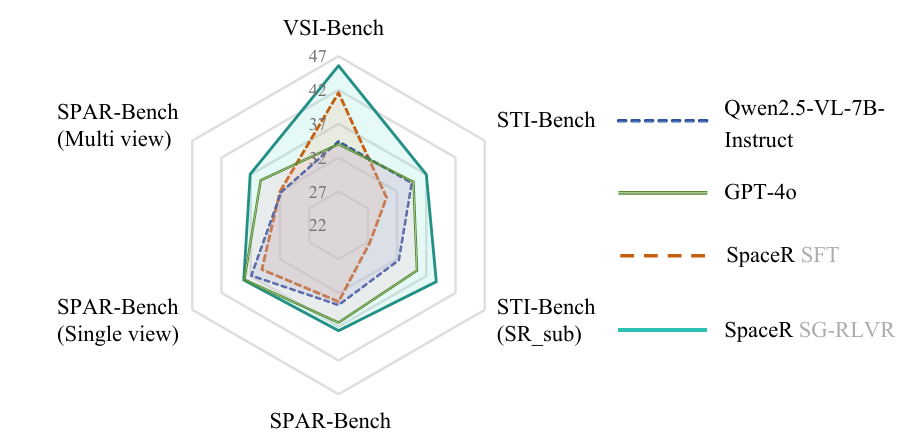
SpaceR: Reinforcing MLLMs in Video Spatial ReasoningARXIV25-04linkStar countVSI-Bench, STI-Bench
and SPAR-Bench
img
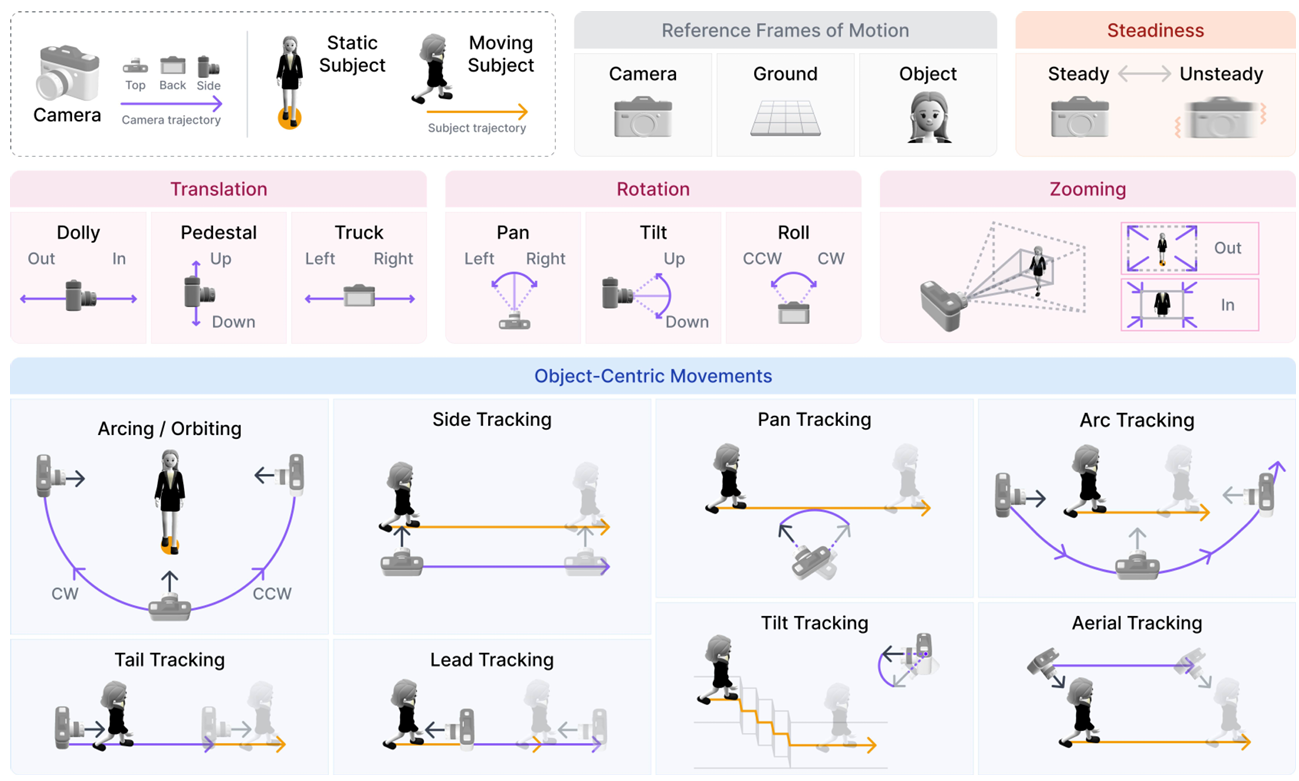
Towards Understanding Camera Motions in Any VideoARXIV25-04linkStar countCameraBenchimg
EgoDTM:Towards 3D-Aware Egocentric Video-Language PretrainingARXIV25-03linkStar countEgoMCQ...img
STI-Bench: Are MLLMsReadyfor Precise Spatial-Temporal World Understanding?ARXIV25-03linkStar countSTI-Benchimg
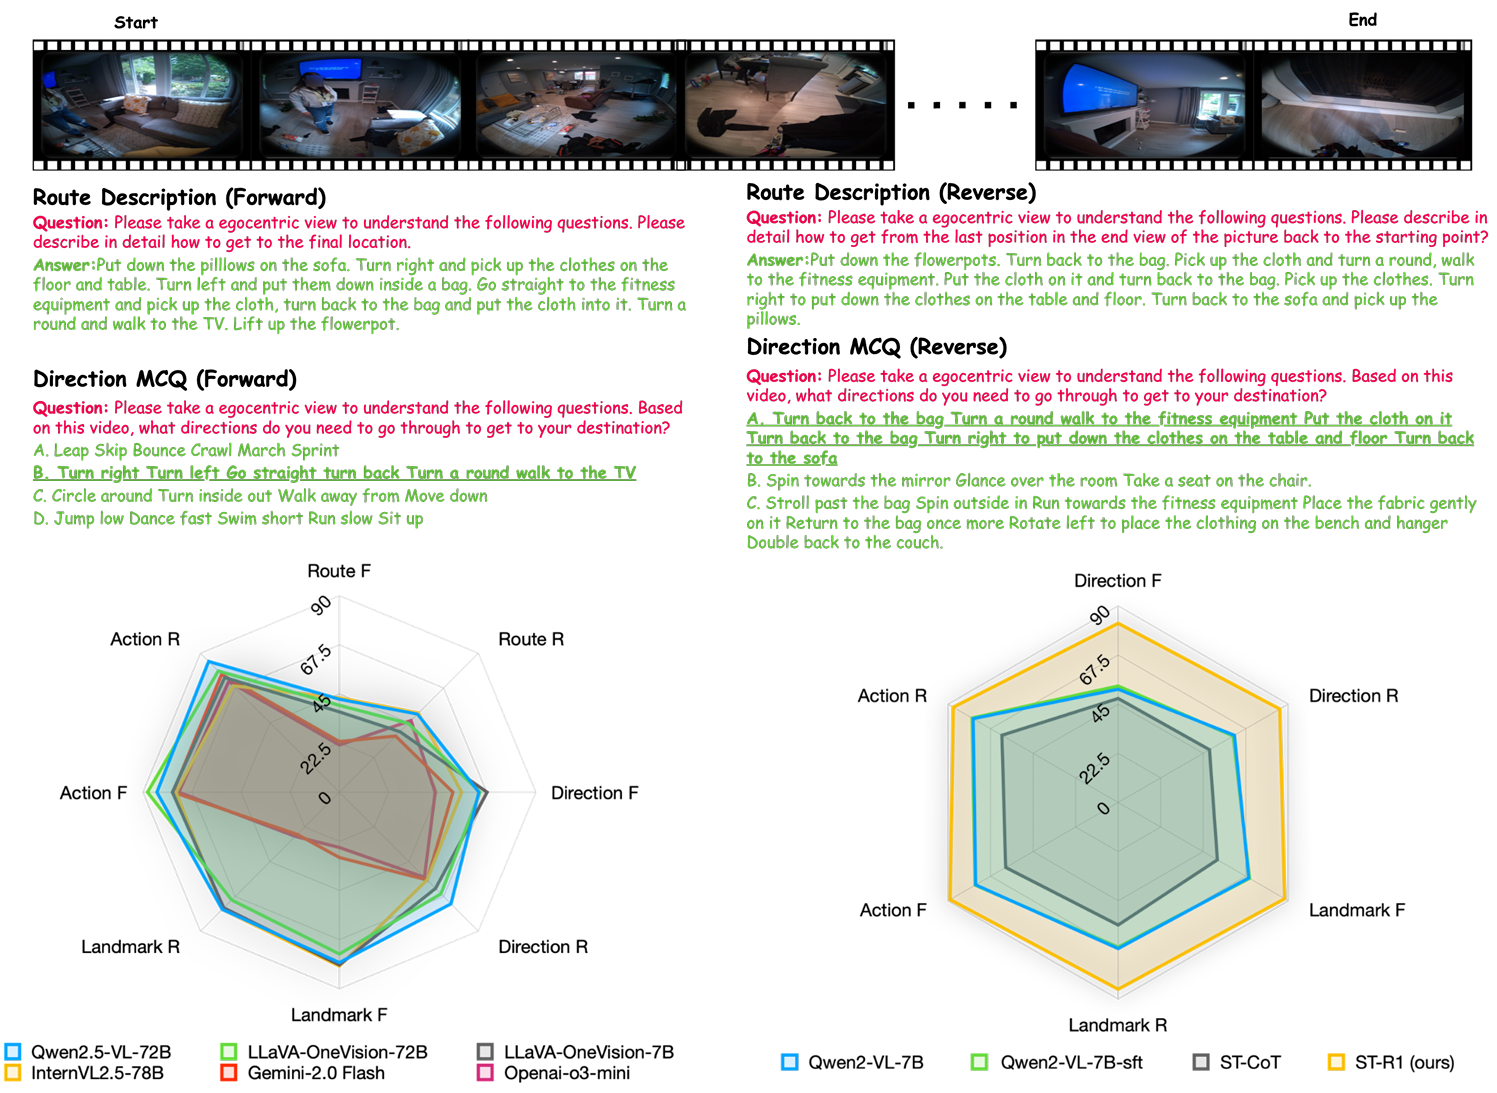
ST-Think: How Multimodal Large Language Models Reason About 4D Worlds from Ego-Centric VideosARXIV25-03linkStar countEgo-STimg
From Flatland to Space: Teaching Vision-Language Models to Perceive and Reason in 3DARXIV25-03linkStar countSPAR-Benchimg
ST-VLM:KinematicInstruction Tuning for Spatio-Temporal Reasoning in Vision-Language ModelsARXIV25-03linkStar countSTKitimg
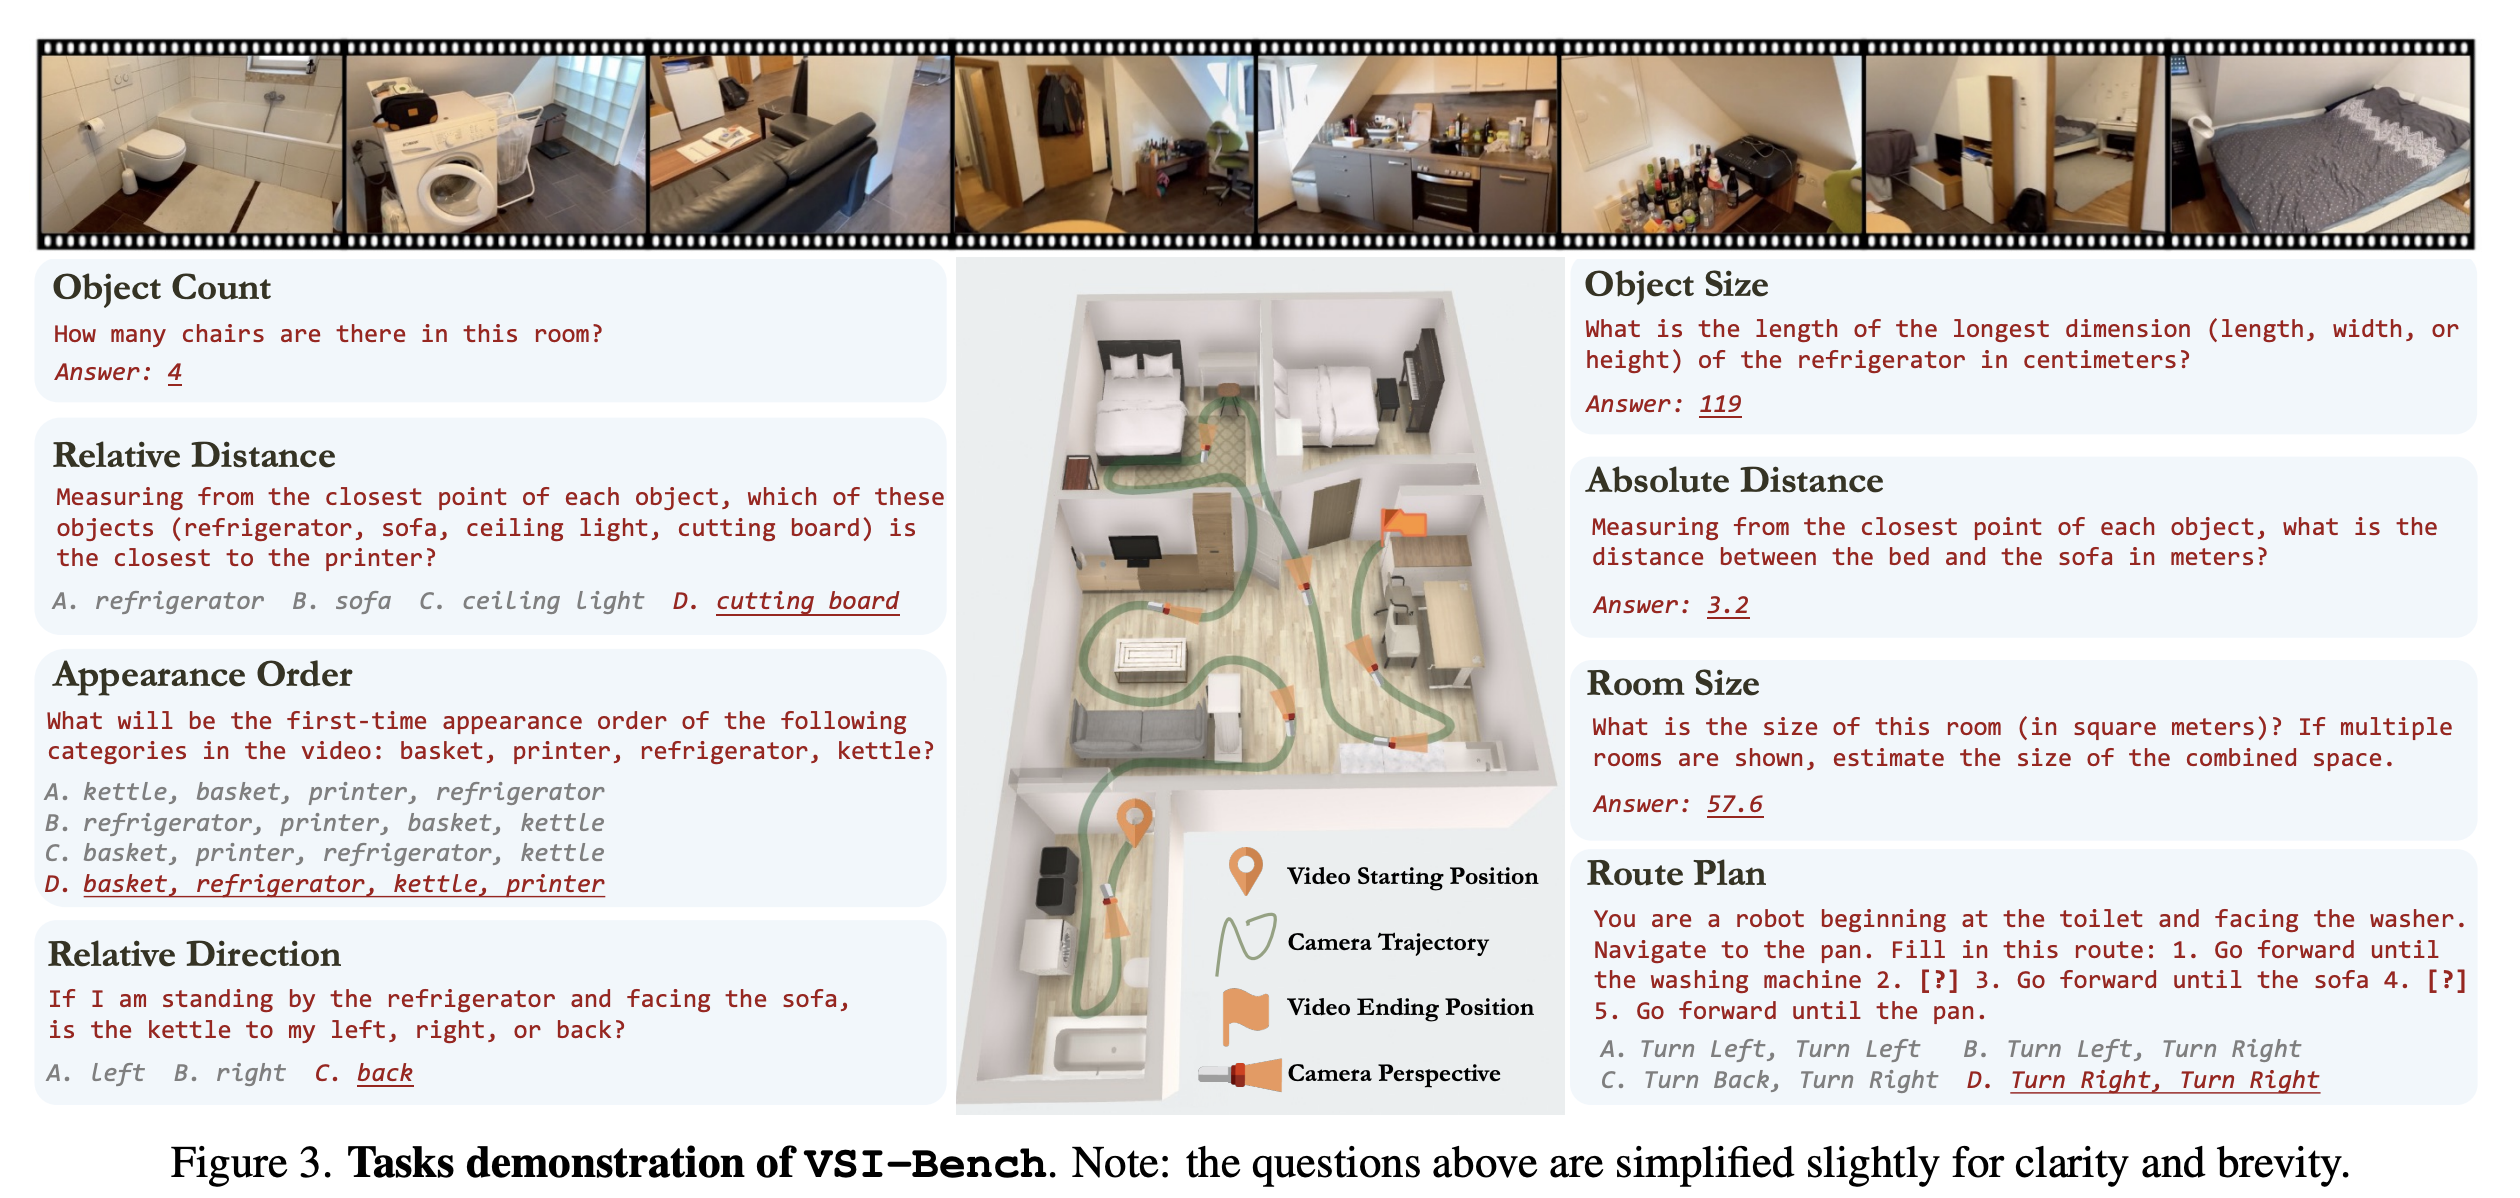
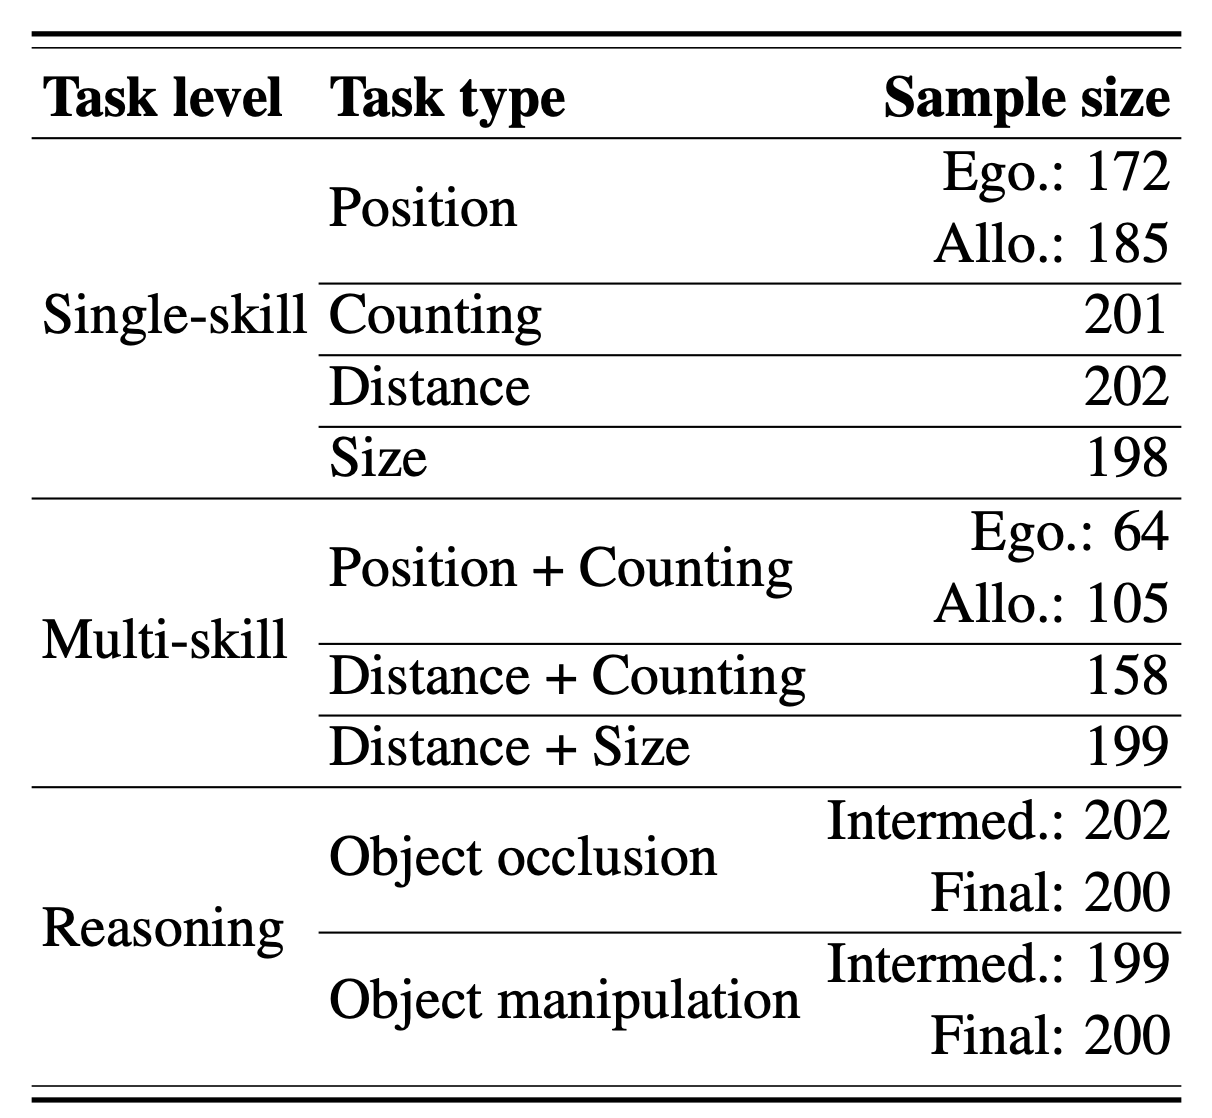
Thinking in Space: How Multimodal Large Language Models See, Remember, and Recall SpacesCVPR25-01linkStar countVSI-Benchimg
M3: 3D-Spatial Multimodal MemoryICLR25-01linkStar count--img
Video-3D LLM: Learning Position-Aware Video Representation for 3D Scene UnderstandingCVPR25-01------img
Compositional 4D Dynamic Scenes Understanding with Physics Priors for Video Question AnsweringICLR25-01linkStar countDynSuperCLEVRimg
DOES SPATIAL COGNITION EMERGE IN FRONTIER MODELS?ICLR24-10linkStar countSPACEimg
Explore until Confident: Efficient Exploration for Embodied Question AnsweringARXIV24-03linkStar count--img
EmbodiedScan: A Holistic Multi-Modal 3D Perception Suite Towards Embodied AICVPR24-01------img

Multi-View Images

<tr>
<td><a href="https://arxiv.org/pdf/2511.21688">G^2VLM: Geometry Grounded Vision Language Model with Unified 3D

Reconstruction and Spatial Reasoning

Others

<tr>
<td><a href="https://arxiv.org/pdf/2512.02487">Masking Matters: Unlocking the Spatial Reasoning Capabilities of LLMs

for 3D Scene-Language Understanding

TitleVenueDateCodeStarsBenchmarkIllustration
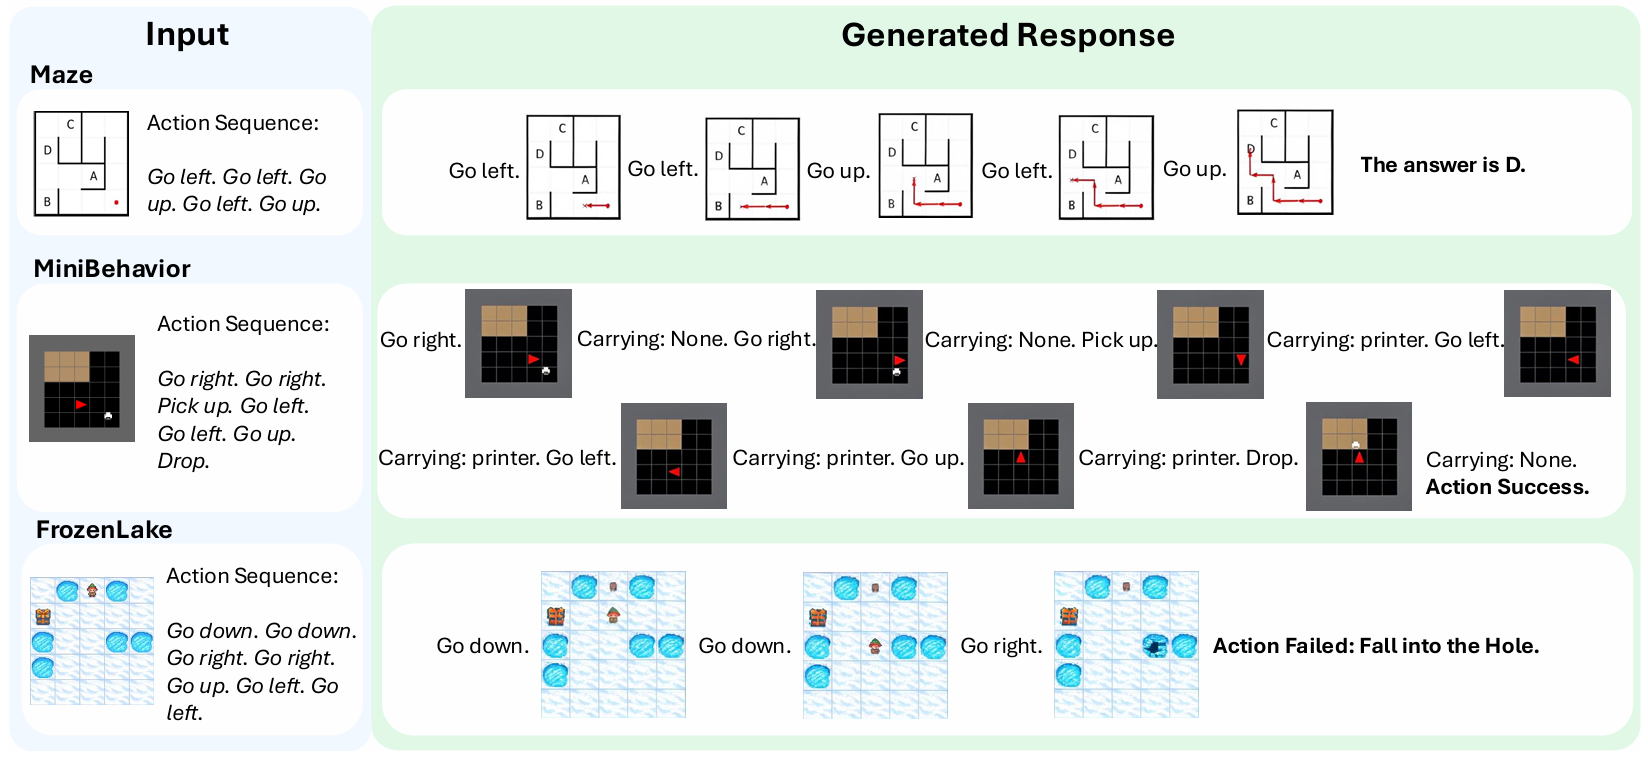
SpatialLadder: Progressive Training for Spatial Reasoning in Vision-Language ModelsARXIV25-10linkStar countSpatialLadder-26k--
N3D-VLM: Native 3D Grounding Enables Accurate Spatial Reasoning in Vision-Language ModelsARXIV25-12link------
ARXIV25-11------img
Visual Spatial TuningARXIV25-11linkStar count--img
Multimodal Spatial Reasoning in the Large Model Era: A Survey and BenchmarksARXIV25-10linkStar countVSTimg
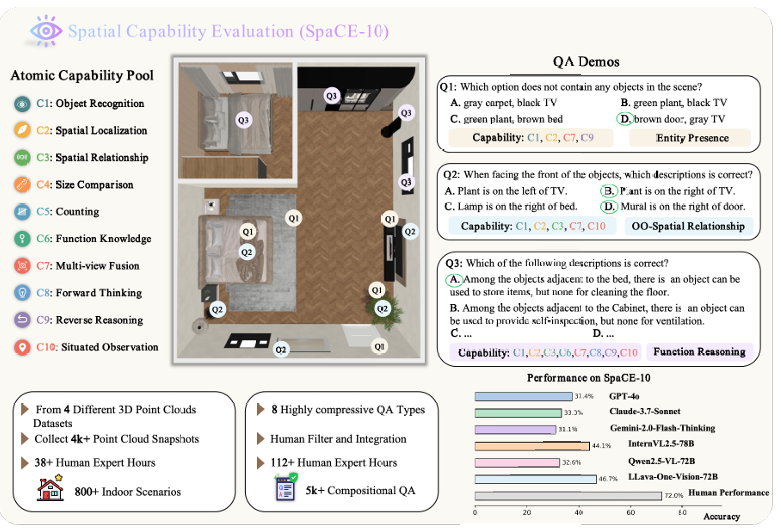
SpaCE-10: A Comprehensive Benchmark for Multimodal Large Language Models in Compositional Spatial IntelligenceARXIV25-06linkStar countSpaCE-10img
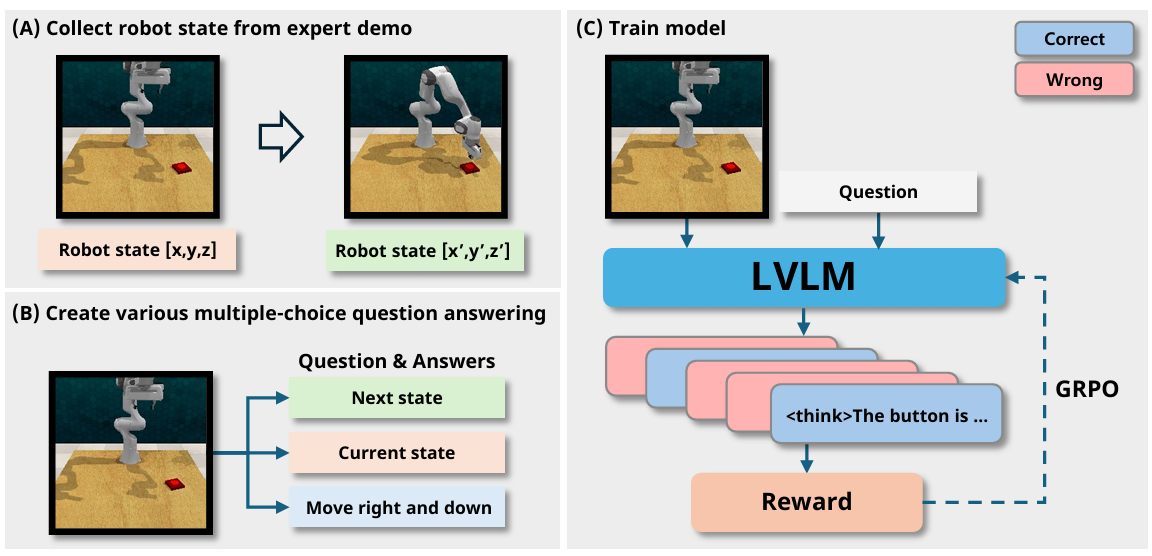
Robot-R1: Reinforcement Learning for Enhanced Embodied Reasoning in RoboticsARXIV25-06----Robot-R1 Benchimg
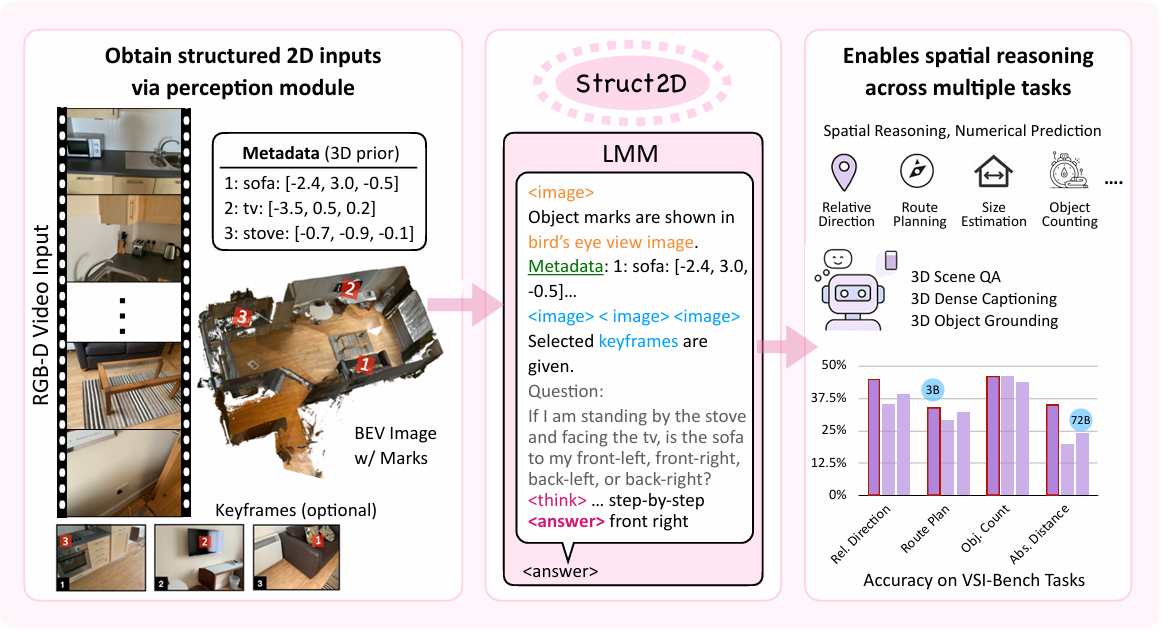
Struct2D: A Perception-Guided Framework for Spatial Reasoning in Large Multimodal ModelsARXIV25-06linkStar count--img
SpatialScore Towards Unified Evaluation for Multimodal Spatial UnderstandingARXIV25-05linkStar countSpatialScoreimg
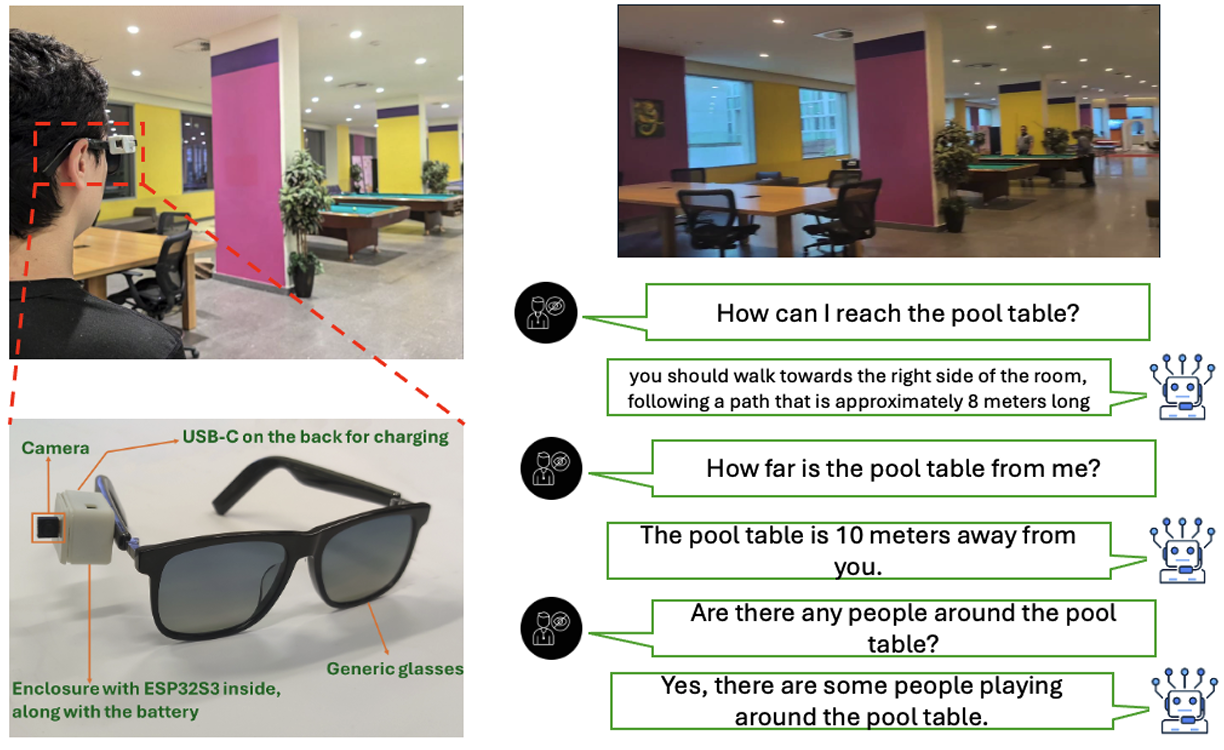
A Light and Smart Wearable Platform with Multimodal Foundation Model for Enhanced Spatial Reasoning in People with Blindness and Low VisionECCV25-05----LVSQAimg
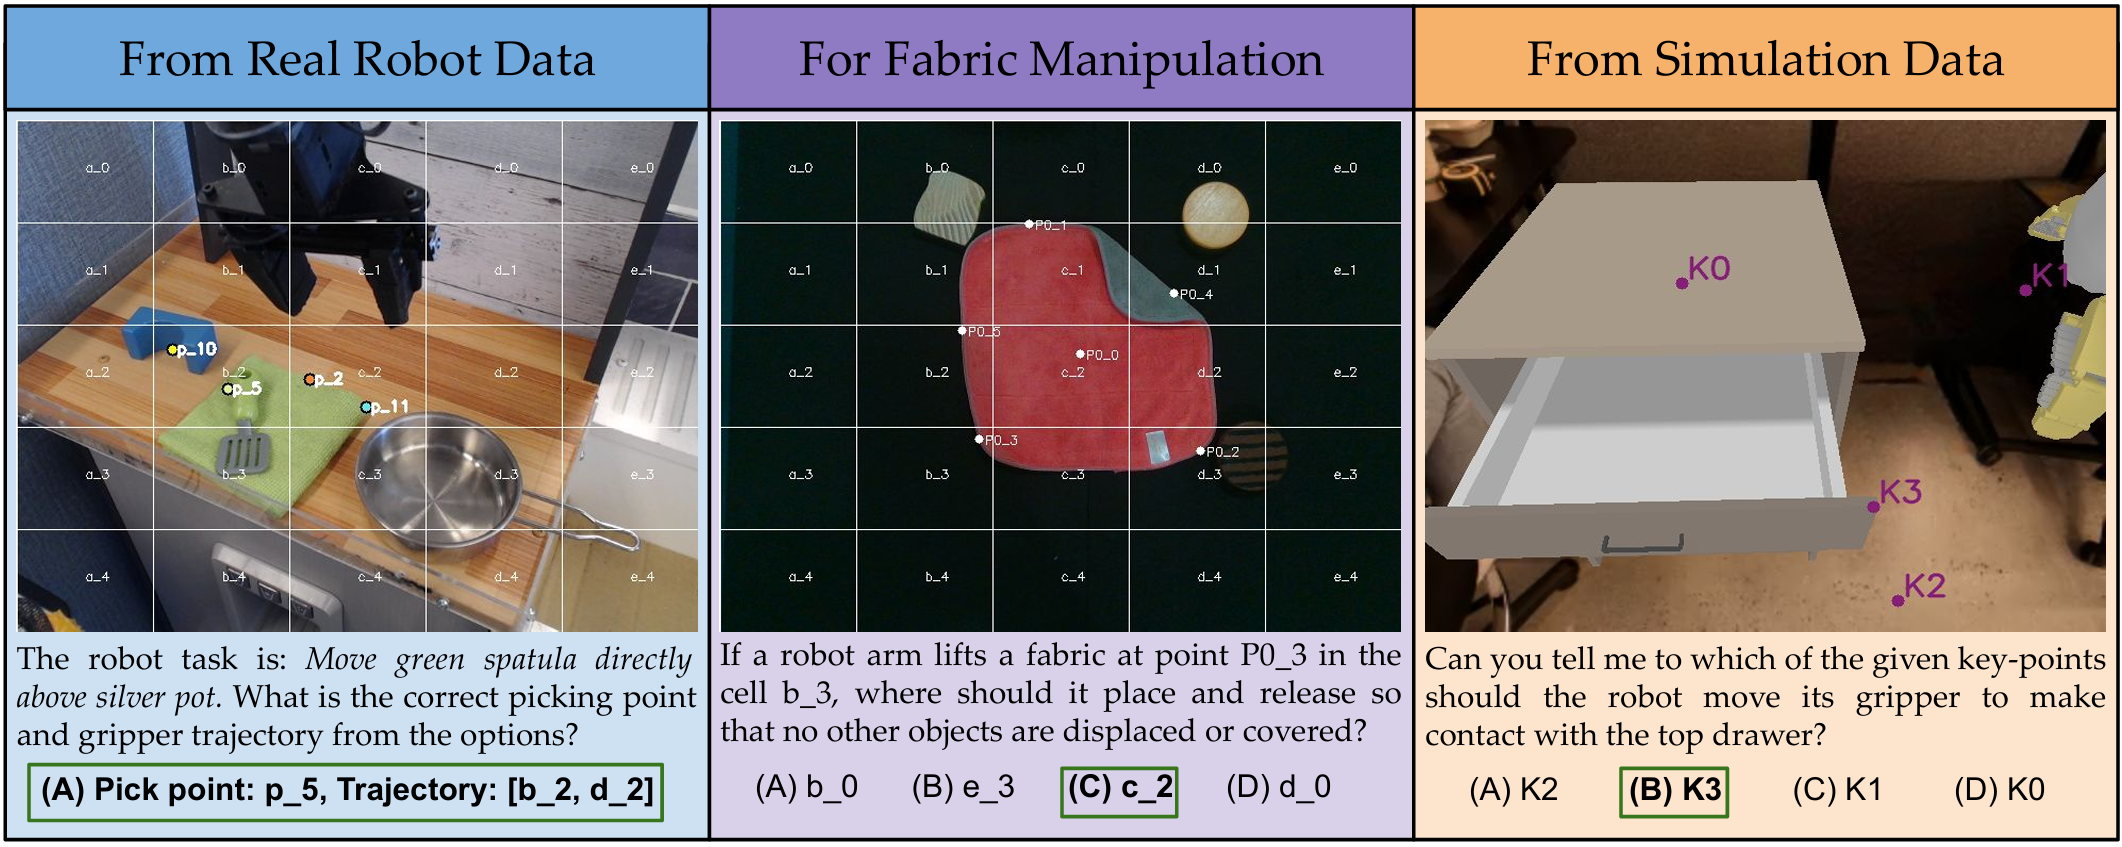
ManipBench: Benchmarking Vision-Language Models for Low-Level Robot ManipulationARXIV25-05link--ManipBenchimg
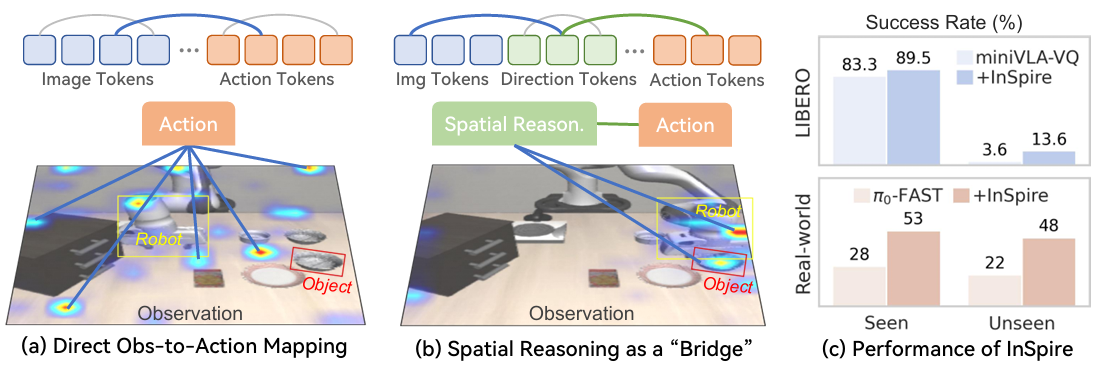
InSpire: Vision-Language-Action Models with Intrinsic Spatial ReasoningARXIV25-05linkStar count--img
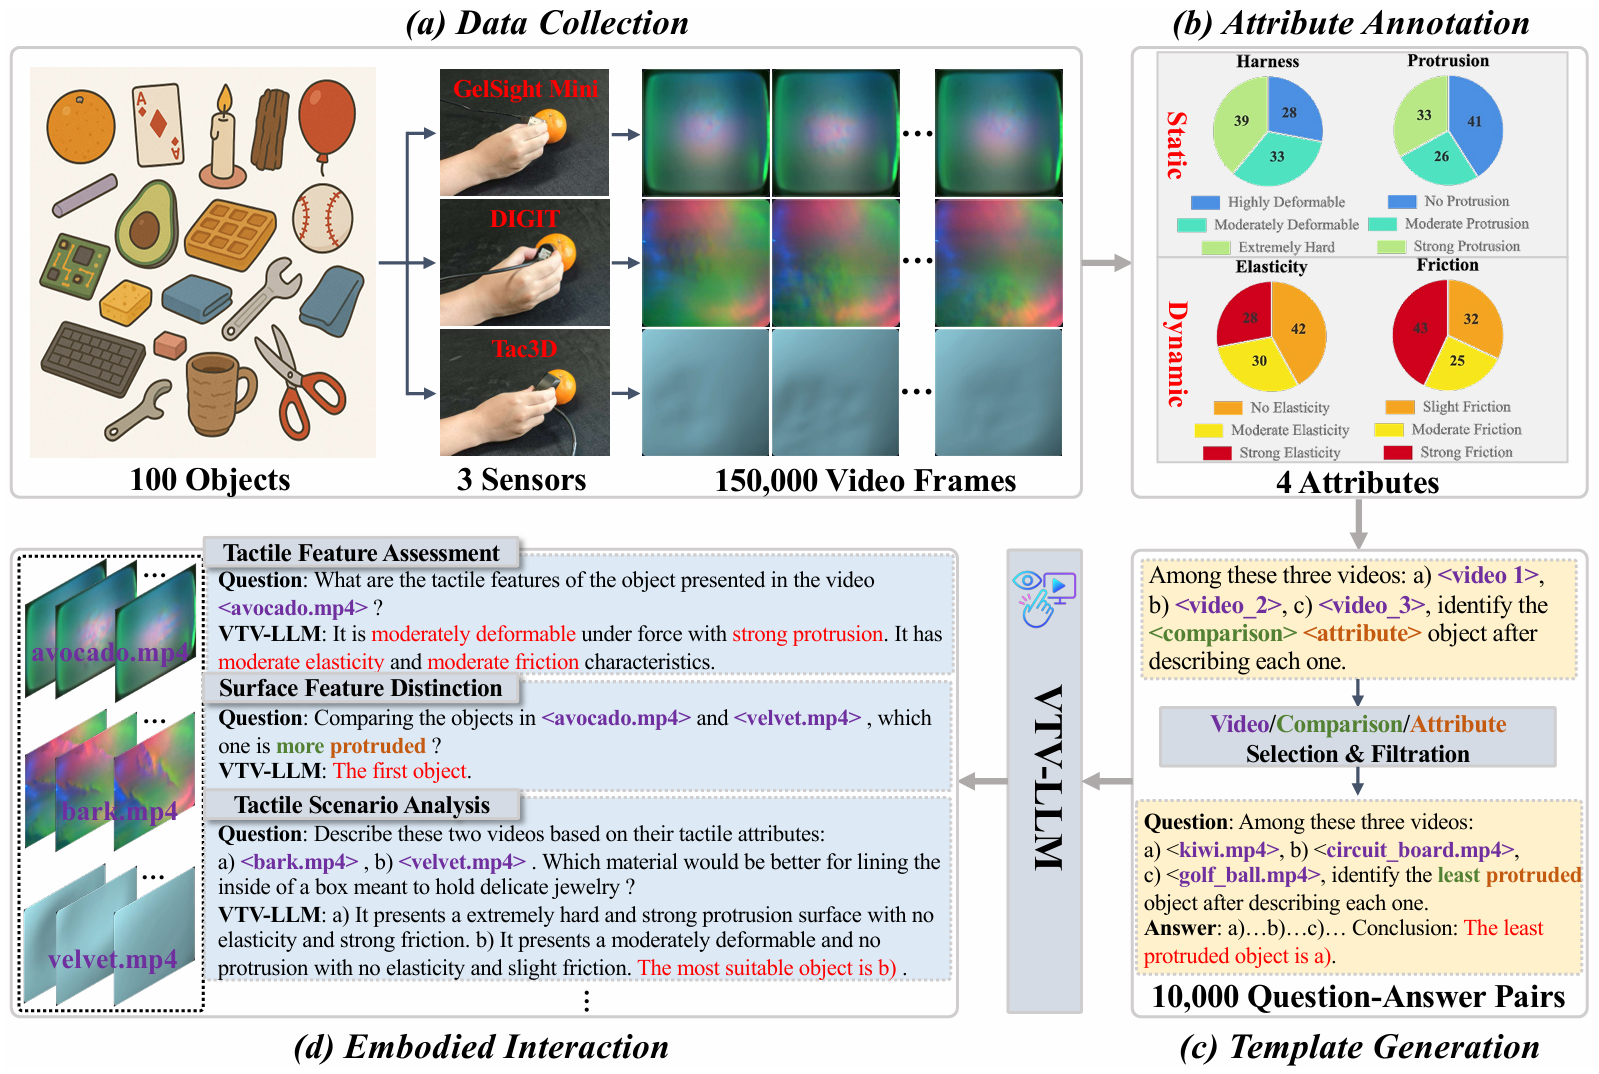
Universal Visuo-Tactile Video Understanding for Embodied InteractionARXIV25-05------img
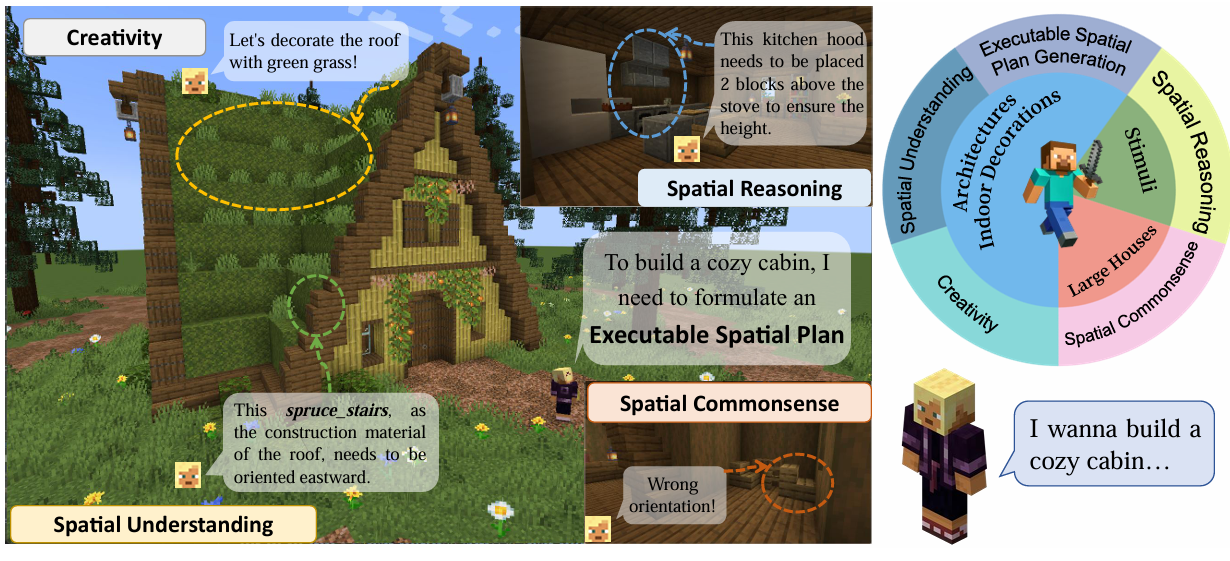
MineAnyBuild: Benchmarking Spatial Planning for Open-world AI AgentsARXIV25-05linkStar count--img
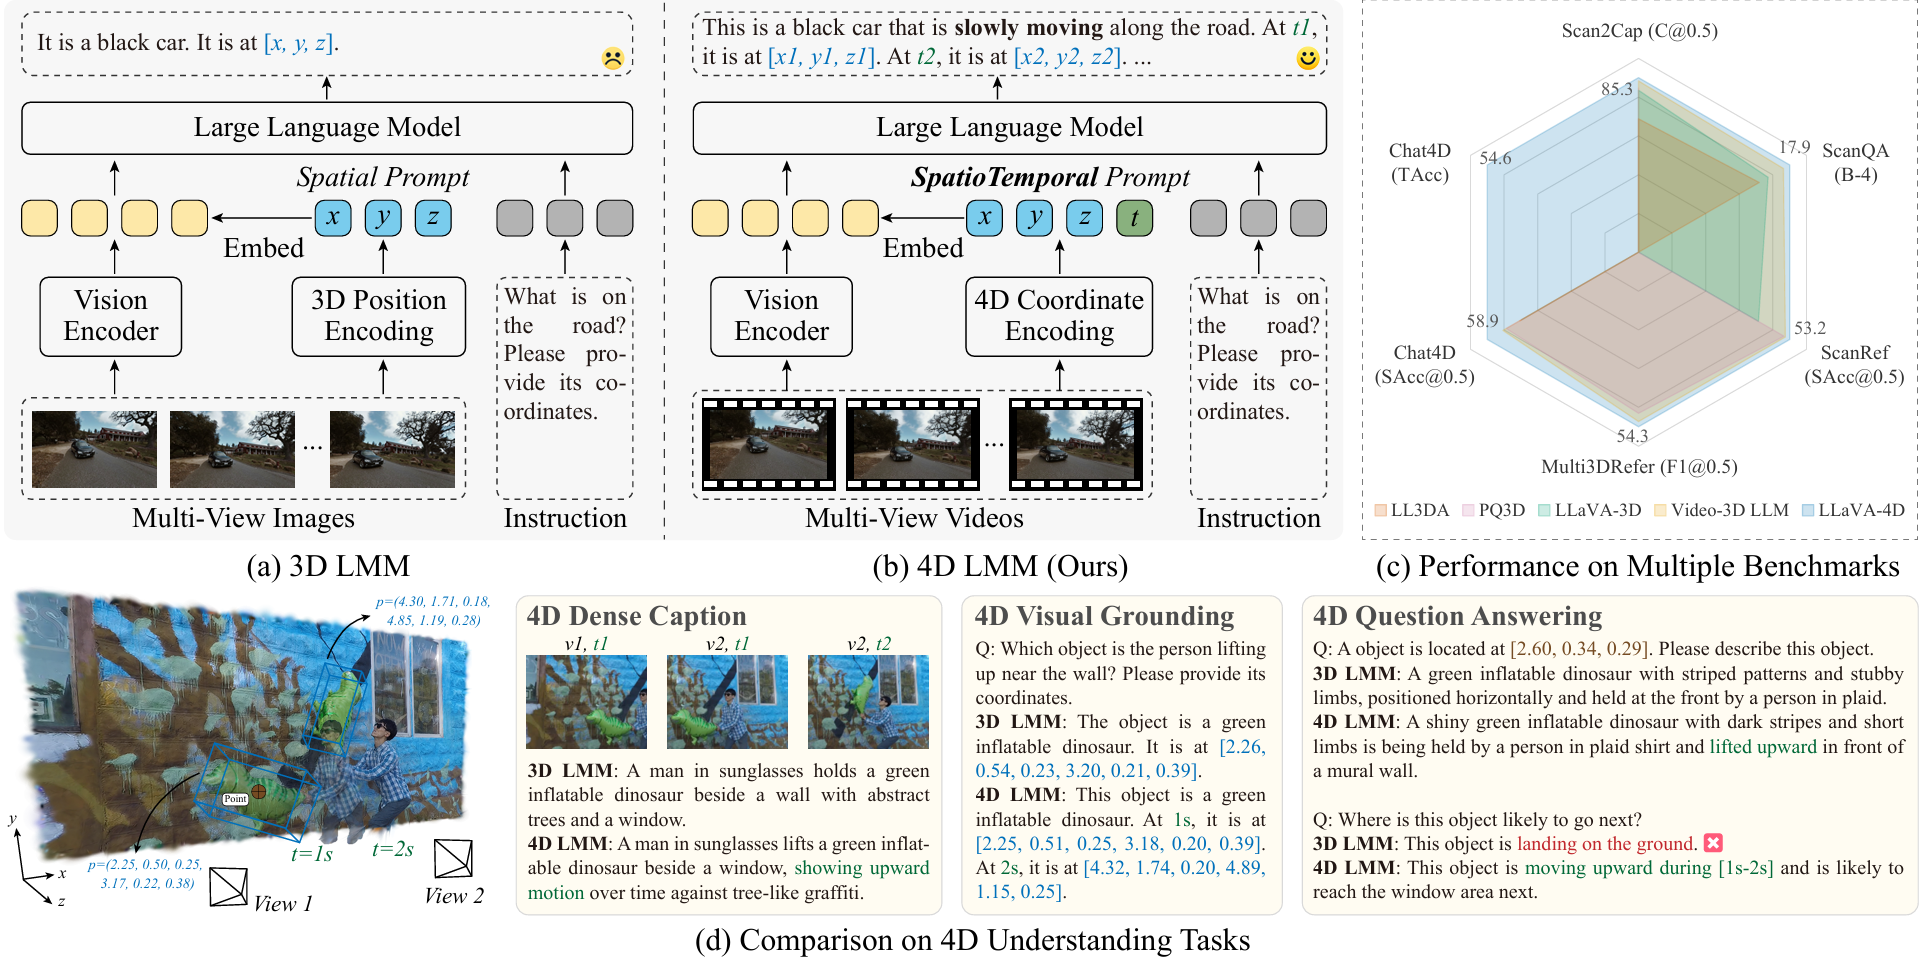
LLaVA-4D: Embedding SpatioTemporal Prompt into LMMs for 4D Scene UnderstandingARXIV25-05----scan2cap, scanqa
scanref, multi3drefer
chat4d
img
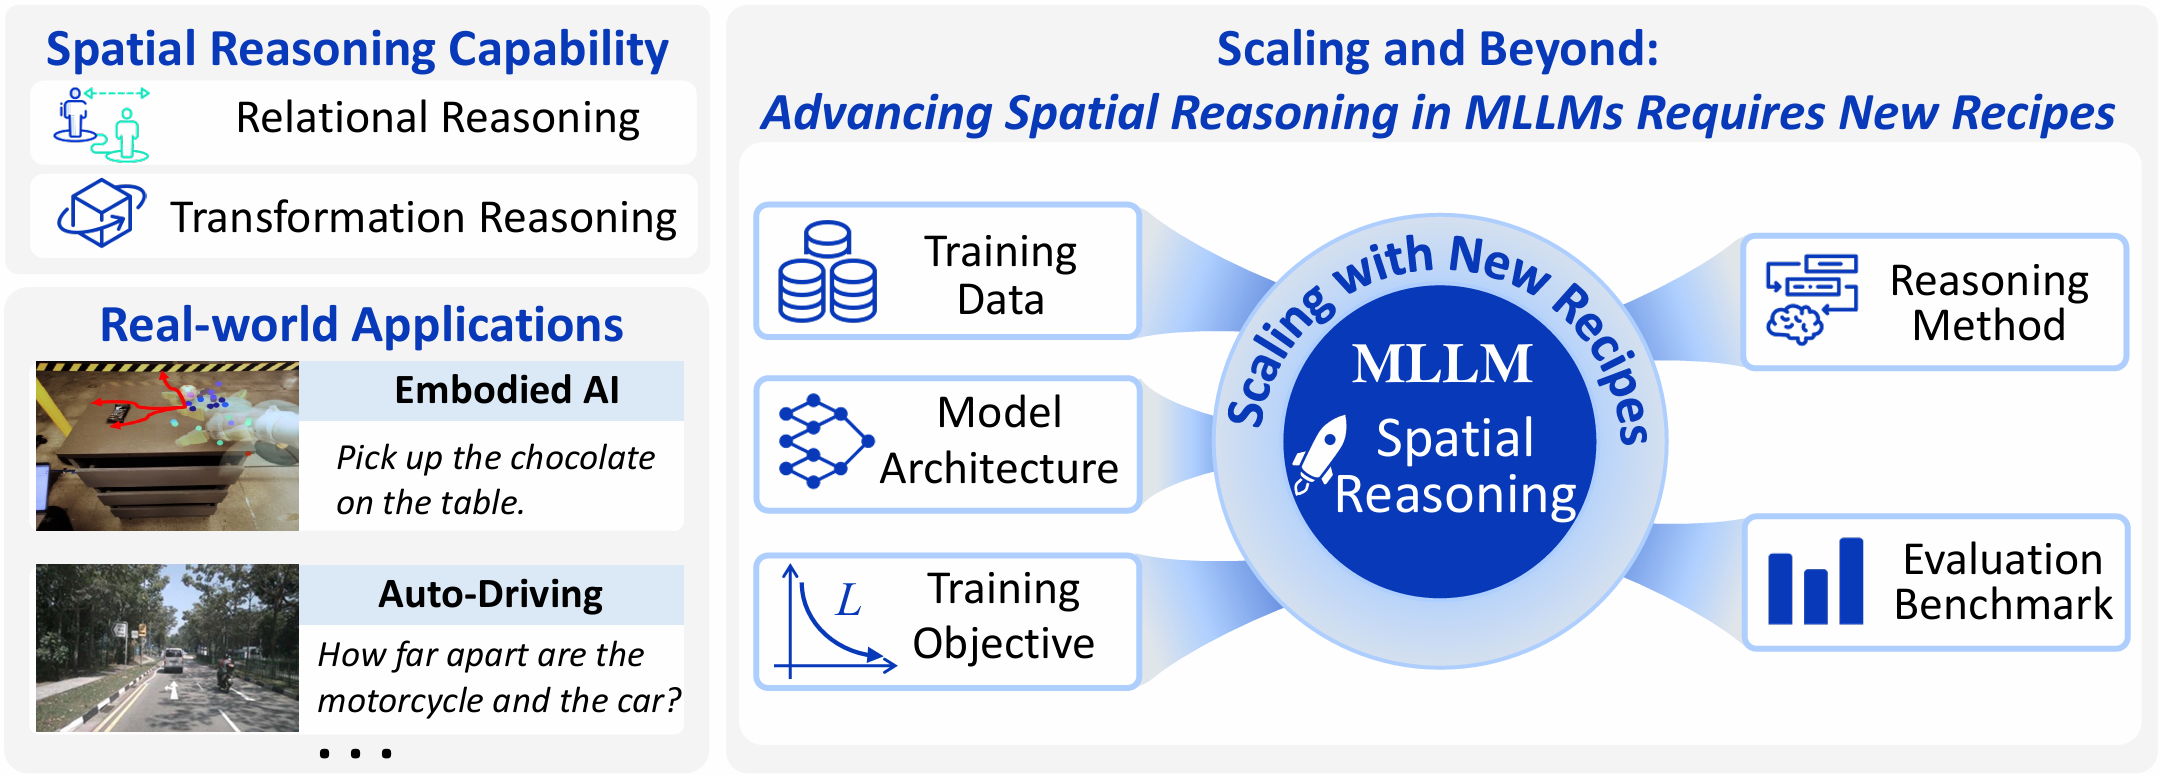
Scaling and Beyond: Advancing Spatial Reasoning in MLLMs Requires New RecipesARXIV25-04------img
A Survey of Large Language Model-Powered Spatial Intelligence Across Scales: Advances in Embodied Agents, Smart Cities, and Earth ScienceARXIV25-04------img
Ross3D: Reconstructive Visual Instruction Tuning with 3D-AwarenessARXIV25-04linkStar countsqa3d, scanqaimg
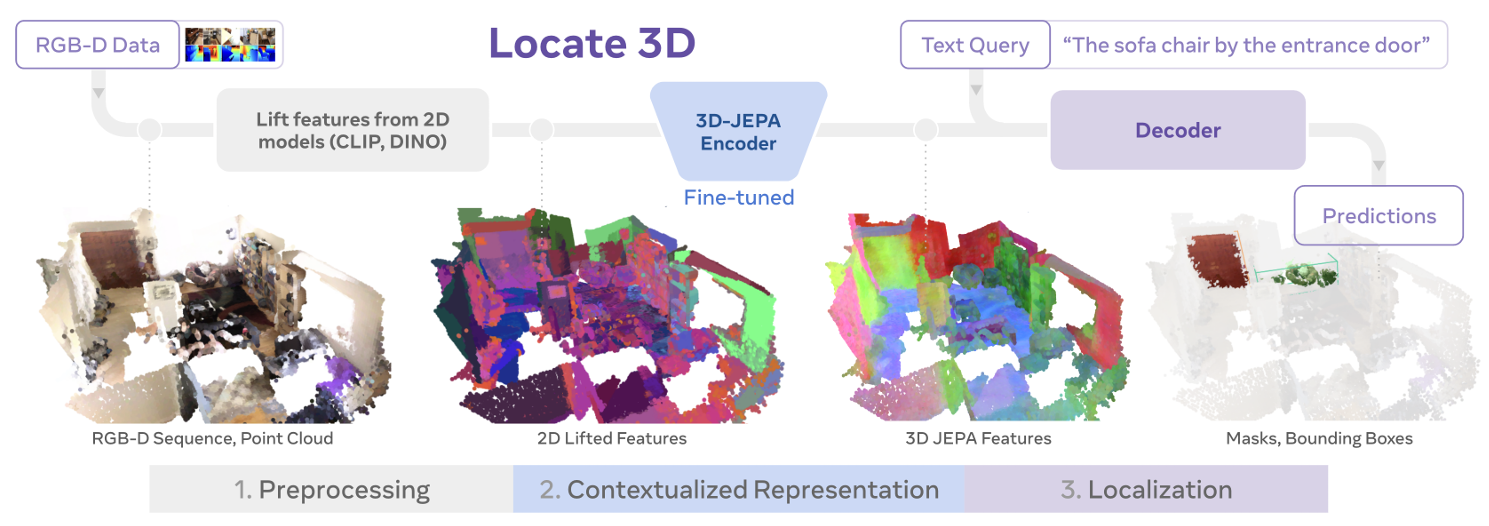
Locate 3D: Real-World Object Localization via Self-Supervised Learning in 3DARXIV25-04linkStar countSR3D, NR3D
ScanRefer
img
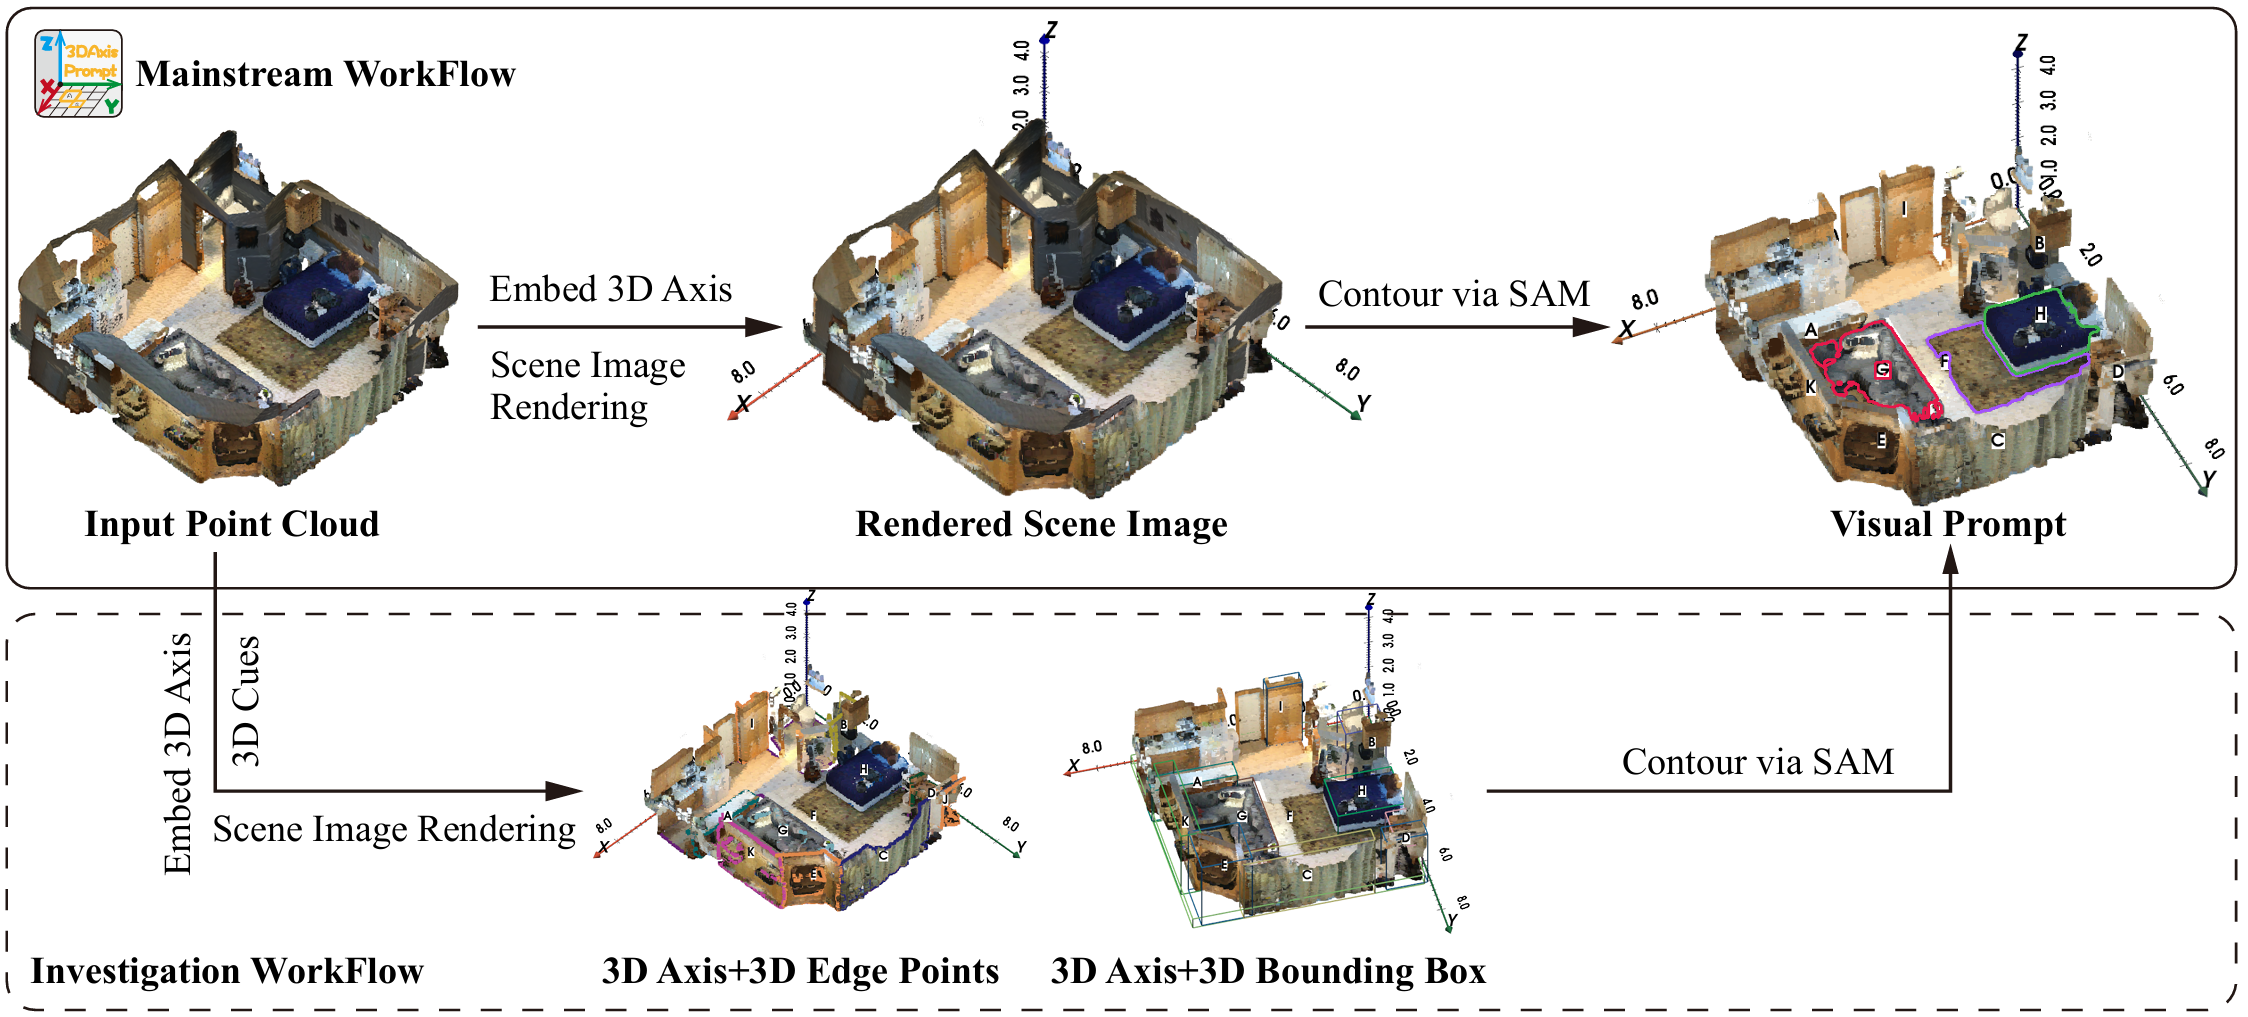
3DAxisPrompt: Promoting the 3D Grounding and Reasoning in GPT-4o--25-03------img
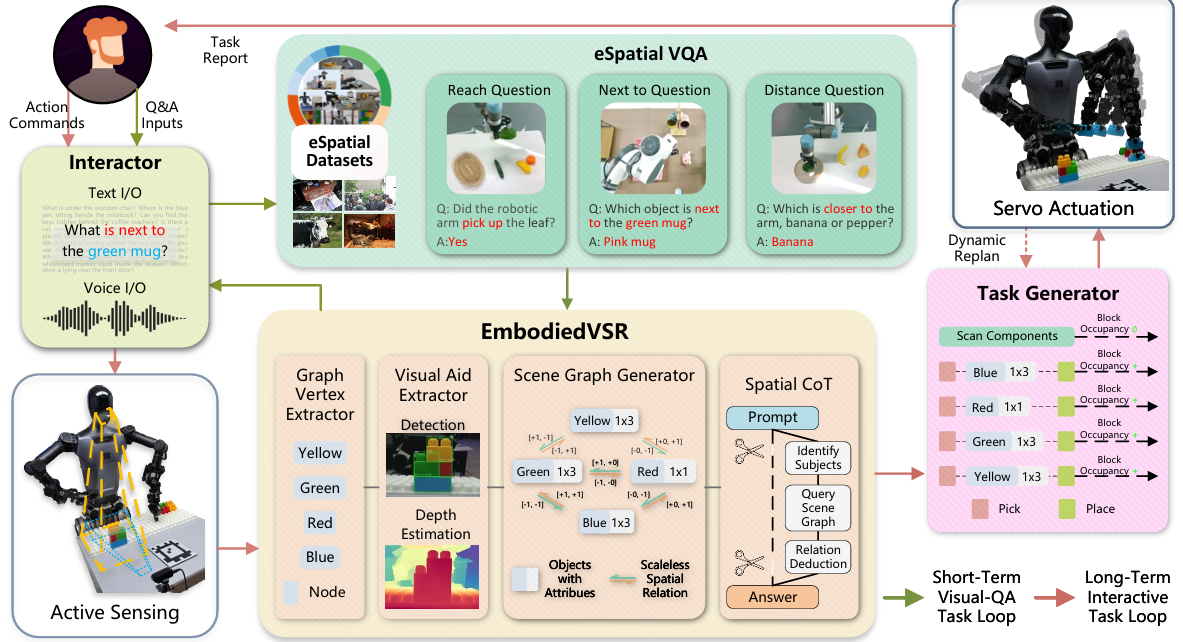
EmbodiedVSR: Dynamic Scene Graph-Guided Chain-of-Thought Reasoning for Visual Spatial TasksARXIV25-03------img
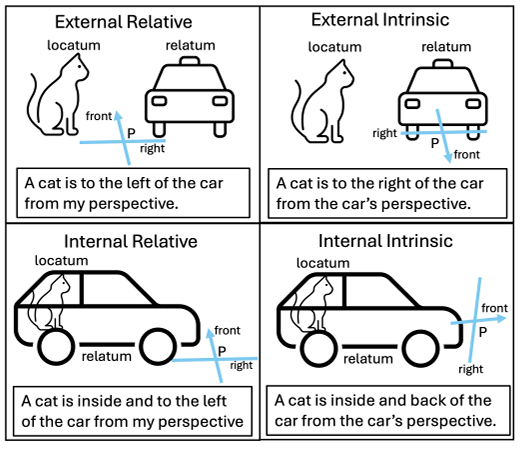
FoREST: Frame of Reference Evaluation in Spatial Reasoning TasksARXIV25-02linkStar countFoRESTimg
A Real-to-Sim-to-Real Approach to Robotic Manipulation with VLM-Generated Iterative Keypoint RewardsICRA25-02linkStar count--img
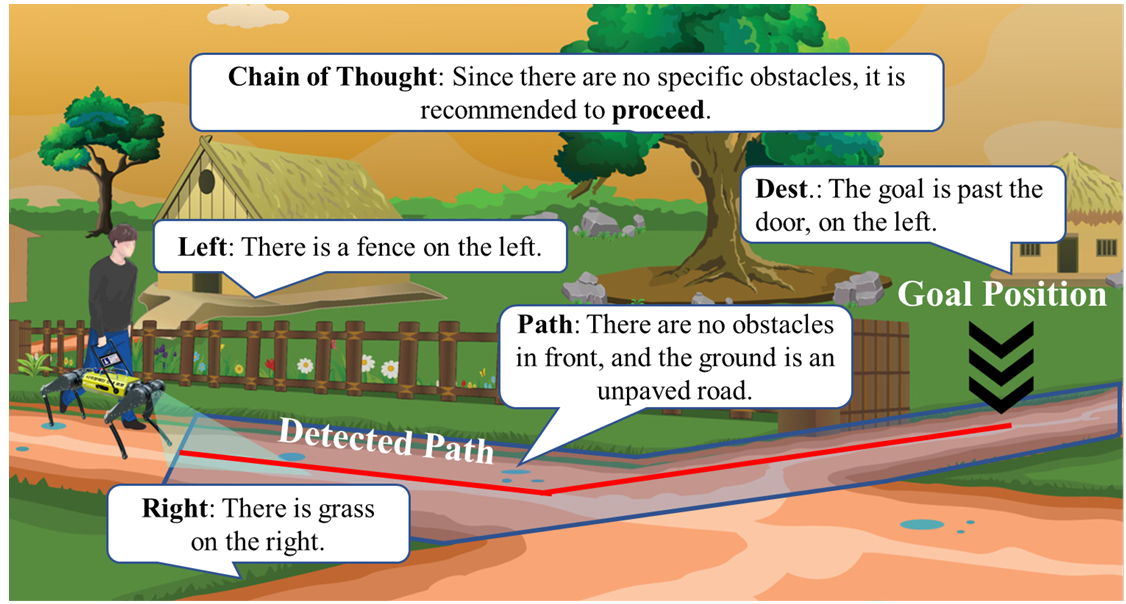
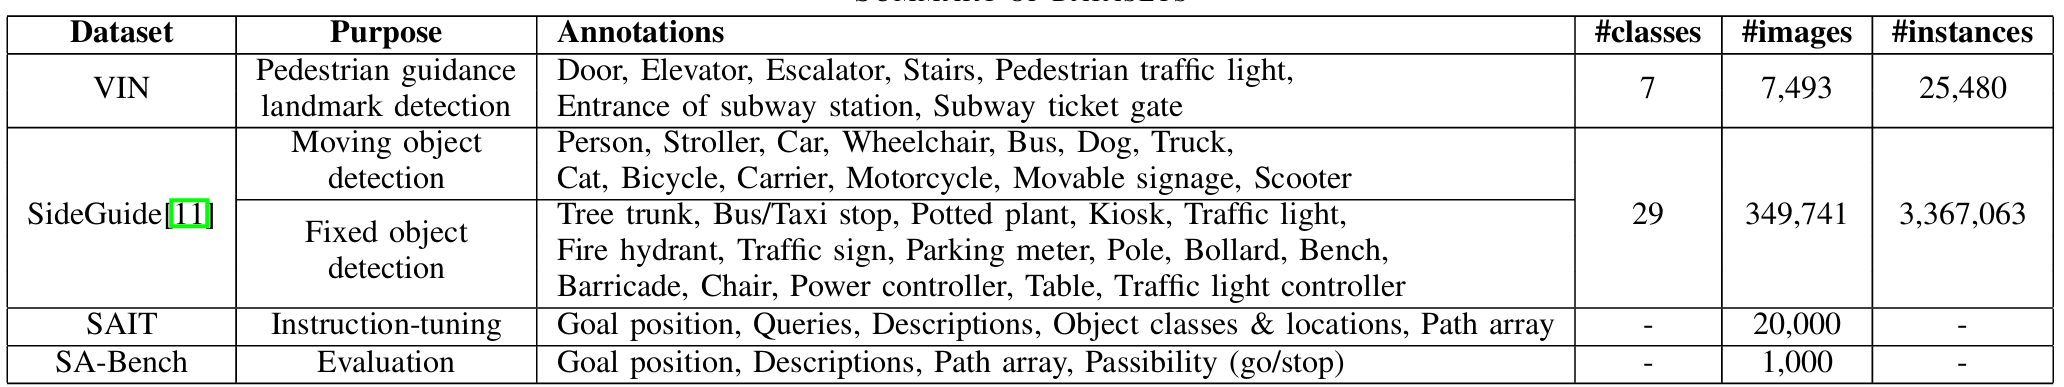
pace-Aware Instruction Tuning: Dataset and Benchmark for Guide Dog Robots Assisting the Visually ImpairedARXIV25-02linkStar countSA-Benchimg
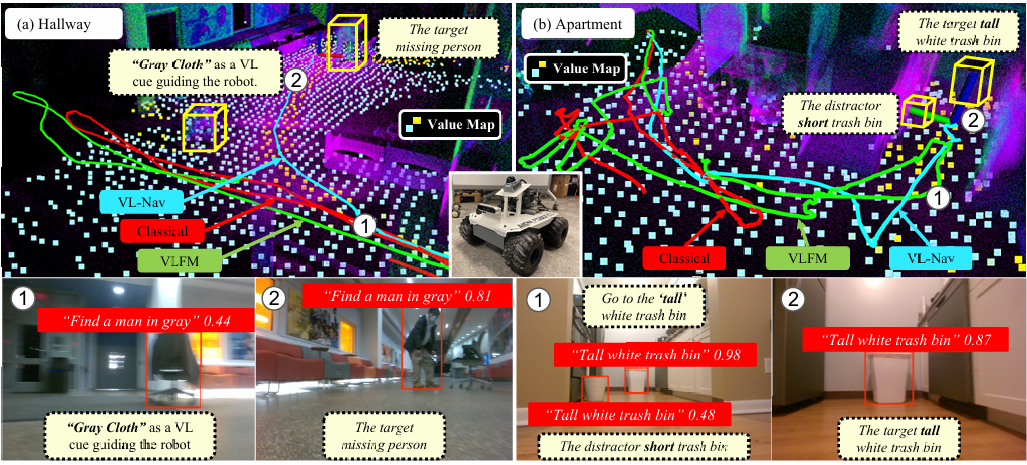
VL-Nav: Real-time Vision-Language Navigation with Spatial ReasoningARXIV25-02------img
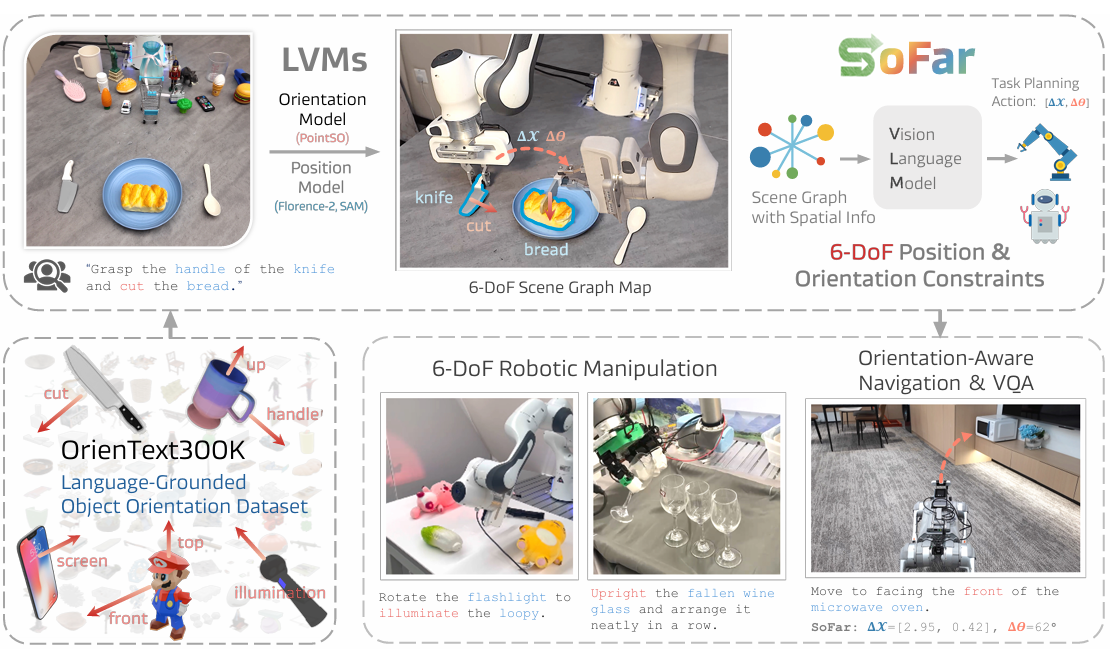
SoFar: Language-Grounded Orientation Bridges Spatial Reasoning and Object ManipulationARXIV25-02linkStar count--img
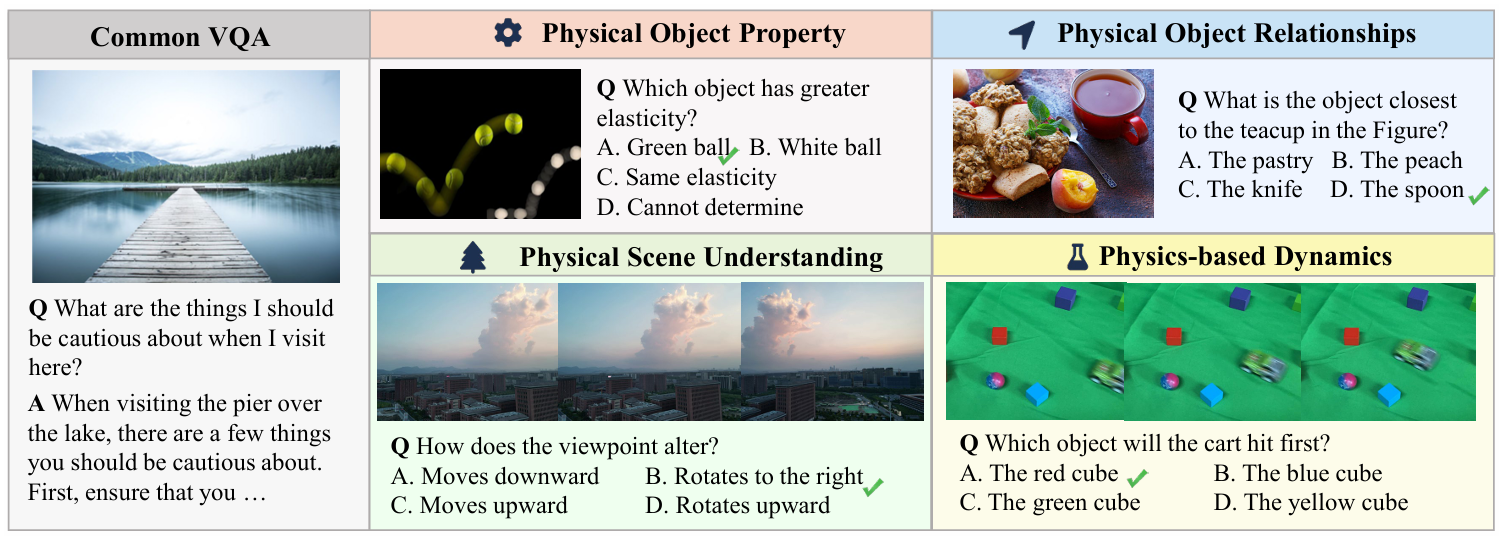
PHYSBENCH: BENCHMARKING AND ENHANCING VISION-LANGUAGE MODELS FOR PHYSICAL WORLD UNDERSTANDINGARXIV25-01linkStar countPhysBenchimg
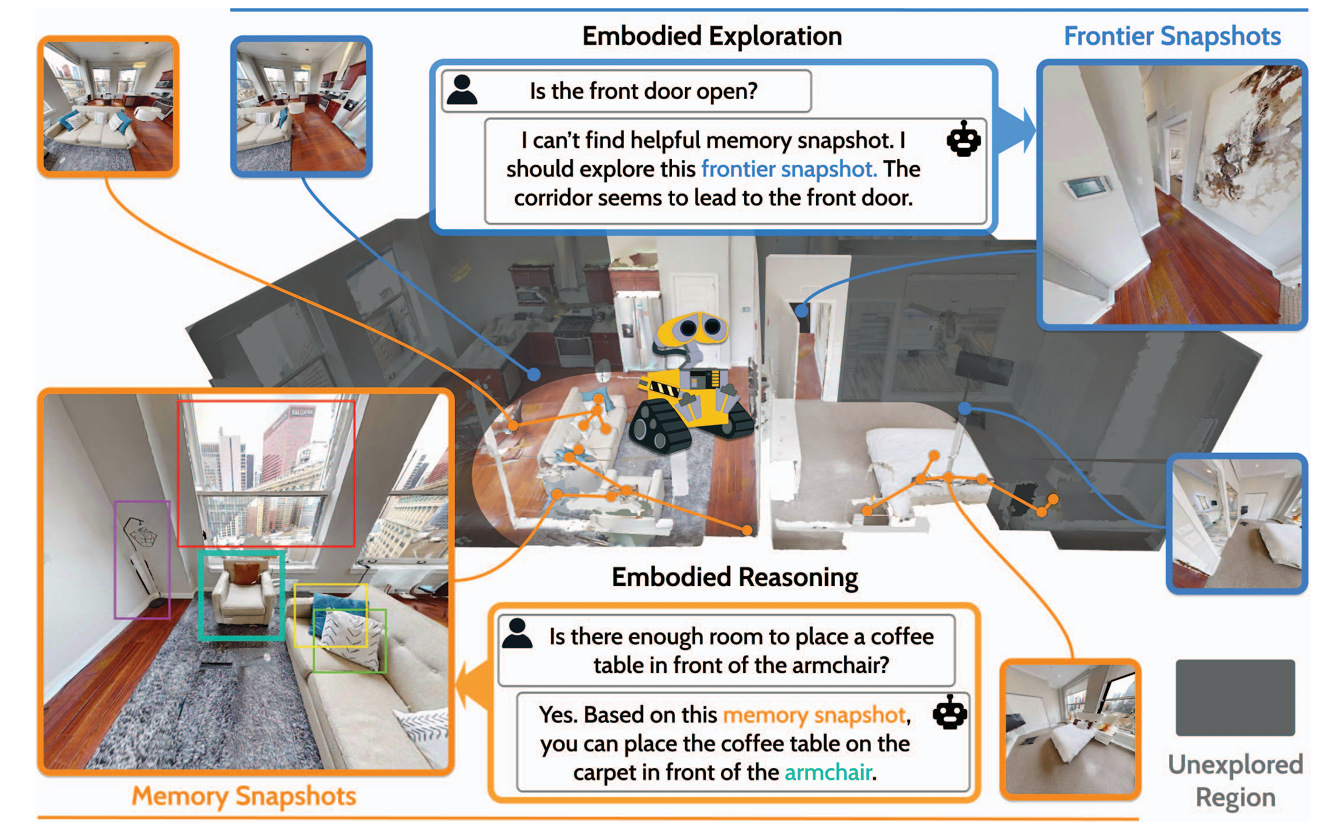
3D-Mem: 3DScene Memory for Embodied Exploration and ReasoningCVPR25-01linkStar count--img
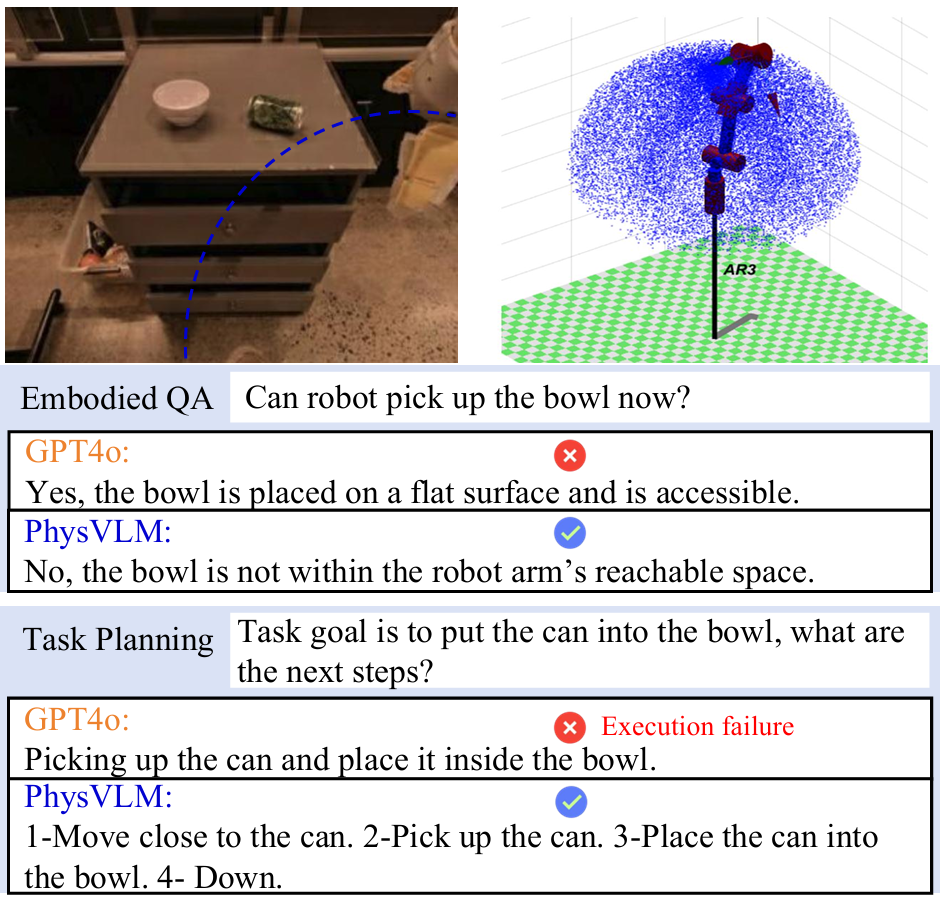
PhysVLM: Enabling Visual Language Models to Understand Robotic Physical ReachabilityCVPR25-01------img
Evaluating and enhancing spatial cognition abilities of large language modelsIJGIS25-01linkStar count--img
EMBODIEDEVAL: Evaluate Multimodal LLMs as Embodied AgentsARXIV25-01----EMBODIEDEVALimg
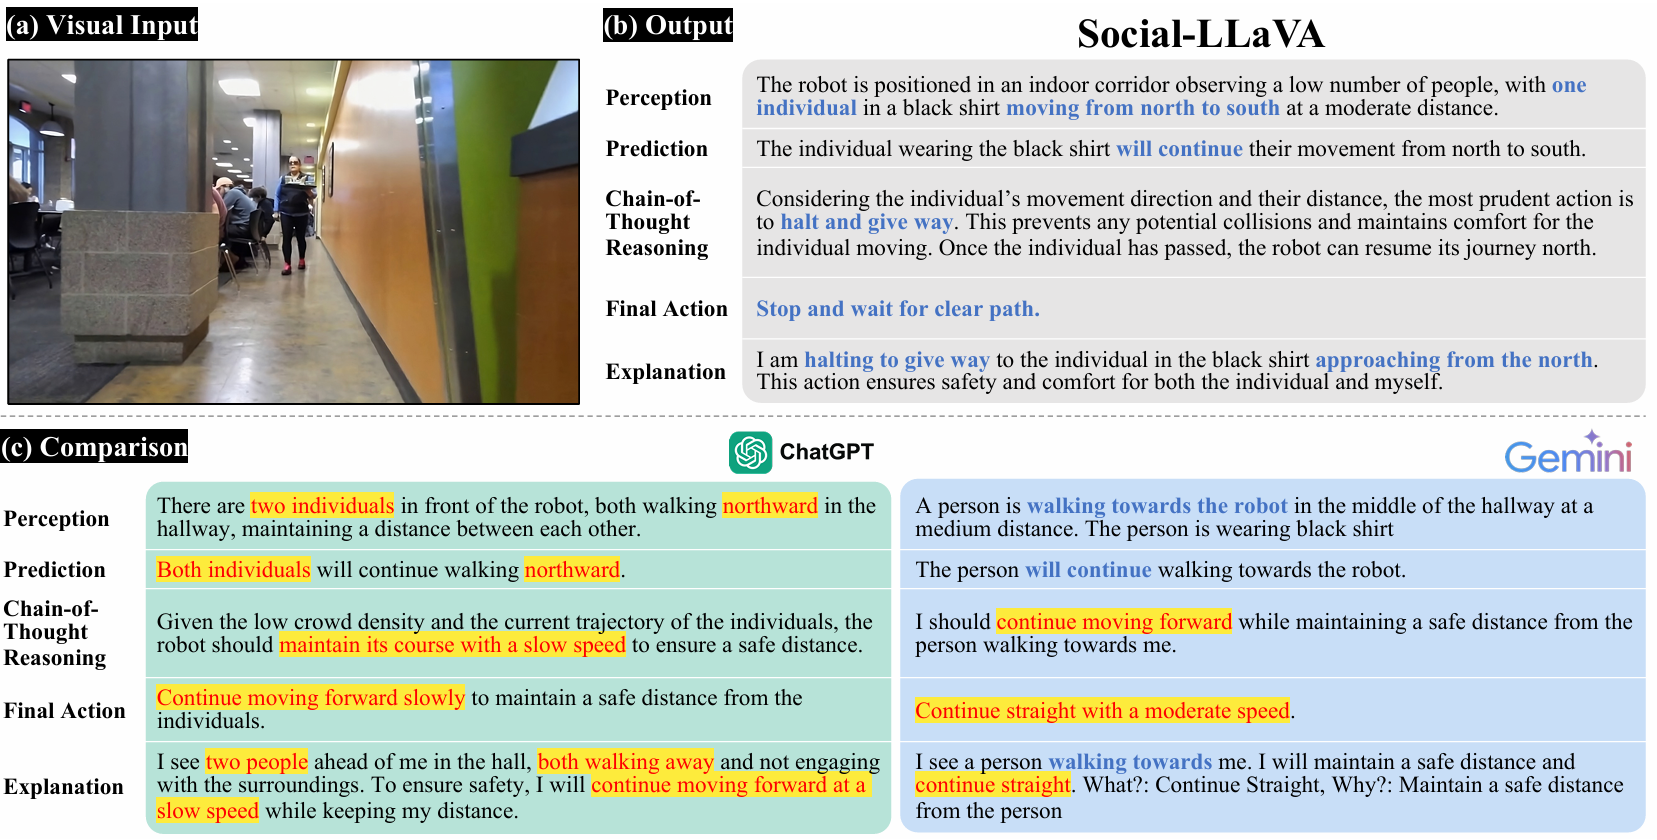
Social-LLaVA: Enhancing Robot Navigation through Human-Language Reasoning in Social SpacesARXIV25-01link--Social-LLaVAimg
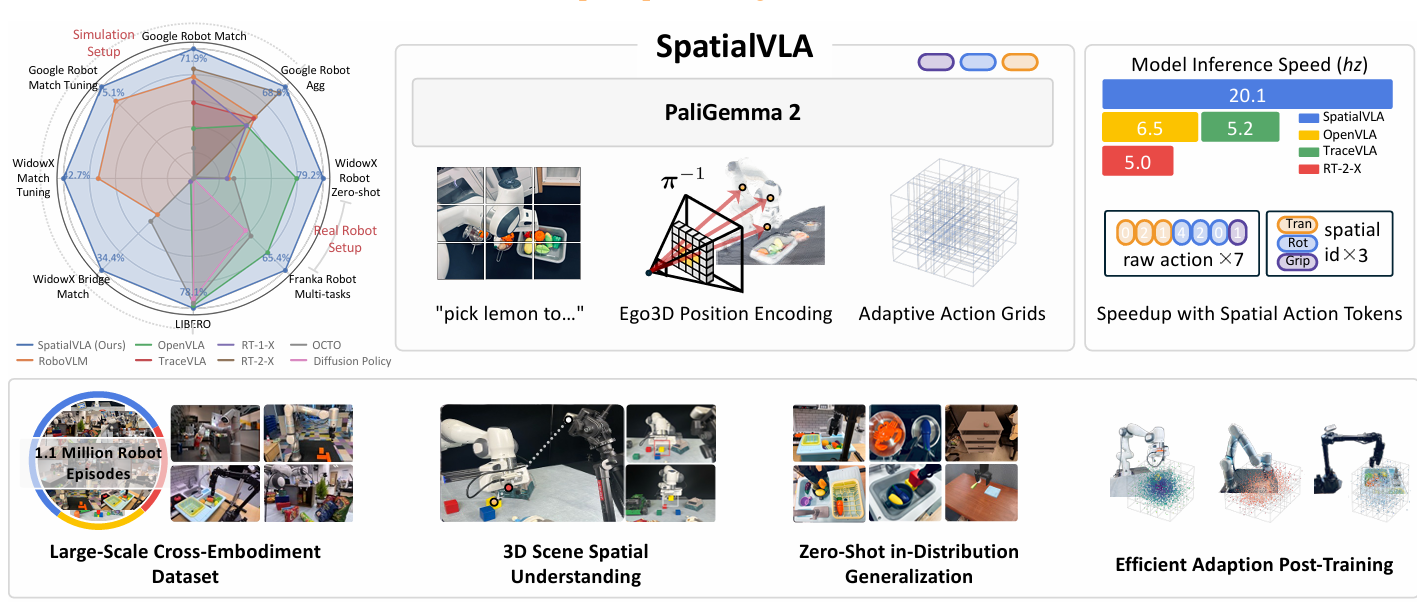
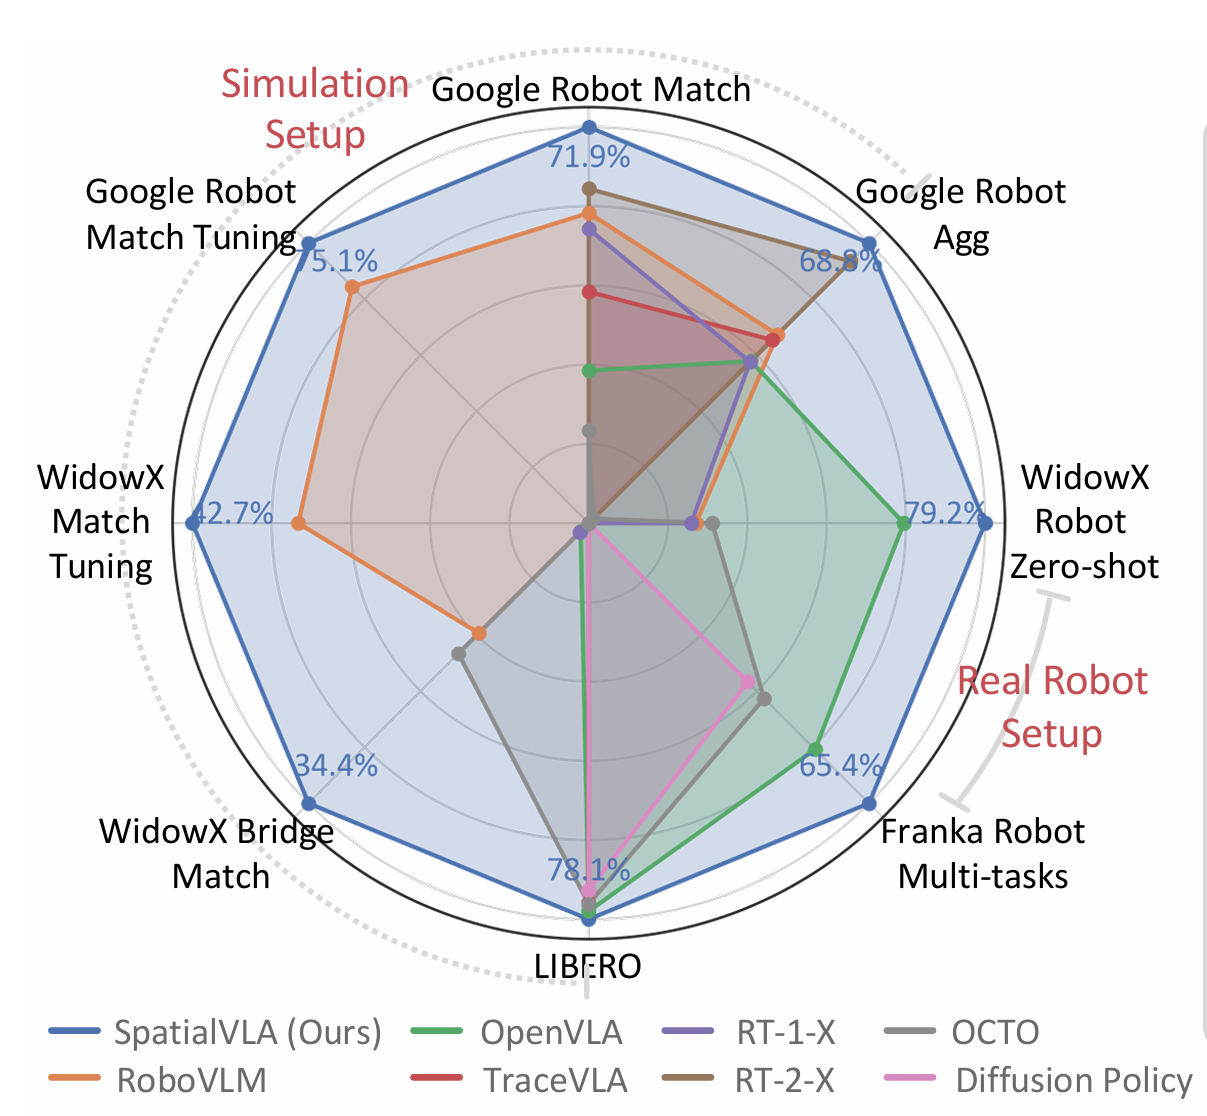
SpatialVLA: Exploring Spatial Representations for Visual-Language-Action ModelARXIV25-01linkStar countSpatialVLAimg
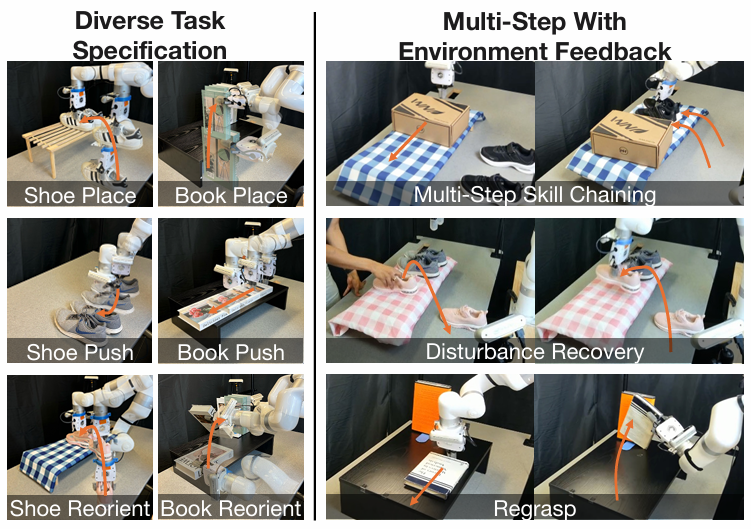
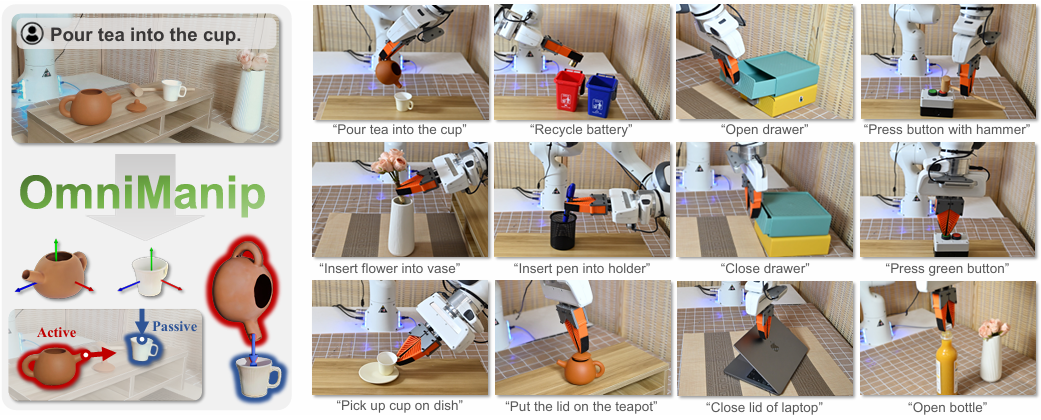
OmniManip: Towards General Robotic Manipulation via Object-Centric Interaction Primitives as Spatial ConstraintsCVPR202525-01linkStar countOmniManipimg
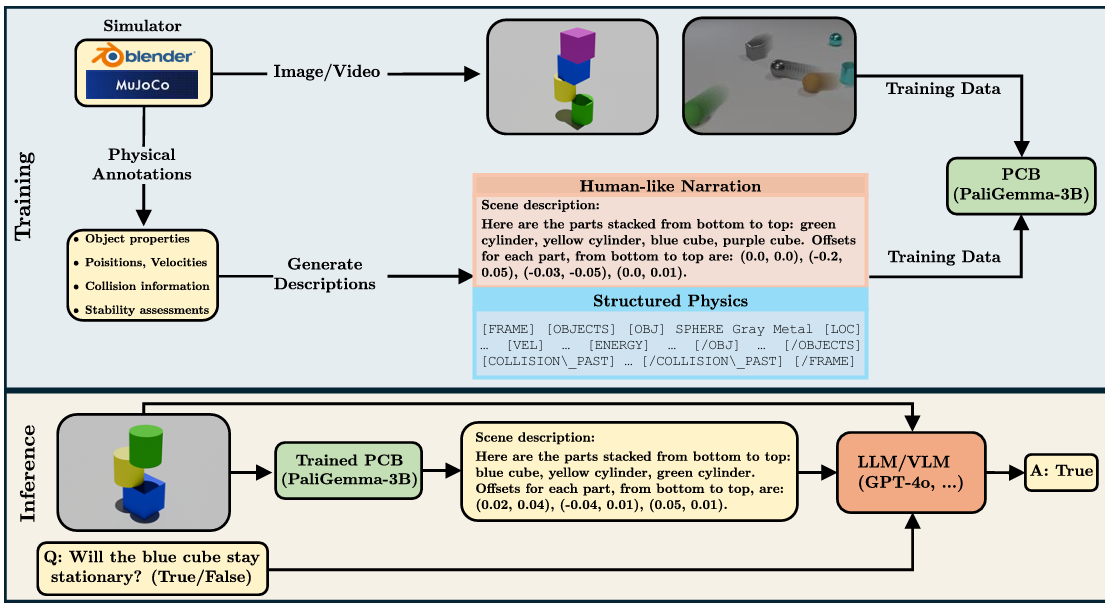
Synthetic Vision: Training Vision-Language Models to Understand Physics--24-12------img
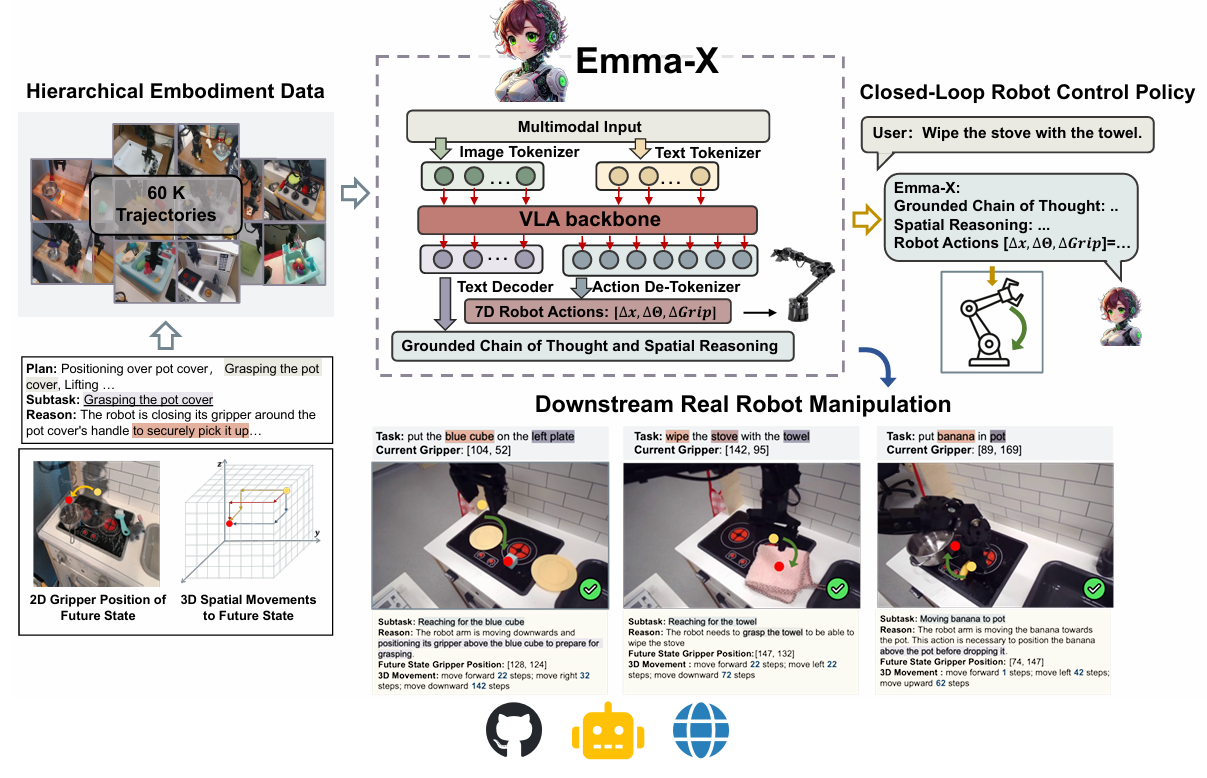
Emma-X: An Embodied Multimodal Action Model with Grounded Chain of Thought and Look-ahead Spatial Reasoning--24-12linkStar countEmma-Ximg
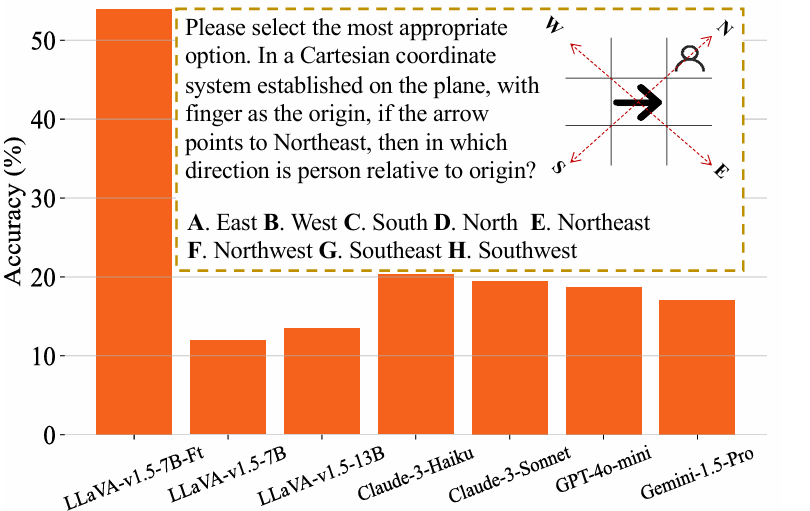
Do Multimodal Language Models Really Understand Direction? A Benchmark for Compass Direction ReasoningARXIV24-12------img
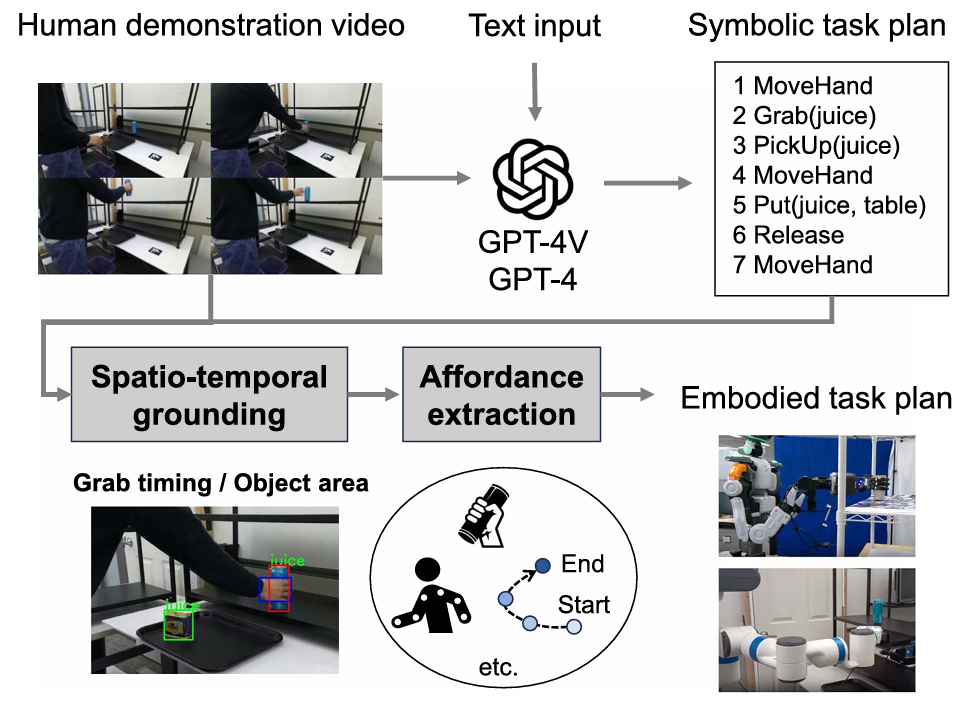
GPT-4V(ision) for Robotics: Multimodal Task Planning From Human DemonstrationOBOTICS AND AUTOMATION LETTERS24-11------img
Do Vision-Language Models Represent Space and How? Evaluating Spatial Frame of Reference Under AmbiguitiesICLR24-10link--COMFORTimg
I KnowAbout“Up”! Enhancing Spatial Reasoning in Visual Language Models Through 3D ReconstructionARXIV24-07------img
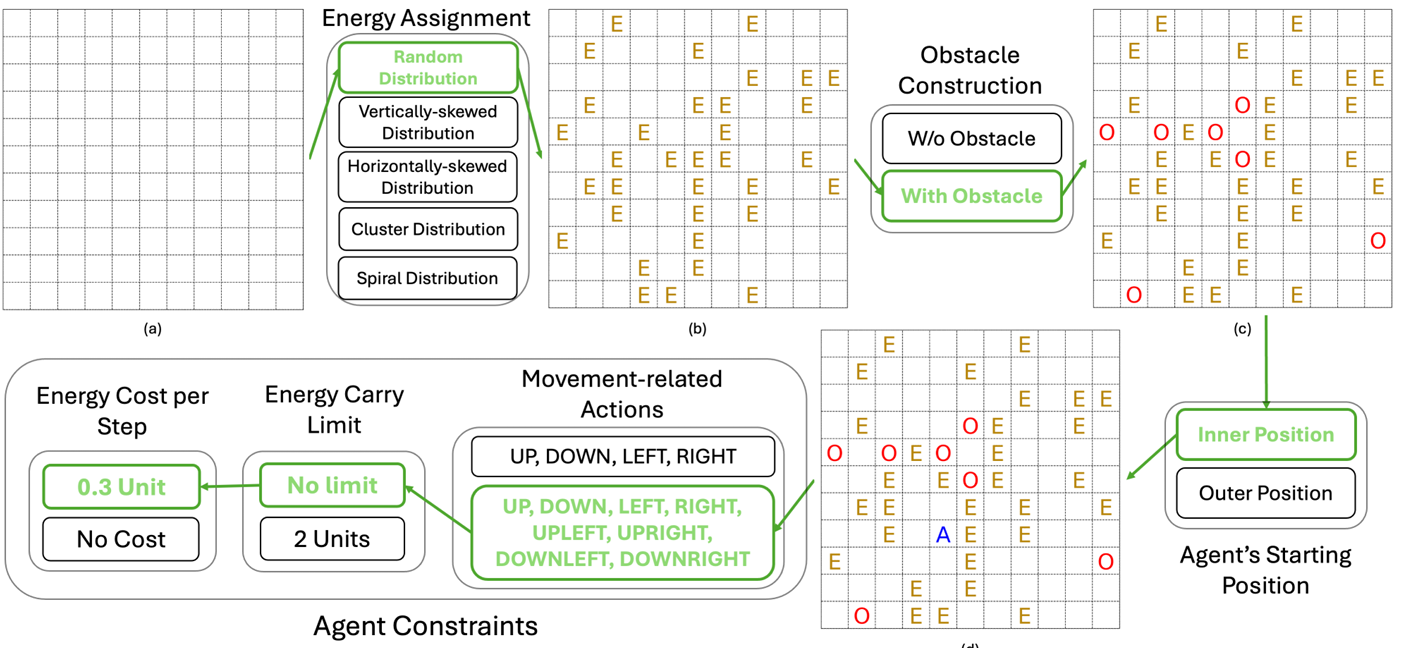
GRASP: A Grid-Based Benchmark for Evaluating Commonsense Spatial ReasoningARXIV24-07linkStar count--img
RoboPoint: AVision-Language Model for Spatial Affordance Prediction for RoboticsARXIV24-06linkStar countRobopointimg
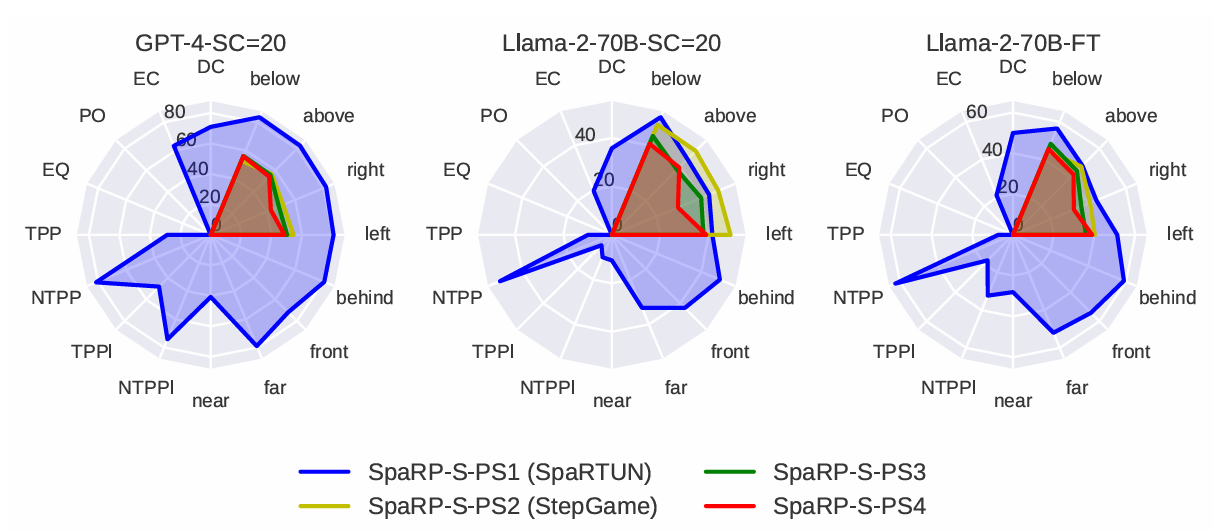
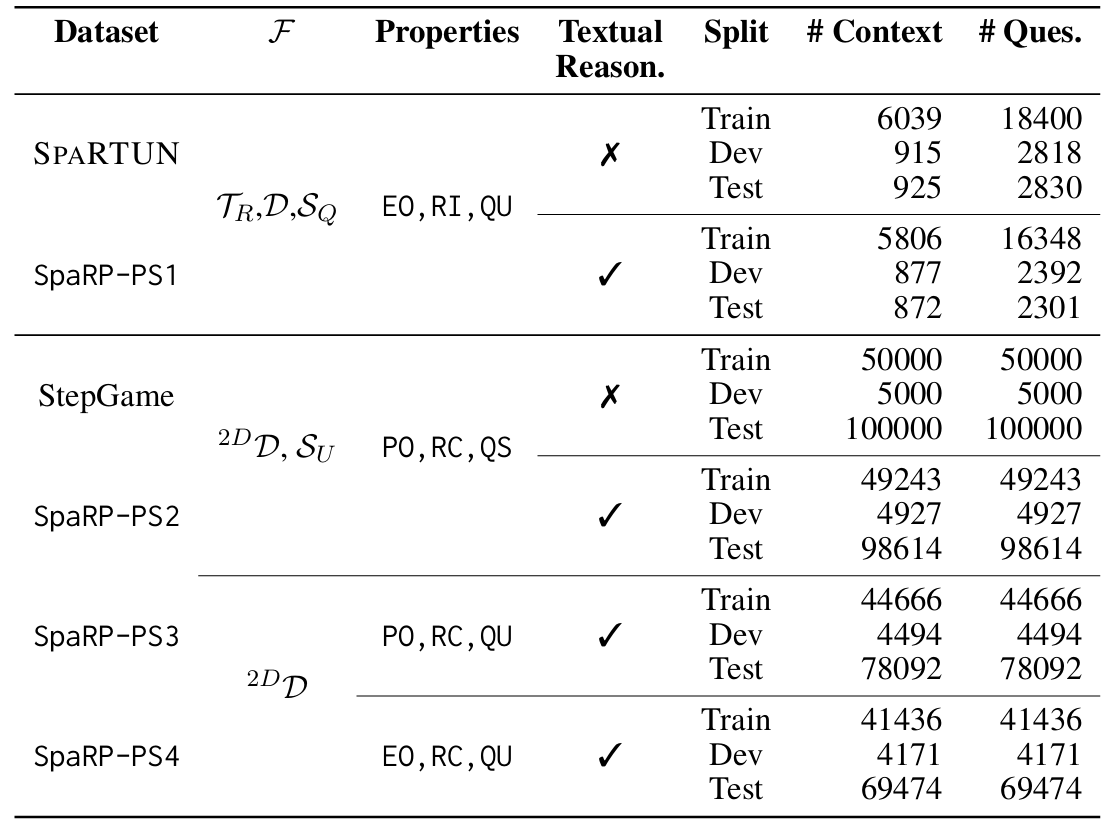
SpaRC and SpaRP: Spatial Reasoning Characterization and Path Generation for Understanding Spatial Reasoning Capability of Large Language ModelsACL24-06linkStar countSpaRPimg
KnowYour Neighbors: Improving Single-View Reconstruction via Spatial Vision-Language ReasoningCVPR24-04linkStar count--img
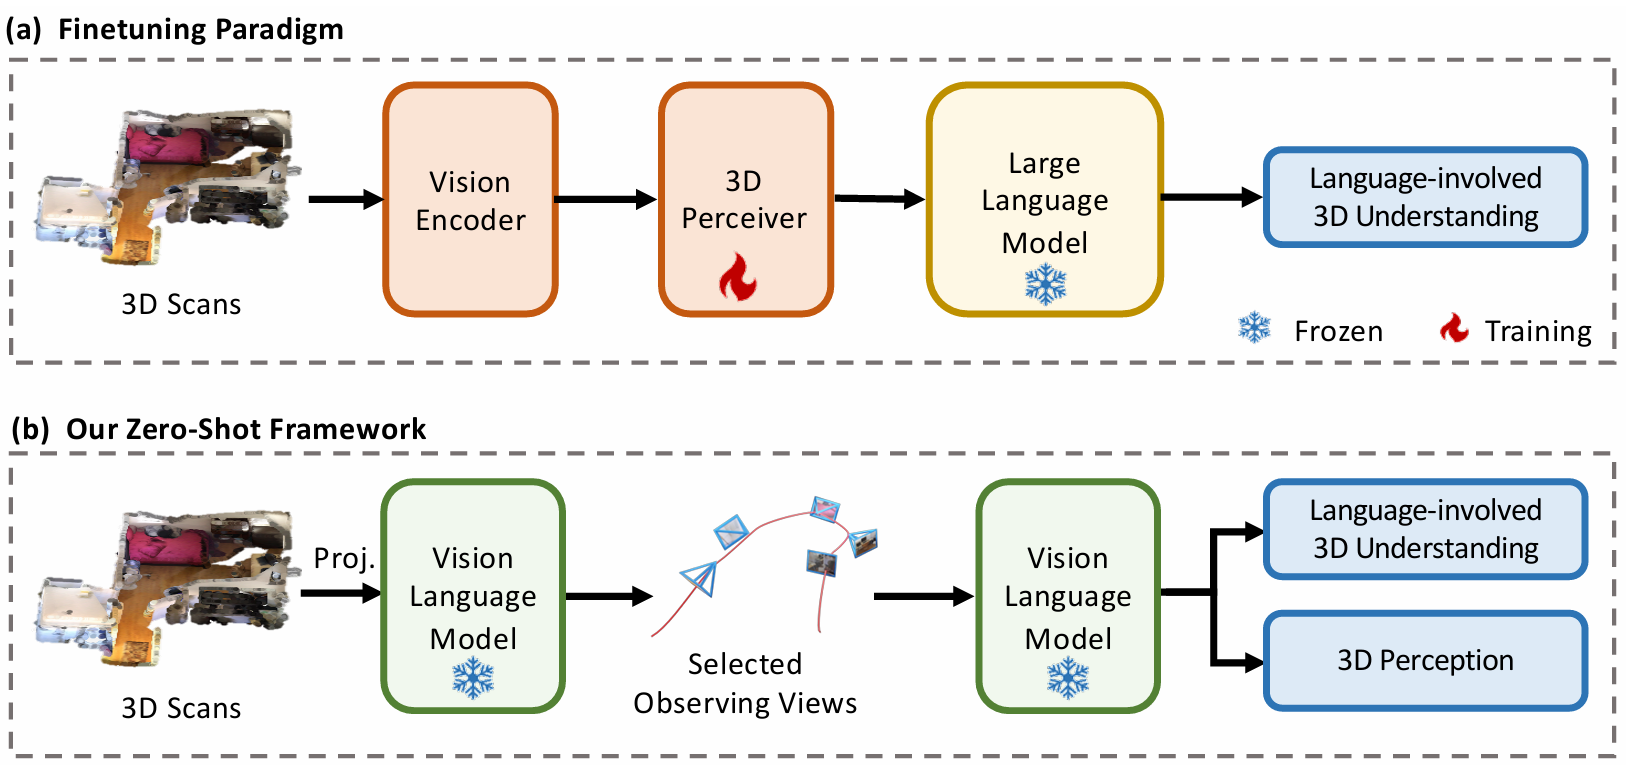
Agent3D-Zero: An Agent for Zero-shot 3D UnderstandingECCV24-03------img
Scene-LLM: Extending Language Model for 3D Visual Understanding and ReasoningWACV24-03----ScanQA, SQA3D
ALFRED
img
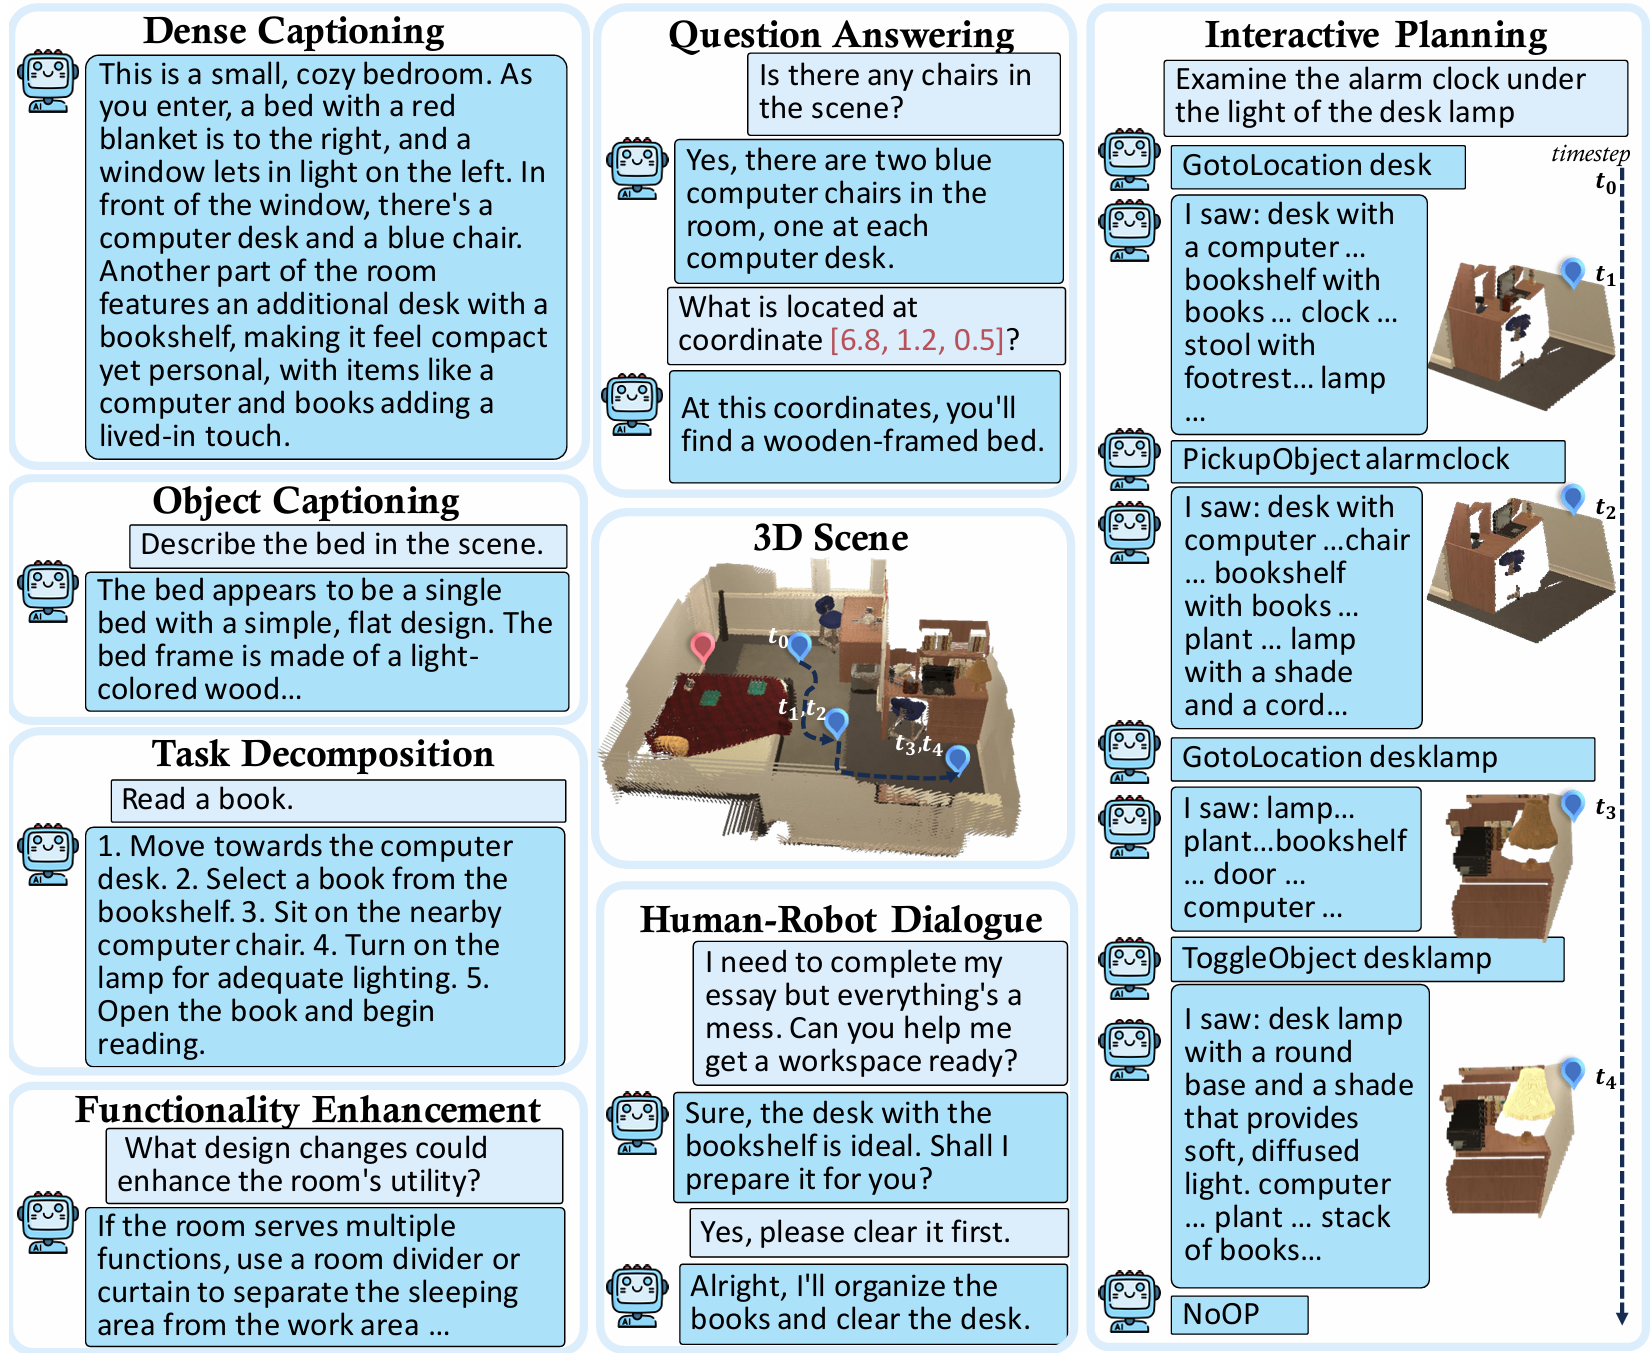
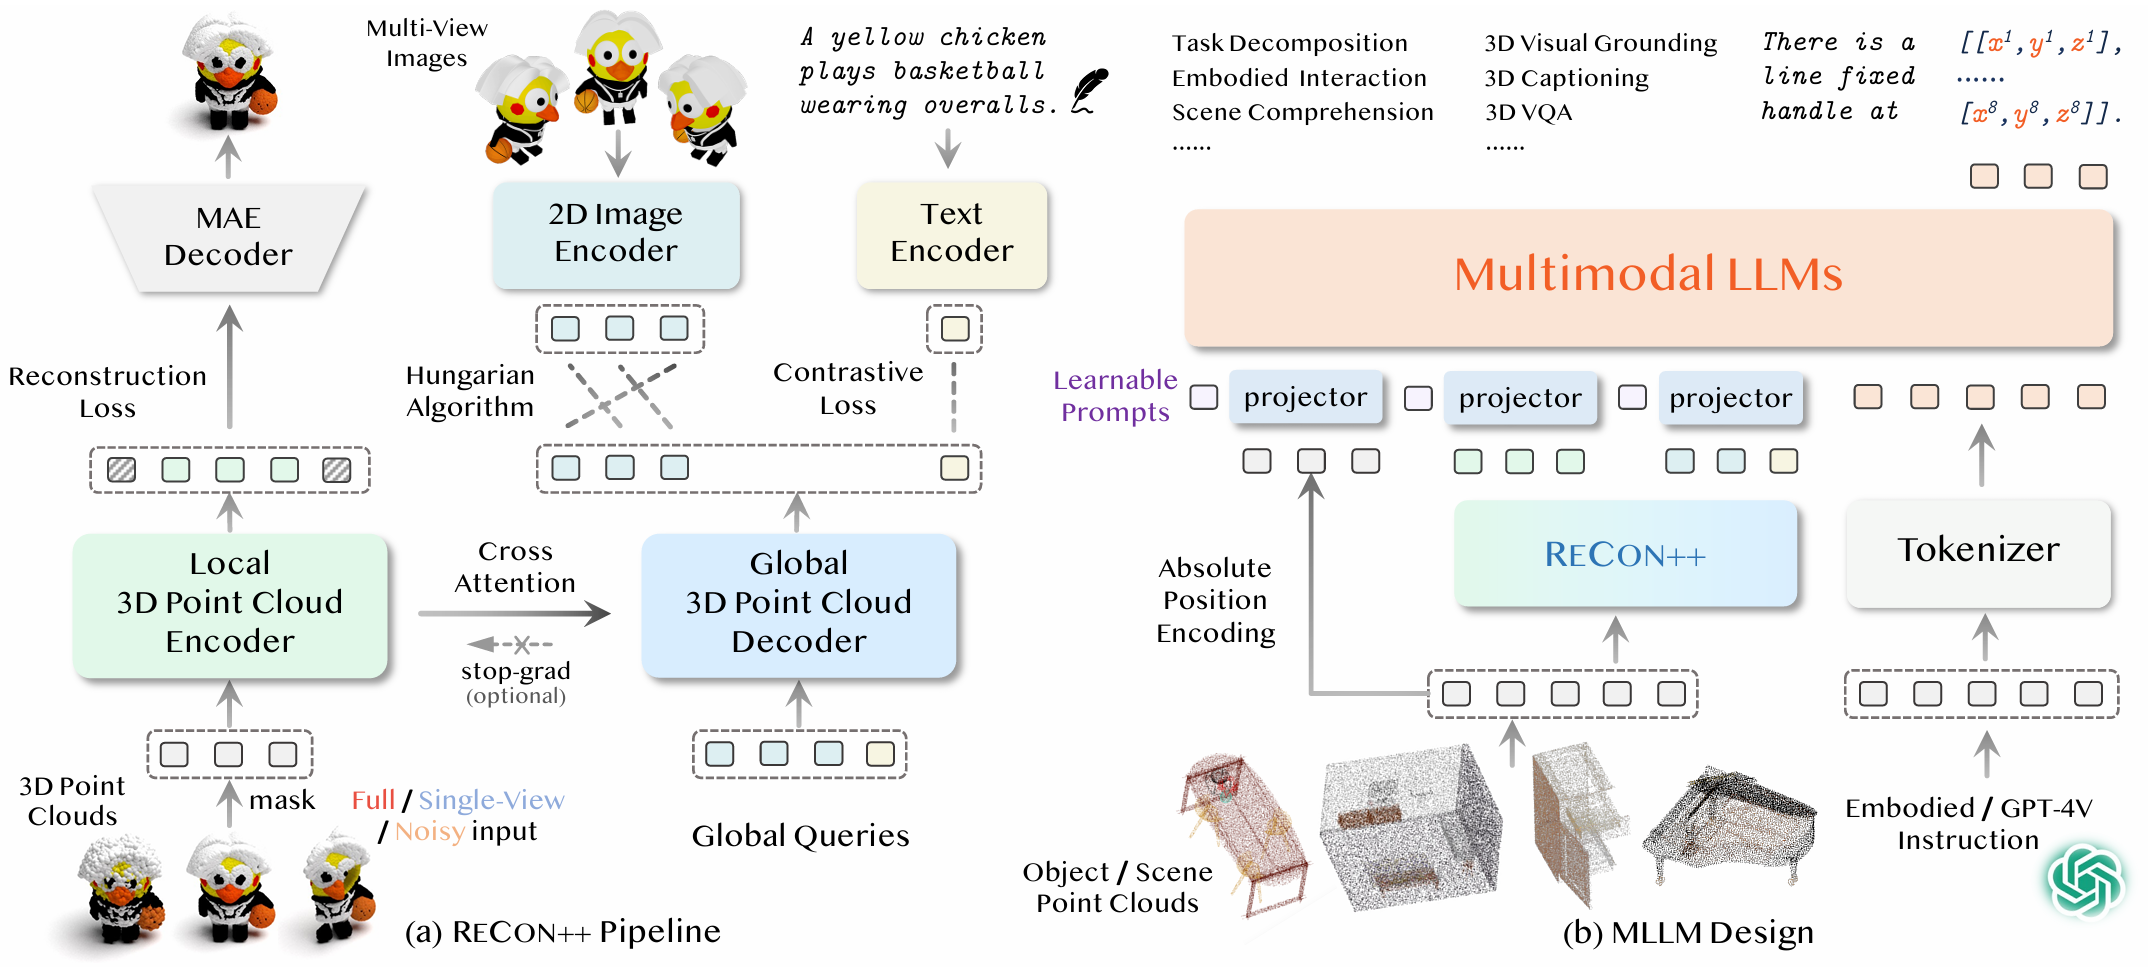
ShapeLLM: Universal 3D Object Understanding for Embodied InteractionECCV24-02linkStar count--img
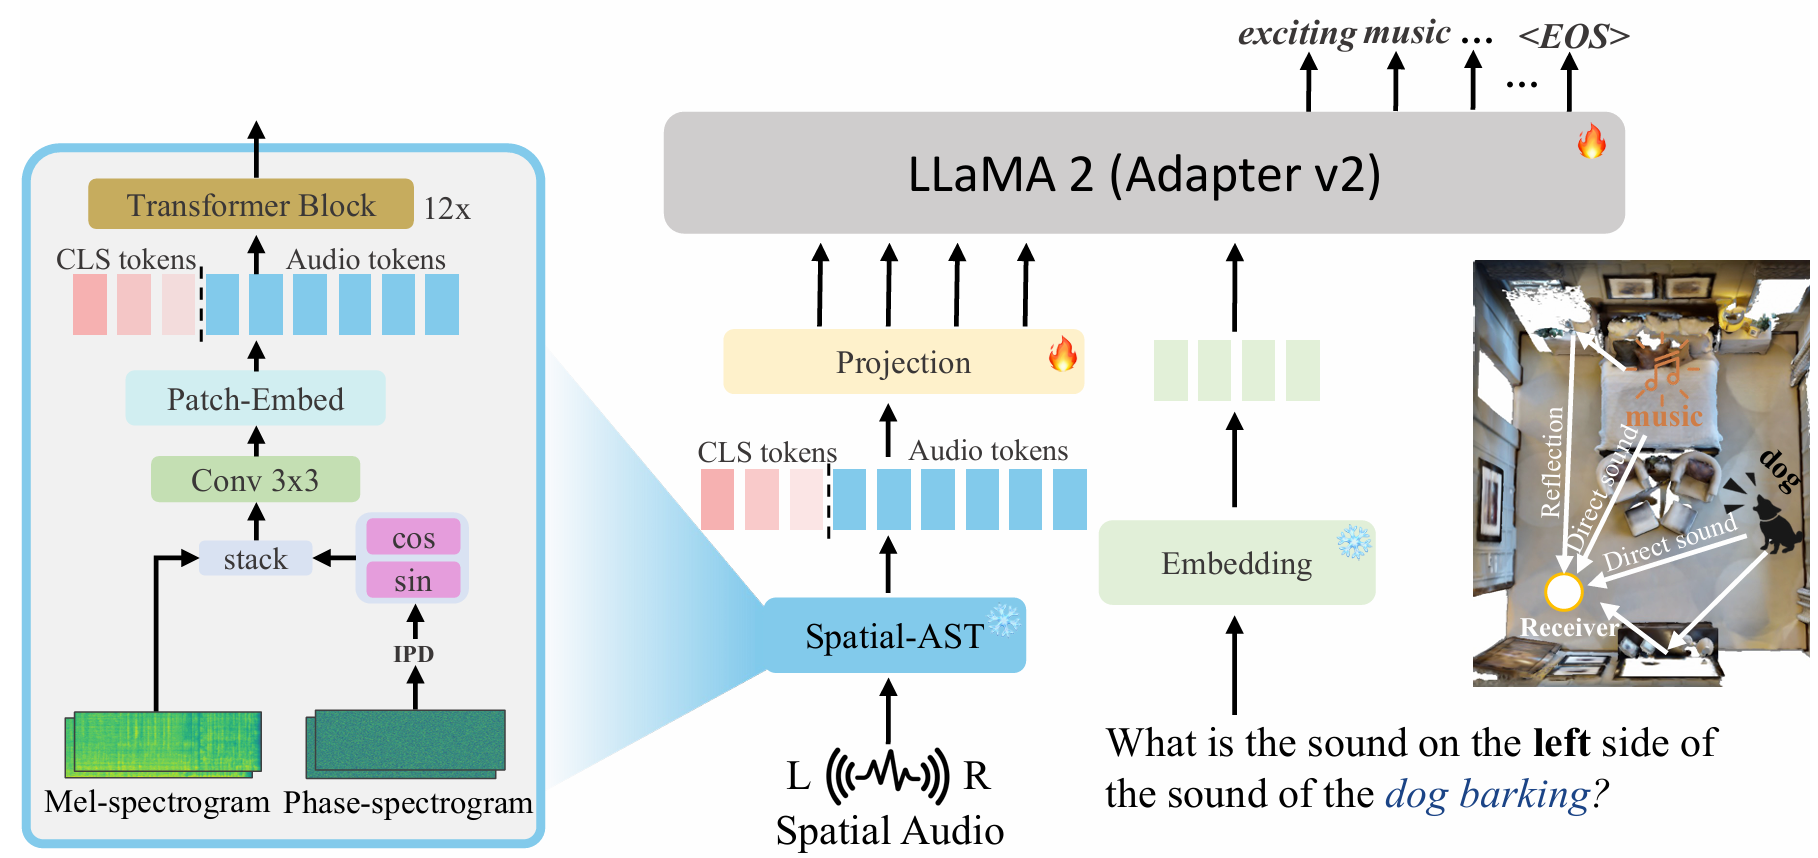
BAT: Learning to Reason about Spatial Sounds with Large Language ModelsARXIV24-02linkStar count--img
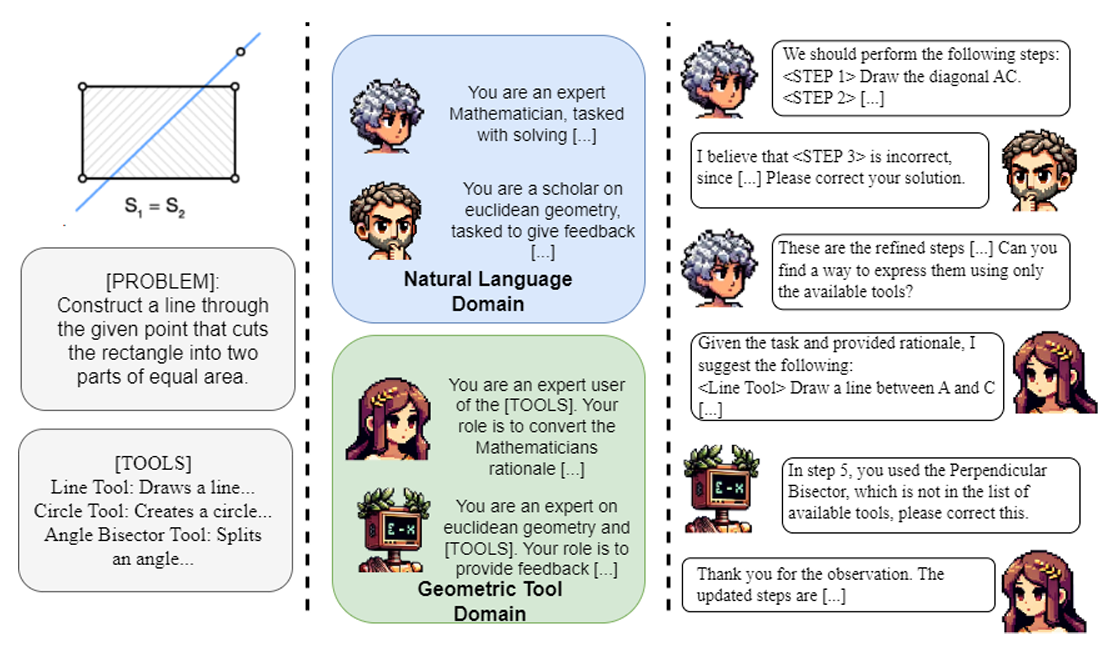
Beyond Lines and Circles: Unveiling the Geometric Reasoning Gap in Large Language ModelsARXIV24-02----Euclideaimg
LL3DA: Visual Interactive Instruction Tuning for Omni-3D Understanding, Reasoning, and PlanningCVPR24-01linkStar count--img
Advancing Spatial Reasoning in Large Language Models: An In-Depth Evaluation and Enhancement Using the StepGame BenchmarkAAAI24-01----StepGameimg
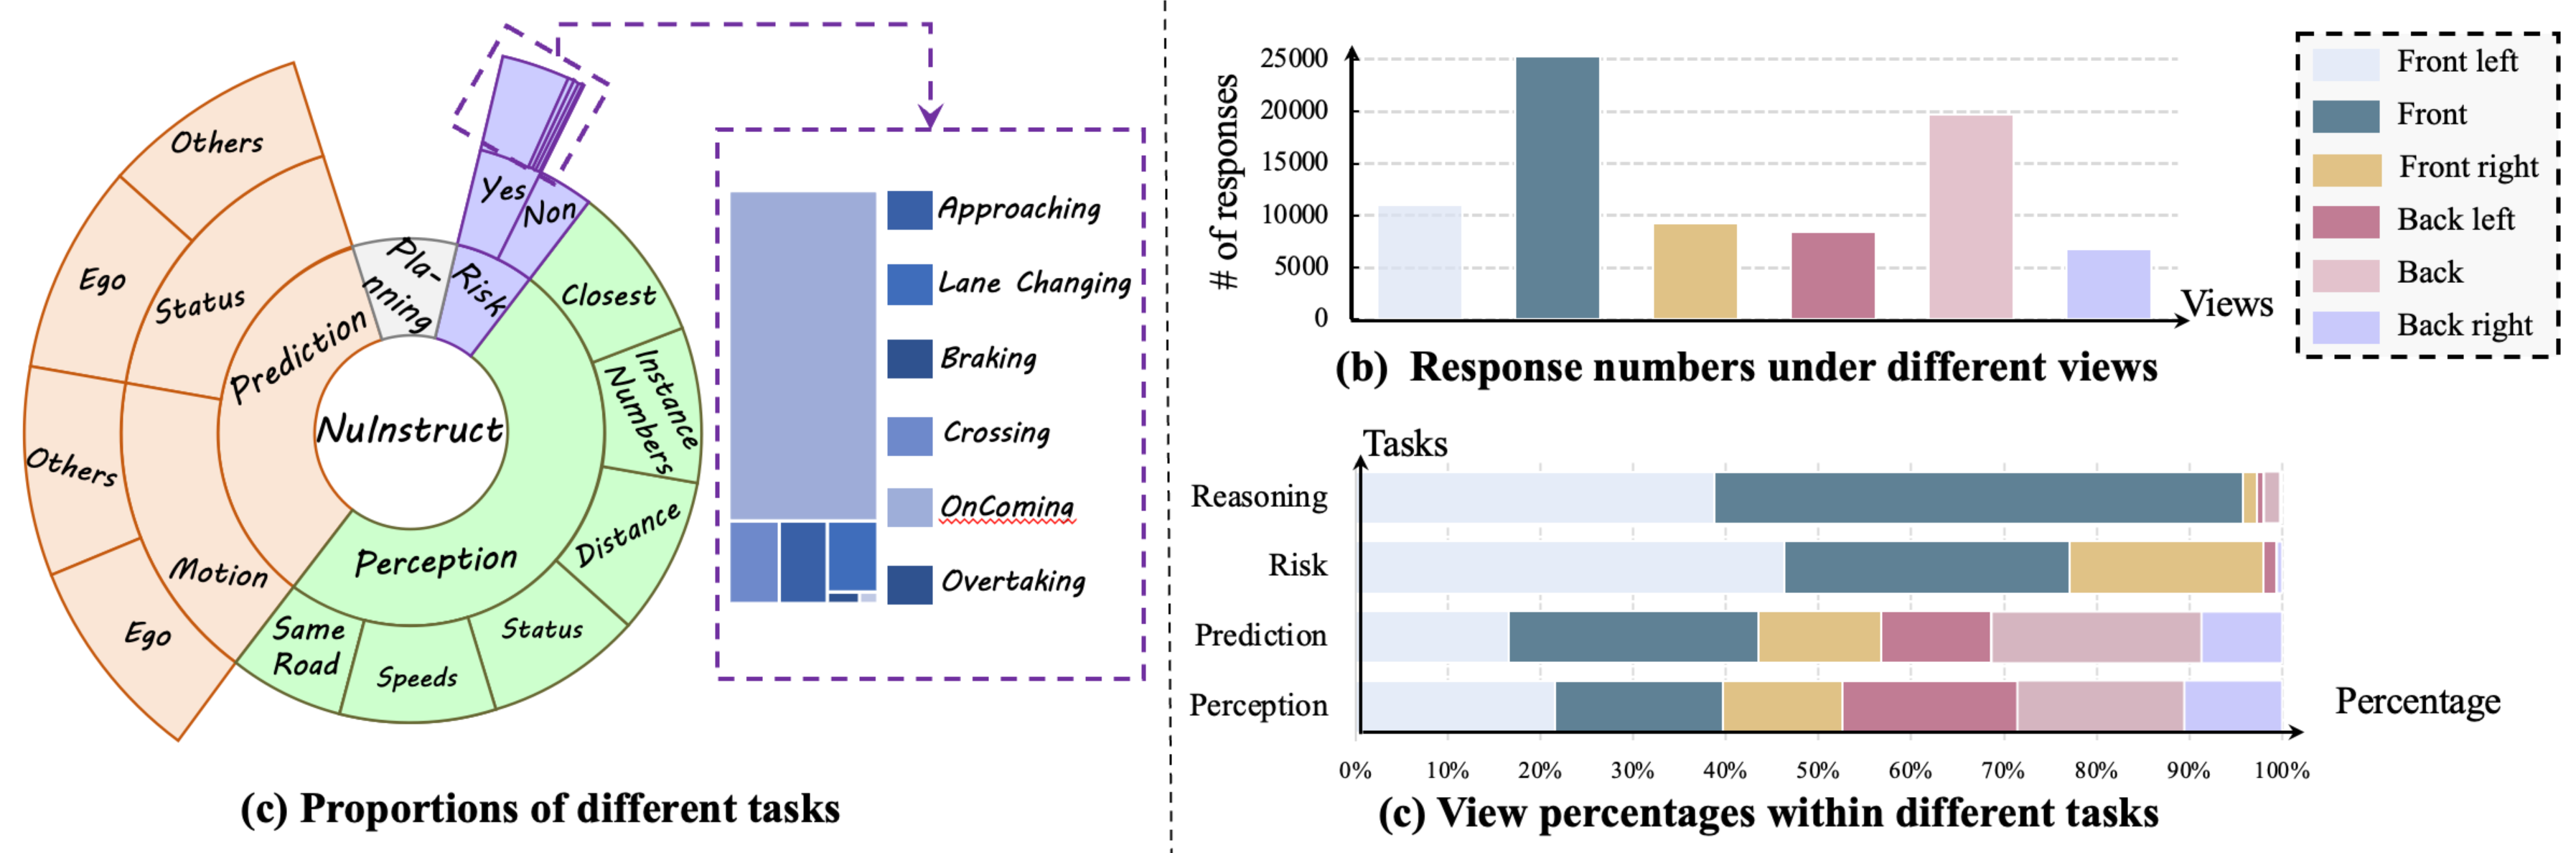
Holistic Autonomous Driving Understanding by Bird's-Eye-View Injected Multi-Modal Large ModelsCVPR24-01linkStar countNuInstructimg

Datasets

TitleVenueDateDownload-LinkCitationInput TypeIllustration
Can LLMs See Without Pixels? Benchmarking Spatial Intelligence from Textual DescriptionsARXIV26-01NA0Imageimg
Scaling Spatial Reasoning in MLLMs through Programmatic Data SynthesisARXIV25-12link0Video,Imageimg
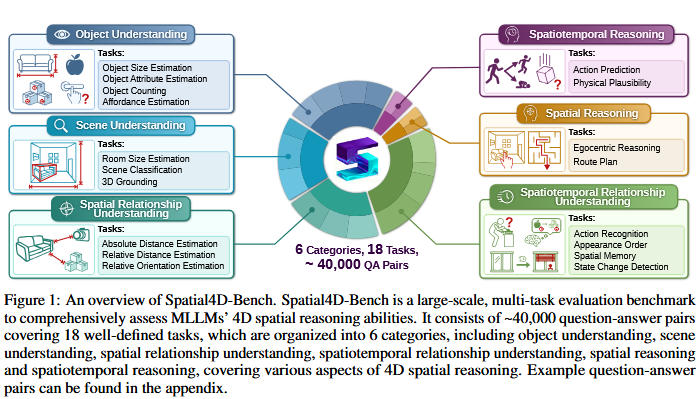
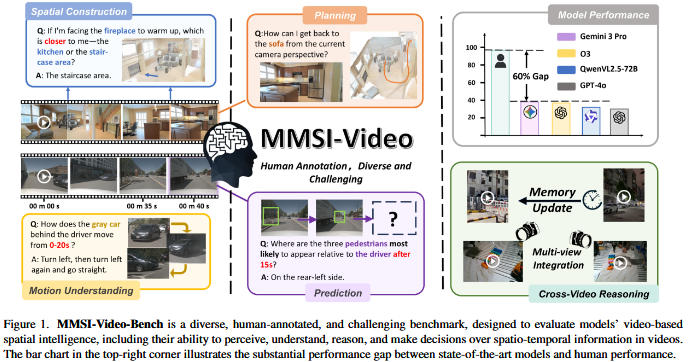
MMSI-Video-Bench: A Holistic Benchmark for Video-Based Spatial IntelligenceARXIV25-12link0Videoimg
Actial: Activate Spatial Reasoning Ability of Multimodal Large Language ModelsARXIV25-11NA1imageimg
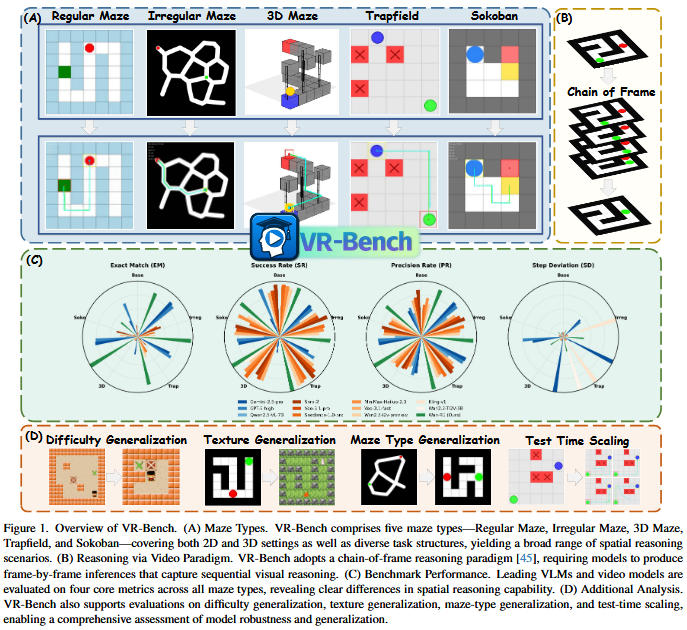
Reasoning via Video: The First Evaluation of Video Models’ Reasoning Abilities through Maze-Solving TasksARXIV25-11link0Videoimg
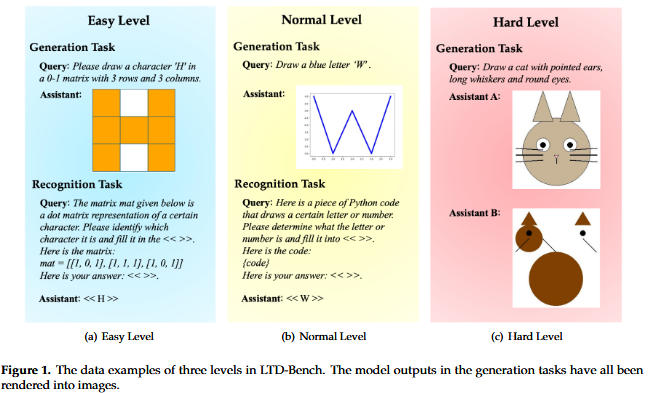
LTD-Bench: Evaluating Large Language Models by Letting Them DrawARXIV25-11link1Imageimg
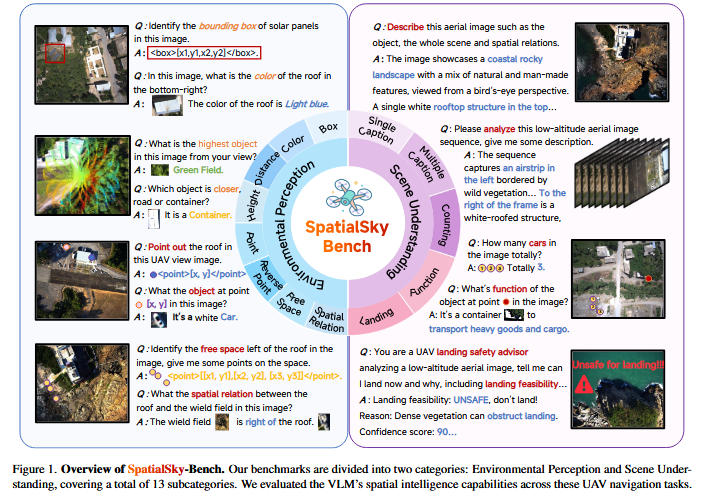
Is your VLM Sky-Ready? A Comprehensive Spatial Intelligence Benchmark for UAV NavigationARXIV25-11link0Imageimg
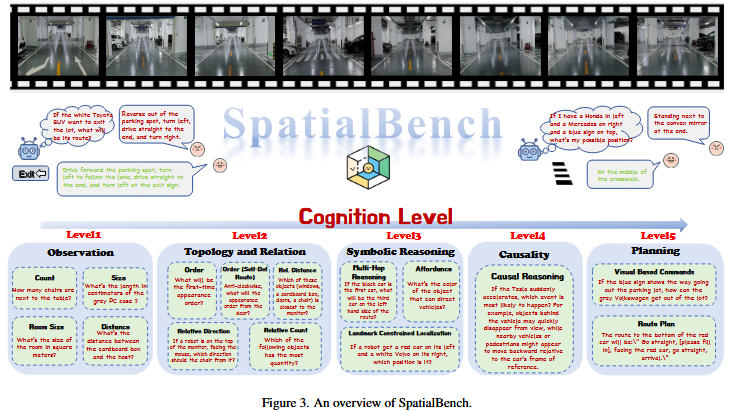
SpatialBench: Benchmarking Multimodal Large Language Models for Spatial CognitionARXIV25-11link1Videoimg
Do Vision-Language Models Represent Space and How. Evaluating Spatial Frame of Reference under AmbiguitiesICLR25-11link0Imageimg
OmniSpatial: Towards Comprehensive Spatial Reasoning Benchmark for Vision Language ModelsARXIV25-06link0Imageimg
SpatialScore Towards Unified Evaluation for Multimodal Spatial UnderstandingARXIV25-05link0Imageimg
Can Multimodal Large Language Models Understand Spatial RelationsARXIV25-05link--Imageimg
Are Multimodal Large Language Models Ready for Omnidirectional Spatial Reasoning?ARXIV25-05link0Imageimg
SITE: towards Spatial Intelligence Thorough EvaluationARXIV25-05link0Image/Multi-view Image/Videoimg
VLM-3R: Vision-Language Models Augmented with Instruction-Aligned 3D ReconstructionARXIV25-05link0Videoimg
MMSI-Bench: A Benchmark for Multi-ImagecSpatial IntelligenceARXIV25-05link1multi-viewimg
ViewSpatial-Bench:Evaluating Multi-perspective Spatial Localization in Vision-Language ModelsARXIV25-05link--multi-viewimg
Improved Visual-Spatial Reasoning via R1-Zero-Like TrainingARXIV25-04link9--img
Towards Understanding Camera Motions in Any VideoARXIV25-04link1Videoimg
Seeing from Another Perspective: Evaluating Multi-View Understanding in MLLMsARXIV25-04link3multi-viewimg
Mind the Gap: Benchmarking Spatial Reasoning in Vision-Language ModelsARXIV25-03link5Imageimg
Open3DVQA: ABenchmark for Comprehensive Spatial Reasoning with Multimodal Large Language Model in Open SpaceOPEN3DVQA25-03link4Imageimg
LEGO-Puzzles: How Good Are MLLMs at Multi-Step Spatial Reasoning?ARXIV25-03link8Multi-viewimg
STI-Bench: Are MLLMsReadyfor Precise Spatial-Temporal World Understanding?ARXIV25-03--7Videoimg
ST-Think: How Multimodal Large Language Models Reason About 4D Worlds from Ego-Centric VideosARXIV25-03link5Videoimg
From Flatland to Space: Teaching Vision-Language Models to Perceive and Reason in 3DARXIV25-03link2Imageimg
Space-Aware Instruction Tuning: Dataset and Benchmark for Guide Dog Robots Assisting the Visually ImpairedARXIV25-02link1Imageimg
VADAR: Visual Agentic AI for Spatial Reasoning with a Dynamic APICVPR25-02link5imageimg
PHYSBENCH: BENCHMARKING AND ENHANCING VISION-LANGUAGE MODELS FOR PHYSICAL WORLD UNDERSTANDINGARXIV25-01link22Image/Videoimg
Social-LLaVA: Enhancing Robot Navigation through Human-Language Reasoning in Social SpacesARXIV25-01link2Imageimg
SpatialVLA: Exploring Spatial Representations for Visual-Language-Action ModelARXIV25-01link--Videoimg
Emma-X: An Embodied Multimodal Action Model with Grounded Chain of Thought and Look-ahead Spatial ReasoningARXIV24-12link--Videoimg
LLaVA-SpaceSGG: Visual Instruct Tuning for Open-vocabulary Scene Graph Generation with Enhanced Spatial RelationsARXIV24-12link2imageimg
3DSRBench: A Comprehensive 3D Spatial Reasoning BenchmarkARXIV24-12link12Imageimg
SPHERE: Unveiling Spatial Blind Spots in Vision-Language Models Through Hierarchical EvaluationACL24-12link3Imageimg
Thinking in Space: How Multimodal Large Language Models See, Remember, and Recall SpacesARXIV24-12link86Videoimg
ROOT: VLM-based System for Indoor Scene Understanding and BeyondARXIV24-11--2imageimg
An Empirical Analysis on Spatial Reasoning Capabilities of Large Multimodal ModelsEMNLP 202424-11link9Imageimg
GEOBench-VLM: Benchmarking Vision-Language Models for Geospatial TasksARXIV24-11link7Imageimg
OpenEQA: Embodied Question Answering in the Era of Foundation ModelsCVPR24-11link149Videoimg
DOES SPATIAL COGNITION EMERGE IN FRONTIER MODELS?ICLR24-10link19Videoimg
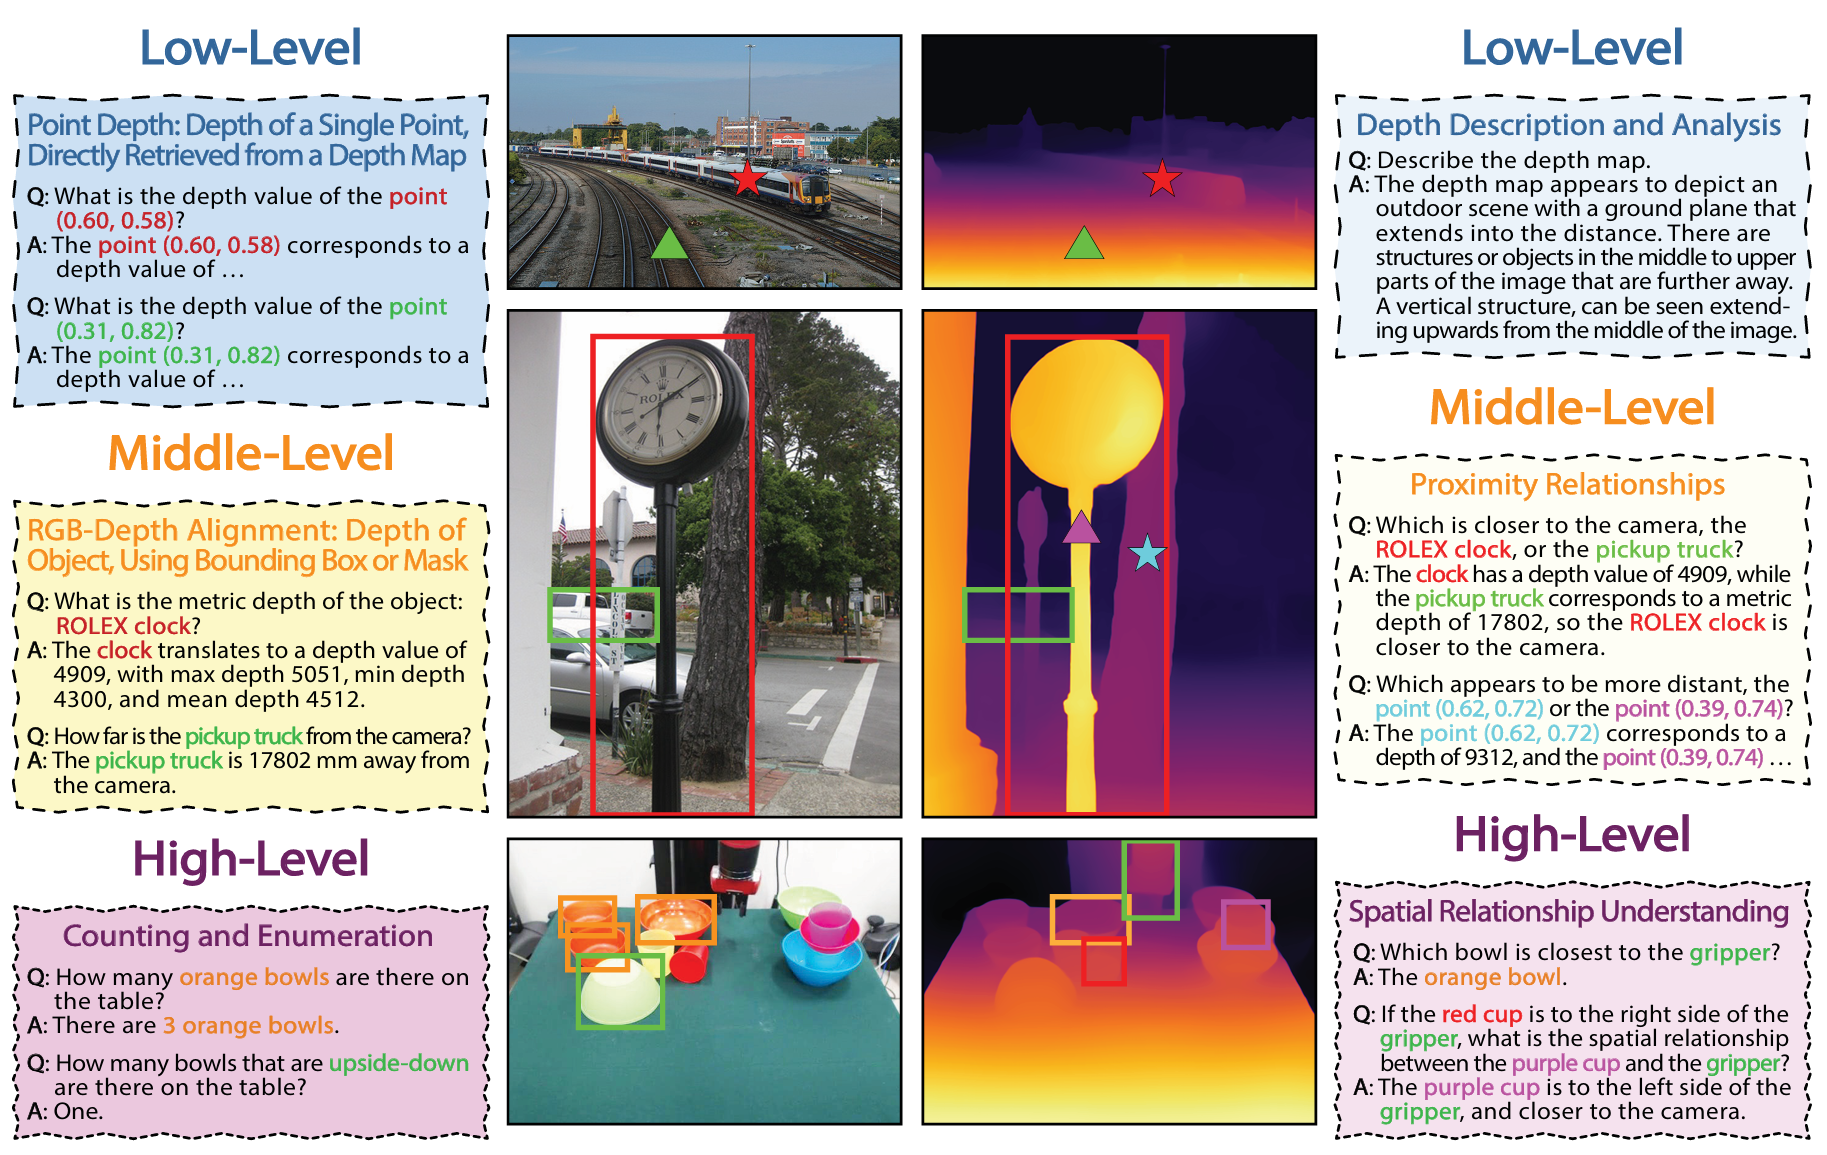
Reasoning Paths with Reference Objects Elicit Quantitative Spatial Reasoning in Large Vision-Language ModelsARXIV24-09link15Imageimg
Understanding Depth and Height Perception of Large Visual-Language ModelsCVPRW24-08link02D/3D imageimg
VSP: Assessing the dual challenges of perception and reasoning in spatial planning tasks for VLMsARXIV24-07link4Imageimg
SpaRC and SpaRP: Spatial Reasoning Characterization and Path Generation for Understanding Spatial Reasoning Capability of Large Language ModelsACL24-06link4textimg
SpatialBot: Precise Spatial Understanding with Vision Language ModelsICRA24-06link43Imageimg
SpatialRGPT: Grounded Spatial Reasoning in Vision-Language ModelsARXIV24-06link104Image, point cloudimg
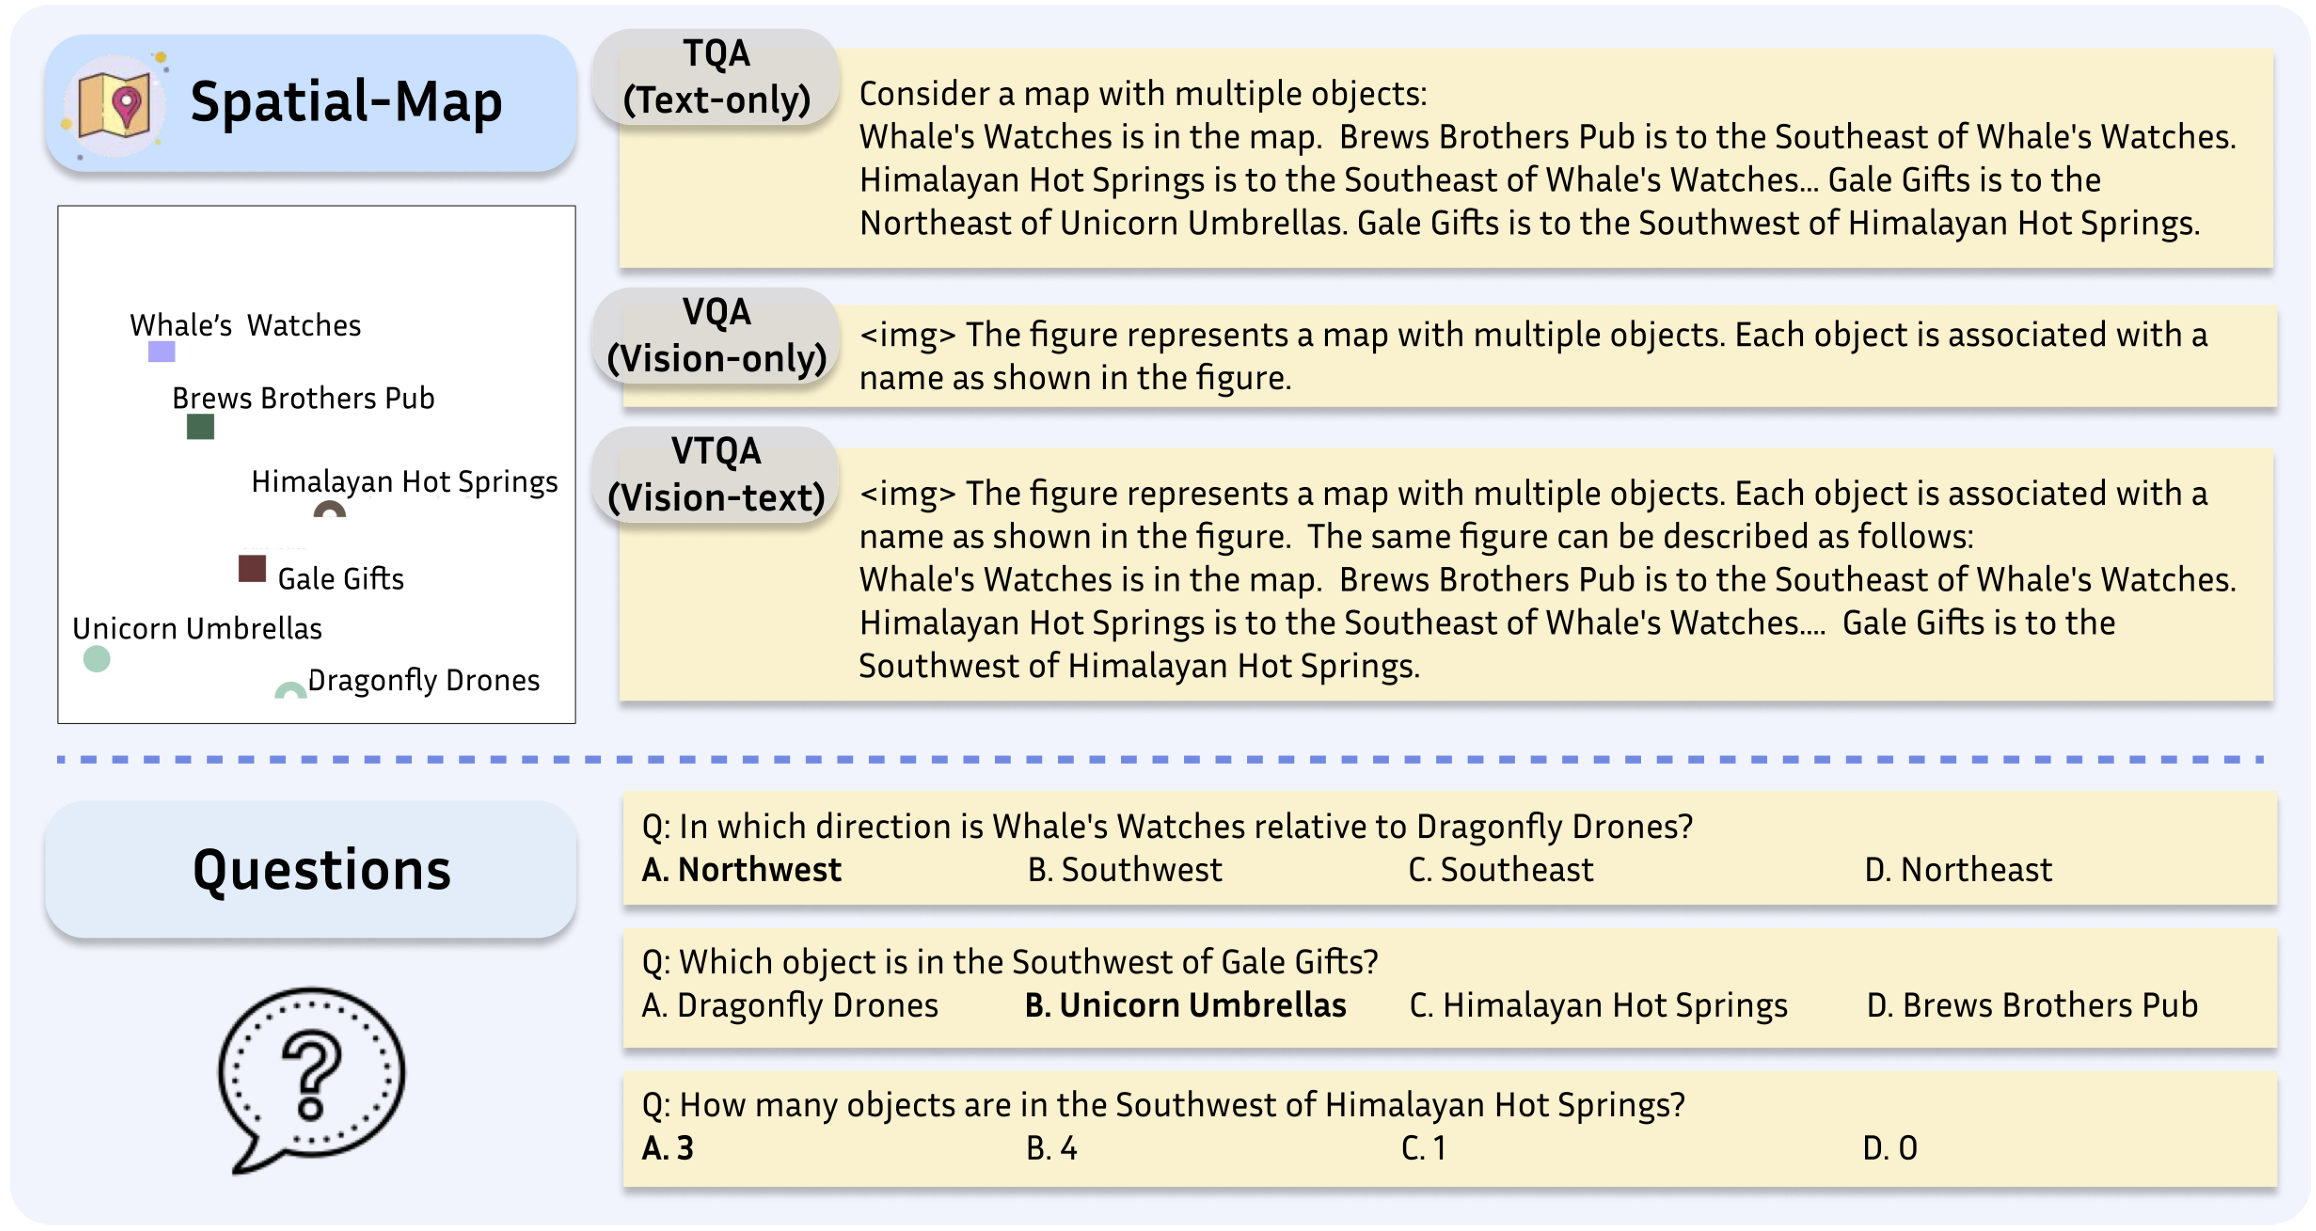
Is A Picture Worth A Thousand Words? Delving Into Spatial Reasoning for Vision Language ModelsNEURIPS24-06link61text only/image only/image-textimg
EmbSpatial-Bench: Benchmarking Spatial Understanding for Embodied Tasks with Large Vision-Language ModelsACL 2024 SHORT24-06link22Imageimg
COMPOSITIONAL 4D DYNAMIC SCENES UNDERSTANDING WITH PHYSICS PRIORS FOR VIDEO QUESTION ANSWERINGICLR202524-06link5Videoimg
Reframing Spatial Reasoning Evaluation in Language Models: A Real-World Simulation Benchmark for Qualitative ReasoningIJCAI 202424-05link9Multi-viewimg
Mind's Eye of LLMs: Visualization-of-Thought Elicits Spatial Reasoning in Large Language ModelsNEURIPS24-04link33imageimg
BLINK: Multimodal Large Language Models Can See but Not PerceiveECCV24-04link180Image/Multi-view Imageimg
Visual CoT: Advancing Multi-Modal Language Models with a Comprehensive Dataset and Benchmark for Chain-of-Thought ReasoningNEURIPS24-03link74imageimg
Can Transformers Capture Spatial Relations between Objects?ICLR24-03link6Imageimg
Holistic Autonomous Driving Understanding by Bird's-Eye-View Injected Multi-Modal Large ModelsCVPR24-01link--Videoimg
Proximity QA: Unleashing the Power of Multi-Modal Large Language Models for Spatial Proximity AnalysisARXIV24-01link2Imageimg
3D-Aware Visual Question Answering about Parts, Poses and OcclusionsNIPS23-10link14Imageimg
Sqa3d: Situated question answering in 3d scenesICLR22-10link161point cloudimg
ScanQA: 3D Question Answering for Spatial Scene UnderstandingCVPR21-12link234point cloudimg
SPARE3D: A Dataset for SPAtial REasoning on Three-View Line DrawingsCVPR202020-03link23multi-viewimg

Acknowledgements

🌍 Visitor Statistics

embodied-ai
vision-language-models
visual-spatial-reasoning

Contributors

HaoDot

98 commits

song2yu

46 commits

SIBench

4 commits

jialianjie

2 commits

SIBench/Awesome-Visual-Spatial-Reasoning

This is a project about visual spatial reasoning.

HTML

148

159 commits

updated Jul 27, 2026

See the code

README

Awesome Visual Spatial Reasoning

Songsong Yu*1,2, Yuxin Chen🌟*2, Hao Ju*3, Lianjie Jia*4, Fuxi Zhang4, Shaofei Huang3,
Yuhan Wu4, Rundi Cui4, Binghao Ran4, Zhang Zaibin4, Zhedong Zheng3, Zhipeng Zhang1,
Yifan Wang4, Lin Song2, Lijun Wang4, Yanwei Li✉️5, Ying Shan2, Huchuan Lu4,

1SJTU, 2ARC Lab, Tencent PCG, 3UM, 4DLUT, 5CUHK * Equal Contributions 🌟 Project Lead ✉️ Corresponding Author

🤗 Dataset    |   🌐 Leaderboard   |   📊 Survey    |   🎯 Code    |   📄 arXiv   |   🗺️ 📖 Interactive Survey Page (中/EN)


News and Updates

  • 🆕🔥✨26.5.6 - Added 4 new papers (2026.03~2026.04) including SpatiO, World2VLM, ReVSI, and Holi-Spatial.
  • 🆕🔥✨26.3.29 - Added 7 new papers (2026.03.22~2026.03.29) and launched 📖 Interactive Bilingual Survey Page covering 110+ papers with ZH/EN toggle, timeline, trend analysis, and benchmark summary.
  • 🆕🔥✨26.3.23 - Added 9 new papers (2025.10 ~ 2026.03) covering benchmarks, training methods, and spatial reasoning frameworks.
  • 📜📜📜25.9.23 - Preprint a survey article on visual spatial reasoning tasks.
  • 🎯🎯🎯25.9.23 - Release comprehensive evaluation results of mainstream models in visual spatial reasoning.
  • 🙌👏👐25.9.15 - Open-source evaluation data for visual spatial reasoning tasks.
  • 🤩🥳🤗25.9.15 - Open-source evaluation toolkit.
  • ✍️🦾💼25.6.28 - Collected the "Datasets" section.
  • 🏃🏃‍♀️🏃‍♂️25.6.16 - The "Awesome Visual Spatial Reasoning" project is now live!
  • 👏🕮💻25.6.12 - The project has conducted research and collected 100 relevant works.
  • 🙋‍♀️🙋‍♂️🙋25.6.10 - We launches a review project on visual spatial reasoning.

Open-source evaluation toolkit
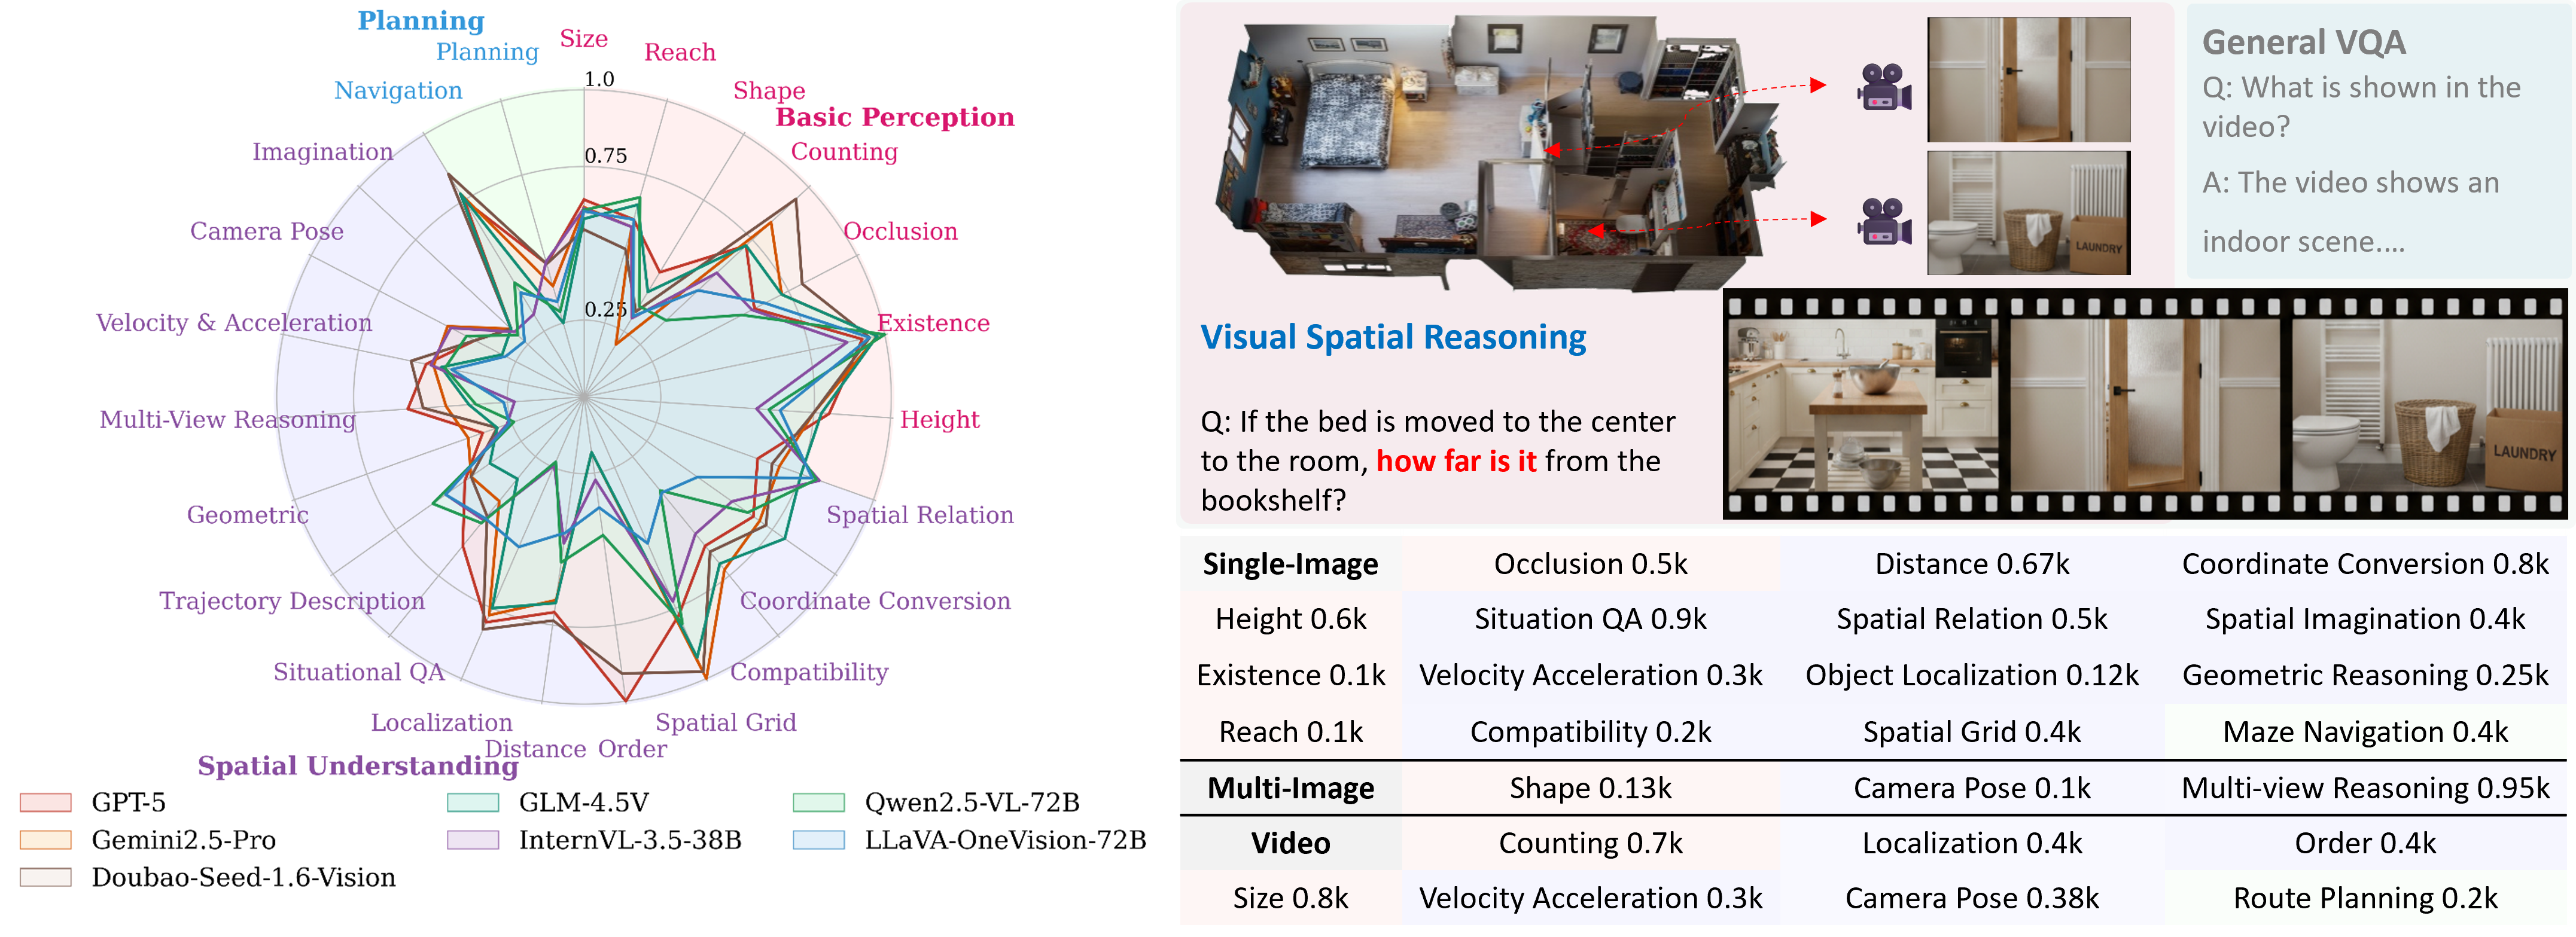
radar2.6

Evaluation of SOTA Models on 23 Visual Spatial Reasoning Tasks.

Code Usage:

- git clone https://github.com/song2yu/SIBench-VSR.git
- Refer to the README.md for more details

Contributing

We welcome contributions to this repository! If you would like to contribute, please follow these steps:

  • Fork the repository.
  • Create a new branch with your changes.
  • Submit a pull request with a clear description of your changes.

You can also open an issue if you have anything to add or comment.

Please feel free to contact us (SongsongYu203@163.com).

Overview

The research community is increasingly focused on the visual spatial reasoning (VSR) abilities of Vision-Language Models (VLMs). Yet, the field lacks a clear overview of its evolution and a standardized benchmark for evaluation. Current assessment methods are disparate and lack a common toolkit. This project aims to fill that void. We are developing a unified, comprehensive, and diverse evaluation toolkit, along with an accompanying survey paper. We are actively seeking collaboration and discussion with fellow experts to advance this initiative.

Task Explanation

Visual spatial understanding is a key task at the intersection of computer vision and cognitive science. It aims to enable intelligent agents (such as robots and AI systems) to parse spatial relationships in the environment through visual inputs (images, videos, etc.), forming an abstract cognition of the physical world. In Embodied Intelligence, it serves as the foundation for agents to achieve the "perception-decision-action" loop—only by understanding attributes like object positions, distances, sizes, and orientations in space can intelligent agents navigate environments, manipulate objects, or interact with humans.

Timeline
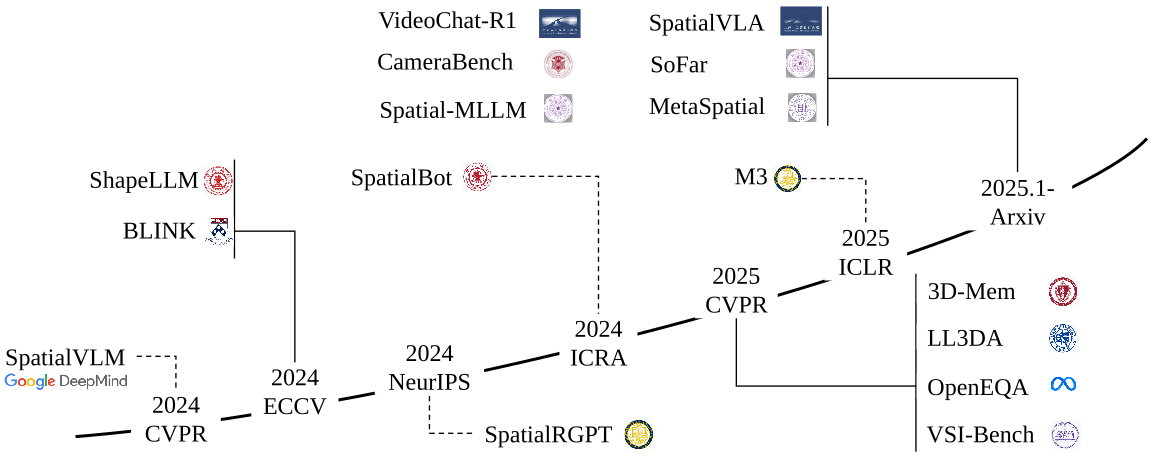
Visual Spatial Intelligence-A Survey

Citation

If you find this project useful, please consider citing:

@article{sibench2025,
  title={How Far are VLMs from True Visual Spatial Intelligence? A Benchmark-Driven Perspective},
  author={Songsong Yu, Yuxin Chen, Hao Ju, Lianjie Jia, Fuxi Zhang, Shaofei Huang, Yuhan Wu, Rundi Cui, Binghao Ran, Zaibin Zhang, Zhedong Zheng, Zhipeng Zhang, Yifan Wang, Lin Song, Lijun Wang, Yanwei Li, Ying Shan, Huchuan Lu},
  journal={arXiv preprint arXiv:2509.18905},
  year={2025}
}

Table of Contents

To facilitate the community's quick understanding of visual-spatial reasoning, we first categorized it by input modalities into Single image, Monocular Video, and Multi-View Images. We also surveyed other input modalities such as point clouds, as well as specific applications like embodied robotics. These are temporarily grouped under "Others," and we will conduct a more detailed sorting in the future.

Papers

Single Image

<tr>
<td><a href="https://arxiv.org/pdf/2512.07733">SpatialDreamer: Incentivizing Spatial Reasoning via Active Mental Imagery</a></td>
<td>ARXIV</td>
<td>25-12</td>
<td><a href="https://github.com/mengcaopku/SpatialDreamer">link</a></td>
<td><img src="https://img.shields.io/github/stars/mengcaopku/SpatialDreamer.svg?style=social&label=Star" alt="Star count"/></td>
<td>--</td>
<td><img src="excel_images/2026-01-09_210340_756.jpg" alt="img" /></td>
TitleVenueDateCodeStarsBenchmarkIllustration
Show, Don't Tell: Evaluating Spatial Cognition in Generative Pixels Rather Than LLM TextARXIV26-07linkStar countSpatialGen-Benchimg
SpatiO: Adaptive Test-Time Orchestration of Vision-Language Agents for Spatial ReasoningARXIV26-04----3DSRBench, CV-Bench, Omni3D-Bench--
HiSpatial: Taming Hierarchical 3D Spatial Understanding in Vision-Language ModelsCVPR 202626-03----SQA3D, ScanQA--
LanteRn: Latent Visual Structured ReasoningARXIV26-03--------
Unleashing Spatial Reasoning in Multimodal Large Language Models via Textual Representation Guided ReasoningARXIV26-03----VSI-Bench, ScanQA--
3D-Layout-R1: Structured Reasoning for Language-Instructed Spatial EditingARXIV26-03--------
Attention in Space: Functional Roles of VLM Heads for Spatial ReasoningARXIV26-03----SpatialBench--
MultihopSpatial: Multi-hop Compositional Spatial Reasoning Benchmark for Vision-Language ModelECCV 202626-03linkStar countMultihopSpatialimg
Thinking with Geometry: Active Geometry Integration for Spatial ReasoningARXIV26-02----VSI-Bench, CVBench--
SpatialBoost: Enhancing Visual Representation through Language-Guided ReasoningARXIV26-03----ScanQA, CVBench--
SSR: Pushing the Limit of Spatial Intelligence with Structured Scene ReasoningARXIV26-03----VSI-Bench--
Perception-Aware Multimodal Spatial Reasoning from Monocular ImagesARXIV26-03----SURDS--
SpatiaLQA: A Benchmark for Evaluating Spatial Logical Reasoning in Vision-Language ModelsCVPR26-02linkStar countSpatiaLQA--
SpatiaLab: Can Vision-Language Models Perform Spatial Reasoning in the Wild?ICLR26-02----SpatiaLab--
CityCube: Benchmarking Cross-view Spatial Reasoning on Vision-Language Models in Urban EnvironmentsARXIV26-01----CityCube--
Thinking with Blueprints: Assisting Vision-Language Models in Spatial Reasoning via Structured Object RepresentationARXIV26-01--------
SpaceTools: Tool-Augmented Spatial Reasoning via Double Interactive RLARXIV25-12linkStar count--img
SpatialGeo: Boosting Spatial Reasoning in Multimodal LLMs via Geometry-Semantics FusionARXIV25-11linkStar count--img
R2D3:ImpartingSpatial Reasoning by Reconstructing 3D Scenes from 2D ImagesARXIV------R2D3img
RoboRefer: Towards Spatial Referring with Reasoning in Vision-Language Models for RobticsARXIV25-06link--RefSpatial-Benchimg
Visual Embodied Brain: Let Multimodal Large Language Models See, Think, and Control in SpacesARXIV25-06linkStar countVeBrain-600kimg
SVQA-R1: Reinforcing Spatial Reasoning in MLLMs via View-Consistent Reward OptimizationARXIV25-06----SVQA-R1img
OmniSpatial: Towards Comprehensive Spatial Reasoning Benchmark for Vision Language Models--25-06linkStar countOmniSpatialimg
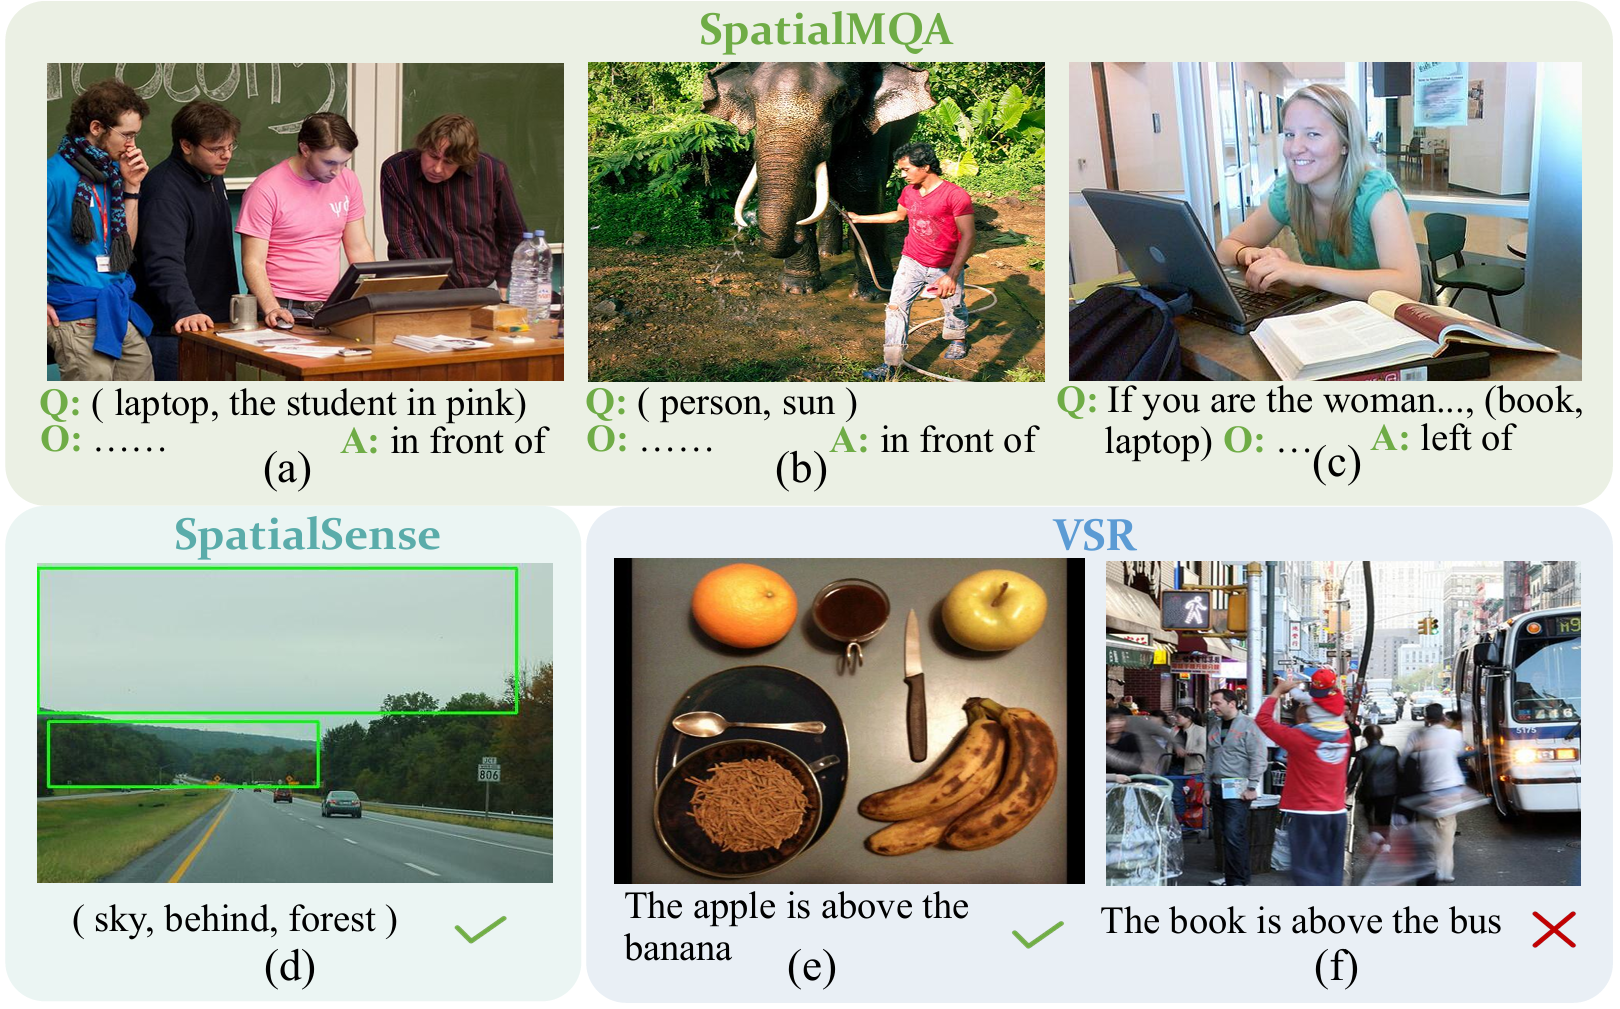
Can Multimodal Large Language Models Understand Spatial RelationsARXIV25-05linkStar countSpatialMQAimg
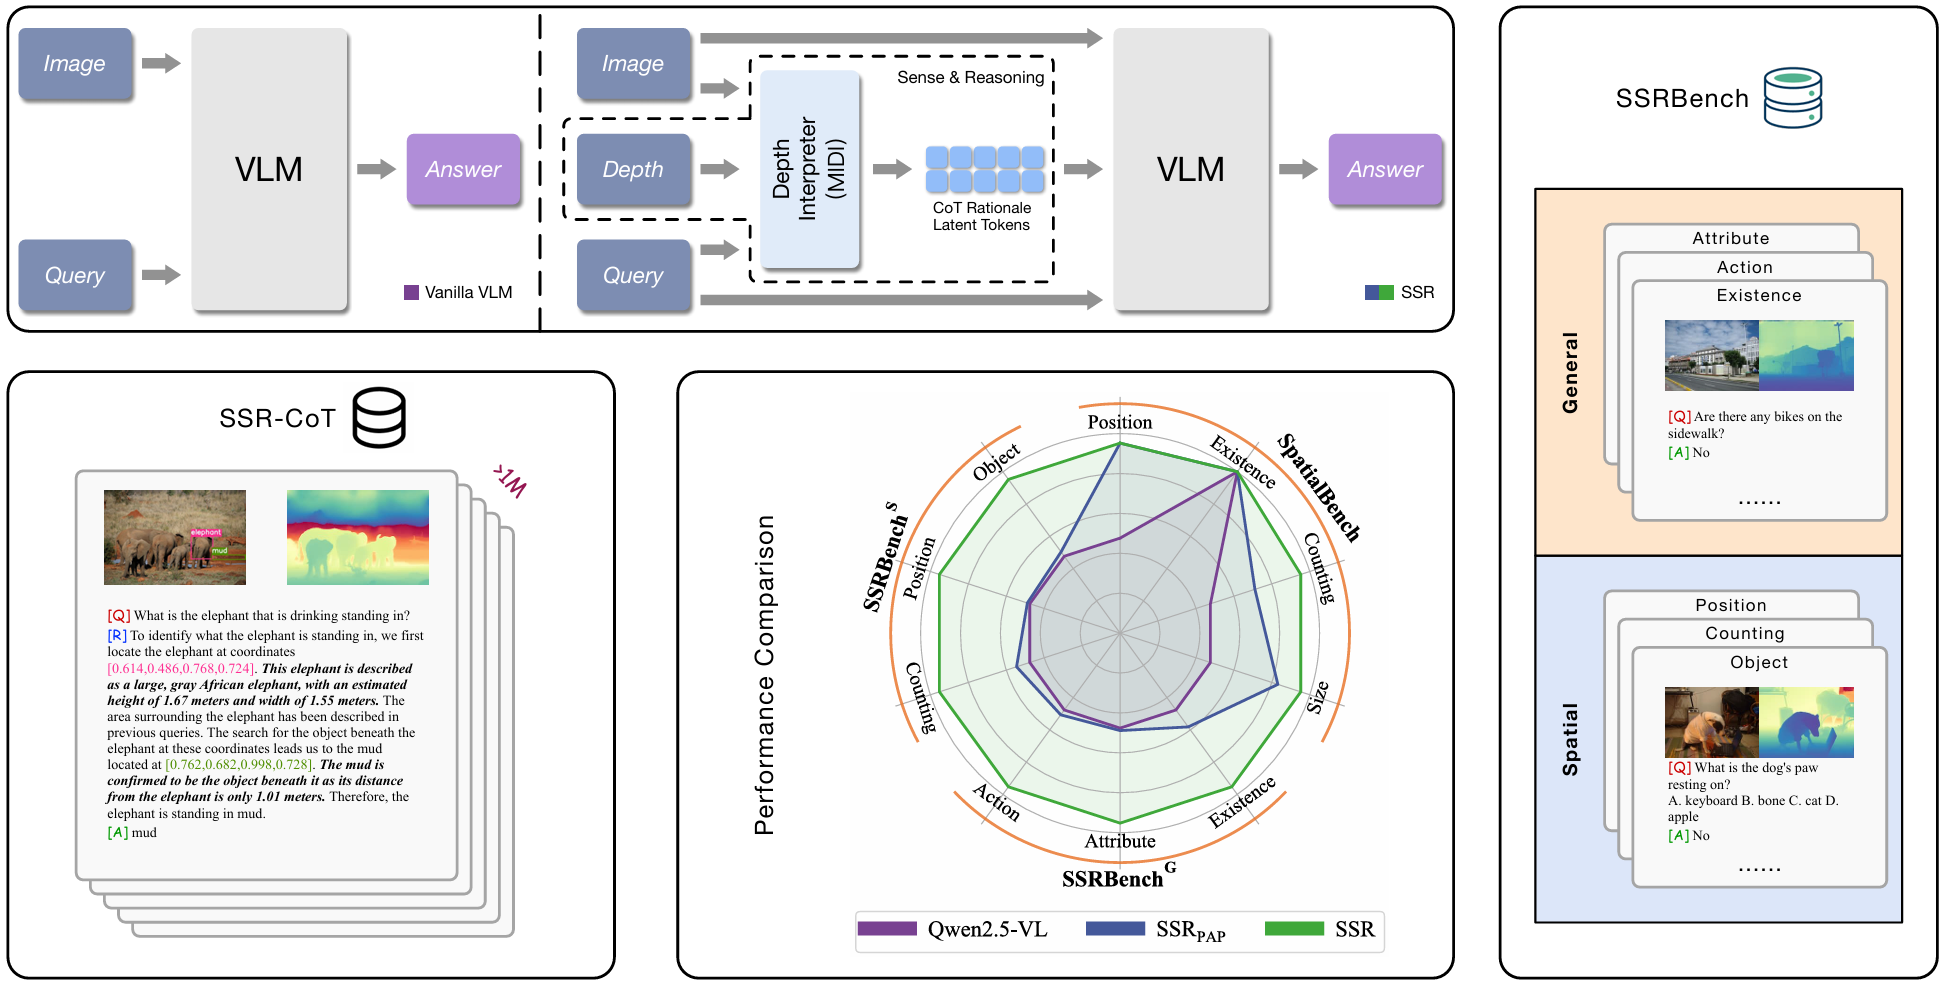
SSR: Enhancing Depth Perception in Vision-Language Models via Rationale-Guided Spatial Reasoning--25-05----SSR-CoTimg
Spatial-LLaVA: Enhancing Large Language Models with Spatial Referring Expressions for Visual UnderstandingARXIV25-05link--SUNSPOTimg
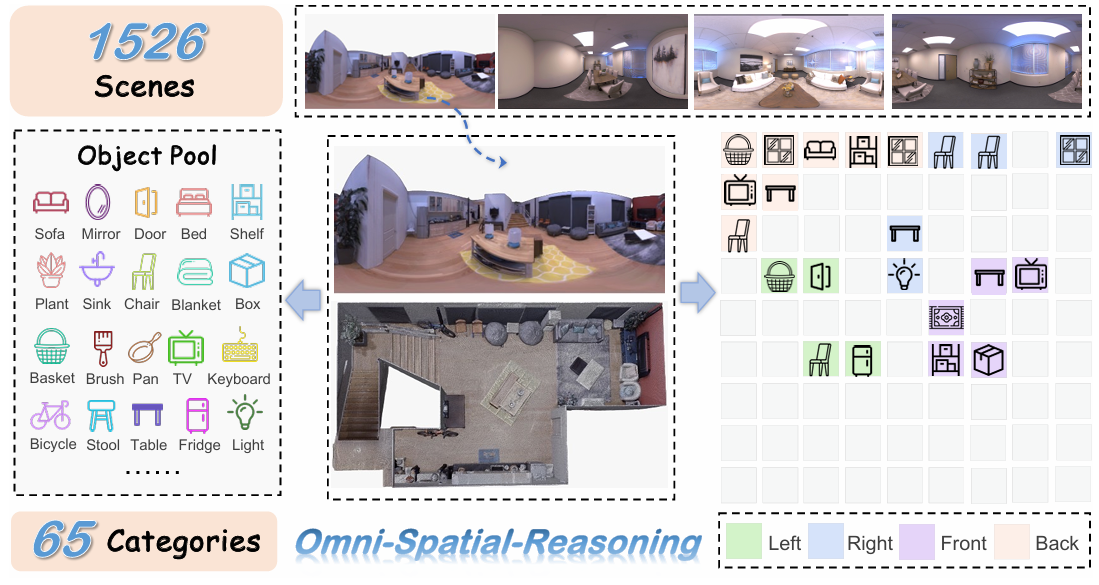
Are Multimodal Large Language Models Ready for Omnidirectional Spatial Reasoning?ARXIV25-05link--OSR-Benchimg
SITE: towards Spatial Intelligence Thorough EvaluationARXIV25-05linkStar countSITEimg
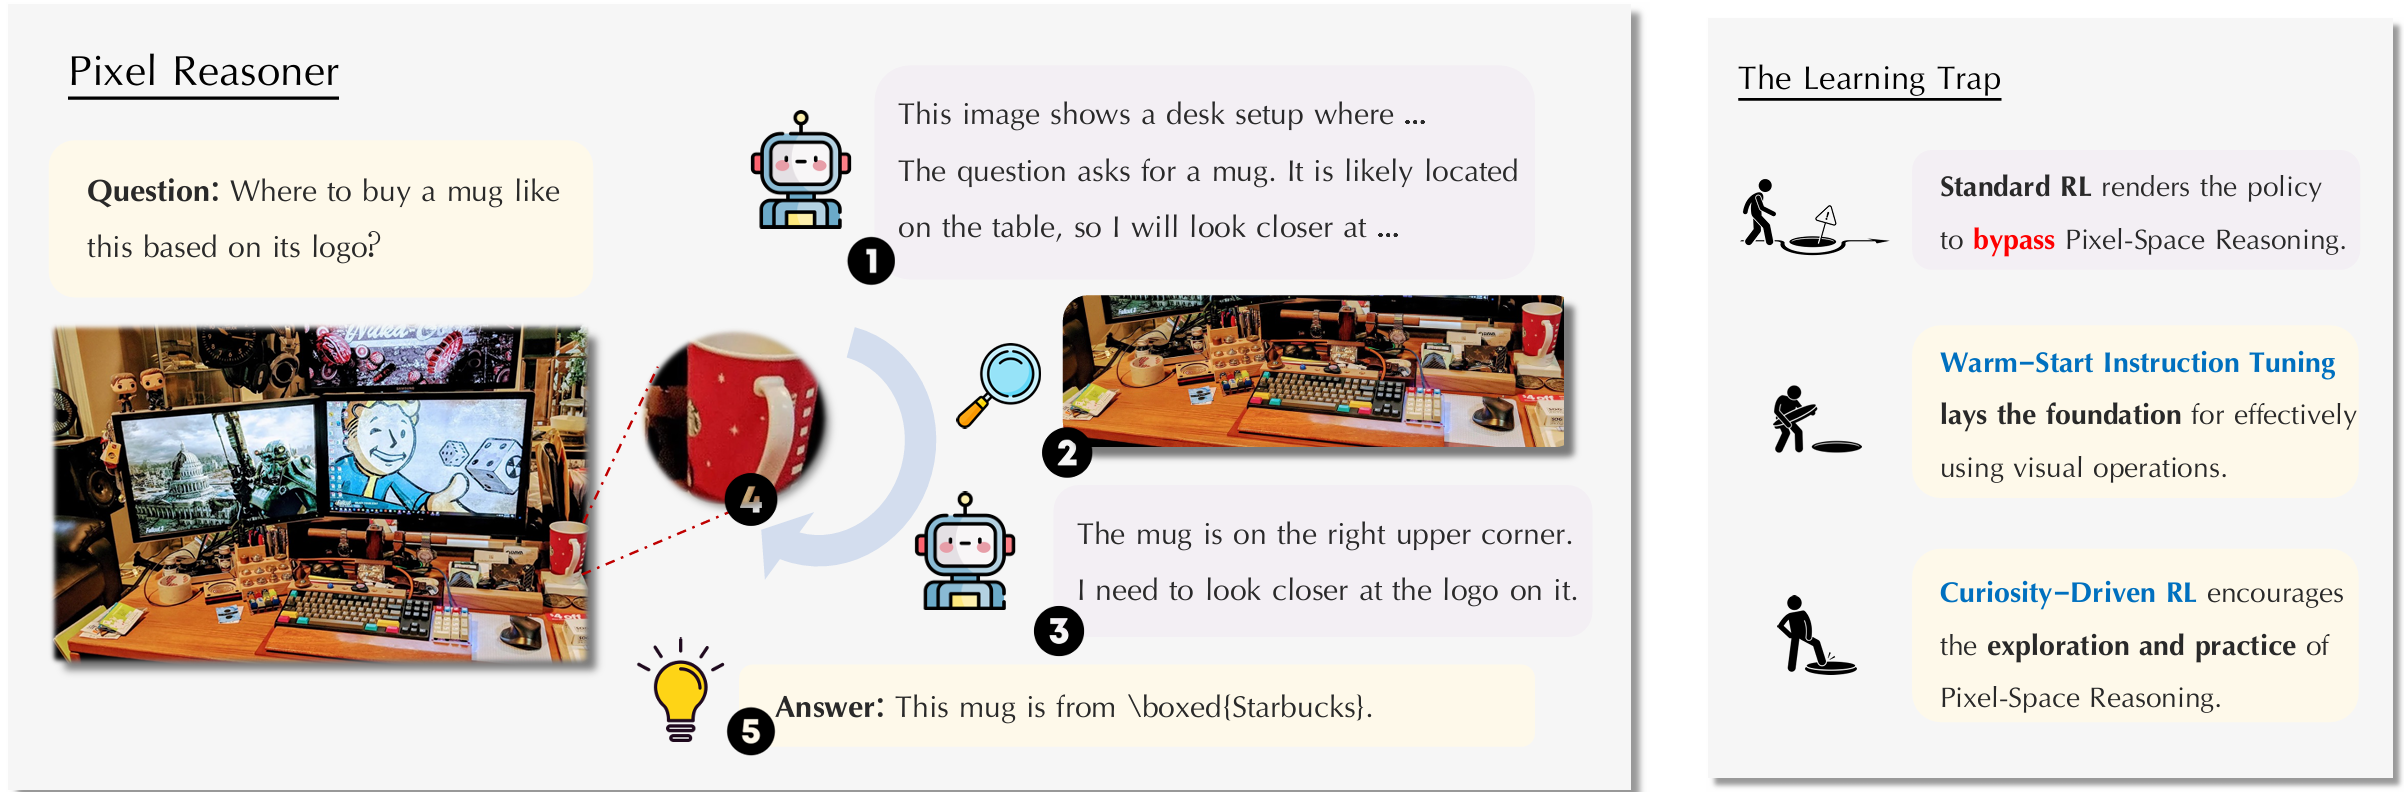
Pixel Reasoner: Incentivizing Pixel-Space Reasoning with Curiosity-Driven Reinforcement LearningARXIV25-05----TallyQA, V*
InfographicVQA, MVBench
img
Improved Visual-Spatial Reasoning via R1-Zero-Like TrainingARXIV25-04linkStar countVSI-100Kimg
Perspective-Aware Reasoning in Vision-Language Models via Mental Imagery SimulationARXIV25-04linkStar countCOMFORT++, 3DSRBenchimg
SpatialReasoner: Towards Explicit and Generalizable 3D Spatial ReasoningARXIV25-04link----img
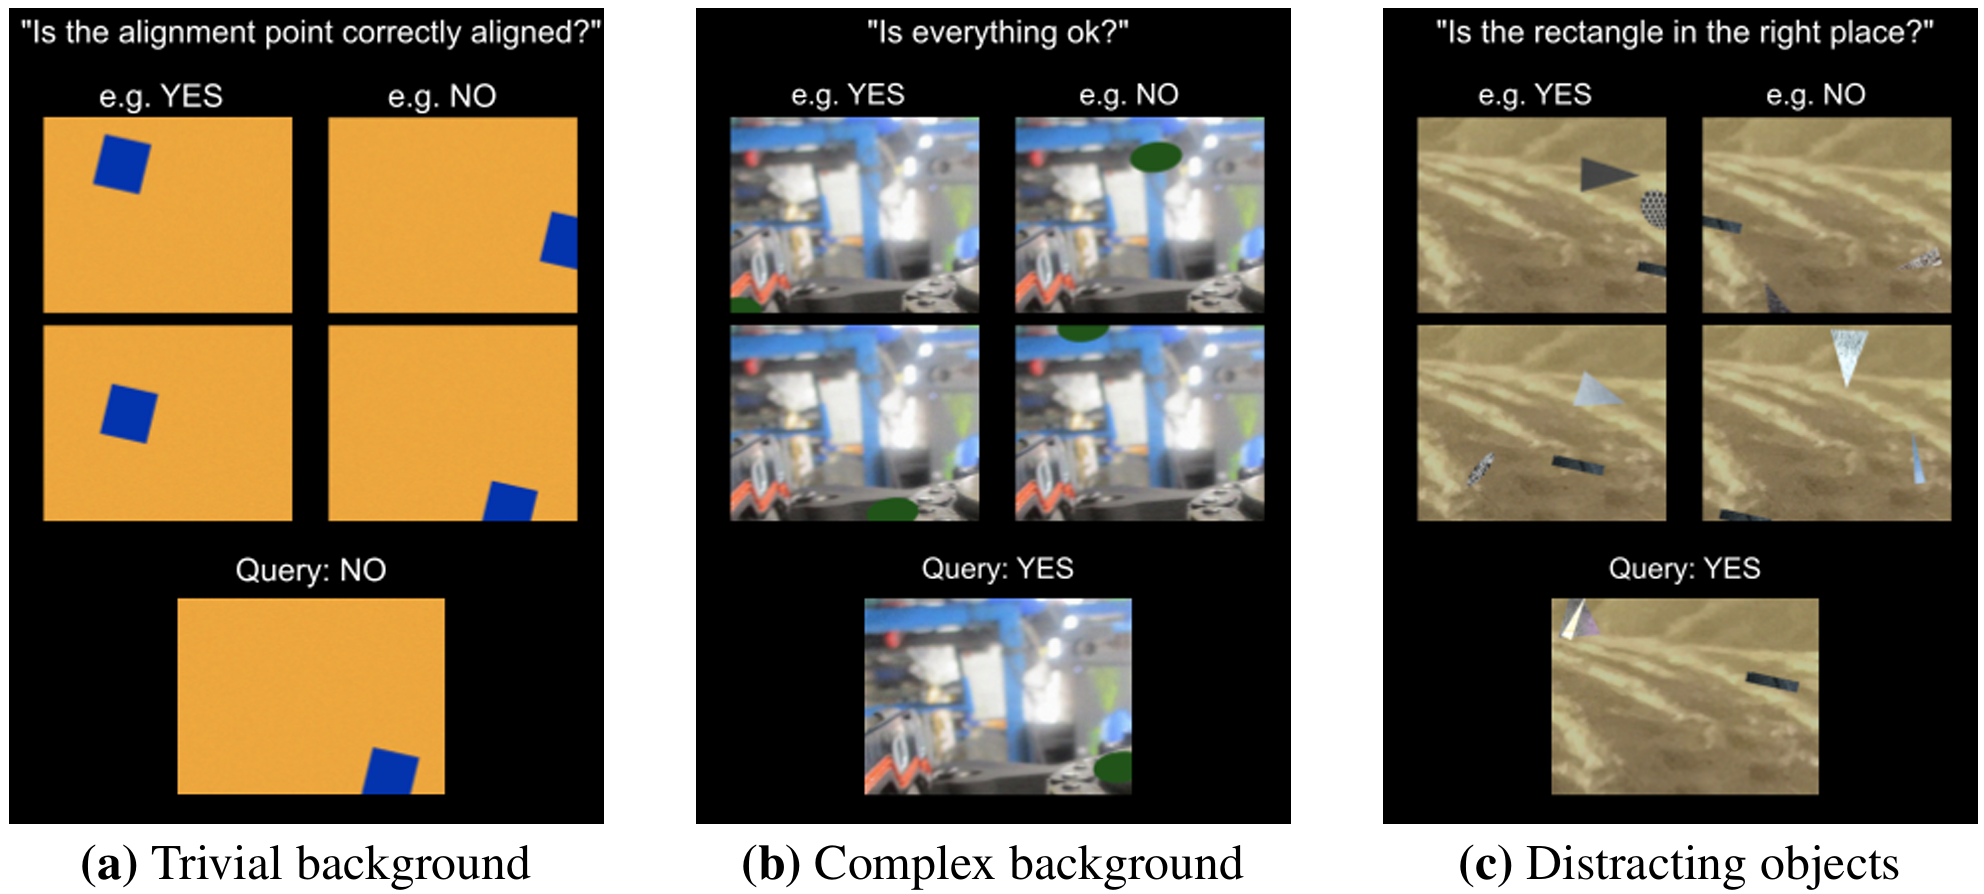
Vision language models are unreliable at trivial spatial cognitionARXIV25-04----TableTestimg
SpaRE: Enhancing Spatial Reasoning in Vision-Language Models with Synthetic DataARXIV25-04----vsr, what's up
3DSR-Bench, RealWorldQA
img
NUSCENES-SPATIALQA: A Spatial Understanding and Reasoning Benchmark for Vision-Language Models in Autonomous DrivingARXIV25-04linkStar countNuScenes-SpatialQAimg
Beyond Semantics Rediscovering Spatial Awareness in Vision-Language Models--25-03link----img
MetaSpatial: Reinforcing 3D Spatial Reasoning in VLMs for the MetaverseARXIV25-03linkStar countMetaSpatialimg
Mind the Gap: Benchmarking Spatial Reasoning in Vision-Language ModelsARXIV25-03linkStar countSRBenchimg
Open3DVQA: ABenchmark for Comprehensive Spatial Reasoning with Multimodal Large Language Model in Open SpaceARXIV25-03linkStar countOpen3DVQAimg
AutoSpatial: Visual-Language Reasoning for Social Robot Navigation through Efficient Spatial Reasoning LearningARXIV25-03linkStar countAutoSpatialimg
Why Is Spatial Reasoning Hard for VLMs? AnAttention Mechanism Perspective on Focus AreasARXIV25-03linkStar count--img
LEGO-Puzzles: How Good Are MLLMs at Multi-Step Spatial ReasoningARXIV25-03linkStar countLEGO-Puzzlesimg
Visual Agentic AI for Spatial Reasoning with a Dynamic APIARXIV25-02linkStar count--img
iVISPAR —AnInteractive Visual-Spatial Reasoning Benchmark for VLMsARXIV25-02linkStar countiVISPARimg
Visual Agentic AI for Spatial Reasoning with a Dynamic APIARXIV25-02linkStar countQ-Spatial Bench, VSI-Benchimg
Defining and Evaluating Visual Language Models’ Basic Spatial Abilities: A Perspective from PsychometricsARXIV25-02----BSA-Testsimg
Mitigating Hallucinations in Multimodal Spatial Relations through Constraint-Aware PromptingNAACL25-02linkStar countARO, GQA
MMRel
img
Do Vision-Language Models Represent Space and How. Evaluating Spatial Frame of Reference under AmbiguitiesICLR25-01link--COMFORTimg
ROBOSPATIAL: Teaching Spatial Understanding to 2D and 3D Vision-Language Models for RoboticsCVPR25-01------img
Spatial457: A Diagnostic Benchmark for 6D Spatial Reasoning of Large Multimodal ModelsCVPR25-01------img
COARSE CORRESPONDENCES Boost Spatial-Temporal Reasoning in Multimodal Language ModelCVPR25-01link----img
SpatialLLM: A Compound 3D-Informed Design towards Spatially-Intelligent Large Multimodal ModelsCVPR25-01link----img
SpatialCLIP: Learning 3D-aware Image Representations from Spatially Discriminative LanguageCVPR25-01linkStar countSpatialBenchimg
SpatialCoT: Advancing Spatial Reasoning through Coordinate Alignment and Chain-of-Thought for Embodied Task PlanningARXIV25-01------img
ReasonGrounder: LVLM-Guided Hierarchical Feature Splatting for Open-Vocabulary 3D Visual Grounding and ReasoningCVPR25-01link--ReasoningGDimg
Imagine while Reasoning in Space: Multimodal Visualization-of-ThoughtARXIV25-01----LEC23, WMS+24
LZZ+24, RDT+24
img
LLaVA-SpaceSGG: Visual Instruct Tuning for Open-vocabulary Scene Graph Generation with Enhanced Spatial RelationsARXIV24-12linkStar countSpaceSGGimg
3DSRBench: A Comprehensive 3D Spatial Reasoning BenchmarkARXIV24-12link--3DSRBenchimg
SPHERE: Unveiling Spatial Blind Spots in Vision-Language Models Through Hierarchical EvaluationACL24-12linkStar countSPHEREimg
TopV-Nav: Unlocking the Top-View Spatial Reasoning Potential of MLLM for Zero-shot Object NavigationARXIV24-11------img
AnEmpirical Analysis on Spatial Reasoning Capabilities of Large Multimodal ModelsEMNLP24-11linkStar countSpatial-MMimg
ROOT: VLM-based System for Indoor Scene Understanding and BeyondARXIV24-11linkStar countSceneVLMimg
An Empirical Analysis on Spatial Reasoning Capabilities of Large Multimodal ModelsEMNLP 202424-11linkStar countSpatial-MM, GQA-spatialimg
GEOBench-VLM: Benchmarking Vision-Language Models for Geospatial TasksARXIV24-11linkStar countGEOBench-VLMimg
Sparkle: Mastering Basic Spatial Capabilities in Vision Language Models Elicits Generalization to Spatial ReasoningNIPS24-10----what's up, coco-spatial
GQA-spatial
img
Reasoning Paths with Reference Objects Elicit Quantitative Spatial Reasoning in Large Vision-Language ModelsARXIV24-09linkStar countQ-Spatial Benchimg
Can Vision Language Models Learn from Visual Demonstrations of Ambiguous Spatial Reasoning?ARXIV24-09linkStar countSVATimg
Understanding Depth and Height Perception in Large Visual-Language ModelsCVPRW24-08linkStar countGeoMeterimg
Coarse Correspondences Boost Spatial-Temporal Reasoning in Multimodal Language Model--24-08----ScanQA, OpenEQA’s episodic memory subset
EgoSchema, R2R
SQA3D
img
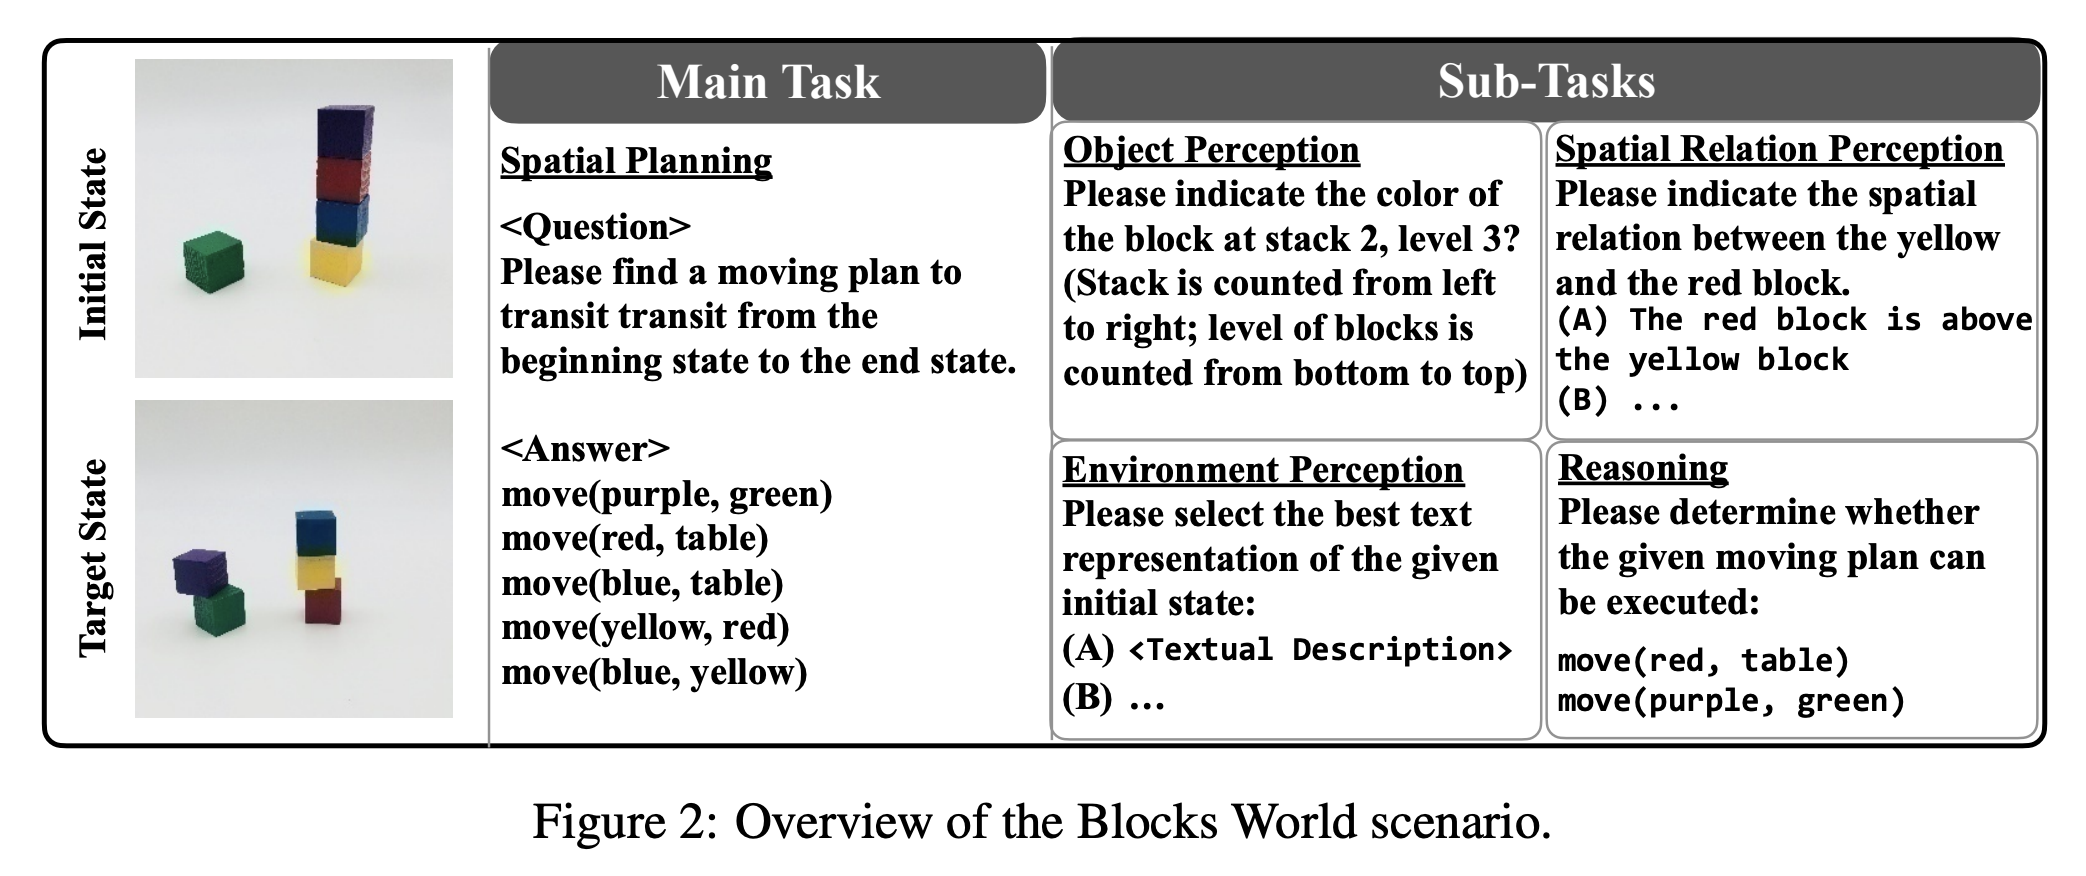
VSP: Assessing the dual challenges of perception and reasoning in spatial planning tasks for VLMsARXIV24-07linkStar countVSPimg
SpatialBot: Precise Spatial Understanding with Vision Language ModelsICRA24-06linkStar countSpatialBenchimg
SpatialRGPT: Grounded Spatial Reasoning in Vision-Language ModelsARXIV24-06linkStar countSpatialRGPT-Benchimg
TOPVIEWRS: Vision-Language Models as Top-View Spatial ReasonersARXIV24-06link----img
Is A Picture Worth A Thousand Words? Delving Into Spatial Reasoning for Vision Language ModelsNIPS24-06linkStar countSpatialEvalimg
EmbSpatial-Bench: Benchmarking Spatial Understanding for Embodied Tasks with Large Vision-Language ModelsARXIV24-06linkStar countEmbSpatial-Benchimg
GSR-BENCH: A Benchmark for Grounded Spatial Reasoning Evaluation via Multimodal LLMsNEURIPS 2024 WORKSHOP24-06----GSR-BENCHimg
RoboPoint: A Vision-Language Model for Spatial Affordance Prediction for RoboticsCORL202424-06linkStar countRoboPointimg
Reframing Spatial Reasoning Evaluation in Language Models:A Real-World Simulation Benchmark for Qualitative ReasoningARXIV24-05----RoomSpace, bAbI
StepGame, SpartQA
SpaRTUN
img
RAG-Guided Large Language Models for Visual Spatial Description with Adaptive Hallucination CorrectorACMMM2424-05----VSDimg
Mind's Eye of LLMs: Visualization-of-Thought Elicits Spatial Reasoning in Large Language ModelsNIPS24-04linkStar countVoTimg
BLINK: Multimodal Large Language Models Can See but Not PerceiveECCV24-04linkStar countBLINKimg
Know Your Neighbors: Improving Single-View Reconstruction via Spatial Vision-Language ReasoningCVPR202424-04linkStar countKITTI-360img
Visual CoT: Advancing Multi-Modal Language Models with a Comprehensive Dataset and Benchmark for Chain-of-Thought Reasoning--24-03linkStar countVisual-CoTimg
Can Transformers Capture Spatial Relations between Objects?ICLR24-03linkStar countSRPimg
SpatialPIN: Enhancing Spatial Reasoning Capabilities of Vision-Language Models through Prompting and Interacting 3D PriorsNEURIPS202424-03linkStar countNOCS, RT-1
BridgeData V2, YCBInEOAT
img
SpatialVLM Endowing Vision-Language Models with Spatial Reasoning CapabilitiesCVPR24-01linkStar count--img
LLaVA-VSD: Large Language-and-Vision Assistant for Visual Spatial DescriptionACM MM24-01------img
Proximity QA: Unleashing the Power of Multi-Modal Large Language Models for Spatial Proximity AnalysisARXIV24-01linkStar countProximity-110Kimg
Improving Vision-and-Language Reasoning via Spatial Relations ModelingWACV23-11------img
3D-Aware Visual Question Answering about Parts, Poses and OcclusionsNIPS23-10linkStar countSuper-CLEVR-3Dimg
Things not Written in Text: Exploring Spatial Commonsense from Visual SignalsACL202222-03linkStar count--img

Monocular-Video

TitleVenueDateCodeStarsBenchmarkIllustration
World2VLM: Distilling World Model Imagination into VLMs for Dynamic Spatial ReasoningARXIV26-04link--SAT-Real, VSI-Bench, MindCube--
ReVSI: Rebuilding Visual Spatial Intelligence Evaluation for Accurate Assessment of VLM 3D ReasoningARXIV26-04----ReVSI--
Holi-Spatial: Evolving Video Streams into Holistic 3D Spatial IntelligenceICML 202626-03linkStar countHoli-Spatial-4M--
CoV: Chain-of-View Prompting for Spatial ReasoningARXIV26-01--------
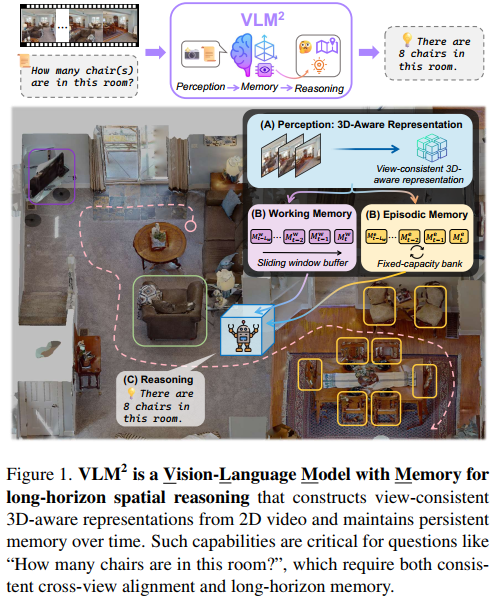
Cambrian-S: Towards Spatial Supersensing in VideoARXIV25-11linkStar countVSI-SUPERimg
Vision-Language Memory for Spatial ReasoningARXIV25-11link----img
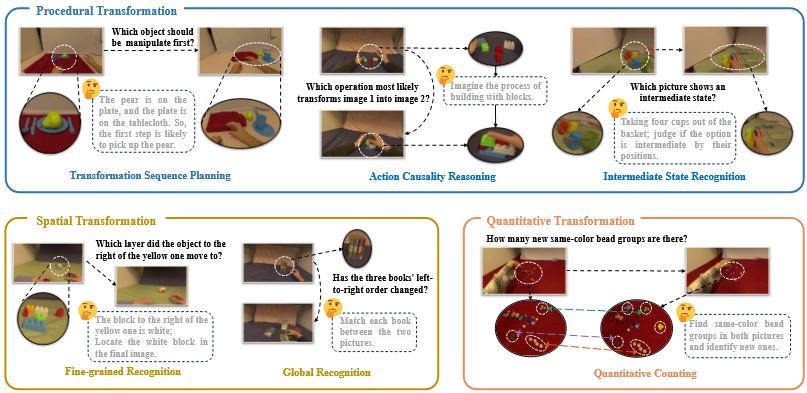
VisualTrans: A Benchmark for Real-World Visual Transformation ReasoningARXIV25-08link--VisualTransimg
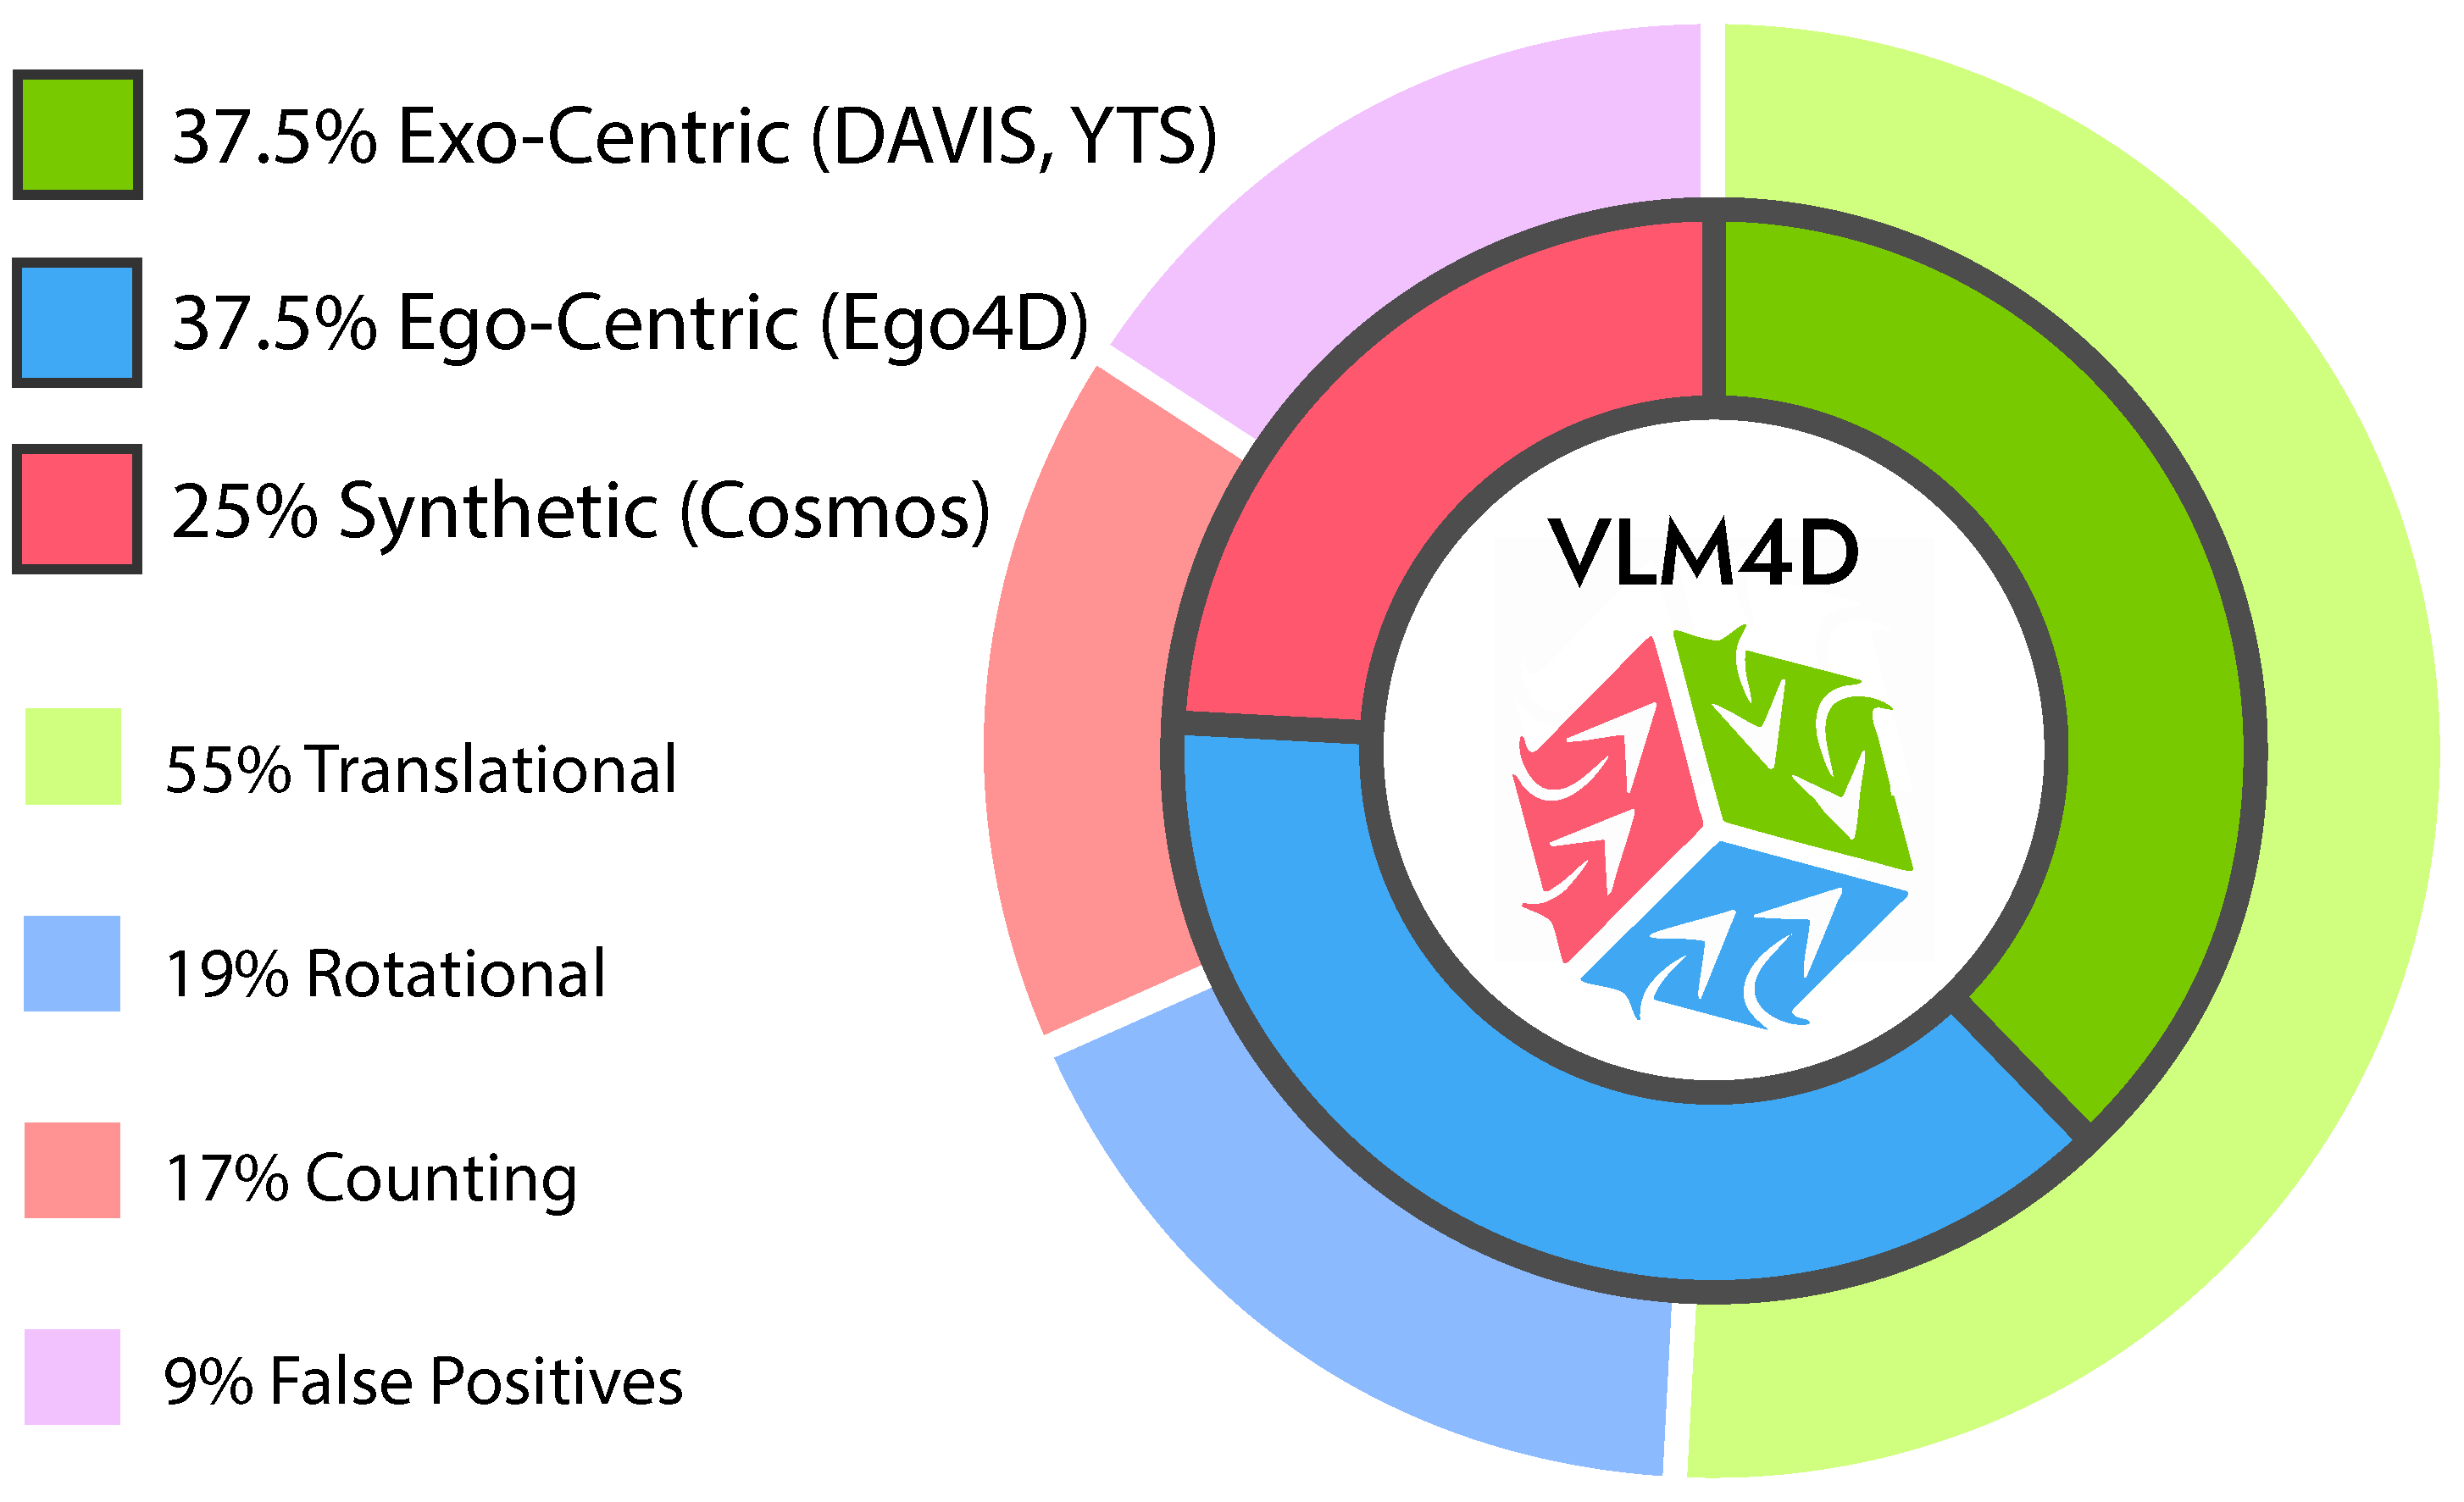
VLM4D: Towards Spatiotemporal Awareness in Vision Language ModelsICCV25-08link--VLM4Dimg
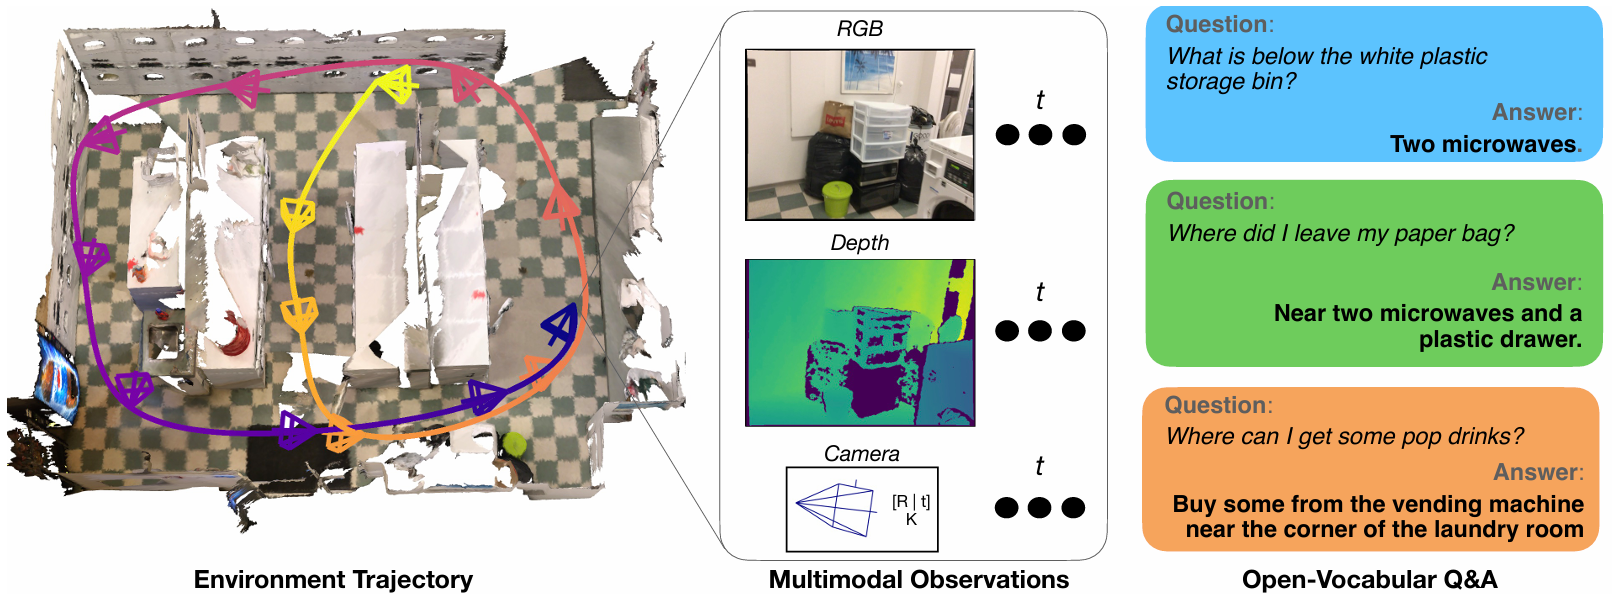
OpenEQA: Embodied Question Answering in the Era of Foundation ModelsCVPR--linkStar countOpenEQAimg
Spatial Understanding from Videos: Structured Prompts Meet Simulation DataARXIV25-06linkStar count--img
VLM-3R: Vision-Language Models Augmented with Instruction-Aligned 3D ReconstructionARXIV25-05linkStar countVSTiBenchimg
3DLLM-Mem: Long-Term Spatial-Temporal Memory for Embodied 3D Large Language ModelARXIV25-05linkStar count3DMEM-Benchimg
Spatial-MLLM Boosting MLLM Capabilities in Visual-based Spatial IntelligenceARXIV25-05linkStar countSpatial-MLLM-120kimg
Out of Sight, Not Out of Context? Egocentric Spatial Reasoning in VLMs Across Disjoint FramesARXIV25-05----DISJOINT-3DQAimg
Learning from Videos for 3D World: Enhancing MLLMs with 3D Vision Geometry PriorsARXIV25-05linkStar countVSI-Benchimg
SpatialPrompting: Keyframe-driven Zero-Shot Spatial Reasoning with Off-the-Shelf Multimodal Large Language ModelsARXIV25-05------img
Towards Visuospatial Cognition via Hierarchical Fusion of Visual ExpertsARXIV25-05linkStar count--img
VideoChat-R1: Enhancing Spatio-Temporal Perception via Reinforcement Fine-TuningARXIV25-04linkStar count--img
Embodied-R: Collaborative Framework for Activating Embodied Spatial Reasoning in Foundation Models via Reinforcement LearningARXIV25-04linkStar countEmbodied-Rimg
SpaceR: Reinforcing MLLMs in Video Spatial ReasoningARXIV25-04linkStar countVSI-Bench, STI-Bench
and SPAR-Bench
img
Towards Understanding Camera Motions in Any VideoARXIV25-04linkStar countCameraBenchimg
EgoDTM:Towards 3D-Aware Egocentric Video-Language PretrainingARXIV25-03linkStar countEgoMCQ...img
STI-Bench: Are MLLMsReadyfor Precise Spatial-Temporal World Understanding?ARXIV25-03linkStar countSTI-Benchimg
ST-Think: How Multimodal Large Language Models Reason About 4D Worlds from Ego-Centric VideosARXIV25-03linkStar countEgo-STimg
From Flatland to Space: Teaching Vision-Language Models to Perceive and Reason in 3DARXIV25-03linkStar countSPAR-Benchimg
ST-VLM:KinematicInstruction Tuning for Spatio-Temporal Reasoning in Vision-Language ModelsARXIV25-03linkStar countSTKitimg
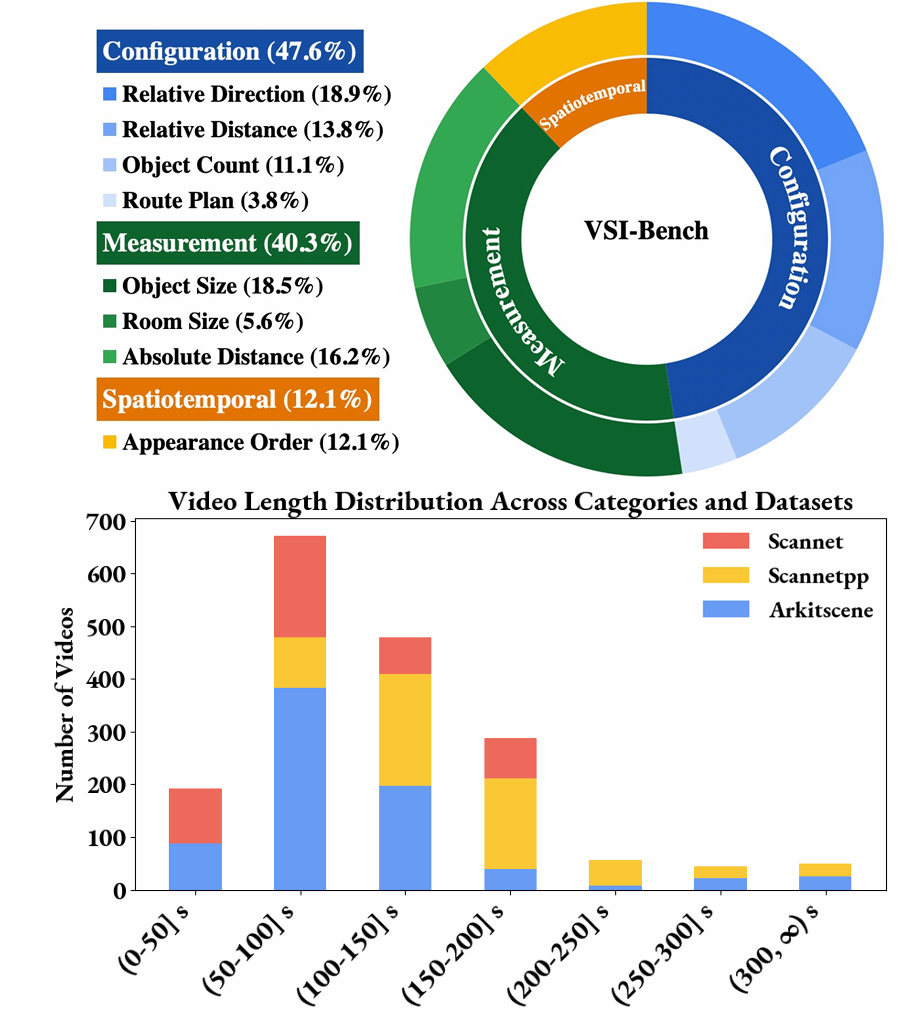
Thinking in Space: How Multimodal Large Language Models See, Remember, and Recall SpacesCVPR25-01linkStar countVSI-Benchimg
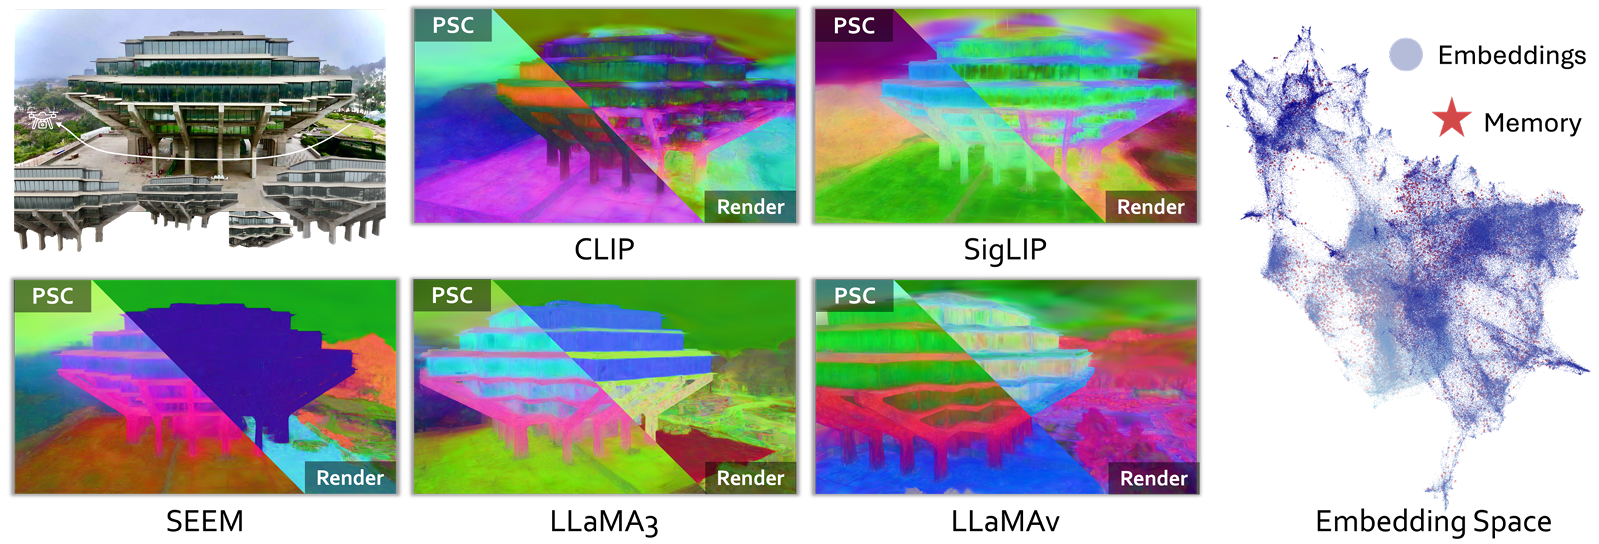
M3: 3D-Spatial Multimodal MemoryICLR25-01linkStar count--img
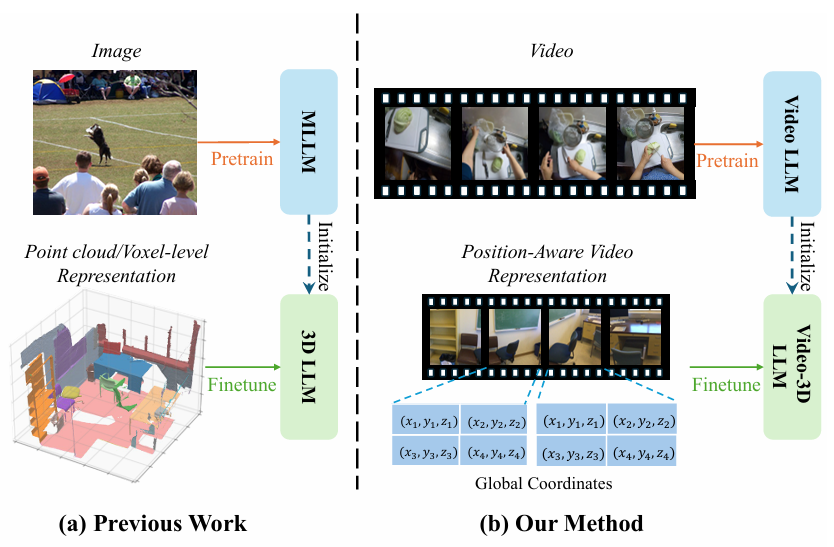
Video-3D LLM: Learning Position-Aware Video Representation for 3D Scene UnderstandingCVPR25-01------img
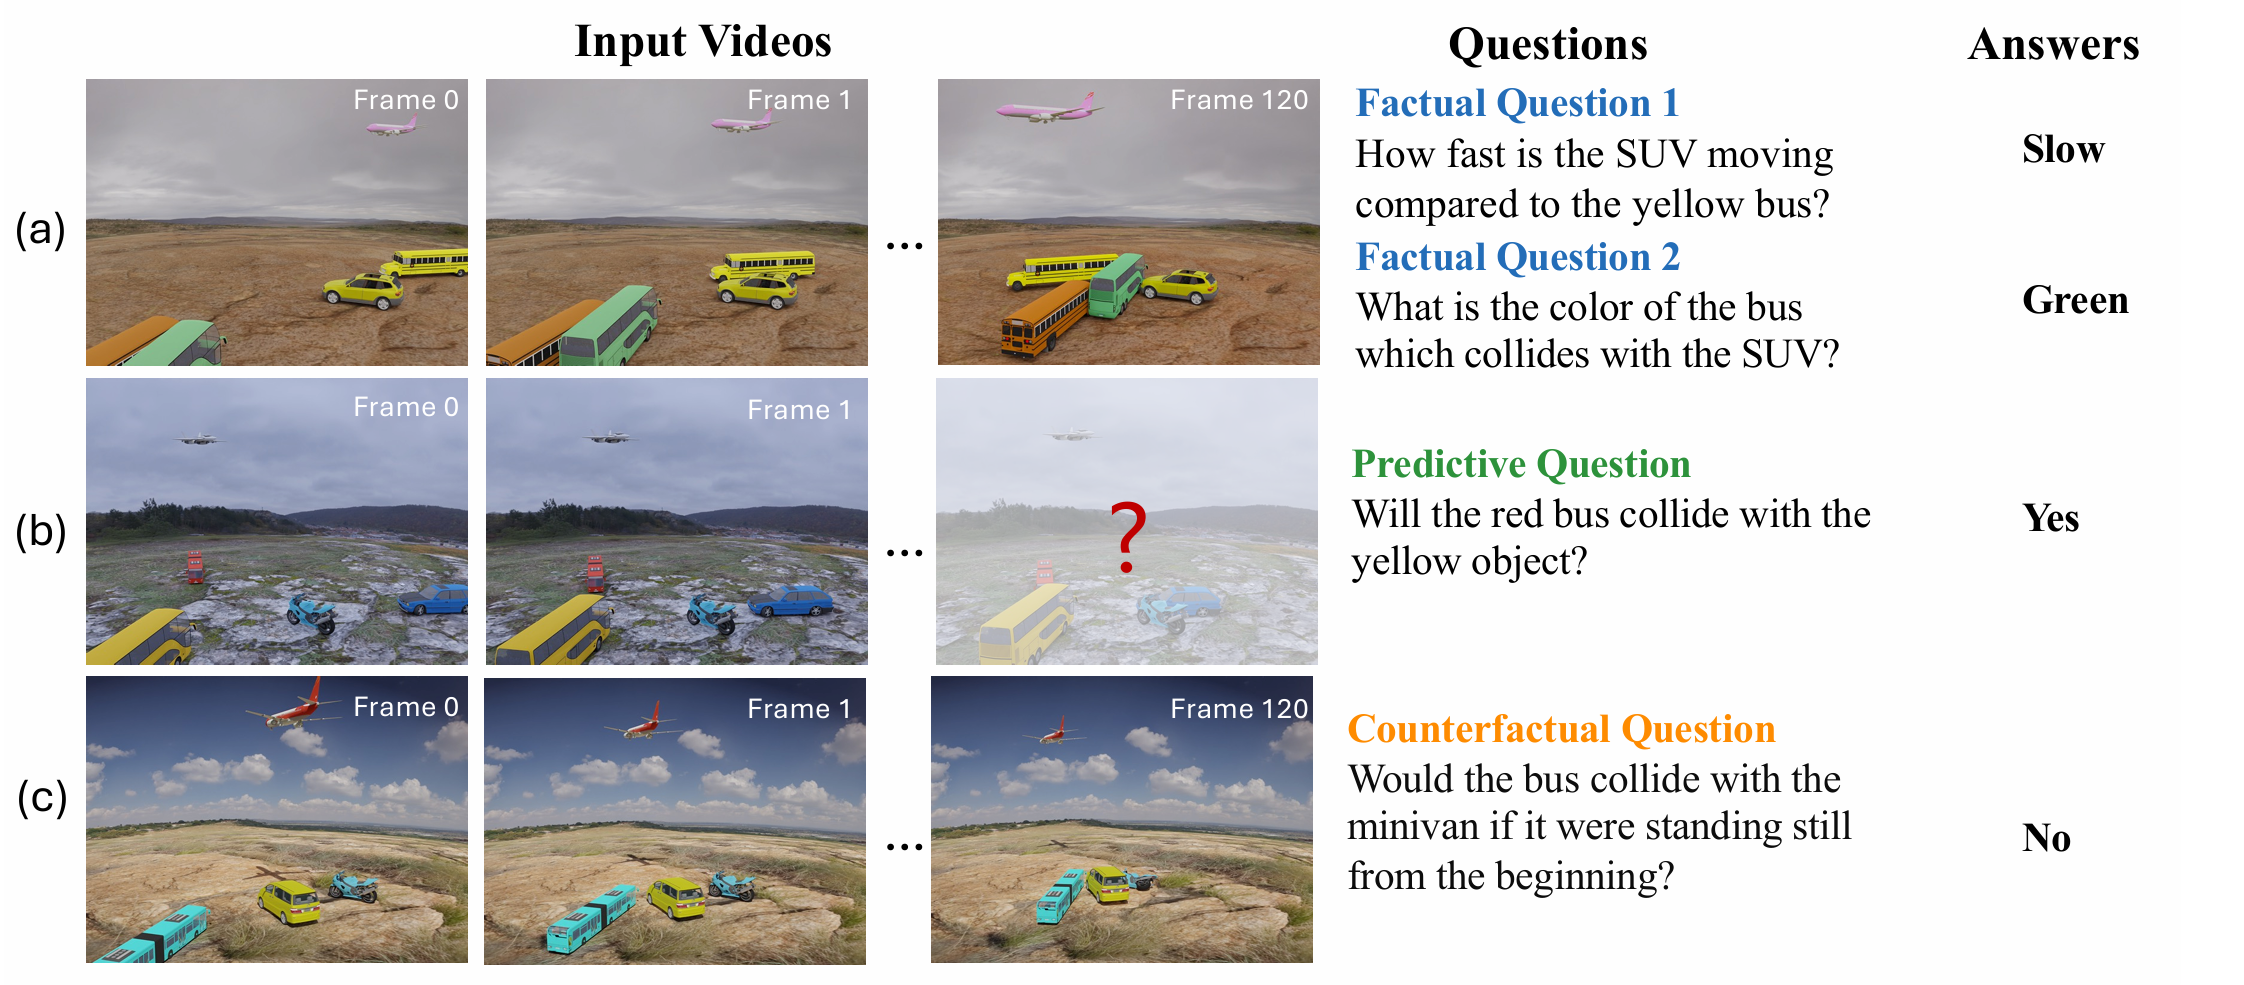
Compositional 4D Dynamic Scenes Understanding with Physics Priors for Video Question AnsweringICLR25-01linkStar countDynSuperCLEVRimg
DOES SPATIAL COGNITION EMERGE IN FRONTIER MODELS?ICLR24-10linkStar countSPACEimg
Explore until Confident: Efficient Exploration for Embodied Question AnsweringARXIV24-03linkStar count--img
EmbodiedScan: A Holistic Multi-Modal 3D Perception Suite Towards Embodied AICVPR24-01------img

Multi-View Images

<tr>
<td><a href="https://arxiv.org/pdf/2511.21688">G^2VLM: Geometry Grounded Vision Language Model with Unified 3D

Reconstruction and Spatial Reasoning

Others

<tr>
<td><a href="https://arxiv.org/pdf/2512.02487">Masking Matters: Unlocking the Spatial Reasoning Capabilities of LLMs

for 3D Scene-Language Understanding

TitleVenueDateCodeStarsBenchmarkIllustration
SpatialLadder: Progressive Training for Spatial Reasoning in Vision-Language ModelsARXIV25-10linkStar countSpatialLadder-26k--
N3D-VLM: Native 3D Grounding Enables Accurate Spatial Reasoning in Vision-Language ModelsARXIV25-12link------
ARXIV25-11------img
Visual Spatial TuningARXIV25-11linkStar count--img
Multimodal Spatial Reasoning in the Large Model Era: A Survey and BenchmarksARXIV25-10linkStar countVSTimg
SpaCE-10: A Comprehensive Benchmark for Multimodal Large Language Models in Compositional Spatial IntelligenceARXIV25-06linkStar countSpaCE-10img
Robot-R1: Reinforcement Learning for Enhanced Embodied Reasoning in RoboticsARXIV25-06----Robot-R1 Benchimg
Struct2D: A Perception-Guided Framework for Spatial Reasoning in Large Multimodal ModelsARXIV25-06linkStar count--img
SpatialScore Towards Unified Evaluation for Multimodal Spatial UnderstandingARXIV25-05linkStar countSpatialScoreimg
A Light and Smart Wearable Platform with Multimodal Foundation Model for Enhanced Spatial Reasoning in People with Blindness and Low VisionECCV25-05----LVSQAimg
ManipBench: Benchmarking Vision-Language Models for Low-Level Robot ManipulationARXIV25-05link--ManipBenchimg
InSpire: Vision-Language-Action Models with Intrinsic Spatial ReasoningARXIV25-05linkStar count--img
Universal Visuo-Tactile Video Understanding for Embodied InteractionARXIV25-05------img
MineAnyBuild: Benchmarking Spatial Planning for Open-world AI AgentsARXIV25-05linkStar count--img
LLaVA-4D: Embedding SpatioTemporal Prompt into LMMs for 4D Scene UnderstandingARXIV25-05----scan2cap, scanqa
scanref, multi3drefer
chat4d
img
Scaling and Beyond: Advancing Spatial Reasoning in MLLMs Requires New RecipesARXIV25-04------img
A Survey of Large Language Model-Powered Spatial Intelligence Across Scales: Advances in Embodied Agents, Smart Cities, and Earth ScienceARXIV25-04------img
Ross3D: Reconstructive Visual Instruction Tuning with 3D-AwarenessARXIV25-04linkStar countsqa3d, scanqaimg
Locate 3D: Real-World Object Localization via Self-Supervised Learning in 3DARXIV25-04linkStar countSR3D, NR3D
ScanRefer
img
3DAxisPrompt: Promoting the 3D Grounding and Reasoning in GPT-4o--25-03------img
EmbodiedVSR: Dynamic Scene Graph-Guided Chain-of-Thought Reasoning for Visual Spatial TasksARXIV25-03------img
FoREST: Frame of Reference Evaluation in Spatial Reasoning TasksARXIV25-02linkStar countFoRESTimg
A Real-to-Sim-to-Real Approach to Robotic Manipulation with VLM-Generated Iterative Keypoint RewardsICRA25-02linkStar count--img
pace-Aware Instruction Tuning: Dataset and Benchmark for Guide Dog Robots Assisting the Visually ImpairedARXIV25-02linkStar countSA-Benchimg
VL-Nav: Real-time Vision-Language Navigation with Spatial ReasoningARXIV25-02------img
SoFar: Language-Grounded Orientation Bridges Spatial Reasoning and Object ManipulationARXIV25-02linkStar count--img
PHYSBENCH: BENCHMARKING AND ENHANCING VISION-LANGUAGE MODELS FOR PHYSICAL WORLD UNDERSTANDINGARXIV25-01linkStar countPhysBenchimg
3D-Mem: 3DScene Memory for Embodied Exploration and ReasoningCVPR25-01linkStar count--img
PhysVLM: Enabling Visual Language Models to Understand Robotic Physical ReachabilityCVPR25-01------img
Evaluating and enhancing spatial cognition abilities of large language modelsIJGIS25-01linkStar count--img
EMBODIEDEVAL: Evaluate Multimodal LLMs as Embodied AgentsARXIV25-01----EMBODIEDEVALimg
Social-LLaVA: Enhancing Robot Navigation through Human-Language Reasoning in Social SpacesARXIV25-01link--Social-LLaVAimg
SpatialVLA: Exploring Spatial Representations for Visual-Language-Action ModelARXIV25-01linkStar countSpatialVLAimg
OmniManip: Towards General Robotic Manipulation via Object-Centric Interaction Primitives as Spatial ConstraintsCVPR202525-01linkStar countOmniManipimg
Synthetic Vision: Training Vision-Language Models to Understand Physics--24-12------img
Emma-X: An Embodied Multimodal Action Model with Grounded Chain of Thought and Look-ahead Spatial Reasoning--24-12linkStar countEmma-Ximg
Do Multimodal Language Models Really Understand Direction? A Benchmark for Compass Direction ReasoningARXIV24-12------img
GPT-4V(ision) for Robotics: Multimodal Task Planning From Human DemonstrationOBOTICS AND AUTOMATION LETTERS24-11------img
Do Vision-Language Models Represent Space and How? Evaluating Spatial Frame of Reference Under AmbiguitiesICLR24-10link--COMFORTimg
I KnowAbout“Up”! Enhancing Spatial Reasoning in Visual Language Models Through 3D ReconstructionARXIV24-07------img
GRASP: A Grid-Based Benchmark for Evaluating Commonsense Spatial ReasoningARXIV24-07linkStar count--img
RoboPoint: AVision-Language Model for Spatial Affordance Prediction for RoboticsARXIV24-06linkStar countRobopointimg
SpaRC and SpaRP: Spatial Reasoning Characterization and Path Generation for Understanding Spatial Reasoning Capability of Large Language ModelsACL24-06linkStar countSpaRPimg
KnowYour Neighbors: Improving Single-View Reconstruction via Spatial Vision-Language ReasoningCVPR24-04linkStar count--img
Agent3D-Zero: An Agent for Zero-shot 3D UnderstandingECCV24-03------img
Scene-LLM: Extending Language Model for 3D Visual Understanding and ReasoningWACV24-03----ScanQA, SQA3D
ALFRED
img
ShapeLLM: Universal 3D Object Understanding for Embodied InteractionECCV24-02linkStar count--img
BAT: Learning to Reason about Spatial Sounds with Large Language ModelsARXIV24-02linkStar count--img
Beyond Lines and Circles: Unveiling the Geometric Reasoning Gap in Large Language ModelsARXIV24-02----Euclideaimg
LL3DA: Visual Interactive Instruction Tuning for Omni-3D Understanding, Reasoning, and PlanningCVPR24-01linkStar count--img
Advancing Spatial Reasoning in Large Language Models: An In-Depth Evaluation and Enhancement Using the StepGame BenchmarkAAAI24-01----StepGameimg
Holistic Autonomous Driving Understanding by Bird's-Eye-View Injected Multi-Modal Large ModelsCVPR24-01linkStar countNuInstructimg

Datasets

TitleVenueDateDownload-LinkCitationInput TypeIllustration
Can LLMs See Without Pixels? Benchmarking Spatial Intelligence from Textual DescriptionsARXIV26-01NA0Imageimg
Scaling Spatial Reasoning in MLLMs through Programmatic Data SynthesisARXIV25-12link0Video,Imageimg
MMSI-Video-Bench: A Holistic Benchmark for Video-Based Spatial IntelligenceARXIV25-12link0Videoimg
Actial: Activate Spatial Reasoning Ability of Multimodal Large Language ModelsARXIV25-11NA1imageimg
Reasoning via Video: The First Evaluation of Video Models’ Reasoning Abilities through Maze-Solving TasksARXIV25-11link0Videoimg
LTD-Bench: Evaluating Large Language Models by Letting Them DrawARXIV25-11link1Imageimg
Is your VLM Sky-Ready? A Comprehensive Spatial Intelligence Benchmark for UAV NavigationARXIV25-11link0Imageimg
SpatialBench: Benchmarking Multimodal Large Language Models for Spatial CognitionARXIV25-11link1Videoimg
Do Vision-Language Models Represent Space and How. Evaluating Spatial Frame of Reference under AmbiguitiesICLR25-11link0Imageimg
OmniSpatial: Towards Comprehensive Spatial Reasoning Benchmark for Vision Language ModelsARXIV25-06link0Imageimg
SpatialScore Towards Unified Evaluation for Multimodal Spatial UnderstandingARXIV25-05link0Imageimg
Can Multimodal Large Language Models Understand Spatial RelationsARXIV25-05link--Imageimg
Are Multimodal Large Language Models Ready for Omnidirectional Spatial Reasoning?ARXIV25-05link0Imageimg
SITE: towards Spatial Intelligence Thorough EvaluationARXIV25-05link0Image/Multi-view Image/Videoimg
VLM-3R: Vision-Language Models Augmented with Instruction-Aligned 3D ReconstructionARXIV25-05link0Videoimg
MMSI-Bench: A Benchmark for Multi-ImagecSpatial IntelligenceARXIV25-05link1multi-viewimg
ViewSpatial-Bench:Evaluating Multi-perspective Spatial Localization in Vision-Language ModelsARXIV25-05link--multi-viewimg
Improved Visual-Spatial Reasoning via R1-Zero-Like TrainingARXIV25-04link9--img
Towards Understanding Camera Motions in Any VideoARXIV25-04link1Videoimg
Seeing from Another Perspective: Evaluating Multi-View Understanding in MLLMsARXIV25-04link3multi-viewimg
Mind the Gap: Benchmarking Spatial Reasoning in Vision-Language ModelsARXIV25-03link5Imageimg
Open3DVQA: ABenchmark for Comprehensive Spatial Reasoning with Multimodal Large Language Model in Open SpaceOPEN3DVQA25-03link4Imageimg
LEGO-Puzzles: How Good Are MLLMs at Multi-Step Spatial Reasoning?ARXIV25-03link8Multi-viewimg
STI-Bench: Are MLLMsReadyfor Precise Spatial-Temporal World Understanding?ARXIV25-03--7Videoimg
ST-Think: How Multimodal Large Language Models Reason About 4D Worlds from Ego-Centric VideosARXIV25-03link5Videoimg
From Flatland to Space: Teaching Vision-Language Models to Perceive and Reason in 3DARXIV25-03link2Imageimg
Space-Aware Instruction Tuning: Dataset and Benchmark for Guide Dog Robots Assisting the Visually ImpairedARXIV25-02link1Imageimg
VADAR: Visual Agentic AI for Spatial Reasoning with a Dynamic APICVPR25-02link5imageimg
PHYSBENCH: BENCHMARKING AND ENHANCING VISION-LANGUAGE MODELS FOR PHYSICAL WORLD UNDERSTANDINGARXIV25-01link22Image/Videoimg
Social-LLaVA: Enhancing Robot Navigation through Human-Language Reasoning in Social SpacesARXIV25-01link2Imageimg
SpatialVLA: Exploring Spatial Representations for Visual-Language-Action ModelARXIV25-01link--Videoimg
Emma-X: An Embodied Multimodal Action Model with Grounded Chain of Thought and Look-ahead Spatial ReasoningARXIV24-12link--Videoimg
LLaVA-SpaceSGG: Visual Instruct Tuning for Open-vocabulary Scene Graph Generation with Enhanced Spatial RelationsARXIV24-12link2imageimg
3DSRBench: A Comprehensive 3D Spatial Reasoning BenchmarkARXIV24-12link12Imageimg
SPHERE: Unveiling Spatial Blind Spots in Vision-Language Models Through Hierarchical EvaluationACL24-12link3Imageimg
Thinking in Space: How Multimodal Large Language Models See, Remember, and Recall SpacesARXIV24-12link86Videoimg
ROOT: VLM-based System for Indoor Scene Understanding and BeyondARXIV24-11--2imageimg
An Empirical Analysis on Spatial Reasoning Capabilities of Large Multimodal ModelsEMNLP 202424-11link9Imageimg
GEOBench-VLM: Benchmarking Vision-Language Models for Geospatial TasksARXIV24-11link7Imageimg
OpenEQA: Embodied Question Answering in the Era of Foundation ModelsCVPR24-11link149Videoimg
DOES SPATIAL COGNITION EMERGE IN FRONTIER MODELS?ICLR24-10link19Videoimg
Reasoning Paths with Reference Objects Elicit Quantitative Spatial Reasoning in Large Vision-Language ModelsARXIV24-09link15Imageimg
Understanding Depth and Height Perception of Large Visual-Language ModelsCVPRW24-08link02D/3D imageimg
VSP: Assessing the dual challenges of perception and reasoning in spatial planning tasks for VLMsARXIV24-07link4Imageimg
SpaRC and SpaRP: Spatial Reasoning Characterization and Path Generation for Understanding Spatial Reasoning Capability of Large Language ModelsACL24-06link4textimg
SpatialBot: Precise Spatial Understanding with Vision Language ModelsICRA24-06link43Imageimg
SpatialRGPT: Grounded Spatial Reasoning in Vision-Language ModelsARXIV24-06link104Image, point cloudimg
Is A Picture Worth A Thousand Words? Delving Into Spatial Reasoning for Vision Language ModelsNEURIPS24-06link61text only/image only/image-textimg
EmbSpatial-Bench: Benchmarking Spatial Understanding for Embodied Tasks with Large Vision-Language ModelsACL 2024 SHORT24-06link22Imageimg
COMPOSITIONAL 4D DYNAMIC SCENES UNDERSTANDING WITH PHYSICS PRIORS FOR VIDEO QUESTION ANSWERINGICLR202524-06link5Videoimg
Reframing Spatial Reasoning Evaluation in Language Models: A Real-World Simulation Benchmark for Qualitative ReasoningIJCAI 202424-05link9Multi-viewimg
Mind's Eye of LLMs: Visualization-of-Thought Elicits Spatial Reasoning in Large Language ModelsNEURIPS24-04link33imageimg
BLINK: Multimodal Large Language Models Can See but Not PerceiveECCV24-04link180Image/Multi-view Imageimg
Visual CoT: Advancing Multi-Modal Language Models with a Comprehensive Dataset and Benchmark for Chain-of-Thought ReasoningNEURIPS24-03link74imageimg
Can Transformers Capture Spatial Relations between Objects?ICLR24-03link6Imageimg
Holistic Autonomous Driving Understanding by Bird's-Eye-View Injected Multi-Modal Large ModelsCVPR24-01link--Videoimg
Proximity QA: Unleashing the Power of Multi-Modal Large Language Models for Spatial Proximity AnalysisARXIV24-01link2Imageimg
3D-Aware Visual Question Answering about Parts, Poses and OcclusionsNIPS23-10link14Imageimg
Sqa3d: Situated question answering in 3d scenesICLR22-10link161point cloudimg
ScanQA: 3D Question Answering for Spatial Scene UnderstandingCVPR21-12link234point cloudimg
SPARE3D: A Dataset for SPAtial REasoning on Three-View Line DrawingsCVPR202020-03link23multi-viewimg

Acknowledgements
🌍 Visitor Statistics
embodied-ai
vision-language-models
visual-spatial-reasoning

Contributors

HaoDot

98 commits

song2yu

46 commits

SIBench

4 commits

jialianjie

2 commits

Languages

HTML

99.6%