
Qwen's most powerful open-source image generation model
Python
51
23 commits
updated Sep 20, 2026
See what people are saying (2)
README
🤖 ModelScope | 🤗 HuggingFace | 📑 Blog | 🖥️ Demo | 🫨 Discord
Introduction
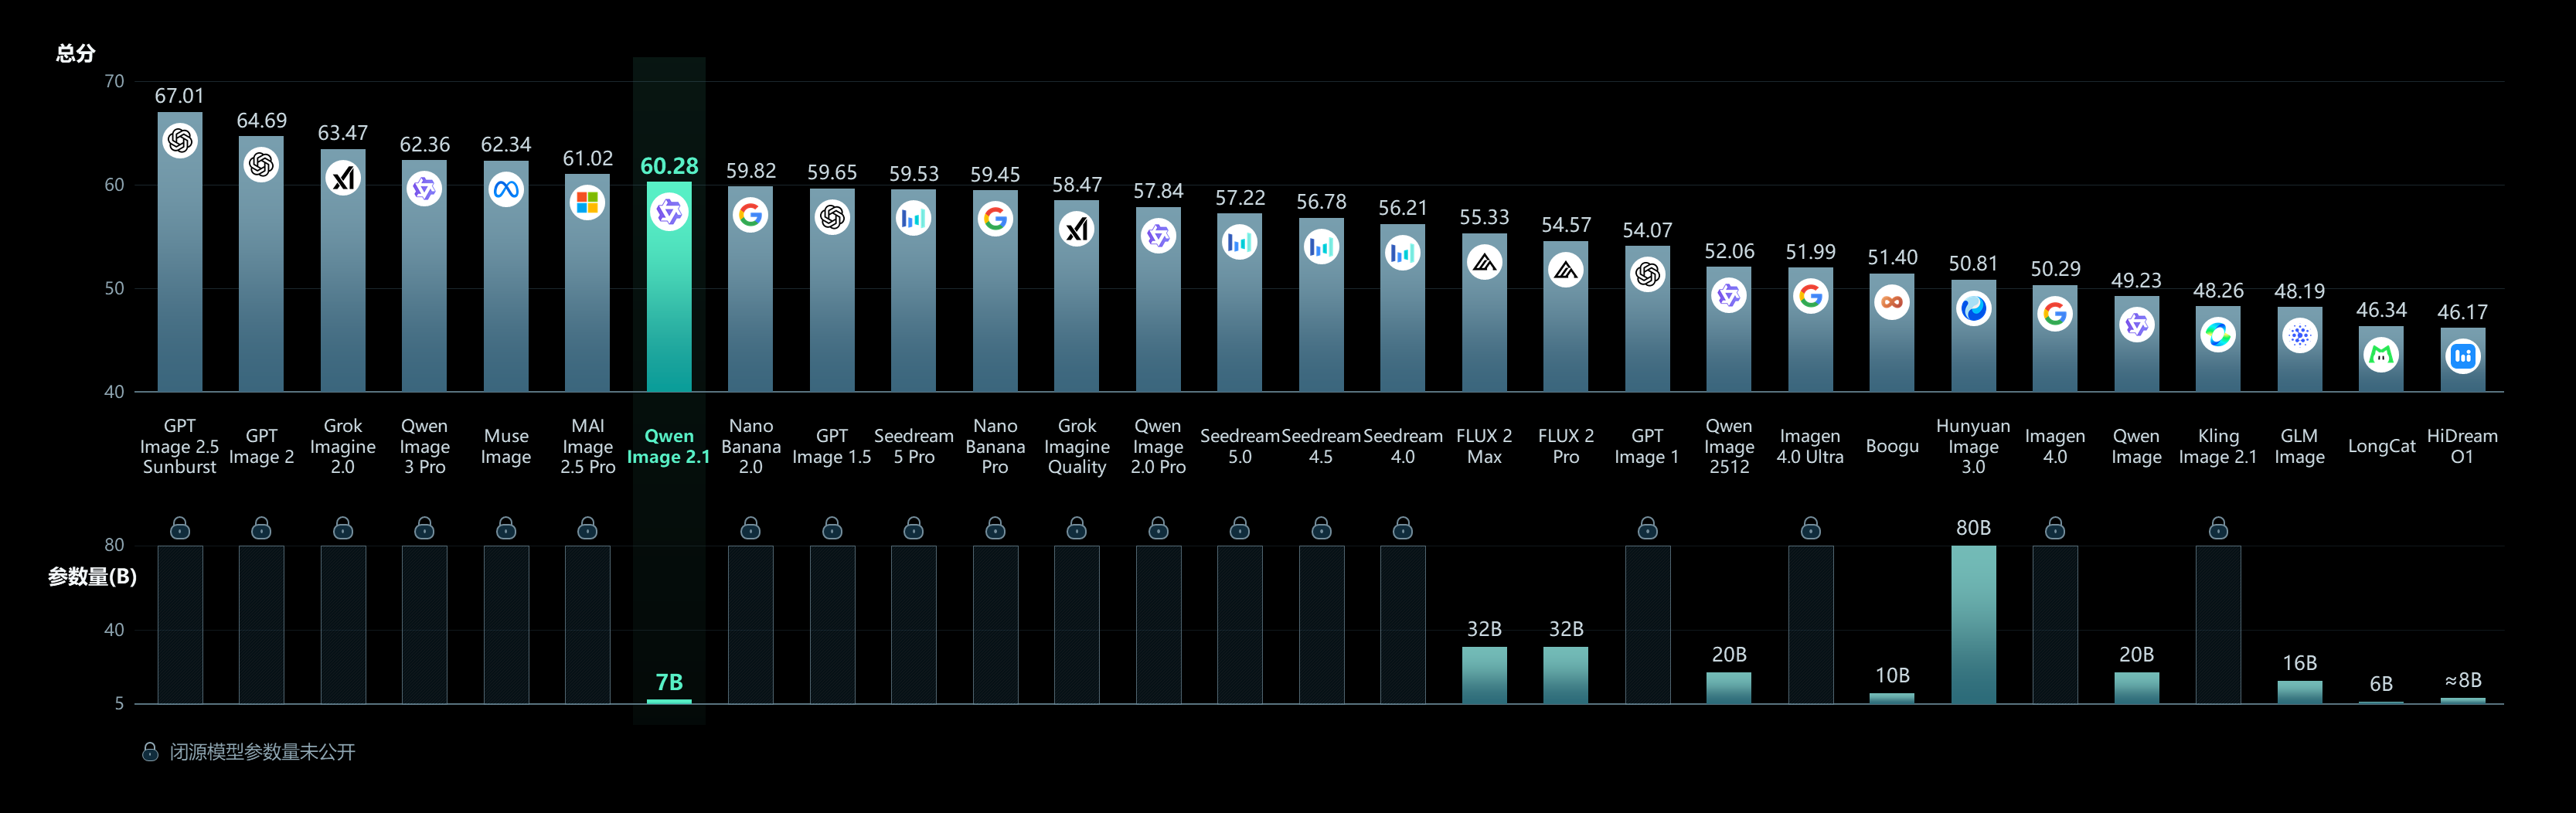
We are excited to open-source Qwen-Image-2.1, a unified text-to-image generation and image editing model in the Qwen family. With just 7B parameters in its visual generation component (32 Single-Stream DiT layers), Qwen-Image-2.1 balances generation quality, inference efficiency, and versatility.
Four key improvements define this release:
- Compact and Efficient — A lightweight architecture with mixed-granularity attention and prefix KV cache reuse delivers strong image quality at low computational cost.
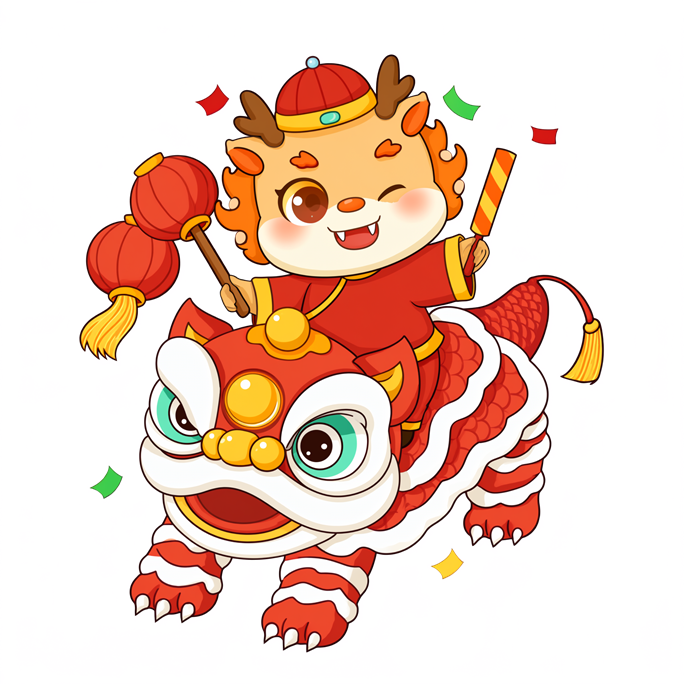
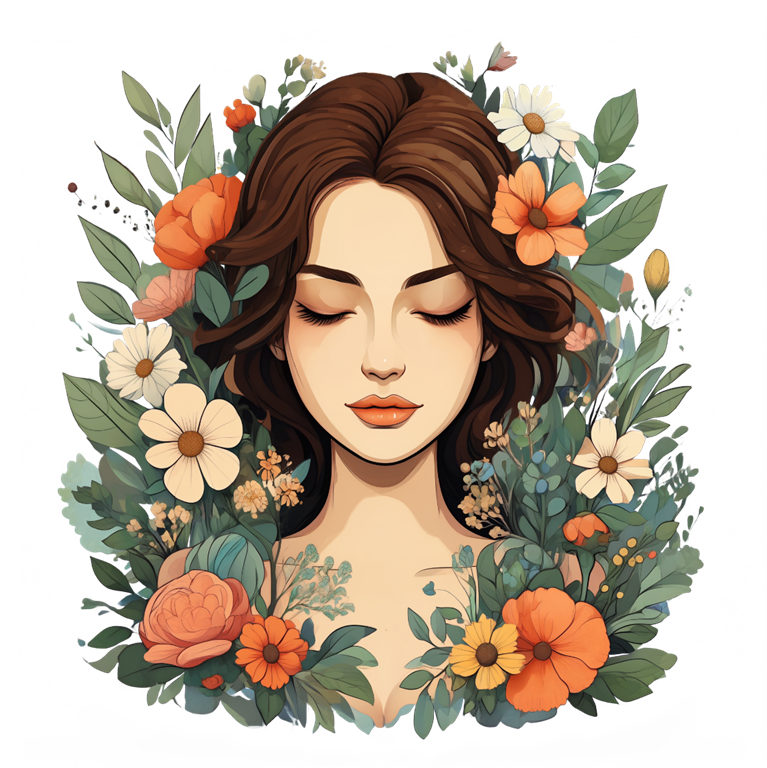
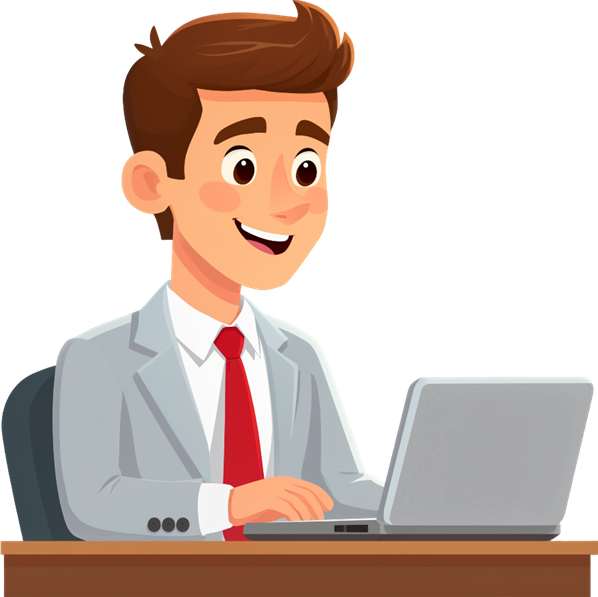
- Native Transparency, Unified Creation and Editing — Generate regular or transparent (RGBA) images from text, edit transparent layers, and extract subjects from photographs—all in one model.
- Versatile Editing — Support up to 10 reference images, specify local edits via circles, painted annotations, or separate masks, and preserve identity for people and products.
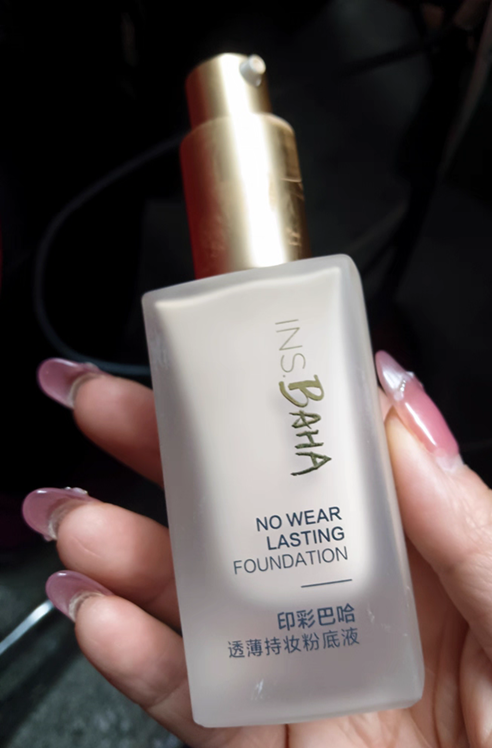
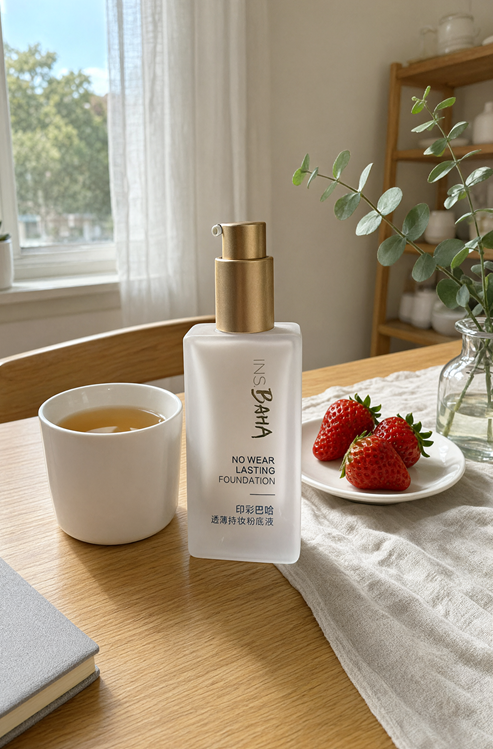
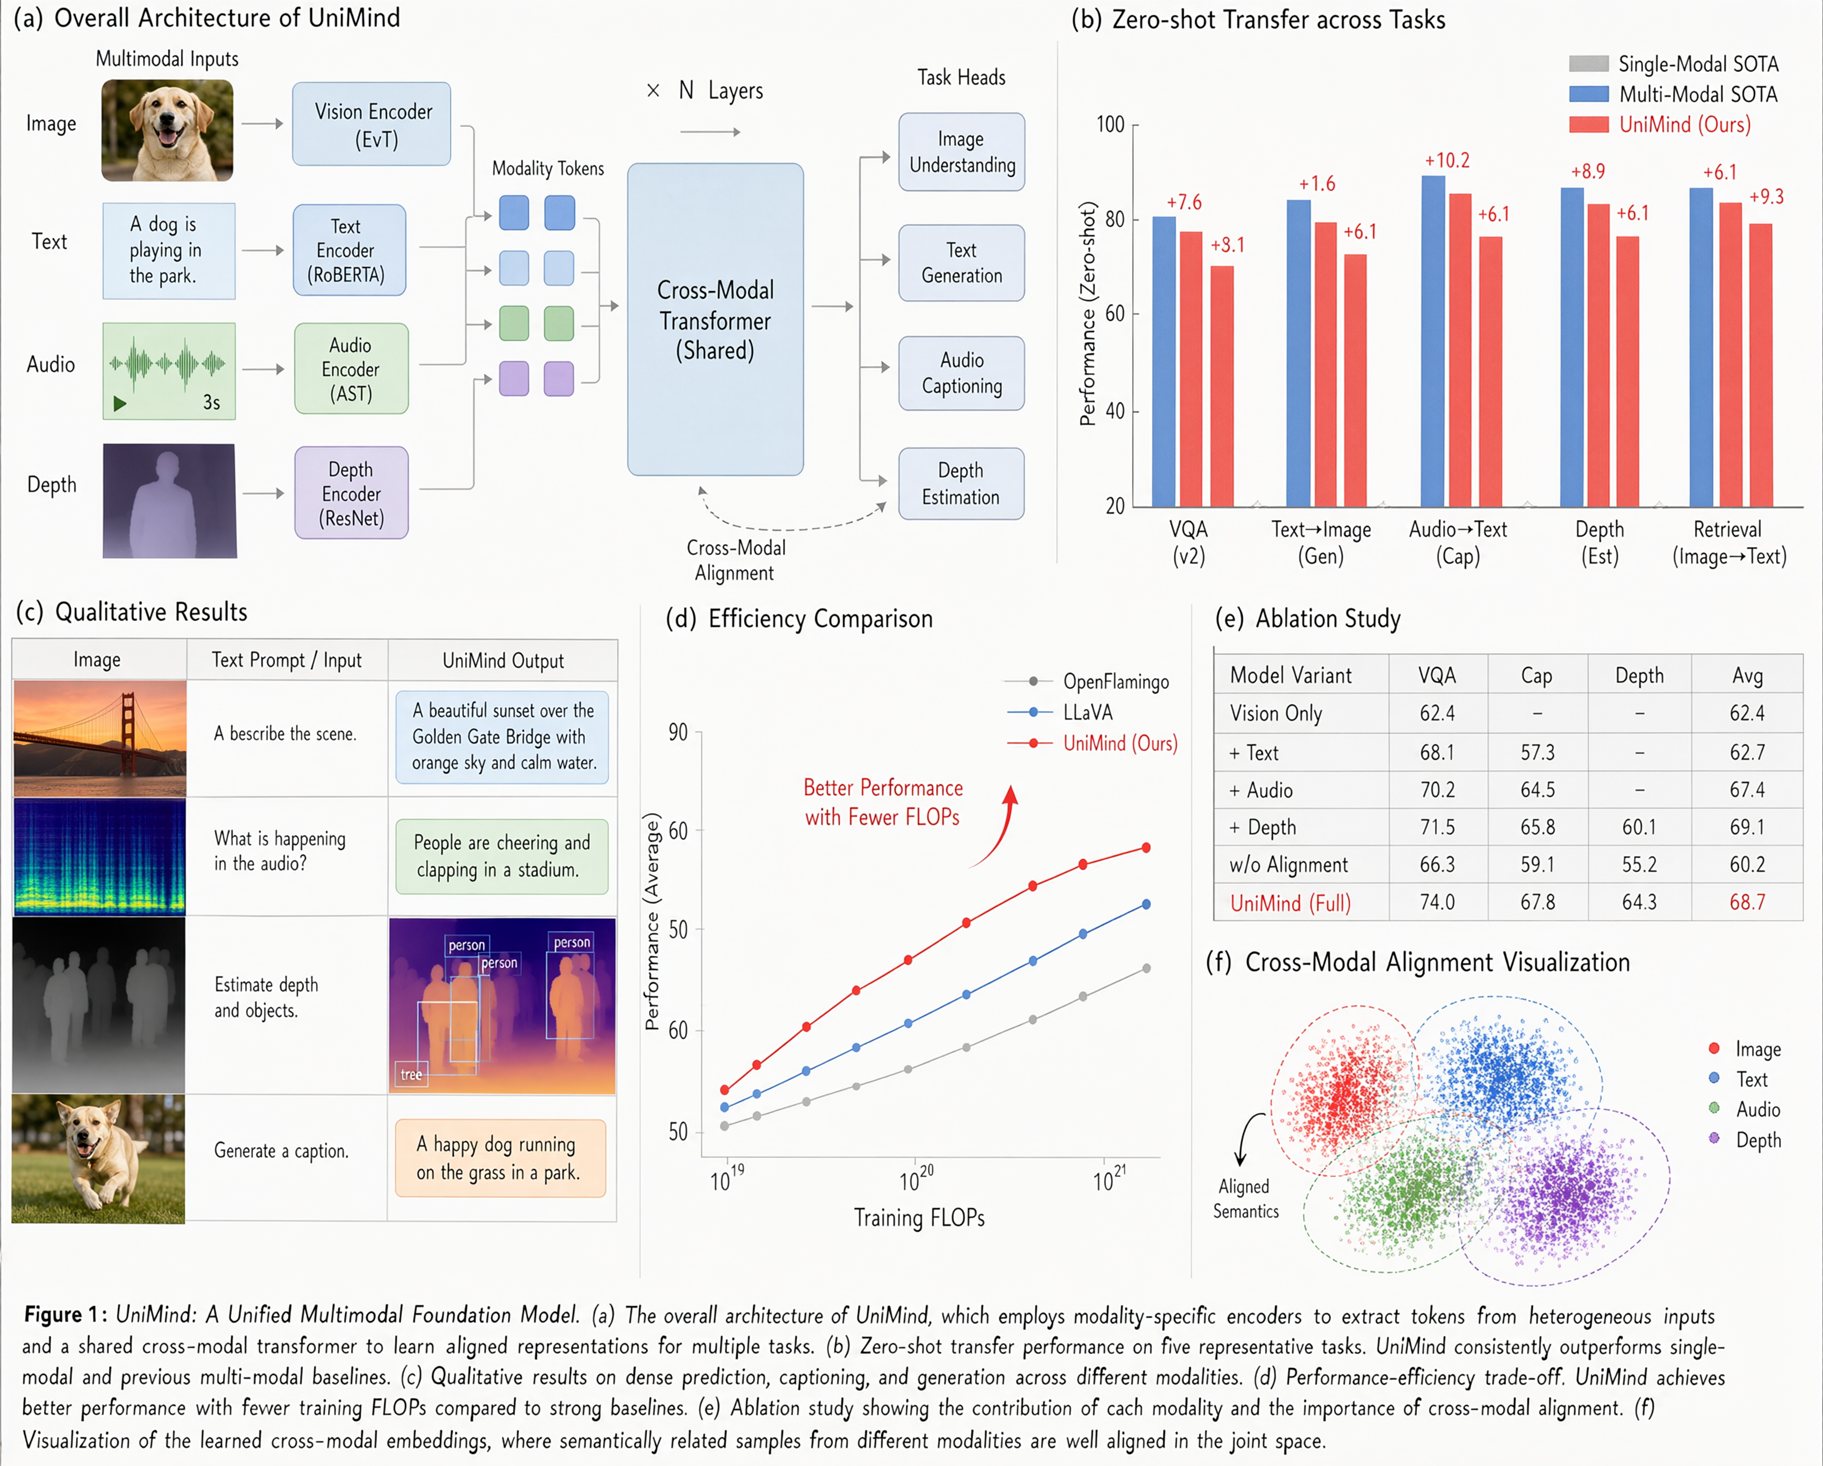
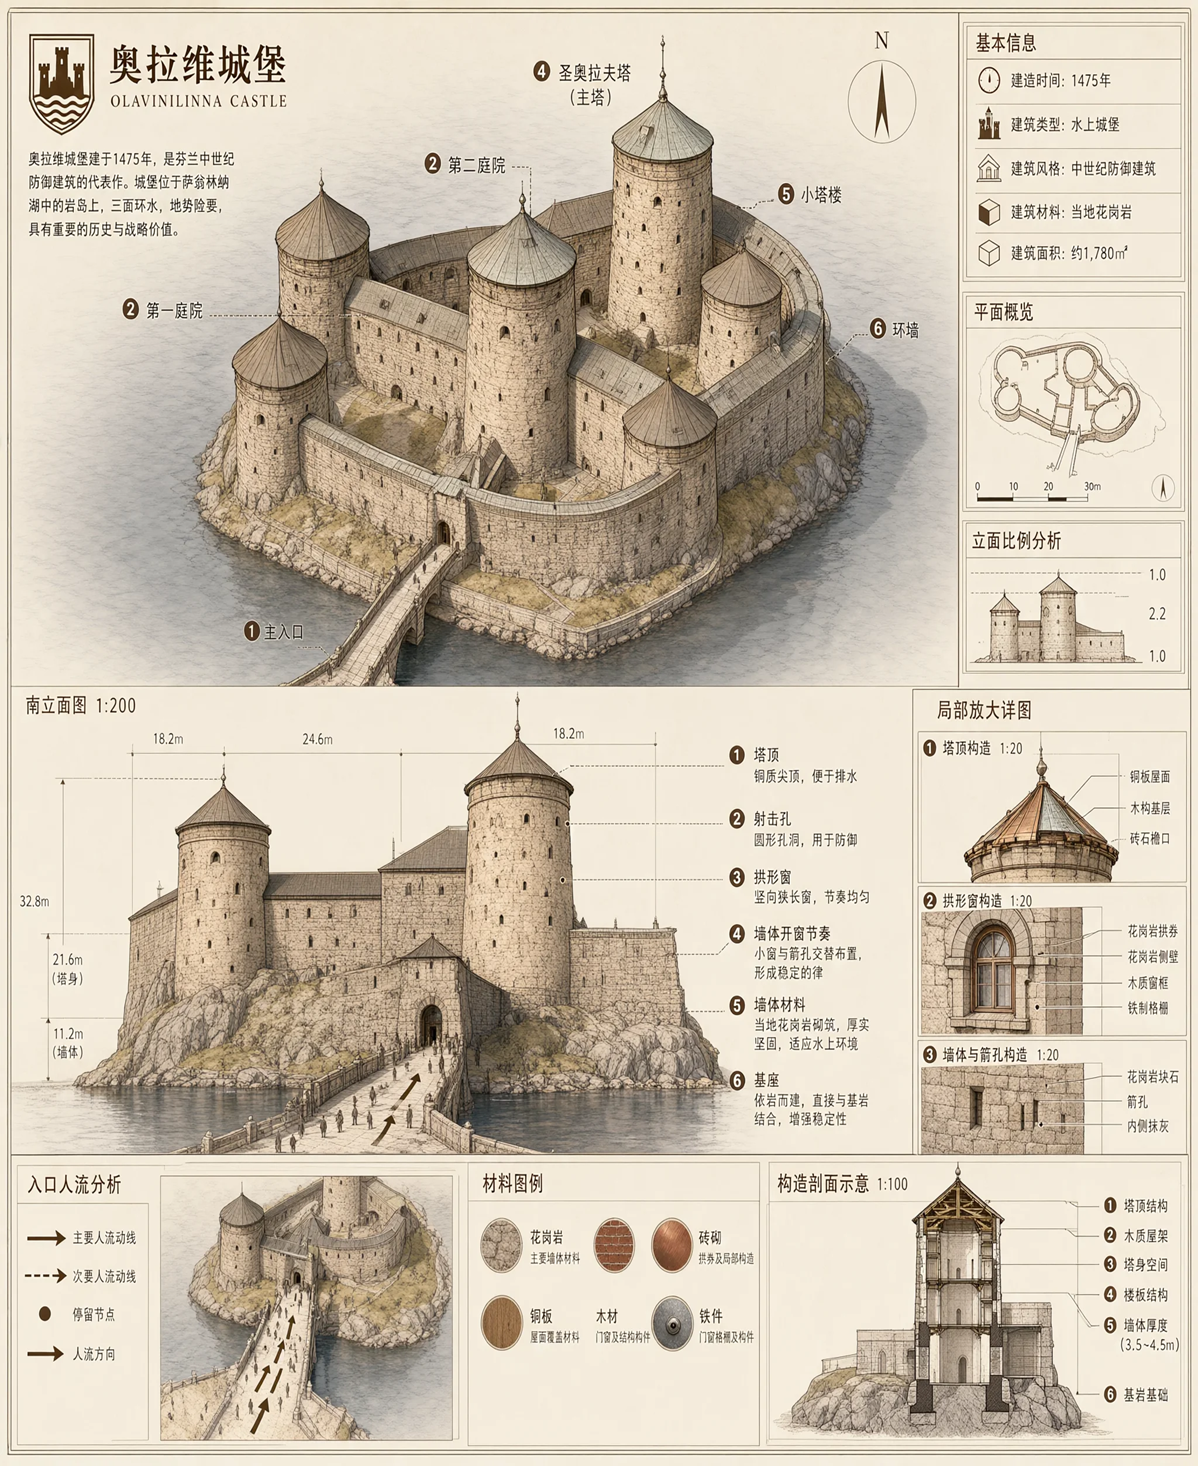
- Realistic Textures and Refined Aesthetics — Improved typography, portrait lighting, and fine details for more visually compelling results.
News
- 2026.09.20: We released Qwen-Image-2.1! Check our Blog for more details. Weights available at HuggingFace and ModelScope.
- 2026.09.20: Diffusers supports Qwen-Image-2.1 from Day 0 via
QwenImage21Pipeline. See PR #14804. - 2026.09.20: ComfyUI natively supports Qwen-Image-2.1 from Day 0. Compatible weights at Comfy-Org/Qwen-Image-2.1, with example workflows for text-to-image and image editing.
- 2026.09.20: vLLM-Omni supports high-performance Qwen-Image-2.1 inference from Day 0, with step-wise execution, prefix KV caching, CUDA Graph decode, FP8 quantization, and TP/Ulysses parallelism.
- 2026.09.20: SGLang provides Day-0 native support for Qwen-Image-2.1, including prefix caching, Cache-DiT, CUDA graphs, TP/Ulysses/Ring/CFG parallelism, and component offload. See PR #39983.
- 2026.09.20: LightX2V delivers Day 0 acceleration for Qwen-Image-2.1! Check out the usage guide for more details.
Quick Start
Requirements
pip install torch>=2.4.0
pip install transformers>=5.17
pip install git+https://github.com/huggingface/diffusers
pip install accelerate
pip install pillow
Text-to-Image
import torch
from diffusers import QwenImage21Pipeline

pipe = QwenImage21Pipeline.from_pretrained(
    "Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")

image = pipe(
    prompt="A neon shop sign that reads \"QWEN IMAGE 2.1\", rainy night, reflections on wet pavement",
    num_inference_steps=40,
    generator=torch.Generator("cuda").manual_seed(42),
).images[0]

image.save("t2i_example.png")
Image Editing (Single Image)
import torch
from PIL import Image
from diffusers import QwenImage21Pipeline

pipe = QwenImage21Pipeline.from_pretrained(
    "Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")

input_image = Image.open("input.png")

image = pipe(
    prompt="Change the background to a sunset beach",
    image=input_image,
    num_inference_steps=40,
    generator=torch.Generator("cuda").manual_seed(42),
).images[0]

image.save("edit_example.png")
Image Editing (Multiple Reference Images)
Qwen-Image-2.1 supports up to 10 reference images for multi-subject composition:
import torch
from PIL import Image
from diffusers import QwenImage21Pipeline

pipe = QwenImage21Pipeline.from_pretrained(
    "Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")

images = [Image.open(f"ref_{i}.png") for i in range(3)]

result = pipe(
    prompt="These three characters are sitting around a campfire in a forest",
    image=images,
    num_inference_steps=40,
    generator=torch.Generator("cuda").manual_seed(42),
).images[0]

result.save("multi_ref_example.png")
Transparent Image Generation (RGBA)
The model natively generates transparent images. For best results, use the recommended prompt format:
This is an RGBA image with transparency. <your description>. The image has alpha channel and the background is transparent.
import torch
from diffusers import QwenImage21Pipeline

pipe = QwenImage21Pipeline.from_pretrained(
    "Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")

image = pipe(
    prompt="This is an RGBA image with transparency. A cute cartoon dragon sticker. The image has alpha channel and the background is transparent.",
    num_inference_steps=40,
    generator=torch.Generator("cuda").manual_seed(42),
).images[0]

image.save("transparent_example.png")  # Saved as RGBA when the model generates transparency
Supported Aspect Ratios
Qwen-Image-2.1 natively supports 2K resolution. Recommended sizes:
aspect_ratios = {
    "1:1":  (2048, 2048),
    "4:3":  (2400, 1792),
    "3:4":  (1792, 2400),
    "3:2":  (2528, 1696),
    "2:3":  (1696, 2528),
    "16:9": (2752, 1536),
    "9:16": (1536, 2752),
}

width, height = aspect_ratios["1:1"]

image = pipe(
    prompt="A panoramic mountain landscape",
    width=width,
    height=height,
    num_inference_steps=40,
).images[0]
Default Parameters
| Parameter | Default | Notes |
|---|---|---|
num_inference_steps | 40 | Number of denoising steps |
width / height | 2048 × 2048 | Native 2K resolution; see aspect ratio table above |
Prompt Rewriting
For best results, we recommend using the official prompt rewriting models to expand short prompts into detailed, high-quality descriptions. Two fine-tuned Qwen3.5-VL 9B checkpoints are provided — one for text-to-image, one for image editing — sharing a unified codebase that auto-detects the mode from input.
The rewriting code and weights are available at:
- T2I: Qwen/Qwen-Image-2.1-PE-T2I
- Edit: Qwen/Qwen-Image-2.1-PE-I2I
- Code:
prompt_rewrite/— unified codebase with--task t2ior--task edit
prompt_rewrite/
├── run_transformers.py       # Local inference, batch size 1
├── run_vllm.py               # vLLM offline batch (recommended at scale)
├── serve.sh + client.py      # vLLM server + client
├── pe_core.py                # Task profiles, parsing, output records
├── requirements.txt
└── data/                     # Example inputs (t2i + edit with images)
Text-to-Image
cd prompt_rewrite
pip install -r requirements.txt

# vLLM batch (recommended)
python run_vllm.py --task t2i \
    --ckpt Qwen/Qwen-Image-2.1-PE-T2I \
    --input data/t2i_example.jsonl --output out.jsonl

# Or local transformers
python run_transformers.py --task t2i \
    --ckpt Qwen/Qwen-Image-2.1-PE-T2I \
    --input data/t2i_example.jsonl --output out.jsonl
Output:
{
  "rewritten_prompt": "<long detailed English prompt>",
  "wh_ratio": "16:9"
}
Image Editing
python run_vllm.py --task edit \
    --ckpt Qwen/Qwen-Image-2.1-PE-I2I \
    --input data/edit_example.jsonl --output out.jsonl
Input format (JSONL):
{"id": "abc123", "prompt": "make the sky sunset", "input_images": ["images/photo.png"]}
Output:
{
  "rewritten_prompt": "Replace the daytime sky with a warm sunset ...",
  "wh_ratio": "",
  "ratio_follow": "<image1>"
}
wh_ratio— model chose a new aspect ratio (e.g."16:9")ratio_follow— output inherits the specified input image's aspect ratio (e.g."<image1>")
vLLM Server
CKPT=Qwen/Qwen-Image-2.1-PE-T2I bash serve.sh
# then:
python client.py --task t2i --model Qwen/Qwen-Image-2.1-PE-T2I \
    "a corgi playing guitar in the rain"
Integration with the Pipeline
import json
import torch
from diffusers import QwenImage21Pipeline

WH_RATIO_TO_SIZE = {
    "1:1": (2048, 2048), "4:3": (2400, 1792), "3:4": (1792, 2400),
    "3:2": (2528, 1696), "2:3": (1696, 2528), "16:9": (2752, 1536),
    "9:16": (1536, 2752),
}

# After running the rewriter, read the output
rewrite = {"rewritten_prompt": "...", "wh_ratio": "16:9"}  # from run_vllm.py output
prompt = rewrite["rewritten_prompt"]
width, height = WH_RATIO_TO_SIZE.get(rewrite["wh_ratio"], (2048, 2048))

pipe = QwenImage21Pipeline.from_pretrained(
    "Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")

image = pipe(
    prompt=prompt,
    width=width, height=height,
    num_inference_steps=40,
    generator=torch.Generator("cuda").manual_seed(42),
).images[0]

image.save("rewritten_example.png")
Advanced Usage
Memory Optimization
For GPUs with limited memory, use model offloading:
pipe = QwenImage21Pipeline.from_pretrained(
    "Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
)
pipe.enable_model_cpu_offload()
Prefix KV Cache
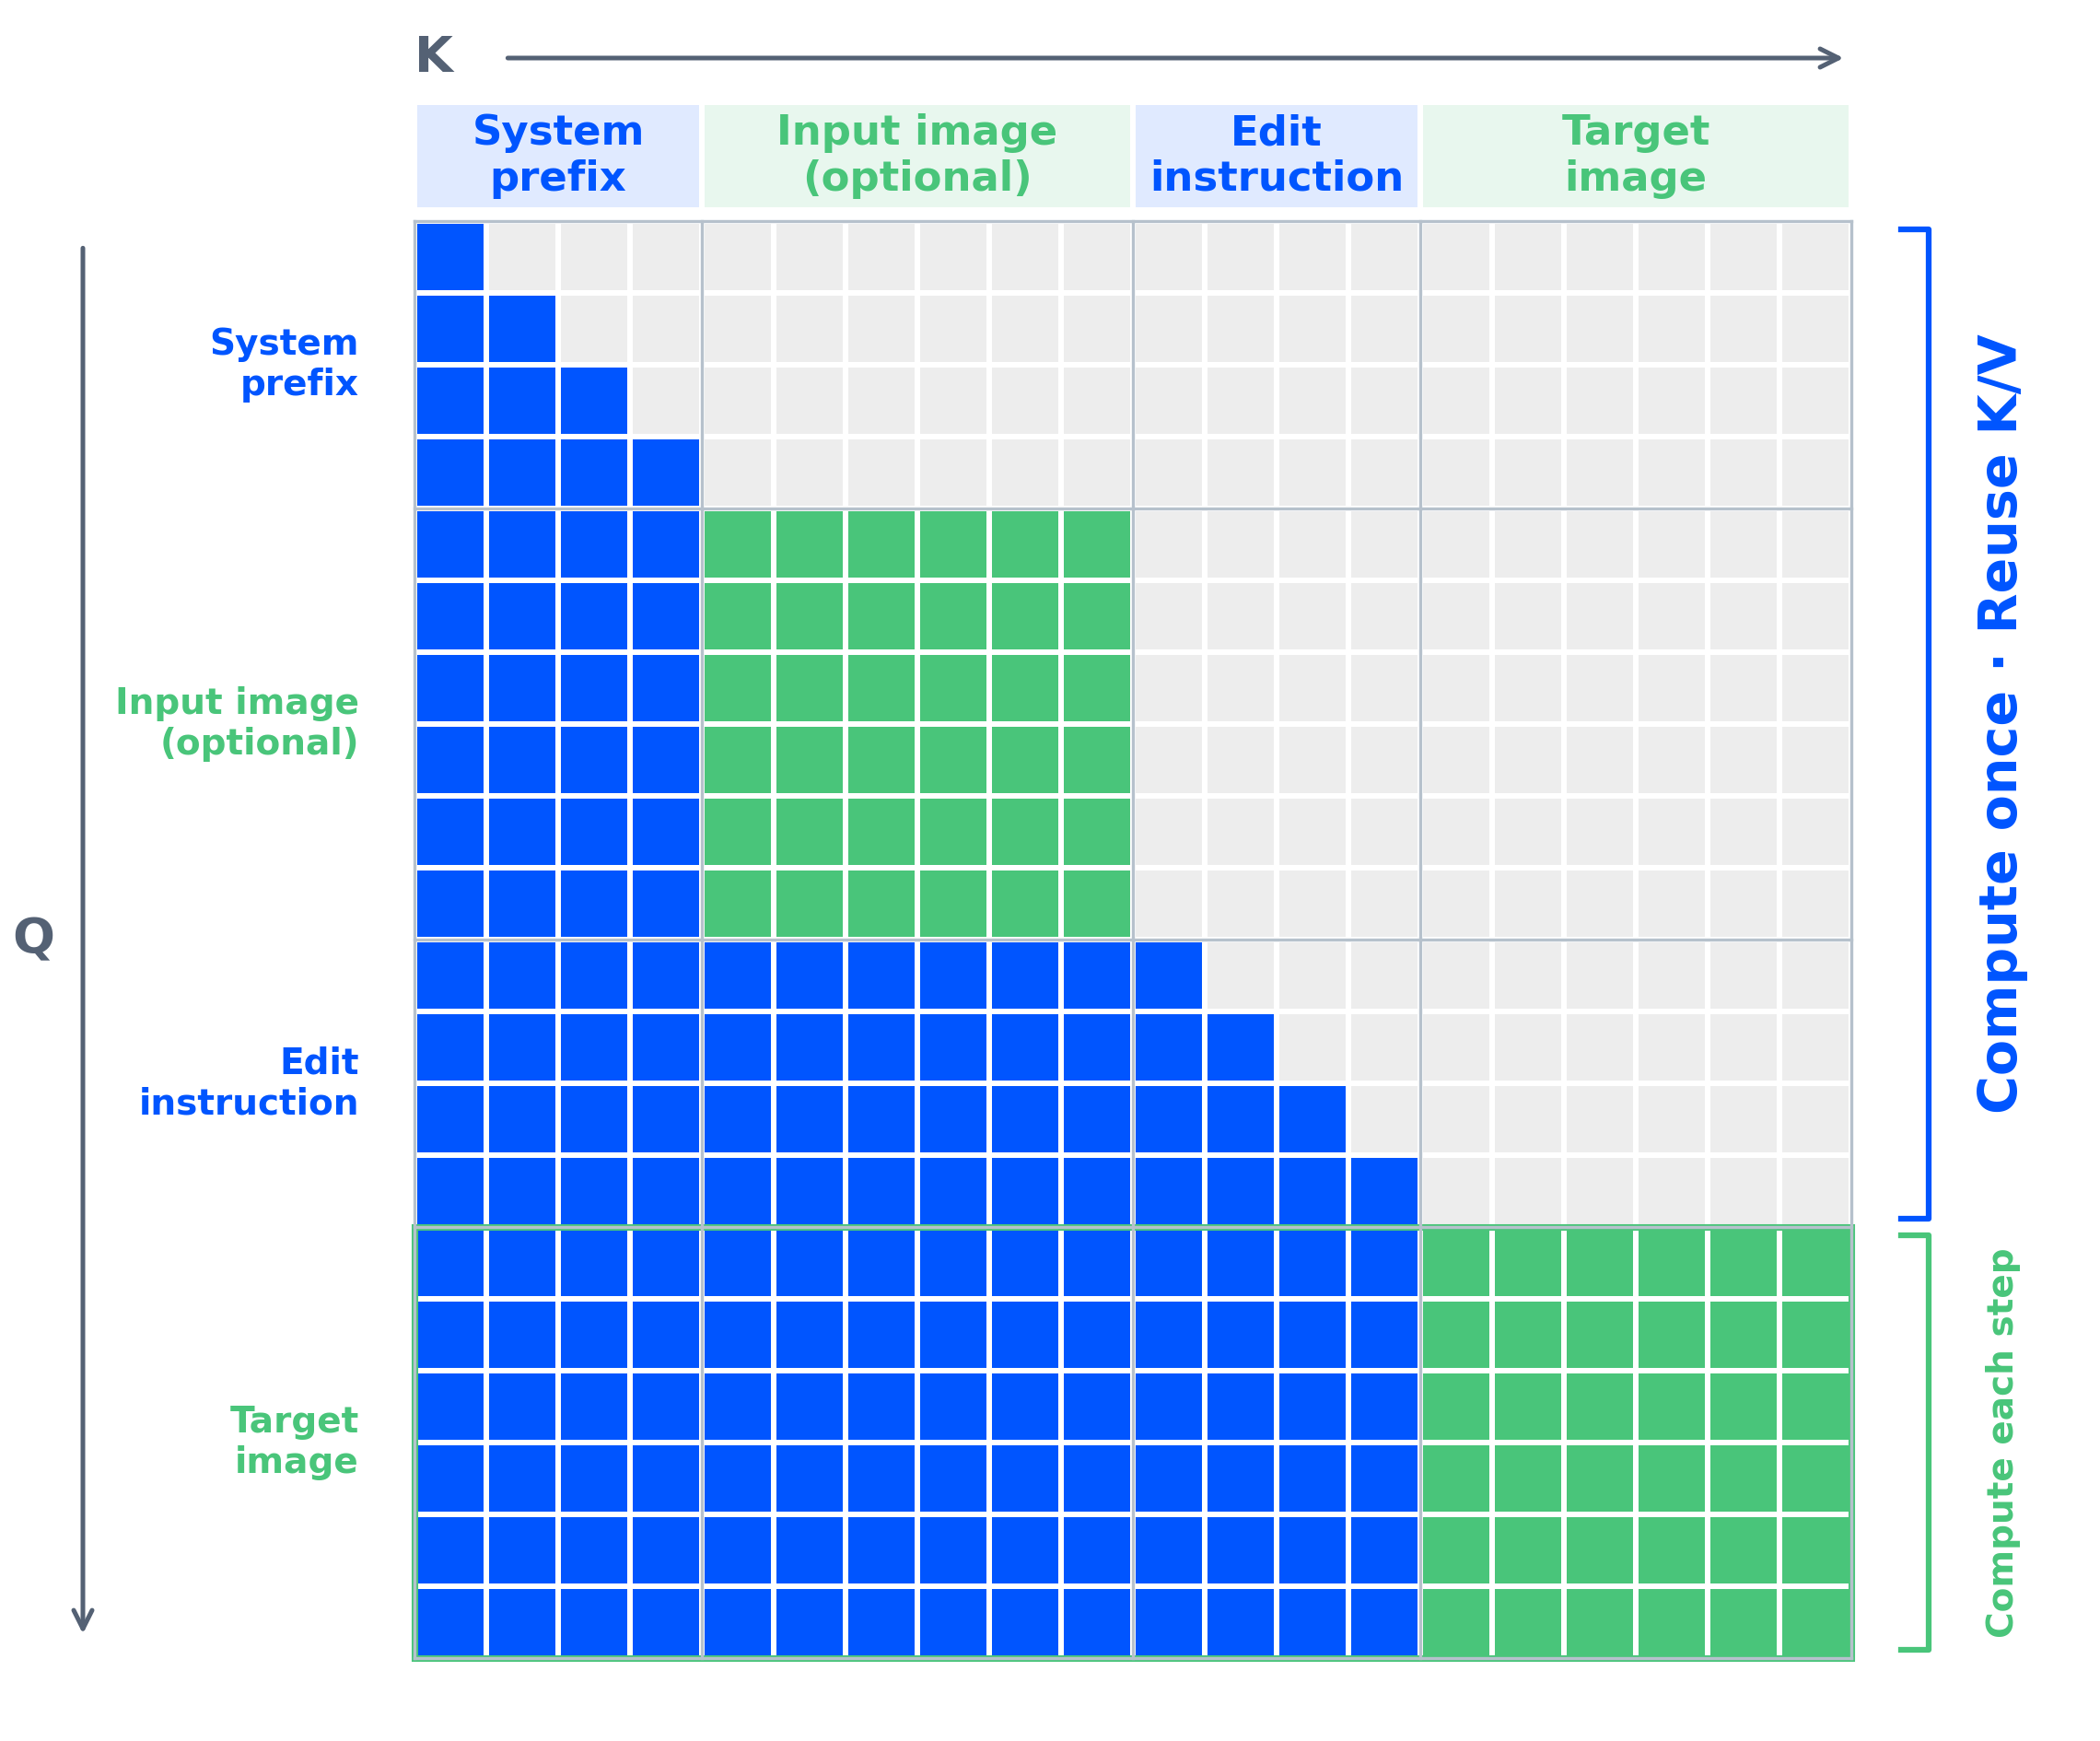
The transformer automatically caches the text and condition-image prefix across denoising steps when the checkpoint has causal_condition: true (the default). This provides significant speedup for image editing tasks with multiple condition images — the condition context is encoded once and reused for all denoising steps.
Inference with vLLM
vLLM-Omni supports high-performance serving with prefix KV caching, CUDA Graph decode, FP8 quantization, and tensor parallelism.
Offline Inference
# Text-to-image
python examples/offline_inference/text_to_image/text_to_image.py \
  --model Qwen/Qwen-Image-2.1 \
  --prompt "A ceramic teapot on a wooden table" \
  --output qwen21_t2i.png \
  --num-inference-steps 40

# Image editing
python examples/offline_inference/image_to_image/image_edit.py \
  --model Qwen/Qwen-Image-2.1 \
  --color-format RGBA \
  --seed 42 \
  --image input.png \
  --prompt "Let this mascot dance under the moon" \
  --output qwen21_edit.png \
  --num-inference-steps 40
Online Serving
vllm serve Qwen/Qwen-Image-2.1 --omni --port 8091
curl http://localhost:8091/v1/images/generations \
  -H "Content-Type: application/json" \
  -d '{
    "model": "Qwen/Qwen-Image-2.1",
    "prompt": "A ceramic teapot on a wooden table",
    "size": "1024x1024",
    "num_inference_steps": 40,
    "seed": 42
  }'
For step-wise execution (batch-level scheduling):
vllm serve Qwen/Qwen-Image-2.1 --omni \
  --port 8091 \
  --step-execution \
  --max-num-seqs 8
See the vLLM-Omni recipe for FP8 quantization, prefix KV cache options, multi-GPU parallelism, and detailed benchmarks.
Inference with SGLang
SGLang-Diffusion provides native, high-performance inference for Qwen-Image 2.1, supporting text-to-image generation, multi-image editing, and transparent RGBA output. It offers multi-GPU parallelism, memory offloading, and optimized kernels across datacenter and consumer GPUs.
Generate a 1024×1024 image:
sglang generate \
  --model-path Qwen/Qwen-Image-2.1 \
  --prompt "A capybara reading a book by candlelight" \
  --height 1024 --width 1024 \
  --num-inference-steps 40 --guidance-scale 1 \
  --seed 42 --save-output
For image editing, add --image-path input.png. See the Qwen-Image 2.1 cookbook for installation, GPU-specific commands, image editing, and transparent-background examples.
Inference with LightX2V
LightX2V is a framework for image and video generation models, highly optimized for inference speed and GPU memory efficiency on both data center and consumer GPUs.
LightX2V supports Qwen-Image-2.1 for both text-to-image generation and image editing. See the usage guide to get started.
Architecture
Qwen-Image-2.1 is a single-stream DiT with the following design:
- Transformer: 32 layers, 7B parameters, single-stream architecture with block-causal attention (
(q_idx >= kv_idx) or same_image_block). Text uses token-level causal mask; images use chunk-level bidirectional mask. - Text Encoder: Qwen3-VL 8B (vision-language model) — encodes both text instructions and condition images into a unified representation.
- VAE: 64-channel RGBA autoencoder with 16× spatial compression, supporting native transparency.
- Scheduler: Flow Matching with Euler discrete scheduling and dynamic shifting.
The mixed-granularity attention architecture enables efficient prefix KV cache reuse: input images and text instructions are computed once at the first denoising step and cached for all subsequent steps.
Showcase
Native Transparency
Multi-Reference Editing
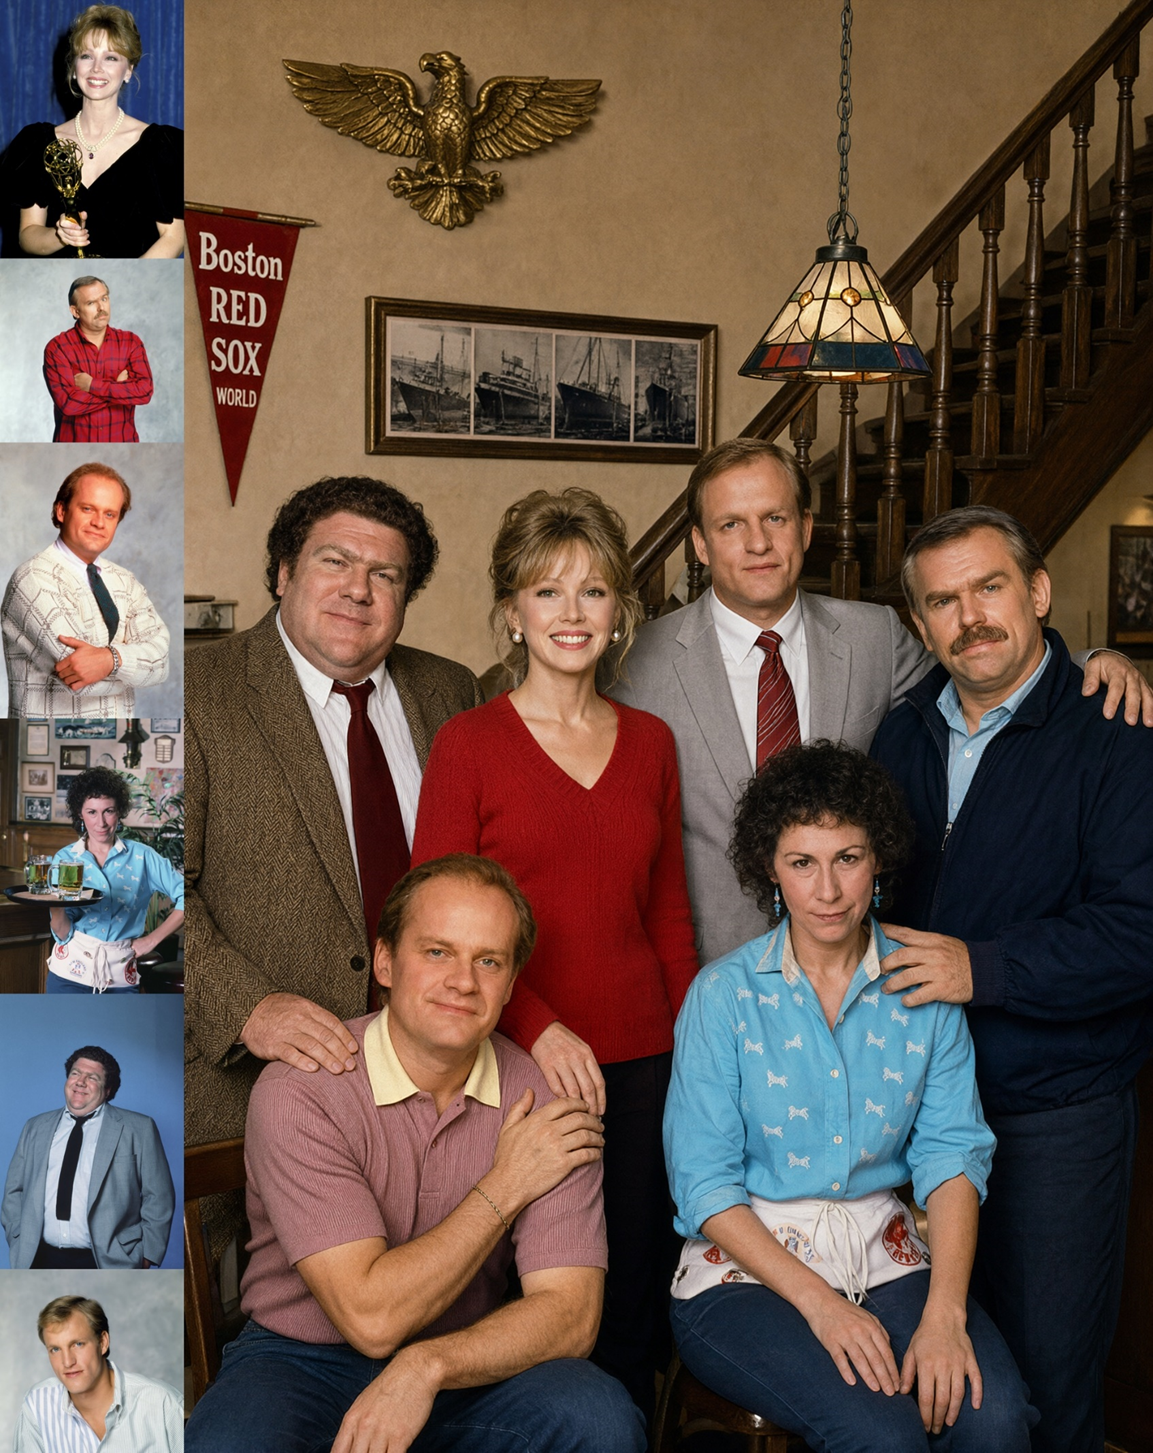
Group photograph generated from six individual portrait references
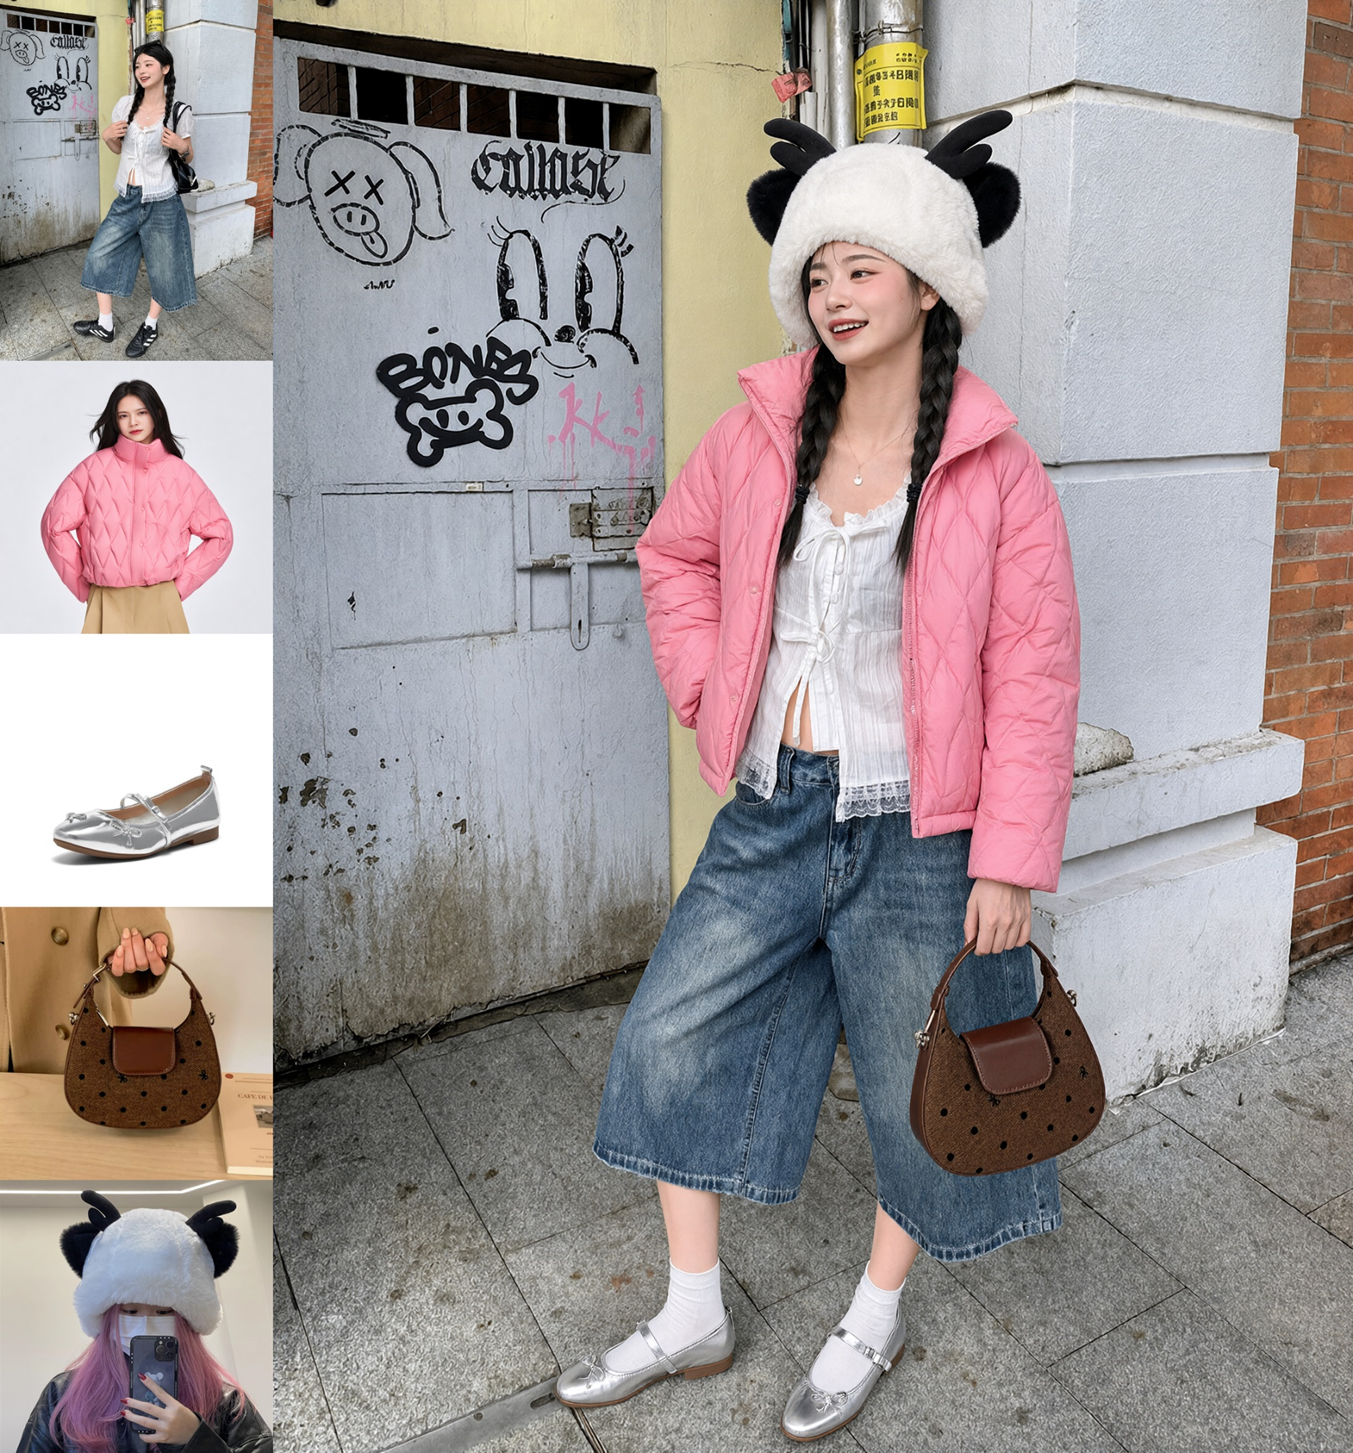
Complete outfit assembled from five reference images (model, clothing, shoes, bag, hat)
Local Editing
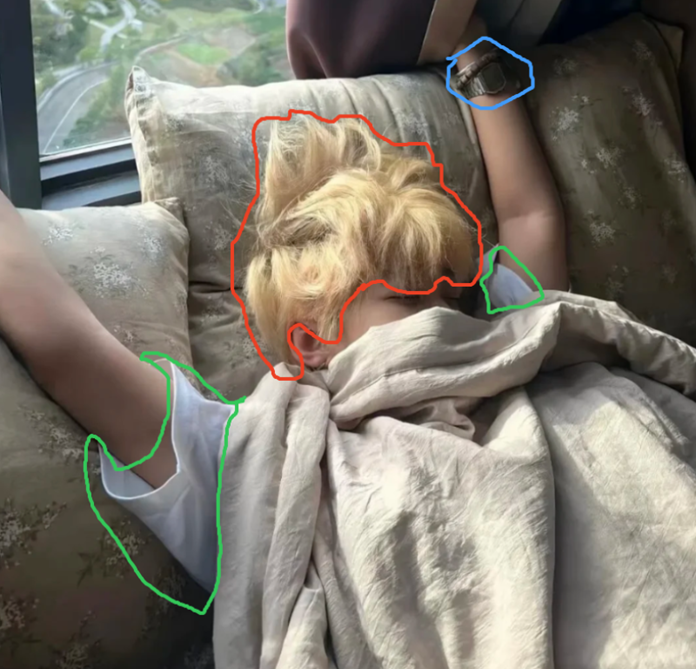
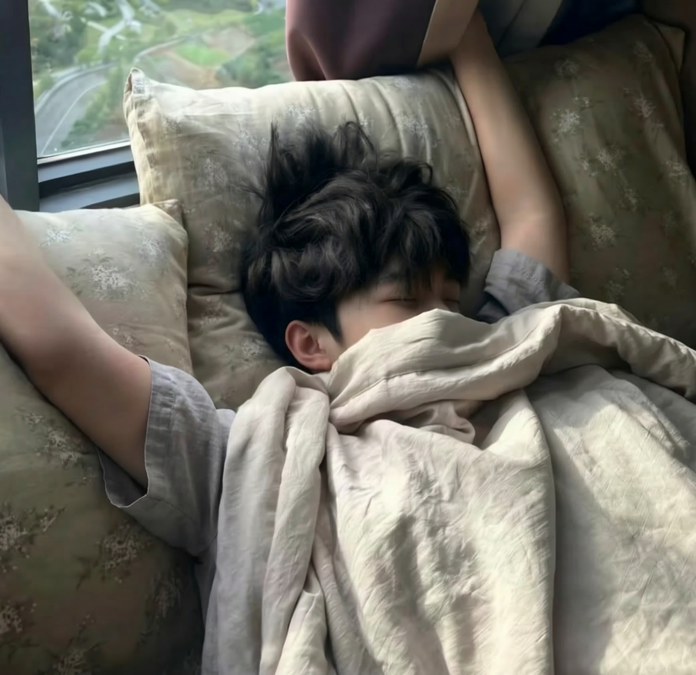
Circle-guided multi-region editing: remove watch, change hair color, replace clothing
Portrait and Product Fidelity
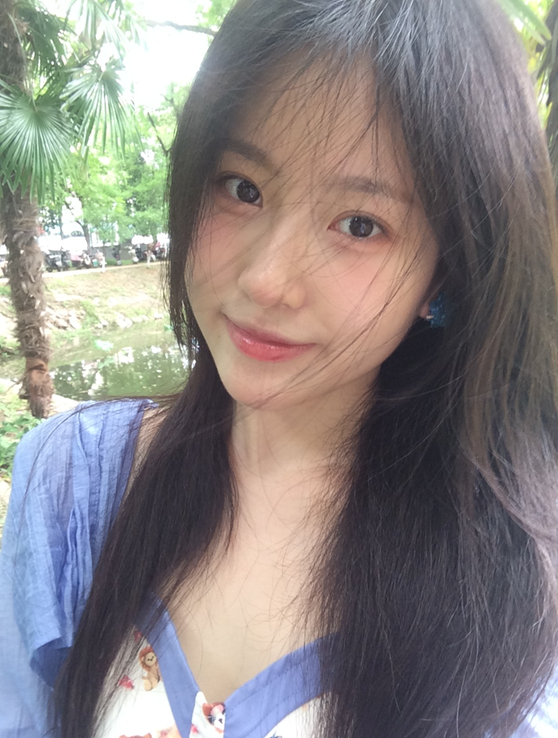
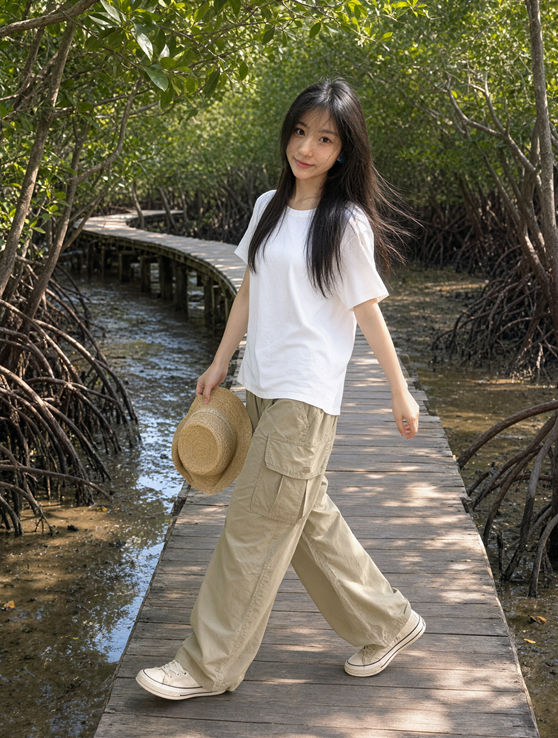
Text Rendering
Panorama and Storyboard
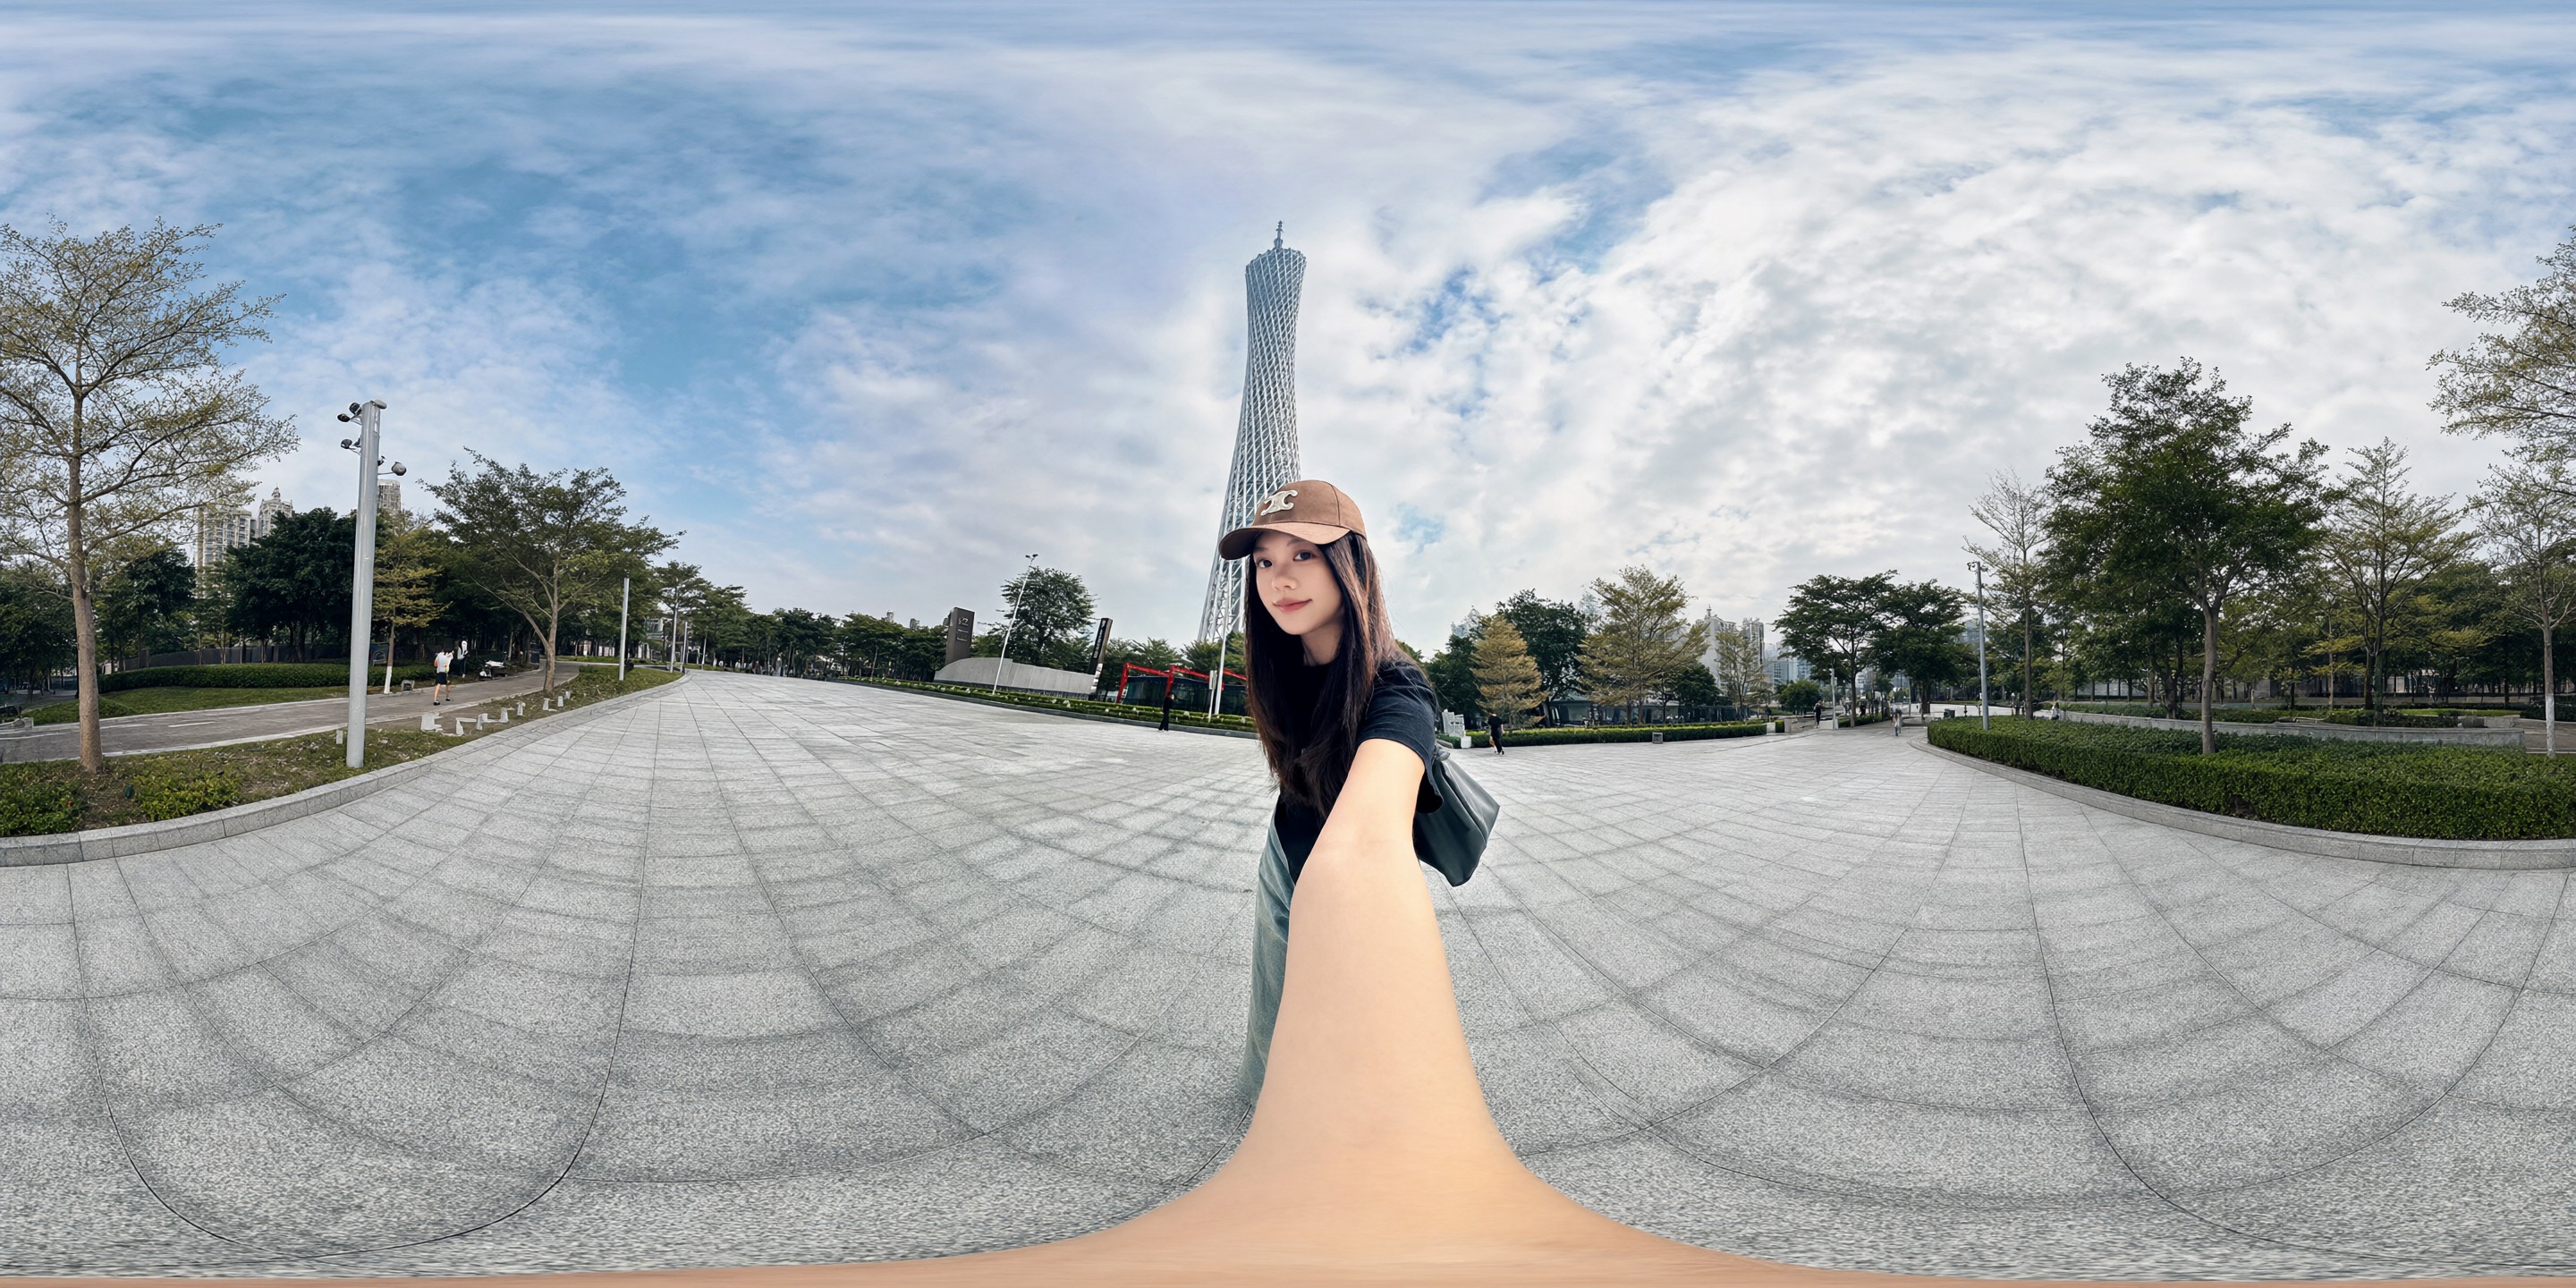
Panorama generated from a selfie
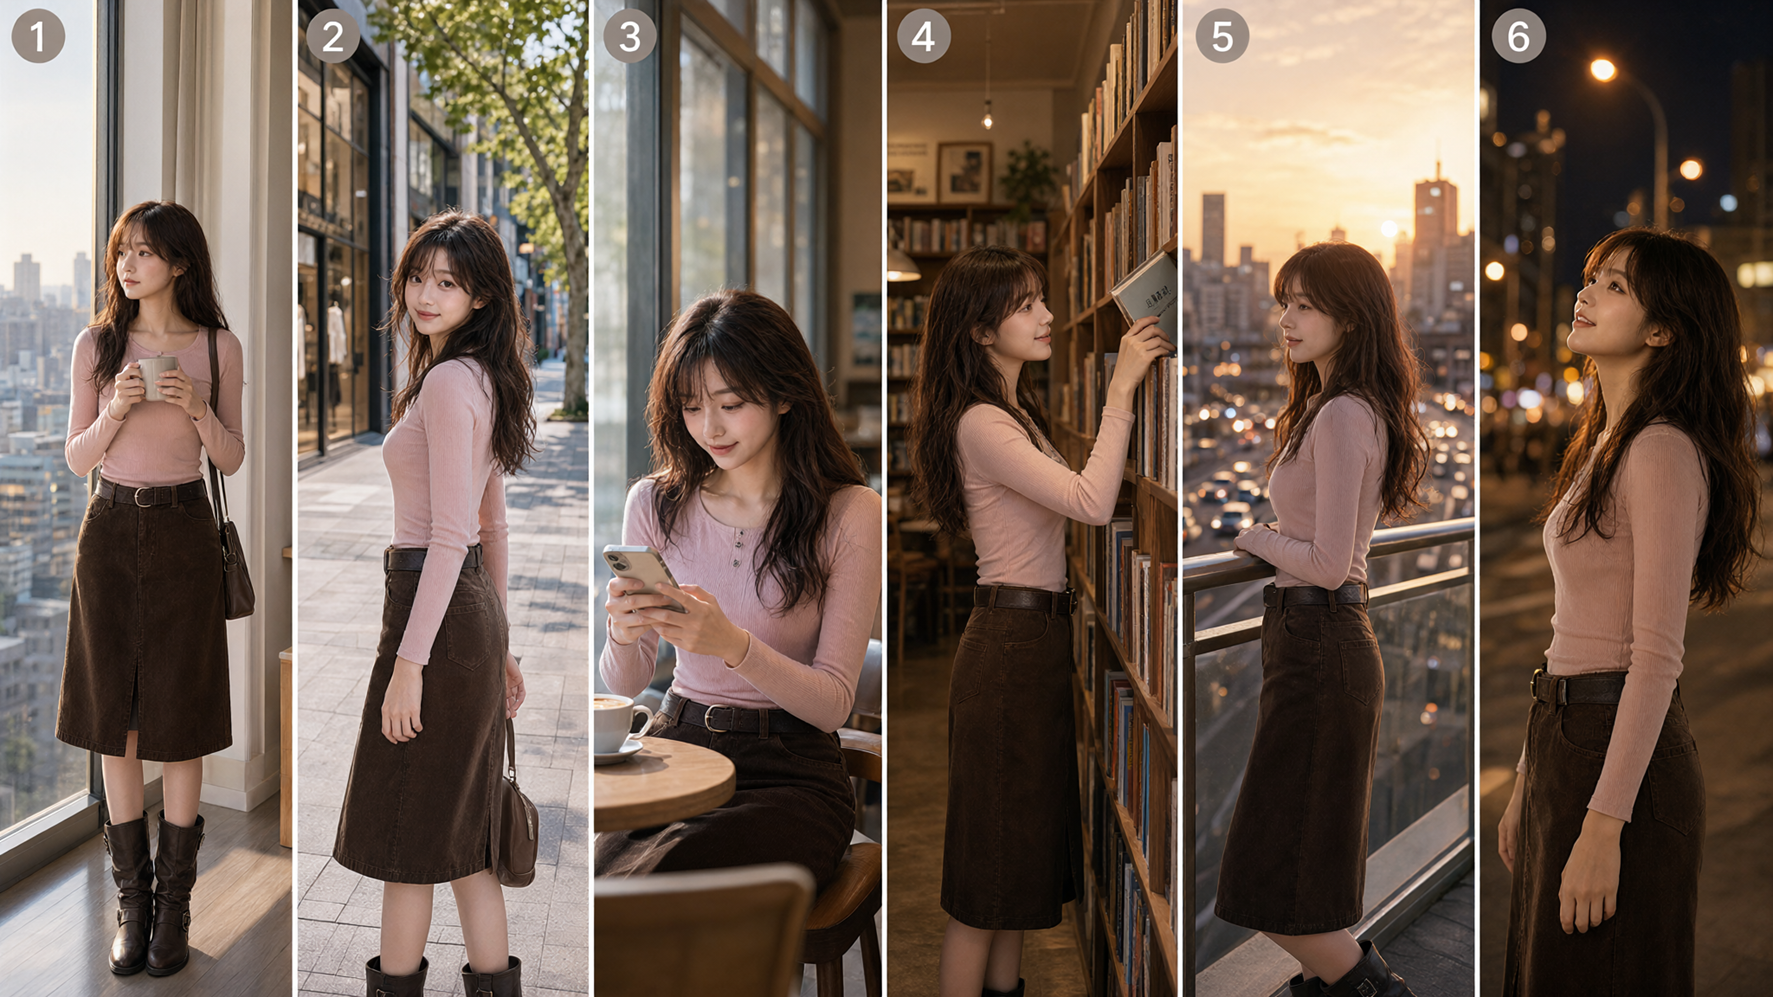
Storyboard generated from a three-view character reference
Community Support
Diffusers (Recommended)
Diffusers supports Qwen-Image-2.1 via QwenImage21Pipeline, handling both text-to-image and image-conditioned generation in a single pipeline. See PR #14804.
ComfyUI
Qwen-Image 2.1 is natively supported in ComfyUI on Day 0. The compatible model weights can be downloaded from Hugging Face Comfy-Org/Qwen-Image-2.1. See example workflows for text-to-image and image editing.
vLLM-Omni
vLLM-Omni accelerates Qwen-Image 2.1 through cross-step prefix KV cache reuse and dedicated CUDA Graphs, reducing redundant computation and kernel launch overhead. Request-level and step-level continuous batching improve GPU utilization and throughput, with phase-aware prefill and decode scheduling. It also supports tensor and Ulysses sequence parallelism, distributed VAE decoding with adaptive OOM recovery, FP8 weights and prefix KV storage, and CPU offloading for varying memory budgets. See the Qwen-Image-2.1 recipe for details.
SGLang
SGLang-Diffusion provides native, high-performance inference with multi-GPU parallelism, memory offloading, and optimized kernels. See the Qwen-Image 2.1 cookbook and PR #39983.
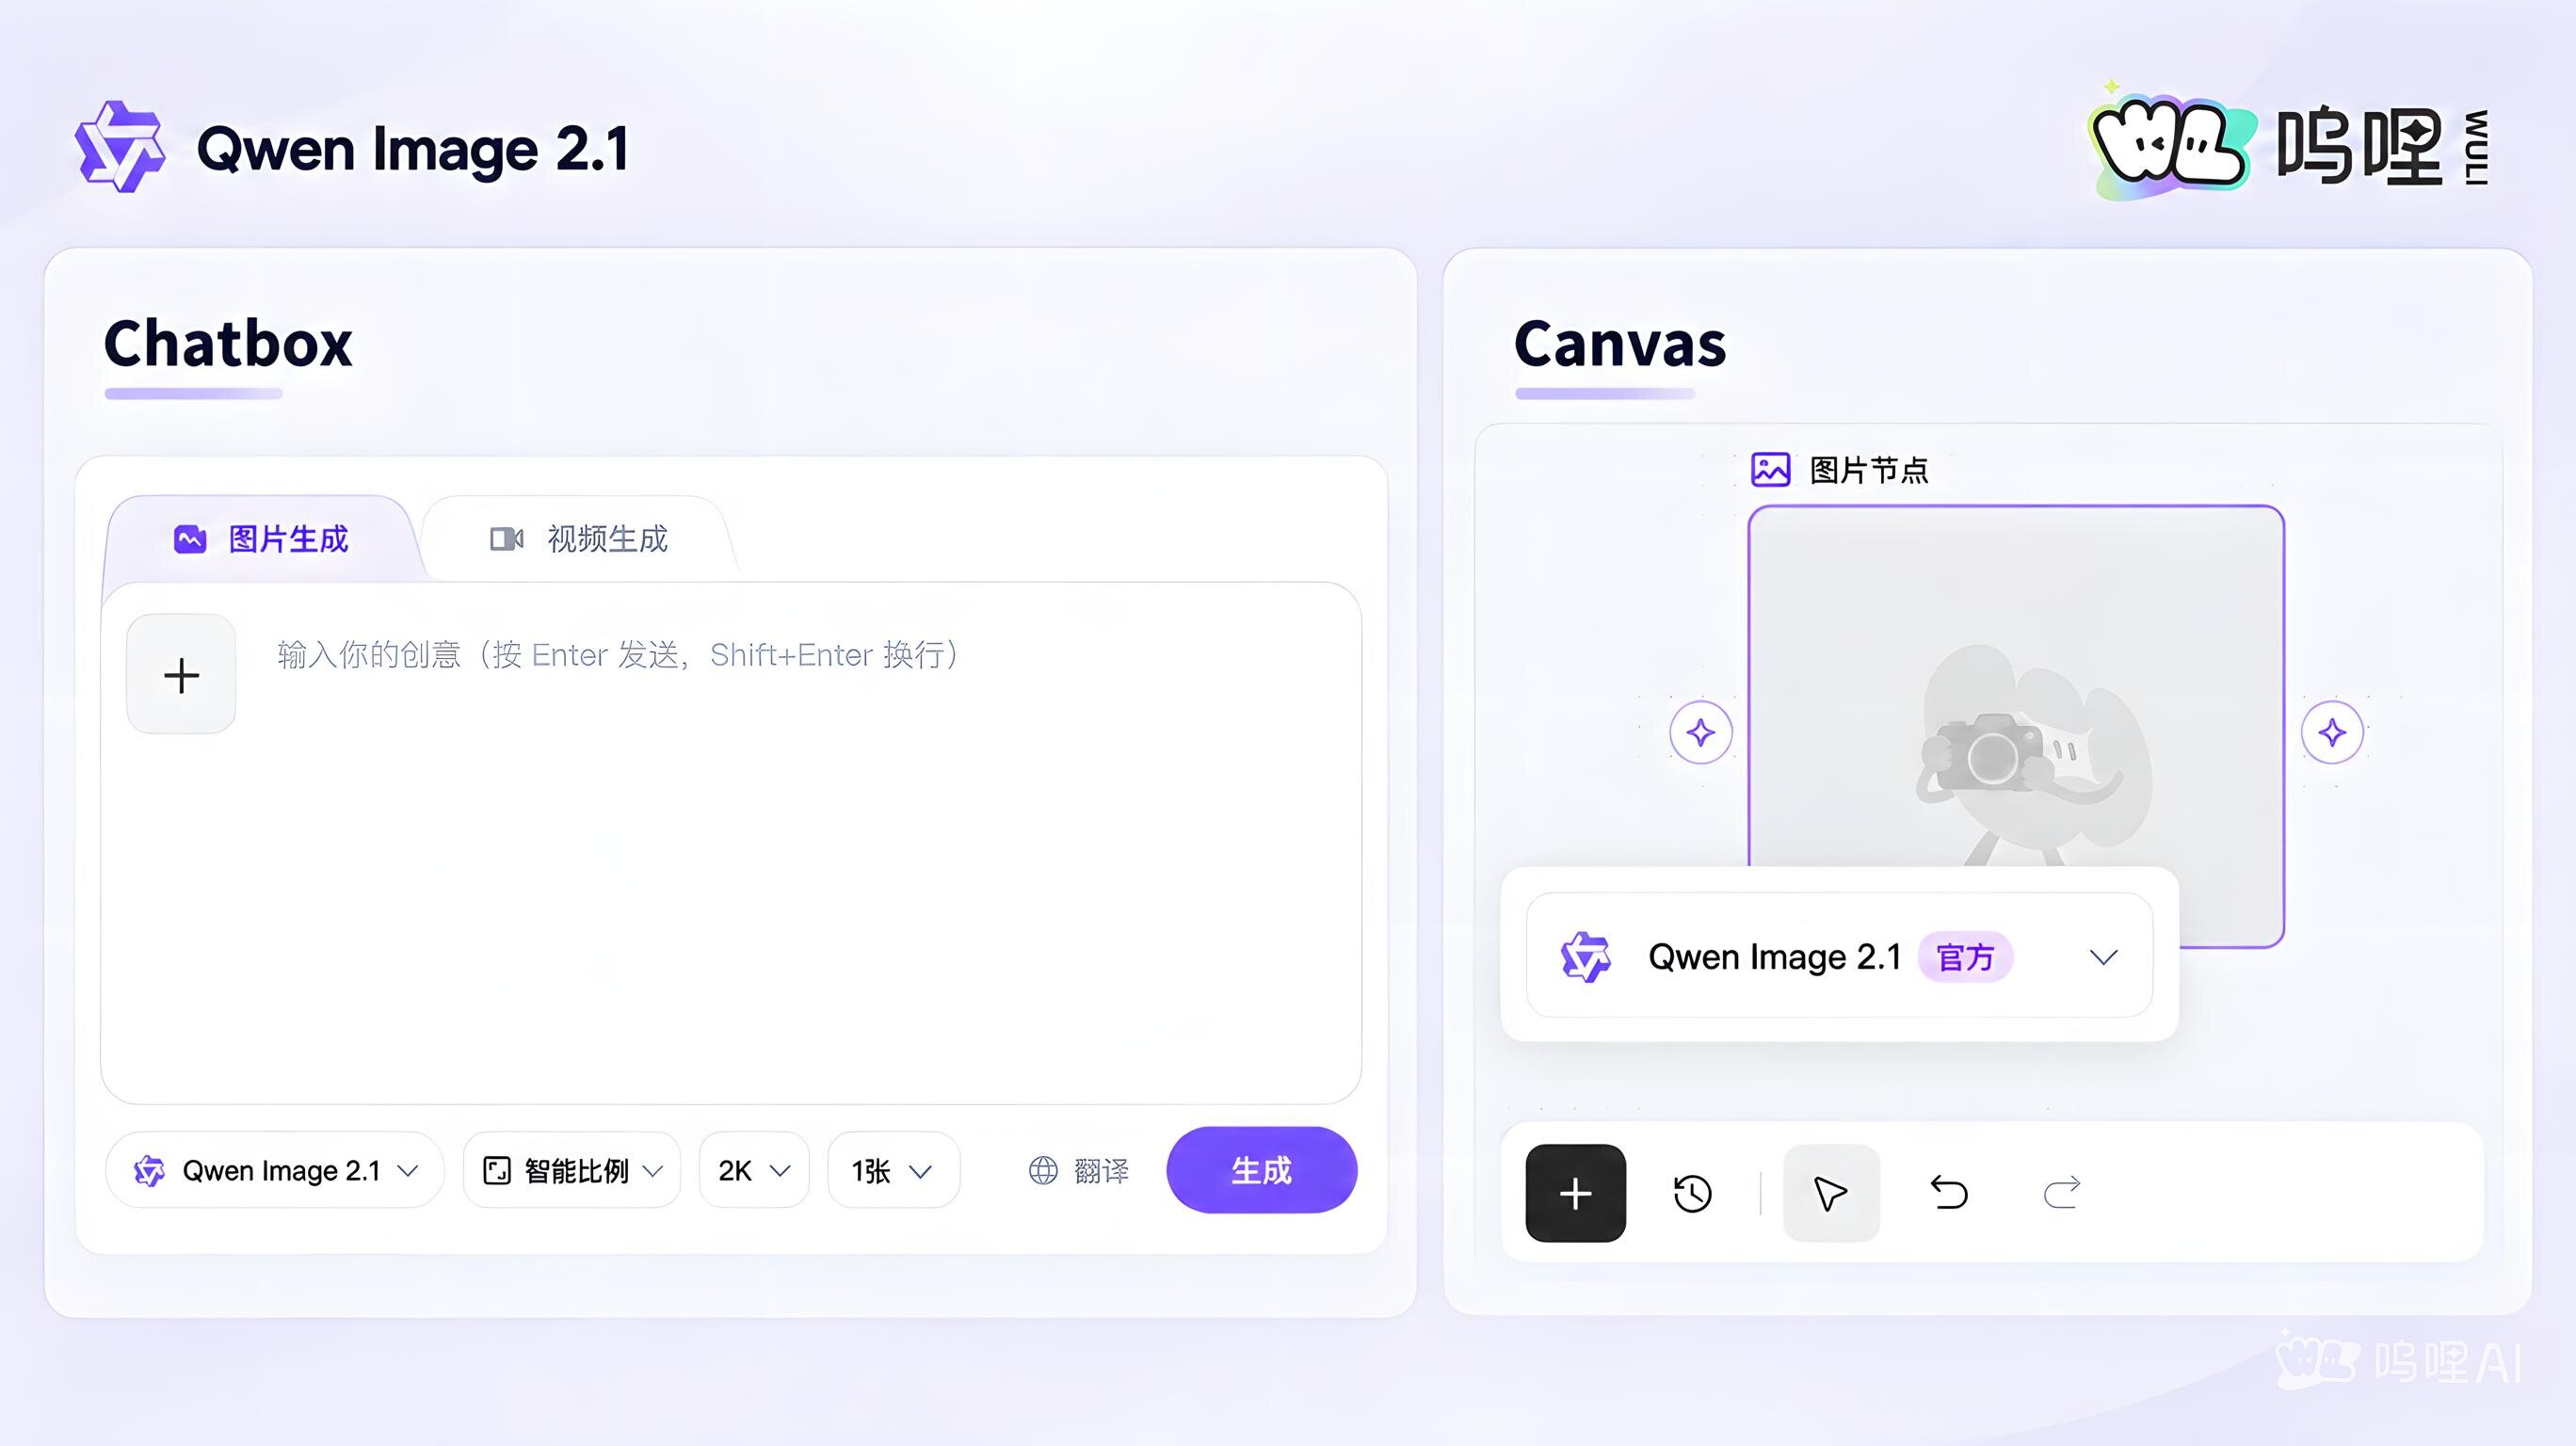
Wuli.art
For users in mainland China, wuli.art offers free access to all Qwen Image 2.1 features in both Chatbox and Canvas, including image generations with transparent background.
ModelScope
ModelScope fully supports Qwen-Image-2.1. Built on its open-source DiffSynth-Studio framework, the platform enables seamless model download, online generation and LoRA training. Explore these capabilities at ModelScope Civision.
Hardware Support
AMD Radeon GPU
Get ready to run Qwen-Image 2.1 on AMD Radeon GPU. With ROCm, PyTorch, and Diffusers, developers can easily explore high-quality text-to-image generation on AMD GPUs.
Diverse AI Chips via FlagOS
FlagOS is a fully open-source system software stack for heterogeneous AI chips. It unifies the model–system–chip layers to enable a "develop once, run anywhere" workflow, eliminating the fragmentation among vendor-specific software stacks and substantially lowering the cost of porting AI workloads across accelerators.
In this release, Qwen-Image-2.1 leverages the FlagOS software stack to provide direct multi-chip support. By integrating the Triton-based operator library FlagGems via the Torch-FL plugin, FlagOS enables seamless adaptation of the Diffusers library across chip platforms; the usage experience remains identical to that on NVIDIA, requiring zero code modifications. Inference accuracy across all platforms has been aligned with the official implementation.
Prebuilt images and weights for 8 chip platforms are released under FlagRelease — for example, T-Head zhenwu and Arm.
License Agreement
This repository is licensed under the Qwen Research License Agreement.
Contact and Join Us
If you'd like to get in touch with our research team, join our Discord. We welcome issues and pull requests on GitHub.
If you're passionate about fundamental research, we're hiring full-time employees and research interns. Reach out at fulai.hr@alibaba-inc.com.
Star History
Contributors

22 commits

1 commits
Similar repos


Languages
Python
91.5%
Shell
8.5%
Qwen's most powerful open-source image generation model
Python
51
23 commits
updated Sep 20, 2026
See what people are saying (2)
README
🤖 ModelScope | 🤗 HuggingFace | 📑 Blog | 🖥️ Demo | 🫨 Discord
Introduction
We are excited to open-source Qwen-Image-2.1, a unified text-to-image generation and image editing model in the Qwen family. With just 7B parameters in its visual generation component (32 Single-Stream DiT layers), Qwen-Image-2.1 balances generation quality, inference efficiency, and versatility.
Four key improvements define this release:
- Compact and Efficient — A lightweight architecture with mixed-granularity attention and prefix KV cache reuse delivers strong image quality at low computational cost.
- Native Transparency, Unified Creation and Editing — Generate regular or transparent (RGBA) images from text, edit transparent layers, and extract subjects from photographs—all in one model.
- Versatile Editing — Support up to 10 reference images, specify local edits via circles, painted annotations, or separate masks, and preserve identity for people and products.
- Realistic Textures and Refined Aesthetics — Improved typography, portrait lighting, and fine details for more visually compelling results.
News
- 2026.09.20: We released Qwen-Image-2.1! Check our Blog for more details. Weights available at HuggingFace and ModelScope.
- 2026.09.20: Diffusers supports Qwen-Image-2.1 from Day 0 via
QwenImage21Pipeline. See PR #14804. - 2026.09.20: ComfyUI natively supports Qwen-Image-2.1 from Day 0. Compatible weights at Comfy-Org/Qwen-Image-2.1, with example workflows for text-to-image and image editing.
- 2026.09.20: vLLM-Omni supports high-performance Qwen-Image-2.1 inference from Day 0, with step-wise execution, prefix KV caching, CUDA Graph decode, FP8 quantization, and TP/Ulysses parallelism.
- 2026.09.20: SGLang provides Day-0 native support for Qwen-Image-2.1, including prefix caching, Cache-DiT, CUDA graphs, TP/Ulysses/Ring/CFG parallelism, and component offload. See PR #39983.
- 2026.09.20: LightX2V delivers Day 0 acceleration for Qwen-Image-2.1! Check out the usage guide for more details.
Quick Start
Requirements
pip install torch>=2.4.0
pip install transformers>=5.17
pip install git+https://github.com/huggingface/diffusers
pip install accelerate
pip install pillow
Text-to-Image
import torch
from diffusers import QwenImage21Pipeline

pipe = QwenImage21Pipeline.from_pretrained(
    "Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")

image = pipe(
    prompt="A neon shop sign that reads \"QWEN IMAGE 2.1\", rainy night, reflections on wet pavement",
    num_inference_steps=40,
    generator=torch.Generator("cuda").manual_seed(42),
).images[0]

image.save("t2i_example.png")
Image Editing (Single Image)
import torch
from PIL import Image
from diffusers import QwenImage21Pipeline

pipe = QwenImage21Pipeline.from_pretrained(
    "Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")

input_image = Image.open("input.png")

image = pipe(
    prompt="Change the background to a sunset beach",
    image=input_image,
    num_inference_steps=40,
    generator=torch.Generator("cuda").manual_seed(42),
).images[0]

image.save("edit_example.png")
Image Editing (Multiple Reference Images)
Qwen-Image-2.1 supports up to 10 reference images for multi-subject composition:
import torch
from PIL import Image
from diffusers import QwenImage21Pipeline

pipe = QwenImage21Pipeline.from_pretrained(
    "Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")

images = [Image.open(f"ref_{i}.png") for i in range(3)]

result = pipe(
    prompt="These three characters are sitting around a campfire in a forest",
    image=images,
    num_inference_steps=40,
    generator=torch.Generator("cuda").manual_seed(42),
).images[0]

result.save("multi_ref_example.png")
Transparent Image Generation (RGBA)
The model natively generates transparent images. For best results, use the recommended prompt format:
This is an RGBA image with transparency. <your description>. The image has alpha channel and the background is transparent.
import torch
from diffusers import QwenImage21Pipeline

pipe = QwenImage21Pipeline.from_pretrained(
    "Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")

image = pipe(
    prompt="This is an RGBA image with transparency. A cute cartoon dragon sticker. The image has alpha channel and the background is transparent.",
    num_inference_steps=40,
    generator=torch.Generator("cuda").manual_seed(42),
).images[0]

image.save("transparent_example.png")  # Saved as RGBA when the model generates transparency
Supported Aspect Ratios
Qwen-Image-2.1 natively supports 2K resolution. Recommended sizes:
aspect_ratios = {
    "1:1":  (2048, 2048),
    "4:3":  (2400, 1792),
    "3:4":  (1792, 2400),
    "3:2":  (2528, 1696),
    "2:3":  (1696, 2528),
    "16:9": (2752, 1536),
    "9:16": (1536, 2752),
}

width, height = aspect_ratios["1:1"]

image = pipe(
    prompt="A panoramic mountain landscape",
    width=width,
    height=height,
    num_inference_steps=40,
).images[0]
Default Parameters
| Parameter | Default | Notes |
|---|---|---|
num_inference_steps | 40 | Number of denoising steps |
width / height | 2048 × 2048 | Native 2K resolution; see aspect ratio table above |
Prompt Rewriting
For best results, we recommend using the official prompt rewriting models to expand short prompts into detailed, high-quality descriptions. Two fine-tuned Qwen3.5-VL 9B checkpoints are provided — one for text-to-image, one for image editing — sharing a unified codebase that auto-detects the mode from input.
The rewriting code and weights are available at:
- T2I: Qwen/Qwen-Image-2.1-PE-T2I
- Edit: Qwen/Qwen-Image-2.1-PE-I2I
- Code:
prompt_rewrite/— unified codebase with--task t2ior--task edit
prompt_rewrite/
├── run_transformers.py       # Local inference, batch size 1
├── run_vllm.py               # vLLM offline batch (recommended at scale)
├── serve.sh + client.py      # vLLM server + client
├── pe_core.py                # Task profiles, parsing, output records
├── requirements.txt
└── data/                     # Example inputs (t2i + edit with images)
Text-to-Image
cd prompt_rewrite
pip install -r requirements.txt

# vLLM batch (recommended)
python run_vllm.py --task t2i \
    --ckpt Qwen/Qwen-Image-2.1-PE-T2I \
    --input data/t2i_example.jsonl --output out.jsonl

# Or local transformers
python run_transformers.py --task t2i \
    --ckpt Qwen/Qwen-Image-2.1-PE-T2I \
    --input data/t2i_example.jsonl --output out.jsonl
Output:
{
  "rewritten_prompt": "<long detailed English prompt>",
  "wh_ratio": "16:9"
}
Image Editing
python run_vllm.py --task edit \
    --ckpt Qwen/Qwen-Image-2.1-PE-I2I \
    --input data/edit_example.jsonl --output out.jsonl
Input format (JSONL):
{"id": "abc123", "prompt": "make the sky sunset", "input_images": ["images/photo.png"]}
Output:
{
  "rewritten_prompt": "Replace the daytime sky with a warm sunset ...",
  "wh_ratio": "",
  "ratio_follow": "<image1>"
}
wh_ratio— model chose a new aspect ratio (e.g."16:9")ratio_follow— output inherits the specified input image's aspect ratio (e.g."<image1>")
vLLM Server
CKPT=Qwen/Qwen-Image-2.1-PE-T2I bash serve.sh
# then:
python client.py --task t2i --model Qwen/Qwen-Image-2.1-PE-T2I \
    "a corgi playing guitar in the rain"
Integration with the Pipeline
import json
import torch
from diffusers import QwenImage21Pipeline

WH_RATIO_TO_SIZE = {
    "1:1": (2048, 2048), "4:3": (2400, 1792), "3:4": (1792, 2400),
    "3:2": (2528, 1696), "2:3": (1696, 2528), "16:9": (2752, 1536),
    "9:16": (1536, 2752),
}

# After running the rewriter, read the output
rewrite = {"rewritten_prompt": "...", "wh_ratio": "16:9"}  # from run_vllm.py output
prompt = rewrite["rewritten_prompt"]
width, height = WH_RATIO_TO_SIZE.get(rewrite["wh_ratio"], (2048, 2048))

pipe = QwenImage21Pipeline.from_pretrained(
    "Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")

image = pipe(
    prompt=prompt,
    width=width, height=height,
    num_inference_steps=40,
    generator=torch.Generator("cuda").manual_seed(42),
).images[0]

image.save("rewritten_example.png")
Advanced Usage
Memory Optimization
For GPUs with limited memory, use model offloading:
pipe = QwenImage21Pipeline.from_pretrained(
    "Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
)
pipe.enable_model_cpu_offload()
Prefix KV Cache
The transformer automatically caches the text and condition-image prefix across denoising steps when the checkpoint has causal_condition: true (the default). This provides significant speedup for image editing tasks with multiple condition images — the condition context is encoded once and reused for all denoising steps.
Inference with vLLM
vLLM-Omni supports high-performance serving with prefix KV caching, CUDA Graph decode, FP8 quantization, and tensor parallelism.
Offline Inference
# Text-to-image
python examples/offline_inference/text_to_image/text_to_image.py \
  --model Qwen/Qwen-Image-2.1 \
  --prompt "A ceramic teapot on a wooden table" \
  --output qwen21_t2i.png \
  --num-inference-steps 40

# Image editing
python examples/offline_inference/image_to_image/image_edit.py \
  --model Qwen/Qwen-Image-2.1 \
  --color-format RGBA \
  --seed 42 \
  --image input.png \
  --prompt "Let this mascot dance under the moon" \
  --output qwen21_edit.png \
  --num-inference-steps 40
Online Serving
vllm serve Qwen/Qwen-Image-2.1 --omni --port 8091
curl http://localhost:8091/v1/images/generations \
  -H "Content-Type: application/json" \
  -d '{
    "model": "Qwen/Qwen-Image-2.1",
    "prompt": "A ceramic teapot on a wooden table",
    "size": "1024x1024",
    "num_inference_steps": 40,
    "seed": 42
  }'
For step-wise execution (batch-level scheduling):
vllm serve Qwen/Qwen-Image-2.1 --omni \
  --port 8091 \
  --step-execution \
  --max-num-seqs 8
See the vLLM-Omni recipe for FP8 quantization, prefix KV cache options, multi-GPU parallelism, and detailed benchmarks.
Inference with SGLang
SGLang-Diffusion provides native, high-performance inference for Qwen-Image 2.1, supporting text-to-image generation, multi-image editing, and transparent RGBA output. It offers multi-GPU parallelism, memory offloading, and optimized kernels across datacenter and consumer GPUs.
Generate a 1024×1024 image:
sglang generate \
  --model-path Qwen/Qwen-Image-2.1 \
  --prompt "A capybara reading a book by candlelight" \
  --height 1024 --width 1024 \
  --num-inference-steps 40 --guidance-scale 1 \
  --seed 42 --save-output
For image editing, add --image-path input.png. See the Qwen-Image 2.1 cookbook for installation, GPU-specific commands, image editing, and transparent-background examples.
Inference with LightX2V
LightX2V is a framework for image and video generation models, highly optimized for inference speed and GPU memory efficiency on both data center and consumer GPUs.
LightX2V supports Qwen-Image-2.1 for both text-to-image generation and image editing. See the usage guide to get started.
Architecture
Qwen-Image-2.1 is a single-stream DiT with the following design:
- Transformer: 32 layers, 7B parameters, single-stream architecture with block-causal attention (
(q_idx >= kv_idx) or same_image_block). Text uses token-level causal mask; images use chunk-level bidirectional mask. - Text Encoder: Qwen3-VL 8B (vision-language model) — encodes both text instructions and condition images into a unified representation.
- VAE: 64-channel RGBA autoencoder with 16× spatial compression, supporting native transparency.
- Scheduler: Flow Matching with Euler discrete scheduling and dynamic shifting.
The mixed-granularity attention architecture enables efficient prefix KV cache reuse: input images and text instructions are computed once at the first denoising step and cached for all subsequent steps.
Showcase
Native Transparency
Multi-Reference Editing
Group photograph generated from six individual portrait references
Complete outfit assembled from five reference images (model, clothing, shoes, bag, hat)
Local Editing
Circle-guided multi-region editing: remove watch, change hair color, replace clothing
Portrait and Product Fidelity
Text Rendering
Panorama and Storyboard
Panorama generated from a selfie
Storyboard generated from a three-view character reference
Community Support
Diffusers (Recommended)
Diffusers supports Qwen-Image-2.1 via QwenImage21Pipeline, handling both text-to-image and image-conditioned generation in a single pipeline. See PR #14804.
ComfyUI
Qwen-Image 2.1 is natively supported in ComfyUI on Day 0. The compatible model weights can be downloaded from Hugging Face Comfy-Org/Qwen-Image-2.1. See example workflows for text-to-image and image editing.
vLLM-Omni
vLLM-Omni accelerates Qwen-Image 2.1 through cross-step prefix KV cache reuse and dedicated CUDA Graphs, reducing redundant computation and kernel launch overhead. Request-level and step-level continuous batching improve GPU utilization and throughput, with phase-aware prefill and decode scheduling. It also supports tensor and Ulysses sequence parallelism, distributed VAE decoding with adaptive OOM recovery, FP8 weights and prefix KV storage, and CPU offloading for varying memory budgets. See the Qwen-Image-2.1 recipe for details.
SGLang
SGLang-Diffusion provides native, high-performance inference with multi-GPU parallelism, memory offloading, and optimized kernels. See the Qwen-Image 2.1 cookbook and PR #39983.
Wuli.art
For users in mainland China, wuli.art offers free access to all Qwen Image 2.1 features in both Chatbox and Canvas, including image generations with transparent background.
ModelScope
ModelScope fully supports Qwen-Image-2.1. Built on its open-source DiffSynth-Studio framework, the platform enables seamless model download, online generation and LoRA training. Explore these capabilities at ModelScope Civision.
Hardware Support
AMD Radeon GPU
Get ready to run Qwen-Image 2.1 on AMD Radeon GPU. With ROCm, PyTorch, and Diffusers, developers can easily explore high-quality text-to-image generation on AMD GPUs.
Diverse AI Chips via FlagOS
FlagOS is a fully open-source system software stack for heterogeneous AI chips. It unifies the model–system–chip layers to enable a "develop once, run anywhere" workflow, eliminating the fragmentation among vendor-specific software stacks and substantially lowering the cost of porting AI workloads across accelerators.
In this release, Qwen-Image-2.1 leverages the FlagOS software stack to provide direct multi-chip support. By integrating the Triton-based operator library FlagGems via the Torch-FL plugin, FlagOS enables seamless adaptation of the Diffusers library across chip platforms; the usage experience remains identical to that on NVIDIA, requiring zero code modifications. Inference accuracy across all platforms has been aligned with the official implementation.
Prebuilt images and weights for 8 chip platforms are released under FlagRelease — for example, T-Head zhenwu and Arm.
License Agreement
This repository is licensed under the Qwen Research License Agreement.
Contact and Join Us
If you'd like to get in touch with our research team, join our Discord. We welcome issues and pull requests on GitHub.
If you're passionate about fundamental research, we're hiring full-time employees and research interns. Reach out at fulai.hr@alibaba-inc.com.
Star History
Similar repos
Contributors
22 commits
1 commits
Languages
Python
91.5%
Shell
8.5%