A set of nodes that improve the work with the Flux model
Python
2
7 commits
updated Sep 2, 2026
Custom node pack for ComfyUI: image samplers for Flux.1 / Flux.2 / Krea2, video generation for LTX-2.5 and MiniMax H3, reference tools, a prompt engine and save utilities — 40+ nodes, modern V3 API (io.ComfyNode), dark neon theme.
DoomSuperLoader (checkpoint or diffusion model, VAE, up to 3 CLIPs, CLIP Vision, StyleModel, fp8/bf16), GGUF support.Doom_ReferenceFree — image reference prep with crop, normalize, overlay, text layer, masks, outpaint padding.lists/), multi-prompt loader, edit presets, builder, constructor, wordbook, prompt saver.DoomSaveUltimate (reliable counter, date subfolders, PNG metadata, prompt logs, UI preview), video saver with audio.cd ComfyUI/custom_nodes
git clone https://github.com/PeterMikhai/DoomAI_nodes.git
Restart ComfyUI. No extra dependencies — everything runs on ComfyUI's own stack (torch, PIL, aiohttp).
| Node | Description |
|---|---|
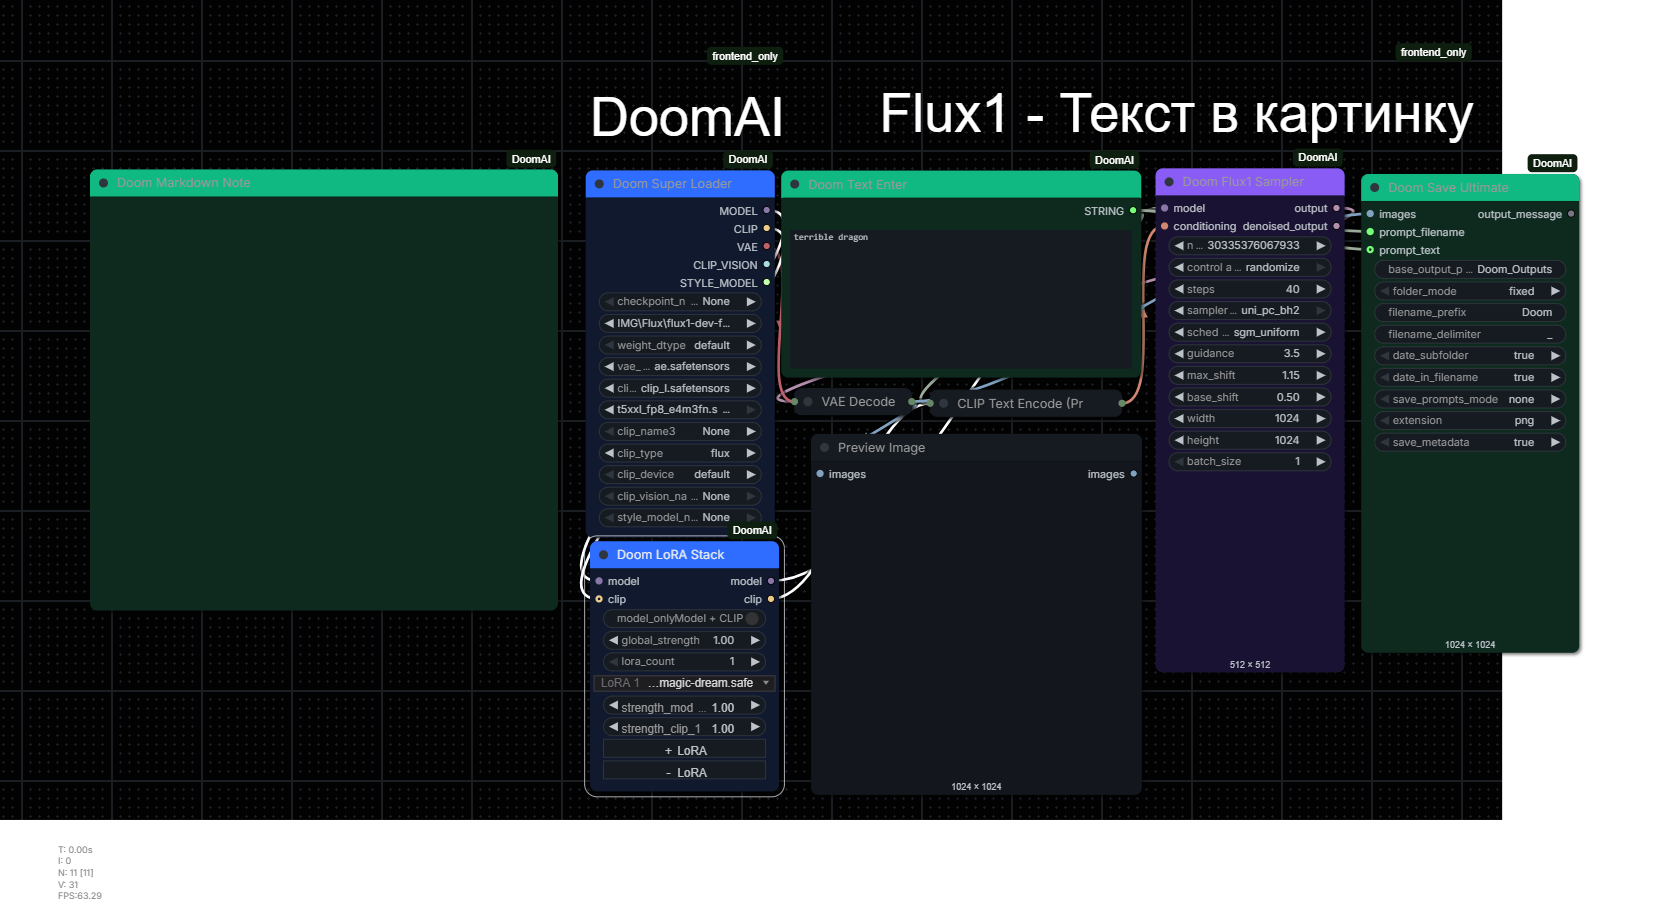
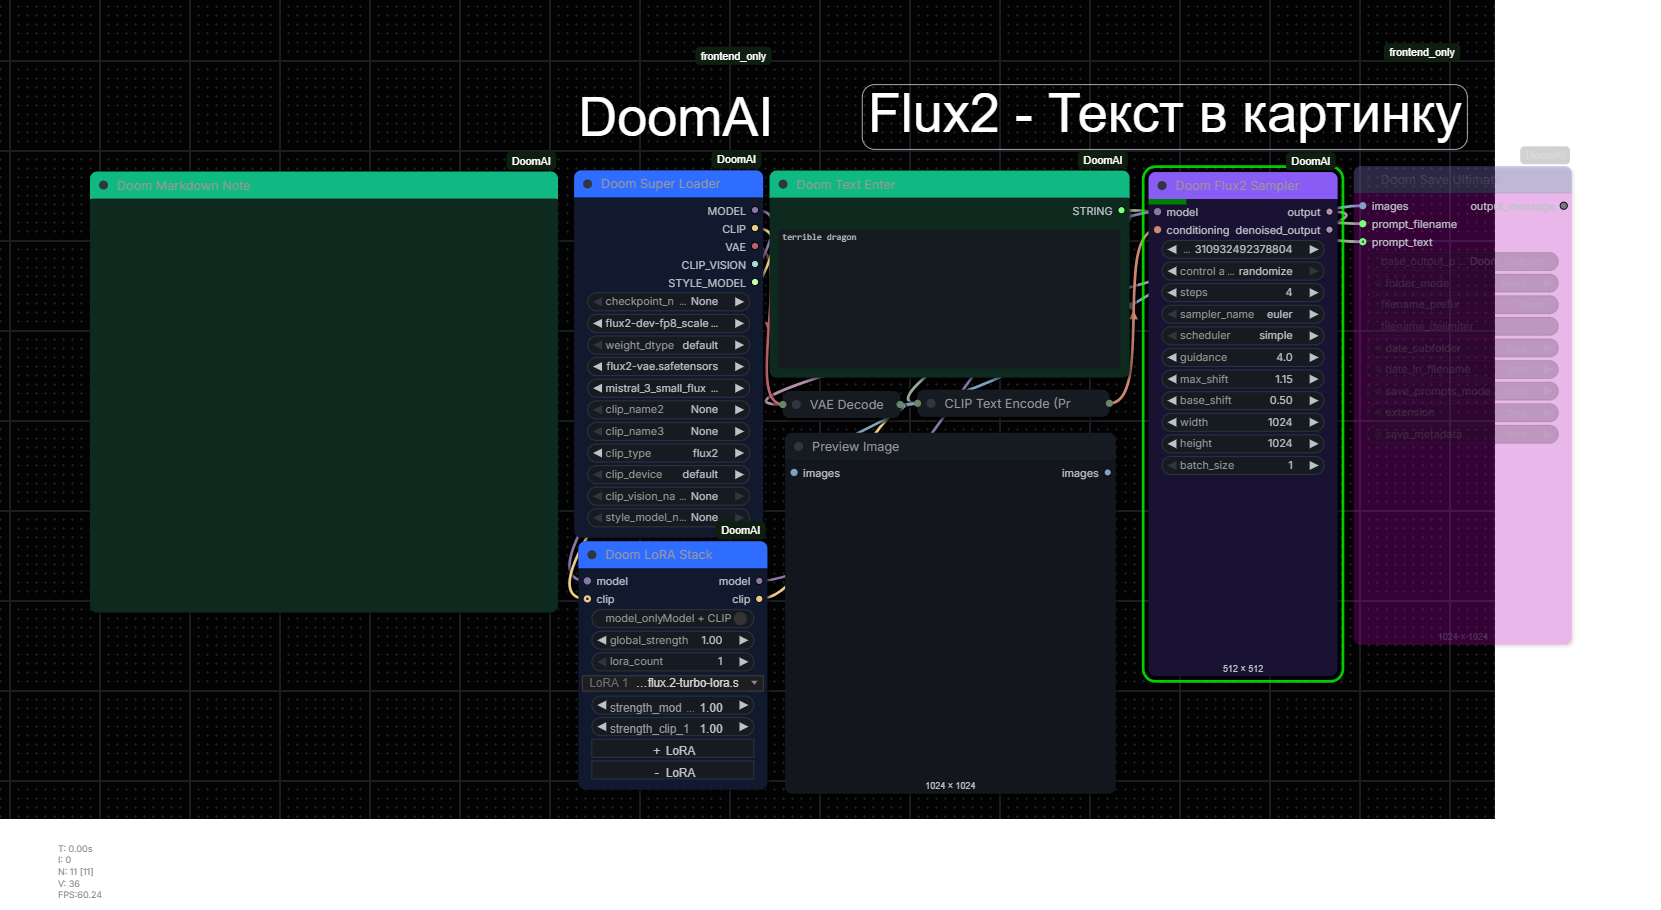
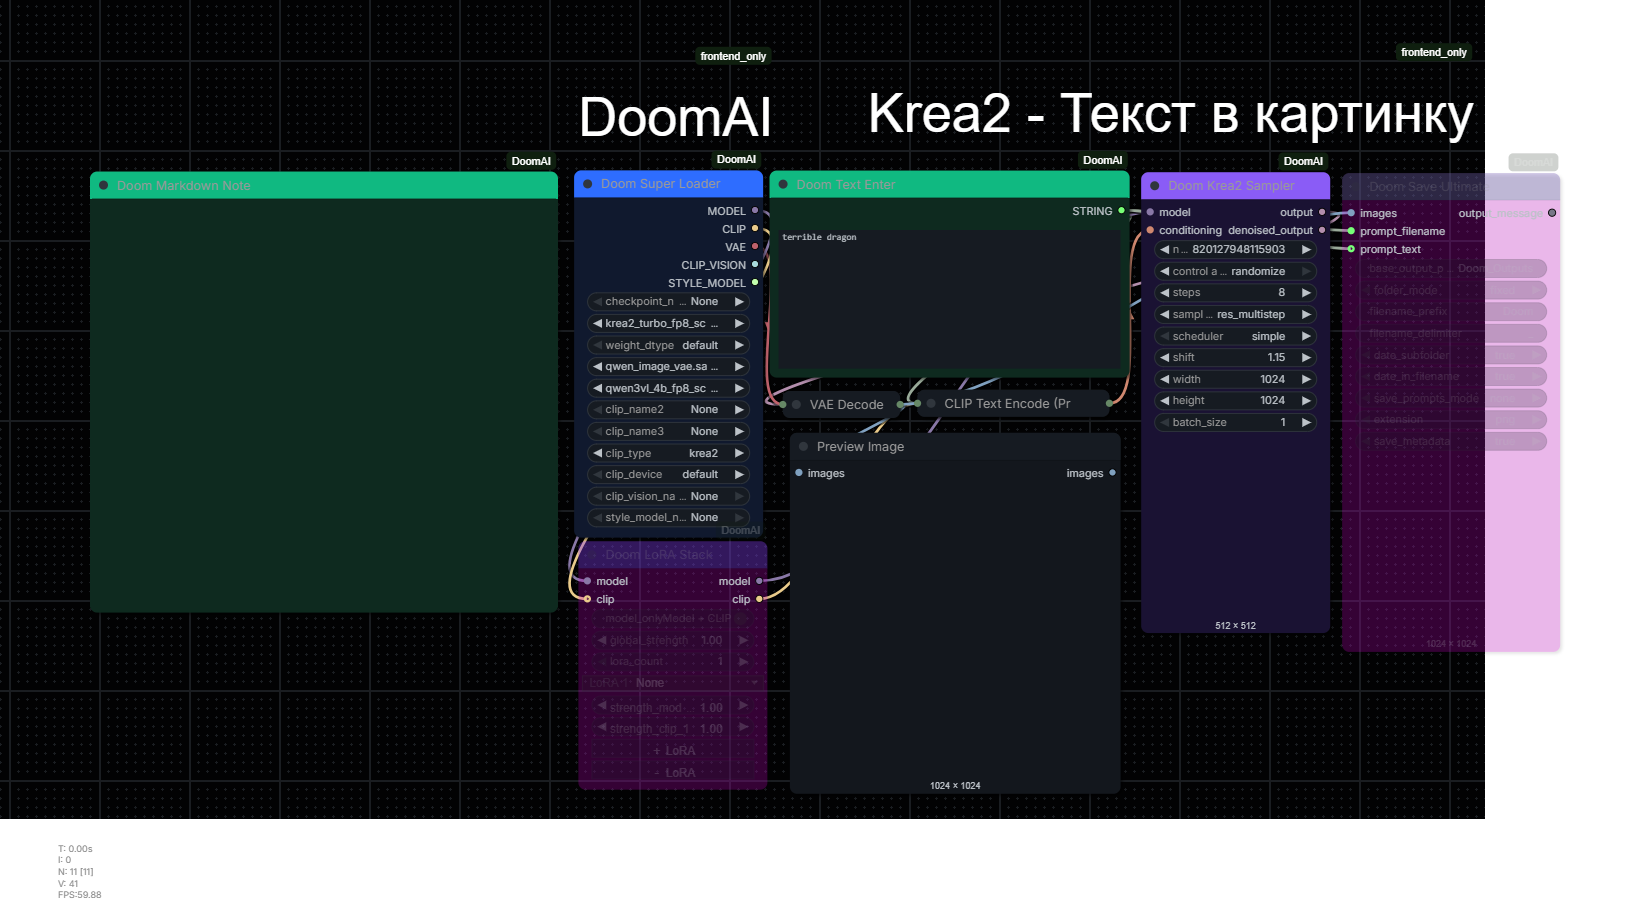
| Doom Super Loader | Universal loader: checkpoint or diffusion model, VAE, up to 3 CLIPs, CLIP Vision, StyleModel, fp8/bf16/GGUF |
| Doom Flux1 Loader (GGUF / WAN) | Auto FP/GGUF detection, MoE dual model, GGUF-CLIP |
| Doom LoRA Stack | Up to 10 LoRA slots with weights |
| Doom LTX Loader | LTX-2.5: diffusion + Gemma 4 CLIP + video VAE + audio VAE + latent upscaler + enhancer Gemma + duration head |
| Doom MiniMax H3 Loader | H3: diffusion + Qwen3-VL CLIP + video VAE + audio VAE |
| Node | Description |
|---|---|
| Doom Flux1 Sampler | Flux.1: prompt → latent, shift by resolution |
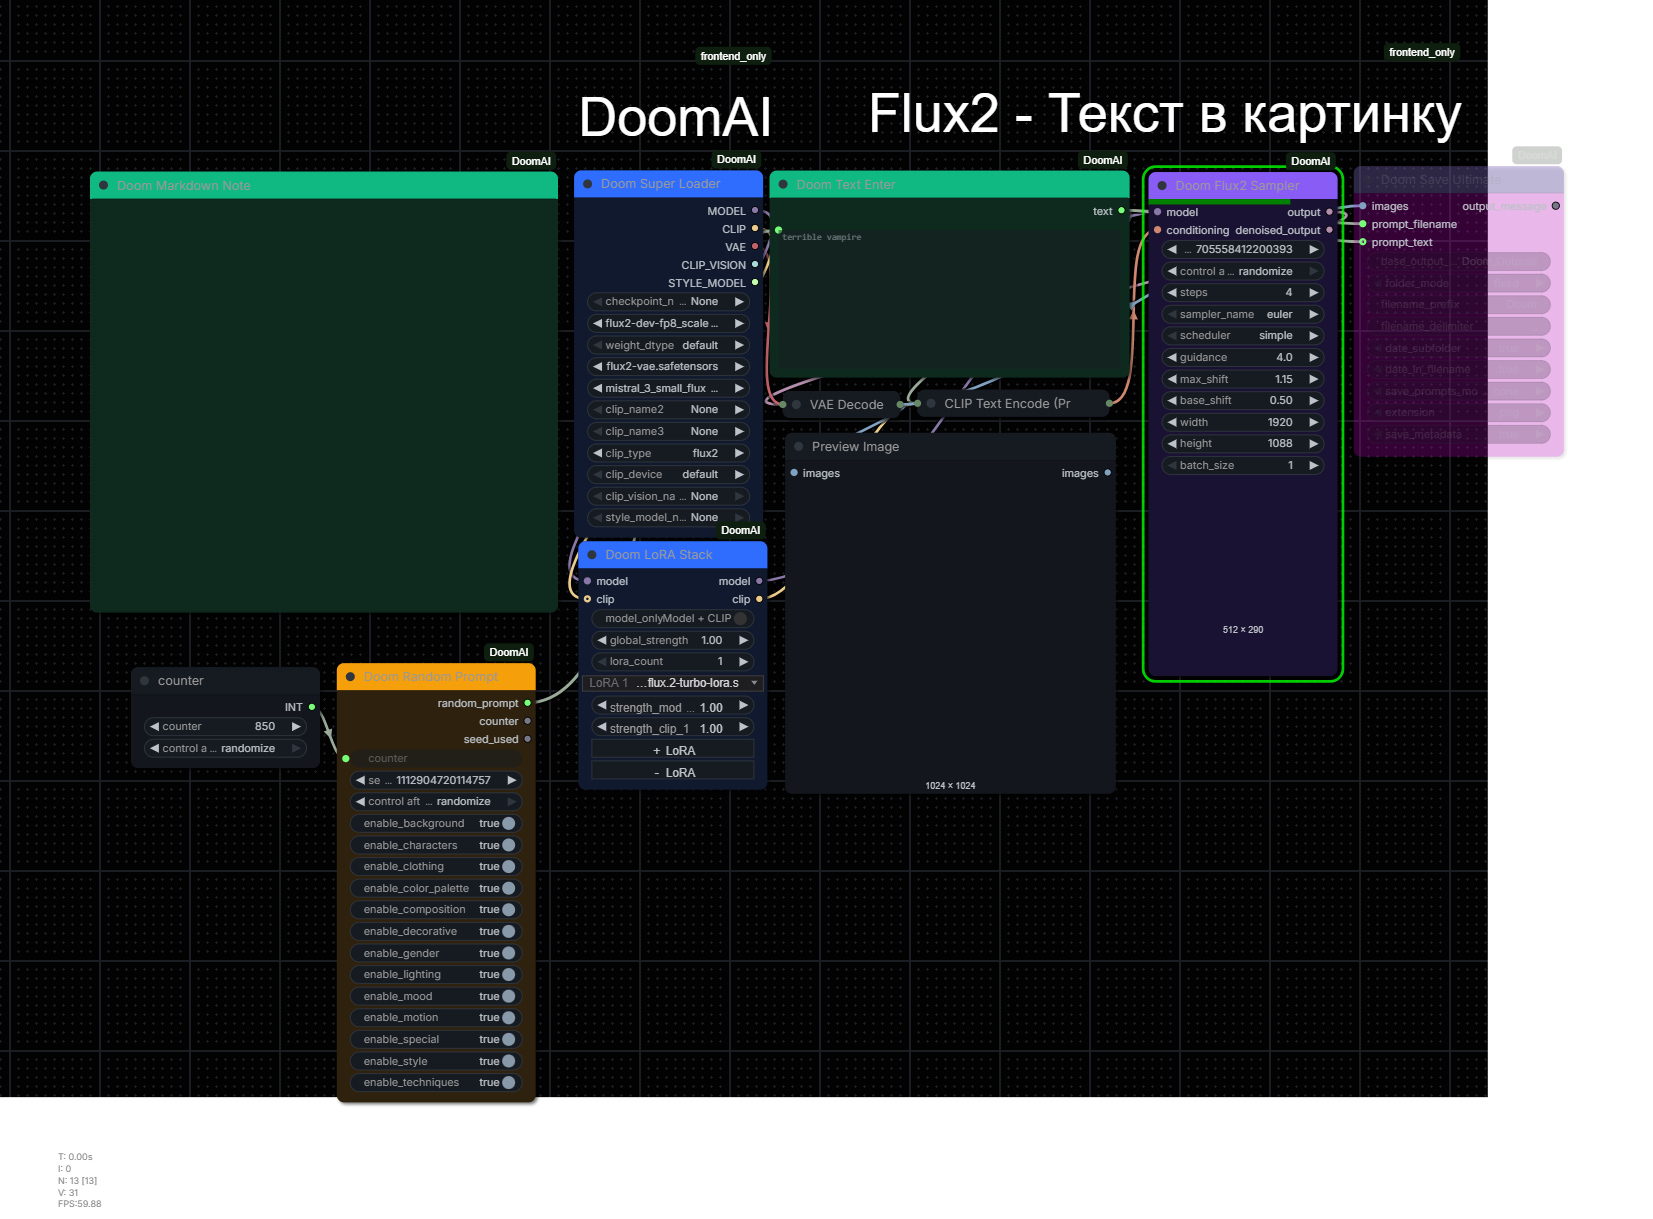
| Doom Flux2 Sampler | Flux.2 (DiT 16×, schedule by seq_len) |
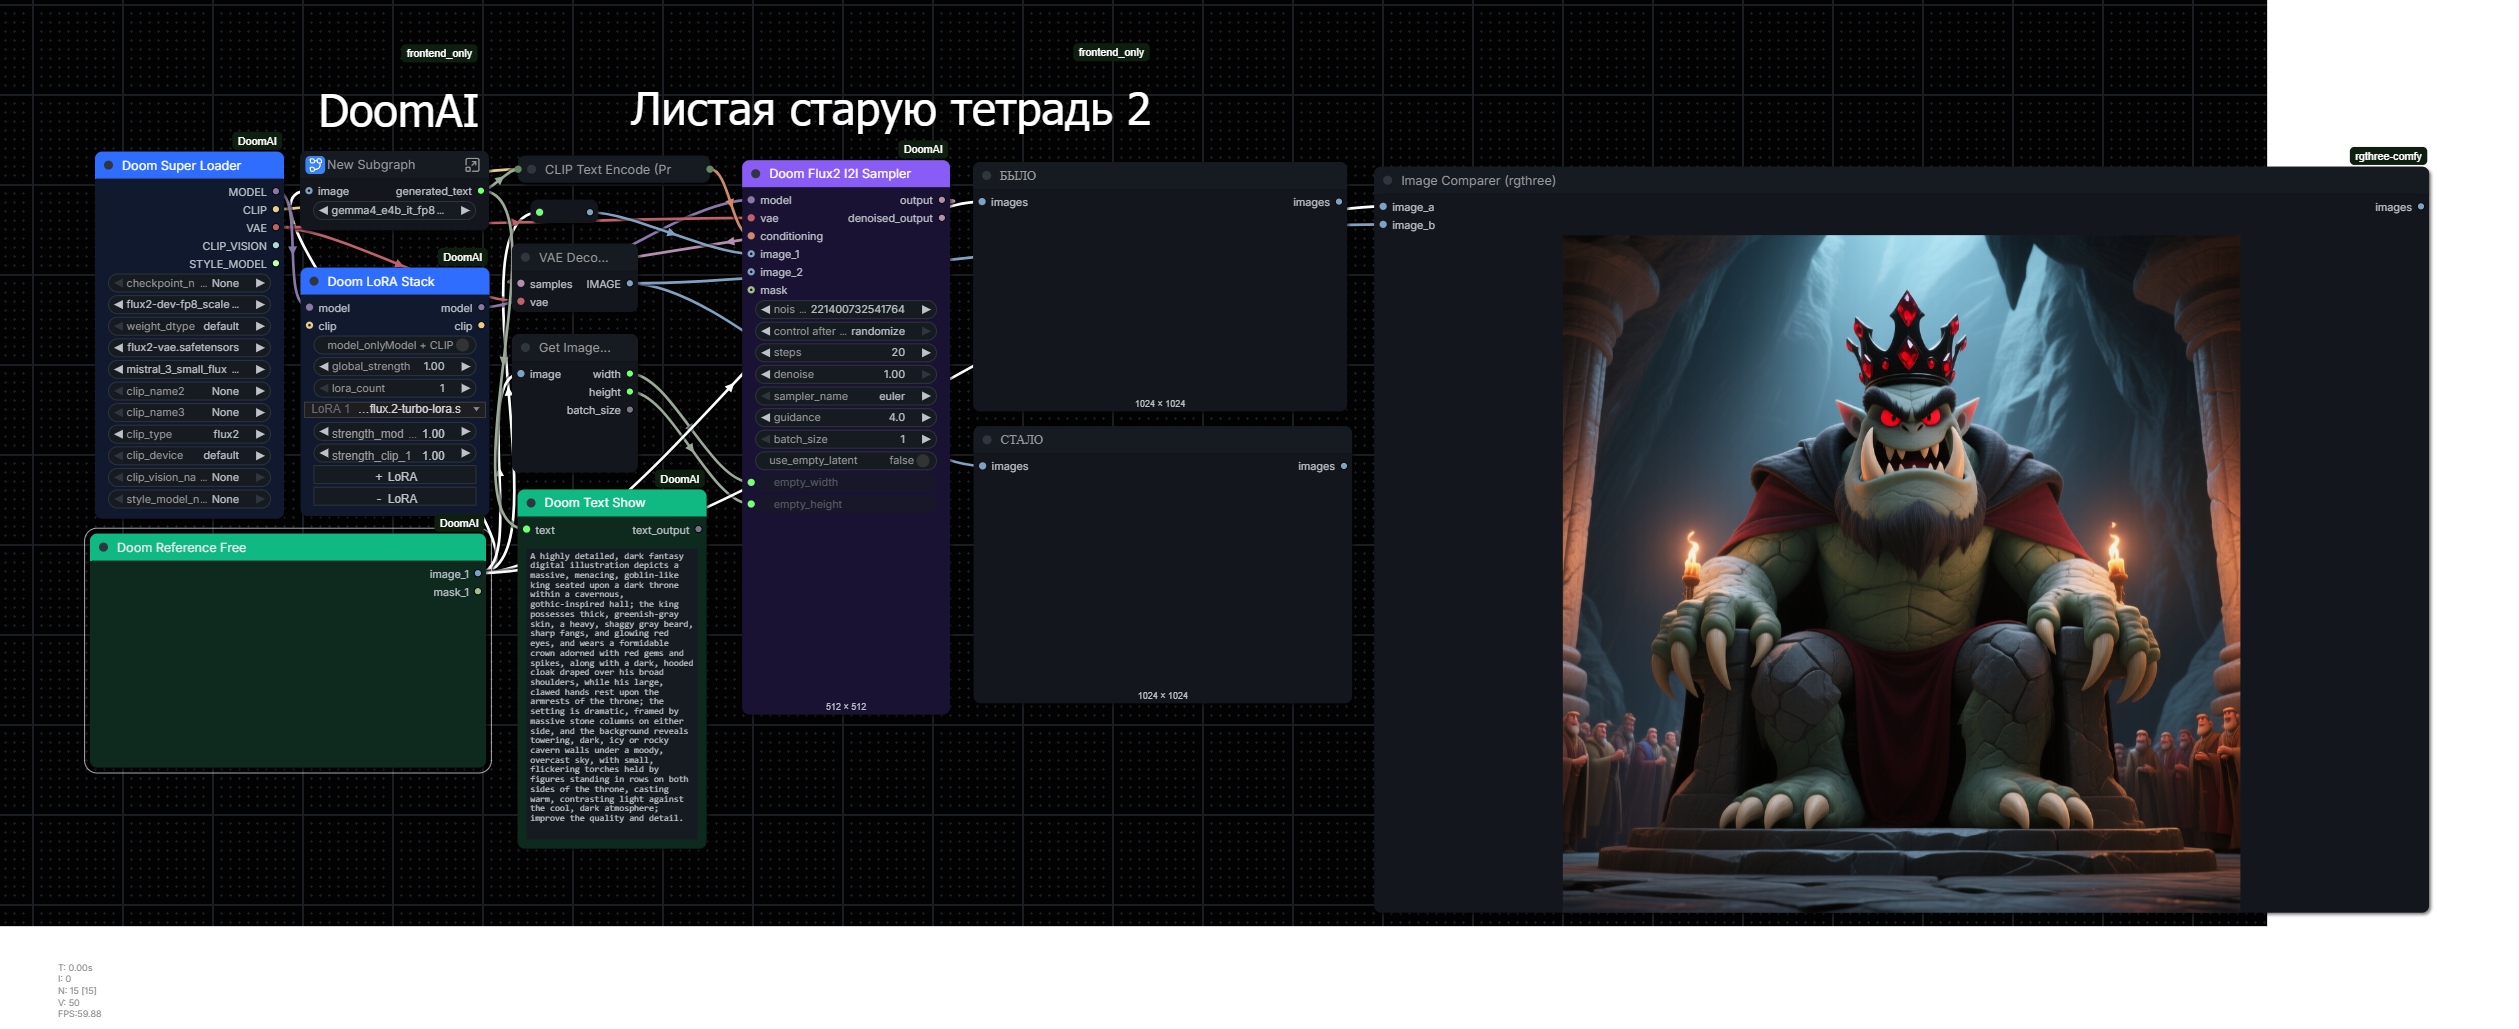
| Doom Flux2 I2I Sampler | img2img / multi-reference (autogrow up to 8 refs, mask) |
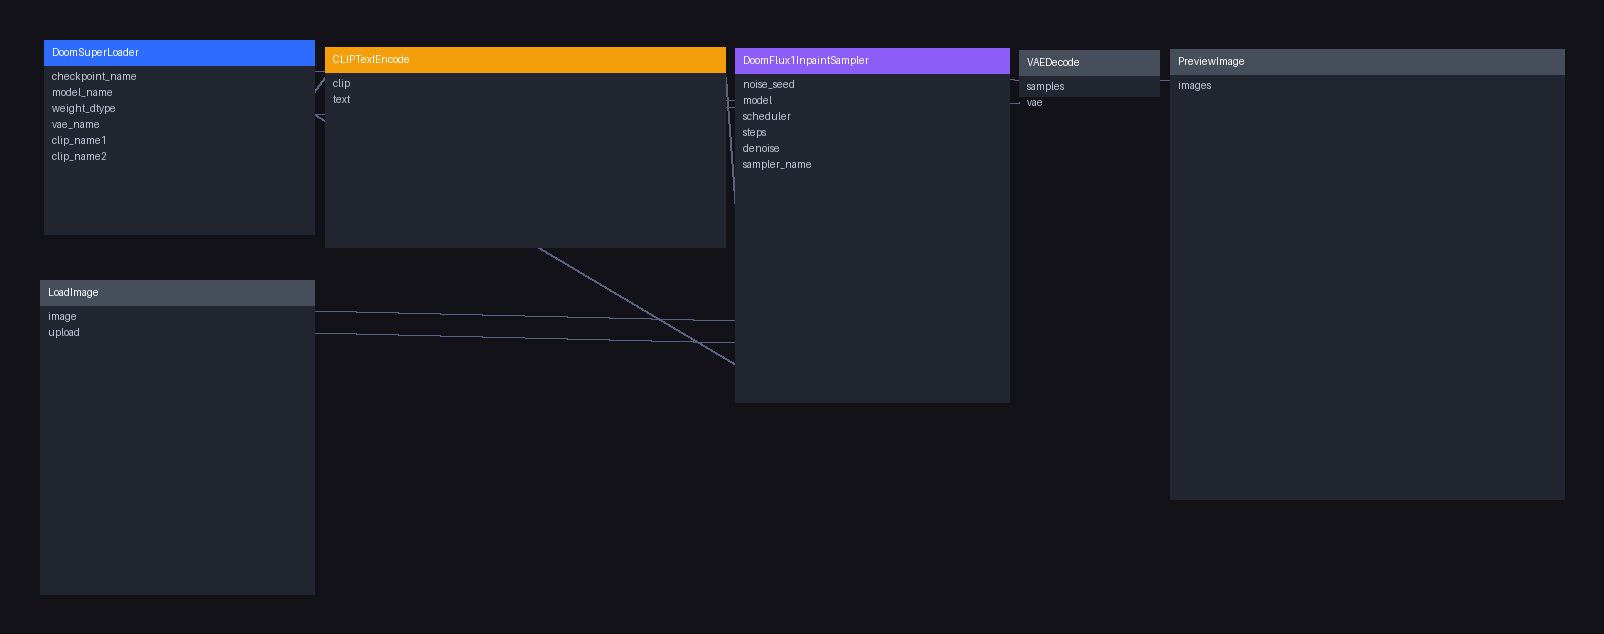
| Doom Flux1 Inpaint Sampler | Inpaint with noise_mask + concat latent |
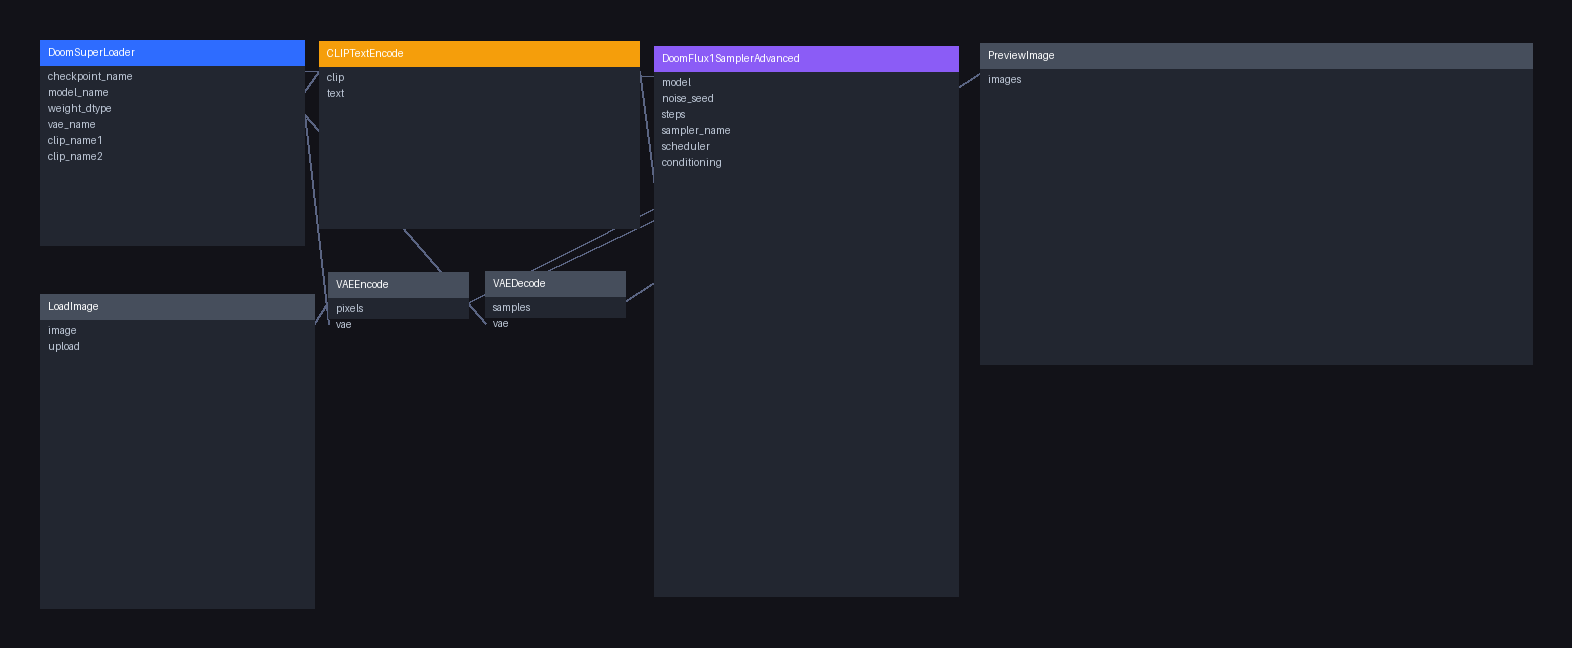
| Doom Flux1 Sampler Advanced | start/end step, dynamic CFG, denoise |
| Doom Krea2 Sampler | Krea2 turbo (8 steps) / RAW, fixed shift 1.15, CFG 1.0 |
| Doom LTX Sampler | LTX-2.5 i2v: first frame + prompt → video with sound, latent upscale ×2, prompt enhancer, auto_duration |
| Doom MiniMax H3 Sampler | H3: refs + prompt → video + audio (CFG-distilled 1.0) |
| Node | Description |
|---|---|
| Doom Save Ultimate | Save with counter, date subfolders, metadata, prompt logs, UI preview |
| Doom Save Video Free | Video encoder with audio (ffmpeg) |
| Doom Image Loader / Router / Resize | Image batch load, conditional routing, resize (MP/W×H/crop/pad) |
| Doom Get Image Size / Resolution From MP | Sizes and resolution math |
| Doom Text Enter / Text Show | Text I/O |
| Doom Index Pair Counter | One index → main/style pair |
| Doom Reference Free | Reference image prep (JS widget, 4 slots) |
| Flux Kontext Pad For Outpaint / Restore And Crop | Outpainting helpers |
| Node | Description |
|---|---|
| Doom Prompt Save | Prompt saving with date, counter, metadata |
| Doom Random Prompt | Wildcards `{a |
| Doom Multi Prompt Loader | Sequential / random / shuffle modes |
| Doom Edit Prompts | Presets incl. modern models (H3/LTX/Krea2/Flux) |
| Doom Prompt Builder | Sectional prompt builder |
| Doom Action Prompter / Constructor / Wordbook | RU template tools |
| Node | Description |
|---|---|
| Doom Markdown Note | In-canvas markdown notes with model-preset templates |
| Doom Translate | Text translation |
| Doom Save Video Free | ffmpeg video save with audio |
Ready-to-use examples in workflows/ — each has a JSON (open it in ComfyUI via Workflow → Open) and a PNG preview:
Note:
flux2_i2i_reference_pagesuses a subgraph prompt enhancer (CLIPLoader + TextGenerate) — requires ComfyUI with subgraph support (0.24+).
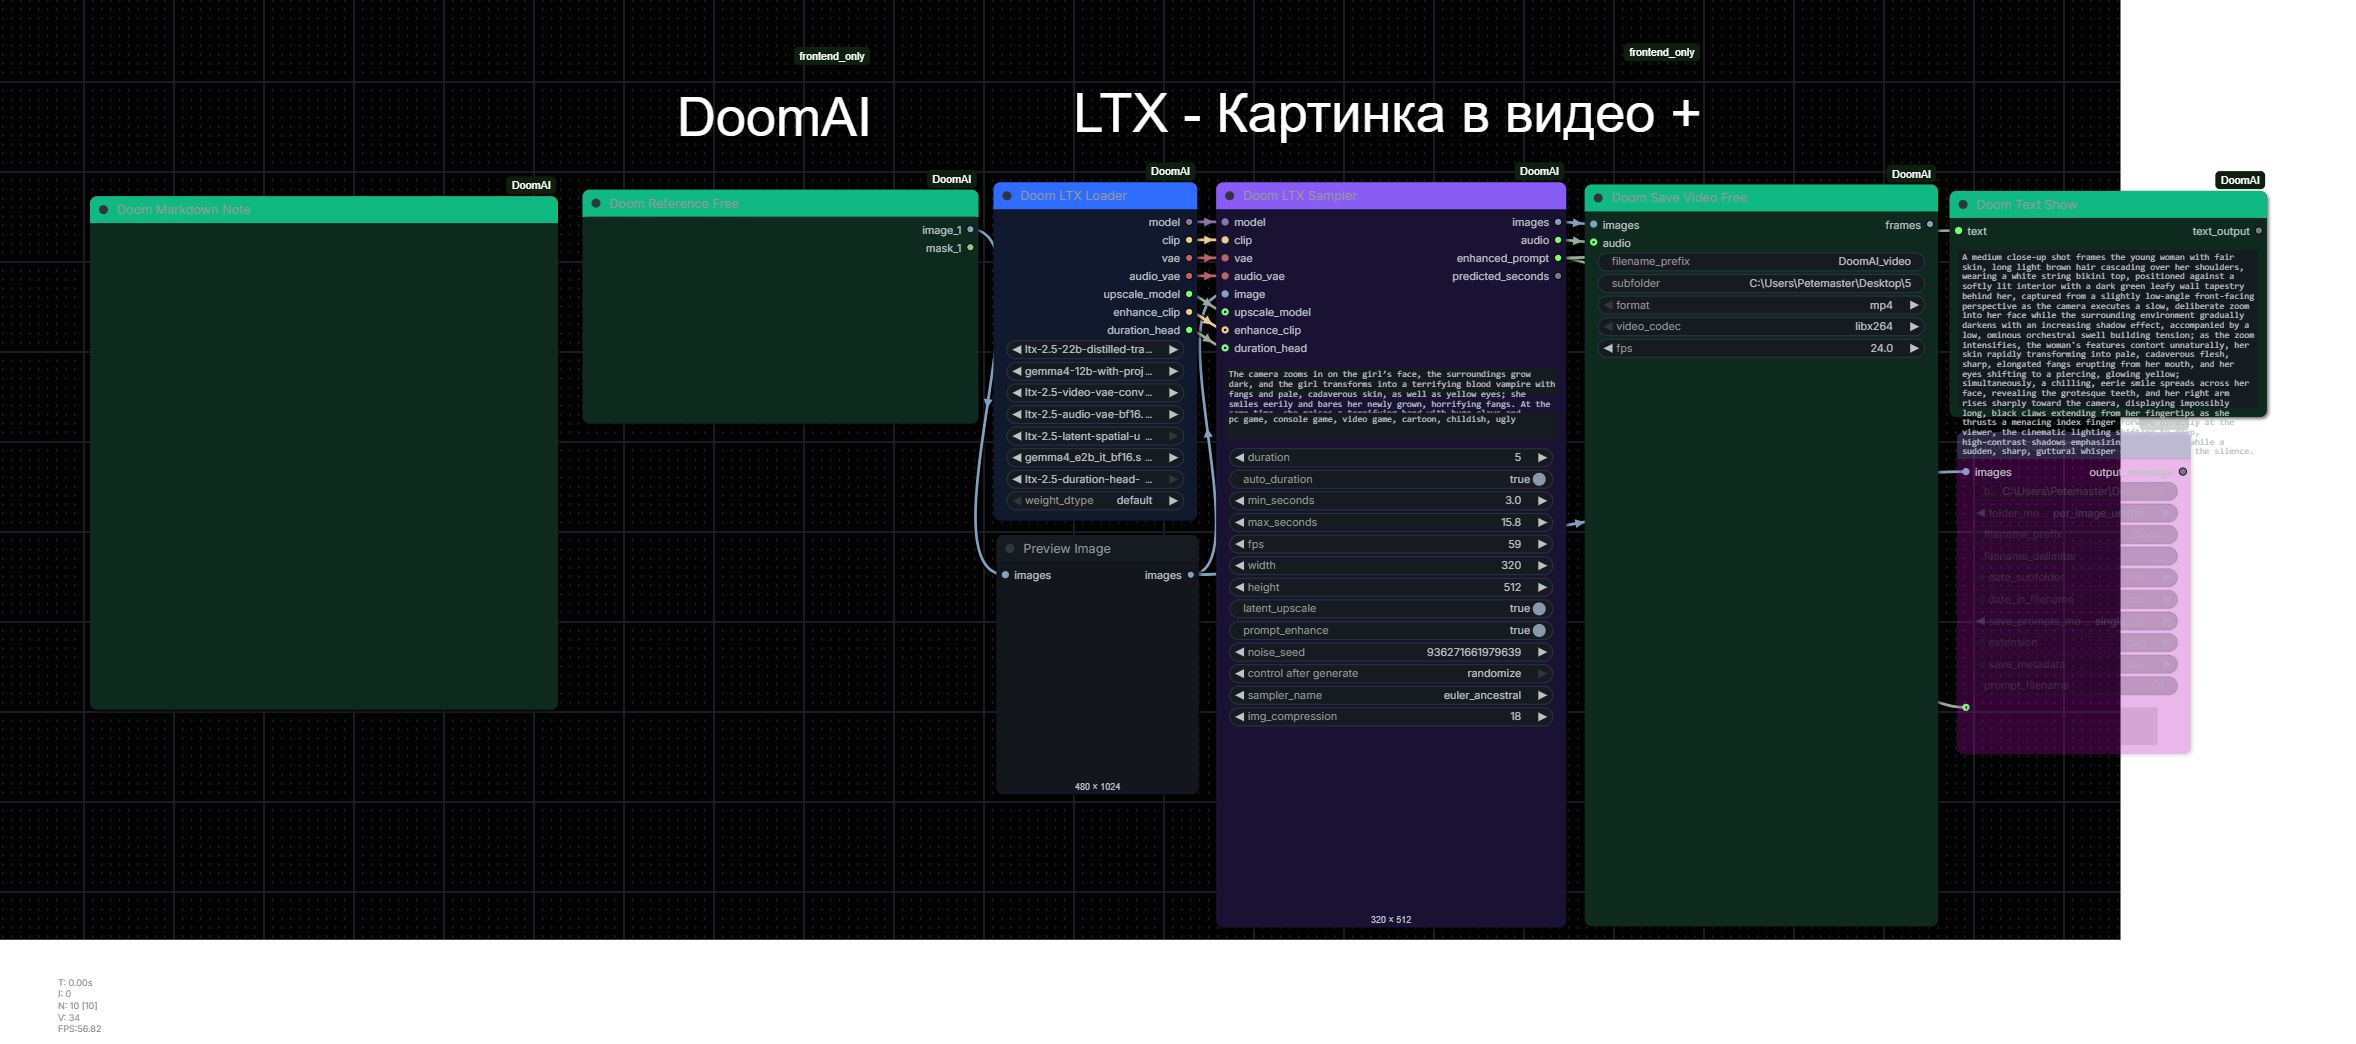
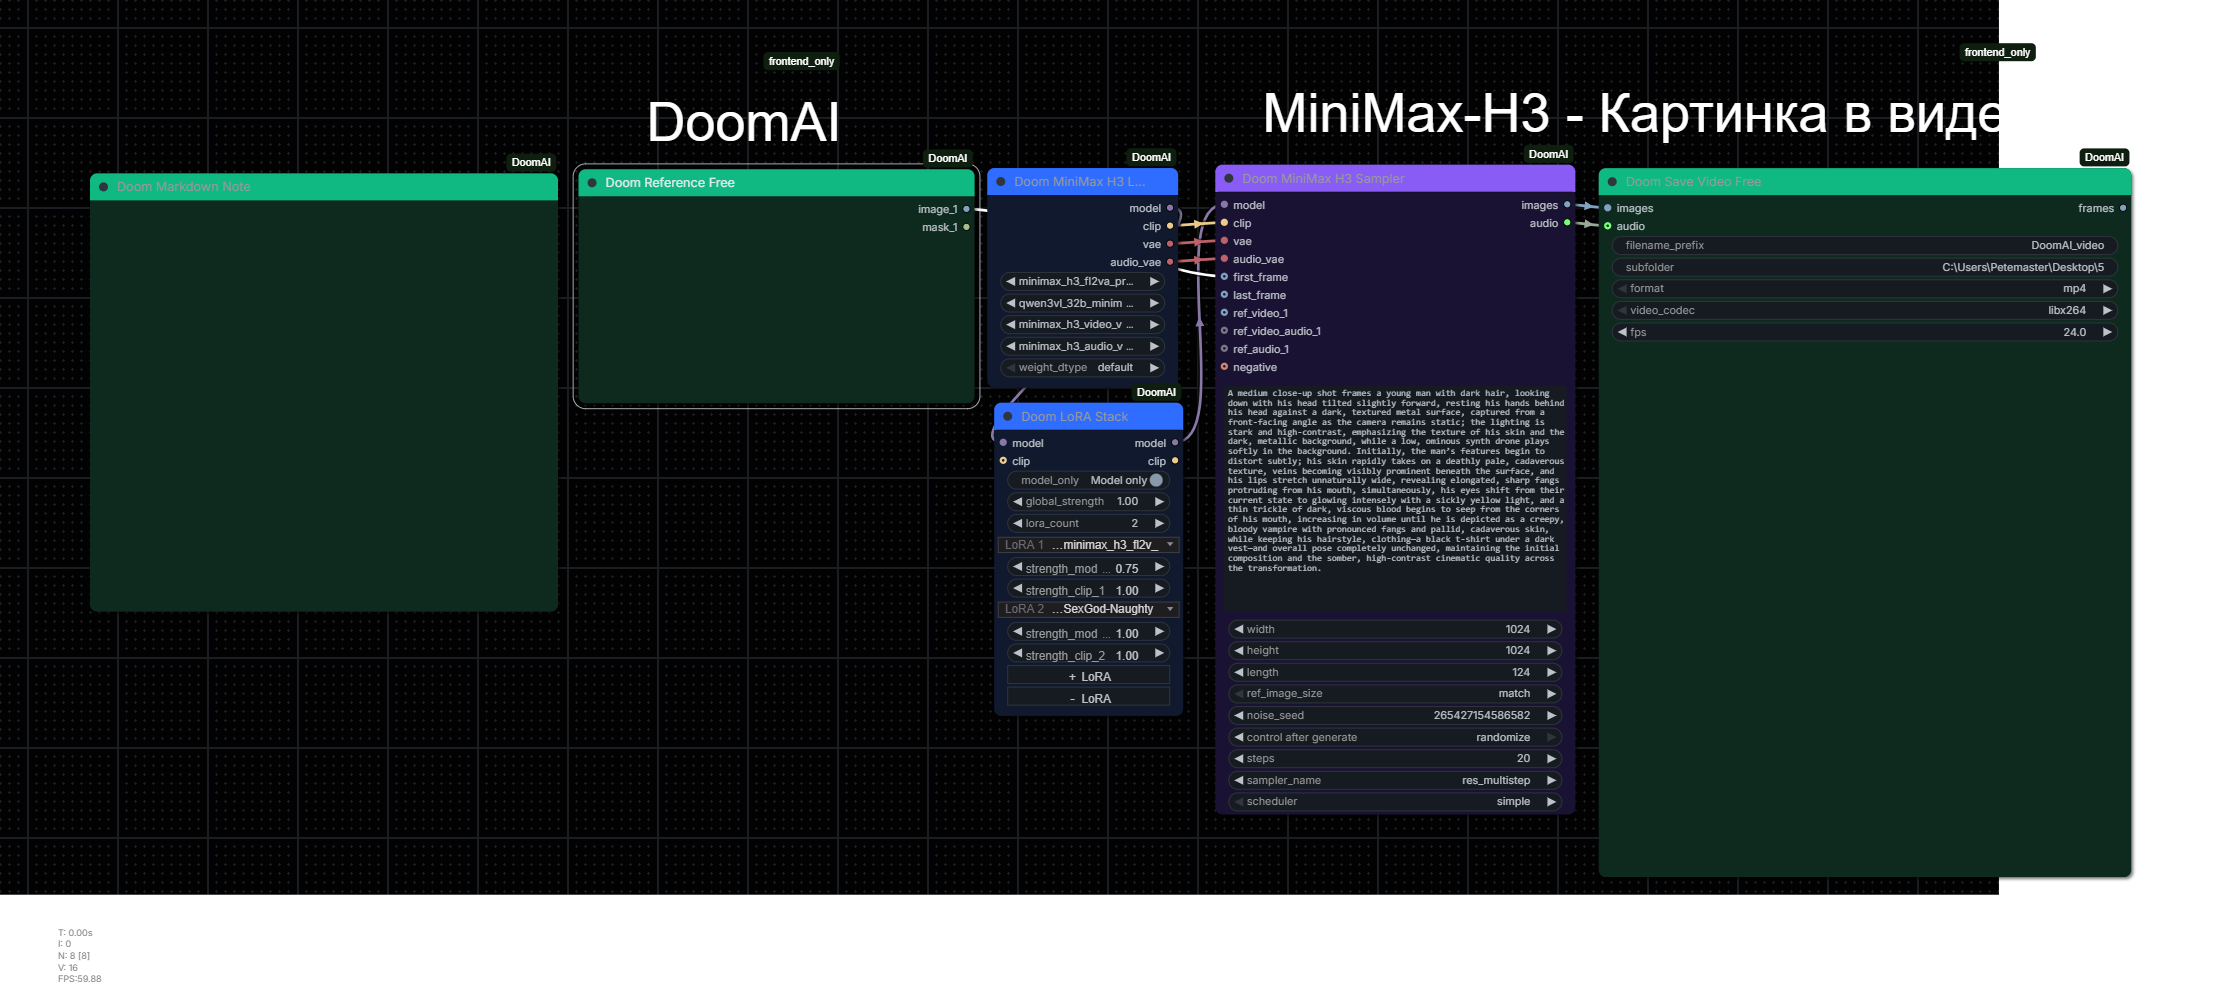
All workflows use the current node names — no legacy remapping needed.
diffusion_models, text_encoders, vae)ltx-2.5-22b-distilled-transformer-comfy-int8-convrot.safetensors + Gemma 4 CLIP + video/audio VAEs + upscaler (optional) + ltx-2.5-duration-head-bf16.safetensors → models/model_patches/ for auto durationSee CHANGELOG.md.
MIT — see LICENSE.
Znai nashih!
A set of nodes that improve the work with the Flux model
Python
2
7 commits
updated Sep 2, 2026
Custom node pack for ComfyUI: image samplers for Flux.1 / Flux.2 / Krea2, video generation for LTX-2.5 and MiniMax H3, reference tools, a prompt engine and save utilities — 40+ nodes, modern V3 API (io.ComfyNode), dark neon theme.
DoomSuperLoader (checkpoint or diffusion model, VAE, up to 3 CLIPs, CLIP Vision, StyleModel, fp8/bf16), GGUF support.Doom_ReferenceFree — image reference prep with crop, normalize, overlay, text layer, masks, outpaint padding.lists/), multi-prompt loader, edit presets, builder, constructor, wordbook, prompt saver.DoomSaveUltimate (reliable counter, date subfolders, PNG metadata, prompt logs, UI preview), video saver with audio.cd ComfyUI/custom_nodes
git clone https://github.com/PeterMikhai/DoomAI_nodes.git
Restart ComfyUI. No extra dependencies — everything runs on ComfyUI's own stack (torch, PIL, aiohttp).
| Node | Description |
|---|---|
| Doom Super Loader | Universal loader: checkpoint or diffusion model, VAE, up to 3 CLIPs, CLIP Vision, StyleModel, fp8/bf16/GGUF |
| Doom Flux1 Loader (GGUF / WAN) | Auto FP/GGUF detection, MoE dual model, GGUF-CLIP |
| Doom LoRA Stack | Up to 10 LoRA slots with weights |
| Doom LTX Loader | LTX-2.5: diffusion + Gemma 4 CLIP + video VAE + audio VAE + latent upscaler + enhancer Gemma + duration head |
| Doom MiniMax H3 Loader | H3: diffusion + Qwen3-VL CLIP + video VAE + audio VAE |
| Node | Description |
|---|---|
| Doom Flux1 Sampler | Flux.1: prompt → latent, shift by resolution |
| Doom Flux2 Sampler | Flux.2 (DiT 16×, schedule by seq_len) |
| Doom Flux2 I2I Sampler | img2img / multi-reference (autogrow up to 8 refs, mask) |
| Doom Flux1 Inpaint Sampler | Inpaint with noise_mask + concat latent |
| Doom Flux1 Sampler Advanced | start/end step, dynamic CFG, denoise |
| Doom Krea2 Sampler | Krea2 turbo (8 steps) / RAW, fixed shift 1.15, CFG 1.0 |
| Doom LTX Sampler | LTX-2.5 i2v: first frame + prompt → video with sound, latent upscale ×2, prompt enhancer, auto_duration |
| Doom MiniMax H3 Sampler | H3: refs + prompt → video + audio (CFG-distilled 1.0) |
| Node | Description |
|---|---|
| Doom Save Ultimate | Save with counter, date subfolders, metadata, prompt logs, UI preview |
| Doom Save Video Free | Video encoder with audio (ffmpeg) |
| Doom Image Loader / Router / Resize | Image batch load, conditional routing, resize (MP/W×H/crop/pad) |
| Doom Get Image Size / Resolution From MP | Sizes and resolution math |
| Doom Text Enter / Text Show | Text I/O |
| Doom Index Pair Counter | One index → main/style pair |
| Doom Reference Free | Reference image prep (JS widget, 4 slots) |
| Flux Kontext Pad For Outpaint / Restore And Crop | Outpainting helpers |
| Node | Description |
|---|---|
| Doom Prompt Save | Prompt saving with date, counter, metadata |
| Doom Random Prompt | Wildcards `{a |
| Doom Multi Prompt Loader | Sequential / random / shuffle modes |
| Doom Edit Prompts | Presets incl. modern models (H3/LTX/Krea2/Flux) |
| Doom Prompt Builder | Sectional prompt builder |
| Doom Action Prompter / Constructor / Wordbook | RU template tools |
| Node | Description |
|---|---|
| Doom Markdown Note | In-canvas markdown notes with model-preset templates |
| Doom Translate | Text translation |
| Doom Save Video Free | ffmpeg video save with audio |
Ready-to-use examples in workflows/ — each has a JSON (open it in ComfyUI via Workflow → Open) and a PNG preview:
Note:
flux2_i2i_reference_pagesuses a subgraph prompt enhancer (CLIPLoader + TextGenerate) — requires ComfyUI with subgraph support (0.24+).
All workflows use the current node names — no legacy remapping needed.
diffusion_models, text_encoders, vae)ltx-2.5-22b-distilled-transformer-comfy-int8-convrot.safetensors + Gemma 4 CLIP + video/audio VAEs + upscaler (optional) + ltx-2.5-duration-head-bf16.safetensors → models/model_patches/ for auto durationSee CHANGELOG.md.
MIT — see LICENSE.
Znai nashih!



