Selective Aggregation for Low-Rank Adaptation in Federated Learning [ICLR 2025]
See the codeThe implementation of Selective Aggregation for Low-Rank Adaptation in Federated Learning [ICLR 2025].
Pengxin Guo, Shuang Zeng, Yanran Wang, Huijie Fan, Feifei Wang, and Liangqiong Qu.
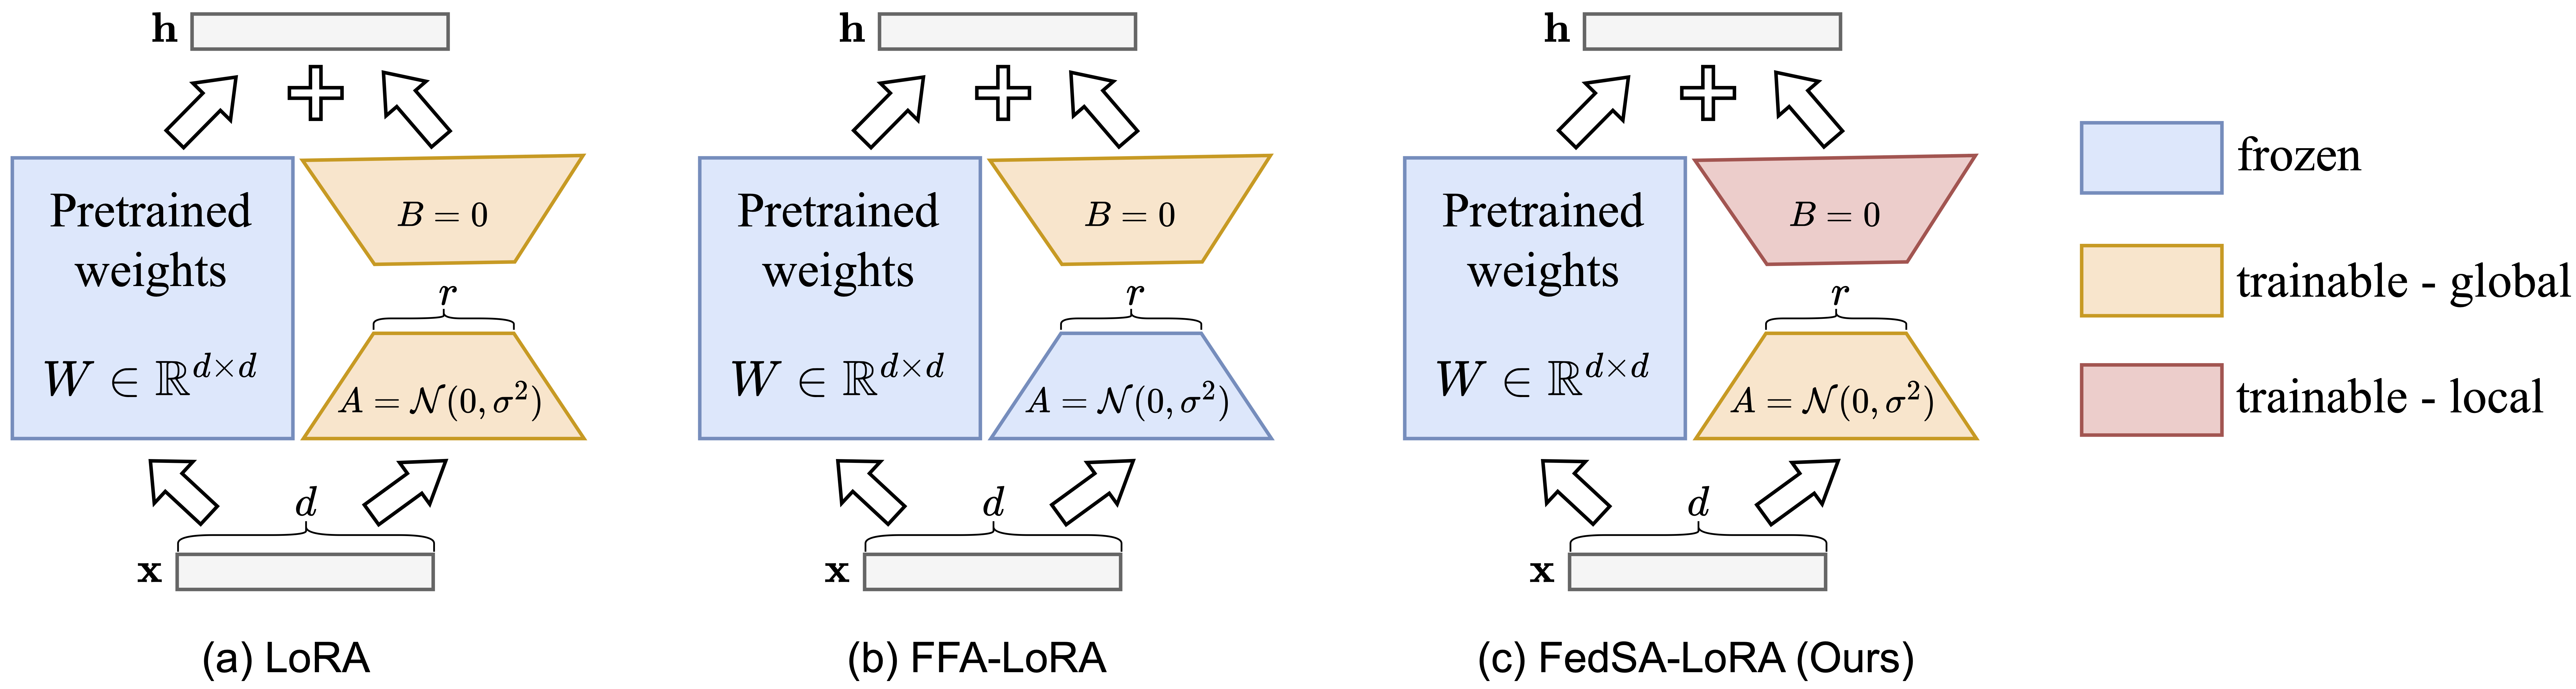
Our code is based on Python version 3.10 and PyTorch version 2.1.0. You can install all the dependencies with the following command:
conda create -n fedsa-lora python=3.10
conda activate fedsa-lora
conda install pytorch==2.1.0 torchvision==0.16.0 torchaudio==2.1.0 pytorch-cuda=12.1 -c pytorch -c nvidia
pip install -e .[llm]
Now, we can fine-tune a LLM with FedSA-LoRA:
python federatedscope/main.py --cfg federatedscope/glue/yamls/fedsa-lora.yaml
We would like to thank the authors for releasing the public repository: FederatedScope-LLM.
Selective Aggregation for Low-Rank Adaptation in Federated Learning [ICLR 2025]
See the codeThe implementation of Selective Aggregation for Low-Rank Adaptation in Federated Learning [ICLR 2025].
Pengxin Guo, Shuang Zeng, Yanran Wang, Huijie Fan, Feifei Wang, and Liangqiong Qu.
Our code is based on Python version 3.10 and PyTorch version 2.1.0. You can install all the dependencies with the following command:
conda create -n fedsa-lora python=3.10
conda activate fedsa-lora
conda install pytorch==2.1.0 torchvision==0.16.0 torchaudio==2.1.0 pytorch-cuda=12.1 -c pytorch -c nvidia
pip install -e .[llm]
Now, we can fine-tune a LLM with FedSA-LoRA:
python federatedscope/main.py --cfg federatedscope/glue/yamls/fedsa-lora.yaml
We would like to thank the authors for releasing the public repository: FederatedScope-LLM.



