See where your Claude Code and Codex tokens go: a local, read-only audit of your own transcripts, plus lean-context rules and a read guard. The rules cut cost 32% over 80 A/B runs on Sonnet 5.
See the code
Find and plug your coding agent's token leaks.
Not leaked API keys: the tokens your AI agent burns on context it didn't need.


Website · Install · Audit · Benchmark · Rules · Français
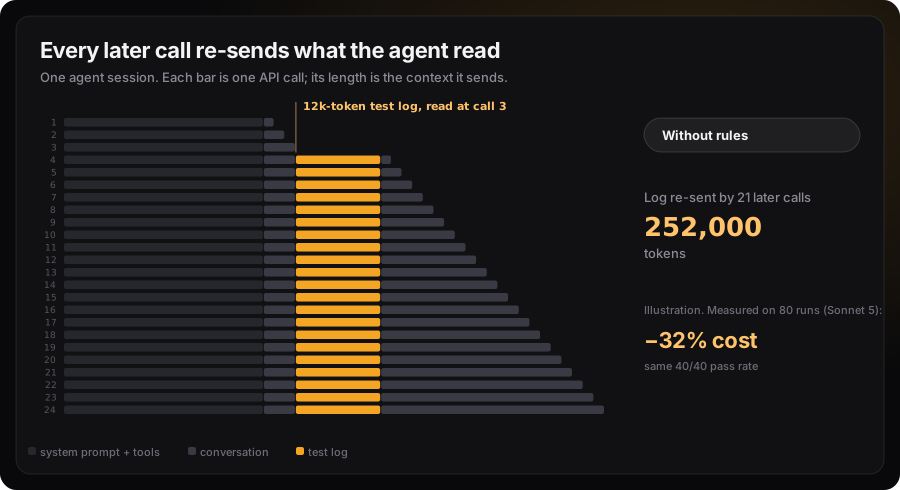
−32% cost over 80 A/B runs on Sonnet 5 with the rules, same pass rate (40/40). −20% to −28% on Haiku 4.5 with the read guard (two batches, 120 runs). Details.
Try it first, nothing to install: see where your own tokens went in ten seconds (Python 3.8+, reads your local transcripts, sends nothing).
curl -fsSL https://raw.githubusercontent.com/Pazificateur69/tokenleak/main/skills/tokenleak/scripts/tokenleak.py | python3 - --since 7d
In an agent loop, every tool result you let into context is re-sent on every later call until the context is compacted. A 6k-token test log read at call 5 of a 60-call session gets paid ~55 more times. Every extra round-trip re-sends the whole context.
So the bill isn't driven by how chatty the agent is. It's driven by what it lets into its context, and how early. In the benchmark's runs without tokenleak, everything the model wrote (replies, tool calls, thinking) was 7% of a run's cost on Sonnet and 10 to 11% on Haiku (medians); the rest was context. Shorter replies save the small part. The audit shows that split on your own sessions.
tokenleak does two things:
Claude Code (plugin, recommended). Rules injected at session start, after compaction, and into every subagent, plus a read guard: a whole-file read of a big text file (over ~24 KB) is stopped, and for code and Markdown the agent gets the file's outline instead (definitions or headings with line numbers) so it can read just the part it needs; passing limit always goes through. Adds the /tokenleak skill. Turn the guard off with TOKENLEAK_GUARD=0, or move its threshold with TOKENLEAK_GUARD_BYTES.
/plugin marketplace add Pazificateur69/tokenleak
/plugin install tokenleak@tokenleak
Codex (plugin). Same rules at session start (and in subagents where your Codex version fires that hook), plus the skill:
codex plugin marketplace add Pazificateur69/tokenleak
codex plugin add tokenleak@tokenleak
Then open /hooks in Codex to review and trust its lifecycle hook, and start a new thread.
Any agent that supports Agent Skills (Codex, Cursor, Gemini CLI, GitHub Copilot, Windsurf, Cline, OpenCode and 50+ more):
npx skills add Pazificateur69/tokenleak -g
Always on, any agent, no install. Append the rules to your instructions file (AGENTS.md, CLAUDE.md, GEMINI.md, .cursorrules…):
curl -fsSL https://raw.githubusercontent.com/Pazificateur69/tokenleak/main/skills/tokenleak/SKILL.md | awk '/^## Audit/{exit} f>=2; /^---$/{f++}' >> AGENTS.md
# no install: Python 3.8+, stdlib only, reads ~/.claude/projects and ~/.codex/sessions
curl -fsSL https://raw.githubusercontent.com/Pazificateur69/tokenleak/main/skills/tokenleak/scripts/tokenleak.py | python3 - --since 30d
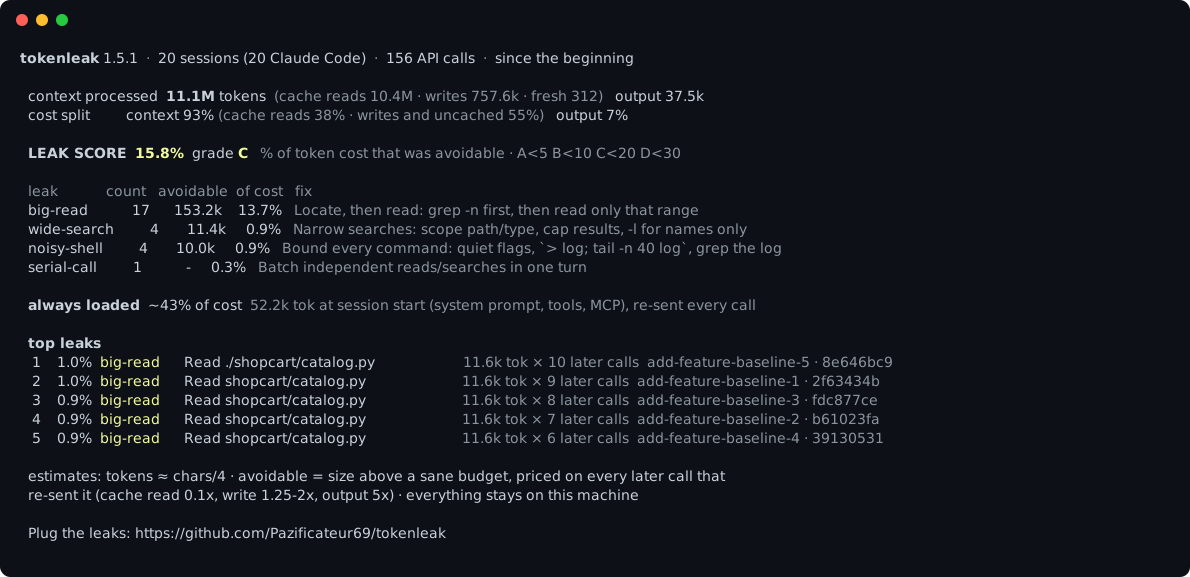
The report starts with where the money went (cost split: context, read from the cache or written to it, versus output), then every leak priced by its estimated context tax.
Or install the CLI: uvx --from git+https://github.com/Pazificateur69/tokenleak tokenleak (or pipx install git+https://github.com/Pazificateur69/tokenleak), or run it from a clone: python3 skills/tokenleak/scripts/tokenleak.py. Or just ask your agent: "audit my token leaks".
| flag | |
|---|---|
--since 24h | 7d | 4w | 2026-10-01 | all | time window (default 7d) |
--here / --current | sessions in this directory / only the latest one |
PATH… | audit specific transcript files or folders instead of the defaults |
--project TEXT, --session ID, --agent all|claude|codex | filters |
--compare 2026-10-01 | before vs after a date, e.g. the day you installed the rules: leak score and cost per call |
--top N | individual leaks to list (default 10) |
--json | machine-readable, for CI or dashboards |
--share | small anonymized card for posting |
--html report.html | self-contained HTML report to open, screenshot or send (add --redact before sharing) |
--redact | hide commands, paths and project names |
--no-color | plain output |
cd your-project && tokenleak suggest # or: python3 /path/to/tokenleak.py suggest
Reads the last 30 days of sessions in that project and prints a block to paste into its CLAUDE.md or AGENTS.md, written from what actually leaked there. Illustrative output (yours depends on your sessions):
<!-- tokenleak suggest: 23 sessions in shop-api since 2026-09-12, leak score 11.2% -->
## Token hygiene for this repo

Keep tool output out of the context; these are this repo's biggest repeat offenders:

- `npm test` printed ~9.1k tokens per run (23x). Run it as `npm test --silent 2>&1 | tail -n 40` (iterate on the one failing test).
- `git diff` printed ~3.0k tokens per run (5x). Run it as `git diff --stat` first, then `git diff -- <path>` for the files you need.
- Large files: `src/data/catalog.ts` (~18.2k tokens, read 14x). `grep -n` them, then read only the lines you need.
Only real project commands (tests, builds, installs, linters, git, docker) and files that exist in the project make the list. The skill offers to add it for you, and asks first.
The full report also ranks your projects by leak score (by project).
See the current session's leak score while you work. Add to ~/.claude/settings.json:
"statusLine": {
  "type": "command",
  "command": "python3 ~/.claude/plugins/marketplaces/tokenleak/skills/tokenleak/scripts/tokenleak.py statusline"
}
It prints leak 3.1% A · ctx 84.2k · top big-read (point the path at wherever tokenleak.py lives if you didn't install the plugin).
| leak | what happened | rule that fixes it |
|---|---|---|
big-read | a file read far bigger than the part you needed | Locate, then read |
noisy-shell | tests, builds, installs or logs dumped into context | Bound every command |
re-read | a file read again, unchanged, while still in context | Never re-read |
wasted-call | the same call, same answer, again (incl. Claude Code's "file unchanged" round-trips) | Never re-read |
serial-call | two independent reads/searches done one turn after the other | Batch independent calls |
wide-search | a search that returned pages of matches | Narrow searches |
big-fetch | a web page or MCP/API payload dumped whole | Narrow fetches |
rewrite | a whole file rewritten to change a few lines | Edit, don't rewrite |
big-result | a subagent or another tool returned a huge result | Narrow searches and fetches |
verbose-reply | long recap prose | Answer lean |
It also shows what's always loaded: your CLAUDE.md / AGENTS.md / memory files and the base context (system prompt, tools, MCP servers) re-sent on every call, with their share of your cost. Not counted as leaks, but often the cheapest win.
For each tool result: context tax = avoidable tokens × (cache write + every later call in the same context × cache read), using each provider's relative prices (Claude: cache read 0.1×, cache write 1.25–2×, output 5×; Codex/GPT-5: cached 0.1×, output 8×). Avoidable is an estimate: only the part above a sane budget counts (e.g. a 6k-token read counts as 4k avoidable), the full size only for exact repeats. The audit can't know whether a big read was truly needed, so treat each finding as a suspect, not a verdict, and judge the trend with --compare. The leak score is the share of your total token cost that this estimate calls avoidable. Dollar amounts come from Claude Code's own per-session cost (prorated when a session started before the --since window), never from a price table we maintain.
Everything stays on your machine: no network, no telemetry, ~1,500 lines of stdlib Python you can read in ten minutes.
A/B tests in Claude Code (claude -p): same prompt, a fresh copy of the same small repo for every run. The only difference is what tokenleak adds: the rules in the system prompt (what the plugin injects), and in the guard arm the plugin's read guard too. Every run is checked by a script: tests green, build passing, exact answer, feature working.
Sonnet 5, 10 runs per task and arm (two batches, 80 runs):
| task | without | with the rules | change | passed |
|---|---|---|---|---|
| fix a failing test (chatty test logs) | $0.148 | $0.140 | −5% | 10/10 · 10/10 |
| answer a question about data in a big module | $0.205 | $0.160 | −22% | 10/10 · 10/10 |
| fix a build buried in 600 lines of output | $0.270 | $0.206 | −24% | 10/10 · 10/10 |
| add a feature (held out, see below) | $0.450 | $0.222 | −51% | 10/10 · 10/10 |
| total | $1.07 | $0.73 | −32% | 40/40 · 40/40 |
Haiku 4.5, 5 runs per task and arm, two batches (120 runs):
| batch | without | rules only | rules + read guard (v1.4) | rules + read guard with outline (v1.5) | passed |
|---|---|---|---|---|---|
| 1 | $0.513 | $0.505 (−1%) | $0.408 (−20%) | 60/60 | |
| 2 | $0.530 | $0.396 (−25%) | $0.379 (−28%) | 60/60 |
Medians of the API-equivalent cost per run, as reported by Claude Code. On Sonnet, context tokens −17% and output tokens −11%. The screenshot under The audit is the audit of 20 runs without the rules.
Read it honestly.
fix-build first failed in every arm alike (3/5 each) because the sandbox blocked Apple's Python bytecode cache in ~/Library. The harness now points that cache inside the run's folder, and the 15 fix-build runs were redone for all three arms; the table uses the redone runs.add-feature task was written before that change and never used to tune them: it shows the biggest gain.--setting-sources project --strict-mcp-config) and sandboxed away from your personal folders.Every run, with the exact rules used and its token usage by type (so the cost split can be rebuilt), is in bench/results. In October 2026 the add-feature checker was made stricter (a second category, and the default report unchanged); all 55 published add-feature runs were re-checked against it and still pass. Reproduce: python3 bench/run.py --runs 5 --variants baseline,tokenleak,guard (60 runs, about $13 of API-equivalent usage on Sonnet).
The full skill is skills/tokenleak/SKILL.md. In short:
grep -n, then read only that range.tail, dig with grep. Never re-run just to see more.git diff --stat before git diff.And never save tokens by truncating away the real error, guessing file contents, or skipping verification.
Does it make the agent worse? Not in the benchmark: every run is checked by a script, and the pass rate was the same in every arm (40/40 on Sonnet, 60/60 per batch on Haiku). The guardrails are explicit: a leak is cheaper than a wrong fix.
My agent already does some of this. Good agents do. Claude Code, for one, already blocks re-reading an unchanged file; the audit counts those blocked attempts as wasted round-trips. The audit tells you how much is left on your own sessions, not on a demo.
ccusage or tokenleak? Both read the same local transcripts. ccusage tells you how much you spent, by day, session or model. tokenleak tells you which tool results made it expensive and plugs them. They work well side by side.
What about rtk, caveman and the rest? Complementary. rtk compresses command output at the shell level; output-style skills shorten replies. tokenleak changes what the agent asks for and measures the result on your real transcripts. Run the audit before and after anything you install.
What do the rules cost? About 770 tokens, re-sent on every call from the cache: over a 60-call session, about as much as 5.5k tokens of fresh input. Keeping one 6k-token test log down to 800 tokens at call 5 of that session saves about six times that.
Limitations. Token sizes of individual results are estimated (~4 chars/token); session token totals come from the usage the transcripts record, and dollars only from the sessions that record a cost. "Avoidable" is an estimate, not a measurement. serial-call is a heuristic (it only flags a call whose target was already known and isn't mentioned in the previous result). Codex transcript formats change between versions; Claude Code is the best-tested path.
Skills Directory (security grade A). Find more tools like this on Claude Market.
Issues and PRs welcome, especially transcript formats from other agents (Gemini CLI, Cursor, OpenCode) and new leak detectors. Tests: python3 -m unittest discover -s tests. Benchmark: python3 bench/run.py --runs 5.
MIT License.
See where your Claude Code and Codex tokens go: a local, read-only audit of your own transcripts, plus lean-context rules and a read guard. The rules cut cost 32% over 80 A/B runs on Sonnet 5.
See the code
Find and plug your coding agent's token leaks.
Not leaked API keys: the tokens your AI agent burns on context it didn't need.
Website · Install · Audit · Benchmark · Rules · Français
−32% cost over 80 A/B runs on Sonnet 5 with the rules, same pass rate (40/40). −20% to −28% on Haiku 4.5 with the read guard (two batches, 120 runs). Details.
Try it first, nothing to install: see where your own tokens went in ten seconds (Python 3.8+, reads your local transcripts, sends nothing).
curl -fsSL https://raw.githubusercontent.com/Pazificateur69/tokenleak/main/skills/tokenleak/scripts/tokenleak.py | python3 - --since 7d
In an agent loop, every tool result you let into context is re-sent on every later call until the context is compacted. A 6k-token test log read at call 5 of a 60-call session gets paid ~55 more times. Every extra round-trip re-sends the whole context.
So the bill isn't driven by how chatty the agent is. It's driven by what it lets into its context, and how early. In the benchmark's runs without tokenleak, everything the model wrote (replies, tool calls, thinking) was 7% of a run's cost on Sonnet and 10 to 11% on Haiku (medians); the rest was context. Shorter replies save the small part. The audit shows that split on your own sessions.
tokenleak does two things:
Claude Code (plugin, recommended). Rules injected at session start, after compaction, and into every subagent, plus a read guard: a whole-file read of a big text file (over ~24 KB) is stopped, and for code and Markdown the agent gets the file's outline instead (definitions or headings with line numbers) so it can read just the part it needs; passing limit always goes through. Adds the /tokenleak skill. Turn the guard off with TOKENLEAK_GUARD=0, or move its threshold with TOKENLEAK_GUARD_BYTES.
/plugin marketplace add Pazificateur69/tokenleak
/plugin install tokenleak@tokenleak
Codex (plugin). Same rules at session start (and in subagents where your Codex version fires that hook), plus the skill:
codex plugin marketplace add Pazificateur69/tokenleak
codex plugin add tokenleak@tokenleak
Then open /hooks in Codex to review and trust its lifecycle hook, and start a new thread.
Any agent that supports Agent Skills (Codex, Cursor, Gemini CLI, GitHub Copilot, Windsurf, Cline, OpenCode and 50+ more):
npx skills add Pazificateur69/tokenleak -g
Always on, any agent, no install. Append the rules to your instructions file (AGENTS.md, CLAUDE.md, GEMINI.md, .cursorrules…):
curl -fsSL https://raw.githubusercontent.com/Pazificateur69/tokenleak/main/skills/tokenleak/SKILL.md | awk '/^## Audit/{exit} f>=2; /^---$/{f++}' >> AGENTS.md
# no install: Python 3.8+, stdlib only, reads ~/.claude/projects and ~/.codex/sessions
curl -fsSL https://raw.githubusercontent.com/Pazificateur69/tokenleak/main/skills/tokenleak/scripts/tokenleak.py | python3 - --since 30d
The report starts with where the money went (cost split: context, read from the cache or written to it, versus output), then every leak priced by its estimated context tax.
Or install the CLI: uvx --from git+https://github.com/Pazificateur69/tokenleak tokenleak (or pipx install git+https://github.com/Pazificateur69/tokenleak), or run it from a clone: python3 skills/tokenleak/scripts/tokenleak.py. Or just ask your agent: "audit my token leaks".
| flag | |
|---|---|
--since 24h | 7d | 4w | 2026-10-01 | all | time window (default 7d) |
--here / --current | sessions in this directory / only the latest one |
PATH… | audit specific transcript files or folders instead of the defaults |
--project TEXT, --session ID, --agent all|claude|codex | filters |
--compare 2026-10-01 | before vs after a date, e.g. the day you installed the rules: leak score and cost per call |
--top N | individual leaks to list (default 10) |
--json | machine-readable, for CI or dashboards |
--share | small anonymized card for posting |
--html report.html | self-contained HTML report to open, screenshot or send (add --redact before sharing) |
--redact | hide commands, paths and project names |
--no-color | plain output |
cd your-project && tokenleak suggest # or: python3 /path/to/tokenleak.py suggest
Reads the last 30 days of sessions in that project and prints a block to paste into its CLAUDE.md or AGENTS.md, written from what actually leaked there. Illustrative output (yours depends on your sessions):
<!-- tokenleak suggest: 23 sessions in shop-api since 2026-09-12, leak score 11.2% -->
## Token hygiene for this repo

Keep tool output out of the context; these are this repo's biggest repeat offenders:

- `npm test` printed ~9.1k tokens per run (23x). Run it as `npm test --silent 2>&1 | tail -n 40` (iterate on the one failing test).
- `git diff` printed ~3.0k tokens per run (5x). Run it as `git diff --stat` first, then `git diff -- <path>` for the files you need.
- Large files: `src/data/catalog.ts` (~18.2k tokens, read 14x). `grep -n` them, then read only the lines you need.
Only real project commands (tests, builds, installs, linters, git, docker) and files that exist in the project make the list. The skill offers to add it for you, and asks first.
The full report also ranks your projects by leak score (by project).
See the current session's leak score while you work. Add to ~/.claude/settings.json:
"statusLine": {
  "type": "command",
  "command": "python3 ~/.claude/plugins/marketplaces/tokenleak/skills/tokenleak/scripts/tokenleak.py statusline"
}
It prints leak 3.1% A · ctx 84.2k · top big-read (point the path at wherever tokenleak.py lives if you didn't install the plugin).
| leak | what happened | rule that fixes it |
|---|---|---|
big-read | a file read far bigger than the part you needed | Locate, then read |
noisy-shell | tests, builds, installs or logs dumped into context | Bound every command |
re-read | a file read again, unchanged, while still in context | Never re-read |
wasted-call | the same call, same answer, again (incl. Claude Code's "file unchanged" round-trips) | Never re-read |
serial-call | two independent reads/searches done one turn after the other | Batch independent calls |
wide-search | a search that returned pages of matches | Narrow searches |
big-fetch | a web page or MCP/API payload dumped whole | Narrow fetches |
rewrite | a whole file rewritten to change a few lines | Edit, don't rewrite |
big-result | a subagent or another tool returned a huge result | Narrow searches and fetches |
verbose-reply | long recap prose | Answer lean |
It also shows what's always loaded: your CLAUDE.md / AGENTS.md / memory files and the base context (system prompt, tools, MCP servers) re-sent on every call, with their share of your cost. Not counted as leaks, but often the cheapest win.
For each tool result: context tax = avoidable tokens × (cache write + every later call in the same context × cache read), using each provider's relative prices (Claude: cache read 0.1×, cache write 1.25–2×, output 5×; Codex/GPT-5: cached 0.1×, output 8×). Avoidable is an estimate: only the part above a sane budget counts (e.g. a 6k-token read counts as 4k avoidable), the full size only for exact repeats. The audit can't know whether a big read was truly needed, so treat each finding as a suspect, not a verdict, and judge the trend with --compare. The leak score is the share of your total token cost that this estimate calls avoidable. Dollar amounts come from Claude Code's own per-session cost (prorated when a session started before the --since window), never from a price table we maintain.
Everything stays on your machine: no network, no telemetry, ~1,500 lines of stdlib Python you can read in ten minutes.
A/B tests in Claude Code (claude -p): same prompt, a fresh copy of the same small repo for every run. The only difference is what tokenleak adds: the rules in the system prompt (what the plugin injects), and in the guard arm the plugin's read guard too. Every run is checked by a script: tests green, build passing, exact answer, feature working.
Sonnet 5, 10 runs per task and arm (two batches, 80 runs):
| task | without | with the rules | change | passed |
|---|---|---|---|---|
| fix a failing test (chatty test logs) | $0.148 | $0.140 | −5% | 10/10 · 10/10 |
| answer a question about data in a big module | $0.205 | $0.160 | −22% | 10/10 · 10/10 |
| fix a build buried in 600 lines of output | $0.270 | $0.206 | −24% | 10/10 · 10/10 |
| add a feature (held out, see below) | $0.450 | $0.222 | −51% | 10/10 · 10/10 |
| total | $1.07 | $0.73 | −32% | 40/40 · 40/40 |
Haiku 4.5, 5 runs per task and arm, two batches (120 runs):
| batch | without | rules only | rules + read guard (v1.4) | rules + read guard with outline (v1.5) | passed |
|---|---|---|---|---|---|
| 1 | $0.513 | $0.505 (−1%) | $0.408 (−20%) | 60/60 | |
| 2 | $0.530 | $0.396 (−25%) | $0.379 (−28%) | 60/60 |
Medians of the API-equivalent cost per run, as reported by Claude Code. On Sonnet, context tokens −17% and output tokens −11%. The screenshot under The audit is the audit of 20 runs without the rules.
Read it honestly.
fix-build first failed in every arm alike (3/5 each) because the sandbox blocked Apple's Python bytecode cache in ~/Library. The harness now points that cache inside the run's folder, and the 15 fix-build runs were redone for all three arms; the table uses the redone runs.add-feature task was written before that change and never used to tune them: it shows the biggest gain.--setting-sources project --strict-mcp-config) and sandboxed away from your personal folders.Every run, with the exact rules used and its token usage by type (so the cost split can be rebuilt), is in bench/results. In October 2026 the add-feature checker was made stricter (a second category, and the default report unchanged); all 55 published add-feature runs were re-checked against it and still pass. Reproduce: python3 bench/run.py --runs 5 --variants baseline,tokenleak,guard (60 runs, about $13 of API-equivalent usage on Sonnet).
The full skill is skills/tokenleak/SKILL.md. In short:
grep -n, then read only that range.tail, dig with grep. Never re-run just to see more.git diff --stat before git diff.And never save tokens by truncating away the real error, guessing file contents, or skipping verification.
Does it make the agent worse? Not in the benchmark: every run is checked by a script, and the pass rate was the same in every arm (40/40 on Sonnet, 60/60 per batch on Haiku). The guardrails are explicit: a leak is cheaper than a wrong fix.
My agent already does some of this. Good agents do. Claude Code, for one, already blocks re-reading an unchanged file; the audit counts those blocked attempts as wasted round-trips. The audit tells you how much is left on your own sessions, not on a demo.
ccusage or tokenleak? Both read the same local transcripts. ccusage tells you how much you spent, by day, session or model. tokenleak tells you which tool results made it expensive and plugs them. They work well side by side.
What about rtk, caveman and the rest? Complementary. rtk compresses command output at the shell level; output-style skills shorten replies. tokenleak changes what the agent asks for and measures the result on your real transcripts. Run the audit before and after anything you install.
What do the rules cost? About 770 tokens, re-sent on every call from the cache: over a 60-call session, about as much as 5.5k tokens of fresh input. Keeping one 6k-token test log down to 800 tokens at call 5 of that session saves about six times that.
Limitations. Token sizes of individual results are estimated (~4 chars/token); session token totals come from the usage the transcripts record, and dollars only from the sessions that record a cost. "Avoidable" is an estimate, not a measurement. serial-call is a heuristic (it only flags a call whose target was already known and isn't mentioned in the previous result). Codex transcript formats change between versions; Claude Code is the best-tested path.
Skills Directory (security grade A). Find more tools like this on Claude Market.
Issues and PRs welcome, especially transcript formats from other agents (Gemini CLI, Cursor, OpenCode) and new leak detectors. Tests: python3 -m unittest discover -s tests. Benchmark: python3 bench/run.py --runs 5.
MIT License.



