
✨✨latest advancements in VLA models(VIsion Language Action)
128
25 commits
updated Feb 27, 2026
README
Awesome Vision-Language-Action (VLA) Models


This is a collection of research papers about Embodied Multimodal Large Language Models (VLA models).
If you would like to include your paper or update any details (e.g., code URLs, conference information), please feel free to submit a pull request. Any advice is also welcome!
📑 Table of Contents
Awesome VLA Models
🔥🔥🔥 ABot-M0: VLA Foundation Model for Robotic Manipulation with Action Manifold Learning
Largest unified open-source robotic manipulation dataset (6M+ trajectories) with Action Manifold Learning (AML) for direct clean action prediction.
Supports modular 3D perception for plug-and-play spatial enhancement and improved precision in complex tasks. ✨
🔥🔥🔥 RT-2: Robotics Transformer 2 — End-to-End Vision-Language-Action Model
Integrates vision-language models trained on internet-scale data directly into robotic control pipelines. ✨
🔥🔥🔥 Helix: Generalist VLA Model for Full-Body Humanoid Control
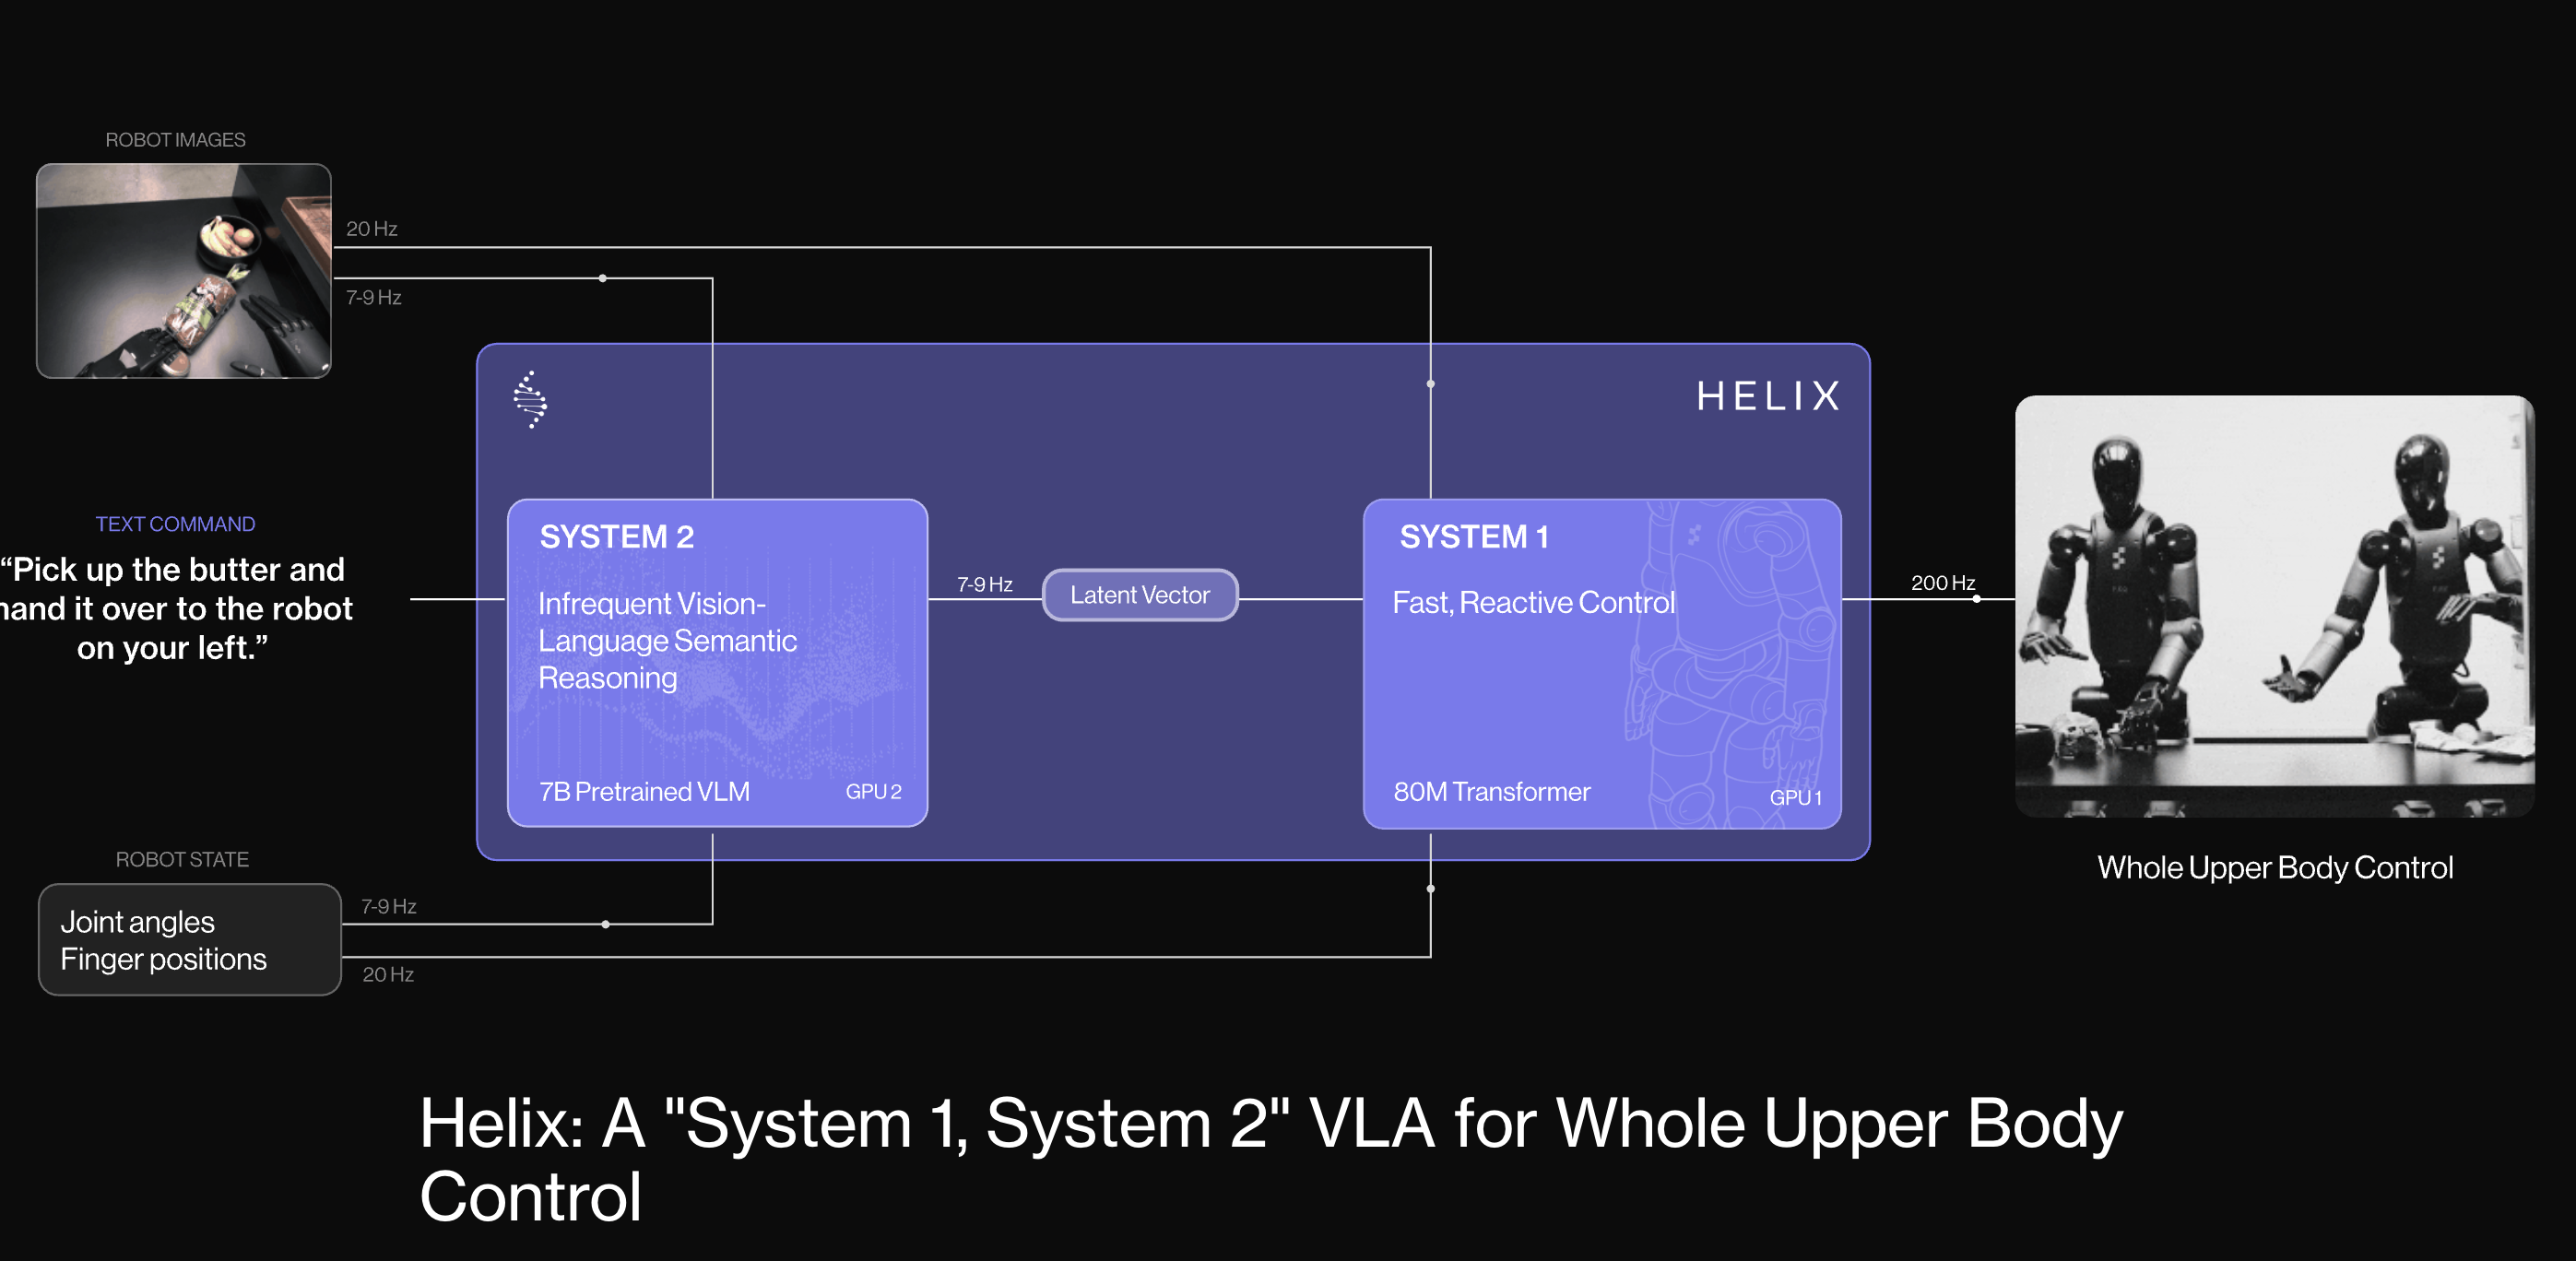
First VLA model achieving full upper-body humanoid control including fingers, wrists, torso, and head. ✨
🔥🔥🔥 π0 (Pi-Zero): Generalist VLA Across Diverse Robots
Generalist control across various robot embodiments, utilizing large-scale pretraining and flow matching action generation. ✨
🔥🔥🔥 OpenVLA: Open-Source Large-Scale Vision-Language-Action Model
📖 Paper | 🌟 Project | 🤖 Hugging Face
Pretrained on 970k+ robotic episodes, setting a new benchmark for generalist robotic policies. ✨
🔥🔥🔥 Gemini Robotics: Multimodal Generalization to Physical Action
Built on Gemini 2.0, enabling complex real-world manipulation without task-specific training. ✨
Awesome Papers
| Title | Introduction | Date | Code |
|---|---|---|---|
| PaLM-E: An Embodied Multimodal Language Model | Integrates perception, language, and action for embodied AI. | 2023-03-06 | - |
| EmbodiedGPT | Vision-language models with embodied CoT reasoning. | 2023-05-24 | Github |
| Co-LLM-Agents | Cooperative embodied agents via modular LLMs. | 2023-07-05 | Github |
| RT-2 | Transfers VLM internet knowledge to robotic control. | 2023-07-28 | - |
| LLM as Policies | Apple: LLMs for embodied tasks as policies. | 2023-10-26 | Github |
| Embodied Generalist Agent 3D | Generalist agent in 3D worlds. | 2023-11-18 | Github |
| LL3DA | Omni-3D understanding via instruction tuning. | 2023-11-30 | Github |
| NaviLLM | Generalist navigation models. | 2023-12-04 | Github |
| MP5 | Open-ended embodied agent in Minecraft. | 2023-12-12 | Github |
| ManipLLM | Object-centric robotic manipulation via LLMs. | 2023-12-24 | Github |
| MultiPLY | Multisensory 3D embodied LLMs. | 2024-01-16 | Github |
| NaVid | Next-step planning in navigation. | 2024-02-24 | - |
| ShapeLLM | 3D object understanding for embodied agents. | 2024-02-27 | Github |
| 3D-VLA | Generative 3D world model for VLA learning. | 2024-03-14 | Github |
| RoboMP² | Multimodal robotic perception-planning. | 2024-04-07 | - |
| Helix | Full-body humanoid control model. | 2024-04 | Project |
| Embodied CoT Distillation | Distilling embodied CoT into agents. | 2024-05-02 | - |
| Gemini Robotics | Real-world manipulation by Gemini. | 2024-05 | Project |
| A3VLM | Actionable articulation-aware VLMs. | 2024-06-11 | Github |
| OpenVLA | Open-sourced 7B vision-language-action model. | 2024-06-13 | Github |
| TinyVLA | Compact and efficient VLA models. | 2024-09 | Paper |
| VLA Expert Collaboration | Improves VLA via expert actions. | 2025-03 | Paper |
| ABot-M0: VLA Foundation Model for Robotic Manipulation with Action Manifold Learning | Largest unified 6M+ manipulation dataset with Action Manifold Learning for stable clean action prediction. | 2026-02 | Github |
Awesome Datasets and Benchmarks
🏗️ Scene / Environment Generation
| Title | Introduction | Date | Code |
|---|---|---|---|
| Holodeck | LLMs generate interactive 3D simulation environments. | 2023-12-14 | Github |
| PhyScene | Physically interactive 3D scenes for embodied training. | 2024-04-15 | Github |
🧠 Question Answering / Language Interaction Benchmarks
| Title | Introduction | Date | Code |
|---|---|---|---|
| OpenEQA | Visual QA benchmark for real-world scenes. | 2024-06-17 | Github |
| EQA-REAL | Real-world EmbodiedQA for indoor settings. | 2024-04 | Github |
| TEACh | Human-human embodied task dialogues. | 2023 update (original 2021) | Github |
👀 Multi-Modal Perception Datasets
| Title | Introduction | Date | Code |
|---|---|---|---|
| EmbodiedScan | Real-world RGB-D + language 3D scans. | 2023-12-26 | Github |
🕹️ End-to-End Embodied Decision Making / Simulators
| Title | Introduction | Date | Code |
|---|---|---|---|
| PCA-EVAL | Decision-making via GPT-4V evaluation. | 2023-10-03 | Github |
| UniSim | Interactive real-world simulator learning. | 2023-10-09 | - |
🏡 Household Activities / Task Benchmarks
| Title | Introduction | Date | Code |
|---|---|---|---|
| BEHAVIOR-1K | 1,000 household activity programs and scenes. | 2023-07-11 | Project |
Similar repos


✨✨latest advancements in VLA models(VIsion Language Action)
128
25 commits
updated Feb 27, 2026
README
Awesome Vision-Language-Action (VLA) Models
This is a collection of research papers about Embodied Multimodal Large Language Models (VLA models).
If you would like to include your paper or update any details (e.g., code URLs, conference information), please feel free to submit a pull request. Any advice is also welcome!
📑 Table of Contents
Awesome VLA Models
🔥🔥🔥 ABot-M0: VLA Foundation Model for Robotic Manipulation with Action Manifold Learning
Largest unified open-source robotic manipulation dataset (6M+ trajectories) with Action Manifold Learning (AML) for direct clean action prediction.
Supports modular 3D perception for plug-and-play spatial enhancement and improved precision in complex tasks. ✨
🔥🔥🔥 RT-2: Robotics Transformer 2 — End-to-End Vision-Language-Action Model
Integrates vision-language models trained on internet-scale data directly into robotic control pipelines. ✨
🔥🔥🔥 Helix: Generalist VLA Model for Full-Body Humanoid Control
First VLA model achieving full upper-body humanoid control including fingers, wrists, torso, and head. ✨
🔥🔥🔥 π0 (Pi-Zero): Generalist VLA Across Diverse Robots
Generalist control across various robot embodiments, utilizing large-scale pretraining and flow matching action generation. ✨
🔥🔥🔥 OpenVLA: Open-Source Large-Scale Vision-Language-Action Model
📖 Paper | 🌟 Project | 🤖 Hugging Face
Pretrained on 970k+ robotic episodes, setting a new benchmark for generalist robotic policies. ✨
🔥🔥🔥 Gemini Robotics: Multimodal Generalization to Physical Action
Built on Gemini 2.0, enabling complex real-world manipulation without task-specific training. ✨
Awesome Papers
| Title | Introduction | Date | Code |
|---|---|---|---|
| PaLM-E: An Embodied Multimodal Language Model | Integrates perception, language, and action for embodied AI. | 2023-03-06 | - |
| EmbodiedGPT | Vision-language models with embodied CoT reasoning. | 2023-05-24 | Github |
| Co-LLM-Agents | Cooperative embodied agents via modular LLMs. | 2023-07-05 | Github |
| RT-2 | Transfers VLM internet knowledge to robotic control. | 2023-07-28 | - |
| LLM as Policies | Apple: LLMs for embodied tasks as policies. | 2023-10-26 | Github |
| Embodied Generalist Agent 3D | Generalist agent in 3D worlds. | 2023-11-18 | Github |
| LL3DA | Omni-3D understanding via instruction tuning. | 2023-11-30 | Github |
| NaviLLM | Generalist navigation models. | 2023-12-04 | Github |
| MP5 | Open-ended embodied agent in Minecraft. | 2023-12-12 | Github |
| ManipLLM | Object-centric robotic manipulation via LLMs. | 2023-12-24 | Github |
| MultiPLY | Multisensory 3D embodied LLMs. | 2024-01-16 | Github |
| NaVid | Next-step planning in navigation. | 2024-02-24 | - |
| ShapeLLM | 3D object understanding for embodied agents. | 2024-02-27 | Github |
| 3D-VLA | Generative 3D world model for VLA learning. | 2024-03-14 | Github |
| RoboMP² | Multimodal robotic perception-planning. | 2024-04-07 | - |
| Helix | Full-body humanoid control model. | 2024-04 | Project |
| Embodied CoT Distillation | Distilling embodied CoT into agents. | 2024-05-02 | - |
| Gemini Robotics | Real-world manipulation by Gemini. | 2024-05 | Project |
| A3VLM | Actionable articulation-aware VLMs. | 2024-06-11 | Github |
| OpenVLA | Open-sourced 7B vision-language-action model. | 2024-06-13 | Github |
| TinyVLA | Compact and efficient VLA models. | 2024-09 | Paper |
| VLA Expert Collaboration | Improves VLA via expert actions. | 2025-03 | Paper |
| ABot-M0: VLA Foundation Model for Robotic Manipulation with Action Manifold Learning | Largest unified 6M+ manipulation dataset with Action Manifold Learning for stable clean action prediction. | 2026-02 | Github |
Awesome Datasets and Benchmarks
🏗️ Scene / Environment Generation
| Title | Introduction | Date | Code |
|---|---|---|---|
| Holodeck | LLMs generate interactive 3D simulation environments. | 2023-12-14 | Github |
| PhyScene | Physically interactive 3D scenes for embodied training. | 2024-04-15 | Github |
🧠 Question Answering / Language Interaction Benchmarks
| Title | Introduction | Date | Code |
|---|---|---|---|
| OpenEQA | Visual QA benchmark for real-world scenes. | 2024-06-17 | Github |
| EQA-REAL | Real-world EmbodiedQA for indoor settings. | 2024-04 | Github |
| TEACh | Human-human embodied task dialogues. | 2023 update (original 2021) | Github |
👀 Multi-Modal Perception Datasets
| Title | Introduction | Date | Code |
|---|---|---|---|
| EmbodiedScan | Real-world RGB-D + language 3D scans. | 2023-12-26 | Github |
🕹️ End-to-End Embodied Decision Making / Simulators
| Title | Introduction | Date | Code |
|---|---|---|---|
| PCA-EVAL | Decision-making via GPT-4V evaluation. | 2023-10-03 | Github |
| UniSim | Interactive real-world simulator learning. | 2023-10-09 | - |
🏡 Household Activities / Task Benchmarks
| Title | Introduction | Date | Code |
|---|---|---|---|
| BEHAVIOR-1K | 1,000 household activity programs and scenes. | 2023-07-11 | Project |