(Full name: Aino Aiko アイノ・アイコ aka 愛のAI子 aka 相野愛子)
A local-first AI companion with a browser WebUI + VRM avatar, optional simple CLI, persistent memory, web search, microphone input, and MioTTS voice output. Optimised for constrained hardware — runs on a Jetson Orin Nano with 8GB unified RAM.
Author: OppaAI · Beautiful British Columbia, Canada

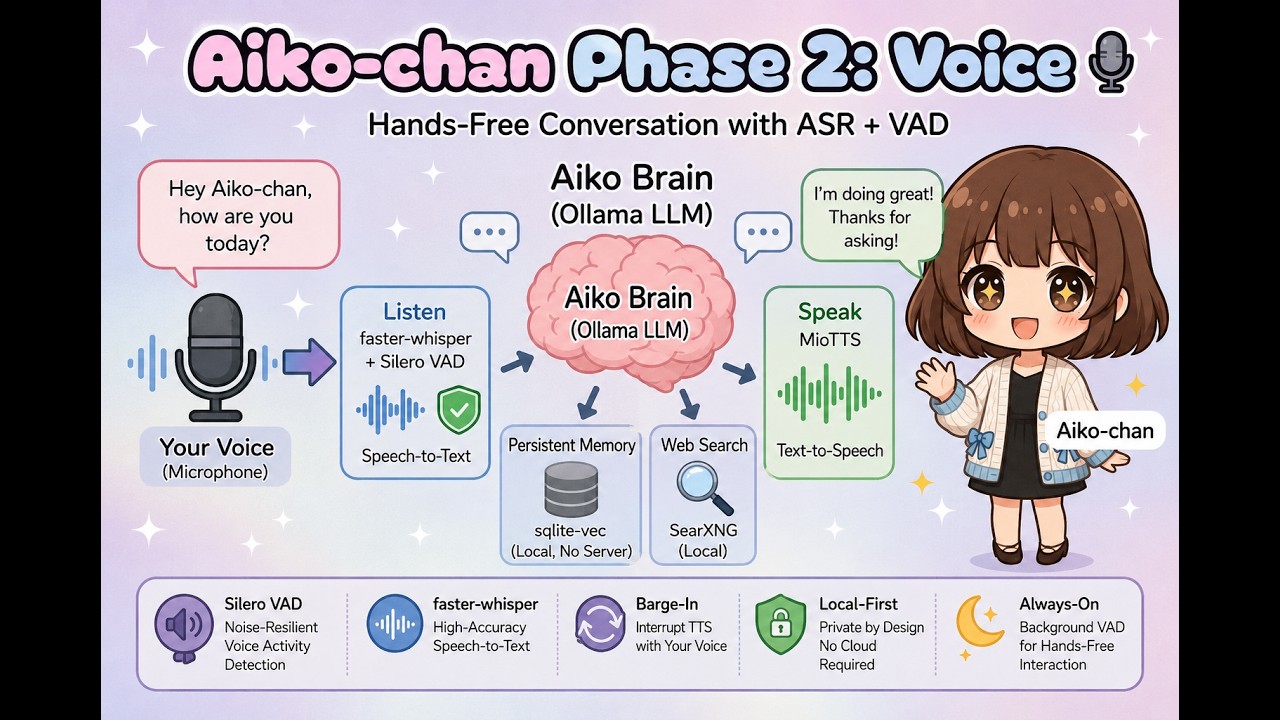
Phase 2 voice is implemented, and Phase 2.5 agentic workflows are now active. The default launch path is the browser WebUI/VRM frontend, including a WebSocket bridge for chat, vitals, voice status, expression, viseme, and browser microphone events. --cli remains available for simple local testing.
ASR and TTS run through the local machine by default. WebUI microphone streaming exists in the frontend/backend bridge, but full remote voice-device polish is still experimental.
Known Issues:
- TTS via MioTTS sometimes cannot inference proper voice output due to memory constraint (MioTTS and embedding models are still tuned for Jetson memory pressure; Harrier replaced BGE for better semantic separation at 640d)
- Time latency between ASR voice input ends to beginning of TTS voice output are still over 5 sec for normal chats. Need to figure out how to do proper synchronized text and speech streaming to save a couple seconds.
- ASR may have transcribing errors that output wrong text or even wrong language, especially when accent is present in speaker's voice or when using low quality microphone.
- Barge-in haven't been fully tested and may cause some runtime issues that needed to conduct more testing and debugging.
Click the following image to watch on YouTube ▶
This project currently serves as:
llama-server recommended), runs entirely on your hardwarepersona/SOUL.md with identity, skills, and user profile/remember command makes memories decay-proofdream() merges near-duplicates, prunes decayed memories, pins daily summariesAIKO_SQLITE_ENCRYPTION=1 for per-user encrypted databases/web <query> command — Grounded answers with source citationsparec capture (local) + browser WebAudio Worklet (WebUI)agentic/skillsets/*.mdschedule.json with cron-like recurrence, due announcementsWORKSPACE_ROOTgithub_123, patreon_456)~/.aiko/<user_id>/{memory.db, schedule.json, workspace/, user}| Document | Description |
|---|---|
| docs/INSTALL.md | Step-by-step installation for every component |
| docs/HISTORY.md | How Aiko evolved from a chatbot into a companion |
| docs/ROADMAP.md | Detailed phase-by-phase feature roadmap |
| docs/TESTS.md | Manual smoke-test checklist for each phase |
| docs/MULTI_USER.md | Multi-user isolation, encryption, and deployment notes |
| docs/ARCHITECTURE.md | Runtime architecture, module boundaries, and data flows |
flowchart TD
    YOU[You] --> UI[UI\nWebUI or CLI]
    UI --> THINK[Think\nllama.cpp/OpenAI-compatible LLM]
    THINK <-->|async| MEM[Memory\nsqlite-vec + Harrier llama.cpp server]
    THINK <-->|on demand| SEARCH[Web search\nSearXNG]
    THINK --> SPEAK[Speak\nMioTTS]
    LISTEN["Listen\nSenseVoice (sherpa-onnx) + dual energy VAD + Silero VAD"] --> THINK
    THINK -.->|nightly| DREAM[Dream\nconsolidation]
    DREAM -.->|optional| REFLECT[Reflect\nHugo + GitHub]
| Layer | Implementation |
|---|---|
| Entry point | main.py (browser WebUI default, --cli optional simple CLI) |
| Interface | browser WebUI in interface/webui/ by default; simple local CLI via --cli |
| Chat model | llama.cpp or any OpenAI-compatible local server via openai.OpenAI |
| Long-term memory | custom sqlite-vec backend (no server required) |
| Embeddings | Harrier llama.cpp, harrier-oss-v1-270m via llama.cpp server |
| Memory lifecycle | Ebbinghaus-style decay, pinned memories, nightly dream() consolidation |
| Web search | local SearXNG instance through agentic/toolkit/research.py |
| TTS | MioTTS 0.4B via llama.cpp server, external MioCodec synthesizer server |
| ASR | SenseVoice via sherpa-onnx with Silero VAD and ERes2Net Speaker verification |
| Conscience judge | Laya SLM served by the ggmlc-built laya serve binary (/v1/decide; see below) |
| Reflection publishing | optional GitHub REST API + Hugo markdown |
| Agentic task mode | agentic/agentic.py ReAct loop + agentic/toolkit/tools.py facade + agentic/toolkit/ modules |
| Skills | agentic/skillsets/*.md workflow registry loaded by agentic/skills.py |
| Scheduling | local schedule/reminder runner using ~/.aiko/<user_id>/schedule.json |
| Multi-user | OAuth provider-scoped IDs, per-user ~/.aiko/<user_id>/ isolation |
| Encryption | optional SQLCipher via AIKO_SQLITE_ENCRYPTION=1 |
Prerequisites: Python 3.12, uv, CUDA 12.6, Docker + Compose, a llama.cpp/OpenAI-compatible local LLM server, and a pulled/served chat model (3B+ recommended).
The conscience layer's Laya judge does not run on stock llama.cpp — it needs the laya serve binary built from ggmlc (compiles the PyTorch Laya model to GGUF and serves /v1/decide):
git clone https://github.com/monatis/ggmlc.git
cd ggmlc
# Follow the repo's Installation & Building docs (Python package + CMake
# native runtime, CUDA backend for Jetson), then build the laya serve binary.
Deployed layout (Jetson Orin): binary at ~/laya-bin/laya-sm86, model at models/laya/conscience-phase3-ft3-q8_0.gguf, serving /v1/decide.
Full installation walkthrough → docs/INSTALL.md
git clone https://github.com/OppaAI/Aiko-chan.git
cd Aiko-chan
cp .env.example .env        # fill secrets only; edit config/*.yaml for settings
docker compose up -d
uv sync
uv run python main.py            # browser WebUI, full voice if services are available
uv run python main.py --text      # WebUI keyboard input, ASR/TTS toggled off but loaded
uv run python main.py --cli       # simple authenticated local CLI
uv run python main.py --debug     # show memory hits each turn
uv run python main.py --clear-mem # wipe all memories and exit
| Command | Action |
|---|---|
/quit or /exit | End the session |
/reset | Clear short-term context; long-term memory persists |
/memory | Print all stored memories |
/clear | Wipe all long-term memories |
/remember | Pin the last exchange — decay-proof |
/think <question> | Higher-token reasoning turn; suppresses 🤔 scratchpad |
/web <query> | SearXNG search → grounded answer |
/voice | Toggle TTS on/off |
/listen | Toggle ASR on/off |
/proactive | Toggle proactive idle check-ins on/off; timing, quiet/focus windows, and prompt hints configured in config/proactive.yaml |
/help | Show the command list |
Aiko-chan/
├── main.py                 # entry point; WebUI default, --cli for simple local testing
├── config/                 # category YAML settings; secrets stay in .env
├── cognition/
│   ├── think.py            # chat facade, routing, history, scheduled-job callbacks
│   └── reason.py           # shared embedding/ranking helpers
├── memory/
│   ├── memorize.py         # sqlite-vec memory, recall, pinned memories
│   ├── vecstore.py         # SQLite/sqlite-vec helpers
│   ├── forget.py           # decay scoring and cleanup gates
│   ├── consolidate.py      # periodic memory consolidation
│   ├── journal.py          # encrypted journal blob store
│   └── reflect.py          # Hugo/GitHub reflection publisher
├── sensory/
│   ├── speak.py            # MioTTS HTTP client
│   └── listen.py           # SenseVoice (sherpa-onnx) + Silero VAD
├── agentic/
│   ├── agentic.py          # ReAct task loop, tool schemas, tool dispatch
│   ├── schema.py           # graph-first playbook DAG executor
│   ├── capability.py       # capability matching for task-mode tool filtering
│   ├── experience.py       # procedural task-run experience store
│   ├── skills.py           # skill registry and workflow retrieval
│   ├── tools.py            # stable facade for pure callable tools
│   ├── wiki.py             # wiki-card retrieval for task mode
│   ├── skillsets/          # human-readable workflow documents
│   └── toolkit/            # focused tool implementations: research, planning, schedule, photo, repo, jobs
├── system/                 # config, wakeup, schedule runner, logging, userspace
├── interface/
│   ├── webui/              # browser WebUI backend + static frontend/VRM bridge
│   └── cli/                # auth and simple CLI helpers
├── persona/                # soul/personality and prompt policy files
├── wiki/                   # trusted local knowledge cards
├── docs/                   # install, architecture, roadmap, tests, history
├── assets/                 # images and VRM assets
├── docker-compose.yml
├── pyproject.toml
├── uv.lock
├── .env.example
└── README.md
| Phase | Name | Status |
|---|---|---|
| 1 | Soul — CLI, Ollama, mem0 + Qdrant, SearXNG | ✅ Done |
| 1.5 | Stream — streaming pipeline, persona, first UI, test TTS models | ✅ Done |
| 2 | Voice — SenseVoice ASR, Silero VAD, MioTTS, hands-free talk | ✅ Done |
| 2.1 | Social — X, Threads, IG, Discord, social media | 🔲 Planned |
| 2.2 | Message — Email, Telegram, Discord, Slack, messaging services | 🔲 Planned |
| 2.5 | Agent — tool registry, skill workflows, scheduled local tasks | ⏳ Active |
| 3 | Face — VRM avatar, three-vrm, expressions, lip-sync | 🔲 Planned |
| 4 | Presence — emotional state, mood, relationship progression | 🔲 Planned |
| 5 | Mobile — React Native / Flutter, WAN, push notifications | 🔲 Planned |
| 6 | Multimodal — camera, vision input, webcam expression awareness | 🔲 Planned |
| 7 | Autonomy — scheduled operation, self-directed exploration | 🔲 Planned |
Full details → docs/ROADMAP.md
All non-secret runtime settings live in config/*.yaml. Environment variables in .env override YAML at runtime.
| Config file | Purpose |
|---|---|
config/index.yaml | Ordered list of YAML files loaded at startup |
config/system.yaml | Identity, logging, userspace, schedule, reflection/social settings |
config/cognition.yaml | LLM endpoints, routing, token limits, vector-cache settings |
config/memory.yaml | Memory, embedding, decay, experience, consolidation settings |
config/skills.yaml | Agentic routing thresholds, tool configs, graph executor settings |
config/sensory.yaml | MioTTS, ASR, VAD, speaker verification, and barge-in settings |
config/interface.yaml | WebUI ports, avatar path, streaming behavior |
| Phase | Before | After |
|---|---|---|
| 1 → 1.5 | CLI + Ollama + mem0/Qdrant | Browser WebUI + llama.cpp + streaming |
| 1.5 → 2 | Text-only | Voice loop: SenseVoice + Silero VAD + MioTTS |
| 2 | mem0 + Qdrant (server, OOM on Jetson) | sqlite-vec + custom Harrier ONNX (serverless, local) |
| 2 | fastembed (BGE v1.5) | Harrier OSS v1 270M Q8 GGUF embedder (640d, last-token pooling) |
| 2 → 2.5 | Chat only | Agentic ReAct loop + skills + scheduling + toolkit |
| 2.5 | Keyword-only routing | Dual-path: semantic exemplar + optional LLM router |
Key architectural decisions:
main.py, not cli.py anymore.LLM_BASE_URL/LLM_MODEL), usually llama.cpp llama-server; older Ollama-specific settings are archived/outdated.GITHUB_TOKEN or GITHUB_REPO are missing.~/.aiko/<user_id>/ with optional SQLCipher encryption.If you find this project useful, consider buying me a coffee ☕

AIKO_MESSENGER_ADAPTERS; only Telegram, Discord, Matrix, and Slack are supported for conversational ingress/egress.#aiko_dev, and Threads when image hosting is available. YouTube remains video-upload only, not YouTube Community teaser posting. Lane A2 manual posting remains out of Aiko.This project uses the JLPT vocabulary and kanji dataset from OpenJLPT (© evanclan), licensed under CC BY-SA 4.0: https://creativecommons.org/licenses/by-sa/4.0/
Used unmodified, as distributed.
OpenJLPT itself is built from:
See OpenJLPT's own NOTICE.md for the complete field-by-field source list.
This work (the dataset as included here) remains licensed under CC BY-SA 4.0.
(Full name: Aino Aiko アイノ・アイコ aka 愛のAI子 aka 相野愛子)
A local-first AI companion with a browser WebUI + VRM avatar, optional simple CLI, persistent memory, web search, microphone input, and MioTTS voice output. Optimised for constrained hardware — runs on a Jetson Orin Nano with 8GB unified RAM.
Author: OppaAI · Beautiful British Columbia, Canada
Phase 2 voice is implemented, and Phase 2.5 agentic workflows are now active. The default launch path is the browser WebUI/VRM frontend, including a WebSocket bridge for chat, vitals, voice status, expression, viseme, and browser microphone events. --cli remains available for simple local testing.
ASR and TTS run through the local machine by default. WebUI microphone streaming exists in the frontend/backend bridge, but full remote voice-device polish is still experimental.
Known Issues:
- TTS via MioTTS sometimes cannot inference proper voice output due to memory constraint (MioTTS and embedding models are still tuned for Jetson memory pressure; Harrier replaced BGE for better semantic separation at 640d)
- Time latency between ASR voice input ends to beginning of TTS voice output are still over 5 sec for normal chats. Need to figure out how to do proper synchronized text and speech streaming to save a couple seconds.
- ASR may have transcribing errors that output wrong text or even wrong language, especially when accent is present in speaker's voice or when using low quality microphone.
- Barge-in haven't been fully tested and may cause some runtime issues that needed to conduct more testing and debugging.
Click the following image to watch on YouTube ▶
This project currently serves as:
llama-server recommended), runs entirely on your hardwarepersona/SOUL.md with identity, skills, and user profile/remember command makes memories decay-proofdream() merges near-duplicates, prunes decayed memories, pins daily summariesAIKO_SQLITE_ENCRYPTION=1 for per-user encrypted databases/web <query> command — Grounded answers with source citationsparec capture (local) + browser WebAudio Worklet (WebUI)agentic/skillsets/*.mdschedule.json with cron-like recurrence, due announcementsWORKSPACE_ROOTgithub_123, patreon_456)~/.aiko/<user_id>/{memory.db, schedule.json, workspace/, user}| Document | Description |
|---|---|
| docs/INSTALL.md | Step-by-step installation for every component |
| docs/HISTORY.md | How Aiko evolved from a chatbot into a companion |
| docs/ROADMAP.md | Detailed phase-by-phase feature roadmap |
| docs/TESTS.md | Manual smoke-test checklist for each phase |
| docs/MULTI_USER.md | Multi-user isolation, encryption, and deployment notes |
| docs/ARCHITECTURE.md | Runtime architecture, module boundaries, and data flows |
flowchart TD
    YOU[You] --> UI[UI\nWebUI or CLI]
    UI --> THINK[Think\nllama.cpp/OpenAI-compatible LLM]
    THINK <-->|async| MEM[Memory\nsqlite-vec + Harrier llama.cpp server]
    THINK <-->|on demand| SEARCH[Web search\nSearXNG]
    THINK --> SPEAK[Speak\nMioTTS]
    LISTEN["Listen\nSenseVoice (sherpa-onnx) + dual energy VAD + Silero VAD"] --> THINK
    THINK -.->|nightly| DREAM[Dream\nconsolidation]
    DREAM -.->|optional| REFLECT[Reflect\nHugo + GitHub]
| Layer | Implementation |
|---|---|
| Entry point | main.py (browser WebUI default, --cli optional simple CLI) |
| Interface | browser WebUI in interface/webui/ by default; simple local CLI via --cli |
| Chat model | llama.cpp or any OpenAI-compatible local server via openai.OpenAI |
| Long-term memory | custom sqlite-vec backend (no server required) |
| Embeddings | Harrier llama.cpp, harrier-oss-v1-270m via llama.cpp server |
| Memory lifecycle | Ebbinghaus-style decay, pinned memories, nightly dream() consolidation |
| Web search | local SearXNG instance through agentic/toolkit/research.py |
| TTS | MioTTS 0.4B via llama.cpp server, external MioCodec synthesizer server |
| ASR | SenseVoice via sherpa-onnx with Silero VAD and ERes2Net Speaker verification |
| Conscience judge | Laya SLM served by the ggmlc-built laya serve binary (/v1/decide; see below) |
| Reflection publishing | optional GitHub REST API + Hugo markdown |
| Agentic task mode | agentic/agentic.py ReAct loop + agentic/toolkit/tools.py facade + agentic/toolkit/ modules |
| Skills | agentic/skillsets/*.md workflow registry loaded by agentic/skills.py |
| Scheduling | local schedule/reminder runner using ~/.aiko/<user_id>/schedule.json |
| Multi-user | OAuth provider-scoped IDs, per-user ~/.aiko/<user_id>/ isolation |
| Encryption | optional SQLCipher via AIKO_SQLITE_ENCRYPTION=1 |
Prerequisites: Python 3.12, uv, CUDA 12.6, Docker + Compose, a llama.cpp/OpenAI-compatible local LLM server, and a pulled/served chat model (3B+ recommended).
The conscience layer's Laya judge does not run on stock llama.cpp — it needs the laya serve binary built from ggmlc (compiles the PyTorch Laya model to GGUF and serves /v1/decide):
git clone https://github.com/monatis/ggmlc.git
cd ggmlc
# Follow the repo's Installation & Building docs (Python package + CMake
# native runtime, CUDA backend for Jetson), then build the laya serve binary.
Deployed layout (Jetson Orin): binary at ~/laya-bin/laya-sm86, model at models/laya/conscience-phase3-ft3-q8_0.gguf, serving /v1/decide.
Full installation walkthrough → docs/INSTALL.md
git clone https://github.com/OppaAI/Aiko-chan.git
cd Aiko-chan
cp .env.example .env        # fill secrets only; edit config/*.yaml for settings
docker compose up -d
uv sync
uv run python main.py            # browser WebUI, full voice if services are available
uv run python main.py --text      # WebUI keyboard input, ASR/TTS toggled off but loaded
uv run python main.py --cli       # simple authenticated local CLI
uv run python main.py --debug     # show memory hits each turn
uv run python main.py --clear-mem # wipe all memories and exit
| Command | Action |
|---|---|
/quit or /exit | End the session |
/reset | Clear short-term context; long-term memory persists |
/memory | Print all stored memories |
/clear | Wipe all long-term memories |
/remember | Pin the last exchange — decay-proof |
/think <question> | Higher-token reasoning turn; suppresses 🤔 scratchpad |
/web <query> | SearXNG search → grounded answer |
/voice | Toggle TTS on/off |
/listen | Toggle ASR on/off |
/proactive | Toggle proactive idle check-ins on/off; timing, quiet/focus windows, and prompt hints configured in config/proactive.yaml |
/help | Show the command list |
Aiko-chan/
├── main.py                 # entry point; WebUI default, --cli for simple local testing
├── config/                 # category YAML settings; secrets stay in .env
├── cognition/
│   ├── think.py            # chat facade, routing, history, scheduled-job callbacks
│   └── reason.py           # shared embedding/ranking helpers
├── memory/
│   ├── memorize.py         # sqlite-vec memory, recall, pinned memories
│   ├── vecstore.py         # SQLite/sqlite-vec helpers
│   ├── forget.py           # decay scoring and cleanup gates
│   ├── consolidate.py      # periodic memory consolidation
│   ├── journal.py          # encrypted journal blob store
│   └── reflect.py          # Hugo/GitHub reflection publisher
├── sensory/
│   ├── speak.py            # MioTTS HTTP client
│   └── listen.py           # SenseVoice (sherpa-onnx) + Silero VAD
├── agentic/
│   ├── agentic.py          # ReAct task loop, tool schemas, tool dispatch
│   ├── schema.py           # graph-first playbook DAG executor
│   ├── capability.py       # capability matching for task-mode tool filtering
│   ├── experience.py       # procedural task-run experience store
│   ├── skills.py           # skill registry and workflow retrieval
│   ├── tools.py            # stable facade for pure callable tools
│   ├── wiki.py             # wiki-card retrieval for task mode
│   ├── skillsets/          # human-readable workflow documents
│   └── toolkit/            # focused tool implementations: research, planning, schedule, photo, repo, jobs
├── system/                 # config, wakeup, schedule runner, logging, userspace
├── interface/
│   ├── webui/              # browser WebUI backend + static frontend/VRM bridge
│   └── cli/                # auth and simple CLI helpers
├── persona/                # soul/personality and prompt policy files
├── wiki/                   # trusted local knowledge cards
├── docs/                   # install, architecture, roadmap, tests, history
├── assets/                 # images and VRM assets
├── docker-compose.yml
├── pyproject.toml
├── uv.lock
├── .env.example
└── README.md
| Phase | Name | Status |
|---|---|---|
| 1 | Soul — CLI, Ollama, mem0 + Qdrant, SearXNG | ✅ Done |
| 1.5 | Stream — streaming pipeline, persona, first UI, test TTS models | ✅ Done |
| 2 | Voice — SenseVoice ASR, Silero VAD, MioTTS, hands-free talk | ✅ Done |
| 2.1 | Social — X, Threads, IG, Discord, social media | 🔲 Planned |
| 2.2 | Message — Email, Telegram, Discord, Slack, messaging services | 🔲 Planned |
| 2.5 | Agent — tool registry, skill workflows, scheduled local tasks | ⏳ Active |
| 3 | Face — VRM avatar, three-vrm, expressions, lip-sync | 🔲 Planned |
| 4 | Presence — emotional state, mood, relationship progression | 🔲 Planned |
| 5 | Mobile — React Native / Flutter, WAN, push notifications | 🔲 Planned |
| 6 | Multimodal — camera, vision input, webcam expression awareness | 🔲 Planned |
| 7 | Autonomy — scheduled operation, self-directed exploration | 🔲 Planned |
Full details → docs/ROADMAP.md
All non-secret runtime settings live in config/*.yaml. Environment variables in .env override YAML at runtime.
| Config file | Purpose |
|---|---|
config/index.yaml | Ordered list of YAML files loaded at startup |
config/system.yaml | Identity, logging, userspace, schedule, reflection/social settings |
config/cognition.yaml | LLM endpoints, routing, token limits, vector-cache settings |
config/memory.yaml | Memory, embedding, decay, experience, consolidation settings |
config/skills.yaml | Agentic routing thresholds, tool configs, graph executor settings |
config/sensory.yaml | MioTTS, ASR, VAD, speaker verification, and barge-in settings |
config/interface.yaml | WebUI ports, avatar path, streaming behavior |
| Phase | Before | After |
|---|---|---|
| 1 → 1.5 | CLI + Ollama + mem0/Qdrant | Browser WebUI + llama.cpp + streaming |
| 1.5 → 2 | Text-only | Voice loop: SenseVoice + Silero VAD + MioTTS |
| 2 | mem0 + Qdrant (server, OOM on Jetson) | sqlite-vec + custom Harrier ONNX (serverless, local) |
| 2 | fastembed (BGE v1.5) | Harrier OSS v1 270M Q8 GGUF embedder (640d, last-token pooling) |
| 2 → 2.5 | Chat only | Agentic ReAct loop + skills + scheduling + toolkit |
| 2.5 | Keyword-only routing | Dual-path: semantic exemplar + optional LLM router |
Key architectural decisions:
main.py, not cli.py anymore.LLM_BASE_URL/LLM_MODEL), usually llama.cpp llama-server; older Ollama-specific settings are archived/outdated.GITHUB_TOKEN or GITHUB_REPO are missing.~/.aiko/<user_id>/ with optional SQLCipher encryption.If you find this project useful, consider buying me a coffee ☕
AIKO_MESSENGER_ADAPTERS; only Telegram, Discord, Matrix, and Slack are supported for conversational ingress/egress.#aiko_dev, and Threads when image hosting is available. YouTube remains video-upload only, not YouTube Community teaser posting. Lane A2 manual posting remains out of Aiko.This project uses the JLPT vocabulary and kanji dataset from OpenJLPT (© evanclan), licensed under CC BY-SA 4.0: https://creativecommons.org/licenses/by-sa/4.0/
Used unmodified, as distributed.
OpenJLPT itself is built from:
See OpenJLPT's own NOTICE.md for the complete field-by-field source list.
This work (the dataset as included here) remains licensed under CC BY-SA 4.0.



