
See what people are saying
README
This is a fork maintained by NimbleMarkets. It focuses on hosting ds4 as a shared library for use in projects like ds4go.
DwarfStar aims to be the best way to run a few excellent large language models on consumer hardware (that is, hardware that people can actually own). To reach this goal, we are building a small native inference engine optimized first for DeepSeek V4 Flash (including the experimental vision model), DeepSeek V4.1 Flash (Metal, and text inference on CUDA), and additionally GLM 5.2 and 5.3, GLM 5.3 Flash and DeepSeek V4 PRO, and Qwen3.8 Flash Next (Metal and CUDA). The code is self-contained and deliberately narrow, not a general GGUF runner: you need to use the GGUF files the project produces, that are part of the project itself.
We test things in integration: model loading, prompt rendering, tool calls, KV state, the HTTP server, and the coding agent are built and tested together. The repository also includes tools and data for GGUF, imatrix, quality, and speed.
Supported hardware
- Metal, the primary target, on Macs with 96 GB or more. Smaller machines can use SSD streaming. SSD streaming is also needed in order to run very large models such as full GLM 5.x (not Flash) on 128GB systems.
- NVIDIA CUDA, the DGX Spark is our main gaol. DwarfStar also supports multi-GPU systems that are not supported by other backends, for instance it can run DeepSeek v4 Flash on Ada Lovelace cards.
- ROCm on Strix Halo systems such as the Framework Desktop.
This project would not exist without llama.cpp and GGML, make sure to read the acknowledgements section, a big thank you to Georgi Gerganov and all the other contributors.
Model support is intentionally opportunistic. The project follows the best open weights for useful local machine sizes, especially 128 GB laptops and 256/512 GB workstations. A model may be removed when a better replacement arrives.
So, what can I do with this software?
- You can run a very capable models in your consumer hardware, a MacBook, a DGX Spark, or a Strix Halo for example. Even if you have not enough RAM, with SSD streaming, you can run it at a decent speed.
- You can use multiple CUDA cards as a multi-user LLM server. Ada Lovelace, including L40S, is supported: newer models can run here even when their other inference implementations require newer GPUs. Our eight-L40S Flash setup has reached about 126 t/s aggregate generation with 16 sessions.
- Using two 128 GB Macs connected with RDMA, you can run 4-bit DeepSeek Flash or GLM 5.3 Flash with tensor parallelism. Larger GLM 5.2 quants need larger machines, such as Mac Studios.
- You can also use pipeline paralellism to glue together multiple systems to sum their RAM and run larger models.
Motivations
- Capable open-weight models now fit on high-end personal machines.
- DeepSeek V4 Flash and PRO, GLM 5.2, tolerate aggressive routed-expert quantization.
- Compressed KV caches and fast local SSDs make long contexts practical.
- The idea of an inference system specialized for a few models.
AI full disclosure
- This software is developed with strong assistance from AI coding agents and with humans leading the ideas, testing, and debugging. We say this openly because it shaped how the project was built. If you are not happy with AI-developed code, this software is not for you. The acknowledgement below is equally important: this would not exist without
llama.cppand GGML, largely written by hand.
Acknowledgements to llama.cpp and GGML
ds4.c does not link against GGML, but it exists thanks to the path opened by the
llama.cpp project and the kernels, quantization formats, GGUF ecosystem, and hard-won
engineering knowledge developed there.
We are thankful and indebted to llama.cpp
and its contributors. Their implementation, kernels, tests, and design choices were
an essential reference while building this DeepSeek V4 specific inference path.
Some source-level pieces are retained or adapted here under the MIT license: GGUF
quant layouts and tables, CPU quant/dot logic, and certain kernels. For this
reason, and because we are genuinely grateful, we keep the GGML authors copyright
notice in our LICENSE file.
Status
The software is currently very fast changing. Consider it beta quality. Before each release, a big QA run is executed, however instabilities and regressions are definitely possible.
How to use this project?
I (Salvatore) believe that the way projects should be shipped and used changed because of AI. The main differences today are:
- With AI, users can modify the software in significant ways with low efforts, costs, and even lacking deep domain knowledge about the task they want to accomplish. For instance, a DwarfStar user with a specific hardware setup can ask a coding agent to improve the inference speed of this software for the specific hardware setup, asking the model to reach the maximum prefill and generation speed without impacting correctness, and also asking to do a deep QA pass.
- Similiarly, because of "1", software may be shipped in a different way than before. It must be more a working template for the biggest use cases, without trying to cover every possible setup. If DwarfStar showcases a few good implementations of tensor parallel execution, the code will work as a rail for implementing the same feature in specific conditions, for a new model, and so forth.
So, while this project attempts to be usable for the featured models and the most common hardware setups, I ask you, if you have access to coding agents, to consider using coding agents as an interface to discover the project, make modifications, create personalized setups. This way you can likely do more than what we ship, and certain things that are not documented or implemented, and that you require, are potentially very easy to achieve.
Start Here
git clone https://github.com/antirez/ds4.git
cd ds4
Choose your build. The platform guides cover prerequisites, memory sizing, and hardware-specific setups:
| Platform guide | Build |
|---|---|
| Metal on Apple Silicon | make |
| DGX Spark | make cuda-spark |
| Strix Halo / Framework Desktop | make strix-halo |
| One or more CUDA cards, including Ada/L40S | make cuda-generic |
For a first run on a 96 or 128 GB machine, download DeepSeek V4 Flash Q2:
./download_model.sh ds4f-q2
Downloads go in gguf/. Repeat the command to resume an interrupted download.
Leave memory for the context and runtime buffers as well as the model.
See other models or use SSD streaming
on a smaller Mac.
Everyday Use
Once built and with a model downloaded:
./ds4
./ds4 -p "Explain Redis streams in one paragraph."
./ds4-agent
./ds4-server --ctx 32768
The default model is ds4flash.gguf, a link updated by main-model downloads.
Pass -m FILE to choose explicitly. Commands normally run from the repository
root; use --chdir /path/to/ds4 when launching elsewhere.
The server listens at http://127.0.0.1:8000 by default; see serving
for API access and multiple sessions.
The interactive CLI keeps a multi-turn conversation. Use /help, /read FILE,
/ctx N, and /quit. Ctrl+C interrupts generation and returns to the prompt.
Run each binary with --help for its full options.
Native coding agent
ds4-agent runs inference directly, without a separate HTTP server. It keeps
the token history and live model state together, shows prefill progress, and
uses the model's native tool format. DeepSeek and GLM have their own templates.
Use /hints on for occasional, brief explanations of the programming choices
behind the work, and /hints off to stop them. Changes take effect at the next
conversation boundary without rebuilding the cached context. New and resumed
sessions start with hints off.
Sessions are stored in ~/.ds4/kvcache:
| Command | Action |
|---|---|
/save | Save the current session |
/list | List saved sessions |
/switch <sha> | Resume a session |
/del <sha> | Delete a saved session |
/strip <sha> | Keep text and title, removing the large KV payload |
Compatible local KV snapshots avoid rebuilding the prompt. Stripped sessions and network TP restores require prefill. Sessions containing images cannot yet be saved. Saved conversations and traces may contain private information.
For Pi, OpenCode, Codex CLI, or Claude Code, use ds4-server instead and follow
the client setup guide.
Models, images, and speculation
Models and vision lists the supported downloads and memory requirements. DeepSeek Vision Experimental uses a different checkpoint from Flash 0731; GLM 5.3 Flash and Qwen3.8 Flash Next add vision to the same text model through a separate encoder.
DeepSeek V4.1 Flash text and vision run on Metal; text also runs on a DGX Spark. Q2 runs with SSD streaming on one 128 GB Mac or Spark, or resident across two Macs or two Sparks using RDMA. Q4 needs SSD streaming or a 512 GB Mac. Engram tables remain on disk in every mode, so use a fast local SSD. See the model guide for downloads and setup.
With the matching encoder passed as --vision FILE, use /read image.png
in the CLI or view_image in the native agent.
Qwen3.8's smaller Q2 release has 41.73 GiB of main/MTP weights, with imatrix IQ2_XXS gate/up experts and padded Q2_K down projections. It is the starting option for 64 GB Macs. The GGUF also contains 95.37 GiB of original BF16 n-grams, read directly from disk rather than loaded into RAM. Keep it on a fast SSD. Start with 8K context:
./download_model.sh qwen38-q2
./ds4 --ctx 8192 --prefill-chunk 1024
The download fetches one 137.10 GiB file and updates ds4flash.gguf.
Add --mtp for speculative decoding. The larger
qwen38-q4k target is also available. Download the optional vision encoder
with ./download_model.sh qwen38-vision and pass it with --vision.
See Qwen setup for details.
Speculative decoding is opt-in. GLM and Qwen use --mtp; V4 Flash DSpark needs a matching
support GGUF. It can improve generation, but not every workload benefits.
Read speculative decoding for setup and the
difference between default opportunistic sampling and --mtp-exact-sampling.
Output and power
Thinking is enabled by default. Use --nothink or /nothink for direct
answers, and --think or /think to enable it again.
For V4.1, ds4 and ds4-agent also accept
--think-level 25 or /think 25: 1 to 100 sets the reasoning effort, and
0 disables thinking. --think selects 75, --think-max selects 100.
Changing the level in a conversation rebuilds its cached prefix.
The normal sampling defaults are temperature 1, top-p 1, and min-p 0.05;
--temp 0 selects greedy output.
For DeepSeek V4, --power N trades throughput for lower sustained GPU load.
The default is 100. V4.1 and GLM currently require --power 100.
DeepSeek V4 Flash and GLM 5.3 Flash also support directional steering. Load a
vector with --dir-steering-file FILE; /steer F adjusts its scale for
subsequent tokens in a local CLI or agent session, without rebuilding the
existing KV cache. See steering documentation.
--prefix-file FILE preloads complete USER: / ASSISTANT: pairs before
the live conversation. A turn marker must start a line, roles must alternate,
and the last turn must be ASSISTANT:.
Capability Evaluation
ds4-eval runs embedded capability regression tests against a real GGUF.
These are DwarfStar integration checks, not official leaderboard scores.
./ds4-eval -m ds4flash.gguf --trace /tmp/ds4-eval.txt
./ds4-eval -m ds4flash.gguf --suite hard-smoke
./ds4-eval -m ds4flash.gguf --suite hard --retry-incomplete
The default suite is core; --suite all runs core and hard cases.
--list-cases lists tests without loading a model. --plain selects
non-interactive output, and --regrade-trace FILE scores an existing trace
without generating again. Sources and licenses are in EVAL_DATA.md.
For inference correctness and release checks, read testing.
Speed
This recorded DeepSeek V4 Flash Q2 sweep uses an M5 Max with 128 GB RAM, 2048-token continued-prefill intervals, and 128 greedy generation tokens per frontier. It is a baseline, not a fresh benchmark of every commit.
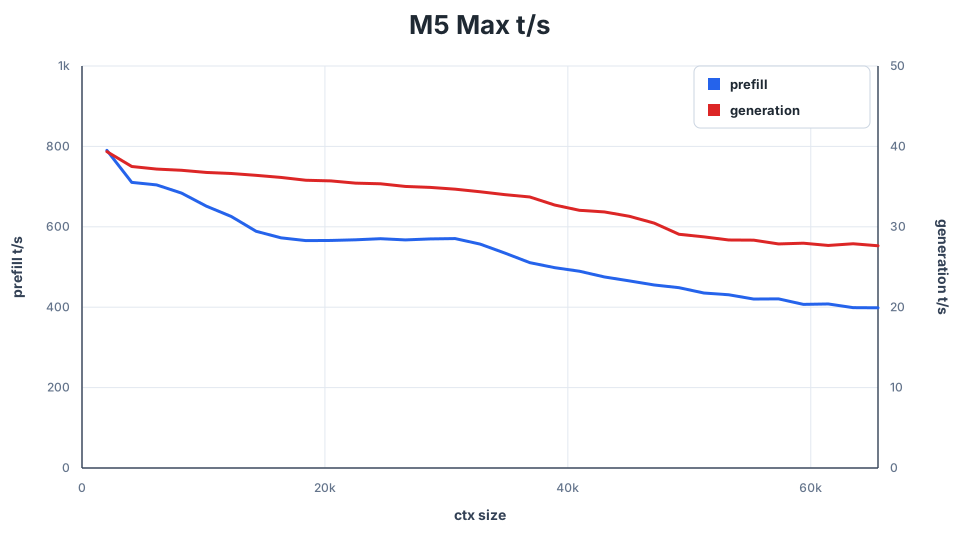
See performance and benchmarking for the full numbers, DGX Spark results, comparison conditions, and benchmark commands.
Detailed Guides
- Models and vision: Flash, PRO, GLM, Qwen, and matching encoders.
- Qwen3.8 Flash Next: model setup, MTP, vision, and validation.
- SSD streaming: run larger than RAM and size the cache.
- Inference across machines: two-Mac TP/RDMA and layer pipelines.
- Speculative decoding: DSpark, GLM and Qwen MTP, and sampling.
- Serving: APIs, images, batching, and disk KV caches.
- Coding agent clients: Pi, OpenCode, Codex CLI, and Claude Code.
- Performance: reproducible measurements and recorded baselines.
- Testing and development: regression tests, debugging, and model-building tools.
Read CONTRIBUTING.md before sending a pull request.
Logo
The DwarfStar logo was designed by hand by Salvatore Sanfilippo, made more graphical with AI, and manually reworked by Ben Gnomino, whose human touch made it rock.
Similar repos


Languages
C
47.1%
Cuda
24.6%
Objective-C
12.7%
Metal
7.4%
Python
4.8%
C++
2.7%
See what people are saying
README
This is a fork maintained by NimbleMarkets. It focuses on hosting ds4 as a shared library for use in projects like ds4go.
DwarfStar aims to be the best way to run a few excellent large language models on consumer hardware (that is, hardware that people can actually own). To reach this goal, we are building a small native inference engine optimized first for DeepSeek V4 Flash (including the experimental vision model), DeepSeek V4.1 Flash (Metal, and text inference on CUDA), and additionally GLM 5.2 and 5.3, GLM 5.3 Flash and DeepSeek V4 PRO, and Qwen3.8 Flash Next (Metal and CUDA). The code is self-contained and deliberately narrow, not a general GGUF runner: you need to use the GGUF files the project produces, that are part of the project itself.
We test things in integration: model loading, prompt rendering, tool calls, KV state, the HTTP server, and the coding agent are built and tested together. The repository also includes tools and data for GGUF, imatrix, quality, and speed.
Supported hardware
- Metal, the primary target, on Macs with 96 GB or more. Smaller machines can use SSD streaming. SSD streaming is also needed in order to run very large models such as full GLM 5.x (not Flash) on 128GB systems.
- NVIDIA CUDA, the DGX Spark is our main gaol. DwarfStar also supports multi-GPU systems that are not supported by other backends, for instance it can run DeepSeek v4 Flash on Ada Lovelace cards.
- ROCm on Strix Halo systems such as the Framework Desktop.
This project would not exist without llama.cpp and GGML, make sure to read the acknowledgements section, a big thank you to Georgi Gerganov and all the other contributors.
Model support is intentionally opportunistic. The project follows the best open weights for useful local machine sizes, especially 128 GB laptops and 256/512 GB workstations. A model may be removed when a better replacement arrives.
So, what can I do with this software?
- You can run a very capable models in your consumer hardware, a MacBook, a DGX Spark, or a Strix Halo for example. Even if you have not enough RAM, with SSD streaming, you can run it at a decent speed.
- You can use multiple CUDA cards as a multi-user LLM server. Ada Lovelace, including L40S, is supported: newer models can run here even when their other inference implementations require newer GPUs. Our eight-L40S Flash setup has reached about 126 t/s aggregate generation with 16 sessions.
- Using two 128 GB Macs connected with RDMA, you can run 4-bit DeepSeek Flash or GLM 5.3 Flash with tensor parallelism. Larger GLM 5.2 quants need larger machines, such as Mac Studios.
- You can also use pipeline paralellism to glue together multiple systems to sum their RAM and run larger models.
Motivations
- Capable open-weight models now fit on high-end personal machines.
- DeepSeek V4 Flash and PRO, GLM 5.2, tolerate aggressive routed-expert quantization.
- Compressed KV caches and fast local SSDs make long contexts practical.
- The idea of an inference system specialized for a few models.
AI full disclosure
- This software is developed with strong assistance from AI coding agents and with humans leading the ideas, testing, and debugging. We say this openly because it shaped how the project was built. If you are not happy with AI-developed code, this software is not for you. The acknowledgement below is equally important: this would not exist without
llama.cppand GGML, largely written by hand.
Acknowledgements to llama.cpp and GGML
ds4.c does not link against GGML, but it exists thanks to the path opened by the
llama.cpp project and the kernels, quantization formats, GGUF ecosystem, and hard-won
engineering knowledge developed there.
We are thankful and indebted to llama.cpp
and its contributors. Their implementation, kernels, tests, and design choices were
an essential reference while building this DeepSeek V4 specific inference path.
Some source-level pieces are retained or adapted here under the MIT license: GGUF
quant layouts and tables, CPU quant/dot logic, and certain kernels. For this
reason, and because we are genuinely grateful, we keep the GGML authors copyright
notice in our LICENSE file.
Status
The software is currently very fast changing. Consider it beta quality. Before each release, a big QA run is executed, however instabilities and regressions are definitely possible.
How to use this project?
I (Salvatore) believe that the way projects should be shipped and used changed because of AI. The main differences today are:
- With AI, users can modify the software in significant ways with low efforts, costs, and even lacking deep domain knowledge about the task they want to accomplish. For instance, a DwarfStar user with a specific hardware setup can ask a coding agent to improve the inference speed of this software for the specific hardware setup, asking the model to reach the maximum prefill and generation speed without impacting correctness, and also asking to do a deep QA pass.
- Similiarly, because of "1", software may be shipped in a different way than before. It must be more a working template for the biggest use cases, without trying to cover every possible setup. If DwarfStar showcases a few good implementations of tensor parallel execution, the code will work as a rail for implementing the same feature in specific conditions, for a new model, and so forth.
So, while this project attempts to be usable for the featured models and the most common hardware setups, I ask you, if you have access to coding agents, to consider using coding agents as an interface to discover the project, make modifications, create personalized setups. This way you can likely do more than what we ship, and certain things that are not documented or implemented, and that you require, are potentially very easy to achieve.
Start Here
git clone https://github.com/antirez/ds4.git
cd ds4
Choose your build. The platform guides cover prerequisites, memory sizing, and hardware-specific setups:
| Platform guide | Build |
|---|---|
| Metal on Apple Silicon | make |
| DGX Spark | make cuda-spark |
| Strix Halo / Framework Desktop | make strix-halo |
| One or more CUDA cards, including Ada/L40S | make cuda-generic |
For a first run on a 96 or 128 GB machine, download DeepSeek V4 Flash Q2:
./download_model.sh ds4f-q2
Downloads go in gguf/. Repeat the command to resume an interrupted download.
Leave memory for the context and runtime buffers as well as the model.
See other models or use SSD streaming
on a smaller Mac.
Everyday Use
Once built and with a model downloaded:
./ds4
./ds4 -p "Explain Redis streams in one paragraph."
./ds4-agent
./ds4-server --ctx 32768
The default model is ds4flash.gguf, a link updated by main-model downloads.
Pass -m FILE to choose explicitly. Commands normally run from the repository
root; use --chdir /path/to/ds4 when launching elsewhere.
The server listens at http://127.0.0.1:8000 by default; see serving
for API access and multiple sessions.
The interactive CLI keeps a multi-turn conversation. Use /help, /read FILE,
/ctx N, and /quit. Ctrl+C interrupts generation and returns to the prompt.
Run each binary with --help for its full options.
Native coding agent
ds4-agent runs inference directly, without a separate HTTP server. It keeps
the token history and live model state together, shows prefill progress, and
uses the model's native tool format. DeepSeek and GLM have their own templates.
Use /hints on for occasional, brief explanations of the programming choices
behind the work, and /hints off to stop them. Changes take effect at the next
conversation boundary without rebuilding the cached context. New and resumed
sessions start with hints off.
Sessions are stored in ~/.ds4/kvcache:
| Command | Action |
|---|---|
/save | Save the current session |
/list | List saved sessions |
/switch <sha> | Resume a session |
/del <sha> | Delete a saved session |
/strip <sha> | Keep text and title, removing the large KV payload |
Compatible local KV snapshots avoid rebuilding the prompt. Stripped sessions and network TP restores require prefill. Sessions containing images cannot yet be saved. Saved conversations and traces may contain private information.
For Pi, OpenCode, Codex CLI, or Claude Code, use ds4-server instead and follow
the client setup guide.
Models, images, and speculation
Models and vision lists the supported downloads and memory requirements. DeepSeek Vision Experimental uses a different checkpoint from Flash 0731; GLM 5.3 Flash and Qwen3.8 Flash Next add vision to the same text model through a separate encoder.
DeepSeek V4.1 Flash text and vision run on Metal; text also runs on a DGX Spark. Q2 runs with SSD streaming on one 128 GB Mac or Spark, or resident across two Macs or two Sparks using RDMA. Q4 needs SSD streaming or a 512 GB Mac. Engram tables remain on disk in every mode, so use a fast local SSD. See the model guide for downloads and setup.
With the matching encoder passed as --vision FILE, use /read image.png
in the CLI or view_image in the native agent.
Qwen3.8's smaller Q2 release has 41.73 GiB of main/MTP weights, with imatrix IQ2_XXS gate/up experts and padded Q2_K down projections. It is the starting option for 64 GB Macs. The GGUF also contains 95.37 GiB of original BF16 n-grams, read directly from disk rather than loaded into RAM. Keep it on a fast SSD. Start with 8K context:
./download_model.sh qwen38-q2
./ds4 --ctx 8192 --prefill-chunk 1024
The download fetches one 137.10 GiB file and updates ds4flash.gguf.
Add --mtp for speculative decoding. The larger
qwen38-q4k target is also available. Download the optional vision encoder
with ./download_model.sh qwen38-vision and pass it with --vision.
See Qwen setup for details.
Speculative decoding is opt-in. GLM and Qwen use --mtp; V4 Flash DSpark needs a matching
support GGUF. It can improve generation, but not every workload benefits.
Read speculative decoding for setup and the
difference between default opportunistic sampling and --mtp-exact-sampling.
Output and power
Thinking is enabled by default. Use --nothink or /nothink for direct
answers, and --think or /think to enable it again.
For V4.1, ds4 and ds4-agent also accept
--think-level 25 or /think 25: 1 to 100 sets the reasoning effort, and
0 disables thinking. --think selects 75, --think-max selects 100.
Changing the level in a conversation rebuilds its cached prefix.
The normal sampling defaults are temperature 1, top-p 1, and min-p 0.05;
--temp 0 selects greedy output.
For DeepSeek V4, --power N trades throughput for lower sustained GPU load.
The default is 100. V4.1 and GLM currently require --power 100.
DeepSeek V4 Flash and GLM 5.3 Flash also support directional steering. Load a
vector with --dir-steering-file FILE; /steer F adjusts its scale for
subsequent tokens in a local CLI or agent session, without rebuilding the
existing KV cache. See steering documentation.
--prefix-file FILE preloads complete USER: / ASSISTANT: pairs before
the live conversation. A turn marker must start a line, roles must alternate,
and the last turn must be ASSISTANT:.
Capability Evaluation
ds4-eval runs embedded capability regression tests against a real GGUF.
These are DwarfStar integration checks, not official leaderboard scores.
./ds4-eval -m ds4flash.gguf --trace /tmp/ds4-eval.txt
./ds4-eval -m ds4flash.gguf --suite hard-smoke
./ds4-eval -m ds4flash.gguf --suite hard --retry-incomplete
The default suite is core; --suite all runs core and hard cases.
--list-cases lists tests without loading a model. --plain selects
non-interactive output, and --regrade-trace FILE scores an existing trace
without generating again. Sources and licenses are in EVAL_DATA.md.
For inference correctness and release checks, read testing.
Speed
This recorded DeepSeek V4 Flash Q2 sweep uses an M5 Max with 128 GB RAM, 2048-token continued-prefill intervals, and 128 greedy generation tokens per frontier. It is a baseline, not a fresh benchmark of every commit.
See performance and benchmarking for the full numbers, DGX Spark results, comparison conditions, and benchmark commands.
Detailed Guides
- Models and vision: Flash, PRO, GLM, Qwen, and matching encoders.
- Qwen3.8 Flash Next: model setup, MTP, vision, and validation.
- SSD streaming: run larger than RAM and size the cache.
- Inference across machines: two-Mac TP/RDMA and layer pipelines.
- Speculative decoding: DSpark, GLM and Qwen MTP, and sampling.
- Serving: APIs, images, batching, and disk KV caches.
- Coding agent clients: Pi, OpenCode, Codex CLI, and Claude Code.
- Performance: reproducible measurements and recorded baselines.
- Testing and development: regression tests, debugging, and model-building tools.
Read CONTRIBUTING.md before sending a pull request.
Logo
The DwarfStar logo was designed by hand by Salvatore Sanfilippo, made more graphical with AI, and manually reworked by Ben Gnomino, whose human touch made it rock.
Similar repos
Languages
C
47.1%
Cuda
24.6%
Objective-C
12.7%
Metal
7.4%
Python
4.8%
C++
2.7%