[ACL 2025 Main] (🏆 Outstanding Paper Award) Rethinking the Role of Prompting Strategies in LLM Test-Time Scaling: A Perspective of Probability Theory
Python
20
32 commits
updated Aug 15, 2025


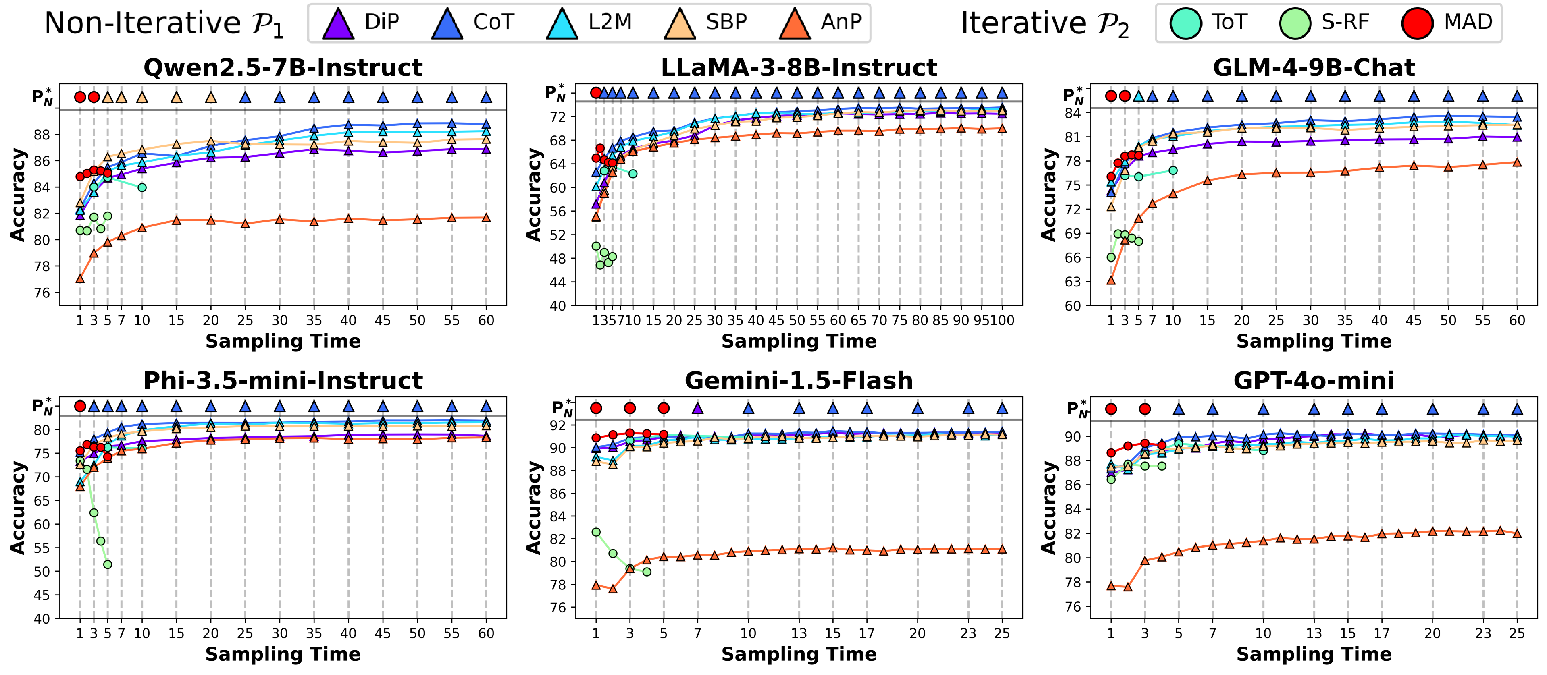
Recently, scaling test-time compute on Large Language Models (LLM) has garnered wide attention. However, there has been limited investigation of how various reasoning prompting strategies perform as scaling. In this paper, we focus on a standard and realistic scaling setting: majority voting. We systematically conduct experiments on 6 LLMs $\times$ 8 prompting strategies $\times$ 6 benchmarks. Experiment results consistently show that as the sampling time and computational overhead increase, complicated prompting strategies with superior initial performance gradually fall behind simple Chain-of-Thought. We analyze this phenomenon and provide theoretical proofs. Additionally, we propose a probabilistic method to efficiently predict scaling performance and identify the best prompting strategy under large sampling times, eliminating the need for resource-intensive inference processes in practical applications. Furthermore, we introduce two ways derived from our theoretical analysis to significantly improve the scaling performance. We hope that our research can promote to re-examine the role of complicated prompting, unleash the potential of simple prompting strategies, and provide new insights for enhancing test-time scaling performance.
git clone https://github.com/MraDonkey/rethinking_prompting.git
cd rethinking_prompting
conda create -n rethinking_prompting  python=3.11
conda activate rethinking_prompting
pip install -r requirements.txt
Before running the framework, you need to set up your API keys for different LLM providers:
openai_api_keyopenai_base_urlgoogle_api_keyComplete the variables hf_token in main.py and base_path in dataset.py.
For example, to get the inference results of all prompting strategies with Qwen2.5-7B-Instruct on GSM8K, you can run this script.
bash scripts/Qwen_GSM8K.sh
You can further customize hyperparameters to suit your specific requirements.
To evaluate the performance of all tested prompting strategies:
python eval_csv_N.py    --model_name "your_model" --dataset "your_dataset"
python eval_csv_cost.py --model_name "your_model" --dataset "your_dataset"
You can customize the variable sampling_times to adjust the points in the figure, in the style of Figure 1 and 2 in our paper.
Should you find our work beneficial to your research, we would appreciate citations to our paper and GitHub stars to support ongoing development. ⭐
@inproceedings{liu-etal-2025-rethinking,
    title = "Rethinking the Role of Prompting Strategies in {LLM} Test-Time Scaling: A Perspective of Probability Theory",
    author = "Liu, Yexiang  and
      Li, Zekun  and
      Fang, Zhi  and
      Xu, Nan  and
      He, Ran  and
      Tan, Tieniu",
    editor = "Che, Wanxiang  and
      Nabende, Joyce  and
      Shutova, Ekaterina  and
      Pilehvar, Mohammad Taher",
    booktitle = "Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)",
    month = jul,
    year = "2025",
    address = "Vienna, Austria",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2025.acl-long.1356/",
    doi = "10.18653/v1/2025.acl-long.1356",
    pages = "27962--27994",
    ISBN = "979-8-89176-251-0"
}
[ACL 2025 Main] (🏆 Outstanding Paper Award) Rethinking the Role of Prompting Strategies in LLM Test-Time Scaling: A Perspective of Probability Theory
Python
20
32 commits
updated Aug 15, 2025
Recently, scaling test-time compute on Large Language Models (LLM) has garnered wide attention. However, there has been limited investigation of how various reasoning prompting strategies perform as scaling. In this paper, we focus on a standard and realistic scaling setting: majority voting. We systematically conduct experiments on 6 LLMs $\times$ 8 prompting strategies $\times$ 6 benchmarks. Experiment results consistently show that as the sampling time and computational overhead increase, complicated prompting strategies with superior initial performance gradually fall behind simple Chain-of-Thought. We analyze this phenomenon and provide theoretical proofs. Additionally, we propose a probabilistic method to efficiently predict scaling performance and identify the best prompting strategy under large sampling times, eliminating the need for resource-intensive inference processes in practical applications. Furthermore, we introduce two ways derived from our theoretical analysis to significantly improve the scaling performance. We hope that our research can promote to re-examine the role of complicated prompting, unleash the potential of simple prompting strategies, and provide new insights for enhancing test-time scaling performance.
git clone https://github.com/MraDonkey/rethinking_prompting.git
cd rethinking_prompting
conda create -n rethinking_prompting  python=3.11
conda activate rethinking_prompting
pip install -r requirements.txt
Before running the framework, you need to set up your API keys for different LLM providers:
openai_api_keyopenai_base_urlgoogle_api_keyComplete the variables hf_token in main.py and base_path in dataset.py.
For example, to get the inference results of all prompting strategies with Qwen2.5-7B-Instruct on GSM8K, you can run this script.
bash scripts/Qwen_GSM8K.sh
You can further customize hyperparameters to suit your specific requirements.
To evaluate the performance of all tested prompting strategies:
python eval_csv_N.py    --model_name "your_model" --dataset "your_dataset"
python eval_csv_cost.py --model_name "your_model" --dataset "your_dataset"
You can customize the variable sampling_times to adjust the points in the figure, in the style of Figure 1 and 2 in our paper.
Should you find our work beneficial to your research, we would appreciate citations to our paper and GitHub stars to support ongoing development. ⭐
@inproceedings{liu-etal-2025-rethinking,
    title = "Rethinking the Role of Prompting Strategies in {LLM} Test-Time Scaling: A Perspective of Probability Theory",
    author = "Liu, Yexiang  and
      Li, Zekun  and
      Fang, Zhi  and
      Xu, Nan  and
      He, Ran  and
      Tan, Tieniu",
    editor = "Che, Wanxiang  and
      Nabende, Joyce  and
      Shutova, Ekaterina  and
      Pilehvar, Mohammad Taher",
    booktitle = "Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)",
    month = jul,
    year = "2025",
    address = "Vienna, Austria",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2025.acl-long.1356/",
    doi = "10.18653/v1/2025.acl-long.1356",
    pages = "27962--27994",
    ISBN = "979-8-89176-251-0"
}



