
README
Curious-VLA
Devil is in Narrow Policy: Unleashing Exploration in Driving VLA Models



News
- 🎉 Our New work Coarse-to-Refine: Trajectory Self-Refinement in Single Autoregressive Pass for Driving VLA has been accepted to NeurIPS'26. Coarse-to-Refine is a successor to CuriousVLA, code will be released soon in this repo.
- 🎉 CuriousVLA has been accepted to CVPR'26 Findings. CuriousVLA can serve as a strong MLLM auto-regressive driving baseline.
Release
- Paper release
- Model weights on HuggingFace
- Prompt Construction and Evaluation code
- Quick Start of environment (SFT + RL + deploy unified; NAVSIM kept independent)
- Training data (IL stage). See HuggingFace.
- SFT-stage model weights. See HuggingFace.
- Training code (RL stage: Basic reward function api server + SDR)
- Training code (RL stage: ADAS)
- Released GRPO filtered tokens for quick start(for the model
curious_vla_qwen2_5_vl_3b_sft_stage2).
The items listed above are now available.
- Whole Data Engine
- Lightning-fast(15x throughput) reward function api server, and faster evaluation
The remaining items will be released in future updates.
Overview
Abstract
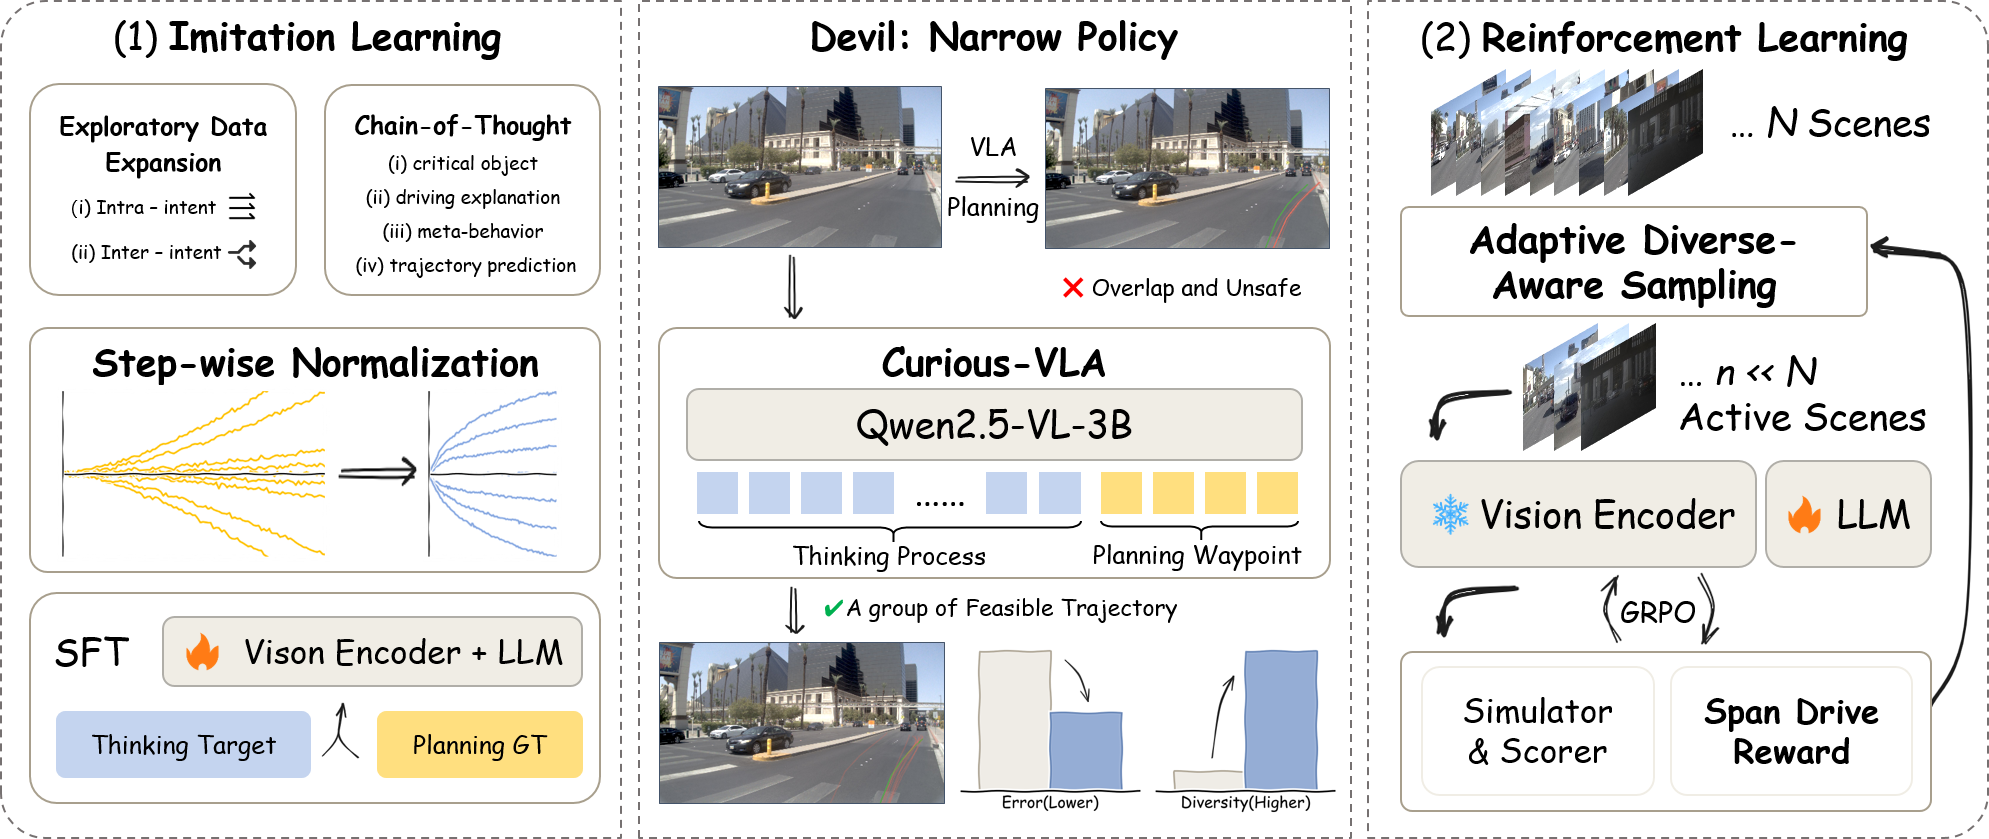
Imitation Learning (IL) followed by Reinforcement Learning (RL) has emerged as a powerful paradigm for Vision-Language-Action (VLA) models in autonomous driving. However, we identify a critical bottleneck: IL training produces overly narrow policies that collapse exploration and limit the potential of subsequent RL stages, causing RL to saturate prematurely due to insufficient feedback diversity.
We propose Curious-VLA, a two-stage framework that unleashes exploration across both IL and RL stages through three key designs:
- Feasible Trajectory Expansion (FTE): Generates multiple physically valid trajectories with step-wise normalized representation during IL, broadening the behavioral diversity of the learned policy.
- Adaptive Diversity-Aware Sampling (ADAS): Prioritizes high-diversity samples during RL to maintain exploration breadth.
- Spanning Driving Reward (SDR): Uses focal-style weighting to amplify the reward's value span, improving sensitivity to differences in driving quality.
Results
Performance on the Navsim benchmark:
| Method | PDMS | EPDMS(V2) | Best-of-N PDMS |
|---|---|---|---|
| Curious-VLA | 90.3 | 85.4 | 94.8 |
Model Zoo
| Model | Base | Link |
|---|---|---|
| Curious-VLA | Qwen2.5-VL-3B-Instruct | HuggingFace |
Getting Started
Start with the unified quick start guide:
Evaluation
See docs/deploy.md.
Training
1. Imitation Learning(SFT)
See docs/train_sft.md.
2. Reinforcement Learning(GRPO)
See docs/train_grpo.md.
The RL parquet data is not stored in this repository and is ignored by git. Download it from:
Place it under:
EasyR1/data/QA_navtrain_poutine_style_full/data/
├── train.parquet
└── test.parquet
For example:
cd /path/to/curious_vla/EasyR1/data
huggingface-cli download MashiroLn/Curious-VLA --repo-type dataset --local-dir QA_navtrain_poutine_style_full
Released token-filter file for direct GRPO training:
token_filters/curious_vla_qwen2_5_vl_3b_sft_stage2_adas1x_6k.txt
This file was recovered from the early filtered training subset navsim_normtrajtext_cot_filter_dynamic_6k/data/train.parquet. It contains one token per line and can be used directly as data.token_filter_file in GRPO training.
Recommended:
- use the released SFT checkpoint
curious_vla_qwen2_5_vl_3b_sft_stage2 - use the released filter file above
- start GRPO directly without rerunning ADAS
Optional:
- rerun ADAS yourself
- replace the default
ADAS_FILTER_FILEwith your own ADAS output
Citation
If you find this work useful, please consider citing:
@misc{chen2026devilnarrowpolicyunleashing,
      title={Devil is in Narrow Policy: Unleashing Exploration in Driving VLA Models},
      author={Canyu Chen and Yuguang Yang and Zhewen Tan and Yizhi Wang and Ruiyi Zhan and Haiyan Liu and Xuanyao Mao and Jason Bao and Xinyue Tang and Linlin Yang and Bingchuan Sun and Yan Wang and Baochang Zhang},
      year={2026},
      eprint={2603.06049},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2603.06049},
}
Acknowledgements
This project is built upon Qwen2.5-VL, Navsim, EasyR1, VeRL. Code for Navsim Agent is inspired by ReCogDrive. We thank the open-source community for their contributions.
License
This project is released under the Apache 2.0 License.
Contributors


Similar repos


Languages
Python
93.8%
Shell
3.6%
HTML
1.4%
README
Curious-VLA
Devil is in Narrow Policy: Unleashing Exploration in Driving VLA Models
News
- 🎉 Our New work Coarse-to-Refine: Trajectory Self-Refinement in Single Autoregressive Pass for Driving VLA has been accepted to NeurIPS'26. Coarse-to-Refine is a successor to CuriousVLA, code will be released soon in this repo.
- 🎉 CuriousVLA has been accepted to CVPR'26 Findings. CuriousVLA can serve as a strong MLLM auto-regressive driving baseline.
Release
- Paper release
- Model weights on HuggingFace
- Prompt Construction and Evaluation code
- Quick Start of environment (SFT + RL + deploy unified; NAVSIM kept independent)
- Training data (IL stage). See HuggingFace.
- SFT-stage model weights. See HuggingFace.
- Training code (RL stage: Basic reward function api server + SDR)
- Training code (RL stage: ADAS)
- Released GRPO filtered tokens for quick start(for the model
curious_vla_qwen2_5_vl_3b_sft_stage2).
The items listed above are now available.
- Whole Data Engine
- Lightning-fast(15x throughput) reward function api server, and faster evaluation
The remaining items will be released in future updates.
Overview
Abstract
Imitation Learning (IL) followed by Reinforcement Learning (RL) has emerged as a powerful paradigm for Vision-Language-Action (VLA) models in autonomous driving. However, we identify a critical bottleneck: IL training produces overly narrow policies that collapse exploration and limit the potential of subsequent RL stages, causing RL to saturate prematurely due to insufficient feedback diversity.
We propose Curious-VLA, a two-stage framework that unleashes exploration across both IL and RL stages through three key designs:
- Feasible Trajectory Expansion (FTE): Generates multiple physically valid trajectories with step-wise normalized representation during IL, broadening the behavioral diversity of the learned policy.
- Adaptive Diversity-Aware Sampling (ADAS): Prioritizes high-diversity samples during RL to maintain exploration breadth.
- Spanning Driving Reward (SDR): Uses focal-style weighting to amplify the reward's value span, improving sensitivity to differences in driving quality.
Results
Performance on the Navsim benchmark:
| Method | PDMS | EPDMS(V2) | Best-of-N PDMS |
|---|---|---|---|
| Curious-VLA | 90.3 | 85.4 | 94.8 |
Model Zoo
| Model | Base | Link |
|---|---|---|
| Curious-VLA | Qwen2.5-VL-3B-Instruct | HuggingFace |
Getting Started
Start with the unified quick start guide:
Evaluation
See docs/deploy.md.
Training
1. Imitation Learning(SFT)
See docs/train_sft.md.
2. Reinforcement Learning(GRPO)
See docs/train_grpo.md.
The RL parquet data is not stored in this repository and is ignored by git. Download it from:
Place it under:
EasyR1/data/QA_navtrain_poutine_style_full/data/
├── train.parquet
└── test.parquet
For example:
cd /path/to/curious_vla/EasyR1/data
huggingface-cli download MashiroLn/Curious-VLA --repo-type dataset --local-dir QA_navtrain_poutine_style_full
Released token-filter file for direct GRPO training:
token_filters/curious_vla_qwen2_5_vl_3b_sft_stage2_adas1x_6k.txt
This file was recovered from the early filtered training subset navsim_normtrajtext_cot_filter_dynamic_6k/data/train.parquet. It contains one token per line and can be used directly as data.token_filter_file in GRPO training.
Recommended:
- use the released SFT checkpoint
curious_vla_qwen2_5_vl_3b_sft_stage2 - use the released filter file above
- start GRPO directly without rerunning ADAS
Optional:
- rerun ADAS yourself
- replace the default
ADAS_FILTER_FILEwith your own ADAS output
Citation
If you find this work useful, please consider citing:
@misc{chen2026devilnarrowpolicyunleashing,
      title={Devil is in Narrow Policy: Unleashing Exploration in Driving VLA Models},
      author={Canyu Chen and Yuguang Yang and Zhewen Tan and Yizhi Wang and Ruiyi Zhan and Haiyan Liu and Xuanyao Mao and Jason Bao and Xinyue Tang and Linlin Yang and Bingchuan Sun and Yan Wang and Baochang Zhang},
      year={2026},
      eprint={2603.06049},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2603.06049},
}
Acknowledgements
This project is built upon Qwen2.5-VL, Navsim, EasyR1, VeRL. Code for Navsim Agent is inspired by ReCogDrive. We thank the open-source community for their contributions.
License
This project is released under the Apache 2.0 License.
Similar repos
Contributors
Languages
Python
93.8%
Shell
3.6%
HTML
1.4%