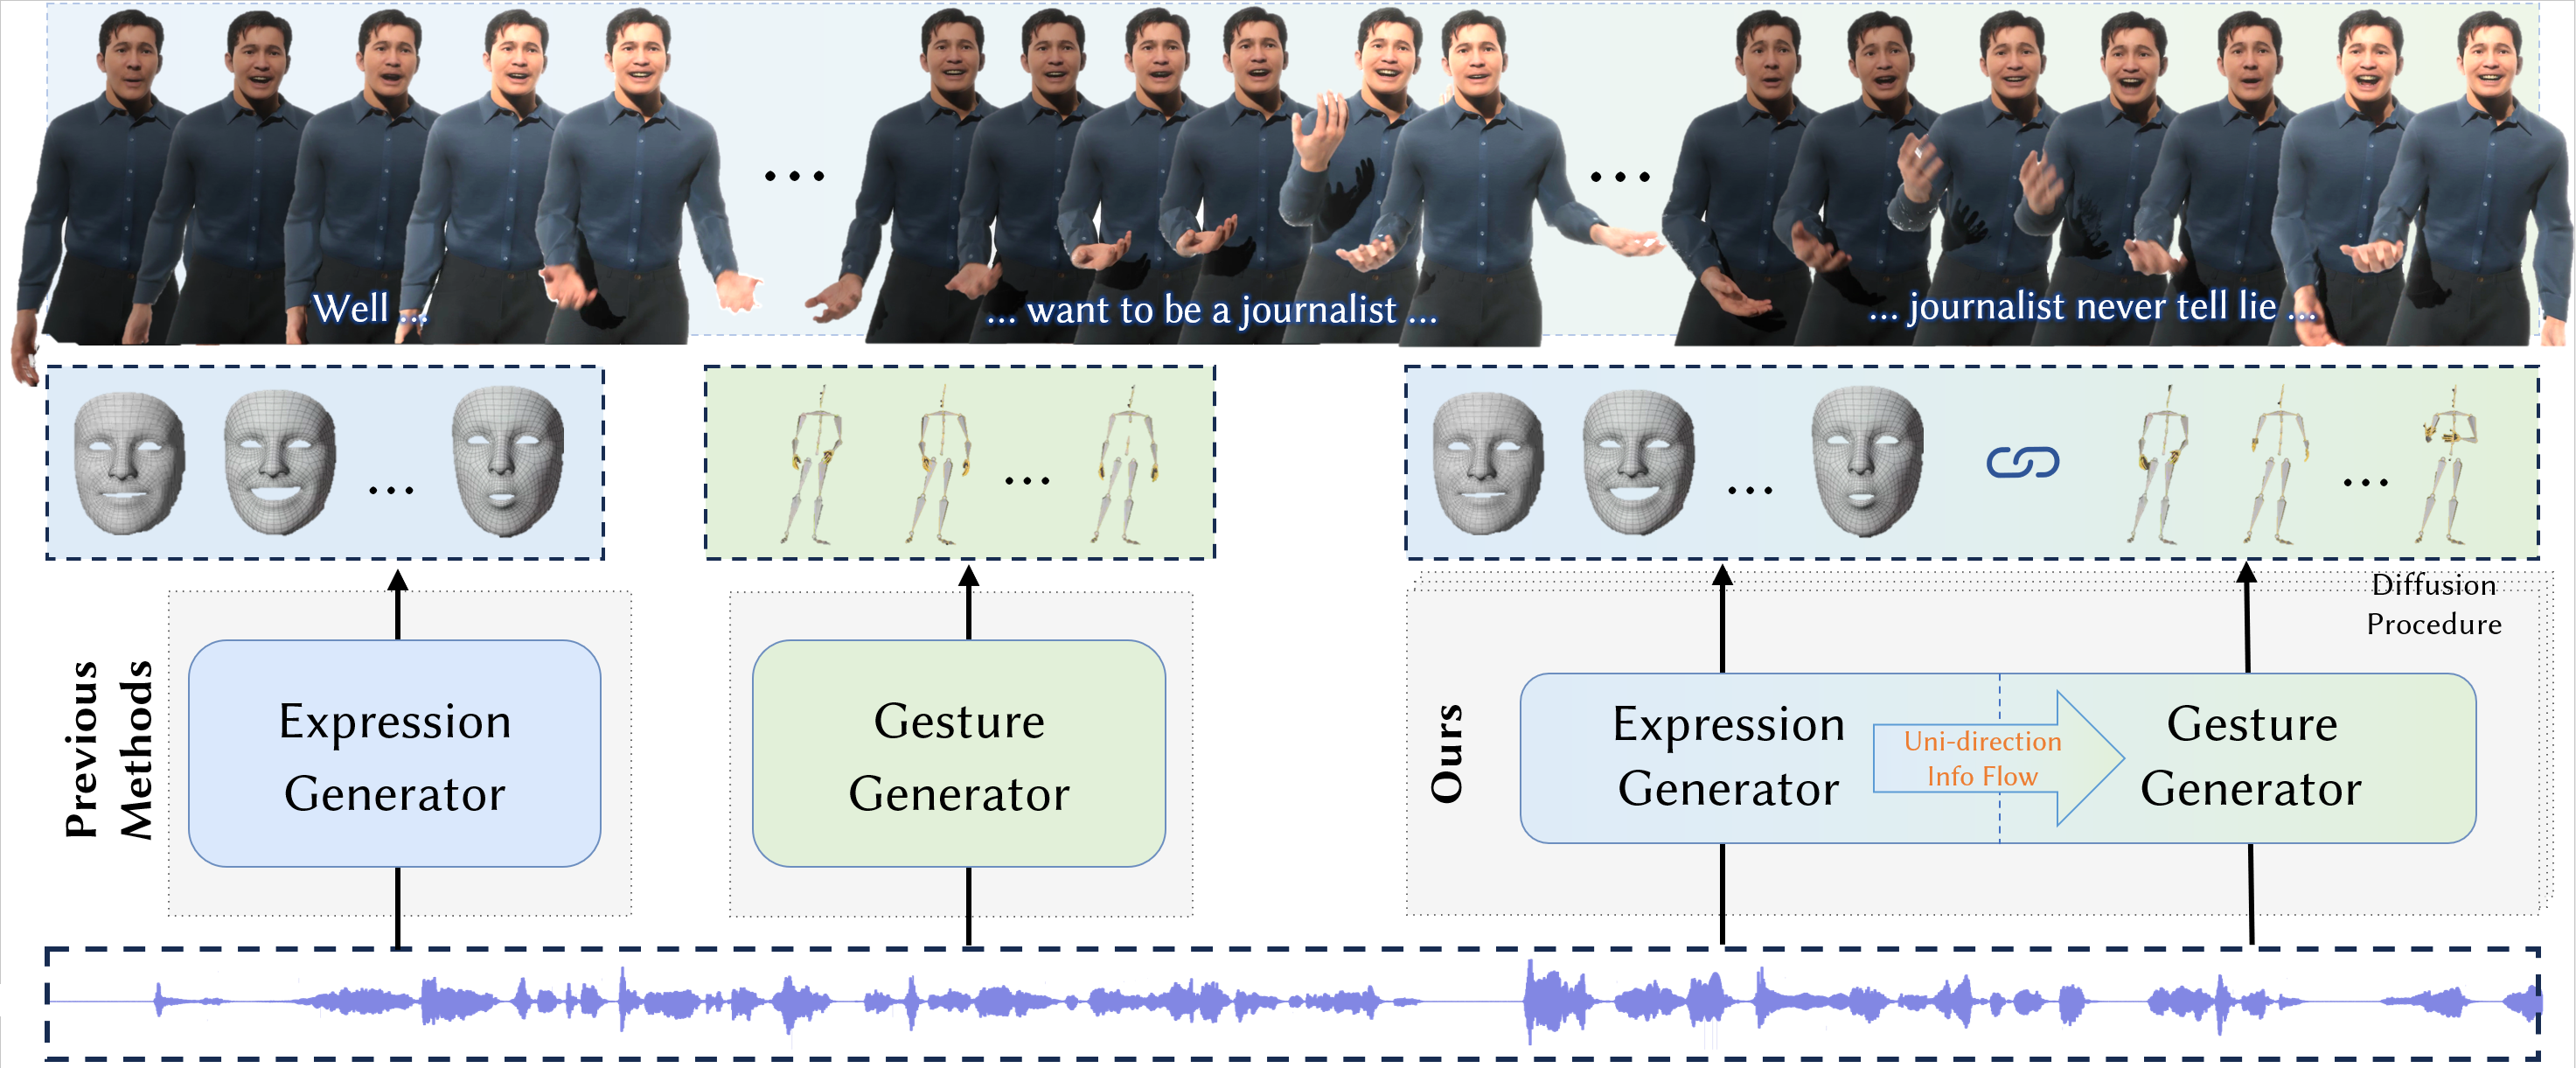
[CVPR'24] DiffSHEG: A Diffusion-Based Approach for Real-Time Speech-driven Holistic 3D Expression and Gesture Generation
See the code(CVPR 2024 Official Repo)
Junming Chen†1,2, Yunfei Liu2, Jianan Wang2, Ailing Zeng2, Yu Li*2, Qifeng Chen*1
1HKUST 2International Digital Economy Academy (IDEA)
*Corresponding authors †Work done during an internship at IDEA
We have tested on Ubuntu 18.04 and 20.04.
cd assets
conda env create -f environment.yml
conda activate diffsheg
conda create -n "diffsheg" python=3.9
conda activate diffsheg
pip install -r requirements.txt
pip install torch==1.13.1+cu117 torchvision==0.14.1+cu117 torchaudio==0.13.1 --extra-index-url https://download.pytorch.org/whl/cu117
tar zxvf data.tar.gz
mv data ../
First specify the '--test_audio_path' argument to your test audio path in the following mentioned bash files. Note that the audio should be a .wav file.
bash inference_custom_audio_beat.sh
bash inference_custom_audio_talkshow.sh
PYTHONPATH="$(dirname $0)/..":$PYTHONPATH \
OMP_NUM_THREADS=10 CUDA_VISIBLE_DEVICES=0,1,2,3,4 python -u runner.py \
    --dataset_name beat \
    --name beat_diffsheg \
    --batch_size 2500 \
    --num_epochs 1000 \
    --save_every_e 20 \
    --eval_every_e 40 \
    --n_poses 34 \
    --ddim \
    --multiprocessing-distributed \
    --dist-url 'tcp://127.0.0.1:6666'
PYTHONPATH="$(dirname $0)/..":$PYTHONPATH \
OMP_NUM_THREADS=10 CUDA_VISIBLE_DEVICES=0,1,2,3,4 python -u runner.py \
    --dataset_name talkshow \
    --name talkshow_diffsheg \
    --batch_size 950 \
    --num_epochs 4000 \
    --save_every_e 20 \
    --eval_every_e 40 \
    --n_poses 88 \
    --classifier_free \
    --multiprocessing-distributed \
    --dist-url 'tcp://127.0.0.1:6667' \
    --ddim \
    --max_eval_samples 200
PYTHONPATH="$(dirname $0)/..":$PYTHONPATH \
OMP_NUM_THREADS=10 CUDA_VISIBLE_DEVICES=0,1,2,3,4,5,6,7 python -u runner.py \
    --dataset_name talkshow \
    --name talkshow_GesExpr_unify_addHubert_encodeHubert_mdlpIncludeX_condRes_LN_ClsFree \
    --PE pe_sinu \
    --n_poses 88 \
    --multiprocessing-distributed \
    --dist-url 'tcp://127.0.0.1:8889' \
    --classifier_free \
    --cond_scale 1.25 \
    --ckpt ckpt_e2599.tar \
    --mode test_arbitrary_len \
    --ddim \
    --timestep_respacing ddim25 \
    --overlap_len 10
After running under the test or test-custom-audio mode, the Gesture and Expression results will be saved in the ./results directory.
assets/beat_visualize.blend with latest Blender on your local computer.Please refer the the TalkSHOW code for the visualization of our generated motion.
Our implementation is partially based on BEAT, TalkSHOW, and MotionDiffuse.
If you use our code or find this repo useful, please consider cite our paper:
@inproceedings{chen2024diffsheg,
  title     = {DiffSHEG: A Diffusion-Based Approach for Real-Time Speech-driven Holistic 3D Expression and Gesture Generation},
  author    = {Chen, Junming and Liu, Yunfei and Wang, Jianan and Zeng, Ailing and Li, Yu and Chen, Qifeng},
  booktitle = {CVPR},
  year      = {2024}
}
605 followers · starred Apr 2024
[CVPR'24] DiffSHEG: A Diffusion-Based Approach for Real-Time Speech-driven Holistic 3D Expression and Gesture Generation
See the code(CVPR 2024 Official Repo)
Junming Chen†1,2, Yunfei Liu2, Jianan Wang2, Ailing Zeng2, Yu Li*2, Qifeng Chen*1
1HKUST 2International Digital Economy Academy (IDEA)
*Corresponding authors †Work done during an internship at IDEA
We have tested on Ubuntu 18.04 and 20.04.
cd assets
conda env create -f environment.yml
conda activate diffsheg
conda create -n "diffsheg" python=3.9
conda activate diffsheg
pip install -r requirements.txt
pip install torch==1.13.1+cu117 torchvision==0.14.1+cu117 torchaudio==0.13.1 --extra-index-url https://download.pytorch.org/whl/cu117
tar zxvf data.tar.gz
mv data ../
First specify the '--test_audio_path' argument to your test audio path in the following mentioned bash files. Note that the audio should be a .wav file.
bash inference_custom_audio_beat.sh
bash inference_custom_audio_talkshow.sh
PYTHONPATH="$(dirname $0)/..":$PYTHONPATH \
OMP_NUM_THREADS=10 CUDA_VISIBLE_DEVICES=0,1,2,3,4 python -u runner.py \
    --dataset_name beat \
    --name beat_diffsheg \
    --batch_size 2500 \
    --num_epochs 1000 \
    --save_every_e 20 \
    --eval_every_e 40 \
    --n_poses 34 \
    --ddim \
    --multiprocessing-distributed \
    --dist-url 'tcp://127.0.0.1:6666'
PYTHONPATH="$(dirname $0)/..":$PYTHONPATH \
OMP_NUM_THREADS=10 CUDA_VISIBLE_DEVICES=0,1,2,3,4 python -u runner.py \
    --dataset_name talkshow \
    --name talkshow_diffsheg \
    --batch_size 950 \
    --num_epochs 4000 \
    --save_every_e 20 \
    --eval_every_e 40 \
    --n_poses 88 \
    --classifier_free \
    --multiprocessing-distributed \
    --dist-url 'tcp://127.0.0.1:6667' \
    --ddim \
    --max_eval_samples 200
PYTHONPATH="$(dirname $0)/..":$PYTHONPATH \
OMP_NUM_THREADS=10 CUDA_VISIBLE_DEVICES=0,1,2,3,4,5,6,7 python -u runner.py \
    --dataset_name talkshow \
    --name talkshow_GesExpr_unify_addHubert_encodeHubert_mdlpIncludeX_condRes_LN_ClsFree \
    --PE pe_sinu \
    --n_poses 88 \
    --multiprocessing-distributed \
    --dist-url 'tcp://127.0.0.1:8889' \
    --classifier_free \
    --cond_scale 1.25 \
    --ckpt ckpt_e2599.tar \
    --mode test_arbitrary_len \
    --ddim \
    --timestep_respacing ddim25 \
    --overlap_len 10
PYTHONPATH="$(dirname $0)/..":$PYTHONPATH \
OMP_NUM_THREADS=10 CUDA_VISIBLE_DEVICES=0,1,2,3,4,5,6,7 python -u runner.py \
    --dataset_name talkshow \
    --name talkshow_GesExpr_unify_addHubert_encodeHubert_mdlpIncludeX_condRes_LN_ClsFree \
    --PE pe_sinu \
    --n_poses 88 \
    --multiprocessing-distributed \
    --dist-url 'tcp://127.0.0.1:8889' \
    --classifier_free \
    --cond_scale 1.25 \
    --ckpt ckpt_e2599.tar \
    --mode test_arbitrary_len \
    --ddim \
    --timestep_respacing ddim25 \
    --overlap_len 10
After running under the test or test-custom-audio mode, the Gesture and Expression results will be saved in the ./results directory.
assets/beat_visualize.blend with latest Blender on your local computer.Please refer the the TalkSHOW code for the visualization of our generated motion.
Our implementation is partially based on BEAT, TalkSHOW, and MotionDiffuse.
If you use our code or find this repo useful, please consider cite our paper:
@inproceedings{chen2024diffsheg,
  title     = {DiffSHEG: A Diffusion-Based Approach for Real-Time Speech-driven Holistic 3D Expression and Gesture Generation},
  author    = {Chen, Junming and Liu, Yunfei and Wang, Jianan and Zeng, Ailing and Li, Yu and Chen, Qifeng},
  booktitle = {CVPR},
  year      = {2024}
}
605 followers · starred Apr 2024



