A Cross-Platform Backend for High-Performance Sparse Convolutions
Python
154
69 commits
updated Jun 25, 2026


FlexGEMM is a high-performance, Triton-powered GEMM backend designed for 3D sparse convolutions.
It implements Explicit, Implicit, and Masked Implicit algorithm variants, featuring optional Split-K parallelism for sparse GEMM. FlexGEMM delivers state-of-the-art performance for Submanifold Convolution and voxel-based neural networks, consistently outperforming existing solutions.
spconv, torchsparse) in training throughput.git clone https://github.com/JeffreyXiang/FlexGEMM.git
cd FlexGEMM
pip install . --no-build-isolation
Here is a minimal example demonstrating how to perform a sparse submanifold convolution using FlexGEMM:
import torch
import flex_gemm
from flex_gemm.ops.spconv import sparse_submanifold_conv3d
from tests.spconv_fwd import sphere_coords

# 1. Prepare Sparse Voxel Data
# Generate a sparse voxel shell
feats, coords, shape = sphere_coords(256, 256, dtype=torch.float16, device='cuda')

# 2. Define Weights and Bias
Ci, Co = 256, 256
Ks = 3
weight = torch.randn(Co, Ks, Ks, Ks, Ci, dtype=torch.float16, device='cuda', requires_grad=True)
bias = torch.randn(Co, dtype=torch.float16, device='cuda', requires_grad=True)

# 3. Configure Algorithm
# Example: Using Masked Implicit GEMM with Split-K optimization
flex_gemm.ops.spconv.set_algorithm(
    flex_gemm.ops.spconv.Algorithm.MASKED_IMPLICIT_GEMM_SPLITK
)

# 4. Forward Pass
out_feats, neighbor_cache = sparse_submanifold_conv3d(
    feats, coords, shape,
    weight, bias,
)

# 5. Backward Pass
out_feats.sum().backward()
FlexGEMM demonstrates significant speed improvements over existing baselines.
Test Environment:
Note: FlexGEMM achieves ~2× acceleration compared to previous state-of-the-art methods under efficient data formats like FP16 and TF32.
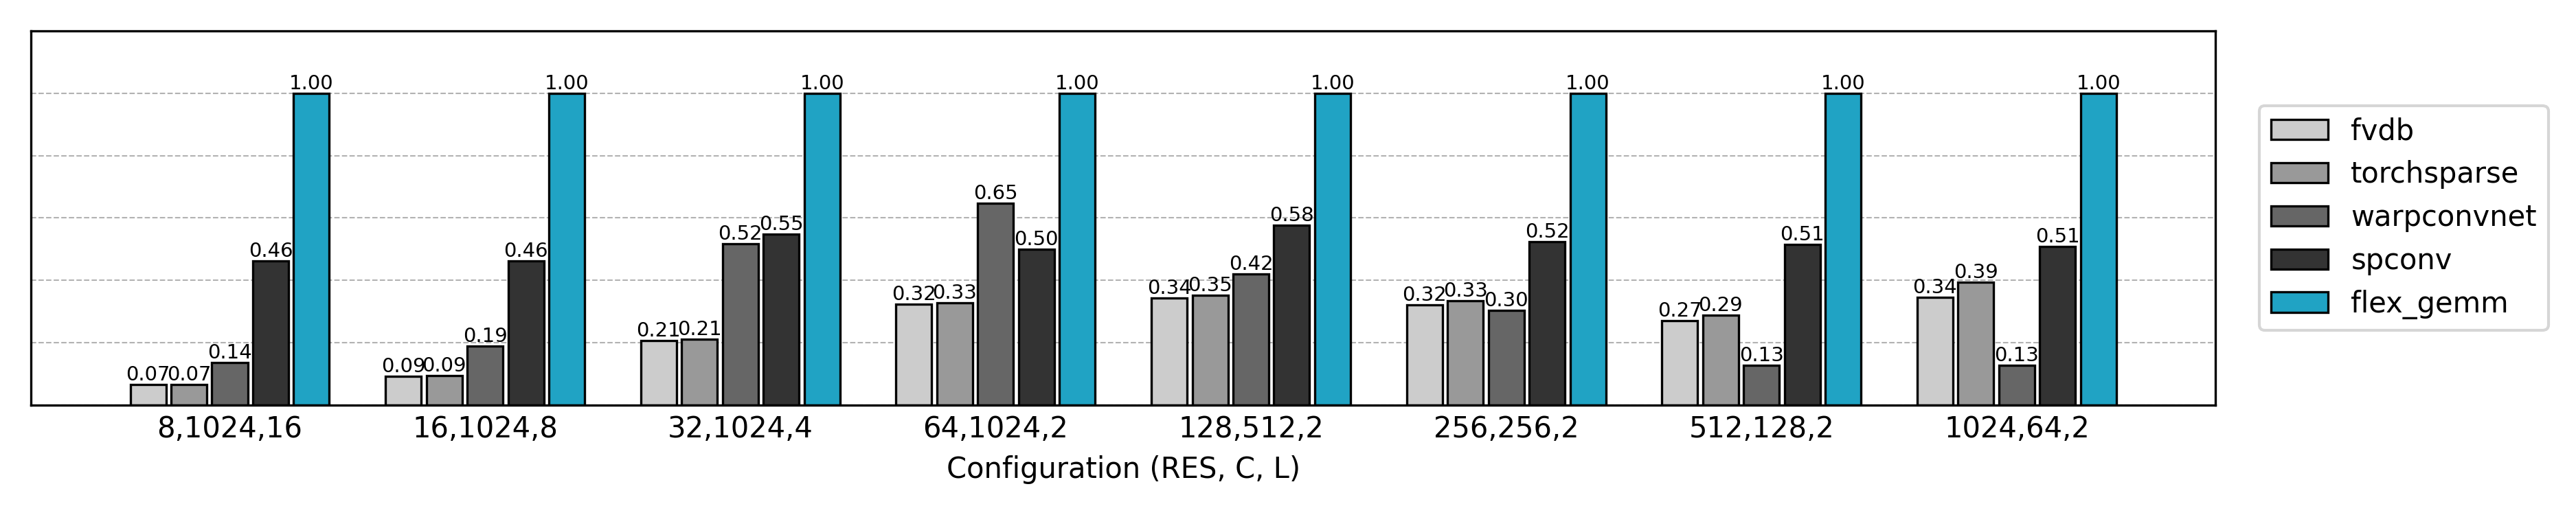
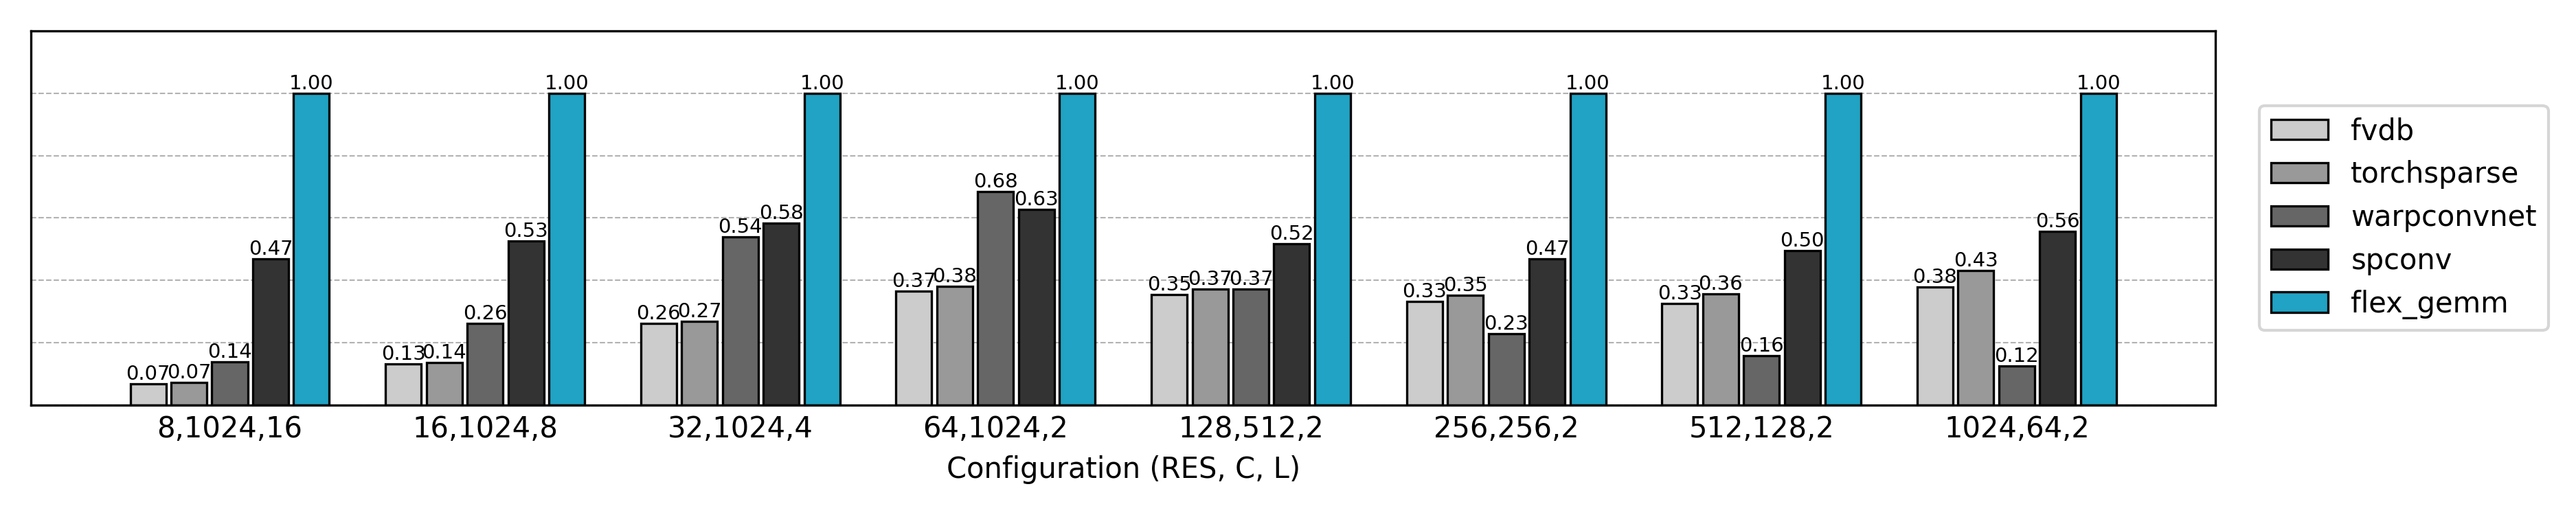
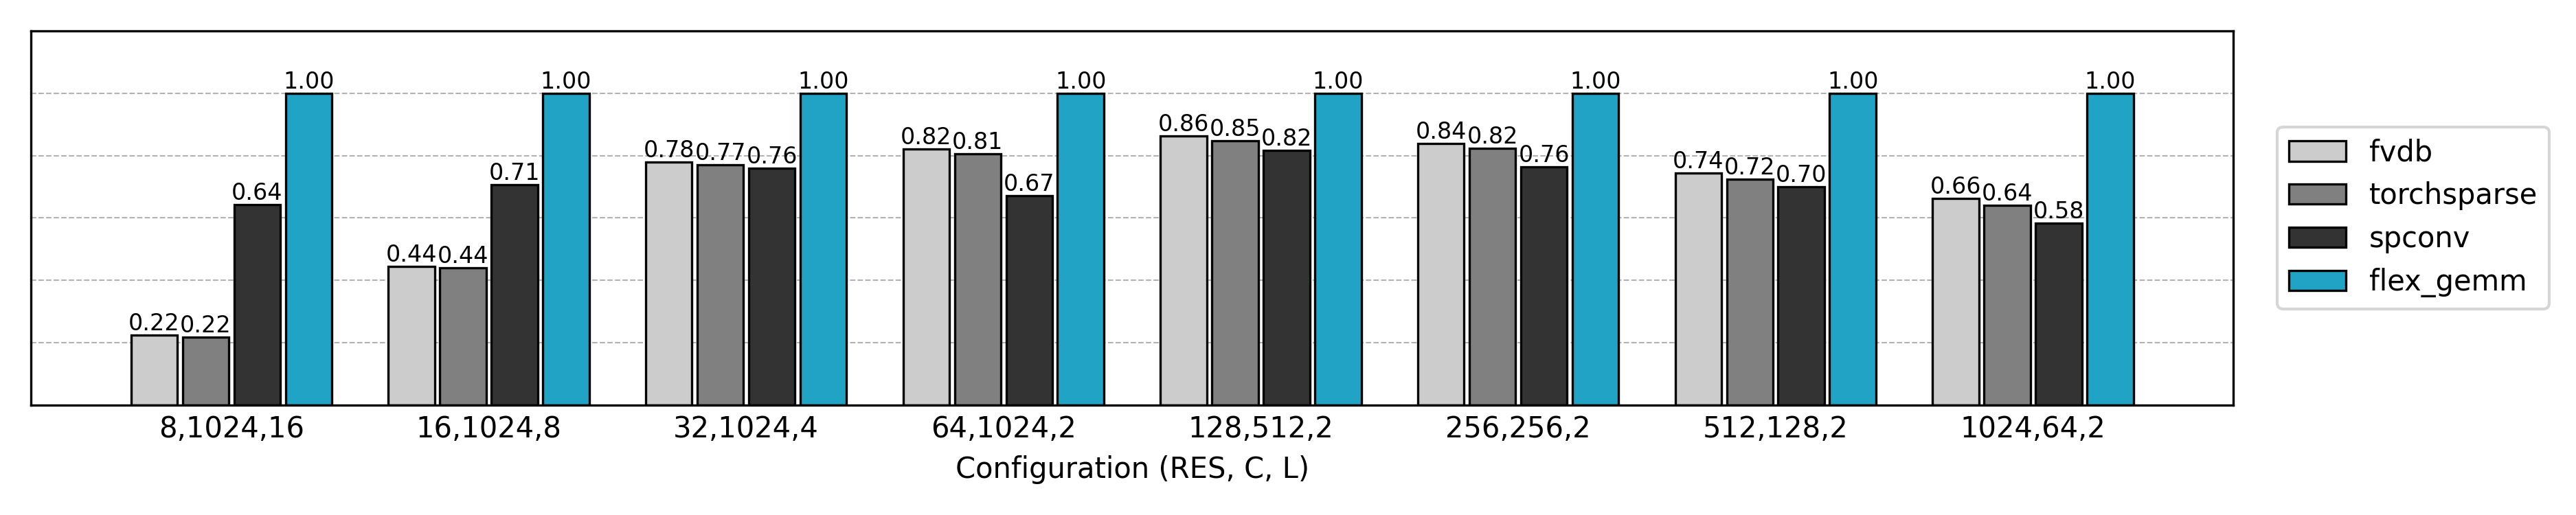
spconv, torchsparse, and fvdb.We welcome contributions to make FlexGEMM faster and more robust!
main.tests/ directory to ensure no regressions.We appreciate all contributors who help improve this project!
This project is released under the MIT License.
296 followers · starred Dec 2025
1,950 followers · starred Dec 2025
467 followers · starred Dec 2025
566 followers · starred Dec 2025
A Cross-Platform Backend for High-Performance Sparse Convolutions
Python
154
69 commits
updated Jun 25, 2026
FlexGEMM is a high-performance, Triton-powered GEMM backend designed for 3D sparse convolutions.
It implements Explicit, Implicit, and Masked Implicit algorithm variants, featuring optional Split-K parallelism for sparse GEMM. FlexGEMM delivers state-of-the-art performance for Submanifold Convolution and voxel-based neural networks, consistently outperforming existing solutions.
spconv, torchsparse) in training throughput.git clone https://github.com/JeffreyXiang/FlexGEMM.git
cd FlexGEMM
pip install . --no-build-isolation
Here is a minimal example demonstrating how to perform a sparse submanifold convolution using FlexGEMM:
import torch
import flex_gemm
from flex_gemm.ops.spconv import sparse_submanifold_conv3d
from tests.spconv_fwd import sphere_coords

# 1. Prepare Sparse Voxel Data
# Generate a sparse voxel shell
feats, coords, shape = sphere_coords(256, 256, dtype=torch.float16, device='cuda')

# 2. Define Weights and Bias
Ci, Co = 256, 256
Ks = 3
weight = torch.randn(Co, Ks, Ks, Ks, Ci, dtype=torch.float16, device='cuda', requires_grad=True)
bias = torch.randn(Co, dtype=torch.float16, device='cuda', requires_grad=True)

# 3. Configure Algorithm
# Example: Using Masked Implicit GEMM with Split-K optimization
flex_gemm.ops.spconv.set_algorithm(
    flex_gemm.ops.spconv.Algorithm.MASKED_IMPLICIT_GEMM_SPLITK
)

# 4. Forward Pass
out_feats, neighbor_cache = sparse_submanifold_conv3d(
    feats, coords, shape,
    weight, bias,
)

# 5. Backward Pass
out_feats.sum().backward()
FlexGEMM demonstrates significant speed improvements over existing baselines.
Test Environment:
Note: FlexGEMM achieves ~2× acceleration compared to previous state-of-the-art methods under efficient data formats like FP16 and TF32.
spconv, torchsparse, and fvdb.We welcome contributions to make FlexGEMM faster and more robust!
main.tests/ directory to ensure no regressions.We appreciate all contributors who help improve this project!
This project is released under the MIT License.
296 followers · starred Dec 2025
1,950 followers · starred Dec 2025
467 followers · starred Dec 2025
566 followers · starred Dec 2025